flowchart TD
SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
SUPPLIES ---|"P"| PROJECT[PROJECT]
SUPPLIER ---|"M"| CANSUPPLY{CANSUPPLY}
CANSUPPLY ---|"N"| PART[PART]
PROJECT ---|"P"| USES{USES}
USES ---|"N"| PART
sName(["sName (key)"]) --- SUPPLIER
projName(["projName (key)"]) --- PROJECT
partNo(["partNo (key)"]) --- PART
INFS1200 — Week 4 Notes
ER to Relational Mapping
Module 2, part 2 — continues on from 2026-03-09-the-relational-model-and-integrity-constraints. See relational-mapping-notation for the schema notation used throughout, and er-diagram-notation for the ER/EER diagram notation being mapped from.
Today’s outline
- The (7+1) steps for mapping an ER/EER diagram to a relational schema
- Worked example: the Company database
- Worked example: a Bank database
Why map at all?
The ER model is commonly used for conceptual design (user’s perspective); the relational model is the basis for most commercial DBMSs (storage perspective). Mapping converts a conceptual ER schema into a logical relational schema — input: an ER model; output: relations with primary/foreign key constraints.
The (7+1) steps
- Entity mapping
- Weak entity mapping
- Binary 1:1 relationship mapping
- Binary 1:N relationship mapping
- Binary M:N relationship mapping
- Multivalued attribute mapping
- N-ary relationship mapping
- (+1, for EER only) Super/subclass mapping
Super/subclass mapping (step “+1”) doesn’t happen at one fixed point — it’s generally done after step 1 or 2, whenever the subclass needs to exist for a later relationship-mapping step to reference it.
Running example — the Company database: EMPLOYEE (key Ssn, composite Name → Fname/Mit/Lname, Sex, Salary, Address, DOB), DEPARTMENT (keys Dnumber/Dname, derived NumberOfEmployees, multivalued Locations), PROJECT (keys Pno/Pname, Plocation), DEPENDENT (weak entity, partial key DepName, Sex, DOB, Relationship) — relationships WORKSFOR (EMPLOYEE N:1 DEPARTMENT), MANAGES (EMPLOYEE 1:1 DEPARTMENT, attribute StartDate), CONTROLS (DEPARTMENT 1:N PROJECT), WORKSON (EMPLOYEE M:N PROJECT, attribute Hours), SUPERVISION (EMPLOYEE recursive 1:N, roles supervisor/supervisee), DEPENDENTSOF (EMPLOYEE 1:N DEPENDENT, identifying), and EMPLOYEE disjointly (d) specialises into SECRETARY (TypingSpeed)/ENGINEER (EngineerType).
Step 1 — Entity mapping
For each (strong) entity type: create a relation, choose a key as the primary key, and include all simple attributes (not composite, derived, or multivalued).
Employee [ssn, fName, mIt, lName, dob, address, sex, salary]

Department [dNumber, dName]

Project [pNo, pName, pLocation]
Name isn’t added directly (it’s composite — its simple components fName/mIt/lName are added instead); Locations and NumberOfEmployees aren’t added to Department yet (multivalued and derived respectively — derived attributes are never stored as columns, since they’re computed on demand).
Step 2 — Weak entity mapping
For each weak entity type: create a relation; its primary key is the combination of its owner’s primary key(s) and its own partial key; include a foreign key back to the owner’s primary key; include all simple attributes.
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn
Ssn (Employee’s key) is included as part of Dependent’s own primary key, and depName is its partial key — so Dependent’s full key is (ssn, depName).
If a weak entity has more than one owner entity type, its relation includes a foreign key to each owner’s primary key, and its own primary key is the combination of all owner keys plus its partial key.
Question — Weak Entities (Cities/Provinces)
PROVINCE (key name, premier) —1:N IN→ CITY (partial key name, mayor). Resolving the dual use of “name” reasonably, which schema is the most reasonable translation?
A. Cities [name, mayor], Provinces [name, premier]
B. Cities [cName, pName, mayor], Provinces [pName, premier], Cities.cName references Provinces.pName, Cities.pName references Provinces.pName
C. Cities [cName, pName, mayor], Provinces [pName, premier], Cities.pName references Provinces.pName
D. Cities [cName, pName, mayor], In [cName, pName], Provinces [name, premier], Cities.pName references Provinces.name
NoteSolution
(C). CITY is a weak entity, so its real key is (pName, cName) — (A) is wrong since it drops pName from Cities’ key entirely. (B) is wrong because cName (the partial key) is not a foreign key — only pName (inherited from the owner) is. (D) is wrong because IN is the identifying relationship for a weak entity — it does not get mapped to its own separate relation (unlike a regular 1:N relationship, which doesn’t need one either, but D invents an unnecessary one here on top of misnaming Provinces’ key column).
Step 3 — Binary 1:1 relationship mapping
For each binary 1:1 relationship: choose one participating entity type (prefer the one with total participation); include a foreign key from it back to the other entity’s primary key; include the relationship’s own simple attributes on the chosen side.
MANAGES (EMPLOYEE 1:1 DEPARTMENT, DEPARTMENT has total participation — every department must have a manager) — extend Department, since it’s the side with total participation:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn
Question — Binary Relationship
S —1:1 R→ T (T has attribute b1). Which schema is a reasonable translation?
A. S [a1, b1], T [b1], S.b1 references T.b1
B. S [a1], T [b1]
C. ST [a1, b1]
D. S [a1], T [b1, a1], T.a1 references S.a1
NoteSolution
(A). S should be the side extended with the foreign key, since S has full/total participation in R (shown by the diagram’s 1 cardinality directly against S, no partial-participation gap) — preferred over T for that reason. (B) loses all information about the relationship itself. (C) merges two intentionally-separate entity types into one relation, discarding a conceptual modelling decision. (D) puts the foreign key on the wrong side.
Step 4 — Binary 1:N relationship mapping
For each (non-weak) binary 1:N relationship: identify the entity type on the N side; add a foreign key there, referencing the primary key of the entity type on the 1 side; include the relationship’s simple attributes on the N side.
WORKSFOR (EMPLOYEE N:1 DEPARTMENT), CONTROLS (DEPARTMENT 1:N PROJECT), SUPERVISION (EMPLOYEE recursive, N side = supervisee):
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber
Question — Relationship Mapping
A —N R 1→ B —N S 1→ C (with attributes a/d on A, b/e on B, c/f on C). Which of the following appears in your relational schema: (A) A [a, b, d], A.b references B.b; (B) B [b, c, e], B.c references C.c; (C) S [b, c]; (D) all of the above; (E) none of the above?
NoteSolution
(B). Each 1:N relationship puts the foreign key on the N side: for R that’s A (referencing B), and for S that’s B (referencing C) — so B [b, c, e], B.c references C.c is exactly right. (A) is wrong: b is the right foreign key column for A, but it shouldn’t be part of A’s primary key — 1:N foreign keys are plain (non-key) attributes on the N side, not treated as part of a composite key like a weak entity’s would be (the answer as written implies b joining A’s key, which the mapping rule doesn’t call for). (C) is wrong — S is a relationship, not an entity type, so 1:N mapping doesn’t create a relation for it at all. The full correct schema: A [a, b, d], A.b references B.b; B [b, c, e], B.c references C.c; C [c, f].
Step 5 — Binary M:N relationship mapping
For each binary M:N relationship: create a new relation; include foreign keys to both participating entity types’ primary keys (their combination becomes the new relation’s primary key); include the relationship’s own simple attributes.
WORKSON (EMPLOYEE M:N PROJECT, attribute Hours):
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo
Note: 1:1 and 1:N relationships can also be mapped this same “new relation” way — useful when the relationship is sparse, since it avoids NULL foreign key values that a direct-embedding mapping would otherwise produce for non-participating rows.
Step 6 — Multivalued attribute mapping
For each multivalued attribute: create a new relation; include a foreign key to the owning entity’s primary key; the new relation’s primary key is the combination of that foreign key and the multivalued attribute itself (if the multivalued attribute is composite, include its simple components instead).
DEPARTMENT.Locations:
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Step 7 — N-ary relationship mapping
For each N-ary relationship (excluding all-1-side cases): create a new relation; include foreign keys to all participating entity types; the foreign keys coming from the many-side entity types form the primary key; include the relationship’s own simple attributes.
(No N-ary relationships in the Company database — WORKSON is binary.)
Step “+1” — Super/subclass mapping (EER)
Works for any combination of total/partial and disjoint/overlapping subclasses. For each subclass: create a relation; its primary key is the superclass’s primary key; include a foreign key back to the superclass’s relation; include the subclass’s own simple attributes.
EMPLOYEE disjointly specialises into SECRETARY/ENGINEER:
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn
This step doesn’t happen at one fixed position in the 7-step sequence — it’s usually done right after step 1 or 2 (whichever applies to the superclass), specifically so the subclass relations already exist by the time any later relationship-mapping step needs to reference them.
Final schema — Company database
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber

Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn

Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn

WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo

DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Worked example — Bank database
A bank (unique code, name, hoAddr) has branches (branchNo unique per-bank, addr). A branch has accounts (acNo, type, balance, ≥1 account holders) and loans (loanNo, type, amount, ≥1 loan holders). Customers (ssn, name, address) can hold accounts and/or loans.
Working through the same 7 steps:
After step 1 (entity mapping):
Bank [code, name, hoAddr]

Account [acNo, type, balance]

Loan [loanNo, type, amount]

Customer [ssn, name, address]
After step 2 (BRANCH is a weak entity, owned by BANK):
Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code
After step 4 (BRANCH 1:N ACCOUNT/LOAN — foreign keys added to the N side; note the FK is composite here, since Branch’s own key is composite):
Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}
After step 5 (ACCOUNT/LOAN M:N CUSTOMER — new relations):
AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Final schema:
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code

Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Customer [ssn, name, address]

AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Applied Class 3: Relational Integrity
Practice for 2026-03-09-the-relational-model-and-integrity-constraints. See relational-mapping-notation for reference.
Section A — Recap and preview
Question 1 — Matching relational concepts
Match each concept to its description: (1) any minimal set of attributes that can uniquely identify tuples in a relation, (2) defines the structure of a relation, specified during database design, (3) a candidate key chosen to identify tuples in a relation, (4) data in a relation, modified via create/update/delete operations.
NoteWorking
Candidate key → 1, Relational Schema → 2, Primary Key → 3, Relational Instance → 4.
Question 2 — Electoral roll schema
Given:
Region [prefix, suffix]

Member [enrolmentId, passportNum, regionPrefix, regionSuffix]
Member.{regionPrefix, regionSuffix} references Region.{prefix, suffix}

Candidate [enrolmentId, name, regionPrefix, regionSuffix]
Candidate.enrolmentId references Member.enrolmentId
Candidate.{regionPrefix, regionSuffix} references Region.{prefix, suffix}
List all examples of each component: candidate key, primary key, composite primary key, foreign key.
The schema comes from this ER diagram, and every answer below can be read straight off it:
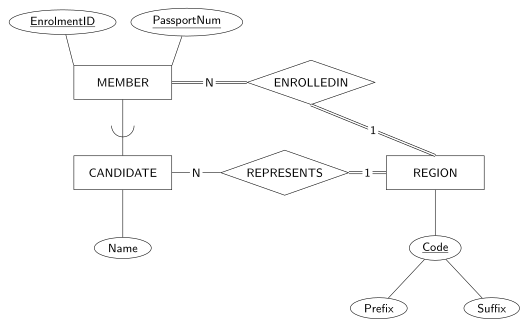
Figure 1: The electoral-roll ER diagram the Question 2 schema was mapped from. CANDIDATE is a subclass of MEMBER (the arc on the connecting line, opening towards the superclass), which is why Candidate.enrolmentId is simultaneously its primary key and a foreign key to Member. REGION’s key Code is a composite attribute splitting into Prefix and Suffix, which is why the mapped primary key is the pair. Both EnrolmentID and PassportNum are drawn as key attributes, giving MEMBER two candidate keys.
NoteWorking
- Candidate key:
Member.enrolmentId,Member.passportNum,Candidate.enrolmentId,Region.{prefix, suffix}. - Primary key:
Member.enrolmentId,Candidate.enrolmentId,Region.{prefix, suffix}. - Composite primary key:
Region.{prefix, suffix}. - Foreign key:
Member.{regionPrefix, regionSuffix},Candidate.{regionPrefix, regionSuffix},Candidate.enrolmentId.
Three things to notice, because each is a different rule doing the work: Member.passportNum is a candidate key that lost the nomination, so it is not a primary key (relational-keys); Region.{prefix, suffix} is the only composite primary key here, and it forces every reference to it to be a composite foreign key; and Candidate.enrolmentId is the one attribute that is a primary key and a foreign key at once, because CANDIDATE is a subclass of MEMBER and subclass mapping gives the subclass relation its superclass’s key.
Question 3 — Schema statements
Select all true statements: (1) a schema is the metadata, or data describing the data, (2) a schema is specified during database design, (3) a schema is created during data updates and changes frequently, (4) a schema is the data in the database at a particular time.
Enter the correct option numbers in ascending order, comma-separated:
NoteWorking
1, 2. A schema is metadata specified at design time — it doesn’t change with every data update (that’s the instance), and it isn’t itself “the data” (statements 3 and 4 both describe the instance, not the schema).
Question 4 — Key statements
Select all true statements: (1) a key is a unique identifier of a tuple in the relation, (2) the key constraint implies no two tuples can share the same values for all attributes, (3) a key cannot have multiple attributes, (4) an entity may have more than one primary key, (5) a primary key is a candidate key chosen as the main key for a relation.
Enter the correct option numbers in ascending order, comma-separated:
NoteWorking
1, 5. (2) is a weaker, different notion (that’s just basic set semantics — no two tuples are ever fully identical in a relation regardless of keys — not what makes something a key specifically). (3) is false — composite keys exist (e.g. Region.{prefix, suffix} above). (4) is false — an entity can have several candidate keys, but only one of them is chosen as the primary key.
Section B — Integrity constraints in practice
A company database: Employee [ssn, fName, mInit, lName, bDate, address, sex, salary, superSsn, dNo], Department [dName, dNumber, mgrSsn, mgrStartDate], DeptLocations [dNumber, dLocation], Project [pName, pNumber, pLocation, dNum], WorksOn [essn, pNo, hours], Dependent [essn, depName, sex, bDate, relationship]. Two extra business rules, requested by the Board of Directors on top of the DBMS-enforced ones: an employee’s salary cannot exceed their supervisor’s, and a department cannot have more than three active projects at a time. For each operation below, does it violate an integrity constraint (assume any earlier operations in this list have not been applied)?
Every answer in this section is a question about the arrows below, so read the foreign-key map before the operations:
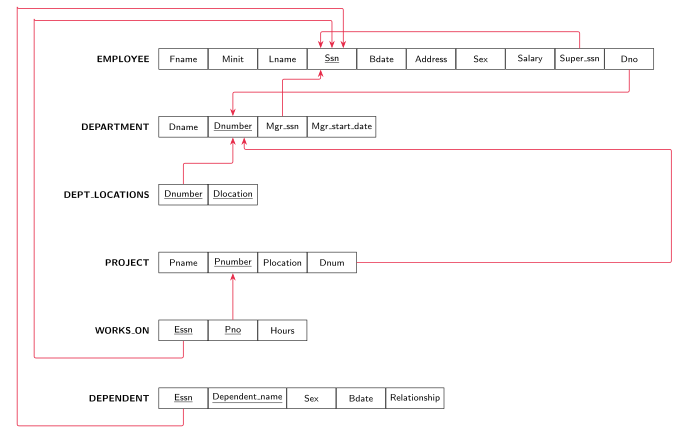
Figure 2: The relational diagram for the company database: eight foreign keys over six relations. Arrowheads land on the referenced attribute: an arrow points child → parent. Three separate relations reference Employee.ssn and Employee references itself through Super_ssn, which is why deleting one employee row is the messiest operation in Section B. Attribute names in the diagram are the textbook spellings (Ssn, Dno, Essn, Pno); the prose above uses the camelCase equivalents for the same columns. Each component of a composite key is underlined in its own box, where the written schema convention runs one continuous underline.
NoteInstance data the operations are judged against
Employee
| fName | mInit | lName | ssn | bDate | address | sex | salary | superSsn | dNo |
|---|---|---|---|---|---|---|---|---|---|
| John | B | Smith | 123456789 | 1965-01-09 | 731 Fondren, Houston, TX | M | 30000 | 333445555 | 5 |
| Franklin | T | Wong | 333445555 | 1955-12-08 | 638 Voss, Houston, TX | M | 40000 | 888665555 | 5 |
| Alicia | J | Zelaya | 999887777 | 1968-01-19 | 3321 Castle, Spring, TX | F | 25000 | 987654321 | 4 |
| Jennifer | S | Wallace | 987654321 | 1941-06-20 | 291 Berry, Bellaire, TX | F | 43000 | 888665555 | 4 |
| Ramesh | K | Narayan | 666884444 | 1962-09-15 | 975 Fire Oak, Humble, TX | M | 38000 | 333445555 | 5 |
| Joyce | A | English | 453453453 | 1972-07-31 | 5631 Rice, Houston, TX | F | 25000 | 333445555 | 5 |
| Ahmad | V | Jabbar | 987987987 | 1969-03-29 | 980 Dallas, Houston, TX | M | 25000 | 987654321 | 4 |
| James | E | Borg | 888665555 | 1937-11-10 | 450 Stone, Houston, TX | M | 55000 | NULL | 1 |
Department and DeptLocations
| dName | dNumber | mgrSsn | mgrStartDate |
|---|---|---|---|
| Research | 5 | 333445555 | 1988-05-22 |
| Administration | 4 | 987654321 | 1995-01-01 |
| Headquarters | 1 | 888665555 | 1981-06-19 |
| dNumber | dLocation |
|---|---|
| 1 | Houston |
| 4 | Stafford |
| 5 | Bellaire |
| 5 | Sugarland |
| 5 | Houston |
Project and WorksOn
| pName | pNumber | pLocation | dNum |
|---|---|---|---|
| ProductX | 1 | Bellaire | 5 |
| ProductY | 2 | Sugarland | 5 |
| ProductZ | 3 | Houston | 5 |
| Computerization | 10 | Stafford | 4 |
| Reorganization | 20 | Houston | 1 |
| Newbenefits | 30 | Stafford | 4 |
| essn | pNo | hours |
|---|---|---|
| 123456789 | 1 | 32.5 |
| 123456789 | 2 | 7.5 |
| 666884444 | 3 | 40.0 |
| 453453453 | 1 | 20.0 |
| 453453453 | 2 | 20.0 |
| 333445555 | 2 | 10.0 |
| 333445555 | 3 | 10.0 |
| 333445555 | 10 | 10.0 |
| 333445555 | 20 | 10.0 |
| 999887777 | 30 | 30.0 |
| 999887777 | 10 | 10.0 |
| 987987987 | 10 | 35.0 |
| 987987987 | 30 | 5.0 |
| 987654321 | 30 | 20.0 |
| 987654321 | 20 | 15.0 |
| 888665555 | 20 | NULL |
Dependent
| essn | depName | sex | bDate | relationship |
|---|---|---|---|---|
| 333445555 | Alice | F | 1986-04-05 | Daughter |
| 333445555 | Theodore | M | 1983-10-25 | Son |
| 333445555 | Joy | F | 1958-05-03 | Spouse |
| 987654321 | Abner | M | 1942-02-28 | Spouse |
| 123456789 | Michael | M | 1988-01-04 | Son |
| 123456789 | Alice | F | 1988-12-30 | Daughter |
| 123456789 | Elizabeth | F | 1967-05-05 | Spouse |
The three facts that decide most of Section B: the only department numbers in use are 1, 4 and 5; department 5 already has three projects (ProductX, ProductY, ProductZ), which is the semantic limit; and 888665555 (James Borg) earns 55000, so any subordinate of his earning more breaks the salary rule.
B1 — Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into Employee (943775543 is not yet an Employee ssn; the supervisor 888665555 is James Borg, who earns 55000 and runs department 1).
B2 — Insert ('ProductA', 'A', 'Bellaire', 2) into Project (no Department with dNumber = 2 exists).
B3 — Insert ('Production', 4, 943775543, '1988-10-01') into Department (a Department with dNumber = 4 already exists; no Employee with ssn = 943775543 exists).
B4 — Insert (677678989, null, 40.0) into WorksOn (no Employee with ssn = 677678989 exists).
B5 — Insert ('Grace', 'G', 'Chan', 31203126, '1962-06-21', '2312 Anchor Rd, Bellaire, TX', 'F', 58000, 888665555, 1) into Employee (supervisor 888665555 earns less than 58000).
B6 — Delete the WorksOn tuples with essn = 333445555.
B7 — Delete the Employee tuple with ssn = 987654321.
B8 — Modify mgrSsn/mgrStartDate of the Department tuple with dNumber = 5 to 123456789/'1988-10-01' (123456789 is an existing Employee SSN).
B9 — Modify superSsn of the Employee tuple with ssn = 999887777 to 943775543 (no Employee with ssn = 943775543 exists).
B10 — Insert ('ProductSuperDuperSecret', 86, 'Washington', 5) into Project (department 5 already has three active projects).
NoteWorking
- B1 No — this is a well-formed, non-conflicting insert: the new
ssndoesn’t already exist (no key violation), the supervisorssndoes exist (no referential violation), and the salary doesn’t exceed the supervisor’s (no semantic violation). - B2 Yes — Referential integrity (
dNum = 2doesn’t exist inDepartment) and domain constraint (pNumbershould be an integer, not the string'A'). - B3 Yes — Key constraint (
dNumber = 4already exists) and referential integrity (mgrSsn = 943775543doesn’t exist inEmployee). - B4 Yes — Entity integrity (
pNo, part ofWorksOn’s primary key, isNULL) and referential integrity (essn = 677678989doesn’t exist inEmployee). - B5 Yes — Semantic constraint (this employee’s salary exceeds their supervisor’s).
- B6 No — nothing else references
WorksOnrows as a foreign key target, and no business rule requires an employee to have work assignments, so deleting them is unconstrained. - B7 Yes — Referential integrity (
WorksOn,Dependent,Department, andEmployeeitself all have tuples referencing thisssn, which would be left dangling). - B8 No —
123456789is a valid existing employee,dNumber = 5already exists (this is an update, not a duplicate insert), and no stated business rule constrains who can be a department’s manager. - B9 Yes — Referential integrity (the new
superSsnvalue doesn’t match any existingEmployee.ssn). - B10 Yes — Semantic constraint (exceeds the “max 3 active projects per department” business rule).
Case Study 3: Dirt Road Driving
Group case study applying ER-to-relational mapping from 2026-03-16-er-to-relational-mapping to a revised Dirt Road Driving EER diagram (the EER diagram itself is week2-tutorial-case-study-1-dirt-road-driving’s, refined per that case study’s open-ended Section B). See relational-mapping-notation for reference.
Section A — Full relational mapping
Elaine’s team maps the revised EER diagram (User, Staff disjointly specialising into Driver/Admin, Vehicles disjointly specialising into 4WD/2WD, weak entities EmergencyContact and TripStop, the ternary-ish Trip, and the UserRatesDriver/ UserRatesVehicle relationships) to a full relational schema.
NoteWorking
User [id, dob, firstName, middleName, lastName]

Staff [id, dob, firstName, middleName, lastName]

Vehicles [vin, make, model]

Driver [id, licence]
Driver.id references Staff.id

Admin [id, deskNumber]
Admin.id references Staff.id

4WD [vin, rideHeight, wheelType]
4WD.vin references Vehicles.vin

2WD [vin, frontWheelDrive]
2WD.vin references Vehicles.vin

EmergencyContact [userID, name, email, phone]
EmergencyContact.userID references User.id

StaffPhone [id, phone]
StaffPhone.id references Staff.id

Trip [userID, driverID, vin, bookingTime, startTime, endTime]
Trip.userID references User.id
Trip.driverID references Driver.id
Trip.vin references Vehicles.vin

TripStop [userID, driverID, vin, bookingTime, location]
TripStop.{userID, driverID, vin, bookingTime} references Trip.{userID, driverID, vin, bookingTime}

UserRatesDriver [userID, driverID, rating]
UserRatesDriver.userID references User.id
UserRatesDriver.driverID references Driver.id

UserRatesVehicle [userID, vin, rating]
UserRatesVehicle.userID references User.id
UserRatesVehicle.vin references Vehicles.vin
Key points:
Driver/Adminand4WD/2WDare standard disjoint-subclass mappings — each subclass’s primary key is its superclass’s key, plus a foreign key back to the superclass.EmergencyContactis a weak entity owned byUser— its real key is(userID, name)(owner’s key + its own partial keyname), not justnamealone (a name is only guaranteed unique per user).StaffPhonemapsStaff’s multivaluedPhoneattribute — its primary key is(id, phone)(the multivalued attribute joins the owner’s key to form the key, per the multivalued-attribute mapping rule), which makes sense of whyphoneisn’t shown as a single extra column onStaffitself.Tripis identified by the combination ofuserID,driverID,vin, andbookingTime— a trip is only unique per that combination (the same user/driver/vehicle triple could recur across different bookings).TripStopis a weak entity too, owned byTrip— it needsTrip’s entire composite key as a foreign key, plus its own partial keylocation.UserRatesDriver/UserRatesVehicleare both M:N relationships (each gets its own new relation, combining both sides’ foreign keys as its primary key, plus the relationship’s ownratingattribute).
Section B — Spot the mistakes
A junior admin partially mapped the same diagram:
User [id, dob, firstName, middleName, lastName]

Staff [id, dob, firstName, middleName, lastName]

Vehicles [vin, make, model]

EmergencyContact [name, userID, email, phone]
EmergencyContact.userID references User.id

Trip [userID, driverID, vin, bookingTime, startTime, endTime]
Trip.userID references User.id
Trip.driverID references Staff.id
Trip.vin references Vehicles.vin

UserRatesDriver [userID, driverID, rating]
UserRatesDriver.userID references User.id
UserRatesDriver.driverID references Driver.id

Driver [id, licence]
Driver.id references Staff.id

4WD [vin, make, model, rideHeight, wheelType]
4WD.vin references Vehicles.vin

StaffPhone [id, phone]
StaffPhone.id references Staff.id
Find 5 mistakes (ignore “missing tables” — some relations from Section A are simply left out here, and that’s not one of the 5).
NoteWorking
EmergencyContact’s primary key is missinguserID. As a weak entity, its key must be(userID, name), notnamealone — otherwise two different users couldn’t each have an emergency contact with the same name (e.g. two users both listing a contact named “Mum”).Trip’s primary key is missingbookingTime. Without it, a user couldn’t take two separate trips with the same driver and vehicle —bookingTimeis exactly what distinguishes repeat trips between the same pair.Trip.driverIDincorrectly referencesStaff.idinstead ofDriver.id. This would let anAdmin-only staff ID (someone who isn’t aDriverat all) be entered as a trip’s driver, corrupting the data and undermining any audit that assumesdriverIDalways names an actual driver.4WDredundantly repeatsmake/model. These are already stored onVehicles(the superclass) — duplicating them wastes space and risks the two copies going out of sync.StaffPhone’s primary key is missingphone. As the mapping of a multivalued attribute, the key must be(id, phone)— withoutphonein the key, each staff member could only ever have one phone number on file, defeating the purpose of the multivalued attribute allowing several.
Reference material
Conceptual Database Design
Conceptual design is everything that happens before a single table exists: deciding which slice of the world the database is about, and expressing that slice as an ER/EER diagram. It is a very important phase in designing a successful database application, and it follows a two-step procedure. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model.
The Universe of Discourse
- Step 1 — identify the Universe of Discourse (UoD): the “mini-world” the database models. A database never models everything in the world, only the part an organisation actually needs to record.
- Step 2 — convert that UoD into a data model a database can capture.
Those two steps are the whole of conceptual design in this course: the world → the UoD → the data model. Everything in entity-types-and-attributes, relationship-types and specialisation-and-generalisation is machinery for step 2.
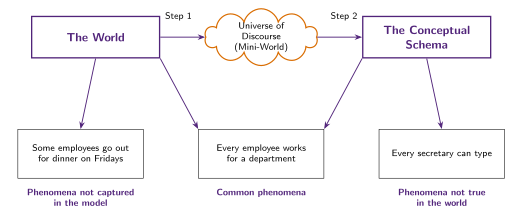
Figure 3: The two-step pipeline and the three categories of phenomena around the finished schema. The pipeline is the World → UoD → Data Model chain, and the three phenomenon boxes fan off the World and the Conceptual Schema. Only the middle box has an arrow from both, which is exactly what makes it common: true in the world and captured in the model.
The UoD is not a formality to get past. Every constraint drawn later — cardinality ratios, participation, disjointness — is read off the UoD rather than chosen arbitrarily (see relationship-constraints), so a vague or ambiguous UoD produces a diagram whose constraints can’t be justified. Where the UoD genuinely is ambiguous, that ambiguity becomes a design decision to record explicitly — see er-design-choices.
A model is never perfect
Around any conceptual schema there are three categories of phenomena (Figure 3):
| Category | Meaning | Example |
|---|---|---|
| Common phenomena | True in the world and captured in the model | “Every employee works for a department” |
| Phenomena not captured | True in the world, deliberately left out as irrelevant | “Some employees go out for dinner on Fridays” |
| Phenomena not true in the world | Captured by the model, but an over-general assumption | “Every secretary can type” |
The first category is the target. The second is fine and unavoidable — a model that captured everything would be the world itself. The third is the dangerous one: the schema will happily enforce a rule that reality violates, and the mismatch only surfaces once real data arrives.
What the ER model is for
The Entity-Relationship (ER) model provides a graphical representation of data entities, which is what makes it useful for defining a project’s scope and requirements with clients and businesses — it’s a communication artefact agreed on before implementation, not an implementation itself. Three questions run through the module: why conceptual modelling matters for designing a successful database application, how the ER model is used to do it, and how to evaluate the trade-offs between design choices by comparing alternative ER diagrams for the same system — the third of which is the whole content of er-design-choices.
An entity is a physical or conceptual object with data (attributes) associated with it. Crucially, the same real-world entity is recorded differently depending on the system’s requirements: an R&D organisation records an employee’s Degree and Field of Study, while a retail organisation records Sales Experience instead. There is no “correct” attribute list for a real-world thing in the abstract — only one that’s correct for a given UoD. See entity-types-and-attributes and relationship-types for the building blocks, specialisation-and-generalisation for the EER extension on top of them, and er-diagram-notation for the symbol legend. Reading a finished diagram back out is its own skill — interpreting-er-diagrams.
Where conceptual design sits
“Conceptual” is also the middle layer of a DBMS’s three-schema architecture (dbms-fundamentals) — the level that describes the whole database for a community of users, as opposed to any one user’s view of it. Conceptual design is where that schema gets written.
This course names no formal design lifecycle. The subject splits into three concerns, worked through in dependency order:
| Concern | Covered by |
|---|---|
| Database design — conceptual database design, then design theory and normalisation | This note, then functional-dependencies and normal-forms |
| Data models — the relational model, its integrity constraints, and ER-to-relational mapping | relational-model, integrity-constraints, er-to-relational-mapping |
| Physical storage — file organisation, hashing, indexing | Explicitly deferred to later INFS courses |
So the working pipeline is: conceptual design produces the ER/EER diagram; mapping turns it into a relational schema; SQL (sql-ddl) declares that schema; and normalisation refines it afterwards. Physical storage — the internal level of the three-schema architecture — never enters the picture here, which is exactly what physical data independence is supposed to buy.
That ordering is why conceptual mistakes are expensive. A decision that looks cosmetic on the diagram propagates into the schema and into the constraints the DBMS can actually enforce — the mapping errors dissected in week4-tutorial-case-study-3-dirt-road-driving are all downstream consequences of getting an entity’s identity or a relationship’s endpoint wrong at the conceptual stage.
Entity Types and Attributes
The two smallest building blocks of an ER diagram: the kinds of thing a database records, and the facts it records about them. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd; see er-diagram-notation for the symbols and the naming style guide.
Entity, entity type, entity set
Three words that are easy to blur together, and are worth keeping apart:
| Term | Meaning |
|---|---|
| Entity | A physical or conceptual object with data associated with it — one particular student, one particular chef |
| Entity type | The format for the data that needs to be recorded to represent a particular entity — described by its name and its attributes. Drawn as a rectangle with attribute ovals attached |
| Entity set | The collection of all entities of one entity type in the database at any point in time |
The entity type is the schema-level thing (it doesn’t change as data comes and goes); the entity set is the instance-level thing (it changes with every insert and delete). The entity set is what becomes a table once the diagram is mapped — see er-to-relational-mapping.
Which attributes an entity type carries is decided by the UoD, not by the real-world object: an R&D organisation records an employee’s Degree and Field of Study where a retail organisation records Sales Experience instead. See conceptual-database-design.
Kinds of attribute
Attributes are classified along several independent axes — an attribute can be composite and multivalued, key and composite, and so on:
| Kind | Meaning | Example |
|---|---|---|
| Simple | Can’t be meaningfully split further | Email, DoB |
| Composite | Divides into smaller parts which are simple attributes with independent meaning | Name → Fname, Mname, Lname; Address → Number, Sname, Suburb, Pcode |
| Single-valued | Holds at most one value per entity | DoB |
| Multivalued | Can hold more than one value per entity (double-lined oval) | Degree — one person can hold several; Specialisations, Ingredients, Locations |
| Stored | Physically recorded | BirthDate |
| Derived | Computed from another stored attribute (dashed oval) | Age from BirthDate; Number_of_employees on a department |
| Key | Value is unique across the whole entity set (name underlined) | StudentID, Ssn |
A single EMPLOYEE entity type can carry every kind at once:
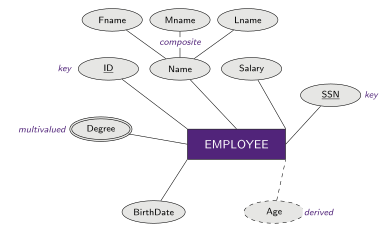
Figure 4: Every kind of attribute on one EMPLOYEE entity type. ID and SSN are two independent key attributes (solid underline). Name is composite — it fans out into Fname/Mname/Lname, and the parent oval itself is unmarked. Degree is multivalued (double outline): one person can hold several degrees. Age is derived from BirthDate, so it gets a dashed outline and a dashed connecting line, and it is never stored.
The single/multivalued split is stated over simple attributes — a composite attribute’s multiplicity is really a property of its components. The distinction between composite and multivalued is the one that catches people out: Name splitting into first/middle/last is composite (one name made of parts), whereas Phone on a student is multivalued (several independent phone numbers). Both attach several ovals to the diagram, but they mean different things and map differently.
Key attributes and candidate keys
Every entity type has at least one key constraint (equivalently, a uniqueness constraint), carried by a key attribute whose value is distinct for each individual entity in the entity set. Two properties matter:
- Multiple keys are possible. An entity type can have several independent candidate keys, each underlined in its own oval — the
EMPLOYEEabove carries bothIDandSSN. Elsewhere in the course: aDISHidentified by either itsNameor itsNumber, aVENUEby either itsIDor the combination ofNameandAddress, aVACCINEby either itsIDorBrand+Name. Any claim that an entity is “only identifiable by X” is false as soon as a second key oval is on the diagram. - A key must hold for every possible extension of the entity type. It isn’t enough that the current data happens to have no duplicates; the key must be a rule about every state the entity set could ever reach.
A composite key is a combination of simple attributes that together must be unique — a car’s Registration = State + Number, alongside a separate simple key VehicleID. On the diagram this is drawn as one underlined parent oval that splits into its component ovals, which is how you can tell “these two attributes are jointly a key” apart from “these are two separate keys”:
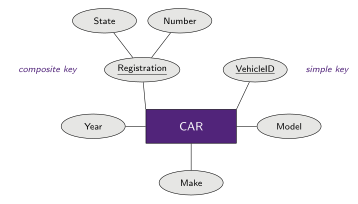
Figure 5: A CAR entity type with two candidate keys side by side: the composite Registration (underlined parent oval, splitting into State and Number — neither of which is unique alone) and the simple VehicleID. Year, Model and Make are ordinary attributes. Which of the two candidate keys is chosen as the primary key is deferred to the mapping stage, and changes the resulting schema — see er-to-relational-mapping.
The single exception to “every entity type has a key” is the weak entity, which has no key attribute of its own and is identified by its owner’s key plus its own partial key — see relationship-constraints. See also relational-keys for the same idea stated over relations rather than entity types.
Value sets and nulls
An attribute’s value set specifies the set of values that may be assigned to that attribute of an entity — employeeAge: integers between 21 and 65; vehicleRegistrationNum: a string of three alphabetic characters followed by three integers. Value sets are never displayed on the ER diagram itself — they resurface later as the domains of the relational-model, enforced as the domain constraint among the integrity-constraints.
A particular entity may not have an applicable value for an attribute, and a null value is used to represent that. Three reasons a null appears are worth keeping apart, because they are different facts about the world:
| Reason | Example |
|---|---|
| Not applicable | tertiaryDegree for a person with no university education |
| Not known whether it exists | homePhone |
| Missing — exists, but not recorded | height |
Nulls are the reason an attribute being “optional” is a real modelling decision rather than an afterthought; see sql-nulls for how they behave once queried.
Why the attribute kind matters later
The classification isn’t decorative — each kind maps differently:
- A multivalued attribute becomes its own relation, keyed on the owner’s key plus the value itself:
Staff’s multivaluedPhonebecomesStaffPhone [id, phone]. It has to — a relational column holds one atomic value (relational-model). Leavingphoneout of that key would cap each staff member at one phone number, defeating the point of making it multivalued in the first place. - A derived attribute is computed on demand, so it gets no column of its own: a trip’s
Fareis derived from its start and end times and simply doesn’t appear in the mappedTriprelation. - A composite attribute is flattened into its simple components (
Name→firstName,middleName,lastName).
All three are worked through in week4-tutorial-case-study-3-dirt-road-driving; the mapping rules themselves live in er-to-relational-mapping.
ER Design Choices
When modelling complex organisations, a database designer faces design choices: two people modelling the same Universe of Discourse will not draw the same diagram, and that isn’t necessarily a sign either of them is wrong. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Equivalent vs inequivalent choices
- Equivalent choices — an aspect of the UoD can be represented in an ER diagram by two different methods which are both equivalent, i.e. the resulting database will be the same. Genuinely a matter of taste; pick either.
- Inequivalent choices — the UoD is slightly ambiguous, and an aspect of it can be mapped two different ways which both meet the specification of the UoD but lead to different limitations/constraints being enforced by the database. Here the choice has consequences, and the right move is to pick one and note the assumption under the diagram.
That second case is the reason a diagram is rarely a complete answer on its own. The medical-clinic model in week3-tutorial-applied-class-2-entity-relationship-diagrams carries the explicit assumptions “every patient in the DB has made an appointment” and “every clinic has at least one doctor” — neither is stated in the brief, both change the participation constraints, so both get written down rather than smuggled into the drawing.
The four common choice points
| Choice | The question | Worked example |
|---|---|---|
| Attribute vs (weak) entity type | Is this a fact about something, or a thing in its own right? | An interview’s Details (Department, Date) as a key attribute of the APPLIES relationship, vs. a separate weak INTERVIEW entity |
| Attribute vs subclass | Is this a value, or a kind? | EMPLOYEE.Type as a plain attribute, vs. splitting into SECRETARY / ENGINEER subclasses |
| Subclass relationship vs superclass relationship | Does this relationship apply to everyone, or only to one kind? | Giving WORKSON (to PROJECT) to the EMPLOYEE superclass, vs. only to ENGINEER |
| Binary relationships vs n-ary relationships | Does the association hold between pairs, or genuinely among all three at once? | SUPPLIER / PROJECT / PART as three binaries (SUPPLIES, CANSUPPLY, USES) vs. one ternary SUPPLIES carrying a quantity |
Each row is a real fork, not a stylistic one:
- Attribute vs entity type. Pulling something out into its own entity type gives it identity — it can then be referred to, counted, and given relationships of its own. The cinema model in the same applied class makes exactly this call about a
VIEWING: it can be read as a weak entity owned byCUSTOMER+MOVIEwithTimestampas its partial key, or as an M:N relationship carryingTimestampas a key attribute. Both fit the brief; they differ in whether a viewing is a thing or a link. (interpreting-er-diagrams shows the reading side of the same call: without a distinguishing attribute, a plain M:N pair can only be recorded once.) - Attribute vs subclass. A subclass earns its place when the subtypes have different attributes or relationships —
SECRETARYrecording aTypingSpeedthat means nothing for an engineer. If the only difference is the label itself, a plain attribute says the same thing with less diagram. Applied class 2 gives the efficiency half of the argument explicitly: subclasses let a data attribute be stored for some entity instances rather than all of them, and so reduce the number of null/empty values — not everySHOWneeds aRating, onlyENTERTAINMENTshows do. See specialisation-and-generalisation. - Binary vs n-ary. Three binary relationships and one ternary relationship are not interchangeable: the binaries record that a supplier can supply a part and that a project uses a part, while the ternary records the specific fact that this supplier supplied this part to this project. Splitting a genuinely three-way fact into pairs loses information; forcing a ternary where only pairwise facts exist invents it. See relationship-types.
- Subclass vs superclass relationship. Attaching a relationship higher up the hierarchy widens what the schema will accept. That looks harmless on a diagram and is not harmless afterwards — see below.
Worked example: attribute vs weak entity type
A candidate applies to a company, and each application involves an interview with a department on a date. Both diagrams below satisfy that description. The world does not choose between them.
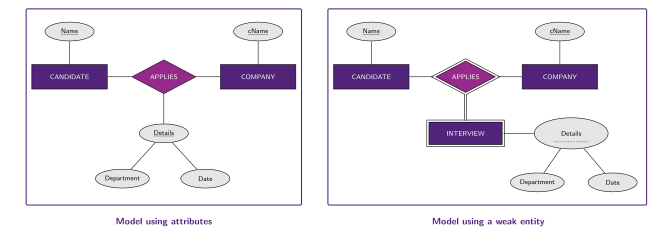
Figure 6: Attribute vs. (weak) entity type: two models of the same description. Left: the interview details hang off the APPLIES relationship as a composite key attribute Details (solid underline) made of Department and Date. Right: the interview becomes a thing — a weak entity owned by both CANDIDATE and COMPANY, so APPLIES becomes an identifying relationship (double diamond, double line into the weak entity) and Details demotes from key attribute to composite partial key (dotted underline). Nothing else on the diagram moves.
The two are alternatives, and the choice between them looks cosmetic. It stops looking cosmetic the moment the UoD says an interview results in a job offer: an attribute cannot be the endpoint of a relationship, so only the weak entity can carry a RESULTSIN link to a JOBOFFER entity. That extended diagram is drawn in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Worked example: binary vs n-ary relationships
Suppliers, projects and parts. Modelled as three binary relationships — a supplier supplies a project, a supplier can supply a part, a project uses a part:
Modelled as one ternary relationship, with all three lines running into a single diamond that can then carry a quantity:
flowchart TD
    SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
    SUPPLIES ---|"P"| PROJECT[PROJECT]
    SUPPLIES ---|"N"| PART[PART]
    SUPPLIES --- quantity(["quantity"])
    sName(["sName (key)"]) --- SUPPLIER
    projName(["projName (key)"]) --- PROJECT
    partNo(["partNo (key)"]) --- PART
The quantity is the tell. It is a fact about a supplier-project-part triple, so there is nowhere to put it in the binary model — hanging it on SUPPLIES there would record how much a supplier sent a project without saying of what. This is the inequivalent case: the two diagrams do not produce the same database.
Worked example: subclass vs superclass relationship
EMPLOYEE specialises disjointly into SECRETARY and ENGINEER, and somebody works on projects. Which box does WORKSON attach to?
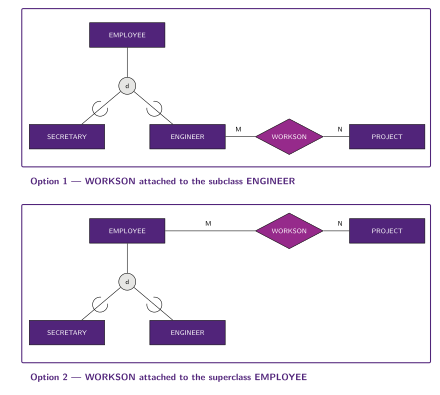
Figure 7: Subclass relationship vs. superclass relationship, reduced to the fragment where the two options differ. Option 1 attaches WORKSON to the subclass ENGINEER; Option 2 attaches it to the superclass EMPLOYEE. The rest of the company diagram (MANAGES, WORKSFOR, CONTROLS and DEPARTMENT) is the same under both options and is left out so the one difference is visible.
This is the clearest inequivalent choice of the four. Option 1 says only engineers work on projects — secretaries cannot be recorded on one at all. Option 2 says anyone may. Both satisfy a brief that only ever mentions engineers working on projects, but they enforce different things: Option 2 will happily accept a secretary on a project, and Option 1 will refuse an engineer’s promotion out of the subclass without also dropping their project assignments. Attaching a relationship higher up the hierarchy always widens what the schema will accept.
Why the choice matters after the diagram
A conceptual choice becomes a constraint the DBMS can or cannot enforce once the diagram is mapped. The clearest example is the third mistake in week4-tutorial-case-study-3-dirt-road-driving: mapping a trip’s driver as a reference to Staff rather than to Driver lets an admin-only staff member be recorded as a trip’s driver, because the schema no longer knows that a driver is a driver. The diagram-level decision about which class a relationship attaches to is the same decision as the schema-level decision about which relation the foreign key points at.
This is also why an assumption noted under a diagram is worth marks and worth memory: it’s the record of a constraint that the notation alone couldn’t distinguish. Once the schema exists, refining it further is a different exercise with different tools — see functional-dependencies and normal-forms for redundancy-driven refinement, and conceptual-database-design for where in the pipeline each one sits.
ER Diagram Notation
Reference legend for the symbols used across every ER/EER diagram in this course — introduced across 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices.
The notation below is the mandatory standard: it is what the lectures’ own notation guide specifies, and it is what assignments and the exam are marked against. (The separately published INFS1200/7900 EER & ER Notation Guide handout only standardises naming — see the style guide at the bottom of this note — and explicitly defers the symbols themselves to the lecture material.)
Core symbols
| Symbol | Meaning |
|---|---|
| Rectangle | Entity type |
| Double-line rectangle | Weak entity type (no key attribute of its own) |
| Oval | Attribute |
| Oval, name underlined | Key attribute |
| Oval, name underlined with a dotted line | Partial key attribute (weak entity’s own distinguishing attribute) |
| Double-line oval | Multivalued attribute (can hold more than one value) |
| Dashed oval, attached by a dashed line | Derived attribute (computed from another stored attribute, e.g. Age from BirthDate) |
| Diamond | Relationship type |
| Double-line diamond | Identifying relationship type (connects a weak entity to its owner entity) |
- Composite attribute: an attribute with its own sub-attributes attached (e.g.
Namesplitting intoFirstName/MiddleName/LastName) — the parent attribute oval isn’t underlined/dashed/doubled itself unless it’s also a key/derived/multivalued attribute. - Value sets (the domain of legal values for an attribute, e.g. “integers 21-65”) are never shown on the diagram itself.
Relationship constraints
| Symbol | Meaning |
|---|---|
1, N, M on the lines into a diamond |
Cardinality ratio — E1 —1— R —N— E2 reads as ratio 1:N for E1:E2 in R |
| Double line between an entity type and a diamond | Total participation of that entity type in that relationship |
| Single line | Partial participation |
See relationship-constraints for what each ratio and each participation constraint actually asserts.
Subclasses / superclasses (EER)
A subclass is drawn as an ordinary rectangle. What makes it a subclass is the ⊂ symbol on the line joining it to its superclass, not the shape of its box — a subclass box is a plain single-line rectangle, never the double-line rectangle that means weak entity. The two are entirely different ideas (a subclass inherits its superclass’s key; a weak entity has no key of its own at all) and the notation keeps them apart.
| Symbol | Meaning |
|---|---|
⊂ on the line between two entity types |
The entity type on the closed (narrow) side of the ⊂ is a subclass of the one on the open (wide) side — read it as the set-inclusion symbol, subclass ⊂ superclass |
A circle joining several subclass lines to one superclass, each line carrying its own ⊂ opening towards the circle |
Several entity types are all subclasses of the same superclass |
d inside that circle |
Disjoint specialisation — an entity instance can belong to at most one of the subclasses |
o inside that circle |
Overlapping specialisation — an entity instance can belong to more than one subclass at once |
| Single line from superclass to the subclass circle | Partial specialisation — not every superclass instance needs to belong to a subclass |
| Double line from superclass to the subclass circle | Total specialisation — every superclass instance must belong to at least one subclass |
Naming conventions (INFS1200/7900 style guide)
Course-specific naming standard for entities/relationships/attributes on ER and EER diagrams (distinct from — and in addition to — the mandatory notation above):
- Entity names: capitalised, no spaces, ideally one word (e.g.
STUDENT,POLICEOFFICER— notPoliceOfficer). - Relationship names: capitalised, no spaces, ideally one word, preferably a verb (e.g.
CREATES,ACTSIN— notLeadActor). - Attribute names: UpperCamelCase — first letter of each word capitalised, no spaces, acronym letters stay capitalised (e.g.
ComputerIP,DateOfBirth— notDate of Birth).
How diagrams are drawn in these notes
Diagrams in this course’s notes are drawn as Mermaid flowchart graphs (renders in both PDF and HTML), using shapes chosen to match the Chen notation above as closely as Mermaid’s flowchart shapes allow:
| Mermaid shape | Used for |
|---|---|
[Entity] (rectangle) |
Entity type — and subclasses, which are ordinary rectangles |
[[WeakEntity]] (subroutine, double vertical bars) |
Weak entity type, and nothing else |
{Relationship} (diamond/rhombus) |
Relationship type |
([Attribute]) (stadium) |
Attribute |
((d)) / ((o)) (small circle) |
Disjoint/overlapping specialisation marker |
The [[X]] shape is reserved for weak entity types. Drawing an EER subclass with it is a notation error, not a stylistic one: it renders the double-line box that the official notation uses for a weak entity, and so asserts the opposite of what a subclass is. Subclasses are plain [X] rectangles; their subclass-ness is carried by the edge into the ((d)) or ((o)) circle, exactly as the ⊂ carries it in the hand-drawn notation.
Since Mermaid can’t reliably underline/dash node text across renderers, attribute qualifiers are written as a plain-text suffix instead: (key), (partial key), (derived), (multi). Composite attributes are drawn as a parent attribute node connected to its component attribute nodes. Cardinality is a text label on the edge ("1", "N", "M"); total participation/identifying relationships use a thick edge (===/==>), partial participation uses a thin edge (---/-->).
Any diagram with more than ~6-8 nodes needs an explicit %%| fig-width: cell option (in inches) or it runs off the right edge of the PDF page - mermaid sizes itself from the diagram’s own SVG bounding box, and there’s no project-wide default that reaches it (a document/project fig-width only applies to executed-code-cell figures, e.g. matplotlib). 5.5 fits this vault’s PDF page width (scrartcl, DIV=11, letter) comfortably:
```{mermaid}
%%| fig-width: 5.5
flowchart TD
    ...
```
ER Mapping Pitfalls
A checklist for reviewing a finished relational schema — every item here is a mistake actually made and corrected in week5-tutorial-applied-class-4-entity-relationship-mapping, week4-tutorial-case-study-3-dirt-road-driving or the worked questions in 2026-03-16-er-to-relational-mapping. The mapping rules themselves are in er-to-relational-mapping; this is what to check after applying them.
Keys
Most of this section is one question asked five ways: what exactly is this relation’s primary key? (relational-keys).
A weak entity’s partial key is not a foreign key. For a weak CITY owned by PROVINCE, the correct mapping is Cities [cName, pName, mayor] with only Cities.pName references Provinces.pName. cName is the city’s own partial key — it references nothing. Declaring both columns as foreign keys is wrong.
A weak entity’s key includes its owner’s key. Mapping Cities [cName, mayor], keyed on cName alone, silently asserts that city names are globally unique — which is precisely the assumption that made CITY weak in the first place.
An ordinary 1:N foreign key is not part of the primary key. For A —N R 1→ B, the answer is A [a, b, d] keyed on a alone, with A.b references B.b as a plain column. Promoting b into A’s key is weak-entity treatment applied to a strong entity. (The genuine exception is an entity with no key of its own, identified through its owners — see foreign-keys.)
A composite foreign key is one constraint, not several. The cinema schema must say
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}and not four separate single-column constraints. Splitting it breaks the link to the specific Viewing row: nothing then forces all four columns to match one real viewing rather than four unrelated ones. In the same botched attempt, name was pointed back at Movie rather than Viewing — a foreign key meant to identify which viewing a snack belongs to must target Viewing.
When the owner’s key is composite, the inherited foreign key is composite. Branch’s key is (bankCode, branchNo), so accounts and loans at a branch carry both columns: Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}.
Relations that shouldn’t exist
An identifying relationship never becomes a relation. A weak entity is connected to its owner purely through the inherited key. Inventing an In [cName, pName] relation alongside the weak entity’s own is a distinctive wrong answer.
1:1 and 1:N relationships don’t get their own relation by default. They are foreign keys on an existing relation. Creating an S [b, c] relation for a 1:N relationship S treats a relationship type as an entity type. (Doing this deliberately for a sparse relationship, to avoid nulls, is a different matter — a considered choice, not the default rule.)
Two entity types don’t merge into one relation. Collapsing S and T into ST [a1, b1] because they happen to be in a 1:1 relationship discards a conceptual modelling decision that was made on purpose.
Nor does a relationship simply vanish. Mapping S —1:1 R— T to S [a1], T [b1] with no foreign key anywhere loses all information about R.
Choosing sides
For 1:1, put the foreign key on the total-participation side. If every department has a manager but only some employees manage, extend Department. Choosing the other side doesn’t lose information, but it fills the column with nulls, and the course’s rule is to prefer the total-participation side. Between a schema putting b1 into S and one putting a1 into T, the first is correct for exactly one reason: S is preferred over T because it has full participation.
For 1:N, the foreign key goes on the N side — no judgement involved. In a chain A —N R 1→ B —N S 1→ C, that means A references B and B references C; each arrow is decided independently by where the N is.
For N-ary, only the many-sides make the key. All participants get foreign keys, but a 1-side participant’s foreign key is a plain attribute — and if the relationship carries a key attribute of its own, that attribute joins the key alongside the many-side foreign keys.
A ternary relationship with no many side gets no relation. 1:1:1 and N:1:1 are explicitly excluded from step 7: creating an R relation for one of them is a wrong answer, because the relationship is absorbed into a participating relation as two foreign keys — into the N side if there is one, otherwise into whichever side is chosen. See step 7 of er-to-relational-mapping.
Attributes
Derived attributes are never columns. NumberOfEmployees is computed from the data, so storing it just creates something that can disagree with the data.
Composite attributes contribute their leaves, not themselves. Name becomes fName, mIt, lName — there is no name column.
Multivalued attributes always become their own relation, keyed on the owner’s key plus the value. A column can only hold one atomic value (see relational-model).
EER
Relationships drawn to a subclass reference the subclass relation. If only a Specialist can run a SpecialistClinic, then Runs.licenceNo references Specialist.licenceNo — not Doctor. Pointing at the superclass silently widens the rule to every doctor and every clinic, losing the constraint the specialisation was drawn to express (specialisation-and-generalisation) — and the same widening is what er-design-choices calls the subclass-vs-superclass relationship fork.
A subclass with no attributes of its own still gets a relation. SpecialistClinic [regNo] with a foreign key back to Clinic records membership, which is information even when there are no extra columns.
Map subclasses before the relationships that use them. The +1 step runs right after step 1 or 2 for a reason — a later step that needs to reference Specialist can’t if Specialist doesn’t exist yet.
Style
Schemas are marked against the course style guide as well as the mapping rules: UpperCamelCase table names, lowerCamelCase attribute names, each relation’s references lines directly beneath it, and a single continuous underline for a composite primary key. See relational-mapping-notation.
ER to Relational Mapping
The (7+1)-step algorithm that converts a conceptual ER/EER diagram into a logical relational schema — input: an ER model; output: relations with primary and foreign key constraints. Introduced in 2026-03-16-er-to-relational-mapping and practised in week5-tutorial-applied-class-4-entity-relationship-mapping and week4-tutorial-case-study-3-dirt-road-driving. See relational-mapping-notation for the notation and naming style used throughout, er-diagram-notation for the diagram being mapped from, and er-mapping-pitfalls for the mistakes to check for afterwards.
Why map at all
The ER model is used for conceptual design — the user’s perspective, good for talking to stakeholders about entities and relationships. The relational model is what commercial DBMSs actually implement — the storage perspective. Mapping is the bridge: every construct that the ER model can draw has to be re-expressed using only relations, primary keys and foreign-keys, because those are the only tools the relational model has (see relational-model).
The steps at a glance
| # | Construct | Produces |
|---|---|---|
| 1 | Strong entity type | A new relation |
| 2 | Weak entity type | A new relation, keyed on owner’s key + partial key |
| 3 | Binary 1:1 relationship | A foreign key on one side |
| 4 | Binary 1:N relationship | A foreign key on the N side |
| 5 | Binary M:N relationship | A new relation |
| 6 | Multivalued attribute | A new relation |
| 7 | N-ary relationship | A new relation — except 1:1:1 and N:1:1, which take foreign keys instead |
| +1 | Subclass (EER) | A new relation per subclass |
Only steps 1, 2, 5, 6, 7 and +1 create relations; steps 3 and 4 only add foreign keys to relations that already exist, and step 7 does the same in its two excluded cases. Working in order matters, because every later step needs the primary keys that earlier steps established.
The running example below is the Company database: EMPLOYEE (key Ssn, composite Name → Fname/Mit/Lname, Sex, Salary, Address, DOB), DEPARTMENT (keys Dnumber/Dname, derived NumberOfEmployees, multivalued Locations), PROJECT (keys Pno/Pname, Plocation), and the weak entity DEPENDENT (partial key DepName), with relationships WORKSFOR (EMPLOYEE N:1 DEPARTMENT), MANAGES (EMPLOYEE 1:1 DEPARTMENT, attribute StartDate), CONTROLS (DEPARTMENT 1:N PROJECT), WORKSON (EMPLOYEE M:N PROJECT, attribute Hours), SUPERVISION (EMPLOYEE recursive 1:N), DEPENDENTSOF (identifying), and EMPLOYEE disjointly specialising into SECRETARY/ENGINEER.
Step 1 — Strong entity types
For each strong (non-weak) entity type: create a relation, choose one of its keys as the primary key, and include all simple attributes.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary]

Department [dNumber, dName]

Project [pNo, pName, pLocation]
Three attribute kinds are deliberately not copied across as columns:
- Composite attributes contribute their simple components instead —
Namenever appears,fName/mIt/lNamedo. - Derived attributes are never stored at all —
NumberOfEmployeesis computed on demand, so storing it would only create an opportunity for it to go stale. - Multivalued attributes can’t be stored in an atomic column and are deferred to step 6 —
Locationsis missing fromDepartmentfor now.
Where an entity has several keys (DEPARTMENT has both Dnumber and Dname), one becomes the primary key and the others are simply ordinary attributes in the relational schema — see relational-keys.
Step 2 — Weak entity types
For each weak entity type: create a relation whose primary key is the owner’s primary key plus the weak entity’s partial key; add a foreign key from the inherited part back to the owner; include all simple attributes.
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssnDependent’s full key is (ssn, depName): ssn is Employee’s key inherited through the identifying relationship, depName is the partial key (see relationship-constraints). Note what does not happen — the identifying relationship DEPENDENTSOF gets no relation of its own; it is entirely represented by the inherited key.
If a weak entity has more than one owner, the rule generalises rather than changes: include as foreign keys the primary key attributes of every owner entity type, and make the primary key the combination of all of them plus the partial key. For a weak W (partial key a1) owned by both E1 (key b1) and E2 (key c1):
E1 [b1]

E2 [c1]

W [a1, b1, c1]
W.b1 references E1.b1
W.c1 references E2.c1
All three columns are underlined as one key; both inherited keys are foreign keys in their own right.
When the owner’s own key is composite, the foreign key is composite too. In the Bank example, BRANCH is a weak entity owned by BANK (branchNo is only unique within a bank):
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code
Step 3 — Binary 1:1 relationships
For each binary 1:1 relationship: pick one participating entity type, add a foreign key there referencing the other’s primary key, and put the relationship’s own simple attributes on that same chosen side.
Preference is given to entity types with total participation (relationship-constraints) — it is part of the rule, not a stylistic tip. In the generic case, with T the totally-participating side (double line) and c1 the relationship’s own attribute:
S [a1, a2]

T [b1, b2, a1, c1]
T.a1 references S.a1
If every department must have a manager but not every employee manages, then putting the foreign key on Department gives a value in every row, whereas putting it on Employee would leave it null for almost everyone (sql-nulls). MANAGES is drawn with the double line on the DEPARTMENT side, so DEPARTMENT is the chosen side:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn
mgrStartDate is MANAGES’s own attribute, and travels with the foreign key. The foreign key is a plain attribute here, not part of Department’s key.
Both landed columns are renamed on arrival — Employee.ssn becomes mgrSSN, StartDate becomes mgrStartDate — and the same happens in step 4 (Dnumber → dNumber in Employee, Ssn → superSSN for SUPERVISION). Renaming an inherited attribute to say what role it plays in its new relation is expected, and is the standard fix when the imported name would collide with one already there.
Step 4 — Binary 1:N relationships
For each binary 1:N relationship that isn’t an identifying relationship: find the entity type on the N side, add a foreign key there referencing the primary key of the entity type on the 1 side, and put the relationship’s own simple attributes on the N side too.
The direction is forced, not chosen: one row on the N side relates to exactly one row on the 1 side, so a single foreign key column can hold it. The other direction would need many values in one cell.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber
SUPERVISION is recursive, and is handled exactly like any other 1:N relationship — the N-side role (supervisee) carries a foreign key back to the 1-side role (supervisor) in the same relation.
Step 5 — Binary M:N relationships
For each binary M:N relationship: create a new relation; give it foreign keys to both participants’ primary keys; the combination of those foreign keys is its primary key; add the relationship’s own simple attributes.
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo
A new relation is unavoidable here: neither side can hold a single foreign key value, since both sides relate to many rows of the other.
One wrinkle the Company example doesn’t show: the relationship may bring a key attribute of its own, and if it does, that attribute joins the primary key rather than sitting outside it. For an M:N R between S and T carrying an underlined c1 and a plain c2:
S [a1, a2]

T [b1, b2]

R [a1, b1, c1, c2]
R.a1 references S.a1
R.b1 references T.b1R’s key is (a1, b1, c1) — the pair of foreign keys plus c1. This is how a relationship that can repeat between the same two entities (the same employee working on the same project in several different years, say) gets modelled without a duplicate-key clash.
1:1 and 1:N relationships may also be mapped this way, and it is worth doing when the relationship is sparse — a separate relation stores only the rows that actually participate, instead of leaving a null foreign key in every row that doesn’t. In the standard implementation the foreign key column is mostly nulls, while the M:N implementation holds one short relation of just the participating pairs, and no nulls at all.
Step 6 — Multivalued attributes
For each multivalued attribute: create a new relation containing a foreign key to the owning entity’s primary key plus the attribute itself; the primary key is the combination of the two. If the multivalued attribute is composite, include its simple components instead of the attribute itself.
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Keying on both columns is what allows one department to have many locations while forbidding the same location twice. If the owning relation’s key is itself composite, the foreign key here is composite — in the cinema example the snack relation carries all four columns of Viewing’s key:
ViewingSnack [name, id, date, time, snack]
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}
Step 7 — N-ary relationships
For each N-ary relationship type — excluding the 1:1:1 and N:1:1 cases, which are handled separately below: create a new relation; give it foreign keys to the primary key of every participating entity type; the foreign keys from the participants with many cardinality form the primary key; the relationship’s own attributes may also contribute to that key; add its remaining simple attributes.
One relation body covers every non-excluded case, and only the underline moves. For a ternary R over E1, E2 and E3, with own attributes d1 and d2:
E1 [a1]

E2 [b1]

E3 [c1]

R [a1, b1, c1, d1, d2]
R.a1 references E1.a1
R.b1 references E2.b1
R.c1 references E3.c1| Cardinalities | Primary key of R |
|---|---|
N:M:P — every participant many |
All three foreign keys, (a1, b1, c1) |
N:M:1 |
The two many-side foreign keys (a1, b1); c1 is a plain attribute |
N:M:1 with d1 an underlined attribute of R |
(a1, b1, d1) — the relationship’s own key attribute joins them |
Every participant is always represented, whatever its cardinality: a 1-side foreign key is present but outside the key. For a ternary K over H (role N), A (role M) and P (role 1), with own attribute l, that gives
K [b, i, q, l]
K.b references A.b
K.i references H.i
K.q references P.q
with only b and i underlined. The Company database contains no N-ary relationship — WORKSON is binary.
The excluded cases — 1:1:1 and N:1:1
These get no new relation at all. With at most one participant on a many side, there is no combination of foreign keys that would make a key, and the relationship can be absorbed exactly as in steps 3 and 4: one participating relation takes a foreign key to each of the others, plus the relationship’s own attributes.
- N:1:1 — the entity type on the
Nside is the one that takes them, and the choice is forced, since only its rows relate to exactly one row of each other participant:
E1 [a1, b1, c1, d1]
E1.b1 references E2.b1
E1.c1 references E3.c1

E2 [b1]

E3 [c1]- 1:1:1 — nothing forces the direction, so choose a participant the same way step 3 does, preferring total participation, and put both foreign keys and the relationship’s attributes there. The schema looks identical to the N:1:1 one above; only the reason for picking
E1differs.
The giveaway that a question is testing this exclusion is a ternary diamond with at most one N on its edges: count the many sides before reaching for a new relation, because with fewer than two of them there is nothing to key it on.
Step +1 — Subclasses (EER)
For each subclass (specialisation-and-generalisation): create a relation whose primary key is the superclass’s primary key; add a foreign key from it back to the superclass relation; include the subclass’s own simple attributes. The same rule works for every combination of total/partial and disjoint/overlapping specialisation.
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn
A subclass with no attributes of its own still gets a relation — it is the row’s membership in that subclass that is being recorded.
This step has no fixed position in the sequence. It is done straight after step 1 or 2 (whichever created the superclass), specifically so the subclass relations exist by the time a later relationship step needs to reference one — and relationships drawn to a subclass must reference the subclass relation, not the superclass.
Final schema — Company database
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber

Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn

Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn

WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo

DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Eight relations: the three strong entity types became three, the weak entity one, the two subclasses two, the M:N relationship one, and the multivalued attribute one — while all four of the 1:1 and 1:N relationships (MANAGES, WORKSFOR, CONTROLS, SUPERVISION) became nothing more than foreign key columns on relations that already existed.
Second worked example — Bank database
The other complete run-through is the bank: a BANK (unique Code, Name, HOAddr) has several branches; a BANK-BRANCH has a BranchNo unique only within its bank, so it is weak. One branch has many ACCOUNTs (ACNo, Type, Balance) and many LOANs (LoanNo, Type, Amount), and every account and loan has one or more holders drawn from CUSTOMER (SSN, Name, Addr) — two M:N relationships, AHOLDER and LHOLDER.
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code

Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Customer [ssn, name, address]

AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Two things are worth reading off this schema. First, a weak entity’s composite key propagates: because Branch is keyed on (bankCode, branchNo), every 1:N foreign key drawn from Branch is composite too. Second, it propagates as a plain column — Account has its own key acNo, so bankCode and branchNo sit outside Account’s primary key, exactly as step 4 requires. AccountHolder and LoanHolder, by contrast, have no key of their own and are keyed on their pair of foreign keys.
The result is a logical schema, ready to be implemented with sql-ddl and checked for redundancy with normal-forms. Whether each inherited foreign key is part of its relation’s primary key — the question that decides most of the answers above — is tabulated in foreign-keys.
Foreign Keys
A foreign key is a set of attributes in one relation that links it to another relation’s primary key — the only mechanism the relational model has for expressing a relationship between two relations, and therefore the thing almost every mapping step in er-to-relational-mapping produces. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints; see relational-keys for keys within a relation and relational-mapping-notation for the references notation used throughout.
Definition
Let FK be a set of attributes in relation R1, and PK the primary key of relation R2. FK is a foreign key referencing PK if:
FKandPKare drawn from the same domain(s) — the names need not match, only the domains (see relational-model on why attribute names and domains are independent), and- for every tuple \(t_1\) in
R1, either \(t_1[\mathit{FK}]\) isNULL, or there exists a tuple \(t_2\) inR2with \(t_1[\mathit{FK}] = t_2[\mathit{PK}]\).
Condition 2 is the referential integrity constraint. Note what it permits: a foreign key value may be NULL (the row simply doesn’t participate), but it may never be a value that points nowhere. A dangling reference is the violation; an absent reference is not.
Department [id, name, manager]
Department.manager references Employee.id

Employee [id, name, sex, salary, department]
Employee.department references Department.id
Foreign keys can point in both directions between the same pair of relations, as here — Department.manager says who runs the department, Employee.department says who works in it. They are two separate constraints expressing two separate relationships.
An instance makes the permission concrete: Department 4 (Human Resources) has a NULL manager and employee 2034 a NULL department, and both rows are legal. An employee whose department read 5, with no department 5 in the referenced relation, would not be.
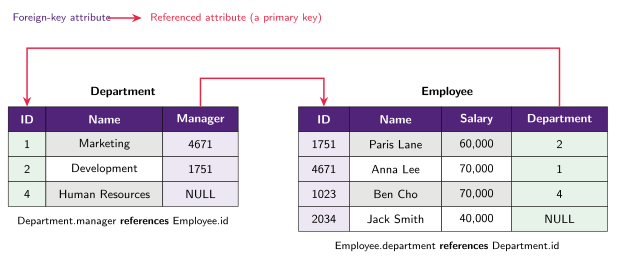
Figure 8: A two-way foreign key between Department and Employee. Each arrow starts at the foreign-key column and its head lands on the referenced primary key — the direction never varies in this course. The tinted columns pair each foreign key with the primary key it points at; the two NULLs are legal, because a foreign key may be absent but may never point nowhere.
Shapes a foreign key can take
Self-referencing
A relation can reference itself, because the two attributes involved share a domain even though they play different roles. Adding a managerId column to the same Employee relation gives one:
Employee [id, name, salary, department, managerId]
Employee.managerId references Employee.id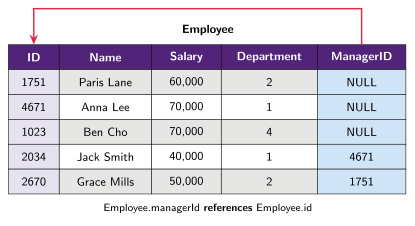
Figure 9: A self-referencing foreign key: the arrow leaves ManagerID and returns to ID in the same relation. The three top-level employees carry NULL, which is what stops the reference chain rather than a special case in the constraint.
The company schema does the same thing with different names:
Employee [ssn, fName, lName, dob, superSSN]
Employee.superSSN references Employee.ssn
This is what a recursive relationship (relationship-types — SUPERVISION: an employee supervises many employees) maps to: the N-side role, the supervisee, carries the foreign key back to the 1-side role, the supervisor. It is also what a sql-joins self-join follows back.
Composite
If the referenced primary key is composite, the foreign key must be composite too, and the whole thing is one constraint over a tuple of columns:
Student [sid, name]

Course [cid, department, manager]

Enrollment [sid, cid, department, grade]
Enrollment.sid references Student.sid
Enrollment.{cid, department} references Course.{cid, department}Course’s key is the pair (cid, department), so Enrollment must carry both columns to name one course, and its own key is all three of (sid, cid, department).
Splitting a composite foreign key into several single-column constraints is a real and commonly-marked mistake — see er-mapping-pitfalls — because it no longer forces all the columns to jointly match one referenced row.
Two foreign keys to the same relation
When a relationship uses the same entity type in two different roles, the referencing relation gets two separate foreign keys to it, given distinct column names so the roles stay readable:
PeerEvaluation [studentSid, assessmentSid, number, evaluationId, sidGrades, mark]
PeerEvaluation.studentSid references Student.sid
PeerEvaluation.sidGrades references Student.sid
PeerEvaluation.{assessmentSid, number} references Assessment.{sid, number}
studentSid is the evaluator submitting the mark; sidGrades is the student whose assessment is being marked.
Is the foreign key part of the primary key?
This is the question that decides most mapping answers, and the rule is structural rather than a matter of taste:
| Situation | Foreign key is… |
|---|---|
| 1:N relationship, FK on the N side (an entity with its own key) | A plain, non-key attribute |
| 1:1 relationship, FK on the chosen side | A plain, non-key attribute |
| Weak entity, FK to its owner | Part of the weak entity’s composite primary key |
| M:N relationship’s own relation | Part of the primary key (the pair of FKs is the key) |
| N-ary relationship’s relation, FK from a many-side participant | Part of the primary key |
| N-ary relationship’s relation, FK from a 1-side participant | A plain, non-key attribute |
| Multivalued attribute’s relation | Part of the primary key (with the value itself) |
| Subclass relation | Is the primary key — the subclass’s key is the superclass’s key |
So in Employee [ssn, …, dNumber, superSSN] the department and supervisor foreign keys are ordinary columns, whereas in Dependent [ssn, depName, …] the inherited ssn is underlined as part of the key. Treating an ordinary 1:N foreign key as key material is a standard wrong answer.
The dividing line is whether the referencing entity has a key of its own. An entity that doesn’t — the cinema Viewing, identified only by which movie, which customer and when — is being identified through its owners, so the inherited foreign keys do join its key: Viewing [name, id, date, time, attendant], keyed on all four of (name, id, date, time). That reads as weak-entity behaviour with two owners rather than as an exception to the rule, and the shape is straight out of the mapping rules: a weak entity with more than one owner takes a foreign key to each owner and is keyed on every owner key plus its partial key (step 2 of er-to-relational-mapping). Reading Viewing as a weak entity with two owners or as a strong entity whose key happens to be composite produces the same relation, so the mapping answer is the same either way.
Nulls, and when to avoid them
Because a foreign key may be NULL, embedding a 1:1 or 1:N relationship directly into an existing relation produces a null in every row that doesn’t participate. When a relationship is sparse — few of the rows actually take part — mapping it as its own relation instead (the M:N treatment) avoids all those nulls at the cost of an extra join. That trade-off is noted under step 5 of er-to-relational-mapping; see sql-nulls for what nulls then do to queries.
Enforcement
Referential integrity is declarative — the DBMS rejects any insert, update, or delete that would leave a dangling reference, with no application code involved (see integrity-constraints).
Three operations from week4-tutorial-applied-class-3-relational-integrity show the full range, and they are worth reading together because two of them look dangerous and are not:
| Operation on the company schema | Verdict |
|---|---|
Delete the EMPLOYEE tuple with ssn = 987654321 |
Violates referential integrity — tuples in WORKS_ON, DEPENDENT, DEPARTMENT and EMPLOYEE itself all reference it |
Modify EMPLOYEE.superSSN of 999887777 to 943775543 |
Violates referential integrity — no employee has that ssn; an update to a foreign key is checked exactly like an insert |
Delete the WORKS_ON tuples with essn = 333445555 |
No violation — nothing references WORKS_ON, so removing rows from it cannot dangle anything |
The last row is the shape people get wrong: whether a delete is safe depends on what points at the relation, not on how many foreign keys the relation itself carries. WORKS_ON is all foreign key and is still free to delete from. The EMPLOYEE delete is dangerous precisely because four relations, one of them EMPLOYEE itself through superSSN, point back at it.
What happens to dependent rows when a referenced row is deleted or its key updated is a policy choice attached to the foreign key itself: the violation can be rejected, cascaded, or the referencing attribute values modified to a default value. See update-operations-and-constraint-violations for those conceptual options and sql-ddl for the four named ON DELETE / ON UPDATE actions that spell them out in SQL.
Integrity Constraints
Integrity constraints are the rules that enforce the correctness of a database: conditions stated on the schema that must hold on every instance of it. A DBMS’s job is to reject any operation that would leave them unsatisfied. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and practised in week4-tutorial-applied-class-3-relational-integrity; these are constraints on a relational schema, distinct from the relationship-constraints placed on an ER diagram.
The five kinds
| Constraint | Violated when | Enforced by |
|---|---|---|
| Domain | An attribute’s value isn’t a member of its domain | The column’s declared type/format |
| Key | Two tuples share the same value for a key | The declared key |
| Entity integrity | Any part of a tuple’s primary key is NULL |
The declared primary key |
| Referential integrity | A non-null foreign key value matches no primary key value in the referenced relation | The declared foreign key |
| Semantic | A business rule that isn’t derivable from the schema’s structure is broken | Application-level rules — triggers, assertions, CHECK |
The first four are structural: they follow from the schema itself, so the DBMS enforces them for free once the types and keys are declared. The fifth is not — nothing in the schema’s shape implies it, so it has to be stated separately.
Enforcement is unconditional and the default outcome is refusal: any insert, modification or deletion submitted to the DBMS that would violate integrity — that would leave the database in an inconsistent state — must be rejected. The only constraint whose violation has other sanctioned outcomes is referential integrity on a delete, and only because the foreign key was declared with a policy saying so (see update-operations-and-constraint-violations).
Which operation can break which constraint is not symmetric, and the asymmetry is examinable:
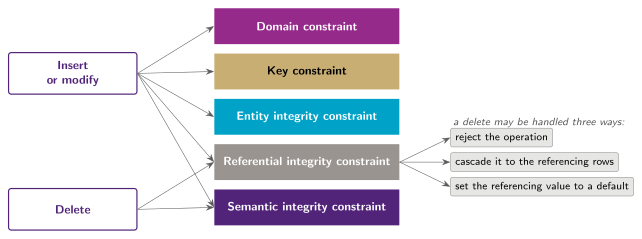
Figure 10: Insert and modify can violate all five constraints; delete can only violate the last two, and a referential violation on delete has three sanctioned outcomes rather than one. The banner colours are the course’s fixed fills for the five constraint types.
A delete cannot break a domain, key or entity-integrity constraint because it adds no value and duplicates no key — it can only strand something that was pointing at the row it removed, or break a business rule about what must continue to exist.
Domain constraint
The domain is the set of legal atomic values for an attribute (see relational-model), so a domain violation is simply a value that isn’t in that set. Employee.id = "LOL" violates it when id is a four-digit integer.
The domain need not be a plain data type — a format counts. A bank rejecting the password password123 with “your password must contain at least one capital letter and a number” is enforcing a domain constraint: the domain of password is defined as the strings matching that format, and password123 isn’t a member of it. Likewise a course code declared as four letters followed by four digits, or an enumerated domain: inserting VehiclePurpose = 'Personal' when the column is ENUM('Private', 'Business') is a domain violation, not a semantic one.
The commonest exam version of a domain violation is subtler — a value of the wrong kind in the right position. Inserting (2644, James, Smith, 1) into Employee [id, name, salary, department] breaks the domain constraint because the third value lands in salary, whose domain is integer or float, not a surname.
Key constraint
No two tuples may share a value for a key. Violated by inserting a tuple whose key duplicates an existing one, or by modifying an existing tuple into a duplicate. See relational-keys for what qualifies as a key in the first place.
Entity integrity constraint
No part of a primary key may be NULL — for a composite primary key, no component may be null, not merely “not all of them”. Inserting (677678989, null, 40.0) into WorksOn [essn, pNo, hours] violates entity integrity because pNo is half of the primary key.
The rationale is that the primary key is the relation’s identity: a tuple with an unknown key value cannot be distinguished from, or referred to by, anything. This is the one place a NULL is categorically banned — sql-nulls has the table of which declarations do and don’t permit one.
Referential integrity constraint
A non-null foreign key value must match some existing primary key value in the referenced relation. Inserting an Employee with department = 5 when no Department has id = 5 violates it; so does deleting Department 5 while employees still reference it, and so does updating a foreign key to a value that doesn’t exist. NULL is always allowed — see foreign-keys for the formal statement.
Semantic (business-rule) constraint
Semantic constraints are defined by the business or organisation during client consultation — they come from the organisation, not from the data structure:
- “An employee’s salary must not exceed their supervisor’s.”
- “The maximum number of hours an employee can work on a project is 56.”
- “A department cannot have more than three active projects at a time.”
- “A customer must be at least 18 years old.”
Take the first and third. Inserting Grace Chan on 58000 with superSSN = 888665555 — James Borg, on 55000 — violates the salary rule and nothing else; inserting a fourth project for department 5, which already has ProductX, ProductY and ProductZ, violates the three-project rule and nothing else. In both cases every structural check passes, which is exactly the signal that the answer is “semantic”.
Nothing about the relations’ shape rules these out, so they’re expressed in a constraint specification language — in SQL’s case, the mechanisms are CHECK clauses, assertions and triggers. This course files the latter two under DCL, alongside transaction control and privilege management. Only CHECK is developed and examined (see sql-ddl for the CHECK and named-constraint syntax); assertions and triggers are the general-purpose fallback and are not defined further, so “enforced by an assertion or a trigger” is as far as the course goes. This is also the category to fall back on when asking “which constraint does this break?” and none of the structural four apply.
The converse matters just as much: a rule that was never stated isn’t a constraint. Updating Department (2, Development, 1751) to (2, Development, 2034) where employee 2034 works in a different department violates nothing, unless the business rule “a manager must work in the department they manage” has actually been specified.
Naming an example of each
The other exam shape is the reverse: given a schema, point at one instance of each kind of constraint. For the enrolment schema
Student [stID, name, email]

Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode

Course [cCode, title, units]
a key is stID in Student, a foreign key is stID in Enrolment, and a domain constraint is cCode being four letters followed by four digits. stID supplies both of the first two answers depending on which relation it is read in — the same attribute name is a key where it identifies and a foreign key where it refers.
Diagnosing a violation
Given an operation and a schema, work down the five in a fixed order. The order isn’t significant in itself; checking all five every time is, since one operation can break several at once.
- Domain — is every value of the right type/format for its column?
- Key — does this key value already exist?
- Entity integrity — is any part of the primary key null?
- Referential integrity — does every non-null foreign key point at a row that exists? And, for a delete, does anything still point at the row being removed?
- Semantic — does it break a stated business rule?
A single operation can violate more than one at once. Inserting ('ProductA', 'A', 'Bellaire', 2) into Project [pName, pNumber, pLocation, dNum] breaks both the domain constraint (pNumber is an integer, not 'A') and referential integrity (no department 2). Inserting ('Production', 4, 943775543, …) into Department breaks the key constraint (dNumber = 4 exists) and referential integrity (mgrSSN isn’t a real employee). Don’t stop at the first one found.
And the operations that violate nothing
Three of the applied class’s ten answers are “No”, and they are the ones worth rehearsing, because each looks like a violation and isn’t:
| Operation on the company schema | Why it is legal |
|---|---|
Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into EMPLOYEE |
Fresh ssn, every value in its domain, superSSN 888665555 and dNo 1 both exist, and 50000 is under the supervisor’s 55000 |
Delete the WORKS_ON tuples with essn = 333445555 |
Nothing references WORKS_ON, so no reference is stranded |
Modify DEPARTMENT’s mgrSSN/mgrStartDate for dNumber = 5 to 123456789 and '1988-10-01' |
123456789 is a real employee (John Smith), so the foreign key still resolves, and no other constraint touches the manager column |
Compare that last row with the case where the new manager works in a different department: it still violates nothing. A manager who works elsewhere offends intuition, not any declared constraint.
See update-operations-and-constraint-violations for which constraints each kind of operation can possibly violate, and what a DBMS does about it; sql-dml shows the same violations as the error messages MySQL actually returns.
Relational Keys
A key is a minimal set of attributes that uniquely identifies the tuples of a relation. Everything else in this note is a refinement of that one sentence. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and drilled in week4-tutorial-applied-class-3-relational-integrity; see relational-mapping-notation for how keys are written down (the primary key is underlined) and foreign-keys for the cross-relation case.
Minimality is the whole point
Uniqueness alone isn’t enough — a key must also be minimal, meaning it contains no redundant attributes. Minimal does not mean “the shortest set anyone could find”: it means that removing any attribute from the set destroys the uniqueness property.
Given Department [id, name, manager] where department IDs are unique:
| Candidate set | Unique? | Minimal? | Key? |
|---|---|---|---|
(id) |
Yes | Yes | Yes |
(id, name) |
Yes | No — id alone already suffices |
No |
(id, manager) |
Yes | No — same reason | No |
Adding anything to an already-unique set keeps it unique but destroys minimality, so (id, name) is never a key while (id) is one.
Ask the same key question twice on one instance, changing only the assumptions, and the pair is the whole lesson:
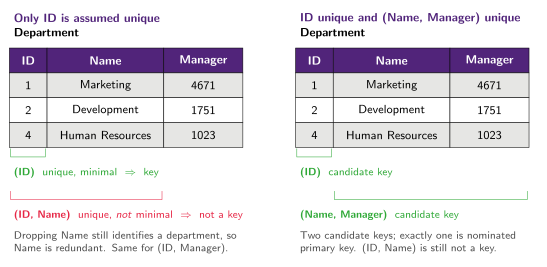
Figure 11: Two key questions on one instance. Left: only ID is assumed unique, so (ID) is the sole key and (ID, Name) fails minimality. Right: (Name, Manager) is also assumed unique, which adds a second candidate key without making (ID, Name) one.
Nothing in the data changed between the two panels — only what the question tells you to assume. Keys are a property of the schema and its stated uniqueness assumptions, never something you can read off one instance.
The vocabulary
| Term | Meaning |
|---|---|
| Superkey | Any set of attributes that uniquely identifies tuples — not necessarily minimal |
| Candidate key | A minimal superkey; a relation may have several |
| Primary key | The one candidate key chosen as the key for the relation; exactly one per relation |
| Composite key | A key made of more than one attribute |
Every key is a superkey; the reverse doesn’t hold. In the table above, (id, name) is a superkey but not a candidate key. The relational-model material works with key, candidate key and primary key only — superkey enters later, with design theory, where the formal treatment of it lives: attribute closure, and how to find all the candidate keys of a relation from its functional dependencies (see functional-dependencies and attribute-closure).
Textbook terms the course never uses are worth not importing: there is no alternate key, secondary key or surrogate key anywhere in INFS1200. A candidate key that lost the nomination is just “another candidate key” and becomes an ordinary attribute in the relational schema; an artificial identifier is just a key that was chosen. Answers should stay inside the four terms above.
Several candidate keys
If department IDs are unique and the combination of name and manager is also unique per department, then Department has two candidate keys: (id) and (name, manager). Both are minimal and both are unique; (id, name) still isn’t a key because (id) alone already suffices. Exactly one of the candidate keys is then nominated as the primary key — a design choice, not something the data dictates.
Composite keys
A key can perfectly well span several attributes. Composite primary keys turn up constantly, and mostly for structural reasons rather than arbitrary ones:
- A weak entity’s relation is keyed on its owner’s primary key plus its own partial key, e.g.
Dependent [ssn, depName, …]. - An M:N relationship’s relation is keyed on the pair of foreign keys it carries, e.g.
WorksOn [ssn, pNo, hours]. - A multivalued attribute’s relation is keyed on the owner’s key plus the value itself, e.g.
DeptLocs [dNumber, location].
All three come out of er-to-relational-mapping. In this course’s notation a composite primary key is written as one continuous underline spanning all of its attributes — one key, not several.
Common misconceptions
From the true/false drill in week4-tutorial-applied-class-3-relational-integrity:
| Statement | Verdict |
|---|---|
| A key is a unique identifier of a tuple in the relation | True — that’s the definition |
| The key constraint (or uniqueness constraint) implies that no two tuples in a relation can have the same values for all attributes | True (as the course marks it) |
| A primary key is a candidate key chosen as the main key for a relation | True |
| A key cannot have multiple attributes | False — composite keys exist |
| An entity may have more than one primary key | False — several candidate keys, but only one is the primary key |
The second row is worth pausing on, because the obvious objection is a good one: no two tuples can agree on all attributes in any relation, declared key or not, since a relation is a set. The course still marks it true, reading it as “the key constraint implies uniqueness of tuples” — so answer it the course’s way, and keep the set-semantics point as the reason the statement is weak rather than as a reason to call it false.
Matching the four terms
Matching definitions to names is a compact statement of all four:
| Definition | Term |
|---|---|
| Any minimal set of attributes that can uniquely identify tuples in a relation | Candidate key |
| A candidate key that is chosen to identify tuples in a relation | Primary key |
| Defines the structure of a relation; specified during database design | Relational schema |
| Data in a relation, modified via create, update and delete operations | Relational instance |
Worked example — electoral roll
Region [prefix, suffix]

Member [enrolmentId, passportNum, regionPrefix, regionSuffix]
Member.{regionPrefix, regionSuffix} references Region.{prefix, suffix}

Candidate [enrolmentId, name, regionPrefix, regionSuffix]
Candidate.enrolmentId references Member.enrolmentId
Candidate.{regionPrefix, regionSuffix} references Region.{prefix, suffix}- Candidate keys:
Member.enrolmentId,Member.passportNum,Candidate.enrolmentId,Region.{prefix, suffix}—Memberhas two, since a passport number identifies a member just as well as an enrolment ID does. - Primary keys:
Member.enrolmentId,Candidate.enrolmentId,Region.{prefix, suffix}— one per relation,passportNumlosing out toenrolmentIdas a design choice. - Composite primary key:
Region.{prefix, suffix}. - Foreign keys:
Member.{regionPrefix, regionSuffix},Candidate.{regionPrefix, regionSuffix},Candidate.enrolmentId— note the last one is simultaneouslyCandidate’s primary key and a foreign key, which is exactly what a subclass relation looks like.
What keys enforce
Two of the five integrity-constraints exist to protect keys:
- The key constraint — no two tuples may share a value for a key. Violated by inserting or modifying a tuple so that it duplicates an existing key value.
- The entity integrity constraint — no part of a primary key may be
NULL. For a composite primary key this means every component must be non-null; a single null component is already a violation.
Both are declarative: the DBMS enforces them automatically once the key is declared, without any application code (see sql-ddl for the PRIMARY KEY / UNIQUE syntax that declares them).
Relational Mapping Notation
Reference legend + course style guide for writing relational schemas — introduced across 2026-03-09-the-relational-model-and-integrity-constraints and 2026-03-16-er-to-relational-mapping. These notations are specific to INFS1200/7900 and may differ from textbooks and online resources, so they are what to follow in an assignment or exam. The guide covers naming and layout only: it recommends nothing about which relations to produce. The mapping steps themselves are in er-to-relational-mapping.
Schema notation
Relation [attr1, attr2, ...]— a relation schema; the (primary) key attribute(s) are underlined.- A composite primary key gets a single continuous underline spanning all of its attributes, e.g.
Enrolment [studentId, courseCode, sem, year]. Relation.fk references OtherRelation.pk— a foreign key constraint, listed directly under the relation it belongs to.Relation.{fk1, fk2} references OtherRelation.{pk1, pk2}— a composite foreign key referencing a composite primary key.
Naming convention (INFS1200/7900 style guide)
- Table names: UpperCamelCase (first letter of each word capitalised, no spaces) — e.g.
Flight, notFLIGHT. - Attribute names: lowerCamelCase (first letter of each word from the second word onwards capitalised) — e.g.
departureTime, notDeparture Time. Acronym attribute names stay entirely lowercase (e.g.eta, notETA). - A space separates the table name from the opening bracket:
Flight [planeNumber, ...], notFlight[planeNumber, ...].
The guide’s compliant and non-compliant pair puts every rule in one line each:
Flight [planeNumber, departureTime, duration, eta]     ✓

FLIGHT[planeNumber, departure time, Duration, ETA]     ✗
The second breaks five rules at once — shouted table name, no space before the bracket, a space inside an attribute name, a capitalised attribute, and an upper-case acronym.
Layout convention
A table’s foreign key constraint lines go directly underneath that table’s own definition, with a blank line before the next table starts — not all grouped together under a separate “Foreign Keys:” heading at the end:
Employee [ssn, firstName, lastName, dob, manager]
Employee.manager references Employee.ssn

Dependant [ssn, name, dob]
Dependant.ssn references Employee.ssn

DependantPhoneNumber [ssn, name, phoneNumber]
DependantPhoneNumber.{ssn, name} references Dependant.{ssn, name}
Relationship Types
The other half of an ER diagram: the associations between entity types. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week3-tutorial-applied-class-2-entity-relationship-diagrams; see er-diagram-notation for the symbols and entity-types-and-attributes for what sits at each end.
Relationship, relationship type, relationship set
The same schema/instance split as entity types:
| Term | Meaning |
|---|---|
| Relationship | An association among two or more entities — “Paris Lane works on the project FileZilla” |
| Relationship type | The definition of that association, drawn as a diamond connected to the participating entity types |
| Relationship set | The collection of all relationships of one relationship type in the database at any point in time |
A relationship set can be drawn as lines between two ovals of entities, or written out as a table of pairs — WORKSON as rows (e1, p1), (e2, p1), (e2, p4), and so on. The tabular form is the one exam questions use when they ask whether a given relationship set is possible under a diagram’s constraints; see interpreting-er-diagrams.
A relationship type may carry its own descriptive attributes, which belong to the pairing rather than to either entity on its own — EMPLOYEE WORKSON PROJECT hangs StartDate and EndDate off the diamond, because a start date belongs to one employee’s stint on one project and to nothing else. A Grade belongs to the enrolment of one student in one course, not to the student and not to the course. Other examples across the notes: a Placement on PARTICIPATES (athlete/event), a Fee on CONSULTS (patient/doctor), a PrepTime on BUYS (customer/bubble tea).
A relationship type may also carry key attributes of its own — on WORKSON it is StartDate that is underlined, which says one employee cannot start on the same project twice on the same day. The Timestamp that distinguishes repeat orders on BUYS does the same job.
Degree
The degree of a relationship type is the number of participating entity types:
| Degree | Name | Example |
|---|---|---|
| 2 | Binary | DEPARTMENT WORKSFOR EMPLOYEE |
| 3 | Ternary | SUPPLIER / PROJECT / PART in one SUPPLIES diamond |
| \(n\) | n-ary | The general case, 3+ entity types |
Degree is decided by counting the lines into the diamond, and it is a real design decision rather than a description — the same UoD can often be modelled as one ternary relationship or as three binary ones, with different consequences. See er-design-choices.
Roles
Each entity type that participates in a relationship type plays a particular role in it. The role name signifies the role a participating entity from that entity type plays in each relationship instance — that is to say, it explains what the relationship means. DEPARTMENT is the Employer and EMPLOYEE is the Worker in WORKSFOR, the relationship between those two entity types. WORKSON is a different relationship: the M:N EMPLOYEE/PROJECT one (relationship-constraints, er-to-relational-mapping).
Roles are optional labelling on an ordinary binary relationship between two different entity types, where the meaning is usually obvious from the names — but they become mandatory in the recursive case below, where they’re the only thing distinguishing the two ends.
Recursive relationships
The same entity type can participate more than once in one relationship type, under different roles — an EMPLOYEE who MANAGES another EMPLOYEE. Both lines run from the same rectangle back to the same diamond, so the role labels carry all of the meaning:
flowchart LR
    EMPLOYEE[EMPLOYEE] ---|"1 Manager"| MANAGES{MANAGES}
    MANAGES ---|"N Subordinate"| EMPLOYEE
Two different relationships share the name MANAGES, and they are not the same thing: this recursive EMPLOYEE/EMPLOYEE one, and the 1:1 EMPLOYEE/DEPARTMENT one that records who runs each department (relationship-constraints, and the mgrSSN foreign key in er-to-relational-mapping). The recursive relationship is also named SUPERVISION in the company diagram used for mapping, and that is the name used for it elsewhere in these notes.
Recursive relationships turn up constantly once you start looking, and they take every cardinality:
| Relationship | Roles | Ratio |
|---|---|---|
EMPLOYEE SUPERVISION EMPLOYEE |
supervisor / supervisee | 1:N |
COURSE PREREQUISITE COURSE |
higher / requires | M:N |
CUSTOMER FRIENDS CUSTOMER |
Requestor / Requestee | M:N |
VACCINE WITH VACCINE |
First / Second | partial on both sides |
NON-WIN SEQUEL NON-WIN |
PrequelTo / SequelTo | 1:1 |
The WITH example from week3-tutorial-applied-class-2-entity-relationship-diagrams is the instructive one: because participation is partial on both sides, the relationship records that a vaccine may be part of a two-dose program — it does not assert that every vaccine has a second dose. Reading a recursive relationship as if it were total is a standard trap.
Constraints
Cardinality ratio (1:1, 1:N, M:N) and participation (total/partial) are covered in relationship-constraints; how to read a claim off them without tripping over the direction is covered in interpreting-er-diagrams.
What happens to a relationship on mapping
The relationship type’s cardinality decides its fate in the relational schema. An M:N relationship becomes its own relation, combining both sides’ foreign keys into one composite primary key (relational-keys), plus any descriptive attributes it carried — UserRatesDriver [userID, driverID, rating] in week4-tutorial-case-study-3-dirt-road-driving. A 1:N relationship doesn’t need a relation of its own; it shows up as a foreign key on the N side, the way EmergencyContact.userID carries the User/EmergencyContact link in the same schema. The full set of rules is in er-to-relational-mapping.
Specialisation and Generalisation
The Enhanced ER (EER) model’s one big addition to plain ER: the ability to say that one entity type is a kind of another. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices; see er-diagram-notation for the notation.
Classes, superclasses and subclasses
In the EER model an entity type is called a class, and entities in the same class share the same attributes. A class can be a superclass or a subclass of another:
- Attributes of a superclass are inherited by its subclasses, and a subclass can add its own specific attributes and its own specific relationships on top.
- Every entity in a subclass is also a member of its superclass(es). The subclass never holds entities the superclass doesn’t.
The motivating example is a supermarket ITEM (ProductName, Price) versus a FOOD item, which is just an ITEM that additionally records an ExpiryDate. Modelling FOOD as a subclass says exactly that — it is an extension of a regular item, not a separate thing that happens to look similar.
Two directions, one relationship
Specialisation and generalisation describe the same superclass/ subclass structure discovered from opposite ends:
| Direction | Starting point | Move | |
|---|---|---|---|
| Specialisation | Top-down | One existing entity type | Define a number of subclasses of it, each containing a subset of the superclass’s entities, on the basis of a more specific distinguishing characteristic |
| Generalisation | Bottom-up | Several existing entity types | Abstraction — ignore the differences amongst the subclasses and generalise them into a common superclass |
The two are duals, not alternatives: the subclasses are a specialisation of the superclass, and the superclass is a generalisation of the subclasses. Which word you use just records how you arrived at the diagram.
Constraints on a specialisation
Two independent constraints apply to every specialisation, and both come from the UoD rather than from preference. They are stated over different things: a specialisation may be total or partial, while the subclass sets may be overlapping or disjoint.
| Constraint | Applies to | Options | Question it answers |
|---|---|---|---|
| Completeness | The specialisation | Total (double line) vs partial (single line) | Must every superclass entity belong to some subclass? |
| Disjointness | The subclass sets | Disjoint (d) vs overlapping (o) |
Can one superclass entity belong to more than one subclass at once? |
Worked readings from the tutorials:
DOCTORspecialises disjointly intoGP/SPECIALIST— “each doctor is either a GP or a specialist, never both”.PARTICIPANTspecialises into overlappingHEALTH/AGEsubclasses — a participant can legitimately be in both at once.STAFFspecialises into overlappingDRIVER/ADMINin week2-tutorial-case-study-1-dirt-road-driving, because a staff member at a small rideshare company can be both at once. Getting this one wrong as disjoint would silently forbid a perfectly ordinary real employee.
flowchart TD
    STAFF[STAFF] --- o1(("o"))
    o1 --- DRIVER[DRIVER]
    o1 --- ADMIN[ADMIN]
    Licence(["Licence"]) --- DRIVER
    DeskNumber(["DeskNumber"]) --- ADMIN
One superclass, several independent specialisations
A superclass can be specialised more than once, along different characteristics, each with its own circle and its own independent pair of constraints. The canonical case is EMPLOYEE carrying two specialisations side by side:
| Specialisation | Subclasses | Disjointness | Completeness |
|---|---|---|---|
| Documents held | PASSPORT / DRIVERLICENSE |
Overlapping (o) |
Partial (single line) |
| How they are paid | HOURLY / SALARY |
Disjoint (d) |
Total (double line) |
All four boxes are ordinary subclasses of EMPLOYEE — none of them is a category or a union type, and each is drawn as a plain rectangle. The o on the left circle is what permits an employee to hold a passport and a driver licence; the single line into it permits one to hold neither. The d on the right circle forbids an employee from being both hourly and salaried, and the double line into it requires every employee to be one or the other. The two circles say nothing about each other: an hourly employee is neither more nor less likely to hold a passport.
flowchart TD
    EMPLOYEE[EMPLOYEE] --- o1(("o"))
    EMPLOYEE === d1(("d"))
    o1 --- PASSPORT[PASSPORT]
    o1 --- DRIVERLICENSE[DRIVERLICENSE]
    d1 --- HOURLY[HOURLY]
    d1 --- SALARY[SALARY]
The same structure turns up elsewhere: GAME in week1-lab-practical-1-course-tools splits disjointly into SINGLEPLAYER / MULTIPLAYER (how it’s played) and, separately, disjointly into WINNABLE / NON-WIN (whether it can be won) — four subclasses, but two unrelated specialisations. EMPLOYEE is also specialised disjointly into SECRETARY / ENGINEER (with TypingSpeed and EngineerDetails respectively) in the running company diagram, which is a third, separate characteristic again.
Reading two circles as one is a common misreading: subclasses under different circles say nothing about each other, so disjointness in one specialisation places no restriction on membership in the other. See interpreting-er-diagrams for the statement-evaluation version of this trap.
Subclasses carry their own relationships
Because a subclass is a full entity type in its own right, relationships can attach to it directly, and this is often the whole point of creating it. SPECIALIST (not DOCTOR) is what RUNS a SPECIALIST CLINIC, and HEALTHWORKER oversees HEALTH participants specifically, not every PARTICIPANT. Attaching a relationship at the subclass level rather than the superclass level is itself a design decision — see er-design-choices.
What happens on mapping
Each subclass becomes its own relation whose primary key is the superclass’s key, plus a foreign key back to the superclass — Driver [id, licence] with Driver.id references Staff.id. The subclass relation holds only its own specific attributes: repeating the superclass’s attributes there (e.g. copying make/model from Vehicles onto 4WD) is a mapping error, since it wastes space and lets the two copies drift apart. See step +1 of er-to-relational-mapping, er-mapping-pitfalls for the rest of the subclass mistakes, and week4-tutorial-case-study-3-dirt-road-driving.
Update Operations and Constraint Violations
There are three update operations on a relational database — insert, delete, and modify — and each can break a different subset of the integrity-constraints. Knowing which subset turns “does this operation violate anything?” from a search into a checklist. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints, drilled across week4-tutorial-applied-class-3-relational-integrity and week6-tutorial-case-study-4-easydrive-insurance. This is the model-level account; sql-dml is the same three operations as SQL statements.
Which operation can violate what
| Domain | Key | Entity integrity | Referential integrity | Semantic | |
|---|---|---|---|---|---|
| Insert | ✓ | ✓ | ✓ | ✓ | ✓ |
| Delete | ✓ | ✓ | |||
| Modify | ✓ | ✓ | ✓ | ✓ | ✓ |
Insert can violate all five: it supplies fresh values for every attribute, so any of them can be out of domain, duplicate an existing key, leave a primary key component null, point at a nonexistent row, or break a business rule. Five candidate tuples for the same two-table schema, differing in one value each, show one of each:
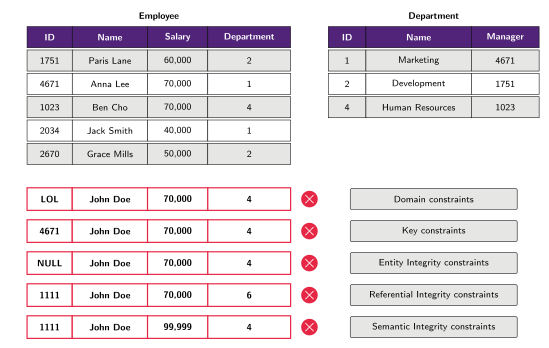
Figure 12: One insert, five ways to break it. Each candidate row differs from a legal Employee tuple in exactly one value, and each trips a different constraint: LOL is not a four-digit integer (domain), 4671 already exists (key), a null ID is a null primary key (entity integrity), department 6 is not in Department (referential integrity), and 99,999 exceeds the supervisor’s salary, which the business rule forbids (semantic). The crimson outline plus ✗ badge is the course’s notation for an illegal tuple.
Modification is the same picture: it can produce any of those five rows out of a legal one, so it inherits the whole column.
Delete is the interesting row. It supplies no values at all, so it cannot possibly produce an out-of-domain value, a duplicate key, or a null primary key. What it can do is remove a row that something else still references — a referential integrity violation on the other relation — or break a business rule. Both happen on the same two-table Employee/Department schema: deleting the department with id = 2 violates referential integrity, because employees still sit in it, while deleting employee 1023 violates a semantic constraint if the rule “every department must have at least one employee” has been stated. This asymmetry is worth remembering: for a delete, the only question is who points at the row being deleted.
Modify behaves like an insert restricted to the columns it touches: changing a key column risks a key violation, changing a foreign key risks a referential one, and changing a primary key component to NULL risks entity integrity.
Handling a referential violation on delete
Rejecting the operation isn’t the only option. At the relational-model stage there are exactly three outcomes for a referential integrity violation — it can be:
| Policy | Effect |
|---|---|
| Rejected | Refuse the delete; the referencing rows keep the referenced row alive |
| Cascaded | Delete the dependent rows too |
| Modified to a default value | Keep the dependent rows, but reset the referencing attribute’s value |
That three-way choice is what is examinable here; the finer-grained named actions — RESTRICT (the default), CASCADE, SET NULL and SET DEFAULT, each available on both delete and update — arrive with SQL DDL and are examined there, not at the model level. See sql-ddl for their exact semantics and syntax, and foreign-keys for the constraint itself.
The choice is a property of the foreign key, decided at design time from what the dependent rows mean without the row they reference: an insurance claim makes no sense without its policy, so EasyDrive declares its claims ON DELETE CASCADE.
Worked diagnoses
Against the company schema Employee [ssn, …, superSSN, dNumber], Department [dName, dNumber, mgrSSN, mgrStartDate], DeptLocations [dNumber, dLocation], Project [pName, pNumber, pLocation, dNum], WorksOn [essn, pNo, hours], Dependent [essn, depName, …], plus two business rules — an employee’s salary cannot exceed their supervisor’s, and a department cannot have more than three active projects:
| Operation | Violates |
|---|---|
Insert an employee with a fresh ssn, a real supervisor, salary below the supervisor’s |
Nothing — a well-formed insert |
Insert ('ProductA', 'A', 'Bellaire', 2) into Project when no department 2 exists |
Referential integrity and domain (pNumber is an integer, not 'A') |
Insert a department whose dNumber already exists and whose mgrSSN doesn’t |
Key and referential integrity |
Insert (677678989, null, 40.0) into WorksOn, essn not an employee |
Entity integrity (pNo is part of the key) and referential integrity |
| Insert an employee earning more than their supervisor | Semantic |
Delete the WorksOn rows for one employee |
Nothing — nothing references WorksOn, and no rule requires an employee to have assignments |
Delete an Employee row |
Referential integrity — WorksOn, Dependent, Department and Employee itself may all reference that ssn |
Modify a department’s mgrSSN to another existing employee |
Nothing, absent a stated rule about who may manage a department |
Modify an employee’s superSSN to an ssn that doesn’t exist |
Referential integrity |
| Insert a fourth active project for a department | Semantic |
Two habits fall out of this. First, always check whether the row being deleted is referenced, not just whether it exists. Second, “no violation” is a legitimate answer — several of the operations above are perfectly legal, and the temptation is to invent a rule that forbids them.
Failures cascade
A rejected operation changes nothing, which means later operations that assumed it succeeded fail too. In the EasyDrive case study, inserting a Vehicle with VehiclePurpose = 'Personal' fails on a domain constraint (the column is ENUM('Private', 'Business')); the next insert, a Policy referencing that vehicle, then fails on referential integrity even though its own values look fine. When a sequence of operations is being analysed, each one has to be judged against the state the previous ones actually left behind — not the state they were intended to leave.
The transaction concept
A transaction is an executing program containing database operations — reads, inserts, deletes, updates. The consistency requirement applies at the end of a transaction, not between its individual steps: constraint violations are permitted at intermediate points, as long as the final state satisfies every constraint specified on the schema.
A transaction is a walk between two consistent states. It starts from consistent state 1, and each INSERT, UPDATE or DELETE moves the database through intermediate states that need not satisfy the constraints; a COMMIT ends the walk at consistent state 2, while a ROLLBACK — or any error or failure along the way — returns the database to consistent state 1 as though nothing had happened. Either way the database is never left inconsistent.
Figure 13: The transaction as a walk between consistent states. Green = a state satisfying every constraint, red = an intermediate state that need not. Only COMMIT and ROLLBACK end the walk, and both end it on a green state. The course has no house notation for transaction diagrams, so the shapes and colours here are not a convention to reproduce in an answer.
This is what makes mutually-dependent business rules satisfiable at all. Given “every department must have at least one employee” and “every employee must work for a department”, neither a new department (no employees yet) nor a new employee (no department yet) can be inserted on its own without breaking a rule. A single transaction that inserts the department and its first employee resolves the deadlock: the intermediate state after the first insert is inconsistent, but the final state after both inserts is valid, and that is the state the constraints are judged against.