flowchart TD
    ID(["ID (key)"]) --- STUDENT[STUDENT]
    Name(["Name"]) --- STUDENT
    Title(["Title"]) --- Name
    Fname(["Fname"]) --- Name
    Initial(["Initial"]) --- Name
    Lname(["Lname"]) --- Name
    Email(["Email"]) --- STUDENT
    Address(["Address"]) --- STUDENT
    Number(["Number"]) --- Address
    Sname(["Sname"]) --- Address
    Suburb(["Suburb"]) --- Address
    Pcode(["Pcode"]) --- Address
    Phone(["Phone (multi)"]) --- STUDENT
INFS1200 — Week 1 Notes
Conceptual Database Design and the ER Model
Module 1, part 1. See er-diagram-notation and relationship-constraints for the reference symbol legend and the cardinality/participation definitions introduced here.
Module outline
Module 1 has five sections. This note covers the first three, and 2026-03-02-weak-entities-the-eer-model-and-design-choices covers the last two:
- Database design overview
- Entities and relationships
- Relationship constraints
- The EER diagram — next lecture
- Design choices — next lecture
The module answers three questions: why conceptual modelling matters for a successful database application; how the Entity-Relationship model is used to do it; and how to evaluate trade-offs between design choices by comparing alternative ER diagrams for the same system.
Conceptual database design
- Step 1: identify the “Universe of Discourse” (UoD) — the database models some “mini-world”/UoD, not everything in the world.
- Step 2: convert the UoD into a data model that a database can capture.
- A model is never perfect — three categories of phenomena around any conceptual schema: common phenomena (captured in the model, e.g. “every employee works for a department”), phenomena not captured (e.g. “some employees go out for dinner on Fridays” — irrelevant, left out), and phenomena not true in the world (e.g. an over-general assumption like “every secretary can type”).
See conceptual-database-design, which draws the two-step pipeline and the three-phenomena picture.
The ER model
The Entity-Relationship (ER) model provides a graphical representation of data entities — it helps define a project’s scope/requirements for clients and businesses. An entity is a physical or conceptual object with data (attributes) associated with it; the same real-world entity can have different attributes recorded depending on the system’s requirements (e.g. an R&D organisation records an employee’s Degree/Field of Study, a retail organisation records Sales Experience instead).
An entity type provides the format (name + attributes) for recording a particular kind of entity — drawn as a rectangle, with attribute ovals attached. The entity set is the collection of all entities of one entity type in the database at a point in time (maps to a table).
The whole notation fits on one diagram, which is the target to work towards. Every symbol on it is defined later in this note or the next:
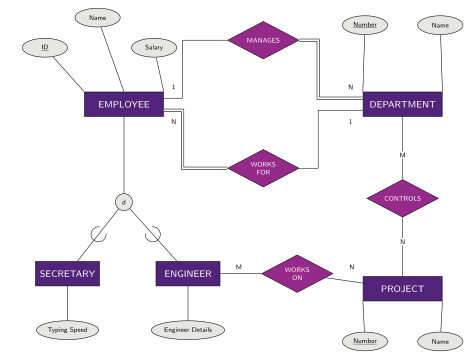
Figure 1: An example company ER diagram. Everything the module teaches is on it: entity types (purple rectangles), relationship types (magenta diamonds), key attributes (underlined ovals), cardinality ratios (1/N/M on the edges), total participation (double edges — every employee must work for a department, every department must have a manager) and an EER disjoint specialisation (the d circle). The diagram exists to gauge how the system works and how data within it is connected.
Attributes
- Key attribute: every entity type has at least one key (or uniqueness) constraint — its value is distinct for each individual entity in the entity set (name underlined). Multiple keys are possible, and a key must hold for every possible extension of the entity type.
- Composite vs simple: a composite attribute (e.g.
Name) can be split into simple attributes with independent meaning (Fname,Mname,Lname). - Composite key: a combination of simple attributes that together must be unique (e.g. a car’s
Registration=State+Number, alongside a separate simple keyVehicleID) — an entity type can have several candidate keys like this. - Single-valued vs multivalued: the split is stated over simple attributes. A multivalued attribute (double-lined oval) can hold more than one value per entity (e.g.
Degree— one person can hold multiple degrees). - Stored vs derived: a derived attribute (dotted oval) is computed from a related attribute value (e.g.
AgefromBirthDate). - Value sets: the set of values that may be assigned to an attribute (e.g.
employeeAge: integers between 21 and 65;vehicleRegistrationNum: a string of three alphabetic characters followed by three integers) — never shown on the diagram itself. Anullvalue represents an inapplicable (tertiaryDegree), unknown (homePhone) or missing (height) value.
entity-types-and-attributes draws the EMPLOYEE figure with every kind of attribute on it, and the CAR candidate-key figure.
Exercise — Student entity
Every student has a unique id, name (title/first/middle initial/last), email, address (number/street/suburb/postcode), and one or more phone numbers. Draw an ER diagram.
NoteSolution
STUDENT entity type with key attribute ID; composite attribute Name (→ Title, Fname, Initial, Lname); simple attribute Email; composite attribute Address (→ Number, Sname, Suburb, Pcode); and multivalued attribute Phone (double-lined oval, since a student can have more than one phone number).
Relationships
A relationship is an association among two or more entities (e.g. “Paris Lane works on the project FileZilla”). A relationship type defines it — drawn as a diamond connected to the associated entity types. A relationship type may have descriptive attributes, and it may have key attributes as well:
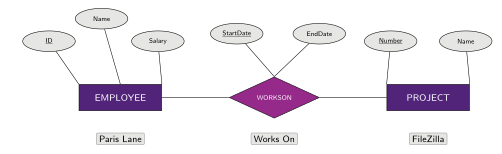
Figure 2: Relationship types carry attributes of their own. WORKSON records a StartDate and an EndDate for each employee/project pairing; StartDate is underlined, so it is a key attribute of the relationship, not merely a descriptive one — a fact the mapping stage has to preserve. The row underneath is the instance-level reading: Paris Lane works on FileZilla.
- Relationship degree = the number of participating entity types: binary (2 entities, e.g.
DEPARTMENT WORKSFOR EMPLOYEE), ternary (3 entities, e.g. a singleSUPPLIESdiamond joiningSUPPLIER,PROJECTandPART), or n-ary (3+) in general. - Roles: each entity type participating in a relationship type plays a particular role, and the role name explains what the relationship means. In
DEPARTMENT WORKSON EMPLOYEE,DEPARTMENTis the Employer andEMPLOYEEis the Worker. - Recursive relationships: the same entity type can participate more than once in one relationship type, under different roles —
EMPLOYEEMANAGESEMPLOYEE, with the two lines labelled Manager and Subordinate. - The relationship set is the collection of all relationships of one relationship type at a point in time. The same relationship set has three representations: the ER fragment (
EMPLOYEEN —WORKSON— MPROJECT), a ball-and-line instance diagram, and a three-column table (WorksOnID,EmployeeID,ProjectID), which is the shape the relationship eventually takes once mapped (er-to-relational-mapping).
Question — Entities and Relationships (courses/students)
Store info about students, courses, courses taken, and grades. Courses have a number/department/title (numbers assigned per-department, so different departments may reuse a number); students have a unique student ID and name; students enrol in courses and receive a grade.
NoteSolution
COURSES (composite key Key = Dept + Number, plus Title) ↔︎ ENROLMENTS (attribute Grade) ↔︎ STUDENTS (key ID, Name) — an M:N relationship, since a student can enrol in many courses and a course has many enrolled students.
flowchart LR
    ID(["ID (key)"]) --- STUDENTS[STUDENTS]
    NameS(["Name"]) --- STUDENTS
    STUDENTS ---|"N"| ENROLMENTS{ENROLMENTS}
    ENROLMENTS ---|"M"| COURSES[COURSES]
    Grade(["Grade"]) --- ENROLMENTS
    CourseKey(["Key (key)"]) --- COURSES
    Dept(["Dept"]) --- CourseKey
    Number(["Number"]) --- CourseKey
    Title(["Title"]) --- COURSES
The composite key comes from the clause that numbers are assigned by departments and different departments may use the same number: Number alone is not unique, so Dept + Number together are the key.
Relationship constraints
Constraints on a relationship type limit the possible combinations of entities that may participate in the corresponding relationship set, and both kinds are determined by the UoD — they are read off the description, not chosen for convenience. There are two:
| Constraint | What it fixes |
|---|---|
| Cardinality constraint | How many relationships of the set one entity can participate in |
| Participation constraint (also called existence dependency) | Whether an entity has to participate at all |
See relationship-constraints for what each ratio and each participation constraint asserts.
Cardinality ratio
A cardinality ratio for a relationship set specifies the number of relationships in the set that an entity can participate in. Take a customer buying items: one customer can purchase many different items, but an individual item (a particular cake) cannot be purchased by several different customers.
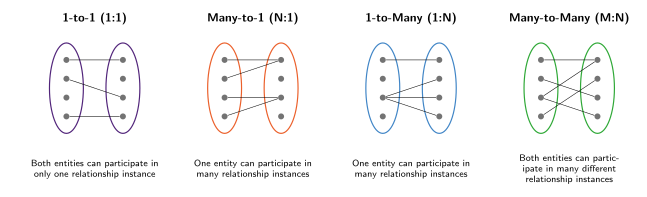
Figure 3: The four cardinality ratios as instance diagrams, colour coded: purple 1:1, orange N:1, blue 1:N, green M:N. Each dot is one entity, each line one relationship instance. Which dots are joined is illustrative; the constraint is the shape — a matching (1:1), a fan-in (N:1), a fan-out (1:N), or an unrestricted graph (M:N).
N:1 and 1:N are the same constraint read from opposite ends. The one relationship EMPLOYEE N — WORKSFOR — 1 DEPARTMENT fits both the orange N:1 picture and the blue 1:N picture. Which name you use depends on which entity type you name first, and the course’s notation guide fixes the reading: E1 —1— R —N— E2 is “cardinality ratio 1:N for E1:E2 in R”. The practical rule for reading a diagram is that the number written next to an entity says how many of that entity may take part with one of the other: N beside EMPLOYEE = many employees per department; 1 beside DEPARTMENT = one department per employee.
Three worked examples:
| UoD sentence | Ratio |
|---|---|
“Each employee can work on any number of projects, and each project can have any number of employees working on it” (WORKSON) |
M:N |
“Each department can have any number of employees, but an employee can work for at most one department” (WORKSFOR) |
N:1 (equivalently 1:N the other way) |
“Each department can have at most one manager and each employee can manage at most one department” (MANAGES) |
1:1 |
Participation constraints (existence dependency)
Existence dependency indicates whether the existence of an entity depends on its relationship to another entity. A double line between an entity type and a diamond means total participation; a single line means partial.
- “Every employee must work for a department” —
EMPLOYEEhas total participation inWORKSFOR, soEMPLOYEEis existentially dependent onDEPARTMENTvia theWORKSFORrelationship type. - “Every department must have a manager” —
DEPARTMENThas total participation inMANAGES, soDEPARTMENTis existentially dependent onEMPLOYEEviaMANAGES, whileEMPLOYEE’s participation stays partial (some employees manage nothing, and legally so).
Worked example — EMPLOYEE / DEPARTMENT
Figure 1 above is the diagram. It encodes four sentences:
- Every department must have a manager — total participation of
DEPARTMENTinMANAGES(double line on that edge). - Every employee can manage 0 or more departments — partial participation of
EMPLOYEEinMANAGES, and the1/Nlabels makeMANAGES1:N forEMPLOYEE:DEPARTMENT(a department has at most one manager; an employee may manage several). - Every employee must work for a department — total participation of
EMPLOYEEinWORKSFOR. - Each department can have any number of employees — with
NbesideEMPLOYEEand1besideDEPARTMENT,WORKSFORis N:1.
The 1:1 example in the table above (“each department can have at most one manager and each employee can manage at most one department”) is a different UoD sentence from statement 2: it is drawn 1 — MANAGES — 1, whereas the company diagram is drawn 1 — MANAGES — N. Two sentences, two ratios, same relationship name, so the ratio has to be read off the UoD and not off the verb.
WORKSON (EMPLOYEE M:N PROJECT) completes the picture: each employee can work on any number of projects, and each project can have any number of employees on it.
Question — Relationship constraints
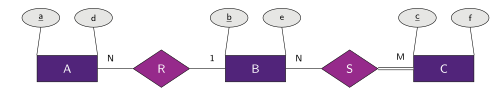
Figure 4: Entity types A, B and C joined by relationship types R and S. A contains a1, a2; B contains b1, b2; C contains c1, c2. Which relationship sets for R and S are possible? The double line into C is the whole difficulty — it constrains the instances, not just the schema.
A. R = {}, S = {}
B. R = {(a1,b1)}, S = {(b2,c2)}
C. R = {(a1,b1), (a1,b2)}, S = {(b1,c1), (b2,c2)}
D. R = {(a1,b2)}, S = {(b1,c2), (b2,c1), (b1,c1)}
NoteSolution
(D). Two constraints have to hold at once:
Ris N:1 forA:B, so eachamay appear at most once inR. That kills C, wherea1is paired with bothb1andb2.Chas total participation inS(the double line), so everycmust appear inS. That kills A (nothing appears) and B (c1is missing).Sbeing M:N places no further limit, so D — which lists bothc1andc2and pairs eachaat most once inR— is legal.
Exercise — ABC Banks
Model a bank with branches (unique name, city, budget, rating 1–10), customers (identified by name + phone, address recorded), accounts and loans (unique number, created/maintained by a single branch), where an account is assigned to one or more customers (balance never negative) and a loan is always assigned to a single customer (fixed interest rate, balance never negative).
NoteSolution
BRANCH (Name, City, Budget, Rating) —1:N OPENS→ ACCOUNT (ID, Balance); BRANCH —1:N GIVES→ LOAN (ID, Rate, Balance); CUSTOMER (ID, Name, Phone, Address) —M:N OWNS→ ACCOUNT; CUSTOMER —1:N TAKES→ LOAN.
flowchart TD
    BRANCH[BRANCH] ---|"1"| OPENS{OPENS}
    OPENS ---|"N"| ACCOUNT[ACCOUNT]
    BRANCH ---|"1"| GIVES{GIVES}
    GIVES ---|"N"| LOAN[LOAN]
    CUSTOMER[CUSTOMER] ---|"M"| OWNS{OWNS}
    OWNS ---|"N"| ACCOUNT
    CUSTOMER ---|"1"| TAKES{TAKES}
    TAKES ---|"N"| LOAN

    NameBr(["Name (key)"]) --- BRANCH
    City(["City"]) --- BRANCH
    Budget(["Budget"]) --- BRANCH
    Rating(["Rating"]) --- BRANCH

    IDa(["ID (key)"]) --- ACCOUNT
    BalanceA(["Balance"]) --- ACCOUNT

    IDl(["ID (key)"]) --- LOAN
    Rate(["Rate"]) --- LOAN
    BalanceL(["Balance"]) --- LOAN

    IDc(["ID (key)"]) --- CUSTOMER
    NameC(["Name"]) --- CUSTOMER
    Phone(["Phone"]) --- CUSTOMER
    AddressC(["Address"]) --- CUSTOMER
Two clauses in the brief are constraints the notation cannot carry: “its balance can never be negative” is a value-set restriction, and value sets are never shown on an ER diagram — it resurfaces later as a domain constraint (integrity-constraints). “Each account and loan is created and maintained by a single branch” is the participation constraint that makes ACCOUNT and LOAN total in OPENS/GIVES.
Practical 1: Course Tools
Introduces the two tools used throughout the course: diagrams.net (draw.io) for building ER diagrams, and Gradescope for submitting assessment. This practical itself is not assessable — it’s onboarding practice before Assignment 1. The semester plan lists it as the first practical, Intro to Course Tools, run in teaching week 2 (infs1200).
WarningUnverified
Nothing on this page (the Always a Gamer UoD, the diagram, or the task breakdown) has been verified against a published version, so treat it as a working reconstruction.
Task 1 — Recreate the “Always a Gamer” diagram in draw.io
UoD: a fictional gaming company’s GAME entity (Name, Year, Language, Description, Console) specialises two separate, disjoint (d) ways:
- How it’s played:
SINGLEPLAYER(Characters) orMULTIPLAYER(MinPlayers,MaxPlayers). - Whether it can be won:
WINNABLE, orNON-WIN(Purpose).
NON-WIN games also have a recursive SEQUEL relationship to other NON-WIN games (roles PrequelTo/SequelTo, 1:1).
flowchart TD
    GAME[GAME] --- d1(("d"))
    d1 --- SINGLEPLAYER[SINGLEPLAYER]
    d1 --- MULTIPLAYER[MULTIPLAYER]
    GAME --- d2(("d"))
    d2 --- WINNABLE[WINNABLE]
    d2 --- NONWIN["NON-WIN"]
    NONWIN ---|"1 PrequelTo"| SEQUEL{SEQUEL}
    SEQUEL ---|"1 SequelTo"| NONWIN

    Name(["Name"]) --- GAME
    Year(["Year"]) --- GAME
    Language(["Language"]) --- GAME
    Description(["Description"]) --- GAME
    Console(["Console"]) --- GAME
    Characters(["Characters"]) --- SINGLEPLAYER
    MinPlayers(["MinPlayers"]) --- MULTIPLAYER
    MaxPlayers(["MaxPlayers"]) --- MULTIPLAYER
    Purpose(["Purpose"]) --- NONWIN
Recreate this EER diagram yourself in draw.io. The mechanics worth finding first are the shape palette, connecting an entity to a relationship diamond, and exporting the finished drawing as an image.
The four subclasses above are drawn as plain rectangles, exactly like GAME itself. Subclass-hood is carried by the edge into the d circle, never by the box outline — a double-line box means weak entity, which is a different idea entirely. See er-diagram-notation for the full symbol table and the Mermaid shape mapping this note follows.
Task 2 — Using the ER diagram
Question 1 — Identifying entities
Which entity type is the superclass that every other entity type in this diagram specialises from (directly or indirectly)?
NoteWorking
GAME is the superclass. Its two disjoint specialisations are SINGLEPLAYER/MULTIPLAYER (one d-circle) and WINNABLE/NON-WIN (a separate d-circle) — four subclasses total, all ultimately specialising GAME.
Task 2.2 — Exporting the diagram
Export the finished diagram from draw.io as an image and attach it to the practical’s Gradescope submission — no fixed “right answer” here, it just confirms the export step works.
Task 3 — Submitting via Gradescope
Submit via the Gradescope link on the course Blackboard site. Not assessable — purely to confirm your Gradescope account is set up correctly ahead of Assignment 1.
Reference material
Conceptual Database Design
Conceptual design is everything that happens before a single table exists: deciding which slice of the world the database is about, and expressing that slice as an ER/EER diagram. It is a very important phase in designing a successful database application, and it follows a two-step procedure. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model.
The Universe of Discourse
- Step 1 — identify the Universe of Discourse (UoD): the “mini-world” the database models. A database never models everything in the world, only the part an organisation actually needs to record.
- Step 2 — convert that UoD into a data model a database can capture.
Those two steps are the whole of conceptual design in this course: the world → the UoD → the data model. Everything in entity-types-and-attributes, relationship-types and specialisation-and-generalisation is machinery for step 2.
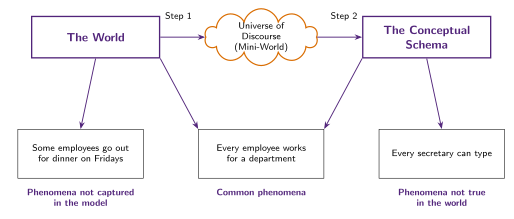
Figure 5: The two-step pipeline and the three categories of phenomena around the finished schema. The pipeline is the World → UoD → Data Model chain, and the three phenomenon boxes fan off the World and the Conceptual Schema. Only the middle box has an arrow from both, which is exactly what makes it common: true in the world and captured in the model.
The UoD is not a formality to get past. Every constraint drawn later — cardinality ratios, participation, disjointness — is read off the UoD rather than chosen arbitrarily (see relationship-constraints), so a vague or ambiguous UoD produces a diagram whose constraints can’t be justified. Where the UoD genuinely is ambiguous, that ambiguity becomes a design decision to record explicitly — see er-design-choices.
A model is never perfect
Around any conceptual schema there are three categories of phenomena (Figure 5):
| Category | Meaning | Example |
|---|---|---|
| Common phenomena | True in the world and captured in the model | “Every employee works for a department” |
| Phenomena not captured | True in the world, deliberately left out as irrelevant | “Some employees go out for dinner on Fridays” |
| Phenomena not true in the world | Captured by the model, but an over-general assumption | “Every secretary can type” |
The first category is the target. The second is fine and unavoidable — a model that captured everything would be the world itself. The third is the dangerous one: the schema will happily enforce a rule that reality violates, and the mismatch only surfaces once real data arrives.
What the ER model is for
The Entity-Relationship (ER) model provides a graphical representation of data entities, which is what makes it useful for defining a project’s scope and requirements with clients and businesses — it’s a communication artefact agreed on before implementation, not an implementation itself. Three questions run through the module: why conceptual modelling matters for designing a successful database application, how the ER model is used to do it, and how to evaluate the trade-offs between design choices by comparing alternative ER diagrams for the same system — the third of which is the whole content of er-design-choices.
An entity is a physical or conceptual object with data (attributes) associated with it. Crucially, the same real-world entity is recorded differently depending on the system’s requirements: an R&D organisation records an employee’s Degree and Field of Study, while a retail organisation records Sales Experience instead. There is no “correct” attribute list for a real-world thing in the abstract — only one that’s correct for a given UoD. See entity-types-and-attributes and relationship-types for the building blocks, specialisation-and-generalisation for the EER extension on top of them, and er-diagram-notation for the symbol legend. Reading a finished diagram back out is its own skill — interpreting-er-diagrams.
Where conceptual design sits
“Conceptual” is also the middle layer of a DBMS’s three-schema architecture (dbms-fundamentals) — the level that describes the whole database for a community of users, as opposed to any one user’s view of it. Conceptual design is where that schema gets written.
This course names no formal design lifecycle. The subject splits into three concerns, worked through in dependency order:
| Concern | Covered by |
|---|---|
| Database design — conceptual database design, then design theory and normalisation | This note, then functional-dependencies and normal-forms |
| Data models — the relational model, its integrity constraints, and ER-to-relational mapping | relational-model, integrity-constraints, er-to-relational-mapping |
| Physical storage — file organisation, hashing, indexing | Explicitly deferred to later INFS courses |
So the working pipeline is: conceptual design produces the ER/EER diagram; mapping turns it into a relational schema; SQL (sql-ddl) declares that schema; and normalisation refines it afterwards. Physical storage — the internal level of the three-schema architecture — never enters the picture here, which is exactly what physical data independence is supposed to buy.
That ordering is why conceptual mistakes are expensive. A decision that looks cosmetic on the diagram propagates into the schema and into the constraints the DBMS can actually enforce — the mapping errors dissected in week4-tutorial-case-study-3-dirt-road-driving are all downstream consequences of getting an entity’s identity or a relationship’s endpoint wrong at the conceptual stage.
DBMS Fundamentals
What a database is, what a Database Management System is layered into, and what it is (and isn’t) responsible for. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and drilled in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd.
Data, information, and where a database sits
Four definitions the course builds on top of each other:
| Term | Definition |
|---|---|
| Data | Facts and statistics collected together for reference or analysis, typically digitised |
| Information | Data put into meaningful and useful context and communicated to recipients who use it to make decisions |
| System | A set of components that interact to accomplish some purpose |
| Information system | A system that manages information |
An information system is built from five blocks — inputs, processes, outputs, databases and technology. This course is about the database block, which is where the data actually lives.
A database is a collection of related data or known facts that:
- represents some aspect of the real world — the mini-world, or Universe of Discourse (UoD);
- is a logically coherent collection of data with some inherent meaning;
- is designed, built and populated with data for a specific purpose, for an intended group of users and some preconceived applications;
- can be of any size and complexity;
- may be maintained manually or computerised.
The third point is the one that does the work later: a database is designed for a purpose, which is why design begins by fixing the UoD rather than by listing tables. See conceptual-database-design.
Data management — capturing, storing, retrieving, analysing, presenting and interpreting (large amounts of) data — is the skill the whole course is in service of. Three application sectors depend on it:
| Sector | Examples |
|---|---|
| Commerce | Cash management, pricing, employee records, purchasing, reordering, trend analysis |
| Government | Law enforcement, election commission, taxation, legal systems, transport and utilities, city councils |
| Science and engineering | Health and medicine, space exploration, geography (GIS), architecture, military and defence, telecommunications |
Banking is an example of an application area where data plays a central role.
What a DBMS is
A database management system (DBMS) is a software system that facilitates the processes of defining, constructing, manipulating and sharing databases among various users and applications. Those four verbs are the standard summary answer to “what is a DBMS”:
| Process | What it covers |
|---|---|
| Defining | Specifying the types, structures and constraints for the data — sql-ddl |
| Constructing | Storing the data on some storage medium controlled by the DBMS |
| Manipulating | Querying to retrieve specific data, updating to reflect changes in the mini-world, and generating reports — sql-select-statement, sql-dml |
| Sharing | Allowing multiple users and programs to access the database simultaneously |
The four components of a database system
The DBMS is only one piece. A database system has four:
| Component | What it is |
|---|---|
| The stored database | The collection of related information itself |
| The DBMS | The software that defines, constructs and manipulates the database |
| The applications | The programs, in specific languages, that manipulate the database |
| The users | People who use the system, either through the DBMS interface or through application programs |
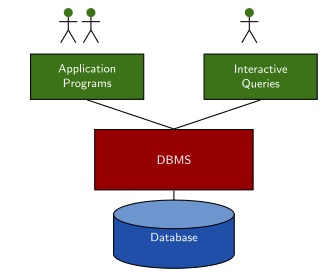
Figure 6: The database system. Users reach the stored database only through one of two front doors — an application program or an interactive query — and both go through the DBMS. Nothing touches the stored database directly.
Users are further split into database administrators, database designers, end users and application programmers. They reach the database through different interfaces by design: query languages for casual end users, programming-language interfaces for application programmers, and forms and commands for parametric users. GUIs, web-enabled interfaces, natural-language interfaces and speech I/O all sit on top of those. A parametric user is someone who runs the same canned transaction over and over.
Getting from the world to a stored database
Conceptual database design is two steps. Keep them separate before any diagram gets drawn:
- Identify the Universe of Discourse. The database will not model everything in the world, only some mini-world — see conceptual-database-design.
- Convert the UoD to a data model that a database can capture.
One example previews the whole arc of the course. An ER diagram has EMPLOYEE (attributes ID, Name, Salary) joined N:1 to DEPARTMENT (attributes Number, Name) through a WORKS FOR relationship. It maps to this relation:
Employee
| ID | Name | Salary | Department |
|---|---|---|---|
| 175 | Paris Lane | 60,000 | 2 |
| 467 | Anna Lee | 70,000 | 1 |
| 1023 | Ben Cho | 70,000 | 4 |
That one mapping is Modules 1 and 2 of this course: the conceptual model on top (entity-types-and-attributes, relationship-types) and the relational model beneath it (relational-model), joined by the mapping rules in er-to-relational-mapping. The WORKS FOR relationship has become the Department column of Employee, not a table of its own. Recognising that column as a foreign key is Module 2’s job (foreign-keys), and the reason a 1:N relationship collapses into a column is in er-to-relational-mapping.
Redundancy: the problem a designed database solves
Redundancy occurs when one fact is stored in more than one place. Take employee records split across two relations:
| ID | Name | Level |
|---|---|---|
| 1 | Paris | Developer |
| 2 | Anna | Manager |
| 3 | Ben | Manager |
| ID | Name | Salary |
|---|---|---|
| 1 | Paris | 60,000 |
| 2 | Anna | 70,000 |
| 3 | Ben | 70,000 |
Two separate facts are stored redundantly here. The ID/name pair is stored twice, once per relation. And assuming an employee’s salary corresponds directly to the level they hold, the fact “Manager earns 70,000” is stored once per manager rather than once — which is why Anna and Ben both carry 70,000 in their own row. Three costs follow:
- duplication of effort,
- wastage of storage space, and
- inconsistent data — the copies drift apart.
The design goal is therefore to minimise redundancy, not merely to store everything somewhere. The systematic machinery for doing that is functional-dependencies and normal-forms; the concrete failure modes are catalogued in update-anomalies. The other thing a database buys you over a pile of files is the ability to represent complex relationships among the data, which is what er-to-relational-mapping turns an ER diagram into.
Typical functions of a DBMS
| Function | What it means | Where it lands in this course |
|---|---|---|
| Data integrity maintenance | Defining and enforcing integrity constraints — restrictions placed on the data, based on the semantics (meaning) of the data | integrity-constraints |
| Query processing | A language simple enough to run a query and get data back in seconds, yet powerful enough to manage millions of tuples without crashing | sql-select-statement |
| Security management | Measures for securing the database against a variety of threats | database-access-control, sql-injection |
| Concurrency control | Control protocols for concurrent access to data files that guarantee serialisability | Deferred to later INFS courses |
| Backup and recovery | Recovering from hardware and software failures via the backup and recovery sub-system | Deferred to later INFS courses |
Integrity constraints are semantic — they come from what the data means, not from how it is stored. Examples: every employee must have a unique code; employee codes must be 4-digit integers; an employee must work in an existing department; an employee cannot work in multiple departments; an employee’s salary should not exceed their supervisor’s salary. Each of those is a constraint the DBMS can be told to police.
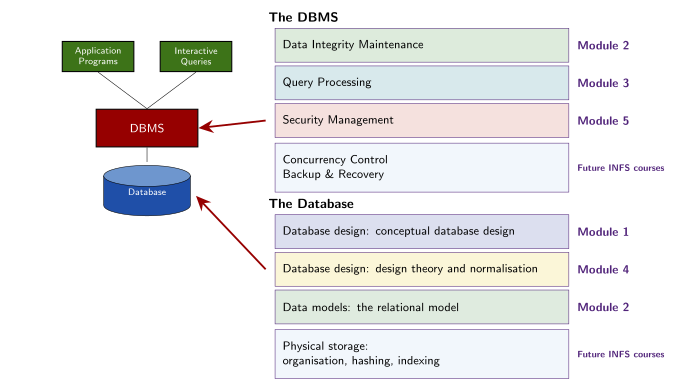
Figure 7: What the two boxes in Figure 6 decompose into, and which module of the course covers each piece: the functions of the DBMS, and what goes into designing and modelling the stored database. Everything greyed as future INFS courses is deferred to those courses.
The recovery example is the one worth remembering. A program transferring $200 from account A to account B is interrupted by a system failure partway through, so the deposit is never recorded in B. The DBMS restores the database to the state prior to the update and restarts the update program, rather than leaving the money in neither account. Concurrency control solves the neighbouring problem: thousands of people editing the same file while each assumes they are the only person using it. Serialisability is the guarantee the control protocols provide: whatever interleaving actually occurred, the result matches some order of running those accesses one at a time.
What a DBMS does — and doesn’t
The dividing line is a single rule: a DBMS enforces the design it is handed, it does not choose the design.
Enforcing integrity constraints, providing secure access, handling concurrent access, and backing up and recovering the database are all DBMS functions. Designing a database is not — and neither is normalising the relational schema (normal-forms) or recommending changes to the database design. Those are design-time decisions made by a human database designer, and no amount of running the database will make them happen by itself. In a list of candidate “DBMS functions”, the design-flavoured option is the odd one out every time.
The three-schema architecture
A DBMS describes the same data at three separate levels, so that each one can change without disturbing the others:
| Level | Describes |
|---|---|
| External level | Provides access to particular parts of the database to particular users, as one or more external views |
| Conceptual level | Describes the structure of the whole database for a community of users, as the conceptual schema |
| Internal level | Describes the physical storage structure of the database, as the internal schema |
The levels are joined by two named mappings: the external/conceptual mapping from each external view down to the conceptual schema, and the conceptual/internal mapping from the conceptual schema down to the internal schema and the stored database beneath it. The mappings are what make data independence possible — a change at one level is absorbed by re-writing the mapping rather than by rewriting the level above.
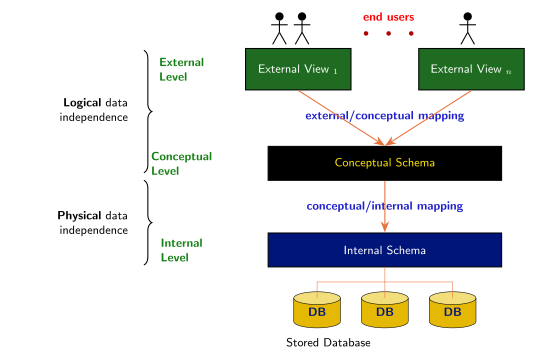
Figure 8: The three-schema architecture, with the two data-independence properties bracketed onto the level pairs they insulate. The colours — green external views, black/yellow conceptual schema, navy internal schema, gold cylinders — are the textbook’s, not INFS1200 notation; the course’s own ER house style is purple/magenta. Each independence property spans exactly one mapping: logical data independence rides the external/conceptual mapping, physical data independence rides the conceptual/internal one.
The external level is per-audience: a user or application sees the slice of the database relevant to it, not the whole thing, and SQL’s views (see sql-views) are the concrete mechanism for carving out that slice. The conceptual level is the one an ER diagram maps onto (see conceptual-database-design and relational-model), and the internal level — file organisation, hashing, indexing — is explicitly out of scope for this course.
Data independence
Data independence is the ability to change the schema at one level of a database system without having to change the schema at the next higher level. The three-schema architecture exists to deliver it in two flavours:
| Kind | What it buys you |
|---|---|
| Logical data independence | The ability to change the conceptual schema without changing the external views or the applications built on them |
| Physical data independence | The ability to modify the physical schema without changing the conceptual schema |
The course treats conceptual schema and logical schema as two names for the same middle level — physical data independence is stated interchangeably as “modify the physical schema without making changes to the logical schema”. So the two independence properties bracket that one level: logical data independence insulates the layer above it, physical data independence insulates it from the layer below.
Two claims that look right and aren’t: logical data independence is not about moving where data is physically stored (that is physical data independence), and the external level provides access to parts of the database, not the ability to change the schema of its relations. Both are distractors in multiple-choice questions. The correct statement is that physical data independence lets you modify the physical schema without changing the logical schema. The same matching is drilled in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd.
Reading
Chapters 1 and 2 of Elmasri & Navathe, Fundamentals of Database Systems (the course textbook, available online via the UQ Library). The module that follows this one is Module 1, conceptual data modelling and ER diagrams — 2026-02-23-conceptual-database-design-and-the-er-model.
Entity Types and Attributes
The two smallest building blocks of an ER diagram: the kinds of thing a database records, and the facts it records about them. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd; see er-diagram-notation for the symbols and the naming style guide.
Entity, entity type, entity set
Three words that are easy to blur together, and are worth keeping apart:
| Term | Meaning |
|---|---|
| Entity | A physical or conceptual object with data associated with it — one particular student, one particular chef |
| Entity type | The format for the data that needs to be recorded to represent a particular entity — described by its name and its attributes. Drawn as a rectangle with attribute ovals attached |
| Entity set | The collection of all entities of one entity type in the database at any point in time |
The entity type is the schema-level thing (it doesn’t change as data comes and goes); the entity set is the instance-level thing (it changes with every insert and delete). The entity set is what becomes a table once the diagram is mapped — see er-to-relational-mapping.
Which attributes an entity type carries is decided by the UoD, not by the real-world object: an R&D organisation records an employee’s Degree and Field of Study where a retail organisation records Sales Experience instead. See conceptual-database-design.
Kinds of attribute
Attributes are classified along several independent axes — an attribute can be composite and multivalued, key and composite, and so on:
| Kind | Meaning | Example |
|---|---|---|
| Simple | Can’t be meaningfully split further | Email, DoB |
| Composite | Divides into smaller parts which are simple attributes with independent meaning | Name → Fname, Mname, Lname; Address → Number, Sname, Suburb, Pcode |
| Single-valued | Holds at most one value per entity | DoB |
| Multivalued | Can hold more than one value per entity (double-lined oval) | Degree — one person can hold several; Specialisations, Ingredients, Locations |
| Stored | Physically recorded | BirthDate |
| Derived | Computed from another stored attribute (dashed oval) | Age from BirthDate; Number_of_employees on a department |
| Key | Value is unique across the whole entity set (name underlined) | StudentID, Ssn |
A single EMPLOYEE entity type can carry every kind at once:
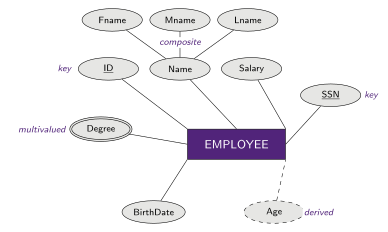
Figure 9: Every kind of attribute on one EMPLOYEE entity type. ID and SSN are two independent key attributes (solid underline). Name is composite — it fans out into Fname/Mname/Lname, and the parent oval itself is unmarked. Degree is multivalued (double outline): one person can hold several degrees. Age is derived from BirthDate, so it gets a dashed outline and a dashed connecting line, and it is never stored.
The single/multivalued split is stated over simple attributes — a composite attribute’s multiplicity is really a property of its components. The distinction between composite and multivalued is the one that catches people out: Name splitting into first/middle/last is composite (one name made of parts), whereas Phone on a student is multivalued (several independent phone numbers). Both attach several ovals to the diagram, but they mean different things and map differently.
Key attributes and candidate keys
Every entity type has at least one key constraint (equivalently, a uniqueness constraint), carried by a key attribute whose value is distinct for each individual entity in the entity set. Two properties matter:
- Multiple keys are possible. An entity type can have several independent candidate keys, each underlined in its own oval — the
EMPLOYEEabove carries bothIDandSSN. Elsewhere in the course: aDISHidentified by either itsNameor itsNumber, aVENUEby either itsIDor the combination ofNameandAddress, aVACCINEby either itsIDorBrand+Name. Any claim that an entity is “only identifiable by X” is false as soon as a second key oval is on the diagram. - A key must hold for every possible extension of the entity type. It isn’t enough that the current data happens to have no duplicates; the key must be a rule about every state the entity set could ever reach.
A composite key is a combination of simple attributes that together must be unique — a car’s Registration = State + Number, alongside a separate simple key VehicleID. On the diagram this is drawn as one underlined parent oval that splits into its component ovals, which is how you can tell “these two attributes are jointly a key” apart from “these are two separate keys”:
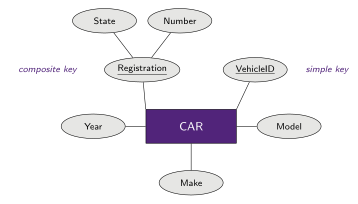
Figure 10: A CAR entity type with two candidate keys side by side: the composite Registration (underlined parent oval, splitting into State and Number — neither of which is unique alone) and the simple VehicleID. Year, Model and Make are ordinary attributes. Which of the two candidate keys is chosen as the primary key is deferred to the mapping stage, and changes the resulting schema — see er-to-relational-mapping.
The single exception to “every entity type has a key” is the weak entity, which has no key attribute of its own and is identified by its owner’s key plus its own partial key — see relationship-constraints. See also relational-keys for the same idea stated over relations rather than entity types.
Value sets and nulls
An attribute’s value set specifies the set of values that may be assigned to that attribute of an entity — employeeAge: integers between 21 and 65; vehicleRegistrationNum: a string of three alphabetic characters followed by three integers. Value sets are never displayed on the ER diagram itself — they resurface later as the domains of the relational-model, enforced as the domain constraint among the integrity-constraints.
A particular entity may not have an applicable value for an attribute, and a null value is used to represent that. Three reasons a null appears are worth keeping apart, because they are different facts about the world:
| Reason | Example |
|---|---|
| Not applicable | tertiaryDegree for a person with no university education |
| Not known whether it exists | homePhone |
| Missing — exists, but not recorded | height |
Nulls are the reason an attribute being “optional” is a real modelling decision rather than an afterthought; see sql-nulls for how they behave once queried.
Why the attribute kind matters later
The classification isn’t decorative — each kind maps differently:
- A multivalued attribute becomes its own relation, keyed on the owner’s key plus the value itself:
Staff’s multivaluedPhonebecomesStaffPhone [id, phone]. It has to — a relational column holds one atomic value (relational-model). Leavingphoneout of that key would cap each staff member at one phone number, defeating the point of making it multivalued in the first place. - A derived attribute is computed on demand, so it gets no column of its own: a trip’s
Fareis derived from its start and end times and simply doesn’t appear in the mappedTriprelation. - A composite attribute is flattened into its simple components (
Name→firstName,middleName,lastName).
All three are worked through in week4-tutorial-case-study-3-dirt-road-driving; the mapping rules themselves live in er-to-relational-mapping.
ER Diagram Notation
Reference legend for the symbols used across every ER/EER diagram in this course — introduced across 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices.
The notation below is the mandatory standard: it is what the lectures’ own notation guide specifies, and it is what assignments and the exam are marked against. (The separately published INFS1200/7900 EER & ER Notation Guide handout only standardises naming — see the style guide at the bottom of this note — and explicitly defers the symbols themselves to the lecture material.)
Core symbols
| Symbol | Meaning |
|---|---|
| Rectangle | Entity type |
| Double-line rectangle | Weak entity type (no key attribute of its own) |
| Oval | Attribute |
| Oval, name underlined | Key attribute |
| Oval, name underlined with a dotted line | Partial key attribute (weak entity’s own distinguishing attribute) |
| Double-line oval | Multivalued attribute (can hold more than one value) |
| Dashed oval, attached by a dashed line | Derived attribute (computed from another stored attribute, e.g. Age from BirthDate) |
| Diamond | Relationship type |
| Double-line diamond | Identifying relationship type (connects a weak entity to its owner entity) |
- Composite attribute: an attribute with its own sub-attributes attached (e.g.
Namesplitting intoFirstName/MiddleName/LastName) — the parent attribute oval isn’t underlined/dashed/doubled itself unless it’s also a key/derived/multivalued attribute. - Value sets (the domain of legal values for an attribute, e.g. “integers 21-65”) are never shown on the diagram itself.
Relationship constraints
| Symbol | Meaning |
|---|---|
1, N, M on the lines into a diamond |
Cardinality ratio — E1 —1— R —N— E2 reads as ratio 1:N for E1:E2 in R |
| Double line between an entity type and a diamond | Total participation of that entity type in that relationship |
| Single line | Partial participation |
See relationship-constraints for what each ratio and each participation constraint actually asserts.
Subclasses / superclasses (EER)
A subclass is drawn as an ordinary rectangle. What makes it a subclass is the ⊂ symbol on the line joining it to its superclass, not the shape of its box — a subclass box is a plain single-line rectangle, never the double-line rectangle that means weak entity. The two are entirely different ideas (a subclass inherits its superclass’s key; a weak entity has no key of its own at all) and the notation keeps them apart.
| Symbol | Meaning |
|---|---|
⊂ on the line between two entity types |
The entity type on the closed (narrow) side of the ⊂ is a subclass of the one on the open (wide) side — read it as the set-inclusion symbol, subclass ⊂ superclass |
A circle joining several subclass lines to one superclass, each line carrying its own ⊂ opening towards the circle |
Several entity types are all subclasses of the same superclass |
d inside that circle |
Disjoint specialisation — an entity instance can belong to at most one of the subclasses |
o inside that circle |
Overlapping specialisation — an entity instance can belong to more than one subclass at once |
| Single line from superclass to the subclass circle | Partial specialisation — not every superclass instance needs to belong to a subclass |
| Double line from superclass to the subclass circle | Total specialisation — every superclass instance must belong to at least one subclass |
Naming conventions (INFS1200/7900 style guide)
Course-specific naming standard for entities/relationships/attributes on ER and EER diagrams (distinct from — and in addition to — the mandatory notation above):
- Entity names: capitalised, no spaces, ideally one word (e.g.
STUDENT,POLICEOFFICER— notPoliceOfficer). - Relationship names: capitalised, no spaces, ideally one word, preferably a verb (e.g.
CREATES,ACTSIN— notLeadActor). - Attribute names: UpperCamelCase — first letter of each word capitalised, no spaces, acronym letters stay capitalised (e.g.
ComputerIP,DateOfBirth— notDate of Birth).
How diagrams are drawn in these notes
Diagrams in this course’s notes are drawn as Mermaid flowchart graphs (renders in both PDF and HTML), using shapes chosen to match the Chen notation above as closely as Mermaid’s flowchart shapes allow:
| Mermaid shape | Used for |
|---|---|
[Entity] (rectangle) |
Entity type — and subclasses, which are ordinary rectangles |
[[WeakEntity]] (subroutine, double vertical bars) |
Weak entity type, and nothing else |
{Relationship} (diamond/rhombus) |
Relationship type |
([Attribute]) (stadium) |
Attribute |
((d)) / ((o)) (small circle) |
Disjoint/overlapping specialisation marker |
The [[X]] shape is reserved for weak entity types. Drawing an EER subclass with it is a notation error, not a stylistic one: it renders the double-line box that the official notation uses for a weak entity, and so asserts the opposite of what a subclass is. Subclasses are plain [X] rectangles; their subclass-ness is carried by the edge into the ((d)) or ((o)) circle, exactly as the ⊂ carries it in the hand-drawn notation.
Since Mermaid can’t reliably underline/dash node text across renderers, attribute qualifiers are written as a plain-text suffix instead: (key), (partial key), (derived), (multi). Composite attributes are drawn as a parent attribute node connected to its component attribute nodes. Cardinality is a text label on the edge ("1", "N", "M"); total participation/identifying relationships use a thick edge (===/==>), partial participation uses a thin edge (---/-->).
Any diagram with more than ~6-8 nodes needs an explicit %%| fig-width: cell option (in inches) or it runs off the right edge of the PDF page - mermaid sizes itself from the diagram’s own SVG bounding box, and there’s no project-wide default that reaches it (a document/project fig-width only applies to executed-code-cell figures, e.g. matplotlib). 5.5 fits this vault’s PDF page width (scrartcl, DIV=11, letter) comfortably:
```{mermaid}
%%| fig-width: 5.5
flowchart TD
    ...
```
ER to Relational Mapping
The (7+1)-step algorithm that converts a conceptual ER/EER diagram into a logical relational schema — input: an ER model; output: relations with primary and foreign key constraints. Introduced in 2026-03-16-er-to-relational-mapping and practised in week5-tutorial-applied-class-4-entity-relationship-mapping and week4-tutorial-case-study-3-dirt-road-driving. See relational-mapping-notation for the notation and naming style used throughout, er-diagram-notation for the diagram being mapped from, and er-mapping-pitfalls for the mistakes to check for afterwards.
Why map at all
The ER model is used for conceptual design — the user’s perspective, good for talking to stakeholders about entities and relationships. The relational model is what commercial DBMSs actually implement — the storage perspective. Mapping is the bridge: every construct that the ER model can draw has to be re-expressed using only relations, primary keys and foreign-keys, because those are the only tools the relational model has (see relational-model).
The steps at a glance
| # | Construct | Produces |
|---|---|---|
| 1 | Strong entity type | A new relation |
| 2 | Weak entity type | A new relation, keyed on owner’s key + partial key |
| 3 | Binary 1:1 relationship | A foreign key on one side |
| 4 | Binary 1:N relationship | A foreign key on the N side |
| 5 | Binary M:N relationship | A new relation |
| 6 | Multivalued attribute | A new relation |
| 7 | N-ary relationship | A new relation — except 1:1:1 and N:1:1, which take foreign keys instead |
| +1 | Subclass (EER) | A new relation per subclass |
Only steps 1, 2, 5, 6, 7 and +1 create relations; steps 3 and 4 only add foreign keys to relations that already exist, and step 7 does the same in its two excluded cases. Working in order matters, because every later step needs the primary keys that earlier steps established.
The running example below is the Company database: EMPLOYEE (key Ssn, composite Name → Fname/Mit/Lname, Sex, Salary, Address, DOB), DEPARTMENT (keys Dnumber/Dname, derived NumberOfEmployees, multivalued Locations), PROJECT (keys Pno/Pname, Plocation), and the weak entity DEPENDENT (partial key DepName), with relationships WORKSFOR (EMPLOYEE N:1 DEPARTMENT), MANAGES (EMPLOYEE 1:1 DEPARTMENT, attribute StartDate), CONTROLS (DEPARTMENT 1:N PROJECT), WORKSON (EMPLOYEE M:N PROJECT, attribute Hours), SUPERVISION (EMPLOYEE recursive 1:N), DEPENDENTSOF (identifying), and EMPLOYEE disjointly specialising into SECRETARY/ENGINEER.
Step 1 — Strong entity types
For each strong (non-weak) entity type: create a relation, choose one of its keys as the primary key, and include all simple attributes.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary]

Department [dNumber, dName]

Project [pNo, pName, pLocation]
Three attribute kinds are deliberately not copied across as columns:
- Composite attributes contribute their simple components instead —
Namenever appears,fName/mIt/lNamedo. - Derived attributes are never stored at all —
NumberOfEmployeesis computed on demand, so storing it would only create an opportunity for it to go stale. - Multivalued attributes can’t be stored in an atomic column and are deferred to step 6 —
Locationsis missing fromDepartmentfor now.
Where an entity has several keys (DEPARTMENT has both Dnumber and Dname), one becomes the primary key and the others are simply ordinary attributes in the relational schema — see relational-keys.
Step 2 — Weak entity types
For each weak entity type: create a relation whose primary key is the owner’s primary key plus the weak entity’s partial key; add a foreign key from the inherited part back to the owner; include all simple attributes.
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssnDependent’s full key is (ssn, depName): ssn is Employee’s key inherited through the identifying relationship, depName is the partial key (see relationship-constraints). Note what does not happen — the identifying relationship DEPENDENTSOF gets no relation of its own; it is entirely represented by the inherited key.
If a weak entity has more than one owner, the rule generalises rather than changes: include as foreign keys the primary key attributes of every owner entity type, and make the primary key the combination of all of them plus the partial key. For a weak W (partial key a1) owned by both E1 (key b1) and E2 (key c1):
E1 [b1]

E2 [c1]

W [a1, b1, c1]
W.b1 references E1.b1
W.c1 references E2.c1
All three columns are underlined as one key; both inherited keys are foreign keys in their own right.
When the owner’s own key is composite, the foreign key is composite too. In the Bank example, BRANCH is a weak entity owned by BANK (branchNo is only unique within a bank):
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code
Step 3 — Binary 1:1 relationships
For each binary 1:1 relationship: pick one participating entity type, add a foreign key there referencing the other’s primary key, and put the relationship’s own simple attributes on that same chosen side.
Preference is given to entity types with total participation (relationship-constraints) — it is part of the rule, not a stylistic tip. In the generic case, with T the totally-participating side (double line) and c1 the relationship’s own attribute:
S [a1, a2]

T [b1, b2, a1, c1]
T.a1 references S.a1
If every department must have a manager but not every employee manages, then putting the foreign key on Department gives a value in every row, whereas putting it on Employee would leave it null for almost everyone (sql-nulls). MANAGES is drawn with the double line on the DEPARTMENT side, so DEPARTMENT is the chosen side:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn
mgrStartDate is MANAGES’s own attribute, and travels with the foreign key. The foreign key is a plain attribute here, not part of Department’s key.
Both landed columns are renamed on arrival — Employee.ssn becomes mgrSSN, StartDate becomes mgrStartDate — and the same happens in step 4 (Dnumber → dNumber in Employee, Ssn → superSSN for SUPERVISION). Renaming an inherited attribute to say what role it plays in its new relation is expected, and is the standard fix when the imported name would collide with one already there.
Step 4 — Binary 1:N relationships
For each binary 1:N relationship that isn’t an identifying relationship: find the entity type on the N side, add a foreign key there referencing the primary key of the entity type on the 1 side, and put the relationship’s own simple attributes on the N side too.
The direction is forced, not chosen: one row on the N side relates to exactly one row on the 1 side, so a single foreign key column can hold it. The other direction would need many values in one cell.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber
SUPERVISION is recursive, and is handled exactly like any other 1:N relationship — the N-side role (supervisee) carries a foreign key back to the 1-side role (supervisor) in the same relation.
Step 5 — Binary M:N relationships
For each binary M:N relationship: create a new relation; give it foreign keys to both participants’ primary keys; the combination of those foreign keys is its primary key; add the relationship’s own simple attributes.
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo
A new relation is unavoidable here: neither side can hold a single foreign key value, since both sides relate to many rows of the other.
One wrinkle the Company example doesn’t show: the relationship may bring a key attribute of its own, and if it does, that attribute joins the primary key rather than sitting outside it. For an M:N R between S and T carrying an underlined c1 and a plain c2:
S [a1, a2]

T [b1, b2]

R [a1, b1, c1, c2]
R.a1 references S.a1
R.b1 references T.b1R’s key is (a1, b1, c1) — the pair of foreign keys plus c1. This is how a relationship that can repeat between the same two entities (the same employee working on the same project in several different years, say) gets modelled without a duplicate-key clash.
1:1 and 1:N relationships may also be mapped this way, and it is worth doing when the relationship is sparse — a separate relation stores only the rows that actually participate, instead of leaving a null foreign key in every row that doesn’t. In the standard implementation the foreign key column is mostly nulls, while the M:N implementation holds one short relation of just the participating pairs, and no nulls at all.
Step 6 — Multivalued attributes
For each multivalued attribute: create a new relation containing a foreign key to the owning entity’s primary key plus the attribute itself; the primary key is the combination of the two. If the multivalued attribute is composite, include its simple components instead of the attribute itself.
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Keying on both columns is what allows one department to have many locations while forbidding the same location twice. If the owning relation’s key is itself composite, the foreign key here is composite — in the cinema example the snack relation carries all four columns of Viewing’s key:
ViewingSnack [name, id, date, time, snack]
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}
Step 7 — N-ary relationships
For each N-ary relationship type — excluding the 1:1:1 and N:1:1 cases, which are handled separately below: create a new relation; give it foreign keys to the primary key of every participating entity type; the foreign keys from the participants with many cardinality form the primary key; the relationship’s own attributes may also contribute to that key; add its remaining simple attributes.
One relation body covers every non-excluded case, and only the underline moves. For a ternary R over E1, E2 and E3, with own attributes d1 and d2:
E1 [a1]

E2 [b1]

E3 [c1]

R [a1, b1, c1, d1, d2]
R.a1 references E1.a1
R.b1 references E2.b1
R.c1 references E3.c1| Cardinalities | Primary key of R |
|---|---|
N:M:P — every participant many |
All three foreign keys, (a1, b1, c1) |
N:M:1 |
The two many-side foreign keys (a1, b1); c1 is a plain attribute |
N:M:1 with d1 an underlined attribute of R |
(a1, b1, d1) — the relationship’s own key attribute joins them |
Every participant is always represented, whatever its cardinality: a 1-side foreign key is present but outside the key. For a ternary K over H (role N), A (role M) and P (role 1), with own attribute l, that gives
K [b, i, q, l]
K.b references A.b
K.i references H.i
K.q references P.q
with only b and i underlined. The Company database contains no N-ary relationship — WORKSON is binary.
The excluded cases — 1:1:1 and N:1:1
These get no new relation at all. With at most one participant on a many side, there is no combination of foreign keys that would make a key, and the relationship can be absorbed exactly as in steps 3 and 4: one participating relation takes a foreign key to each of the others, plus the relationship’s own attributes.
- N:1:1 — the entity type on the
Nside is the one that takes them, and the choice is forced, since only its rows relate to exactly one row of each other participant:
E1 [a1, b1, c1, d1]
E1.b1 references E2.b1
E1.c1 references E3.c1

E2 [b1]

E3 [c1]- 1:1:1 — nothing forces the direction, so choose a participant the same way step 3 does, preferring total participation, and put both foreign keys and the relationship’s attributes there. The schema looks identical to the N:1:1 one above; only the reason for picking
E1differs.
The giveaway that a question is testing this exclusion is a ternary diamond with at most one N on its edges: count the many sides before reaching for a new relation, because with fewer than two of them there is nothing to key it on.
Step +1 — Subclasses (EER)
For each subclass (specialisation-and-generalisation): create a relation whose primary key is the superclass’s primary key; add a foreign key from it back to the superclass relation; include the subclass’s own simple attributes. The same rule works for every combination of total/partial and disjoint/overlapping specialisation.
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn
A subclass with no attributes of its own still gets a relation — it is the row’s membership in that subclass that is being recorded.
This step has no fixed position in the sequence. It is done straight after step 1 or 2 (whichever created the superclass), specifically so the subclass relations exist by the time a later relationship step needs to reference one — and relationships drawn to a subclass must reference the subclass relation, not the superclass.
Final schema — Company database
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber

Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn

Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn

WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo

DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Eight relations: the three strong entity types became three, the weak entity one, the two subclasses two, the M:N relationship one, and the multivalued attribute one — while all four of the 1:1 and 1:N relationships (MANAGES, WORKSFOR, CONTROLS, SUPERVISION) became nothing more than foreign key columns on relations that already existed.
Second worked example — Bank database
The other complete run-through is the bank: a BANK (unique Code, Name, HOAddr) has several branches; a BANK-BRANCH has a BranchNo unique only within its bank, so it is weak. One branch has many ACCOUNTs (ACNo, Type, Balance) and many LOANs (LoanNo, Type, Amount), and every account and loan has one or more holders drawn from CUSTOMER (SSN, Name, Addr) — two M:N relationships, AHOLDER and LHOLDER.
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code

Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Customer [ssn, name, address]

AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Two things are worth reading off this schema. First, a weak entity’s composite key propagates: because Branch is keyed on (bankCode, branchNo), every 1:N foreign key drawn from Branch is composite too. Second, it propagates as a plain column — Account has its own key acNo, so bankCode and branchNo sit outside Account’s primary key, exactly as step 4 requires. AccountHolder and LoanHolder, by contrast, have no key of their own and are keyed on their pair of foreign keys.
The result is a logical schema, ready to be implemented with sql-ddl and checked for redundancy with normal-forms. Whether each inherited foreign key is part of its relation’s primary key — the question that decides most of the answers above — is tabulated in foreign-keys.
Integrity Constraints
Integrity constraints are the rules that enforce the correctness of a database: conditions stated on the schema that must hold on every instance of it. A DBMS’s job is to reject any operation that would leave them unsatisfied. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and practised in week4-tutorial-applied-class-3-relational-integrity; these are constraints on a relational schema, distinct from the relationship-constraints placed on an ER diagram.
The five kinds
| Constraint | Violated when | Enforced by |
|---|---|---|
| Domain | An attribute’s value isn’t a member of its domain | The column’s declared type/format |
| Key | Two tuples share the same value for a key | The declared key |
| Entity integrity | Any part of a tuple’s primary key is NULL |
The declared primary key |
| Referential integrity | A non-null foreign key value matches no primary key value in the referenced relation | The declared foreign key |
| Semantic | A business rule that isn’t derivable from the schema’s structure is broken | Application-level rules — triggers, assertions, CHECK |
The first four are structural: they follow from the schema itself, so the DBMS enforces them for free once the types and keys are declared. The fifth is not — nothing in the schema’s shape implies it, so it has to be stated separately.
Enforcement is unconditional and the default outcome is refusal: any insert, modification or deletion submitted to the DBMS that would violate integrity — that would leave the database in an inconsistent state — must be rejected. The only constraint whose violation has other sanctioned outcomes is referential integrity on a delete, and only because the foreign key was declared with a policy saying so (see update-operations-and-constraint-violations).
Which operation can break which constraint is not symmetric, and the asymmetry is examinable:
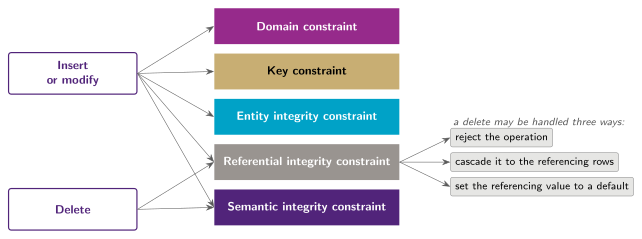
Figure 11: Insert and modify can violate all five constraints; delete can only violate the last two, and a referential violation on delete has three sanctioned outcomes rather than one. The banner colours are the course’s fixed fills for the five constraint types.
A delete cannot break a domain, key or entity-integrity constraint because it adds no value and duplicates no key — it can only strand something that was pointing at the row it removed, or break a business rule about what must continue to exist.
Domain constraint
The domain is the set of legal atomic values for an attribute (see relational-model), so a domain violation is simply a value that isn’t in that set. Employee.id = "LOL" violates it when id is a four-digit integer.
The domain need not be a plain data type — a format counts. A bank rejecting the password password123 with “your password must contain at least one capital letter and a number” is enforcing a domain constraint: the domain of password is defined as the strings matching that format, and password123 isn’t a member of it. Likewise a course code declared as four letters followed by four digits, or an enumerated domain: inserting VehiclePurpose = 'Personal' when the column is ENUM('Private', 'Business') is a domain violation, not a semantic one.
The commonest exam version of a domain violation is subtler — a value of the wrong kind in the right position. Inserting (2644, James, Smith, 1) into Employee [id, name, salary, department] breaks the domain constraint because the third value lands in salary, whose domain is integer or float, not a surname.
Key constraint
No two tuples may share a value for a key. Violated by inserting a tuple whose key duplicates an existing one, or by modifying an existing tuple into a duplicate. See relational-keys for what qualifies as a key in the first place.
Entity integrity constraint
No part of a primary key may be NULL — for a composite primary key, no component may be null, not merely “not all of them”. Inserting (677678989, null, 40.0) into WorksOn [essn, pNo, hours] violates entity integrity because pNo is half of the primary key.
The rationale is that the primary key is the relation’s identity: a tuple with an unknown key value cannot be distinguished from, or referred to by, anything. This is the one place a NULL is categorically banned — sql-nulls has the table of which declarations do and don’t permit one.
Referential integrity constraint
A non-null foreign key value must match some existing primary key value in the referenced relation. Inserting an Employee with department = 5 when no Department has id = 5 violates it; so does deleting Department 5 while employees still reference it, and so does updating a foreign key to a value that doesn’t exist. NULL is always allowed — see foreign-keys for the formal statement.
Semantic (business-rule) constraint
Semantic constraints are defined by the business or organisation during client consultation — they come from the organisation, not from the data structure:
- “An employee’s salary must not exceed their supervisor’s.”
- “The maximum number of hours an employee can work on a project is 56.”
- “A department cannot have more than three active projects at a time.”
- “A customer must be at least 18 years old.”
Take the first and third. Inserting Grace Chan on 58000 with superSSN = 888665555 — James Borg, on 55000 — violates the salary rule and nothing else; inserting a fourth project for department 5, which already has ProductX, ProductY and ProductZ, violates the three-project rule and nothing else. In both cases every structural check passes, which is exactly the signal that the answer is “semantic”.
Nothing about the relations’ shape rules these out, so they’re expressed in a constraint specification language — in SQL’s case, the mechanisms are CHECK clauses, assertions and triggers. This course files the latter two under DCL, alongside transaction control and privilege management. Only CHECK is developed and examined (see sql-ddl for the CHECK and named-constraint syntax); assertions and triggers are the general-purpose fallback and are not defined further, so “enforced by an assertion or a trigger” is as far as the course goes. This is also the category to fall back on when asking “which constraint does this break?” and none of the structural four apply.
The converse matters just as much: a rule that was never stated isn’t a constraint. Updating Department (2, Development, 1751) to (2, Development, 2034) where employee 2034 works in a different department violates nothing, unless the business rule “a manager must work in the department they manage” has actually been specified.
Naming an example of each
The other exam shape is the reverse: given a schema, point at one instance of each kind of constraint. For the enrolment schema
Student [stID, name, email]

Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode

Course [cCode, title, units]
a key is stID in Student, a foreign key is stID in Enrolment, and a domain constraint is cCode being four letters followed by four digits. stID supplies both of the first two answers depending on which relation it is read in — the same attribute name is a key where it identifies and a foreign key where it refers.
Diagnosing a violation
Given an operation and a schema, work down the five in a fixed order. The order isn’t significant in itself; checking all five every time is, since one operation can break several at once.
- Domain — is every value of the right type/format for its column?
- Key — does this key value already exist?
- Entity integrity — is any part of the primary key null?
- Referential integrity — does every non-null foreign key point at a row that exists? And, for a delete, does anything still point at the row being removed?
- Semantic — does it break a stated business rule?
A single operation can violate more than one at once. Inserting ('ProductA', 'A', 'Bellaire', 2) into Project [pName, pNumber, pLocation, dNum] breaks both the domain constraint (pNumber is an integer, not 'A') and referential integrity (no department 2). Inserting ('Production', 4, 943775543, …) into Department breaks the key constraint (dNumber = 4 exists) and referential integrity (mgrSSN isn’t a real employee). Don’t stop at the first one found.
And the operations that violate nothing
Three of the applied class’s ten answers are “No”, and they are the ones worth rehearsing, because each looks like a violation and isn’t:
| Operation on the company schema | Why it is legal |
|---|---|
Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into EMPLOYEE |
Fresh ssn, every value in its domain, superSSN 888665555 and dNo 1 both exist, and 50000 is under the supervisor’s 55000 |
Delete the WORKS_ON tuples with essn = 333445555 |
Nothing references WORKS_ON, so no reference is stranded |
Modify DEPARTMENT’s mgrSSN/mgrStartDate for dNumber = 5 to 123456789 and '1988-10-01' |
123456789 is a real employee (John Smith), so the foreign key still resolves, and no other constraint touches the manager column |
Compare that last row with the case where the new manager works in a different department: it still violates nothing. A manager who works elsewhere offends intuition, not any declared constraint.
See update-operations-and-constraint-violations for which constraints each kind of operation can possibly violate, and what a DBMS does about it; sql-dml shows the same violations as the error messages MySQL actually returns.
Interpreting ER Diagrams
Drawing a diagram and reading one are different skills, and the applied classes test the second at least as hard as the first: given an ER/EER diagram and a plain-English claim about the world, decide whether the diagram actually says it. Practised in the statement-evaluation questions in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd and week3-tutorial-applied-class-2-entity-relationship-diagrams, and in the questions in 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices. See er-diagram-notation for what each symbol is.
The checklist
| If the claim is about… | Check | Trap |
|---|---|---|
| How many X per Y | The cardinality ratio, from the far side | Reading 1:N in the wrong direction |
| Whether every X does something | Participation (double vs single line) | Assuming total participation because the relationship exists |
| Uniqueness of an attribute | Whether that attribute is underlined | Treating a non-key attribute as if it were unique |
| “Only identifiable by…” | Whether a second key oval exists | Missing a second candidate key |
| A weak entity’s identity | Owner’s key + partial key | Treating the partial key as a full key |
| An instance being two kinds at once | d vs o on the specialisation circle |
Reading two separate circles as one |
| A relationship’s degree | Count the lines into the diamond | Calling a pair of binaries “ternary” |
| Whether a given relationship set is possible | Every cardinality ratio and every participation constraint, tuple by tuple | Checking the ratios and forgetting the double lines |
Cardinality: read it from the far side
A 1:N relationship constrains both ends, and the interesting constraint is usually the one on the “many” side. HEALTHWORKER —1:N OVERSEEN→ HEALTH means one health worker can oversee many participants, and therefore each participant has at most one overseeing health worker. “A participant can be overseen by several healthcare workers” is incorrect against that diagram — a claim that reads naturally in English and is contradicted by the diagram in the direction most people don’t check. See relationship-constraints.
An M:N relationship with no distinguishing attribute also says something: each pair appears at most once. An athlete/event pair in a plain PARTICIPATES relationship cannot be recorded twice, so “an athlete cannot participate at the same event more than once” is correct. Making repeats possible requires a distinguishing key attribute (a Timestamp, say) or a weak entity — see er-design-choices.
Participation: absence of a double line is a fact
Total participation (double line) says every instance must participate; partial participation (single line) says it need not. Both are claims, and the partial one is easy to skip over:
- The recursive
WITHrelationship onVACCINEis partial on both sides, so “each vaccine must have a second dose or a preceding dose” is incorrect — the relationship allows a two-dose program, it doesn’t require one. OVERSEENhas total participation on theHEALTHside, so “every participant in the HEALTH subclass is overseen by a health worker” is correct.- Some venues are backups and never host an event, which is exactly why
VENUE’s participation inHOSTSis partial — “all venues must host an event” is incorrect.
Keys: what isn’t underlined can repeat
If an attribute isn’t marked as a key, the diagram is asserting nothing about its uniqueness — so two different venues may share an Address when only ID is underlined. Conversely, HOTEL.Address being the key attribute is what makes “two hotels can share an address” false.
Claims of the form “X can only be identified by Y” need the whole attribute list checked, because entity types routinely have more than one candidate key: VACCINE has both ID and the composite Brand + Name, so “a vaccine can only be identified by the combination of its brand and name” is incorrect. See entity-types-and-attributes.
Weak entities: the partial key is not the key
A weak entity’s partial key is unique only within its owner, so any claim that treats it as globally unique is false. The hotel/room question is the canonical case: ROOM’s real key is (HOTEL.Address, ROOM.Number), so neither “no two rooms share a number” nor “no two hotels have rooms with the same number” holds — room numbers repeat freely across hotels, which is the entire reason ROOM is weak. The same logic makes “a BATCH is uniquely identified by only its number” incorrect, and makes an emergency contact named “Mum” registrable by two different users.
The hotel/room question is also a reminder that “none of the above” is a live option: with HOTEL.Address as the key and ROOM.Number as a partial key, every uniqueness claim on offer — two hotels sharing an address, no two rooms sharing a number, no two hotels having rooms with the same number — is false at once.
Checking a candidate relationship set
A second question format hands you a small diagram plus several candidate relationship sets written out as tables of tuples, and asks which one is possible. It is mechanical once you know the two things to check:
| Notation on the diagram | What it forbids in the table |
|---|---|
A 1 on E’s side of R |
An entity of E appearing in more than one row of R |
An N or M on E’s side of R |
Nothing — that side is unconstrained |
| A double line between E and R | An entity of E appearing in no row of R |
Worked instance. Take A —N— R —1— B —N— S ═M═ C, with entity sets {a₁, a₂}, {b₁, b₂} and {c₁, c₂}. The 1 on B’s side of R means each a may appear at most once in R; the double line on C’s side of S means every c must appear somewhere in S; M:N on S constrains nothing else. So:
R = ∅,S = ∅fails —c₁andc₂are missing fromS.R = {(a₁,b₁)},S = {(b₂,c₂)}fails —c₁is still missing.R = {(a₁,b₁), (a₁,b₂)}fails —a₁appears twice, violating the1.R = {(a₁,b₂)},S = {(b₁,c₂), (b₂,c₁), (b₁,c₁)}is possible — noarepeats and bothcs appear.
Note that an empty relationship set is perfectly legal wherever participation is partial; it is only the double line that forces rows to exist. That is the half of the check people skip.
Subclasses: d and o are per circle
An overlapping (o) specialisation permits an instance to be in several subclasses at once, so “a participant can be in both the HEALTH subclass and the AGE subclass” is correct when those two hang off an o circle. A disjoint (d) specialisation forbids it. The per-circle part matters: a superclass with two separate specialisation circles constrains each one independently, and membership in a subclass under one circle says nothing about membership under the other. See specialisation-and-generalisation.
Degree: count the lines
“EVENT has a ternary relationship” is incorrect when EVENT’s relationships are PARTICIPATES (to ATHLETE) and HOSTS (to VENUE) — two separate binary relationships, not one three-way one. An entity type participating in several relationships is not the same as participating in a high-degree relationship. See relationship-types.
Relationship Constraints
Constraints on a relationship type limit the possible combinations of entities that may participate in its relationship set — determined by the Universe of Discourse (UoD), not chosen arbitrarily. There are exactly two kinds, cardinality constraints and participation constraints. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model; see er-diagram-notation for the full symbol legend.
Cardinality ratio
A cardinality ratio for a relationship set specifies the number of relationships in the set that an entity can participate in. The intuition is a customer buying items: one particular customer can purchase many different items, however an individual item — this particular cake — cannot be purchased by several different customers.
| Ratio | Name | Meaning |
|---|---|---|
| 1:1 | One-to-one | Both entities can participate in only one relationship instance |
| N:1 | Many-to-one | One entity can participate in many relationship instances, the other in only one |
| 1:N | One-to-many | The same constraint, viewed from the other side |
| M:N | Many-to-many | Both entities can participate in many different relationship instances |
Three worked readings, all on the same two entity types, are worth memorising as a set because the English is nearly identical each time and only the ratio changes:
| Statement of the UoD | Ratio |
|---|---|
| “Each employee can work on any number of projects, and each project can have any number of employees working on it” | EMPLOYEE —N— WORKSON —M— PROJECT (M:N) |
| “Each department can have any number of employees, but an employee can work for at most one department” | EMPLOYEE —N— WORKSFOR —1— DEPARTMENT (N:1) |
| “Each department can have at most one manager and each employee can manage at most one department” | EMPLOYEE —1— MANAGES —1— DEPARTMENT (1:1) |
Note where the N sits in the second row: on the EMPLOYEE side, because it is employees that are many. Reading the label on the wrong end is the standard error — see interpreting-er-diagrams.
Participation constraint (existence dependency)
The course’s own name for the participation constraint is existence dependency: it indicates whether the existence of an entity depends on its relationship to another entity — i.e. whether every instance of the entity type must participate in at least one relationship instance.
- Total participation (double line in the diagram) — every entity instance must participate. “Every employee must work for a department” makes
EMPLOYEEtotally participate inWORKSFOR, and the phrasing to use is thatEMPLOYEEis existentially dependent onDEPARTMENTvia theWORKSFORrelationship type. - Partial participation (single line) — an entity instance is not required to participate. “Every employee can manage 0 or more departments” makes
EMPLOYEE’s participation inMANAGESpartial.
The two ends are constrained independently, and MANAGES is the example that shows it: EMPLOYEE participates partially (most employees manage nothing) while DEPARTMENT participates totally (every department must have a manager), so DEPARTMENT is existentially dependent on EMPLOYEE via MANAGES and not the other way round.
Why the participation constraint is worth getting right
It is not just documentation: it decides where a foreign key ends up. The Module 2 mapping rule for a binary 1:1 relationship says to pick one of the two participating entity types and give it the foreign key, and that preference is given to entity types with total participation. MANAGES is exactly that case — because DEPARTMENT totally participates, the mapping extends Department with mgrSSN (plus the relationship’s own startDate, renamed mgrStartDate) rather than putting a department reference in Employee, which would be null for almost every employee. The mirror-image answer fails for precisely this reason: given S ═1═ R ─1─ T, putting the foreign key in T is wrong, because S has full participation and is preferred over T. See er-to-relational-mapping for the rule in full.
Weak entities
An entity type with no key attribute of its own is a weak entity — it can be identified uniquely only by considering the primary key of another owner entity together with its own partial key (underlined with a dotted line). The relationship type that relates a weak entity to its owner is the identifying relationship, and the weak entity always has total participation in it: it cannot exist without its owner. Both the weak entity box and the identifying relationship diamond are drawn with double lines.
An example is an EMPLOYEE (key SSN) who INSURES a DEPENDANT (partial key Pname, plus Age), 1:N, with Cost as a descriptive attribute on the identifying relationship. Two different employees can each insure a dependant named John, which is precisely why Pname cannot be a key on its own — the identity of a dependant is (SSN, Pname).
Provinces and cities have the same shape, and it is the compact example to memorise because all three notations — cardinality, participation and partial key — are on it at once:
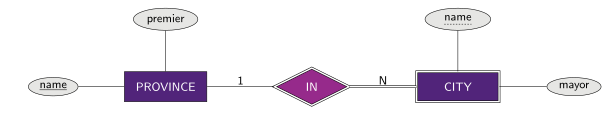
Figure 12: A weak entity in full notation. CITY is weak (double box) with the partial key name (dash-underlined); IN is the identifying relationship (double diamond); the CITY–IN edge is doubled for CITY’s total participation, and the ratio is 1:N, so one province holds many cities. PROVINCE’s own name is a full key (solid underline). Entity boxes are purple, relationship diamonds magenta and attribute ovals grey.
The two names do different jobs. PROVINCE.name identifies a province outright; CITY.name identifies a city only within a province, so the mapped Cities relation needs a pName column as part of its primary key and as a foreign key to Provinces — the mapping is Cities [cName, pName, mayor] with Cities.pName references Provinces.pName, and the wrong mappings are the ones that drop pName from the key, make cName a foreign key, or turn the identifying relationship IN into a relation of its own. See er-to-relational-mapping for the mapping rule that produces this.
A weak entity can have two (or more) owner entity types, in which case the identifying relationship is n-ary rather than binary. The generic version shows how the constraints are placed in that case — many weak entities per combination of owners, one owner of each kind per weak entity:
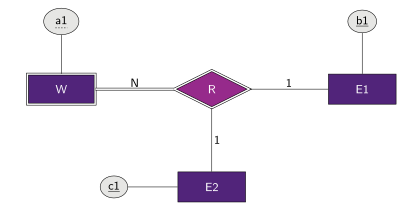
Figure 13: A weak entity with two owner entity types. The identifying relationship R is ternary: N on the weak side, 1 towards each owner, with the double edge marking W‘s total participation. W’s identity is its partial key a1 plus both owners’ keys, which is why the mapped relation is W [a1, b1, c1] with b1 and c1 as foreign keys.
INTERVIEW is the worked case: it is owned by both CANDIDATE and COMPANY, so the identifying relationship APPLIES is ternary, and INTERVIEW’s composite partial key Details (Department, Date) only distinguishes interviews within one candidate/company pair. INTERVIEW is a full entity type despite being weak, so it can carry relationships of its own — it RESULTSIN a JOB OFFER. See er-design-choices for the decision that produced it and interpreting-er-diagrams for the claims it makes false.
Relationship Types
The other half of an ER diagram: the associations between entity types. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week3-tutorial-applied-class-2-entity-relationship-diagrams; see er-diagram-notation for the symbols and entity-types-and-attributes for what sits at each end.
Relationship, relationship type, relationship set
The same schema/instance split as entity types:
| Term | Meaning |
|---|---|
| Relationship | An association among two or more entities — “Paris Lane works on the project FileZilla” |
| Relationship type | The definition of that association, drawn as a diamond connected to the participating entity types |
| Relationship set | The collection of all relationships of one relationship type in the database at any point in time |
A relationship set can be drawn as lines between two ovals of entities, or written out as a table of pairs — WORKSON as rows (e1, p1), (e2, p1), (e2, p4), and so on. The tabular form is the one exam questions use when they ask whether a given relationship set is possible under a diagram’s constraints; see interpreting-er-diagrams.
A relationship type may carry its own descriptive attributes, which belong to the pairing rather than to either entity on its own — EMPLOYEE WORKSON PROJECT hangs StartDate and EndDate off the diamond, because a start date belongs to one employee’s stint on one project and to nothing else. A Grade belongs to the enrolment of one student in one course, not to the student and not to the course. Other examples across the notes: a Placement on PARTICIPATES (athlete/event), a Fee on CONSULTS (patient/doctor), a PrepTime on BUYS (customer/bubble tea).
A relationship type may also carry key attributes of its own — on WORKSON it is StartDate that is underlined, which says one employee cannot start on the same project twice on the same day. The Timestamp that distinguishes repeat orders on BUYS does the same job.
Degree
The degree of a relationship type is the number of participating entity types:
| Degree | Name | Example |
|---|---|---|
| 2 | Binary | DEPARTMENT WORKSFOR EMPLOYEE |
| 3 | Ternary | SUPPLIER / PROJECT / PART in one SUPPLIES diamond |
| \(n\) | n-ary | The general case, 3+ entity types |
Degree is decided by counting the lines into the diamond, and it is a real design decision rather than a description — the same UoD can often be modelled as one ternary relationship or as three binary ones, with different consequences. See er-design-choices.
Roles
Each entity type that participates in a relationship type plays a particular role in it. The role name signifies the role a participating entity from that entity type plays in each relationship instance — that is to say, it explains what the relationship means. DEPARTMENT is the Employer and EMPLOYEE is the Worker in WORKSFOR, the relationship between those two entity types. WORKSON is a different relationship: the M:N EMPLOYEE/PROJECT one (relationship-constraints, er-to-relational-mapping).
Roles are optional labelling on an ordinary binary relationship between two different entity types, where the meaning is usually obvious from the names — but they become mandatory in the recursive case below, where they’re the only thing distinguishing the two ends.
Recursive relationships
The same entity type can participate more than once in one relationship type, under different roles — an EMPLOYEE who MANAGES another EMPLOYEE. Both lines run from the same rectangle back to the same diamond, so the role labels carry all of the meaning:
flowchart LR
    EMPLOYEE[EMPLOYEE] ---|"1 Manager"| MANAGES{MANAGES}
    MANAGES ---|"N Subordinate"| EMPLOYEE
Two different relationships share the name MANAGES, and they are not the same thing: this recursive EMPLOYEE/EMPLOYEE one, and the 1:1 EMPLOYEE/DEPARTMENT one that records who runs each department (relationship-constraints, and the mgrSSN foreign key in er-to-relational-mapping). The recursive relationship is also named SUPERVISION in the company diagram used for mapping, and that is the name used for it elsewhere in these notes.
Recursive relationships turn up constantly once you start looking, and they take every cardinality:
| Relationship | Roles | Ratio |
|---|---|---|
EMPLOYEE SUPERVISION EMPLOYEE |
supervisor / supervisee | 1:N |
COURSE PREREQUISITE COURSE |
higher / requires | M:N |
CUSTOMER FRIENDS CUSTOMER |
Requestor / Requestee | M:N |
VACCINE WITH VACCINE |
First / Second | partial on both sides |
NON-WIN SEQUEL NON-WIN |
PrequelTo / SequelTo | 1:1 |
The WITH example from week3-tutorial-applied-class-2-entity-relationship-diagrams is the instructive one: because participation is partial on both sides, the relationship records that a vaccine may be part of a two-dose program — it does not assert that every vaccine has a second dose. Reading a recursive relationship as if it were total is a standard trap.
Constraints
Cardinality ratio (1:1, 1:N, M:N) and participation (total/partial) are covered in relationship-constraints; how to read a claim off them without tripping over the direction is covered in interpreting-er-diagrams.
What happens to a relationship on mapping
The relationship type’s cardinality decides its fate in the relational schema. An M:N relationship becomes its own relation, combining both sides’ foreign keys into one composite primary key (relational-keys), plus any descriptive attributes it carried — UserRatesDriver [userID, driverID, rating] in week4-tutorial-case-study-3-dirt-road-driving. A 1:N relationship doesn’t need a relation of its own; it shows up as a foreign key on the N side, the way EmergencyContact.userID carries the User/EmergencyContact link in the same schema. The full set of rules is in er-to-relational-mapping.
Specialisation and Generalisation
The Enhanced ER (EER) model’s one big addition to plain ER: the ability to say that one entity type is a kind of another. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices; see er-diagram-notation for the notation.
Classes, superclasses and subclasses
In the EER model an entity type is called a class, and entities in the same class share the same attributes. A class can be a superclass or a subclass of another:
- Attributes of a superclass are inherited by its subclasses, and a subclass can add its own specific attributes and its own specific relationships on top.
- Every entity in a subclass is also a member of its superclass(es). The subclass never holds entities the superclass doesn’t.
The motivating example is a supermarket ITEM (ProductName, Price) versus a FOOD item, which is just an ITEM that additionally records an ExpiryDate. Modelling FOOD as a subclass says exactly that — it is an extension of a regular item, not a separate thing that happens to look similar.
Two directions, one relationship
Specialisation and generalisation describe the same superclass/ subclass structure discovered from opposite ends:
| Direction | Starting point | Move | |
|---|---|---|---|
| Specialisation | Top-down | One existing entity type | Define a number of subclasses of it, each containing a subset of the superclass’s entities, on the basis of a more specific distinguishing characteristic |
| Generalisation | Bottom-up | Several existing entity types | Abstraction — ignore the differences amongst the subclasses and generalise them into a common superclass |
The two are duals, not alternatives: the subclasses are a specialisation of the superclass, and the superclass is a generalisation of the subclasses. Which word you use just records how you arrived at the diagram.
Constraints on a specialisation
Two independent constraints apply to every specialisation, and both come from the UoD rather than from preference. They are stated over different things: a specialisation may be total or partial, while the subclass sets may be overlapping or disjoint.
| Constraint | Applies to | Options | Question it answers |
|---|---|---|---|
| Completeness | The specialisation | Total (double line) vs partial (single line) | Must every superclass entity belong to some subclass? |
| Disjointness | The subclass sets | Disjoint (d) vs overlapping (o) |
Can one superclass entity belong to more than one subclass at once? |
Worked readings from the tutorials:
DOCTORspecialises disjointly intoGP/SPECIALIST— “each doctor is either a GP or a specialist, never both”.PARTICIPANTspecialises into overlappingHEALTH/AGEsubclasses — a participant can legitimately be in both at once.STAFFspecialises into overlappingDRIVER/ADMINin week2-tutorial-case-study-1-dirt-road-driving, because a staff member at a small rideshare company can be both at once. Getting this one wrong as disjoint would silently forbid a perfectly ordinary real employee.
flowchart TD
    STAFF[STAFF] --- o1(("o"))
    o1 --- DRIVER[DRIVER]
    o1 --- ADMIN[ADMIN]
    Licence(["Licence"]) --- DRIVER
    DeskNumber(["DeskNumber"]) --- ADMIN
One superclass, several independent specialisations
A superclass can be specialised more than once, along different characteristics, each with its own circle and its own independent pair of constraints. The canonical case is EMPLOYEE carrying two specialisations side by side:
| Specialisation | Subclasses | Disjointness | Completeness |
|---|---|---|---|
| Documents held | PASSPORT / DRIVERLICENSE |
Overlapping (o) |
Partial (single line) |
| How they are paid | HOURLY / SALARY |
Disjoint (d) |
Total (double line) |
All four boxes are ordinary subclasses of EMPLOYEE — none of them is a category or a union type, and each is drawn as a plain rectangle. The o on the left circle is what permits an employee to hold a passport and a driver licence; the single line into it permits one to hold neither. The d on the right circle forbids an employee from being both hourly and salaried, and the double line into it requires every employee to be one or the other. The two circles say nothing about each other: an hourly employee is neither more nor less likely to hold a passport.
flowchart TD
    EMPLOYEE[EMPLOYEE] --- o1(("o"))
    EMPLOYEE === d1(("d"))
    o1 --- PASSPORT[PASSPORT]
    o1 --- DRIVERLICENSE[DRIVERLICENSE]
    d1 --- HOURLY[HOURLY]
    d1 --- SALARY[SALARY]
The same structure turns up elsewhere: GAME in week1-lab-practical-1-course-tools splits disjointly into SINGLEPLAYER / MULTIPLAYER (how it’s played) and, separately, disjointly into WINNABLE / NON-WIN (whether it can be won) — four subclasses, but two unrelated specialisations. EMPLOYEE is also specialised disjointly into SECRETARY / ENGINEER (with TypingSpeed and EngineerDetails respectively) in the running company diagram, which is a third, separate characteristic again.
Reading two circles as one is a common misreading: subclasses under different circles say nothing about each other, so disjointness in one specialisation places no restriction on membership in the other. See interpreting-er-diagrams for the statement-evaluation version of this trap.
Subclasses carry their own relationships
Because a subclass is a full entity type in its own right, relationships can attach to it directly, and this is often the whole point of creating it. SPECIALIST (not DOCTOR) is what RUNS a SPECIALIST CLINIC, and HEALTHWORKER oversees HEALTH participants specifically, not every PARTICIPANT. Attaching a relationship at the subclass level rather than the superclass level is itself a design decision — see er-design-choices.
What happens on mapping
Each subclass becomes its own relation whose primary key is the superclass’s key, plus a foreign key back to the superclass — Driver [id, licence] with Driver.id references Staff.id. The subclass relation holds only its own specific attributes: repeating the superclass’s attributes there (e.g. copying make/model from Vehicles onto 4WD) is a mapping error, since it wastes space and lets the two copies drift apart. See step +1 of er-to-relational-mapping, er-mapping-pitfalls for the rest of the subclass mistakes, and week4-tutorial-case-study-3-dirt-road-driving.
NULLs in SQL
NULL is the special value a relational attribute takes when there is no ordinary value to store — it represents an inapplicable, unknown or missing value rather than zero or the empty string. Because a null is not a value in the attribute’s domain, it needs its own handling everywhere it appears: in constraints, in WHERE conditions, and in the results a query produces. Defined in 2026-02-23-conceptual-database-design-and-the-er-model, constrained in 2026-03-09-the-relational-model-and-integrity-constraints, and handled in SQL from 2026-03-30-basic-sql-ddl-and-dml onwards.
Which constraints permit a null
| Declaration | Nulls allowed? |
|---|---|
PRIMARY KEY |
No — a primary key value is unique and not null; for a composite key, no part of it may be null (entity integrity) |
FOREIGN KEY |
Yes — a foreign key value must either be null, or match an existing row of the referenced relation (referential integrity) |
UNIQUE |
Yes — the value must be unique or null; this is the one difference from a primary key |
NOT NULL |
No — a value must be supplied |
See integrity-constraints for the underlying entity and referential integrity rules, relational-keys and foreign-keys for what the keys themselves are, and sql-ddl for how each is declared.
The nullable foreign key is what makes several mappings work at all: an employee with no manager, or a department with no manager assigned yet, is represented by a null foreign key rather than by a missing row. It is also why er-to-relational-mapping prefers to hang a 1:1 foreign key off the total-participation side — the other side would be null for almost every row.
Testing for a null
NULL is tested with IS, never with =. IS sits alongside LIKE, IN and BETWEEN in the course’s catalogue of things a WHERE search condition may contain (sql-select-statement):
SELECT * FROM Employee WHERE dNum IS NULL;
SELECT * FROM Employee WHERE dNum IS NOT NULL;
This shows up inside subqueries as well as at the top level — here, restricting the result to employees whose department currently has a manager assigned:
SELECT name, dNum
FROM   Employee e
WHERE  EXISTS (
    SELECT * FROM Department d
    WHERE  d.dNumber = e.dNum AND d.mgrSSN IS NOT NULL
);
An explicit IS NOT NULL is also the usual guard before grouping or building a derived value out of several columns, so that rows with missing components are excluded rather than silently contributing:
-- Last names shared by more than one employee, ignoring unknown names
SELECT   DISTINCT LastName FROM Employee
WHERE    LastName IS NOT NULL
GROUP BY LastName
HAVING   COUNT(FirstName) > 1;

-- Build FirstName-LastName-yyyy only where all three parts exist
SELECT CONCAT(FirstName, '-', LastName, '-', YEAR(DOB))
FROM   Employee
WHERE  FirstName IS NOT NULL
  AND  LastName  IS NOT NULL
  AND  DOB       IS NOT NULL;
The limits of what the course specifies
Module 3 treats nulls operationally rather than logically. It gives the IS operator, the constraint rules above, and the places a null can come from — and it stops there. The lectures do not develop a three-valued logic of TRUE/FALSE/UNKNOWN, do not state how an aggregate function treats the nulls inside a group, and do not cover what happens when a NOT IN subquery returns a null among its values. Those questions are simply not settled by the material, so don’t reason from a rule the course never gave you.
What the course does teach is the defensive habit: write the IS NOT NULL guard explicitly wherever a null could reach a comparison, a grouping, or a derived value, rather than relying on the DBMS to do something sensible with it. Every example above follows that habit.
Where nulls come from
Not every null is data someone failed to enter — several are created by the schema or the query itself:
| Source | Why |
|---|---|
| A genuinely inapplicable/unknown/missing value | The original meaning of a null |
ALTER TABLE … ADD <column> |
Every existing row gets a null in the new column — which is exactly why the new column cannot be declared NOT NULL (sql-ddl) |
ON DELETE SET NULL |
The referential action deliberately clears the link instead of deleting the dependent rows (update-operations-and-constraint-violations) |
| An outer join | Unmatched rows are padded with nulls in the columns of the table that had no match (sql-joins) |
| Access-control masking | A cell above a user’s clearance is presented to them as null rather than withheld (database-access-control) |
The last two matter when reading results: a null in the output of a LEFT JOIN means “no matching row existed”, which is information about the relationship, not about the row’s stored data.
-- Departments with no manager still appear, with NULL for the name
SELECT    D.dName, E.name
FROM      Department AS D
LEFT JOIN Employee AS E ON D.mgrSSN = E.ssn;
Nulls as a design smell
A schema that produces many nulls is usually telling you something. Reducing the number of null values in tuples is guideline 3 of the informal design guidelines behind normalisation (update-anomalies) — an attribute that is null for most rows of a relation often belongs in a separate relation instead. See 2026-04-27-database-design-guidelines-and-functional-dependencies and normal-forms.