CSSE2002 — Week 5 Notes
Testing
See csse2002 for course logistics.
Outline
- Levels of Testing
- Test Frameworks
- Black Box Testing
- White Box Testing
- Test Driven Development (TDD)
Testing
See java-testing — the four levels of testing (unit → integration → system → acceptance), regression testing, black-box vs white/glass-box testing (smoke tests, boundary tests, equivalence classes, code coverage), and TDD.
JUnit
See java-junit — @Test, @Before/@After, Assert methods, and testing for expected exceptions.
Black box: the bus example
The black-box example is a bus. The specification is all you get: getCurrentPassengers() and getAverageCount() are given as Javadoc only, with their bodies elided ({...}). With a maximum capacity of 80, the equivalence classes and their boundary probes are:
| Class | Values | Boundary tests |
|---|---|---|
| Valid – Empty | 0 | -1, 0, 1 |
| Valid – Normal | 1 – 79 | Covered by above and below |
| Valid – Full capacity | 80 | 79, 80, 81 |
| Invalid | – | -1, 81 |
This gives the minimal boundary set -1, 0, 1, 79, 80, 81.
Summary: the black-box method
The black-box method in six points:
- Black box testing: no knowledge of implementation, only specification.
- JUnit is a test framework.
- Tests must not violate preconditions.
- Start with smoke tests.
- Expand test suite with boundary tests.
- Stop when confidence is high.
Worked: coverage of register
One short method, with the same question asked at each of the three levels of white-box coverage:
public void register(int x) {
    if (x > 0) {
        positives += 1;
    }
    if (x % 2 == 0) {
        evens += 1;
    }
}
What input for x would give statement coverage? Any odd positive value, e.g. x = 1, gives only a partial run: if (x > 0), positives += 1 and the if (x % 2 == 0) test are all executed, but evens += 1 is missed. x = 2 alone executes every statement.
What input for x would give branch coverage? Branch coverage means each branch is tested for the true case and the false case. x = 2 makes both conditions true, which is half of it. Adding x = -1 makes both conditions false as well. So x = 2 and x = -1: two tests.
What input for x would give path coverage? Path coverage means every path through the code is traversed. Drawn as a decision tree, the code has four exit leaves, so there are four paths, each with its own input:
| Path | x |
|---|---|
x > 0 && x % 2 == 0 |
2 |
x > 0 && !(x % 2 == 0) |
1 |
!(x > 0) && x % 2 == 0 |
-2 |
!(x > 0) && !(x % 2 == 0) |
-1 |
The tree, with the four inputs placed on the paths they drive, is under “White box technique: code coverage” in java-testing, along with the loop argument that follows it: a 100-iteration loop containing one if has \(2^{100}\) paths, so exhaustive path coverage is abandoned in favour of the 0/1/2-iteration approximation.
The worked JUnit white-box example, DiscountCalculator, is in java-junit: five reachable returns, five tests.
Exercise (HW): black box tests for contains
/**
 * Determine if value is contained within the array.
 *
 * @requires array is sorted in ascending order.
 * @return true if value is in the array, false otherwise.
 */
boolean contains(int[] array, int value) {

}
Write black box tests for contains — from this specification only, without seeing the body.
Worked the same way as the bus example:
@requires array is sorted in ascending orderis a precondition, so summary point 3 applies: an unsorted array is not a legal test case. Passing one proves nothing, whatevercontainsreturns.- Equivalence classes on the array: empty; one element; many elements. On the value: present in the array; absent.
- Boundary probes (from the collection and whole-number rows of the boundary table in java-testing): empty array; single-element array with the value present and with it absent; value equal to the first element; value equal to the last element; value falling strictly between two neighbours; value below the minimum and above the maximum;
Integer.MIN_VALUE/Integer.MAX_VALUE. array == nullis a reference-type boundary, but the spec neither permits nor forbids it, so whether it is a legal test case depends on reading@requiresas implying non-null.
Further material
I hear and I forget. I read and I remember. I do and I understand.
— Confucius (according to popular belief)
The CodeCamp playlist has supplementary material and the Git repo has the code samples. Muddy cards as usual.
Debugging
Practical for week 5: using the IntelliJ debugger to find and fix bugs in a small provided codebase of chat bots (ChatBot implementations) — reinforcing java-junit (the provided tests are what reveal each bug) and java-exceptions (RecursiveFibonacci’s bug manifests as a StackOverflowError).
This practical is hands-on IntelliJ-debugger work rather than a computable Q&A, so there are no interactive checks here — just each bug and its fix, as a static reference/answer key.
Setup and ground rules
A provided .zip (from Blackboard) contains thirteen files — ChatBot.java (the shared interface), five bot implementations, and a JUnit test class for each:
CachedFibonacci.java              MockBot.java
CachedFibonacciTest.java          MockBotTest.java
ChatBot.java                      MultiplayerGuessingGameBot.java
CommitBot.java                    MultiplayerGuessingGameBotTest.java
CommitBotTest.java                RecursiveFibonacci.java
GuessingGameBot.java              RecursiveFibonacciTest.java
GuessingGameBotTest.java
The setup is itself part of the exercise: create an IntelliJ project with a src/ source root (blue) and a test/ test source root (green), read the top of the files to discover they all declare a debugging package, create debugging/ under both roots, and copy the files in accordingly. If it worked, the run shows 37 tests, 24 of them failing.
This is also a Git exercise (java-version-control): initialise a repository before you start and commit after each bug fix with a message describing the fix, so the history is one commit per defect.
The practical is about learning the debugger, so for this practical only, modifying the code to add debugging print statements is banned. Modifying the code at all is banned until you have found the bug and are ready to start fixing it. The ban applies to the tests as well.
For the number-guessing bot the work splits into three separate tasks, and they are the actual method being taught — the fix is the last step, not the first:
- Where does the code stop working?
- Why does the code stop working?
- How can you fix the code so that it does work?
Every other bot gets the same sequence in compressed form: step through the failing tests with the debugger to work out why they fail, then implement the fix, then repeat until the tests pass.
Every bot implements one interface, so a failing test always points at one replyTo call:
public interface ChatBot {
    String replyTo(String username, String message);
}
The method takes the user’s username and their message, and either replies or returns null to indicate no response.
Bug 1 — MockBot
MockBot responds to all messages with a copy of the message in alternating caps:
[you]> its a mock bot world after all iTS a mock boT WoRld afTeR allChatBot bot = new MockBot();
System.out.println(bot.replyTo("you", "its a mock bot world after all"));
// iTS a mock boT WoRld afTeR allThe rule is not “alternate letter by letter” but a threshold on the letter: once the message has been folded to uppercase — which is exactly what the fix adds — a letter at or below 'O' comes out lowercase and a letter above 'O' comes out uppercase. (Check it against the example: a, b, c, d, e, f, i, k, l, m, o all sit at or below O in the alphabet and are printed lowercase, while r, s, t, w sit above it and are printed R, S, T, W. The listing below is the buggy body, i.e. before that fold — run as it stands it compares the raw lowercase codes instead, which is the bug.)
private String mock(String message) {
    StringBuilder result = new StringBuilder();
    for (char letter : message.toCharArray()) {
        if (letter > 'O') {
            result.append(Character.toUpperCase(letter));
        } else {
            result.append(Character.toLowerCase(letter));
        }
    }
    return result.toString();
}The bug comes from improper handling of lowercase letters: all lowercase letters are converted to capitals. Converting the message to uppercase first fixes it.
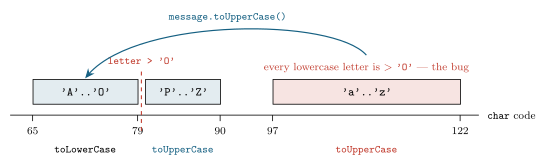
Figure 1: Why every lowercase letter comes out shouted, and what toUpperCase fixes. Comparing a char with > compares its numeric code, and the entire lowercase alphabet (97-122) sits above the threshold letter O (79), so the buggy loop routes all of a-z into the toUpperCase branch. Folding the message to uppercase first collapses a-z onto A-Z, putting each letter back on the side of the threshold its position in the alphabet intends.
Comparing two chars with > compares their numeric codes, and Java’s letter codes run 'A'–'Z' = 65–90 then 'a'–'z' = 97–122. Every lowercase letter therefore exceeds 'O' (79) regardless of where it sits in the alphabet, so the buggy loop sends the whole of a–z down the toUpperCase branch: every lowercase letter is converted to a capital.
Normalising the message to uppercase before the loop puts every letter into the 65–90 range, where the comparison against 'O' means what it was meant to mean:
private String mock(String message) {
    ...
-   for (char letter : message.toCharArray()) {
+   for (char letter : message.toUpperCase().toCharArray()) {
    ...
}
The debugger route to this: set a breakpoint inside the loop, watch letter and the branch taken, and the first lowercase character shows the wrong branch being entered.
Bug 2 & 3 — GuessingGameBot
A bot that plays a number-guessing game: the user asks whether the secret “magic number” is higher or lower than a guess, and the bot answers.
[you]> help
Guessing game bot!
There are 3 options
1) guess higher <number>
2) guess lower <number>
3) guess equal <number>
[you]> guess higher 2
yes
[you]> guess lower 5
no
[you]> guess equal 3
you lose!
Two independent bugs.
Bug 2 — message splitting. split(String) breaks a message into words on spaces:
private static List<String> split(String input) {
    ...
    while (index != -1) {
        newIndex = input.indexOf(' ', index + 1);
        if (newIndex == -1) {
            output.add(input.substring(index));
        } else {
            output.add(input.substring(index, newIndex));
        }
        index = newIndex;
    }
}
Bug 3 — comparison logic. The higher/lower branches compare the wrong way:
public static String replyTo(String message) {
    ...
    if (type.equals("higher")) {
        ...
        return guess > SECRET_NUMBER ? "yes" : "no";
    } else if (type.equals("lower")) {
        ...
        return guess < SECRET_NUMBER ? "yes" : "no";
        ...
    } else if (type.equals("equal")) {
    ...
}Reading the documentation in the source files helps in working out how the code functions. Both bugs are only visible once you know what split and replyTo are each supposed to return.
Bug 2 fix. Messages are not split correctly, leaving extra whitespace before words, because substring() includes the char at the first index it is given.
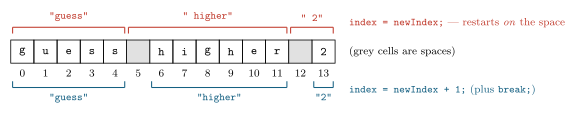
Figure 2: Bug 2 traced on the message the transcript uses. Top: the substring ranges the buggy loop produces, because index is reassigned to the position OF the space rather than one past it, so every word after the first keeps a leading space. Bottom: the ranges after the fix. The leading space is not cosmetic - it makes type.equals(higher) false and would make Integer.parseInt on the last token throw.
Stepping "guess higher 2" through the buggy loop gives ["guess", " higher", " 2"] — the two later tokens carry a leading space, which is enough to make type.equals("higher") false and to make Integer.parseInt(" 2") throw a NumberFormatException. The fix advances past the space:
private static List<String> split(String input) {
    while (index != -1) {
        newIndex = input.indexOf(' ', index + 1);
        if (newIndex == -1) {
            output.add(input.substring(index));
+           break;
        } else {
            output.add(input.substring(index, newIndex));
        }
-       index = newIndex;
+       index = newIndex + 1;
    }
}
The break is not optional, and it is a consequence of the other line: with index = newIndex + 1, the loop’s own while (index != -1) guard can no longer stop it — on the last word newIndex is -1, so index becomes 0 and the loop restarts from the beginning of the string forever. Adding the + 1 without the break trades a wrong answer for an infinite loop.
Bug 3 fix. Guesses are checked against the secret number incorrectly. Swapping the > and < fixes it.
public static String replyTo(String message) {
    ...
    if (type.equals("higher")) {
        ...
-       return guess > SECRET_NUMBER ? "yes" : "no";
+       return guess < SECRET_NUMBER ? "yes" : "no";
    } else if (type.equals("lower")) {
        ...
-       return guess < SECRET_NUMBER ? "yes" : "no";
+       return guess > SECRET_NUMBER ? "yes" : "no";
        ...
    } else if (type.equals("equal")) {
    ...
}
The reading that makes the swap obvious: guess higher 2 asks “is the secret higher than 2?”, so the answer is "yes" exactly when 2 < SECRET_NUMBER. Checked against the transcript above — guess higher 2 → yes and guess lower 5 → no — the fixed code says the secret is greater than 2 and not less than 5, which the guess equal 3 → you lose! line is consistent with.
Bug 4 & 5 — MultiplayerGuessingGameBot
The multiplayer variant lets several users each submit one guess; whoever is closest wins, and only the host may finish the game:
[you]> start game
Starting new game...
[you]> guess 12
[root]> guess 5
[admin]> guess 100
[test]> guess 34
[root]> finish game
You do not have a game running.
Host must finish game.
[you]> finish game
The secret number was 13
1) you (12)
2) root (5)
3) test (34)
4) admin (100)
Two independent bugs.
Bug 4 — host check inverted:
public String replyTo(String username, String message) {
    ...
    if (username.equals(host)) {
        return "You do not have a game running.\n"
                + "Host must finish game.";
    }
    ...
}
Bug 5 — leaderboard rank off-by-one:
private String results() {
    ...
    int rank = 0;
    ...
}Bug 4 fix. Finishing a game is not handled correctly. The user finishing the game should be the same as the host; the current implementation does the opposite. The refusal message belongs to the non-host:
public String replyTo(String username, String message) {
    ...
-   if (username.equals(host)) {
+   if (!username.equals(host)) {
    ...
}
Read against the transcript: [root]> finish game is refused because root is not the host, and [you]> finish game succeeds because you started the game. The buggy version does exactly the reverse — the host is the only user who cannot end their own game.
Bug 5 fix. The leaderboard has an off-by-one error in the ranking: it starts from zero instead of one.
private String results() {
    ...
-   int rank = 0;
+   int rank = 1;
    ...
}
The transcript’s leaderboard begins at 1) you (12), so the counter that labels the rows is a display index rather than an array index — and Java’s habit of counting positions from zero is what makes int rank = 0; look right at a glance.
Bug 6 & 7 — CommitBot
Lets a user generate a random commit message (commit new), save the last-generated one (commit save), and reload it later (commit load):
[you]> commit new
I know what I am doing. Trust me.
[you]> commit save
Commit saved
[you]> commit new
Does this work
[you]> commit load
I know what I am doing. Trust me.
Two independent bugs. The transcript requires that commit load returns the message that was saved, not the one most recently generated.
Bug 6 — generated message never recorded as “last”:
public String replyTo(String username, String message) {
    ...
            String commit = generateMessage();
            return commit;
    ...
}
Bug 7 — load reads from the wrong map:
public String replyTo(String username, String message) {
    ...
        if (message.endsWith("load")) {
            if (!lastMessages.containsKey(username)) {
                return "No saved message to load";
            }
            return lastMessages.get(username);
        }
    ...
}Bug 6 fix. The last generated commit message is not recorded when it is generated. commit save reads whatever lastMessages holds for the user, so if commit new never writes there, save has nothing (or something stale) to promote:
public String replyTo(String username, String message) {
    ...
            String commit = generateMessage();
+           lastMessages.put(username, commit);
            return commit;
    ...
}
Bug 7 fix. The load command loads commit messages from the last message rather than the saved message.
public String replyTo(String username, String message) {
    ...
        if (message.endsWith("load")) {
-           if (!lastMessages.containsKey(username)) {
+           if (!savedMessages.containsKey(username)) {
                return "No saved message to load";
            }
-           return lastMessages.get(username);
+           return savedMessages.get(username);
        }
    ...
}
The two maps exist for two different lifetimes — lastMessages is whatever was generated most recently, savedMessages is what the user chose to keep — and each bug is one of them being used where the other belongs. The bugs mask each other, so the transcript is worth re-reading between fixes. Fix bug 6 alone and commit load starts returning the most recently generated message — "Does this work" — rather than the saved one; fix bug 7 alone and savedMessages still has nothing in it to load. Only both fixes together reproduce the transcript’s last line.
Bug 8 — RecursiveFibonacci (bonus)
The tests throw a “StackOverflow” exception. A stack overflow exception is thrown when a function recursively calls itself so many times that the program runs out of stack memory. A recursive method needs a base case so that the function knows when to stop. Two things to check: whether this code has a base case, and whether it is being reached.
The issue arises when x > 1: the recursive calls to calculate then include subtractions of 2 or greater, so the base case of x == 1 is skipped, resulting in infinite calls of negative numbers. The base case is written n == 1, an equality test, so any step that moves n past 1 by more than one at a time misses it entirely and the recursion runs away into the negatives.
Two fixes, given \(\mathcal{F}(1) = \mathcal{F}(2) = 1\):
// Preferred: widen the existing base case so it cannot be stepped over.
public static int calculate(int n, int x) {
-   if (n == 1) {
+   if (n <= 2) {
        return 1;
    }
}
// Alternative: add an explicit zero case.
public static int calculate(int n, int x) {
+ if (n == 0) { // or n < 1
+ return 0;
+ }
...
}The first is preferred. The second preserves and tolerates recursive calls that violate the precondition, n >= 1; the first removes the offending calls where n < 1. In the language of java-specification: the second fix makes the method cope with arguments outside its own precondition, which quietly widens the contract; the first fix makes those calls never happen.
The general lesson is about the shape of a guard rather than this method: a base case tested with == is only safe if the recursion is guaranteed to land exactly on it. Testing with <= is robust to any step size.
A naming point: StackOverflowError is an Error, not an Exception — both are Throwables, but Error marks conditions a program is not expected to catch and recover from. The distinction is drawn in java-exceptions; calling it an exception is informal.
Bug 9 — CachedFibonacci (challenge)
“Code is broken. Please fix. Good luck.” The symptom is that the results are wrong for larger Fibonacci numbers only — small inputs pass.
The cache is two parallel arrays, cacheKeys and cacheValues, kept in most-recently-used order: on a hit at position index, the entry is shuffled to the front.
...
int key = cacheKeys[index], value = cacheValues[index];
for (int i = index - 1; i >= 0; --i) {
    cacheKeys[i + 1] = cacheKeys[i];
    cacheValues[i + 1] = cacheValues[i];
}
cacheKeys[0] = key;
cacheValues[0] = value;
...The code gives incorrect results for larger Fibonacci numbers. The problem is that the index of the current number n is not updated after its position is shuffled to the front of the cache.
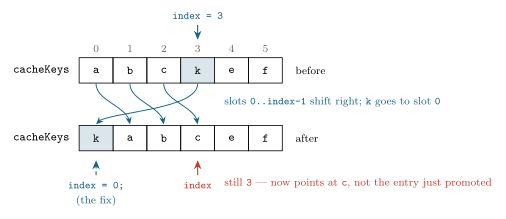
Figure 3: The move-to-front shuffle and the variable it forgets. The slot values a..f stand in for cache contents. Slots 0 through index-1 each shift one place right and the promoted key k is written into slot 0, so after the shuffle every entry at or below index has moved. index itself is untouched, so it now names a different entry than the one just looked up - which is why only lookups that hit deep in the cache, i.e. larger inputs, come back wrong.
...
int key = cacheKeys[index], value = cacheValues[index];
for (int i = index - 1; i >= 0; --i) {
    cacheKeys[i + 1] = cacheKeys[i];
    cacheValues[i + 1] = cacheValues[i];
}
cacheKeys[0] = key;
cacheValues[0] = value;
+ index = 0;
...
This bug is a good argument for the ground rule about the debugger. The symptom (“wrong only for larger numbers”) is the giveaway once the mechanism is on paper: index == 0 is a hit at the front, where the shuffle moves nothing and the stale value is accidentally correct. Only a hit at index > 0 — which needs a cache deep enough to have been populated, i.e. a larger input — leaves index naming the wrong slot. Reading the code alone, the missing line is invisible because nothing is written incorrectly; a variable is simply left behind by a state change happening around it.
Exceptions
Applied class exercises for week 5, tracing execution through nested try/catch/finally blocks — reinforcing java-exceptions and 2026-03-19-exceptions. Two exception families are defined up front and used throughout. It helps to draw a diagram of the inheritance relationships between the classes, because every answer below turns on which class is a subclass of which.
class E1 extends Exception {};      class F1 extends Exception {};
class E2 extends E1 {};             class F2 extends F1 {};
class E3 extends E1 {};             class F3 extends F1 {};
class E4 extends E3 {};             class F4 extends F1 {};
class E5 extends E3 {};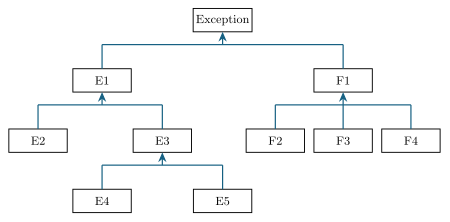
Figure 4: The two exception families declared above. Two independent subtrees under Exception - no E is ever an F, which is why an F-typed catch clause can never claim an E and vice versa. E1 has two children and E3 two grandchildren; F1 has three children and no depth. Each connector ends in a single solid arrowhead at the parent’s bottom edge, so the arrows run from subclass to superclass.
Every one of these nine classes descends from Exception and none from RuntimeException, so all nine are checked exceptions — which is what makes the throws questions at the end of each exercise worth asking at all. The two rules the questions test are both readable off Figure 6:
catch (T e)claims a thrown object ifTis that object’s class or any ancestor of it — so acatchhigh in the tree swallows everything beneath it.catchclauses are tried in source order, and the first match wins. Order therefore matters whenever one clause’s type sits above another’s in the tree.
The code that follows is intended to illustrate concepts. Some details (for example, class declarations) are omitted. In all exercises, x and y are member variables.
On the HTML site, fill in each blank with your answer (as a quoted string, in the form x, y, e.g. "12, 20"), then click Run Code to check it. In the PDF, the Working callout is shown as a static answer key instead (interactive checking needs a browser).
Question 1
x and y are member variables, both starting at 0:
int x = 0, y = 0;
public void exercise1() {
    try {
        try {
            f();
            y += 10;
        } catch (F3 e) {
            x += 1;
        } catch (F1 e) {
            x += 10;
        } catch (F4 e) {
            x += 100;
        } catch (E5 e) {
            y += 1;
            throw e;
        } finally {
            x += 2;
        }
        y += 20;
    } catch (Exception e) {
        y += 100;
    }
}
What are x, y after exercise1() is called, if f() throws each of the following?
f() throws F2 →
f() throws F3 →
f() throws F4 →
f() throws E4 →
f() throws E5 →
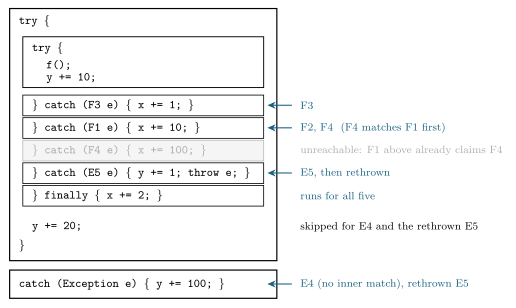
Figure 5: Exercise 1’s structure with each thrown type routed to the clause that actually claims it, and the outcome labelled beside each clause. The three things to read off it: catch (F1) sits above catch (F4) in source order and so claims F4 before that clause is ever reached; finally runs on every one of the five paths; and the two throws that leave the inner try - the unmatched E4 and the rethrown E5 - are the ones that skip y += 20 on the way to the outer handler.
- F2 → not
F3, notF4, notE5, but is anF1(F2 extends F1), socatch (F1 e):x += 10.finallyalways runs:x += 2→ x = 12. Nothing escapes the innertry, soy += 20still runs → y = 20. - F3 → matched directly by
catch (F3 e):x += 1;finally:x += 2→ x = 3;y += 20runs → y = 20. - F4 → this is the ordering trap.
catch (F1 e)comes first in source order andF4 extends F1, so theF1clause claims it andcatch (F4 e)never runs:x += 10,finallyx += 2→ x = 12,y += 20→ y = 20. Identical to theF2answer, for the same reason. - E4 → nothing in the inner
trymatches.F3/F1/F4are the other family entirely, andE5isE4’s sibling, not an ancestor (both hang offE3). Onlyfinallyruns —x += 2→ x = 2 — and the exception keeps propagating, skippingy += 20, intocatch (Exception e):y += 100→ y = 100. - E5 → matched by
catch (E5 e):y += 1, then re-thrown.finallystill runs on the way out:x += 2→ x = 2. The rethrow escapes the innertryentirely (soy += 20is skipped — a rethrow from acatchis not offered to that sametry’s other clauses) and lands in the outercatch (Exception e):y += 100→ y = 1 + 100 = 101.
Does exercise1 need a throws declaration? No. All the exceptions thrown by f() are caught either by the inner try or by the outer try, and the re-thrown exception is caught by the outer try. If all thrown exceptions are handled by a try/catch then a throws declaration is not required. The outer catch (Exception e) is what guarantees this — it sits at the root of Figure 6 and therefore claims anything at all.
The exercise is a paper trace only. catch (F1 e) followed by catch (F4 e) is a compile-time error in Java, not merely a dead branch — javac reports “exception F4 has already been caught” whenever a preceding clause’s type is a superclass of a later clause’s. So the F4 answer is testing the rule (first matching clause wins, subclasses must be caught before superclasses) rather than describing code you could run. The same reasoning is what makes catch (Exception e) legal only as the last clause of a chain.
Question 2 — bonus
int x = 0, y = 0;
public void exercise2() throws ... {
    try {
        y += g();
    } catch (E3 e) {
        x += 100;
    }
}

public int g() throws ... {
    try {
        f();
        y += 10;
        return 400;
    } catch (E1 e) {
        x += 1;
    } finally {
        x += 10;
    }
    return 1;
}
f() throws E1 →
f() throws E2 →
f() throws E3 →
All three inputs give the same answer, x = 11, y = 1, and the reason is one line of Figure 6: E1, E2 and E3 all sit at or below E1, so g’s single catch (E1 e) claims every one of them.
Tracing g() for any of the three:
f()throws, soy += 10andreturn 400are both skipped.catch (E1 e)runs:x += 1→x = 1.finallyruns:x += 10→x = 11.- Control leaves the
try/catch/finallynormally — thecatchbody has noreturnof its own — and reachesreturn 1. Sog()returns 1. - Back in
exercise2,y += g()adds that1→y = 1. No exception ever escapesg, soexercise2’scatch (E3 e)never runs andxstays at11, not111.
The return 400 inside the try is the trap: it looks like the method’s answer but it is unreachable on every path where f() throws. On the path where f() does not throw, y += 10 runs, return 400 is evaluated, finally still executes x += 10 before the value leaves the method, and exercise2 ends at x = 10, y = 410 — finally runs on a return just as it does on a throw.
The throws declarations for the methods exercise2 and g would be different, depending on which type of exception f() is throwing. That is why both signatures are written as throws ... — the declaration is a function of f’s, and f’s is deliberately left unspecified.
Question 3 — bonus
g() throws F2 (unconditionally, when called):
int x = 0, y = 0;
public void exercise3() throws ... {
    try {
        try {
            try {
                f();
                x += 100;
            } catch (F2 e) {
                x += 5;
                g();
            } catch (F1 e) {
                x += 1;
            } catch (E1 e) {
                y += 2;
                throw e;
            }
            y += 10;
        } catch (F2 f) {
            y += 100;
        }
    } catch (Exception e) {
        x += 1000;
    }
}
f() throws F3 →
f() throws F2 →
f() throws E1 →
f() throws F1 →
x += 100 sits inside the innermost try, immediately after f() — so on every one of these four inputs it is skipped.
- F3 →
catch (F2 e)does not match (F3isF2’s sibling, not its descendant);catch (F1 e)does:x += 1. Nothing further is thrown, soy += 10runs and neither outer handler fires → x = 1, y = 10. - F2 →
catch (F2 e)matches:x += 5, then it callsg(), which throwsF2. A throw from inside acatchbody is not offered to that sametry’s remaining clauses — it propagates outward. It skipsy += 10and lands in the middlecatch (F2 f):y += 100→ x = 5, y = 100. - E1 → neither
Fclause matches,catch (E1 e)does:y += 2, then rethrows. AnE1is not anF2, so the middle handler passes; the outermostcatch (Exception e)claims it:x += 1000→ x = 1000, y = 2. - F1 → an
F1is not anF2(the subclass relation only runs downward), so the first clause passes andcatch (F1 e)takes it:x += 1,y += 10runs → x = 1, y = 10. Same answer asF3, because both reach the same handler.
The pair of F2 cases is the one to take away: throwing F2 into a try whose own first clause is catch (F2 e) gets caught there, but throwing F2 from inside that clause escapes to the next try out. Two identical exception types, two completely different destinations, decided by where the throw happens rather than what is thrown.
Reference material
Java Exceptions
Introduced in 2026-03-19-exceptions (Lecture, Week 4, Part 1). Traced in depth in week5-tutorial-exceptions.
What is an exception?
An unexpected event that occurs during program execution, e.g.:
System.out.println(5 / 0); // Infinity??No — integer division by zero causes a java.lang.ArithmeticException: / by zero. Infinity is the tempting wrong answer: it is what floating-point division gives, not integer division.
Common causes:
- invalid user input
- loss of network connection
- physical limitations (out of disk memory)
- code errors
- opening an unavailable file
When an exception occurs within a method it creates an object — the exception object — which contains information about the exception. Effective Java (2017), Item 75, says to include failure-capture information in detail messages: that object is where the diagnostic information has to live.
We can catch the exception to handle it, and the catch block is where the program is put back into a usable state:
try {
    System.out.println(5 / 0);
}  catch (ArithmeticException e) {
    System.out.println(e); // print out error message
    //do something to recover
}
Exception hierarchy
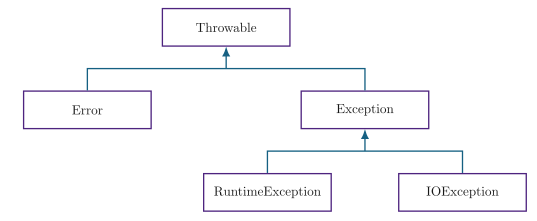
Figure 6: The exception hierarchy. Throwable is the root; Error and Exception sit beneath it; RuntimeException (unchecked) and IOException (checked) sit beneath Exception. Each connector joins the subclasses and points up to their parent. Which branch a class is on is what decides whether the compiler forces you to handle it, so this one picture settles the checked/unchecked question.
RuntimeException — unchecked
A runtime exception happens due to a programming error. Also known as unchecked exceptions: the compiler does not force you to handle them.
| Cause | Exception |
|---|---|
| Improper use of an API | IllegalArgumentException |
| Null pointer access | NullPointerException |
| Out-of-bounds array access | ArrayIndexOutOfBoundsException |
| Dividing a number by 0 | ArithmeticException |
IOException — checked
Also known as a checked exception: it is checked by the compiler at compile time, and the programmer is prompted to handle it.
| Cause | Exception |
|---|---|
| Trying to open a file that doesn’t exist | FileNotFoundException |
| Trying to read past the end of a file | EOFException |
| A connection attempt to a remote host fails | ConnectException |
Java exception handling
There are three mechanisms: the try…catch block, the throw and throws keywords, and the finally block.
try … catch
Place the code that might generate an exception inside the try block. Every try block is followed by a catch block.
int result;
try {
    result = 5 / 0;
    …
} catch (ArithmeticException e) {
    System.out.println(e);      // print out error message
    result = Integer.MAX_VALUE; // Assign a default or fallback value
}- When an exception occurs, the rest of the code inside the
tryblock is skipped. - The
catchblock catches the exception and the statements inside thecatchblock are executed. - If none of the statements in the
tryblock generates an exception, thecatchblock is skipped.
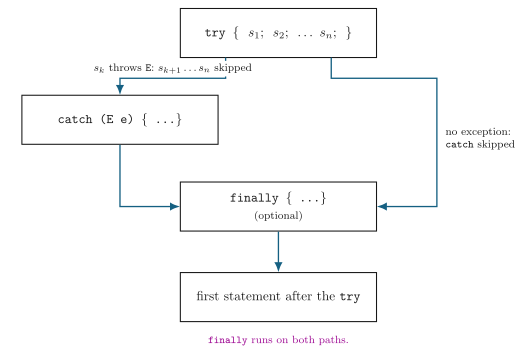
Figure 7: The two paths through a try/catch/finally, and the fact that both of them end up in finally. This is the three numbered rules together with the finally rule, drawn as one picture: the exceptional path abandons the remaining statements of the try and enters catch, the normal path skips catch entirely, and neither can skip finally.
throw
The throw keyword is used to explicitly throw a single exception. Two examples:
public class Main {
    public static void main(String[] args) {
        divideByZero();
    }
    public static void divideByZero() {
        // throw an exception
        throw new ArithmeticException("Trying to divide by 0");
    }
}
public class Main {
public static void main(String[] args) {
checkEntry(17);
}
public static void checkEntry(int age) {
if (age < 18) {
throw new IllegalArgumentException("Access denied ");
}
else {
System.out.println("Access granted ");
}
}
}throw is used to manually trigger an error when your program detects something invalid, so it doesn’t continue in a bad state. That is the point of the whole keyword, and it is also the bridge to java-specification: throwing is how a method refuses input that breaks its precondition instead of limping on.
throws
The throws keyword declares the type of exceptions that might occur within the method, and it is used in the method declaration. The caller is then the one prompted to handle it:
public class ThrowsEx {
    public static void main(String[] args) {
        try {
            findFile();
        } catch (FileNotFoundException e) {
            System.out.println(e);
        }
    }
    public static void findFile() throws FileNotFoundException {
        // code that may generate FileNotFoundException
        File newFile = new File("file.txt");
        FileInputStream stream = new FileInputStream(newFile);
    }
}
throw and throws are not two spellings of one thing: throw (statement, inside a body) raises an exception; throws (clause, in a signature) declares that one can escape. Only checked exceptions have to be declared — that is exactly what “checked by the compiler” buys you.
finally
- The
finallyblock is executed regardless of whether an exception is thrown. - The
finallyblock is optional.
try {
    //code
}
catch (ExceptionType1 e1) {
    // catch block
}
finally {
    // finally block always executes
}
Exercise — what will the following print?
try{
    System.out.println("Good Morning");
    throw  new FileNotFoundException();
    System.out.println("the earth says");
}catch (Exception e){
    System.out.println("hello");
}finally {
    System.out.println("world");
}
Answer:
Good Morning
hello
world
Working through it against the rules above: "Good Morning" prints; the throw immediately abandons the rest of the try, so "the earth says" never prints; the catch parameter is Exception, and FileNotFoundException is an Exception, so this catch matches and "hello" prints; finally always runs, so "world" prints last.
As written this snippet would not actually compile. System.out.println("the earth says"); sits directly after an unconditional throw in the same block, and Java rejects that at compile time as an unreachable statement. Read it as a tracing exercise about the order of the three rules, not as something to paste into a file.
Custom exceptions
Define your own by extending Exception (or a subclass of it), then declare it with throws and raise it with throw:
public class MyCustomException extends Exception {
...

}

int myFunction() throws MyCustomException {
throw new MyCustomException();
}
Worked example — ItemNotFoundException
The exception class gives a no-argument constructor with a fixed message and a second constructor taking a custom one, both delegating to super(...) — the Throwable message is the failure-capture information from Item 75:
public class ItemNotFoundException extends Exception{
    public ItemNotFoundException(){
        super("Item not found");
    }
    // Constructor that accepts a custom message
    public ItemNotFoundException(String message) {
        super(message);
    }
}
The class that uses it declares throws on the searching method and throws when the loop falls through without a match:
public class Store {
    private List<String> items;
    public Store() {
        items = new ArrayList<>();
        items.add("apple");
        items.add("banana");
        items.add("orange");
    }
    public String findItem(String itemName) throws ItemNotFoundException {
        for (String item : items) {
            if (item.equals(itemName)) {
                return item;
            }
        }
        throw new ItemNotFoundException("Item '" + itemName + "' not found in the list.");
    }

    public static void main(String[] args) {
        Store store = new Store();
        try {
            String item = store.findItem("grape");
            System.out.println("Found item: " + item);
        } catch (ItemNotFoundException e) {
            System.err.println(e.getMessage());
        }
    }
}
findItem("grape") misses, so the try is abandoned at the call — "Found item: …" never prints — and the catch reports Item 'grape' not found in the list. on System.err.
Java JUnit
Introduced in 2026-03-26-testing (Lecture, Week 5). See java-testing for the broader testing concepts JUnit is used to implement.
What is JUnit?
An open-source test automation framework for Java — one of many xUnit frameworks (JUnit, NUnit, CPPUnit, PyUnit…). This course uses JUnit 4 (http://junit.org/junit4, and the cookbook at https://junit.org/junit4/cookbook.html). Depending on how software is structured, unit-testing frameworks like JUnit can also be used for other kinds of automated testing, but “unit testing” is sometimes incorrectly used to mean any automated test.
Writing tests
Tests are defined in classes — one test class per real class. @Test marks a method as a test JUnit should run; test methods take no parameters and return void, and should be named for what they check.
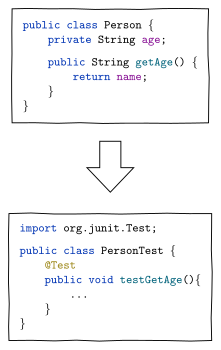
Figure 8: One test class per real class: Person produces PersonTest, which imports org.junit.Test and carries one @Test-annotated method per thing being checked. The hollow block arrow pointing down means produces/translates-to. The Person snippet does not compile as drawn: getAge() returns name, which the snippet never declares, and the field is typed String age. The full Person below types it int and is the version that compiles.
The full class and its test class:
public class Person {
    private String name;
    private int age;

    public Person(String name, int age) {
        this.name = name;
        this.age = age;
    }

    public String getName() {
        return name;
    }

    public int getAge() {
        return age;
    }
}
import org.junit.Test;
import static org.junit.Assert.assertEquals;
public class PersonTest {
@Test
public void TestGetAge() {
Person p1 = new Person("Jack", 10);
int age = p1.getAge();
assertEquals(10, age);
}
@Test
public void TestGetName() {
Person p1 = new Person("Jack", 10);
String name = p1.getName();
assertEquals("Jack", name);
}
}The test class uses two imports: org.junit.Test for the annotation, and a static import of org.junit.Assert.assertEquals so the assertion can be called bare rather than as Assert.assertEquals(...).
@Before and @After
Each test method should be independent, but you may want common things set up before each test (e.g. object creation):
public class PersonTest {

    private Person person;

    @Before
    public void setUp() {
        person = new Person("Jack", 10);
    }

    @After
    public void tearDown() {
        person = null;
    }
    // ...
}
@Before will be run before each test; @After will be run after each test. Every test method gets a freshly built fixture rather than whatever the previous test left behind, which is how the tests are kept independent.
Assert
Some static methods in Assert:
assertEquals— asserts that two objects are equal.assertArrayEquals— asserts that two object arrays are equal.assertFalse/assertTrue— asserts that a condition is false or true.assertSame/assertNotSame— asserts that two objects refer to the same object or not.
The difference between assertSame and assertEquals is reference identity vs .equals: two distinct Person objects with the same fields can be assertEquals-equal (if equals is overridden) but are never assertSame.
Checking for exceptions
Don’t catch the exception — the test runner does. Tell the test runner which exception it should catch, via @Test(expected = ...):
@Test(expected = EOFException.class)
public void testExceptions() throws EOFException {
    callThatShouldThrowEOFException();
}
.class is required after the name of the class. The test passes if that exception is thrown and fails if it is not, or if a different one is. See java-exceptions.
Black box tests in JUnit
Write the tests purely from the specification/Javadoc, without looking at the implementation, then use smoke tests, boundary tests and equivalence classes (see java-testing) to decide what to check. The hard constraint is that tests must not violate preconditions. A test that breaks @requires tells you nothing, because the method is entitled to do anything at all in that case.
White box tests in JUnit
Design tests based on the internal logic. You try to cover branches, loops and edge cases, and you may aim for a code coverage target (e.g. 100%).
The worked example is a discount calculator with two nested levels of branching:
public class DiscountCalculator {

    public double calculateDiscount(double amount, boolean isMember) {
        if (amount <= 0) {
            return 0;
        }

        if (isMember) {
            if (amount > 100) {
                return amount * 0.2;
            } else {
                return amount * 0.1;
            }
        } else {
            if (amount > 100) {
                return amount * 0.1;
            } else {
                return 0;
            }
        }
    }
}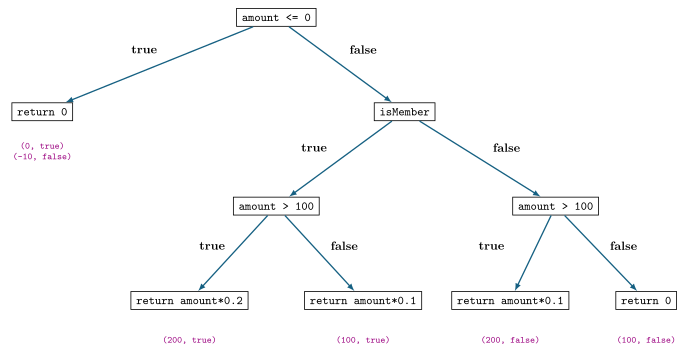
Figure 9: Why DiscountCalculator needs exactly five tests: the method as a decision tree, one leaf per test. Each box is a condition from the method or the return its branch reaches, so the expected values in the tests can be read off the leaves. The magenta (amount, isMember) pair under each leaf is the argument list of the test that reaches that leaf. The early return on amount <= 0 is the one leaf covered by two assertions in a single test, which is why it carries two pairs.
The five tests, one per leaf:
public class DiscountCalculatorTest {

    DiscountCalculator calc = new DiscountCalculator();

    @Test
    public void testAmountLessOrEqualZero() {
        assertEquals(0.0, calc.calculateDiscount(0, true));
        assertEquals(0.0, calc.calculateDiscount(-10, false));
    }

    @Test
    public void testMemberAbove100() {
        assertEquals(40.0, calc.calculateDiscount(200, true));
    }

    @Test
    public void testMemberBelowOrEqual100() {
        assertEquals(10.0, calc.calculateDiscount(100, true));
    }

    @Test
    public void testNonMemberAbove100() {
        assertEquals(20.0, calc.calculateDiscount(200, false));
    }

    @Test
    public void testNonMemberBelowOrEqual100() {
        assertEquals(0.0, calc.calculateDiscount(100, false));
    }
}
Two things worth reading off this example:
- The tests are named for the branch they cover, not for the method (
testMemberAbove100, nottestCalculateDiscount3), which is what naming a test for what it checks looks like in practice. amount = 100is the argument in two of the five tests. It is the boundary ofamount > 100, so it is both a white-box branch probe and a black-box boundary test.
The tests above call assertEquals(0.0, ...) on double values. JUnit 4’s two-argument assertEquals(double, double) is deprecated precisely because floating-point equality is unreliable; the three-argument assertEquals(expected, actual, delta) is the form that compiles without a deprecation warning. The code above will warn if you type it in.
Java Specification
Introduced in 2026-03-12-object-oriented-programming-ii (Lecture, Week 3). Extended in 2026-03-19-exceptions and formalised later in java-hoare-logic; pre/postconditions come back as class invariants in week8-tutorial-class-invariants and as the substitution principle in week9-tutorial-substitution-principle-and-pre-post-conditions.
The order below: Javadoc → restrictiveness → generality → formality → contracts → defensive programming.
Javadoc
- Ordinary comments:
//and/* ... */. - Javadoc comments:
- begin with
/**— note the second*; the Javadoc generator ignores all other comments; - end with
*/; - must sit immediately above the thing being documented;
- use tags beginning with
@; - some tags take parameters, some just text.
- begin with
A worked example:
/**
 * Calculates a sum by combining the hash code of the provided string
 * and the long value of the provided float.
 *
 * @param inputString the input string whose hash code will be used
 * @param inputFloat  the float value to be converted to long and combined with the string hash code
 * @return a long value representing the sum of the string's hash code and the long value of the float
 */
public long doCalculation(String inputString, float inputFloat){
    long floatToLong = (long) inputFloat;

    // Combine the hash code of the string with the float-to-long value
    long result = inputString.hashCode() + floatToLong;

    return result;
}What makes a good specification
Ideally a specification will:
- Allow the use of a method by only reading the specification, not by reading and understanding the implementation.
- Allow a method to be re-implemented without requiring changes to any methods that use it.
And it should:
- Rule out all implementations that are unacceptable — i.e. be sufficiently restrictive.
- Not preclude acceptable implementations — i.e. be sufficiently general.
- Be easy for users (programmers) to understand — i.e. be clear.
The next three sections take one method, search, and fail each of those three tests in turn.
Restrictiveness — keep out incorrect implementations
/**
 * Returns an index (i) of ar such that
 * ar[i] == x, if any.
 */
public int search(int[] ar, int x) {…}
This does not say what happens if x is not in ar. It is tempting to assume the obvious answer, but the specification doesn’t say, so don’t assume. By its silence, the specification allows any value to be returned. So a return of 1 or 0 could mean “It’s at index 1/0” or “I didn’t find it”.
Adding the missing case makes it better, still bad:
/**
 * Returns an index (i) of ar such that
 * ar[i] == x, if any
 * else, return -1
 */
public int search(int[] ar, int x) {…}
Suppose x appears in ar multiple times. There is nothing in the spec that requires:
- that you will get the lowest index;
- that you will get the same answer running multiple times.
The specification is non-deterministic.
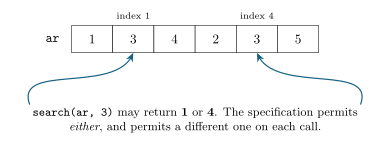
Figure 10: With the spec worded as ‘returns an index i such that ar[i] == x’, both cells holding 3 are legal answers, and nothing forbids the method returning a different one on each call. That is what makes the specification non-deterministic.
Generality — allow acceptable alternative versions
The obvious fix for the non-determinism is to say which index you get. Saying it like this, however, is a bad example:
/**
 *  Examine ar[0], ar[1], ... in turn and
 *  return the index of the
 *  first one that is equal to x, if any,
 *  else return -1
 */
public int search(int[] ar, int x) {…}
It is restrictive enough, but it over-commits: it describes how the method walks the array. A forward-scanning implementation goes with it (see the warning below before trusting this listing):
public int search(int[] ar, int x) {
    int found = -1;
    for (int i = 0; i < ar.length; i++) {
        if (ar[i] == x) {
            found = i;
        }
    }
    return found;
}
The consequence of the over-committed wording shows when the loop is run the other way:
public int search(int[] ar, int x) {
    int found = -1;
    for (int i = ar.length-1; i >= 0; i--) {
        if (ar[i] == x) {
            found = i;
        }
    }
    return found;
}
Scanning backwards and keeping the last match found is the smallest matching index — the answer the spec asks for — but the specification said ar[0], ar[1], ... in turn, so this version does not satisfy the specification. A perfectly good implementation has been outlawed by wording that was never about the outcome.
Even if you think that is the most natural way to do something, that doesn’t mean it should be part of the specification.
Specs should describe what happens, not how.
Rewritten to talk about the result only, the specification now accepts the backward implementation:
/**
 * Return smallest index (i) of ar such that
 * ar[i] == x, if any,
 * else return -1
 */
public int search(int[] ar, int x) {…}The backward scan above returns the smallest index, so it satisfies the rewritten spec. The forward scan from earlier does not:
for (int i = 0; i < ar.length; i++) {
    if (ar[i] == x) { found = i; }
}
return found;
That loop overwrites found on every match, so it returns the largest matching index, not the smallest — and not the first one either, which is what the earlier spec asked for. On ar = [1,3,4,2,3,5] with x = 3 it returns 4 where both specs want 1. The forward and backward listings only agree when x occurs at most once. A forward scan that satisfies the spec has to stop at the first match:
for (int i = 0; i < ar.length; i++) {
    if (ar[i] == x) { return i; }
}
return -1;
Clarity
- A specification should facilitate communication between people.
- Two ways in which communication could fail:
- the reader doesn’t understand;
- the reader only thinks they understand.
- Clarity can be improved by being as concise as possible. Long specs are:
- more likely to contain errors/contradictions,
- less likely to be read properly,
- more likely to be misunderstood.
- Redundancy may help — but be clear that it is redundant, by using e.g. “e.g.” or “i.e.”.
Four specs to judge
Four one-line specifications. The question for each is whether it is a good specification.
/**
 * Sorts the given array.
 */
public void sort(int[] ar) {...}
/**
* Calculate x to the power of two with Math.pow.
*/
public int square(int x) {...}/**
* Returns the list of ResourceContainers stored by this instance.
*/
public List<ResourceContainer> getResources() {...}/**
* Calculate the nth value of the fibonacci sequence.
*/
public long fib(int n) {...}Applying the three criteria (restrictive, general, clear):
sort— under-restrictive. Ascending or descending? In place, or is the return ofvoidsupposed to imply in place? What about equal elements?square— over-general in one direction and over-specific in another: it namesMath.pow, which is a how, exactly the generality failure above; and it never says what happens on overflow.getResources— the mutability trap from java-mutability. Is the returnedListthe instance’s own list, so that the caller can add to it, or a copy? Restrictiveness: the spec’s silence permits either, so no caller can safely do anything with it.fib— under-restrictive on the domain and on the indexing convention. Isfib(0)0 or 1? What happens for negativen, or for annwhose answer overflowslong?
Formality
Specifications of software range in formality:
- informal — e.g. normal comments;
- semi-formal — structured English documentation, e.g. using Javadoc tags;
- formal — mathematical constraints, e.g. using Java syntax for boolean expressions.
Here is the same method specified three times, once at each level.
Informal:
/**
 * Withdraws an amount from this account and
 * returns how much is left.
 */
public int withdraw(int amount) {...}
This leaves three things open: what happens when amount is negative, what happens when amount is bigger than the balance, and whether the balance is changed when there is a failure.
Semi-formal — structured English, one tag per obligation:
/**
 * Withdraw an amount from this account.
 *
 * @param amount the amount to withdraw, must be a positive integer.
 * @return the new balance after the withdrawal.
 * @throws IllegalArgumentException if the amount is negative.
 * @throws InsufficientFundsException if the amount is greater than the current balance.
 */
public int withdraw(int amount) {...}
Formal — boolean expressions in Java syntax, with \old(...) naming the value an expression had before the call:
/**
 * Withdraws an amount from this account.
 *
 * @require amount >= 0
 * @require amount <= getBalance()
 * @ensure getBalance() == \old(getBalance()) - amount
 */
public int withdraw(int amount) {...}
There is no @throws in the formal version. The failure cases have not been forgotten: they have been moved into the caller’s obligations. The next section covers this.
Contracts
Specifications can be written using contracts:
/**
 * [Description of method's behaviour]
 *
 * @require [Precondition]
 * @ensure [Postcondition]
*/- If the code calling the method satisfies the precondition, then the method guarantees to satisfy the postcondition.
- If the code calling the method does not satisfy the precondition, then the method guarantees nothing — any behaviour is allowed.
Programming with contracts
\result names the returned value inside a postcondition:
/**
 * Withdraws an amount from this account.
 *
 * @require amount >= 0
 * @require amount <= getBalance()
 * @ensure getBalance == \old(getBalance()) - amount
 * @ensure \result == getBalance()
 */
public int withdraw(int amount) {
    // no need to check the conditions
}
int balance = myAccount.withdraw(amt);In the first @ensure, getBalance is written without the parentheses it has in the formal specification above.
It is up to the calling code to make sure it fulfils its side of the contract, i.e. 0 <= amt <= myAccount.getBalance().
The method body carries no validation at all, and the call site carries no error handling — the postcondition is unconditional, so balance is always meaningful.
Programming without contracts
The same method written defensively instead, with the failure folded into the return value:
/**
 * Withdraw an amount from this account.
 *
 * @param amount The amount to withdraw.
 * @return The balance of this account after
 *         the withdrawal successfully occurs,
 *         or -1 if it fails.
 */
public int withdraw(int amount) {
    if (amount < 0) {
        return -1;
    }
    if (balance < amount) {
        return -1;
    }
}
int balance = myAccount.withdraw(amt);
If(balance == -1) {
...
}The method body shows only the two checks; the success path is left out. The call site writes If with a capital where Java needs if.
The cost is visible on both sides: the method now checks twice on every call, and every call site has to branch on a sentinel. It also re-introduces exactly the restrictiveness problem from search — -1 has to mean both “a balance” and “it failed”.
Defensive programming
Definition (Defensive Programming) Explicitly checking for invalid inputs and bad situations, ensuring the software does not behave dangerously regardless of input.
Sooner or later someone will call the method without checking the precondition. Particularly when dealing with external input sources or when guarding critical resources, it may be better to be defensive outside the wall and use contracts inside it.
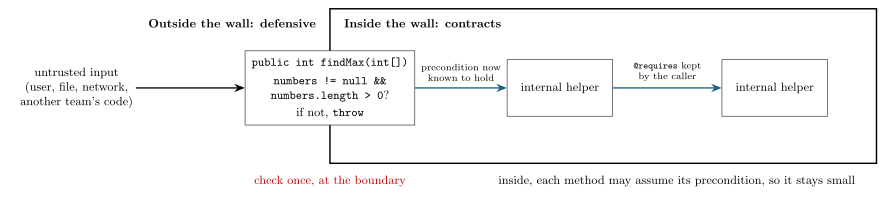
Figure 11: Defensive outside the wall, contracts inside it: validate defensively where untrusted input crosses into the system, and rely on contracts for the internal calls behind that boundary, so the check happens once rather than at every hop. The gate box is the findMax method worked through below.
Worked example: findMax
The starting point, with no specification and no checks:
public int findMax(int[] numbers) {
    int max = Integer.MIN_VALUE;
    for (int i = 0; i < numbers.length-1; i++) {
        if (numbers[i] > max) {
            max = numbers[i];
        }
    }
    return max;
}
Documented, and with the defensive check added:
/**
 * Finds the maximum value in the given array of integers.
 *
 * @param numbers An array of integers from which the maximum value is to be found.
 * @return The maximum value in the array.
 * @throws IllegalArgumentException if the array is null or empty.
 *
 * @requires numbers != null && numbers.length > 0
 *    - The array must not be null.
 *    - The array must contain at least one element.
 *
 * @ensures
 *    - The method returns the maximum value found in the array.
 *
 */
public int findMax(int[] numbers) {
    if (numbers == null || numbers.length == 0) {
        throw new IllegalArgumentException("Array must not be null or empty.");
    }

    int max = Integer.MIN_VALUE;
    for (int i = 0; i < numbers.length; i++) {
        if (numbers[i] > max) {
            max = numbers[i];
        }
    }
    return max;
}
This version writes the precondition down as @requires, promises an exception in @throws for callers who break it anyway, and then checks it in the body — belt and braces, which is the whole point of being defensive at a boundary. Without the check, a null array throws NullPointerException and an empty array silently returns Integer.MIN_VALUE as if that were a real maximum.
The first version loops i < numbers.length-1 and the documented version loops i < numbers.length. The first version therefore never examines the last element, so findMax(new int[]{1, 2, 9}) returns 2. No specification was attached to the first version, so nothing about it was wrong according to its spec, because it did not have one.
Further reading
Key takeaways
- A specification describes the contract between a method and its client.
- It explains what the method does, not how it is implemented.
- A good specification clearly states:
- Preconditions — conditions that must be true before the method is called;
- Postconditions — conditions that will be true after the method finishes successfully;
- Side effects — any additional changes the method makes to the system.
- Clear specifications make code easier to understand, use, and maintain.
Java Testing
Introduced in 2026-03-26-testing (Lecture, Week 5).
Levels of testing
- Unit testing — check that each “unit” in the project behaves correctly.
- Integration testing — check that components work together and that the interfaces between components work as expected.
- System testing — does the system as a whole work correctly?
- (User) acceptance testing — do users of the system agree that the system does what it’s supposed to do?
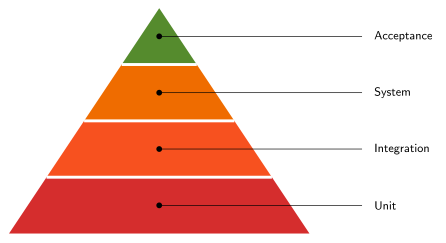
Figure 12: The four levels of testing as a pyramid. Unit tests form the wide base, acceptance tests the narrow apex. In the usual test-pyramid reading, the width of a band stands for how many tests of that kind a project has.
Test frameworks
Libraries that make writing and running tests easier. xUnit is the prevalent family — JUnit, NUnit, CPPUnit, PyUnit, … — and this course uses JUnit 4 (http://junit.org/junit4); see java-junit.
Depending on how the software is structured, a unit-testing framework can also be driven for other kinds of automated testing. A caveat: “unit testing” is sometimes incorrectly used to mean any automated test.
Regression testing
During development, testing helps answer (at least) two questions:
- Does the new stuff work?
- Have we broken things which used to work — have we regressed?
Regression testing ensures that old features are still working as they should when new features are introduced.
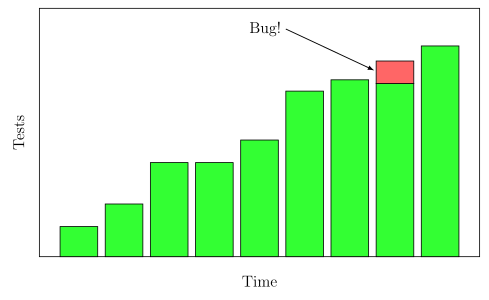
Figure 13: A regression (chart after browserstack.com/guide/regression-testing). Nine bars on Tests/Time axes: read each bar as a build, and its height as the size of the test suite growing as features are added. The red top slice on the second-to-last bar is the regression, and the arrow labelled Bug! points at it.
Black box vs white/glass box testing
- Black box — the software has inputs and outputs to test, but the implementation is unknown to you; you test according to the specification (see java-specification) — what it’s supposed to do.
- White/glass box — testing designed with knowledge of the internal implementation, so tests can pay special attention to cases where the implementation is complicated.
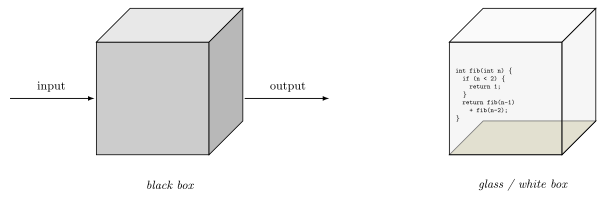
Figure 14: The two testing stances. Both are the same grey cube. The black box is opaque and shows only its input and output arrows. The glass box is translucent, so the implementation inside, a recursive fib, can be seen through its walls.
Black box techniques
Black box testing works from the Javadoc alone. The running example is a bus, and the specification is all you get:
/**
 * Calculate how many passengers are currently on the bus.
 *
 * @returns The number of passengers on the bus.
 */
public int getCurrentPassengers() {...}

/**
 * Calculate the average number of passengers on the bus between stops.
 *
 * @returns The average passengers on the bus.
 */
public int getAverageCount() {...}The tag is written @returns here and @return in the specification tag table from the exceptions lecture. The course uses both spellings — see csse2002-diagram-notation, “Specification tag spelling”.
Smoke tests — test the common-case functionality. Usually the first test to be performed (“can it run?”), used to determine whether further, more rigorous testing is required. The name comes from electronic hardware testing: plug in a new board, turn on the power, and if you see smoke coming from the board, turn the power off — you don’t have to do any more testing. (From Lessons Learned in Software Testing.)
Boundary tests — investigate extremes and corner cases, i.e. where bugs often occur:
| Input type | Try |
|---|---|
| Whole number | 0, -1, minimum value, maximum value |
| Floating point | 0, -1, NaN, infinity |
| Collection (array, list, set, etc.) | empty, one element, large |
| Reference type | null |
| Resource (file, link) | non-existent resource |
Equivalence classes — groups of inputs that the system treats the same way. For getCurrentPassengers() on a bus whose maximum capacity is 80, build the table in two passes: first the classes, then the boundary tests for each class.
| Class | Values | Boundary tests |
|---|---|---|
| Valid – Empty | 0 | -1, 0, 1 |
| Valid – Normal | 1 – 79 (any number within the range) | Covered by above and below |
| Valid – Full capacity | 80 | 79, 80, 81 |
| Invalid | – | -1, 81 |
Minimal boundary set: -1, 0, 1, 79, 80, 81. The “Normal” class contributes no probes of its own because its edges are already the outer probes of the classes on either side.
The black-box method
The method in six points:
- Black box testing: no knowledge of implementation, only specification.
- JUnit is a test framework.
- Tests must not violate preconditions.
- Start with smoke tests.
- Expand test suite with boundary tests.
- Stop when confidence is high.
Point 3: a test that breaks @requires proves nothing, because the method is free to do anything at all once its precondition is violated. Point 6: testing is never exhaustive, so you stop on judgement rather than on a completeness proof. The loop argument below makes the same admission concrete.
White box technique: code coverage
With tests and an implementation, code coverage measures how much of the code is actually tested: of all the different ways your program could run, how many are covered by your tests. There are three levels, in this order:
- Statement coverage — each statement is executed.
- Branch coverage — each branch is tested for the
truecase and thefalsecase. - Path coverage — every ‘path’ through the code is traversed.
A worked example:
public void register(int x) {
    if (x > 0) {
        positives += 1;
    }
    if (x % 2 == 0) {
        evens += 1;
    }
}- Statement coverage: any odd positive value, e.g.
x = 1, gives a partial run:if (x > 0),positives += 1and theif (x % 2 == 0)test are executed whileevens += 1is missed.x = 2alone executes every statement, since it is positive and even so bothifbodies run. - Branch coverage:
x = 2makes both conditionstrueandx = -1makes bothfalse, sox = 2andx = -1together give each condition both outcomes,true, false. Two tests. - Path coverage: all four combinations of the two conditions, so four tests. The four inputs are in the table below.
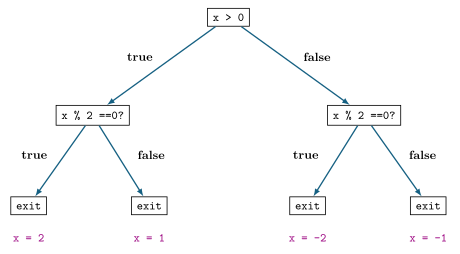
Figure 15: Path coverage for register. Each internal box is a condition, each teal arrow an outcome labelled true/false, each leaf one complete path to exit — four leaves, so four tests. The magenta input under each leaf is a value of x that drives that path.
Written out, the four paths and their inputs are:
| Path | x |
|---|---|
x > 0 && x % 2 == 0 |
2 |
x > 0 && !(x % 2 == 0) |
1 |
!(x > 0) && x % 2 == 0 |
-2 |
!(x > 0) && !(x % 2 == 0) |
-1 |
The three levels run from weakest to strongest, and this exercise makes that concrete: the same x = 2 that gives full statement coverage misses three of the four paths. That is why “100% statement coverage” is a weak claim.
Loops make exhaustive path coverage infeasible
for (int i = 0; i < 100; i++) {
    if (f(i, k)) {
        j++;
    }
}
There are \(2^{100}\) paths through this program — 1,267,650,600,228,229,401,496,703,205,376 of them. At a billion tests per second that is 40.2 trillion years, roughly 2900 times the age of the universe.
So path coverage is approximated. The common approximation is that 2 or more iterations through a loop, or recursive calls, are equivalent. This is engineers’ induction: “One, two, three — that’s good enough for me.” For for (init; test; iterate) { body } the three cases to test are:
- 0 iterations:
init;test(fails);nextStatement; - 1 iteration:
init;test;body;iterate;test(fails);nextStatement; - 2 iterations:
init;test;body;iterate;test;body;iterate;test(fails);nextStatement;
Using JUnit for white-box testing
Design tests based on internal logic. You try to cover branches, loops and edge cases, and you may aim for a code coverage target (e.g. 100%). A worked white-box example — DiscountCalculator, the five tests that cover it, and its branch tree — is in java-junit.
Test Driven Development (TDD)
The TDD approach originates from the Agile manifesto principles and Extreme Programming. In TDD, developers create small test cases for every feature based on their initial understanding. The primary intention is to modify or write new code only if the tests fail — this prevents duplication of test scripts. Use the tests to determine when code is “ready”.
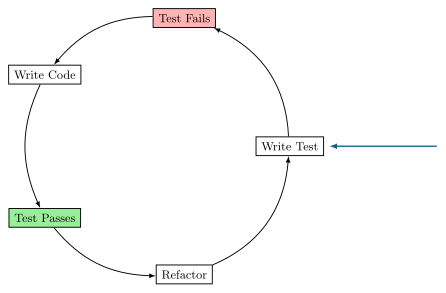
Figure 16: The TDD cycle. Read it counter-clockwise: write a test, watch it fail (pink), write code, watch it pass (green), refactor, and go round again. The teal arrow on the right points at Write Test and marks the entry point of the loop: the test comes before the code.
The Refactor step connects to java-refactoring: the green test suite is what makes it safe to restructure code without changing its behaviour.
Version Control
A Week 4 supplementary topic, and the only one in the course that isn’t about Java. Not examinable (confirmed in 2026-05-28-course-summary-and-exam-preparation) — but it’s the piece of the course you’ll use every day afterwards.
Why
Software changes frequently, and version control preserves the history of those changes. The everyday shape of the thing is a word processor’s version-history sidebar: a list of edits, each entry timestamped and attributed to a named collaborator, with a Restore this version button.
The alternative most students reach for — copying files into another directory — is incredibly error prone. It ends up as a folder of Super Cool Report v1.xlsx … v3.1 … v4a … v4b … vFinal … vFinal_1 … vFinal_Final … vFinal_Final-UPDATED_NEW.xlsx, or a set of directories running project-v0.1 through project-v2.3 with a project-v2.1-backup wedged in the middle.
In real development we want three things that copying can’t give us:
- To work on our own version and send changes back (commit) when they work. We don’t want everyone editing the same code in real time; the software would rarely compile while others were working on it.
- Labelled changes — a record of what changed and why, so bad changes are easy to find and undo. Changes frequently introduce new bugs.
- To work with any text files, not just source.
What a VCS does
A version control system tracks a folder and its contents, the history of changes within it, and metadata about that history (when a change was made, and by whom). History is recorded as snapshots — the entire contents of the folder at one point in time.
Benefits in this course:
- Inspect old versions of your code — “this was working before!”
- Identify what you changed recently — and remember, be suspicious of recently changed code when debugging (see week5-lab-debugging).
- Practice for your future career.
Terminology
| Term | Meaning |
|---|---|
| Version control | Tracking the history of changes such that old versions can be restored |
| Repository | A folder placed under version control |
| Commit | A snapshot of a repository at a point in time |
| History | A list of commits in a repository |
By market share: Git 93.87%, Subversion 5.17%, none 4.31%, Mercurial 1.13%.
When to commit
Commit when you create something that works, or fix something that was broken.
| Commit | Do not commit |
|---|---|
Finished the dependencies method of addCustomer |
It’s 5 o’clock |
Fixed the code style of AddressBook |
Changing to a new computer |
Fixed a bug in Farm.core |
Completed the assignment |
Fixed a typo in the description of the update method |
The pattern: the left column describes a change to the code; the right column describes something that happened to you. A commit message should be about the former.
The staging area
To prepare a commit you add your changes to the staging area — the middle ground between what you have done to your files (the working directory) and what you last committed.
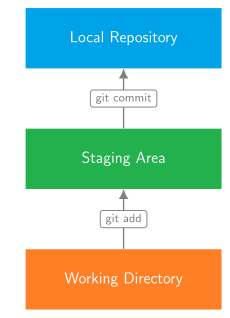
Figure 17: The three places a change can be, and the one command that moves it between each pair. This is the whole reason the staging area is a separate idea: git add does not save anything permanently and git commit does not look at your files, it looks at what you staged.
What should be committed?
Not everything in a folder belongs in version control. A repository should contain everything required to build or run the project, and not more.
- Beware generated files — if you don’t edit the file, don’t commit it.
- Beware proprietary formats like PowerPoint or Word documents — if your file is not plain text, consider leaving it out.
- Tell Git what to skip with a
.gitignore.
Common commands
| Command | Does |
|---|---|
git init |
Create a new Git repository |
git add |
Add working changes to the staging area |
git commit |
Commit the changes in the staging area |
git log |
View the repository history |
git diff |
View working changes |
Remotes — and a warning
A repository can be stored on a remote site; popular ones are GitHub, GitLab and BitBucket. An account with a lot of contributions can look good on a resume, but the rule that matters here is:
Do not make assessment public on these websites.
Publishing coursework counts as showing your code, which csse2002 lists explicitly under misconduct.
Further learning
Git is a powerful tool you’ll use extensively, and there is much more to it than the above. To go further, use the Git edX courses (accessible with a UQ student account) and the Atlassian Git tutorials.