CSSE1001 — Full Course Notes
Week 1
A Brief History of Computing
Lecture 1A, the first hour of week 1. Course logistics are in csse1001. Lecture 1B, the same day, is 2025-07-29-python-as-a-calculator.
Six questions, grouped into four sections below. Five get a tentative definition, a “perhaps…”, not a formal claim. The exception is how do we describe something to a computer?, which is answered with examples and code listings, not a definition. This hour is one of the two blocks csse1001 carves out of assessment (the other is all of week 13). It sets up the definitions that the end of the course returns to. See history-of-computing for the full reference, including the hardware timeline, the Turing machine figure and the language progression.
Outline
- What is a computer?
- What is software?
- How do we describe something to a computer?
- What is an algorithm? What is computer science? What is software engineering?
What is a computer?
A computer is a machine that can carry out sequences of arithmetic or logical operations automatically.
The word machine has not always applied: the Harvard “Computers” of the 1800s were people doing calculations by hand.
Formally, a finite state machine changes state when given input; a Turing Machine is a finite state machine with (infinite) read/write memory called tape, and is a general purpose computer — one machine that can be programmed to do different tasks. Alan Turing gave this definition, showed some problems are not computable, and helped break Enigma. Charles Babbage designed the first general purpose computer (the Analytical Engine; the schematics are dated 1840), never built in his lifetime — hardware following the design was assembled in 1910 as a four-operation calculator.
A concrete example of a finite state machine is a Turing machine that adds two binary numbers, with carry and no carry as its two working states. The formal theory belongs to Theory of Computing (COMP2048), so it is background here, not examinable material. The machine is drawn and read transition by transition in history-of-computing.
The hardware timeline runs Z3 (1941) → ENIAC (1945) → EDVAC (1949) → UNIVAC 1 (1951) → integrated circuit (1958) → UQ’s GE-225 (1962) → Intel 4004 (1971) → 8086 (1978) → Pentium (1993) → today’s Threadripper. UQ’s own entry is the GE-225, installed in the Hawken Building (now the Prentice Centre) in 1962, weighing 900kg.
What is software?
Software is the complement of hardware. They are instructions for the machine.
Ada Lovelace described an algorithm for the Analytical Engine to compute Bernoulli numbers, making her the first computer programmer. Grace Hopper pioneered machine-independent, English-word-based programming and invented COBOL.
The first computer bug is a moth taped to a 1947 logbook page. The entry, made at 15:45 on 9 September, reads:
Relay #70 Panel F (moth) in relay.
First actual case of bug being found.
How do we describe something to a computer?
First the Jacquard loom, punch cards and the 5MB punch-card program. Then a ladder of languages, every rung the same integer exponentiation program:
machine code → assembly (1947) → Fortran (1957) → COBOL (1959) → C (1972) → Python (1991)
The listings get shorter overall as they get higher-level, though not at every step: 19 lines of x86 machine code, 22 lines of assembly, 11 of Fortran, 19 of COBOL, 7 of C, 5 of Python. By the Python version the loop machinery has vanished entirely:
def power(x: int, y: int) -> int:
    ans = 1
    for _ in range(y):
        ans = ans * x
    return ans
Python itself was written by Guido van Rossum and named after Monty Python — a general-purpose, high-level language meant to support several programming styles (see programming-paradigms) and be fun to use.
Algorithms, computer science, software engineering
An algorithm is an ordered sequence of unambiguous instructions that eventually terminates.
The language we use to express ourselves is less important than what we are expressing: an instruction sequence that does something useful, like sorting a list.
The example for the second statement is a nine-row trace of selection sort on [26, 54, 93, 17, 77, 31, 44, 55, 20], with no code beside it. The trace is drawn in sorting-algorithms, and selection sort comes back in week 13.
Computer science is the practice/art of creating algorithms and measuring their relative effectiveness.
Software engineering is the practice/art of creating and maintaining software (realized algorithms) in groups.
Where this comes back
“Creating algorithms and measuring their relative effectiveness” is the exact brief of the final lecture, 2025-10-28-complexity-and-sorting — five ways to sort a list (sorting-algorithms) and a formal way to compare them (algorithmic-complexity). The course opens and closes on the same definition, and on the same selection-sort trace.
Next lecture
2025-07-29-python-as-a-calculator, Lecture 1B: arithmetic expressions and variables.
Python as a Calculator
See csse1001 for course logistics. This is Lecture 1B. The same day’s first hour is 2025-07-29-a-brief-history-of-computing (Lecture 1A).
Outline
- The Python REPL
- Syntax vs. semantics
- Arithmetic expressions, order of operations, and associativity
- Variables
- Worked exam questions
Learning objectives
- Python expressions have syntax and semantics.
- Python can evaluate arithmetic expressions, but this requires an order of operations and rules for associativity.
The Python REPL
A REPL (read-evaluate-print loop) is an interactive environment for a programmer to work in: it reads input, evaluates it, prints the result, then loops. A four-line transcript makes the acronym concrete, one letter per line:
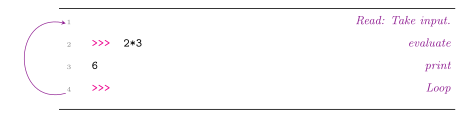
Figure 1: The four letters of read-evaluate-print-loop annotated onto the four lines of a transcript, with magenta >>> prompts and purple italic notes in the right margin. The return arrow is the loop. Only line 2 is typed by the user: line 3 is the printed result and line 4 is the prompt coming back.
The >>> prompt is only shown in the interactive REPL — it isn’t included when writing Python instructions into files. Every transcript below is REPL output, so read >>> lines as what was typed and unprefixed lines as what Python printed back.
Syntax vs. semantics
A programming language like Python has both:
- Syntax — defines what it means to be a valid program.
- Semantics — defines what a valid program actually does.
2 + 3 is syntactically correct Python and evaluates to 5. Prefix notation like + 2 3 (valid in Lisp) is not valid Python syntax:
>>> + 2 3
    + 2 3
      ^
SyntaxError: invalid syntax
Python’s language rules must be followed precisely for a program to run. Each new construct below has the same two parts: its syntax, which says what counts as a well-formed expression, and its semantics, which says what it evaluates to. See python-operator-precedence-and-associativity for all of them collected together, plus the order-of-operations table, associativity, integer division, and the ^ xor gotcha.
Building the expression language
Arithmetic is built up one construct at a time, each with its own transcript.
Constants and brackets. A constant is the most basic expression; if x is valid then so is (x), and bracketed expressions get evaluated first.
>>> 2
2
>>> (2)
2
>>> (  2   )                 # space is ignored
2
>>> ((2))
2
>>> 2)
    2)
     ^
SyntaxError: unmatched ')'
Negation and affirmation. If x is valid then +x and -x are valid; affirming is multiplying by positive one, negating is multiplying by negative one. Both chain freely, and neither can trail off the end of an expression.
>>> ++3
3
>>> +(+(3))
3
>>> 3+
    3+
      ^
SyntaxError: invalid syntax
>>> --3
3
>>> -+3
-3
>>> +-+-+-3
-3
Adding and subtracting. As a matter of style, bind the sign to the number it belongs to rather than leaving it floating next to the operator:
>>> 3 + - 3
0
>>> 3 + -3                   # best to group like this
0
>>> + 1 + + + 3
4
>>> +1 + ++3                 # best to group like this
4
>>> 2 - - 2
4
>>> 2 - -2                   # best to group like this
4Multiplication, which is where evaluation order starts to matter:
>>> 2 + 3 * 2 - 1            # multiplication was done first
7
>>> (2 + 3) * 2 - 1          # brackets change outcome
9
>>> 1 + 2 * 3 + 4
11
That last line is the argument for needing a rule at all: since 1 + 2 * 3 + 4 is 11 and not 13, * must be evaluated before +. Without an order of operations an expression like this is ambiguous.
Order of operations
For what has been introduced so far, the order is parentheses, unary -x/+x, *, then +/-. Once division, integer division, remainder and exponentiation are added, the full table becomes:
| Operator | Description |
|---|---|
() |
Parenthesis |
** |
Exponents |
-x, +x |
Negation, Affirmation |
*, /, //, % |
Multiplication, Division, Integer Division, Remainder |
+, - |
Addition, Subtraction |
Highest precedence at the top. Worked examples:
>>> 10 - 2 * 3               # multiplication before subtraction
4
>>> 2 * - 3                  # negation before multiplication
-6
>>> 2 * -3                   # best to group according to precedence
-6
>>> 1 - - 2 * - 3 - 4
-9
>>> 1 - -2 * -3 - 4          # best to group according to precedence
-9
Associativity
Precedence alone is not enough, because some operators share a level:
>>> 1 - 2 + 3
2
>>> 1 - (2 + 3)
-4
>>> (1 - 2) + 3
2
Since Python’s answer matches the left bracketing, + and - are left-associative. The rule: operators of the same precedence are left associative, excepting exponentiation which is right associative — so if # and @ have equal precedence, a # b @ c = (a # b) @ c.
>>> 3 * 1 // 2
1
>>> 3 * (1 // 2)
0
>>> 2 ** 1 ** 0
2
>>> (2 ** 1) ** 0
1
The bracketing Python uses is (3 * 1) // 2 for the first pair and 2 ** (1 ** 0) for the second.
Division, floats, exponents
>>> 4 / 2                    # notice the decimal
2.0
>>> type(2)
<class 'int'>
>>> type(2.0)
<class 'float'>
>>> 6 / 2 * (1 + 2)
9.0
>>> 1 / 3                    # notice this is an approximate solution
0.3333333333333333
>>> 1 / 0
Traceback (most recent call last):
  File "<stdin>", line 1, in <module>
ZeroDivisionError: division by zero
>>> 1 / float('inf')
0.0
>>> 2 ** 3.0
8.0
>>> 2 ** -1
0.5
>>> 0 ** 0
1
The int/float distinction is picked up properly next week in python-primitive-data-types.
Warning. The caret ^ is bit-wise xor, not exponentiation, and using it wrongly raises no error at all — 2 ^ 3 is 1 and 4 ^ 1 is 5.
Integer division
How can we divide two integers so that we get an integer?
Using “grade school” division: for x = 17 and y = 3 we say 17 ÷ 3 is 5 remainder 2, or equivalently \(17 = 5 \cdot 3 + 2\), or \(\tfrac{17}{3} = 5 + \tfrac{2}{3}\).
>>> 17 // 3                  # quotient
5
>>> 17 % 3                   # remainder
2
>>> 3 * (17 // 3) + (17 % 3)
17
Division algorithm. For positive integers \(x\) and \(y\) there is a unique quotient \(q\) and a unique remainder \(r\) with \(0 \leq r < y\) satisfying \(x = q \cdot y + r\). The remainder can be computed two ways, both using machinery that comes later:
>>> def remainder(x: int, y: int) -> int:
...     ans = x
...     while ans >= y:
...         ans = ans - y
...     return ans
>>> remainder(17, 7)
3
>>> def remainder(x: int, y: int) -> int:
... return x if x < y else remainder(x - y, y)
>>> remainder(17, 7)
3The first is python-while-loops (week 4); the second is python-recursion (week 12).
Worked exam questions
Q: What does 2 ** 3 % 5 - 1 evaluate to? (Options: 0, 2, 4, 7.)
((2 ** 3) % 5) - 1 = (8 % 5) - 1 = 3 - 1 = 2
Q: What value gets assigned to x in x = 35 * 2 % 5 ** 2? (Options: 0, 20, 70, 140, none of the above.)
(35 * 2) % (5 ** 2) = 70 % 25 = 20. python-operator-precedence-and-associativity draws out the two steps that produce that bracketing.
Variables
Values can be named — these names are called variables. Assigning a value to a variable doesn’t print anything in the REPL:
>>> width = 2
>>> height = 3
>>> area = width * height
>>> 4 * area
24
min and max
>>> max(1, 2)
2
>>> min(1, 2)
1
>>> max(5, 1, -2, 3, 2*7)
14
In the last one the arguments are themselves expressions, evaluated before max ever sees them.
Exercise: second largest of three numbers
Given three distinct numbers a, b, c, write an expression for the second largest. Three answers, set up with a multiple assignment:
>>> a, b, c = -9, 19, 3      # assignment like this saves vertical space
>>> a + b + c - max(a, b, c) - min(a, b, c)
3
>>> min( max(a, b), max(a, c), max(b, c) )
3
>>> max( min(a, b), min(a, c), min(b, c) )
3
Next lecture
- 2025-08-04-python-memory-model — Python memory model.
- 2025-08-04-primitive-data — Primitive data types.
Week 2
Primitive Data
See csse1001 for course logistics — this note covers Lecture 2B’s technical content.
Outline
- Primitive data types built into Python
- Booleans, integers, strings, and tuples
- Converting between types
Learning objectives
- There are more built-in types besides integers that can form expressions.
- These types are immutable.
- We can convert between types, albeit imperfectly.
Primitive data
The types “built-in” to Python by default are called primitive data. They are:
- booleans,
- integers,
- float (which we skip),
- strings, and
- tuples.
Booleans, integers and strings each come with a conversion function that shares the type’s name: bool, int and str.
See python-primitive-data-types for the full definitions, operators, and worked examples — comparison operators and truthy/falsy for booleans; unbounded precision for integers; concatenation, comparison, indexing/slicing and immutability for strings; and construction, indexing/slicing, immutability and packing/unpacking for tuples.
Key results
A handful of results carry everything else:
- Booleans are numbers when you need them to be.
Truehas integer value1, so3 + (2>1) + 3is7. Comparison has lower precedence than arithmetic, so3 + 2 > 1 + 3is(3+2) > (1+3). - Falsy is whatever acts as zero.
bool(0),bool("")andbool(())are allFalse; everything else in these types is truthy. A space is not empty —len(" ")is1andbool(" ")isTrue. - Strings and tuples are the same shape. Both are ordered, so both index from zero, index from the back with negatives, slice, concatenate with
+, and repeat with*. Both are immutable, so both reject item assignment with the sameTypeError—'str' object does not support item assignmentand'tuple' object does not support item assignment. A tuple slices with the same[start:stop:step]syntax as a string, e.g.xs[0:4]. - The singleton tuple needs its comma.
(1)is the integer1;(1,)is the tuple.(1) + (2,3)is the common error.
Converting between types — “albeit imperfectly”
Each of bool, int and str doubles as a conversion function, which gives six conversions among those three types. Only one of the six can fail — which is what the third learning objective is about.
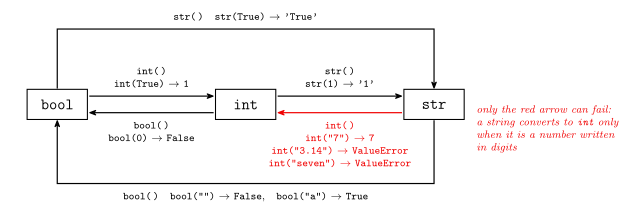
Figure 2: The six conversions among bool, int and str, each with an example call and its result. Only the red arrow, str to int, can fail. float is left out.
Python will not do the conversion for you: 3 + "7" is a TypeError, and you have to say whether you meant str(3) + "7" ('37') or 3 + int("7") (10).
Exercise: string comparison
An exercise on string comparison:
def string_less_than(cs: str, ds: str) -> bool:
    """
    Restrict yourself to comparing integers only.
    Return true only when cs < ds.
    >>> string_less_than("aba", "ab")
    False
    >>> string_less_than("aZ", "aa")
    True
    """
“Restrict yourself to comparing integers only” rules out < on the strings themselves and points at ord. The two doctests are the two cases that catch a naive attempt — a prefix loses to its extension ("aba" < "ab" is False), and an uppercase letter beats a lowercase one, since ord("Z") is 90 and ord("a") is 97.
Summary
We have booleans, integers, strings, and tuples. Strings and tuples are indexed and can be sliced. We can convert between the types (imperfectly).
Next lecture
- 2025-08-11-functions — Functions (sequence).
- 2025-08-11-sequence-selection-and-iteration — If-statements (selection).
Python Memory Model
Lecture 2A. See csse1001 for course logistics.
Outline
- Memory as a sequence of bits
- Variables as named memory locations
- Sequencing: why the order of instructions matters
Learning objectives
- Memory is a sequence of bits that we can toggle.
- We can (and should) store values in named memory locations called variables.
- The order of instructions matters.
How much can a byte hold?
Computer memory is a very long series of on/off switches (bits, short for binary digit). Eight consecutive bits form a byte, and 4 or 8 bytes form a word (depending on machine architecture).
To see how much can be stored in a byte, build up: one bit, two bits, three bits, four bits.
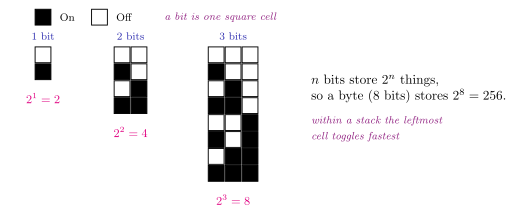
Figure 3: Adding a bit doubles the number of things you can code. The three stacks enumerate every pattern of one, two and three bits (filled = on, empty = off). Within each stack the leftmost cell toggles fastest (off-off, on-off, off-on, on-on), which reads the leftmost cell as the least significant; a word read as an integer is read the other way round. A byte is 8 bits, so it stores \(2^8 = 256\) things.
In general, \(n\) bits store \(2^n\) distinct things:
- 1 bit: \(2^1 = 2\) things (
off,on) - 2 bits: \(2^2 = 4\) things (
off-off,on-off,off-on,on-on) - 3 bits: \(2^3 = 8\) things
- 4 bits: \(2^4 = 16\) things
A byte is eight bits, so it codes \(2^8 = 256\) things.
A very long series of such bits is computer memory. We put something in memory by toggling the on/off bits into some meaningful configuration; in Python the “somethings” we put in memory are called objects.
Variables and memory
See python-variables-and-memory-model for how Python interprets a word of memory as a typed object, how id() reveals an object’s address, and the rules for assigning, retrieving, naming, and reassigning variables. In brief:
- A word of bits means nothing until a type says how to read it —
x = 3931377233both toggles the bits and records “read this as an unsigned 32-bit integer”. The type dictates which functions are compatible with the object. - Memory is divided into addressed words;
id(42)returns the address where42is stored. - A variable is a nickname for one of those addresses. Assignment prints nothing, because its imperative is to perform an action (a state change to memory).
=is assignment, not equality: readx = x + 1as “xgetsx+1”.
Sequencing: order matters
The same instructions executed in a different order will (usually) produce a different outcome. Five short programs make the point, each one to step through in Python Tutor.
Python Tutor 1 — the two lines cannot be swapped:
>>> x = 1
>>> x = x + 1
x = x + 1 cannot come first: the name x has no associated value on line 1, so evaluating the right-hand side throws a NameError.
Python Tutor 2 and 3 — the same three assignments, the last two swapped, giving 4 and 3:
>>> x = 1
>>> x = x + 1
>>> x = 2*x
>>> x
4
>>> x = 1
>>> x = 2*x # swapped
>>> x = x + 1 # swapped
>>> x
3Python Tutor 4 and 5 — two variables, and the assignment that gets clobbered decides which value survives:
>>> x = 2
>>> y = 3
>>> y = x
>>> x = y
>>> x
2
>>> y
2
>>> x = 2
>>> y = 3
>>> x = y
>>> y = x
>>> x
3
>>> y
3The last two lines are the ones that change between these two examples — the first two assignments are identical.
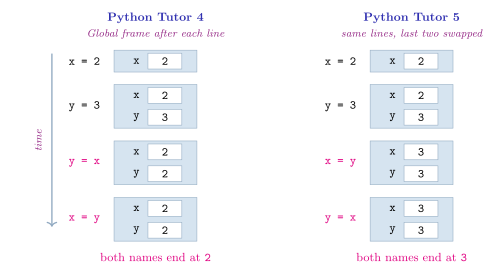
Figure 4: Why examples 4 and 5 disagree: the first assignment of the swapped pair overwrites one name, and the second then copies the overwritten value back — so both names always end up equal, but at 2 when y = x goes first and at 3 when x = y does. The two reordered lines are magenta. Each pale blue box is the global frame after that line, drawn the way Python Tutor shows it: one row per name, value in the slot. y does not exist until line 2.
Neither ordering swaps x and y, which is what these four lines look like they should do. Swapping two names needs a third name to hold one value while the other is overwritten (or the tuple packing of 2025-08-04-primitive-data).
Summary
We can manipulate memory using Python and refer to that memory with variables. The order in which we do this manipulation matters — the same sequence of instructions done in a different order will (usually) result in a different outcome.
Next lecture
2025-08-04-primitive-data — immutable objects (the things we put in memory that cannot be changed).
Week 3
Functions
Lecture 3A. See csse1001 for course logistics.
Outline
- What a function is and how to define one
- The
returnstatement, and how it differs fromprint - Improving a function with type hints and docstrings
- PEP8: how the course expects that code to be laid out
Learning objectives
- User-defined functions bundle code together and are the building blocks of more sophisticated programs.
returnhands back a value and exits the function; it is not the same asprint.- Functions can be documented with type hints and docstrings, neither of which Python enforces.
What is a function?
User-defined functions are perhaps the single most important feature of programming languages. They let us abstract away complexity by bundling lines of code together, and are themselves the building blocks of more sophisticated functions.
We have already been using functions — * and max, for example. Each takes input and returns output: multiplication takes two numbers and returns a number; max takes two or more numbers and returns a number.
Python functions are analogous to those of mathematics and can also be named. A parabola in mathematics is given by the function \(f(x) = x^2 + x + 1\), and in Python we write
>>> def f(x):
...     return x**2 + x + 1
>>> f(3)
13
See python-functions for the full syntax rules — indentation, multiple parameters, the return statement, return vs. print, type hints, and docstrings — all of which are used throughout the rest of this note.
Building up Heron’s formula
One function, built three times over, each version better than the last. The exercise:
Exercise (Heron’s formula). The area of \(\triangle ABC\) is \(\sqrt{s(s-a)(s-b)(s-c)}\) where \(s = \tfrac{1}{2}(a+b+c)\). Write a function which computes the area of a triangle from the side lengths \(a\), \(b\), \(c\).
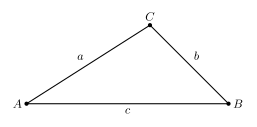
Figure 5: The triangle and its side labels: a on the side from A to C, b on the side from C to B, c on the side from A to B. That is not the usual convention, under which each side is named for the vertex opposite it — here only c is opposite its namesake vertex, while a sits alongside A and b alongside B. Heron’s formula is symmetric in a, b and c so this changes no arithmetic, but it changes what you should picture when the code says a.
Question. What is the area of the triangle with sides 3, 4, and 5?
Answer 1 — Python as a calculator. Everything inline, s spelled out four times over:
>>> (0.5*(3+4+5)
... *(0.5*(3+4+5)-3)
... *(0.5*(3+4+5)-4)
... *(0.5*(3+4+5)-5))**0.5
We have to type a lot. It would be hard to repeat.
Answer 2 — using names and sequencing. Naming s once removes the repetition (see 2025-08-04-python-memory-model):
>>> a, b, c = 3, 4, 5
>>> s = (a + b + c)/2
>>> (s*(s-a)*(s-b)*(s-c))**0.5
6.0
But the names are now stuck at those three values — a different triangle means retyping the lot.
Answer 3 — using functions. The same three lines, parameterised and reusable for any triangle:
>>> def heron(a, b, c):
...     s = (a + b + c)/2
...     return (s*(s-a)*(s-b)*(s-c))**0.5

>>> heron(3, 4, 5)
6.0
The result is 6.0, not 6: **0.5 produces a float.
Improving the function: type hints
In mathematics we would define a mapping \[\text{triangle\_area} : \mathbb{R} \times \mathbb{R} \times \mathbb{R} \to \mathbb{R}.\] In Python we can write that mapping into the def line itself:
>>> def triangle_area(a: float, b: float, c: float) -> float:
...     s = (a+b+c)/2
...     return (s*(s-a)*(s-b)*(s-c))**0.5
>>> triangle_area(2.2, 3.3, 4.4)
3.5147323866832307
Type hints are not enforced. They are documentation, for making the code more readable — annotate the same function str throughout and it still returns the same float. See python-functions.
Improving the function: docstrings and examples
>>> def triangle_area(a: float, b: float, c: float) -> float:
...     """
...     Return the area of the triangle with sides length <a>,
...     <b>, and <c>.
...     Preconditions: <a>, <b>, <c> are all nonzero positive.
...     >>> triangle_area(3, 4, 5)
...     6.0
...     """
...     s = (a+b+c)/2
...     return (s*(s-a)*(s-b)*(s-c))**0.5
That is the full shape the course expects of a Python function: def line with type hints, docstring with a short description, preconditions, and a worked example, then the body, then return.
return, and what it does to the lines below it
return is a reserved word — one that cannot be assigned by us. It designates what value the function should return while also terminating the function itself.
The striking case is the one where the return is the first line:
>>> def example(x):
...     return 3*x
...     return 2*x
...     print(1*x)

>>> a = example(1)
>>> a
3
Neither the second return nor the print ever runs. The other variants of this question, and the diagram of what control actually does, are in python-functions.
A function with no return at all returns None:
>>> def example(x):
...     print(2*x)
>>> a = example(1)
2
>>> a
>>> type(a)
<class 'NoneType'>
The default return value is None, and print is exactly this kind of function: it returns nothing, and its side effect is that it displays something.
Exercise: the middle number
Exercise. Write a function that takes three integers and returns the number which is not the largest or the smallest.
def middle_number(x: int, y: int, z: int) -> int:
    """Return the number that is not the largest or smallest
    among the three inputs.

    Precondition: The numbers are distinct.

    >>> middle_number(3, 1, 2)
    2
    >>> middle_number(2, 3, 1)
    2
    """
    return (x+y+z) - min(x, y, z) - max(x, y, z)
The trick is that the three numbers sum to (smallest + middle + largest), so subtracting min and max leaves the middle one — no comparisons or if-statements needed.
Two worked questions
What is the type of foo’s return value?
def foo(radius: int):
    """
    Precondition:  radius > 0
    """
area = 3.14159 * radius**2NoneType. There is no explicit return statement, so the computed area is thrown away.
Is this valid Python code?
def foo(x: int, y: int) -> int:
    """
    >>> foo(2, 3)
    6
    """
    return x
ans = foo("oi", 3)
Yes. Type hints are not enforced. The docstring’s own example is wrong too — this foo returns x, so foo(2, 3) is 2, not 6 — and Python will not complain about that either unless the doctests are actually run. See python-testing.
Style: PEP8
The style rules apply to every function above. A PEP is a Python Enhancement Proposal — a design document on how to style our code — and this course follows Google’s PEP, a variant of PEP8. In brief: names start with a letter, are lowercase and underscore-separated; lines stay strictly under 80 characters, wrapped inside a redundant enclosing bracket; and a comment should explain something not obvious in the design rather than restate the line it sits on. The yes/no tables for naming and spacing, and the rule behind the spacing one, are in python-pep8-style-guide.
Summary
Blocks of code can be grouped into functions. Functions take zero or more inputs and hand back a single value designated by return.
Next lecture
2025-08-11-sequence-selection-and-iteration — selection.
Sequence, Selection, and Iteration
Lecture 3B. Course logistics are in csse1001.
Outline
Despite the title, this is entirely about selection — controlling program flow. Sequencing is in 2025-08-04-python-memory-model, and iteration is the topic of the next lecture. The order is: boolean logic → the if statement → refactoring the if-statements you end up with.
Learning objectives
- Predicates and the logical operators
and,or,notlet us build up complex conditions. - The
ifstatement, and itselif/elsevariants, lets us skip or select blocks of code based on a condition. - If-statements can often be refactored into simpler, equivalent forms — and some innocuous-looking ones are silently wrong.
Part 1 — logic
The basic operands of logic are True, False, or, and, not. Let \(\mathbb{B} = \{\texttt{True}, \texttt{False}\}\) be the boolean domain; a predicate is any function mapping into \(\mathbb{B}\), and and, or are themselves predicates \(\mathbb{B} \times \mathbb{B} \to \mathbb{B}\).
Three results that catch people out:
andbinds tighter thanor, andnotis evaluated first among the three.notis still looser than the comparison operators, sonot a == 6parses asnot (a == 6).and/orshort-circuit, soTrue or 1/0isTruewhileFalse or 1/0raises. Short-circuiting saves you from evaluating the right operand, not from parsing it:True or !is still aSyntaxError.and/ordo not returnTrue/False—andreturns its first falsy operand,orits first truthy one, and the last operand if there is no such value. Hence0 or 2is2.
Full reference, truth tables, and worked transcripts: python-boolean-logic.
Worked question — truthiness
Which of these evaluate to True?
bool(not () and "hello")
bool(True or 1/0)
bool(" ")
bool(2 > True)
bool("False")
All five. () is falsy, so not () is True and and hands back "hello"; or short-circuits before dividing; " " is a non-empty string; True is 1, so 2 > True; and "False" is a non-empty string whatever it spells.
Exercises
Bracket for False. Bracket the expression below so that it evaluates to False. How many different bracketings can you find?
False and False or True and False or False or TrueAdd a single not. Add a single not to the same expression so that it evaluates to False.
Part 2 — the if statement
Definition (if-statement). Given a condition \(C\) (i.e. a predicate that evaluates to
TrueorFalse), an if-statement is a control structure that executes a block of code when \(C\) isTrue(and skips it otherwise).
It comes in four shapes — if, if/else, if/elif, if/elif/else — each with its own flowchart. The four flowcharts, plus the code templates and the warnings that go with them, are in python-if-statements.
Two warnings:
>>> if False:
...     ans = 0
>>> ans
NameError: name 'ans' is not defined
A variable assigned only inside a skipped block does not exist afterwards. And:
>>> if x == 1 or 2 or 3:
...     print("hello")
This always prints, because it parses as (x == 1) or 2 or 3 and 2 is truthy on its own. You need x == 1 or x == 2 or x == 3 — later refactored to x in [1,2,3].
Worked example — the beverage chain
The running example, and the bug it is built to expose:
>>> age = 60

>>> if age >= 18:
...     beverage = "cheap beer"
... elif age >= 30:
...     beverage = "standard beer"
... elif age >= 50:
...     beverage = "expensive beer"

>>> beverage
'cheap beer'
This code does not work as intended. Nothing in it is a syntax error and every condition is individually correct; the fault is entirely in the order. Because each elif is only reached when everything above it failed, and age >= 18 is the loosest test, a 60-year-old is caught by the first branch and the other two can never fire for anybody:
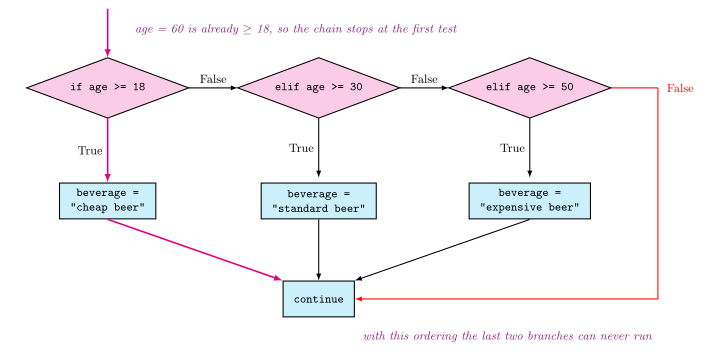
Figure 6: The buggy beverage chain as an if/elif/elif flowchart. The magenta trace is the path age = 60 takes. The red edge is the False exit from the last test, where no branch runs. Because age >= 18 is the loosest test and sits first, any age reaching the second diamond is already under 18 — so the second and third branches can never run, for any age at all.
Fix 1 — make the ranges disjoint (18 <= age < 30, 30 <= age < 50, 50 <= age). Once they are disjoint the elifs are not earning their keep; three separate ifs would do the same job.
Fix 2 — keep the open-ended tests but order them tightest-first (>= 50, then >= 30, then >= 18), so each elif inherits a guarantee from the ones above it: reaching the second test guarantees age < 50, reaching the third guarantees age < 50 and age < 30.
Both fixes still leave age = 9 with no branch at all and hence a NameError on beverage; adding else: beverage = "apple juice" is what closes that off. The code for all of these, and the flowchart contrast between a chain with and without an else, is in python-if-statements.
Part 3 — factoring and refactoring
Definition (factoring). In computer science factoring means breaking a complex problem into parts that are easier to conceive, understand, program, and maintain.
Definition (refactoring). Code refactoring is the process of restructuring existing computer code — changing the factoring — without changing its behaviour.
The if-statement simplifications (nested ifs → one anded condition; if/else returning True/False → return the condition; == True / == False → drop it or not it) are written out in python-if-statements.
Worked question — is elif the same as a second if?
Equivalent. An elif may drop whatever the condition above it already ruled out:
>>> if x > 0:                     >>> if x > 0:
...     print("A")                ...     print("A")
... elif x <= 0 and x % 2 == 0:   ... elif x % 2 == 0:
...     print("B")                ...     print("B")
Reaching the elif already guarantees x <= 0, so the extra conjunct is redundant.
Not equivalent. Change both elifs to if and the same edit becomes a bug, because the second if is independent of the one before it:
>>> if x > 0:                     >>> if x > 0:
...     print("A")                ...     print("A")
>>> if x <= 0 and x % 2 == 0:     >>> if x % 2 == 0:
...     print("B")                ...     print("B")
Let x = 2. The first prints A; the second prints A and B.
Refactoring exercise
Exercise. Refactor the code.
def foo(x, y):
    if x > 100 and y > 0:
        if y > 100 and x > 0:
            return "A"
        elif y > 100 or x > 0:
            return "A"
        else:
            return "B"
    elif y <= 0 or x <= 0:
        if x == y:
            return "A"
        if x <= y and x >= y:
            return "B"
        if y < x and x < y:
            return "C"
        else:
            return "A"
    else:
        if x <= 100 and y > 0:
            return "A"
        if x > 100 or y <= 0:
            return "B"
        else:
            return "D"
The tools it is built to exercise are all above: conditions that are already guaranteed by an enclosing branch, mutually exclusive conditions that can never both hold (
x <= y and x >= ymeansx == y;y < x and x < yis impossible), andif/returnpairs that need noelse.
Summary
Blocks of code can be skipped using if statements. This control flow depends on the evaluation of predicate statements.
Next lecture
2025-08-18-while-loops — iteration.
Week 4
Non-Primitive Data
See csse1001 for course logistics. This is Lecture 4B.
Outline
- Lists: mutable ordered collections
- Dictionaries: hash tables
Learning objectives
- Lists are mutable ordered collections; tuples (python-primitive-data-types) are immutable ordered collections. Both can be sliced and indexed.
- A name bound to a list is a reference, so copying, appending and passing to functions do not always do what they look like they do.
- A dictionary maps keys to values via a hash function, and is unordered and mutable.
Lists
Definition (List). A list is a mutable ordered collection of elements. These elements are not necessarily of the same type. Square brackets
[]are used to create lists in Python.
See python-lists for the full reference on lists: creation, mutability, comparison, membership, append/extend, aliasing, copying (shallow/deep), passing to functions, slicing, nested lists/matrices, type hints, and unpacking into function arguments. Two of those matter most and are drawn out there as figures — that ys = xs makes an alias rather than a copy, and that .copy() on a list-of-lists is only shallow.
Exercise: counting occurrences
def count(xs: list[int], ys: list[int]) -> int:
    """ Return the number of times members of ys are in xs.
    >>> count([1, 2], [1, 2, 3, 4])
    2
    >>> count([1, 2], [1, 2, 2, 2, 3, 1, 4])
    5
    """
A while-loop solution (python-while-loops), walking ys by index:
def count(xs: list[int], ys: list[int]) -> int:
    ans, k = 0, 0
    while k < len(ys):
        y = ys[k]
        k += 1
        if y in xs:
            ans += 1
    return ans
It is certainly better to use for-loops in this situation:
def count(xs: list[int], ys: list[int]) -> int:
    ans = 0
    for y in ys:
        if y in xs:
            ans += 1
    return ans
There is also a one-line solution:
def count(xs: list[int], ys: list[int]) -> int:
    return sum(y in xs for y in ys)
(This last one relies on True counting as 1 under sum, and on the generator-expression syntax that 2025-08-25-comprehensions introduces the week after.)
Exercise: rotating a list
We say the list [0, 1, 2, 3, 4, 5] rotated by 2 is [2, 3, 4, 5, 0, 1]. Write a function def rotate(xs: list, k: int) -> list that rotates a list by \(k\).
This is left as an open exercise. Slicing (see python-lists) is the hint about how it is meant to be solved.
Question: Caesar cipher
Write code for encrypting and decrypting messages using the Caesar cipher. In particular, write functions with the headers:
def encrypt_caeser(plaintext: str, shift: int) -> str:

def decrypt_caeser(ciphertext: str, shift: int) -> str:
This is left as an open exercise. A working caesar_cipher implementation (a single shift parameter instead of separate encrypt/decrypt functions) is in Lecture 5C — see week-five-exercises.
Dictionaries
Here is a deliberately vague question: write a function that returns the character frequency of a string, ignoring case. For example, the character frequency of "hello world" would encode that there is one “h”, three “ℓ”’s and so on.
Viable representations
Two lists (characters paired positionally with their counts):
[['h', 'e', 'l', 'o', ' ', 'w', 'r', 'd'],
 [ 1,   1,   3,   2,   1,   1,   1,   1 ]]
One-to-one encoding (a count for every letter of the alphabet, in order):
# a b c d e f g h i j k l m n o p q r s t u v w x y z
 [0,0,0,1,1,0,0,1,0,0,0,3,0,0,2,0,0,1,0,0,0,0,1,0,0,0]
Hash functions
In both cases we provided a way to map a key (character) to a value (number):
\[\texttt{str} \to \texttt{int}, \quad \texttt{h} \mapsto 1, \; \texttt{e} \mapsto 1, \; \texttt{l} \mapsto 3, \; \ldots\]
This mapping is called a hash function.
The hash function for the two-list encoding looks up the key’s position in the first list, then indexes the second list at that position:
>>> def hash_1(key: str) -> int:
...     """Two list encoding."""
...     xs = ['h', 'e', 'l', 'o', ' ', 'w', 'r', 'd']
...     ys = [1, 1, 3, 2, 1, 1, 1, 1]
...     k = xs.index(key)   # position of key in xs
...     return ys[k]
>>> hash_1('o')
2
>>> hash_1('r')
1
The hash function for the one-to-one encoding computes the key’s position in the alphabet directly, via ord:
>>> def hash_2(key: str) -> int:
...     """One-to-one encoding."""
...     xs = [0,0,0,1,1,0,0,1,0,0,0,3,0,0,2,0,0,1,0,0,0,0,1,0,0,0]
...     pos_in_alpha = ord(key) - ord('a')   # position of key in alphabet
...     return xs[pos_in_alpha]
>>> hash_2('o')
2
>>> hash_2('r')
1
Both return the same count for the letters of the example even though they store completely different things. That is the point of the exercise: the encoding is a free choice, and the hash function is whatever computation turns a key into an index into it.
They are not interchangeable in general. hash_1 only knows the eight characters in its own xs, and hash_2’s ord(key) - ord('a') only lands inside its list for 'a'–'z' — so the space character that hash_1 counts is out of range for hash_2.
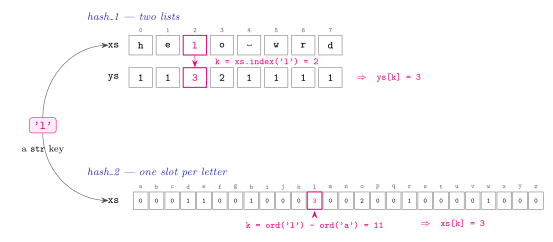
Figure 7: The same key routed through both encodings. hash_1 finds the key’s position in a list of characters and reads the count off a parallel list at that position; hash_2 computes the position arithmetically from the character code and reads a single alphabet-sized list. Different storage, different index arithmetic, same answer — which is why Python’s dict can hide the choice behind a magic hash function. Magenta marks the key and the value it leads to.
Generally speaking we can index a list by any type of key given some hash function which takes keys to values. Python has a magic hash function that will index anything appropriately. The result is implemented as the dict data-type.
Dictionaries have no ordering because the keys can be of mixed type.
The “hello world” example encoded using a dictionary is
>>> char_to_freq = {
...     'd': 1,
...     'o': 1,
...     ' ': 1,
...     'r': 1,
...     'w': 1,
...     'e': 1,
...     'l': 3,
...     'h': 0
... }Two entries disagree with the two-list encoding above (and with "hello world" itself): that encoding has 'o' at 2 and 'h' at 1, which is what hash_1('o') returns above. As written, char_to_freq is wrong for the string it claims to encode.
See python-dictionaries for the full reference on dictionaries: creation, indexing, keys/values/items, clear/copy (and its shallow-copy gotcha), get, and the requirement that keys be immutable.
Summary
Lists are mutable ordered collections; tuples are immutable ordered collections. Dictionaries are for storing key-value relationships — a key must be an immutable type and gets mapped to a value using a hash function that is magically fast.
Hash tables are a candidate for the most important/useful data-structure in computer science.
Next lecture
For-loops and comprehension — 2025-08-25-for-loops and 2025-08-25-comprehensions.
While-Loops
See csse1001 for course logistics — this note covers Lecture 4A’s technical content.
Outline
- Why we need to repeat code, possibly indefinitely
- The while-loop
- Simulating a do-while, and reading user input
Learning objectives
- Loops are a control structure for repeating code.
- A while-loop repeats code while a condition holds — and the condition is tested before each repetition.
breakleaves a loop immediately;while True+breakis how Python writes a do-while.input()reads from the keyboard;random.randintgenerates random integers.
Motivation
There are (at least) two scenarios where repeating possibly indefinitely is necessary:
- prompting the user for valid input, and
- playing a random game (i.e. guessing dice rolls).
The common feature is that neither has a repetition count you could work out in advance, which is what a while-loop buys you over the counted for-loop of 2025-08-25-for-loops.
The two definitions
Definition (Loop). A loop is a control structure that repeats code that belongs to it.
Definition (While-Loop). A while-loop is a control structure that repeats code while some condition is satisfied.
In Python that is written
while <condition>:
    <code>
and it behaves like this:
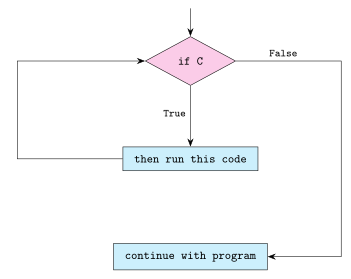
Figure 8: The while-loop as a flowchart. The condition C is tested first: while it is True control drops into the body and then loops straight back to the test, and only when it is False does control fall through to the rest of the program. The pink diamond is the decision and the blue boxes are code.
Reading Figure 8, the only thing separating a while-loop from an if is the back-edge from the body to the diamond. See python-while-loops for the full reference on loops, while-loops, break, augmented assignment operators (+=, *=, /=, %=), simulating a do-while, input(), and random.randint.
Accumulator pattern
The loop variable is updated inside the body so that the condition eventually fails:
>>> x = 0
>>> while x < 10:
...     x = x + 1          # accumulator
>>> x
10
Using an augmented assignment operator (see python-while-loops) makes the accumulation more concise — x += 1 is exactly x = x + 1:
>>> x = 0
>>> while x < 10:
...     x += 1             # accumulator
>>> x
10
The loop stops at exactly 10, not 9: the test x < 10 is re-checked after the body has already pushed x to 10.
When the condition never changes
If the condition is never falsified the loop never stops:
>>> x = 0
>>> while True:
...     print(x)
...     x += 1
0
1
2
3 ...
There is usually a key-stroke, typically ctrl+c, that terminates a loop — it is a good idea to learn what it is in your IDE.
The mirror case is a condition that is false to begin with. The body then never runs at all, because the test comes first:
>>> x = 0
>>> while False:
...     print(x)
...     x += 1
Nothing prints.
Exercise: guess the number
x = input() waits for input from the keyboard and then assigns it to x with type(x) is str — so a numeric guess has to be converted with int(...).
Write a function foo(target: int) -> int that prompts the user to input a number until the user guesses some (secret) target. For each guess the function should print Too high, Too low, or That's it! depending on the guess. Return the number of guesses required.
>>> def foo(target: int) -> int:
...     number_of_guesses = 0
...     while True:
...         guess = int(input("Guess: "))
...         number_of_guesses += 1
...         if guess > target:
...             print("Too high")
...         elif guess < target:
...             print("Too low")
...         else:
...             print("That's it!")
...             return number_of_guesses
>>> foo(10)
Guess:
The loop is deliberately while True: there is no condition available at the top of the loop that says “the user has not guessed yet”, because the guess does not exist until the body has run. The exit is the return in the else branch, which leaves the function (and so the loop) outright.
Exercise: guess the dice roll
Write a function called bar() -> None that prompts the user to predict the result of a six-sided dice roll. Repeat the prompt until the user predicts correctly.
Random number generation is handled by an external library. It is not built-in and therefore must be imported (see python-while-loops for both import forms):
>>> from random import randint
>>> def bar() -> None:
...     """
...     Prompt user to predict the result of a six sided
...     dice roll until the guess is correct.
...     """
...     while True:
...         guess = int(input("Guess in [1..6]: "))
...         roll  = randint(1, 6)
...         if roll == guess:
...             break
...     return
>>> bar()
Guess in [1..6]:
Here the exit is a break rather than a return, because the function has nothing to hand back. The die is re-rolled every iteration, so the user is predicting a fresh roll each time rather than searching for one fixed hidden number.
Further exercises
Open exercises:
- Write a function that prints the result of a six-sided dice roll until a six is rolled, and returns the number of rolls required.
- Write a function that accumulates the result of dice rolls until some threshold is met/passed, and returns the number of rolls required.
- Develop functions for adding and multiplying positive integers together, restricting ourselves to exactly two arithmetic operations —
succ(adding one) andpred(subtracting one). The two building blocks are:
def succ(x: int) -> int:
    return x+1

def pred(x: int) -> int:
    return x-1
Both the add and the multiply function are accumulators driven by a while-loop.
Summary
The while-loop is a control structure for repeating code a possibly infinite number of times.
Next lecture
2025-08-18-non-primitive-data — lists and dictionaries.
Week 5
Comprehensions
Lecture 5B. See csse1001 for course logistics and python-comprehensions for the full reference on comprehension syntax.
Outline
- List comprehensions
- Dictionary comprehensions
- Nested comprehensions
- Two worked exercises:
disassembleandmore_capitals allandany- Filtering, and the general pattern
List comprehension
Mathematics builds sets and sums this way:
\[ \{k^2 : k \in \{0, 1, 2, 3\}\} = \{0, 1, 4, 9\} \qquad \sum_{k \in \{0,1,2,3\}} k^2 = 0^2+1^2+2^2+3^2 \]
Python mirrors this directly:
>>> [k**2 for k in range(4)]
[0, 1, 4, 9]
>>> sum(k**2 for k in range(4))
14
Dictionary comprehension
>>> {x: f"value is {x}" for x in range(3)}
{0: 'value is 0', 1: 'value is 1', 2: 'value is 2'}

>>> {x: 0 for x in "ABC"}   # useful for assigning default values
{'A': 0, 'B': 0, 'C': 0}

>>> cs = "hello world"
>>> {x: cs.count(x) for x in cs}
{'h': 1, 'e': 1, 'l': 3, 'o': 2, ' ': 1, 'w': 1, 'r': 1, 'd': 1}
Nested comprehensions
Multiple for clauses can appear in one comprehension — order matters:
>>> [(a, x) for a in "ABC" for x in range(2)]
[('A', 0), ('A', 1), ('B', 0), ('B', 1), ('C', 0), ('C', 1)]

>>> [(a, x) for x in range(2) for a in "ABC"]
[('A', 0), ('B', 0), ('C', 0), ('A', 1), ('B', 1), ('C', 1)]
Implementing [(a, x) for a in "ABC" for x in range(2)] with a for-loop:
>>> xs = []
>>> for a in "ABC":
...     for x in range(2):
...         xs.append((a, x))
Reading the two side by side is what makes the order rule obvious — and it explains why swapping the two for clauses swaps which loop is on the outside, and therefore changes the order of the result:
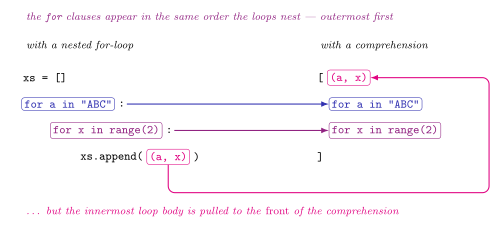
Figure 9: The same computation written both ways, piece by piece. Colour keys the boxed code: magenta the output expression, blue the outer generator clause, purple the inner one. The two italic sentences are annotations, not entries in that colour key. The for clauses keep their order, but the output expression jumps from the innermost loop body to the front.
Exercise: disassemble a string
def disassemble(cs: str) -> list[str]:
    """ Returns a list of characters comprising cs, maintaining order.
    >>> disassemble("")
    []
    >>> disassemble("abcdef")
    ['a', 'b', 'c', 'd', 'e', 'f']
    """
With a for-loop:
>>> def disassemble(xs: str) -> list[str]:
...     ans = []
...     for x in xs:
...         ans.append(x)
...     return ans
With a list comprehension the whole body collapses to one line:
>>> def disassemble(xs: str) -> list[str]:
...     return [x for x in xs]
>>> disassemble("abcdef")
['a', 'b', 'c', 'd', 'e', 'f']
The accumulator (ans = []), the loop, the append and the return of the four-line version all fold into the single comprehension.
return [c for c in cs]Exercise: more capitals than lower-case
Check if a string has (strictly) more capitals than lower-case letters, ignoring all other characters:
def more_capitals(cs: str) -> bool:
    """
    >>> more_capitals("aAbBcCdD")
    False
    >>> more_capitals("CSSE 1001")
    True
    >>> more_capitals("")
    False
    """
A useful “hack”: the integer value of True and False is 1 and 0 respectively, so sum(...) over a sequence of booleans counts how many are True:
>>> True + True + False
2return (sum('A' <= c <= 'Z' for c in cs)
> sum('a' <= c <= 'z' for c in cs))Exercise: all
Check if every element of a list is truthy:
def all(xs: list) -> bool:
    """
    >>> all([1, 2, 3])
    True
    >>> all(["a", "", "c"])
    False
    >>> all([])
    True
"""return len(xs) == sum(bool(x) for x in xs)Exercise: any
Check if any element of a list is truthy:
def any(xs: list) -> bool:
    """
    >>> any([0, 0, 0])
    False
    >>> any(["a", "", "c"])
    True
    >>> any([])
    False
"""return sum(bool(x) for x in xs) > 0Both are already included in base Python — no library call needed — and they are useful:
>>> xs = "HELLO WORLD"

>>> all(['A' <= x <= 'Z' for x in xs])   # is every letter a capital?
False                                    # (space is not a capital)

>>> any(['A' <= x <= 'Z' for x in xs])   # is any letter a capital?
True
Defining your own all/any as the two exercises above do shadows the built-ins for the rest of that scope — fine as an exercise in reimplementing them, a bug anywhere else.
Filtering
Comprehension elements may be filtered with a trailing if. E.g. the numbers less than 100 divisible by both 3 and 7:
>>> [x for x in range(101) if not (x % 3) and not (x % 7)]
[0, 21, 42, 63, 84]
range(101) includes 100. It makes no difference here — 100 is divisible by neither 3 nor 7 — but range(100) is what “less than 100” asks for.
The general pattern
[x for x in xs if P(x)]
[x for x in xs for y in ys if P(x, y)]
[x for x in xs for y in ys for z in zs if P(x, y, z)]
...
where P is some predicate.
Summary
Comprehensions are a rapid way of forming lists and dictionaries that would otherwise require an accumulator for-loop.
Next: week-five-exercises (Lecture 5C). See python-comprehensions for the syntax reference and python-for-loops for the accumulator forms comprehensions shortcut.
For-Loops
Lecture 5A. See csse1001 for course logistics and python-for-loops for the full reference on for-loop syntax, ranges, and enumerate.
Outline
- For-loops: definition and syntax
- String iteration, character by character; nesting for-loops
- The accumulator pattern
- For-loops vs. while-loops — which can replace which
- List looping, index by index; out-of-place vs. in-place
range(iterating through numbers) andenumerate(iterating with index)- Dictionary looping, key by key
Definitions
Loop — a control structure that repeats code that belongs to it.
For-loop — a control structure that, given a group, repeats code for every member of that group, in order.
for <name> in <iterator>:
    <code>
String iteration (character by character)
A for-loop iterates through a string’s characters, in order:
>>> for x in "abcd":
...     print(x)
a
b
c
d
>>> x
'd'
The looping name (x) retains its final value after the loop exits.
Nesting for-loops
>>> (digits, alphas) = ("012", "xy")
>>> for d in digits:
...     for a in alphas:
...         print(d + a)
0x
0y
1x
1y
2x
2y
Python disallows empty for-loop bodies — use pass (the empty instruction, which has no effect) as a placeholder:
>>> for d in digits:
...     for a in alphas:
...         pass
...     print(d + a)
0y
1y
2y
Again, the names used to iterate through an iterator retain their values after the for-loop exits — by the time the outer loop’s print runs, the inner loop has already finished, leaving a at its last value ('y') each time.
Pulling print out of both loops leaves it running exactly once, on whatever d and a were left holding:
>>> (digits, alphas) = ("012", "xy")
>>> for d in digits:
...     for a in alphas:
...         pass
... print(d + a)
2y
So the same two loops give six lines, three lines or one line depending only on where print is indented.
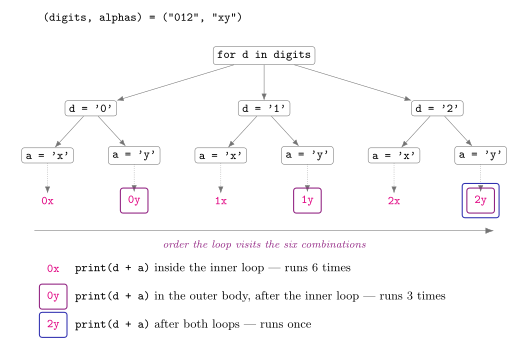
Figure 10: Where the print statement is indented decides how many times it runs. The tree is the order the two nested loops visit their six (d, a) combinations, left to right. The three variants (6 lines, then 3, then 1) are keyed by the box around each printed value — none, purple, blue — and by nothing else: the purple traversal-order label beneath the tree is an annotation, not a fourth entry in that key.
The accumulator pattern
An accumulator is a variable a loop uses to build up an aggregate value:
>>> acc = ""
>>> for x in "abcd":
...     acc = acc + x
...     print(acc)
a
ab
abc
abcd
Building it in reverse order just by swapping the order of concatenation:
>>> acc = ""
>>> for x in "abcd":
...     acc = x + acc
...     print(acc)
a
ba
cba
dcba
The loop visits 'a', 'b', 'c', 'd' in the same order both times — only the side the new character is joined on changes, and that alone reverses the result:
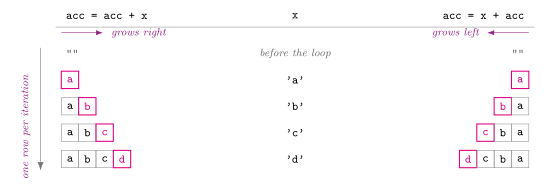
Figure 11: Why acc = acc + x builds abcd and acc = x + acc builds dcba. The top row, marked before the loop, is the empty accumulator each snippet sets up on its first line — not a pass, and never printed; each of the four rows below it is one pass, and the magenta cell is the character just added. Those four rows per column are exactly the printed output of the two loops above.
For-loops vs. while-loops
Can every for-loop be rewritten with only while-loops? Yes:
>>> for x in xs:
...     ...   # do something with x
is code-equivalent to:
>>> k = 0
>>> while k < len(xs):
...     ...   # do something with xs[k]
...     k += 1
Can every while-loop be rewritten with only for-loops? No — consider how many times you’d need to repeat asking a user for correct input (not known in advance). That is exactly the validation loop from 2025-08-18-while-loops: the trip count is not known until the user cooperates, so there is no group to iterate over.
Technical caveat: a for-loop can be tricked into looping forever in Python, by giving it an iterator that never exhausts. And if you dig deep enough, Python itself used a while-loop to build that iterator in the first place.
Exercise: removing characters
def remove(c: str, cs: str) -> str:
    """ Return the string with all instances of c removed from cs.
    Precondition: len(c) == 1
    >>> remove('b', "bluey")
    'luey'
    >>> remove('b', "Bluey")
    'Bluey'
    >>> remove('b', "chilli")
    'chilli'
    >>> remove('b', "")
    ''
    """
The shape is the accumulator pattern: accumulate into acc, skipping the character to be removed. The loop variable needs its own name (x), compared against the parameter c. Reusing c as the loop variable would shadow the parameter it is supposed to be compared against.
Fill in the blank to complete remove:
acc = ""
for x in cs:
    if x != c:
        acc += x
return acc
List looping (index by index)
A for-loop also iterates directly through a list’s elements. This example uses no index at all — indices arrive later, with range and enumerate.
>>> xs = ['a', 2, 'c', 4, 'e']
>>> for x in xs:
...     print(x)
a
2
c
4
e
Exercise: unique elements
def make_unique(xs: list[int]) -> list[int]:
    """ Returns the UNIQUE elements of xs.
    >>> make_unique([1, 2, 3, 4])
    [1, 2, 3, 4]
    >>> make_unique([1, 2, 2, 2, 3, 1, 4, -3])
    [1, 2, 3, 4, -3]
"""acc = []
for x in xs:
if x not in acc:
acc.append(x)
return accThis is an out-of-place computation — the original list xs is not modified. An in-place change would instead modify xs directly; those are covered later, in the object-oriented part of the course.
Ranges (iterating through numbers)
range builds an iterator of numbers, with the general form range([start], stop[, step]) (square brackets denote optional arguments) — similar to list slicing:
>>> range(10)
range(0, 10)
>>> type(range(10))
<class 'range'>
>>> list(range(10))
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
>>> list(range(2, 7))
[2, 3, 4, 5, 6]
>>> list(range(2, 7, 3))
[2, 5]
>>> list(range(2, 7, -1))
[]
>>> list(range(7, 2, -1))
[7, 6, 5, 4, 3]
The rule for reading the last four follows the slicing analogy: the walk starts at start, hops by step, and yields every value it lands on that is still short of stop in the direction it is travelling. So stop is never produced, and start is produced only when the walk produces anything at all: range(2, 7, -1) is empty because a negative step walks down from 2, away from 7, and 2 is already past 7 going that way, so not even start comes out. See python-for-loops for a diagram of those four.
range is commonly used to walk through a list by index:
>>> xs = [11, 22, 33, 44]
>>> for k in range(len(xs)):
...     ...   # code involving xs[k]
Enumerate (iterating with index)
enumerate simplifies the index-and-value pattern above. Roughly:
enumerate([x0, ..., xn]) == [(0, x0), ..., (n, xn)](this isn’t the full story — enumerate actually returns an iterable, not a list — but the pairs it produces work the same way):
>>> xs = [1, 2, 3, 4]
>>> for k, xk in enumerate(xs):
...     ...   # code involving k and xk == xs[k]
Each (k, xk) pair is a tuple, an immutable list (see python-lists):
>>> for k, x in enumerate(["Scientia", "ac", "Labore"]):
...     print(k, x)
0 Scientia
1 ac
2 Labore
(“Scientia ac Labore” is UQ’s motto — “by means of knowledge and hard work”.)
Dictionary looping (key by key)
A for-loop iterates through a dictionary’s keys (see python-dictionaries) — not its values, and not its key/value pairs. To reach a value you index the dictionary with the key the loop hands you:
>>> for key in table:            # for loop over keys
...     value = table[key]
>>> h = {"red": 1, "blue": 2, "green": 3}
>>> for key in h:
... print(key)
red
blue
green
>>> for key in h:
... print(h[key])
1
2
3Exercise: character index
Write a function that maps each character of a string to the list of indices at which it occurs:
def char_index(xs: str) -> dict[str, list[int]]:
    """ Return a dictionary mapping the characters (length one
    substrings) of <xs> to the list of indices at which they occur.
    >>> char_index("")
    {}
    >>> char_index("aaAbbB")
    {'a': [0, 1], 'A': [2], 'b': [3, 4], 'B': [5]}
"""acc = {}
for k, x in enumerate(xs):
if x in acc:
acc[x].append(k)
else:
acc[x] = [k]
return accSummary
For-loops let us iterate through anything iterable. Strictly speaking they’re not necessary (a while-loop, or copy-pasting code k times, can always do the same job) but they’re used often enough to merit their own dedicated syntax.
Next: 2025-08-25-comprehensions (Lecture 5B) — a rapid way of building lists and dictionaries that would otherwise need an accumulator for-loop.
Week 5 Exercises — For-Loop Practice
Practice exercises for week 5 (Lecture 5C, “For Loop Practice”), following on from 2025-08-25-for-loops and 2025-08-25-comprehensions. See python-for-loops and python-comprehensions for the reference material needed to solve these.
Q1–Q6 are the week 5 set. Q7–Q11 are the week 4 exercises, from 2025-08-18-while-loops (Lecture 4A) and 2025-08-18-non-primitive-data (Lecture 4B). Q7 is also worked three ways in 2025-08-18-non-primitive-data; it is repeated here because it is the same shape as the rest. Q8–Q11 are worked here, as is the week 4 Caesar cipher (Q3). Every one is a loop over a list, a dictionary or a counter, so they belong in the same practice set. See python-lists, python-dictionaries and python-while-loops for the reference material those need.
On the HTML site, fill in each blank with your answer, then click Run Code to check it. In the PDF, the Working callout is shown as a static answer key instead (interactive checking needs a browser).
The figures use the palette recorded in csse1001-diagram-notation.
Q1 — Capitalize a string
def capitalize(cs: str) -> str:
    """ Capitalize every alphabet letter of a string.
    >>> capitalize("boom goes the dynamite!")
    'BOOM GOES THE DYNAMITE!'
    >>> capitalize("123")
    '123'
"""acc += chr(ord('A') + ord(c) - ord('a'))Shifting a lower-case letter up to its capital by the fixed gap between 'A' and 'a' in the character encoding.
Q2 — Matrix transpose
def transpose(xss: list[list[int]]) -> list[list[int]]:
    """ Return the transpose of xss (rows and columns swapped).
    Precondition: xss is square, i.e. len(xss) == len(xss[0]) == ...
    >>> transpose([[1, 2, 3], [4, 5, 6], [7, 8, 9]])
    [[1, 4, 7], [2, 5, 8], [3, 6, 9]]
    >>> transpose([[1]])
    [[1]]
    """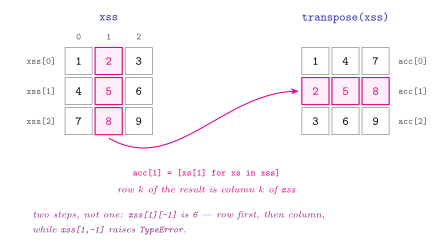
Figure 12: Q2 on a \(3\times3\) matrix. A matrix can be represented by a list-of-lists in Python, and indexing it takes two steps — xss[1][-1] is 6, while xss[1,-1] raises TypeError: list indices must be integers or slices, not tuple. Row \(k\) of the result is column \(k\) of the original, which is the whole of the answer. Magenta marks column 1 of xss and the row of the result it becomes.
row = [xs[k] for xs in xss]Row k of the transpose is column k of the original — the k-th element of every row xs in xss, which is what Figure 12 draws.
Written out with two-step indexing instead of a comprehension, the same row is [xss[i][k] for i in range(len(xss))]. The comprehension form is shorter because xs is xss[i].
Q3 — Caesar cipher
A Caesar cipher shifts each letter a fixed number of places down the alphabet (wrapping around) to encrypt; shifting by the negative amount decrypts it again.
def caesar_cipher(cs: str, shift: int) -> str:
    """ Return a string where each character of <cs> has been shifted
    by <shift> according to the Caesar cipher.
    >>> caesar_cipher("HELLO", 3)
    'KHOOR'
    >>> caesar_cipher("KHOOR", -3)
    'HELLO'
    >>> caesar_cipher("abc xyz", 2)
    'cde zab'
    >>> caesar_cipher("cde zab", -2)
    'abc xyz'
    """
The Caesar cipher exercise in 2025-08-18-non-primitive-data asks for separate
encrypt_caeseranddecrypt_caeserfunctions. Same idea here, with a single shift parameter instead of two functions:decrypt_caeser(ct, s)iscaesar_cipher(ct, -s).
acc += chr((ord(c) - ord('a') + shift) % 26 + ord('a'))% 26 wraps the shift around the alphabet in both directions (including for negative shifts, since Python’s % always returns a non-negative result for a positive divisor).
Q4 — Combine two dictionaries
def combine(d1: dict[int, list[int]], d2: dict[int, list[int]]) -> dict[int, int]:
    """ Return the dictionary where each key is a key that is in both
    d1 and d2. The value for each key is the sum of all the integers
    associated with that key in d1 and d2.
    >>> combine({1: [2], 4: [5, 6]}, {4: [8]})
    {4: 19}
"""acc[key] = sum(d1[key]) + sum(d2[key])The if key in d2 guard is what keeps d2[key] from raising a KeyError. Bare indexing of a missing key raises an error such as KeyError: 'green'. The method alternative, h.get(key), is safer because no error is thrown: it returns None instead.
Q5 — Reverse lookup
def reverse_lookup(d: dict, item) -> list:
    """ Returns all keys of <d> such that d[key] == item.
    Precondition: the items of <d> are immutable.
    >>> reverse_lookup({1: 'bluey', 19: 'chilli', -31: 'bluey'}, 'bluey')
    [1, -31]
    >>> reverse_lookup({1: 'bluey', 19: 'chilli', -31: 'bluey'}, 'muffin')
    []
    """
A dictionary gives every key one value, but nothing stops two keys sharing a value — which is the only reason this function returns a list. Figure 13 under Q6 draws that.
if d[k] == item:In CSSE1001 a dictionary is treated as having no ordering, because the keys can be of mixed type. The expected answer [1, -31] nevertheless comes out in the order the keys were written, and [-31, 1] would fail the check above.
A dict iterates in insertion order from Python 3.7 onward. The habit that works either way is not to depend on the order — compare as a set, or sorted(...), when the order is not part of the specification.
Q6 — Invert a dictionary
def invert(d: dict) -> dict:
    """ Return the inverted version of d (values become keys, mapping
    to a list of the original keys that shared that value).
    >>> invert({1: 10, 2: 10})
    {10: [1, 2]}
    """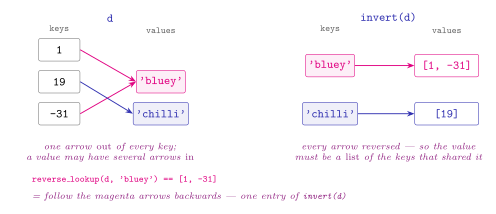
Figure 13: Q5 and Q6 are one picture read in two directions, drawn on Q5’s dictionary. A dictionary is a store of tuple(key, value) pairings found by a hash function. Each arrow is one pairing, which can also be written as a maplet such as \(\texttt{h} \mapsto 1\). A dict gives every key exactly one value, so several keys can land on the same value — 1 and -31 both map to 'bluey'. reverse_lookup follows those arrows backwards for one chosen value; invert reverses all of them at once, which is exactly why the inverted value has to be a list: reversing a many-to-one map gives a one-to-many map. The key order shown is the literal order Q5 writes the dictionary in; nothing should be read into it.
acc[val] = [key]A one-element list, not the bare key — the if branch above then has something to .append to on the second key that shares this value. Getting this wrong is the usual way Q6 fails: acc[val] = key works for {1: 10} and breaks the moment two keys collide, which is the only interesting case.
This is the same shape as the way of avoiding a KeyError without methods:
if key in table:
    table[key] += 1
else:
    table[key] = 0
Q6 is the same test with a list in place of a counter. That else branch initialises a new key to 0 rather than 1, which would leave every count one low.
Carry-over: the week-4 exercises
Everything from here on comes from week 4: while-loops (2025-08-18-while-loops, Lecture 4A) and lists and dictionaries (2025-08-18-non-primitive-data, Lecture 4B). Q7 is also worked in 2025-08-18-non-primitive-data. Q8–Q11 are stated in those two notes and worked here.
Q7 — Count occurrences
def count(xs: list[int], ys: list[int]) -> int:
    """ Return the number of times members of ys are in xs.
    >>> count([1, 2], [1, 2, 3, 4])
    2
    >>> count([1, 2], [1, 2, 2, 2, 3, 1, 4])
    5
    """
Read the specification carefully: the walk is over ys, and xs is only ever asked does it contain this. That is why the second example answers 5 and not 2 — five of the seven members of ys are in xs, counting repeats.
if y in xs:in is list membership. The whole function can be written three ways.
The while-loop version, walking ys by index:
def count(xs: list[int], ys: list[int]) -> int:
    ans, k = 0, 0
    while k < len(ys):
        y = ys[k]
        k += 1
        if y in xs:
            ans += 1
    return ans
The for-loop version. It is certainly better to use a for-loop in this situation.
def count(xs: list[int], ys: list[int]) -> int:
    ans = 0
    for y in ys:
        if y in xs:
            ans += 1
    return ans
The one-line version.
def count(xs: list[int], ys: list[int]) -> int:
    return sum(y in xs for y in ys)
That last one leans on True counting as 1 under sum, and on the generator-expression syntax of 2025-08-25-comprehensions.
Q8 — Rotate a list
def rotate(xs: list, k: int) -> list:
    """ Return xs rotated by k.
    >>> rotate([0, 1, 2, 3, 4, 5], 2)
    [2, 3, 4, 5, 0, 1]
    >>> rotate([0, 1, 2, 3, 4, 5], 0)
    [0, 1, 2, 3, 4, 5]
    """
The hint is slicing, as in xs[3:6], xs[::2] and xs[7:2:-2].
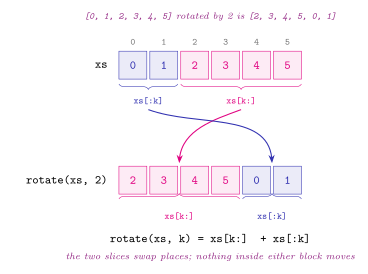
Figure 14: The rotate exercise solved by slicing. Along the top are the list, the rotation amount and the answer; rotation is defined by that one example and nothing else. Below, the answer: xs[:k] and xs[k:] are the two blocks the list splits into, and rotating is writing them in the other order. Nothing moves within either block, which is why one concatenation of two slices, xs[k:] + xs[:k], is the whole function.
return xs[k:] + xs[:k]Two slices concatenated, as in Figure 14. The slice bounds need no guarding for k = 0 (xs[0:] is all of it, xs[:0] is empty) and none for k = len(xs) (the other way round), so both ends of the range come out right for free.
The exercise defines rotation by a single example, which leaves two cases unsettled:
klarger than the list.rotate([0, 1, 2], 5)returns[0, 1, 2]unchanged, becausexs[5:]is empty. If a rotation by 5 of a 3-element list should mean a rotation by 2, open withk = k % len(xs). The single example never leaves the range, so it does not say which is wanted.- Negative
k.rotate([0, 1, 2, 3, 4, 5], -1)gives[5, 0, 1, 2, 3, 4]— a rotation the other way. That falls out of Python’s negative-index rule rather than out of any decision, and the example does not say whether it is wanted either.
An index-based alternative, if you want it as a for-loop rather than a slice:
def rotate(xs: list, k: int) -> list:
    return [xs[(i + k) % len(xs)] for i in range(len(xs))]
This one does handle k beyond the length, because the % is applied per element.
Q9 — Roll until a six
def roll_until_six() -> int:
    """ Print the result of each roll of a six-sided die until a six
    is rolled. Return the number of rolls required.
    """
Random number generation is not built in and must be imported:
>>> from random import randint
>>> randint(1, 6)          # chosen uniformly over the interval
2if roll == 6:The loop is while True for the same reason as the guess-the-number game in 2025-08-18-while-loops: the value the condition needs to test does not exist until the body has run, so there is nothing to put at the top of the loop. The exit is a return, which leaves the function and so the loop outright (break is for the case where there is nothing to hand back).
Because randint is re-rolled every pass, this loop has no bound on how long it runs — only a probability of stopping. That is repeating possibly indefinitely, which is what a while-loop is for, and it is why this cannot be a for-loop.
The rigged die in the cell above is a testing device: rebinding the name randint after the function is defined makes the function pick up the replacement, because Python resolves a global name at call time and not at definition time. Delete those two assignments and the function rolls for real.
Q10 — Accumulate rolls until a threshold
def rolls_to_reach(threshold: int) -> int:
    """ Roll a six-sided die, accumulating the results, until the running
    total meets or passes <threshold>. Return the number of rolls required.
    """
Q9’s stopping condition looks at the latest roll. This one looks at an accumulator over all of them — the x = x + 1 pattern, which the Python assignment operators let you write as x += 1.
while total < threshold:Unlike Q9 this loop has a real condition to put at the top, so it needs no while True and no break: total is a genuine accumulator, and the test “have we got there yet” can be asked before the first roll. At the boundary, with threshold = 0, the body never runs at all and the answer is 0 rolls, the same as a while False loop.
The specification says met/passed, so the test must be strict (total < threshold), not total <= threshold: the loop has to stop the moment total reaches the threshold exactly. With the rigged die above the sixth roll takes the total to exactly 20, so a <= here would answer 7 rather than 6 — the boundary is not academic.
Q11 — Addition and multiplication from succ and pred
Two building blocks are given, and the arithmetic has to be built from nothing else:
def succ(x: int) -> int:
    return x+1

def pred(x: int) -> int:
    return x-1
Develop functions for adding and multiplying positive integers together restricting ourselves to exactly two arithmetic operations:
succ(adding one) andpred(subtract one).
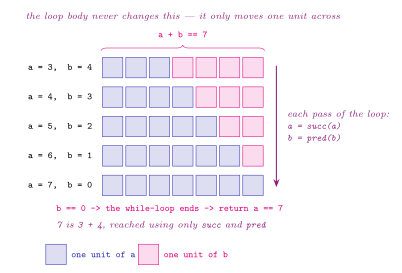
Figure 15: Why the add loop of Q11 is correct and why it stops, traced on add(3, 4). Each pass moves one unit from b across to a, so the total width of the row — the quantity a + b — is the same on every line: it starts at \(3+4\) and ends at \(7+0\), which is why a holds the answer at the moment b reaches 0. The same reading gives termination, since b strictly decreases and cannot go below 0.
total = add(total, a)add is succ applied b times, and multiply is add applied b times: each function is one loop that walks b down to zero with pred while doing the previous operation once per step. That layering is the point of the exercise — multiplication is repeated addition in the same way addition is repeated succession.
def add(a: int, b: int) -> int:
    while b > 0:
        a = succ(a)
        b = pred(b)
    return a

def multiply(a: int, b: int) -> int:
    total = 0
    while b > 0:
        total = add(total, a)
        b = pred(b)
    return total
Figure 15 is the argument that add is right: a + b is unchanged by the body, so when the loop ends with b == 0 the surviving a is the original a + b. The same trace argues termination — b strictly decreases every pass, so a non-negative b must reach 0.
Both functions read b down to zero and never test a, so the stated precondition matters on one side only: b must be non-negative or the loop never starts and you get a (for add) or 0 (for multiply) back. The exercise says positive integers, so nothing outside that is specified.
Both functions are accumulators driven by a while-loop, which is what makes this a while-loop exercise rather than an arithmetic one.
Week 6
File IO
Lecture 6B. See csse1001 for course logistics and python-file-io for the full reference on file modes and reading/writing patterns.
Outline
- Memory hierarchy and why files
- Opening, reading, and closing files
- The file-pointer, and why it can only be spent once
- Reading numbers out of a file, and casting
- Exercises: counting empty lines, finding the highest-rated band, reading a Sudoku board
- Writing and appending to files
Memory hierarchy
Five kinds of memory, with the capacity and the persistence of each:
| Type | Order | 2016 MacBook Pro | Persistence |
|---|---|---|---|
| CPU Cache L2 | KB | 256KB | Requires power |
| CPU Cache L3 | MB | 8MB | Requires power |
| Random Access Memory | GB | 16GB | Requires power |
| Disk | GB/TB | 256GB | Persistent |
| Cloud | PB | Functionally infinite | Persistent |
As you go down the list you get more space and, past Random Access Memory, you also get permanence.
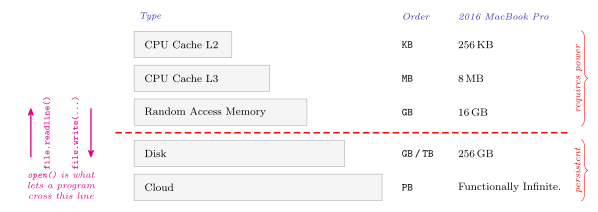
Figure 16: The memory hierarchy and its one boundary: everything above the dashed line is gone when the power goes, everything below it survives. That boundary is why files are needed. A Python program lives in RAM, and open is the one thing that lets it reach across. The stepped bar widths stand for the growing Order column, and the two arrows are a write and a read crossing the line.
Why files?
When Python (i.e. IDLE) launches it gets allocated space in RAM, which is possible to fill up. This is a problem if we want to solve memory-intensive problems — analyzing tweets, payroll, scientific computing. We may also want to save our data with persistence.
In either case, it is necessary to instruct Python to use the disk memory one level up.
Opening a file
To open a file assumed to be in the same directory as your running Python:
file = open("file.dat", "<mode>")| Mode | Description |
|---|---|
r |
read |
w |
write |
a |
append |
Append means write at the end of the file.
os.getcwd() and os.chdir() are what you reach for when the file is not in the same directory as the running program.
Reading a file
The example file, hello.txt, is three lines:
What a
wonderful
hello world.
where ¶ is the new-line character, which normally is not displayed. The third line carries none.
>>> file = open("hello.txt", "r")     # open for read.
>>> file.readline()
'What a\n'
>>> file.readline()
'wonderful\n'
>>> file.readline()
'hello world.'      # note lack of newline character
>>> file.readline()
''
>>> file.readline()
''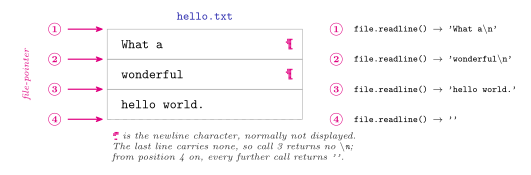
Figure 17: How readline moves the file-pointer. Each call to readline returns everything from the file-pointer up to and including the next newline, and then leaves the pointer past it. So the five calls in the transcript are not five readings of the same file, but reads taken from four successive pointer positions, the fifth call finding the pointer exactly where the fourth left it. Once the pointer reaches position 4 there is nothing left and every further call returns the empty string, which is why only four positions are drawn. This is why, to read a line twice, the file must be opened twice. The pilcrow stands for the newline character.
Past the end of the file readline returns '' every time. That is the empty string, not a newline, and it is what makes readline a usable loop-termination test.
A for-loop iterates line by line:
>>> file = open("hello.txt", "r")     # open for read.
>>> for line in file:
...     print(line)
What a

wonderful

hello world.

>>>
The three ¶ in that output are inserted by Python’s print: every print call ends with a newline of its own. For the first two lines that added newline lands on top of the \n the line already carries, so the terminal shows a blank line between outputs. The third line carries no \n, so its ¶ is the only newline printed and nothing blank follows it.
The file-pointer is exhausted after one pass
Run the same loop again on the same file:
>>> for line in file:
...     print(line)
>>>
Nothing prints. The file-pointer file has already reached the end of the file during the last loop. To reset the file pointer to the beginning, open the file again:
>>> file = open("hello.txt", "r")
>>> for line in file:
...     line
'What a\n'
'wonderful\n'
'hello world.'
This loop uses a bare line rather than print(line), which is why the newline characters are visible here and were invisible in the previous transcript.
Closing files
If you do not close your files they remain open and vulnerable to side-effects. That is, you may find some of your file is missing, or extra bits in your file, when you neglect to close after use.
>>> file = open("hello.txt", "r")
>>> for line in file:
...     line
'What a\n'
'wonderful\n'
'hello world.'
>>> file.close()
Alternative to close
Using the with construct has the advantage of closing your file for you — even if the program crashes while it is executing its code block.
with open("hello.txt", "r") as file:
    for line in file:
        print(line)
Exercise: counting empty lines
Write a function
def num_empty_lines(file: str) -> int:that counts the number of empty lines (those that only contain\n) in a file.
>>> def num_empty_lines(path: str) -> int:
...     """
...     Count 'empty' lines.
...     """
...     ans = 0
...     with open(path, 'r') as file:
...         for line in file:
...             if line == '\n':
...                 ans = ans + 1
...     return ans
>>> num_empty_lines("filename.txt")
The answer calls the parameter path rather than file. path is the better name: the argument is a file name, not an open file, and the next exercise turns on exactly that distinction.
The equivalent written with the compound assignment operator, and with the file variable named so it cannot be confused with the parameter:
def num_empty_lines(path: str) -> int:
    ans = 0
    with open(path, "r") as the_file:
        for line in the_file:
            if line == "\n":
                ans += 1
    return ans
The same function over a file-pointer
Write a function that counts empty lines, but takes an already-open file:
from typing import TextIO

def num_empty_lines(file_pointer: TextIO) -> int:
This is different from the last one, which took a name and not a pointer (to a file).
TextIO is a new doc-hint type, imported from typing.
from typing import TextIO

def num_empty_lines(file_pointer: TextIO) -> int:
    """
    Count 'empty' lines.
    """
    ans = 0
    for line in file_pointer:
        if line == '\n':
            ans = ans + 1
    return ans

>>> fp = open("filename.txt")
>>> num_empty_lines(fp)
Two consequences of the change, both visible in the code:
- There is no
openand nowithinside the function any more — the caller now owns opening (and closing) the file. - The function is handed a pointer that may already have been partly consumed. It counts from wherever the pointer happens to be, not from the start of the file.
Reading numbers from a file
Given numbers.dat, one number per line (the file ends without a newline after the 6):
1
2
3
4
5
6
When reading from a file we are always reading strings. Do not forget to cast your strings to more appropriate types when necessary:
>>> with open("numbers.dat", "r") as file:
...     ans = []
...     for line in file:
...         ans.append(int(line))
>>> ans
[1, 2, 3, 4, 5, 6]
int("1\n") works because int tolerates surrounding whitespace. That is the reason no strip() is needed here (see python-string-methods).
Exercise: the highest-rated band
Write a function that finds the highest-rated band in
bands.txt:
Band,Rating,Plays          <- this is called a header
Metallica,7,512
The Black Keys,8,193
Amy MacDonald,5,290
The Killers,9,402
U2,9,789
Portishead,6,116
Wiggles,2,1849
Coldplay,7,0
Taylor Swift,11,1234567
Drake,0,1
Each line of the body goes through the same short pipeline:
line → .split(',') → band, rating, _ → int(rating) → compare against the running best
def highest_rated(path: str) -> str:
    """ Return the highest-rated band in the file at <path>.
    Precondition: the file has a header row.
    """
    current_most_popular_band = ""
    current_highest_rating = -float('inf')   # guarantees the first row passes the > test

    with open(path, "r") as file:
        file.readline()   # skip the header
        for line in file:
            band, rating, _ = line.split(',')   # don't give names to values you don't intend on using
            rating = int(rating)
            if rating > current_highest_rating:
                current_highest_rating = rating
                current_most_popular_band = band

    return current_most_popular_band
The three comments in that block mark the three ideas in it:
-float('inf')as the starting rating guarantees the first row passes theif rating > current_highest_rating:test, so no special case is needed for “the first line”.- The bare
file.readline()before the loop skips the header — it is called for its side effect on the file-pointer, and its return value is thrown away. This only works because the pointer moves (see Figure 81). _is the conventional name for a value you unpack but do not want: don’t give names to values you don’t intend on using.
The parameter path is a str, not a TextIO: the body passes it straight to open(path, "r"), exactly as in the earlier exercise.
The third column, Plays, is unpacked into _ and thrown away. On this particular data the highest rating (11) and the highest play count (1234567) both belong to Taylor Swift, so a version that ranked by the wrong column would still return the right answer here.
Exercise: an arbitrary attribute
Extend the previous answer to take an arbitrary file with a header of attributes like
name,grade,ageand write a function
def most(path: str, attribute: str) -> str:that finds the maximum of that attribute.
The header is what makes it possible: attribute has to be looked up in the header row to find which column to compare.
Exercise: reading a Sudoku board
Write a function
def read_board(fname: str) -> list[list[int]]:that, given a file containing a partially filled Sudoku board, returns a list of lists of integers withNonein unfilled spots.
In board.txt, | separates the 3x3 blocks column-wise, a row of - separates them row-wise, and a space marks an empty cell:
685|13 | 47
7  |   | 1
 1 |764| 5
-----------
9  | 7 |5 4
8 1|  9| 72
4 3|  6|
-----------
   |427|39
 4 |9  | 68
1 7|   |4
A return type of list[list[int]] has no room for the Nones the statement asks for, so the stub is annotated list[list[int | None]]:
def read_board(path: str) -> list[list[int | None]]:
    """ Return a board representation for the Sudoku board in the
    file at <path>. None denotes an empty position.
    """
Character-by-character:
def read_board_v1(path: str) -> list[list[int | None]]:
    with open(path, "r") as the_file:
        board = []
        for line in the_file:
            row = []
            if "-" in line:
                continue   # skip horizontal dividers
            for x in line:
                if x.isdigit():
                    row.append(int(x))
                if x == " ":
                    row.append(None)
            board.append(row)
    return board
The same thing with a list comprehension. Where v1 simply declines to append on | and on the trailing newline, a comprehension has to filter both out explicitly, and each omission costs a different amount: drop the if x != '|' and every row comes back with eleven entries instead of nine, drop the rstrip("\n") and every row but the file’s last comes back with ten.
def read_board_v2(path: str) -> list[list[int | None]]:
    with open(path, "r") as the_file:
        board = []
        for line in the_file:
            if "-" in line:
                continue   # skip horizontal divider
            row = [int(x) if x.isdigit() else None
                   for x in line.rstrip("\n") if x != '|']
            board.append(row)
    return board
See python-comprehensions for the comprehension form.
Exercise: has the Sudoku been won?
def has_won(board: list[list[int]]) -> bool:
    """ Return True when the Sudoku board is solved (contains the
    digits 1 through 9 in each row, column, and 3x3 grid).
    """
Writing to files
>>> with open("numbers.dat", "w") as file:
...     file.write("Hello World.\n")             # Write single string.
...     file.writelines(["Hello\n", "World\n"])  # Write a list of strings.
Both calls write exactly the characters given. The newlines in the example are part of the strings themselves, not something the call adds.
Careful! Opening a file for write will create the numbers.dat file, or overwrite the old one if it exists.
Appending to files
Appending will open a file without over-writing, instead appending to the end of the file. A file is created if one does not exist.
>>> with open("numbers.dat", "a") as file:
...     file.write("Hello World.\n")
See python-file-io for a side-by-side picture of what r, w and a each do to an existing file.
Summary
We can read strings from files and write strings to files. A file-pointer is moved every time a line from the file is read. Therefore, if we want to read a line twice the file must be opened twice.
Next: 2025-09-01-testing (Lecture 6C).
String Methods
Lecture 6A. Course logistics are in csse1001. The full reference on these string methods is python-string-methods.
Outline
- Built-in string methods and
help() - Method invocation syntax
- Reading a
helpsignature: optional parameters in square brackets - Exercises:
title,center - Splitting and joining strings
- Sanitizing data with
strip
Why learn string methods?
Three points frame the topic:
- During file processing (Lecture 6B, 2025-09-01-file-io) we will be working extensively with strings.
- We are able to replicate the functionality of any string method with our current tools.
- So: strive to implement any string method you use at least once.
The point is not that these methods do something you couldn’t write yourself; it’s that you should know what’s in the box before you rewrite it.
Built-in string methods
Python’s str type has a myriad of built-in methods. Review them via help(str):
>>> help(str)
...
| capitalize(self, /)
|     Return a capitalized version of the string.
|
| casefold(self, /)
|     Return a version of the string suitable for
|     caseless comparisons.
Type Enter to scroll and q to escape (quit) help.
Methods
Strings are objects — we’ll eventually learn what that means fully (2025-09-09-object-oriented-programming). Objects have methods, which are like functions but have a different invocation syntax. We don’t say:
>>> capitalize("hello")
NameError: name 'capitalize' is not defined
but rather:
>>> "hello".capitalize()   # Note the ()
'Hello'
The receiver goes before the dot, and the empty parentheses are still required even when there are no arguments.
For information on a particular method:
>>> help(str.find)
find(...)
    S.find(sub[, start[, end]]) -> int

    Return the lowest index in S where substring sub is found,
    such that sub is contained within S[start:end]. Optional
    arguments start and end are interpreted as with slice notation.

    Return -1 on failure.
(END)
Interpreting help
The square brackets in the parameters for find
find(sub[, start[, end]])indicate that the parameter is optional. This rule recurses — an optional parameter can itself have optional parameters — so the nesting says that end is only available once start has been given.
The comprehensive ways of calling find are therefore:
"team".find("I")
"team".find("I", 1)
"team".find("I", 1, -1)
whereas find(1, -1) is not allowed, since sub is required.
>>> "hello world".find("world", 6)
6
>>> "hello hello".find("hello")
0
>>> "hello hello".find("hello", 1)
6
>>> "hello hello".find("hello", 1, 3)
-1
The last two calls show what start and end do: they do not shift the answer, they shrink the haystack.
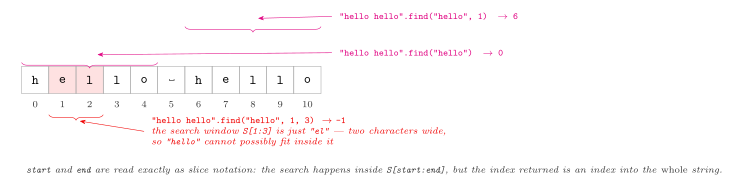
Figure 18: The three find calls on the string hello hello, drawn against the indexed string. Searching for hello with no window matches at 0; passing start=1 skips past that match and finds the second copy at 6; passing start=1, end=3 restricts the search to S[1:3], which is the two characters el and so cannot contain a five-character needle — hence -1. The returned index is still an index into the whole string, not into the window.
Exercise: title case
Convert a string of text into title format. For example,
'a tale of two cities'should be converted to'A Tale Of Two Cities'.
This can be accomplished by invoking the appropriate string method correctly:
>>> cs = "a tale of two cities"
>>> cs.title()
'A Tale Of Two Cities'

>>> "a tale of two cities".title()
'A Tale Of Two Cities'
Both forms work: the receiver can be a variable or a literal, since the literal is the object.
Exercise: centering text
Write a function that, given a word and an integer width, centers the word in a sequence of
xs.
The expected behaviour, for a function foo:
>>> foo('spam', 10)
'xxxspamxxx'

>>> foo('101', 20)
'xxxxxxxx101xxxxxxxxx'

>>> foo('UQQU', 30)
'xxxxxxxxxxxxxUQQUxxxxxxxxxxxxx'
A string method already does this. Its help:
>>> help(str.center)
Help on method_descriptor:

center(self, width, fillchar=' ', /)
    Return a centered string of length width.

    Padding is done using the specified fill character
    (default is a space).
(END)

>>> 'spam'.center(10, 'x')
'xxxspamxxx'
>>> '101'.center(20, 'x')
'xxxxxxxx101xxxxxxxxx'
Compare fillchar=' ' here with the bracket notation on the find help: both mean “optional”, but this signature also tells you the default value. The / marks the end of the positional-only parameters.
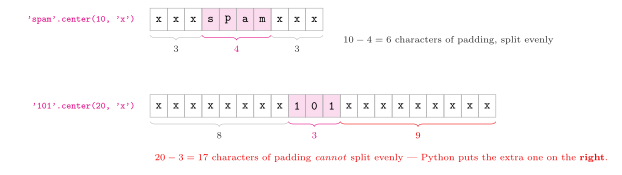
Figure 19: Why '101'.center(20, 'x') is not symmetric. center fills the leftover width with fillchar; when that leftover is odd it cannot split evenly, and the output here has 8 padding characters on the left and 9 on the right, so in this call the extra one goes on the right.
foo('UQQU', 30) has no such problem: \(30 - 4 = 26\) splits evenly into 13 and 13.
Splitting strings
>>> "a b c".split()          # Default split at space.
['a', 'b', 'c']
>>> "axbxc".split()
['axbxc']
>>> "axbxc".split('x')
['a', 'b', 'c']
>>> "axbxc".split('bx')
['ax', 'c']
>>> "a, b, c".split(',')     # Useful for CSV processing
['a', ' b', ' c']
>>> "a, b, c".split(', ')    # Removing tailing/leading spaces
['a', 'b', 'c']
What the transcript shows:
- With no argument,
splitsplits on whitespace: any run of whitespace serves, not only a single space. That is why"axbxc".split()finds nothing to split on and returns a one-element list. - The separator is an arbitrary string, not a single character (
'bx'). - The separator is consumed. Splitting
"a, b, c"on','leaves the spaces attached to the following fields; splitting on', 'eats them too. See python-string-methods for a drawing of exactly which characters each call removes.
That last point is the one that matters for 2025-09-01-file-io — CSV rows read from a file arrive with whatever spacing the file happens to use.
Joining strings
>>> ",".join(["A", "B", "C"])
'A,B,C'
>>> "".join(["A", "B", "C"])
'ABC'
>>> ", ".join(["A", "B", "C"])
'A, B, C'
>>> "xxx".join(["A", "B", "C"])
'AxxxBxxxC'
The separator is the string the method is called on, and the list is the argument — the opposite way round from how it reads in English. The separator goes between elements only, never at the ends.
Sanitizing data
>>> help(str.strip)
strip(self, chars=None, ) unbound builtins.str method
    Return a copy of the string with leading and trailing
    whitespace removed.

    If chars is given and not None, remove characters in
    chars instead.

>>> "   123   \n".strip()   # A newline is considered whitespace
'123'
strip removing \n is exactly what makes it useful in the next lecture: every line a file hands you (except possibly the last) ends in a newline.
Summary
Sometimes datatypes come with extra functionality by way of methods. In particular, there are many string methods that will aid with text processing.
Next: 2025-09-01-file-io (Lecture 6B).
Testing
See csse1001 for course logistics. This is Lecture 6C, which concludes the module on imperative programming. It follows 2025-09-01-string-methods (6A) and 2025-09-01-file-io (6B). See python-testing for the full reference on doctest and assertions.
Outline
- Docstring (value) testing with
doctest.testmod() - Writing good doctests, and common whitespace/equality pitfalls
- Testing unordered types, and multi-line docstrings
- Black-box testing
doctest.testfile()- Assertions
- Practice exercises
Docstring testing
The docstrings so far have included doctests, e.g.:
def factorial(k: int) -> int:
    """Returns k! where k! = k*(k-1)! and 0! = 1.
    Assumes k > 0
    >>> factorial(3)
    6
    >>> factorial(0)
    1
    """
doctest.testmod() actually runs these tests, rather than just documenting intended usage.
Catching mistakes
def factorial(k: int) -> int:
    """
    >>> factorial(3)
    6
    >>> factorial(0)
    1
    """
    ans = 1
    for ell in range(k):
        ans *= ell     # bug: multiplies by ell, not k - ell
    return ans
>>> import doctest
>>> doctest.testmod(verbose=True)
**********************************************************************
File "__main__", line 5, in __main__.factorial
Failed example:
factorial(3)
Expected:
6
Got:
0
**********************************************************************
1 items had failures:
1 of 2 in __main__.factorial
***Test Failed*** 1 failures.
TestResults(failed=1, attempted=2)The corrected version:
def factorial(k: int) -> int:
    ans = 1
    for ell in range(k):
        ans *= k - ell
    return ans

>>> doctest.testmod()
TestResults(failed=0, attempted=2)
Writing good doctests
A comprehensive doctest suite should:
- Test typical cases and edge cases.
- Test the zero of the data type — e.g.
0,[],"". - Test the singleton of the data type — e.g.
1,[1],"a". - Test for correctness, not violations of the function’s contract (precondition).
- Avoid redundant tests.
Whitespace pitfalls
Doctest compares printed output exactly, character for character — not equality of values. Both of the following would fail:
def identity(x):
    """
    >>> identity([])
    [ ]
    >>> identity([1, 2, 3])
    [1, 2, 3]
    """
(an extra space inside [ ] doesn’t match Python’s actual [] output)
def identity(x):
    """
    >>> identity([])
    []
    >>> identity([1, 2, 3])
    [1,2,3]
    """
(the empty-list line matches this time, but [1,2,3] doesn’t match Python’s own printed form, [1, 2, 3] — Python always prints a space after each comma in a collection literal)
String testing vs. equality testing
>>> identity(1.0)
1
fails because doctest compares the printed string 1.0 against the expected string 1 — they don’t match, even though 1.0 == 1 is True as values. Expected output must match exactly what Python would print.
Black-box testing
Suppose we’re given a function whose code is hidden. Confidence in its correctness then has to come through testing alone.
def pow(x: int, y: int) -> float:
    """ Returns x**y. Precondition: y >= 0. """
    return x*pow(x, y-1) if y else 1
def pow(x: int, y: int) -> int:
"""
>>> pow(0, 0) # zero
1
>>> pow(1, 0) # unit and zero
1
>>> pow(0, 1) # zero and unit
0
>>> pow(3, 1) # typical and unit
3
>>> pow(1, 3) # unit and typical
1
>>> pow(6, 10) # typical
60466176
"""Exercise: ourmax
def ourmax(x: int, y: int) -> int:
    """ Return the larger of x and y. """
This is left as an open exercise: write the doctests, then implement.
Testing sets
A set does not print in the order it was written. Below, the small-integer sets happen to come out sorted and the string sets do not — neither is a language guarantee, since the printed order simply follows the hash table’s layout. That is what makes a set’s printed form a poor thing to write a doctest against:
>>> {3, 2, 1}
{1, 2, 3}
>>> {2, 1, 3}
{1, 2, 3}
>>> {"a", "b", "c"}
{'c', 'b', 'a'}
>>> {"b", "c", "a"}
{'c', 'b', 'a'}
Testing unordered types
Since string-testing an unordered type’s printed representation is unreliable, compare against a literal value with == instead:
def identity(x):
    """
    >>> {3, 1, 2} == identity({1, 2, 3})
    True
    >>> {1: "A", 2: "B"} == identity({1: "A", 2: "B"})
    True
    """
Multi-line docstrings
Setting up intermediate values across multiple >>> lines within one doctest is allowed:
def identity(x: int) -> int:
    """
    >>> a = 2
    >>> b = 1
    >>> identity(a + b)
    3
    """
Exercise: poly_min
def poly_min(a: int, b: int, c: int) -> float:
    """ Return the (approximate) minimum value of
    f(x) = a*x**2 + b*x + c
    for x any float.
    """
Float testing is complicated by the fact that float arithmetic is inexact — we usually only insist on answers being close enough, rather than equal, using a tolerance:
def poly_min(a: int, b: int, c: int) -> float:
    """
    >>> tolerance = 10**-3
    >>> abs(poly_min(1, 0, 0) - 0) < tolerance
    True
    >>> abs(poly_min(3, -5, 10) - 7.916666666666666) < tolerance
    True
    """
The implementation is left as an open exercise; the doctests show the tolerance-based comparison technique.
Testing outside the module: doctest.testfile
Docstring examples inside a function aren’t meant to fully test a module — they explain usage to users. A full test suite belongs outside the functions, in its own file:
# testing.txt
sandbox.py should be in the same directory as this file
and contain fact. This entire file will be treated as
a docstring. For instance, this paragraph is considered
a comment despite not having quotes around it.
>>> from sandbox import fact
>>> fact(3)
6
>>> fact(0)
1
>>> doctest.testfile("testing.txt", verbose=True)
...
1 items passed all tests:
3 tests in testing.txt
3 tests in 1 items.
3 passed and 0 failed.
Test passed.
TestResults(failed=0, attempted=3)Assertions
An assertion is a truth claim that Python enforces at runtime. Programming with assertions helps catch problems early, by preventing (what are supposed to be) impossible situations from silently propagating — a failed assertion raises an AssertionError and stops the program.
def fact(x: int) -> int:
    ans = 1
    for k in range(x):
        ans *= k
    assert ans > 0   # all factorials are positive/non-zero
    return ans

>>> fact(3)
AssertionError
(This deliberately reuses the earlier buggy pattern — multiplying by the loop variable itself, which starts at 0 — to demonstrate the assertion catching the bug.)
>>> fact(3)
Traceback (most recent call last):
  File "<python-input-0>", line 1, in <module>
    fact(3)
  File "sandbox.py", line 7, in fact
    assert ans > 0
AssertionError
assert False can also mark a line that’s assumed to be unreachable — e.g. after an exhaustive if/else that’s supposed to cover every case:
def maximum(x: int, y: int) -> int:
    if x > y:
        return x
    else:
        return y

    assert False   # (supposed to be) unreachable
Practice exercises
The following all ask: write doctests for the given signature, then implement it.
def indices(cs: str, subcs: str) -> list[int]:
    """ Return the indices in cs at which non-overlapping copies of
    subcs start. subcs is non-empty.
    >>> indices("A Coool pool look", "oo")
    [3, 9, 14]
    """
def insert_after(xs: list[int], a: int, b: int) -> list[int]:
""" Insert <a> after each occurrence of <b> in list <xs>. """def increment_count(hash: dict[str, int], key: str) -> None:
""" Increment the value associated with key in hash in-place.
If key is not a key in hash, add key with value 1.
"""
if key in hash:
hash[key] += 1
else:
hash[key] = 1
return Nonedef average_grade(grades: list[list[object]]) -> float:
""" Return the average grade for all the students in grades,
where the inner lists contain a student ID and a grade.
>>> grades = [['998765', 70], ['111234', 90], ['444567', 83]]
>>> average_grade(grades)
81.0
"""def choose_chars(xs: str, ys: str, mask: str) -> str:
""" Return a string where index i is xs[i] if mask[i] is '0'
and ys[i] if mask[i] is '1'.
Precondition:
1. xs, ys, and mask are all of the same length.
2. mask consists only of characters '0' and '1'.
"""indices, insert_after, average_grade and choose_chars are left as open exercises. increment_count is already implemented; only its doctests are left to write.
Summary
We can verify our docstring examples using doctest. Tests should have sufficient coverage and not be redundant. Testing cannot guarantee a function works in general — it gives confidence that it’s working, and helps prevent coding mistakes.
This concludes the module on imperative programming.
Next: 2025-09-09-exceptions and 2025-09-09-object-oriented-programming (Lecture 7).
Week 7
Exceptions
Lecture 7A. See csse1001 for course logistics and python-exceptions for the full reference on try/except and raising errors.
Outline
- Syntax errors vs. run-time errors (exceptions)
- Common built-in exception types
try/except,else,finally- Catching specific vs. all exceptions
- Exercise: robust input reading
- Raising exceptions
Syntax errors vs. exceptions
When Python parses a file, it returns a syntax error if the contents don’t correspond to valid Python code. Code that passes parsing transitions to run-time, where errors (exceptions) can occur — these differ from syntax errors because you cannot detect them until they trigger.
As a pipeline: source → parse → (SyntaxError, or run-time) → exception → execution aborts.
Run-time errors are bad because they abort the execution of the program and all intermediate work is lost (unless saved to a file).
Common run-time exceptions
| Exception | Description |
|---|---|
AssertionError |
an assertion fails |
IOError |
file does not exist |
IndexError |
index out of range |
KeyError |
key in dict does not exist |
NameError |
variable does not exist |
TypeError |
unexpected type is given to a function |
ValueError |
correct type, but inappropriate value |
ZeroDivisionError |
division by zero attempted |
Four of them are shown below at the REPL. An uncaught exception prints a traceback before the error line; the traceback is shown in full once below and elided in the later transcripts.
>>> xs = [1, 2, 3]
>>> xs[4]
Traceback (most recent call last):
  File "<stdin>", line 1, in <module>
IndexError: list index out of range
>>> xs = {'a': 1}
>>> xs['b']
KeyError: 'b'TypeError’s message depends on which operand comes first, because it is the left operand’s + that is tried first:
>>> "two" + 2
TypeError: can only concatenate str (not "int") to str
>>> 2 + "two"
TypeError: unsupported operand type(s) for +: 'int' and 'str'
The integer casting function has the type contract int(xs: str) -> int, and thus int("ten") should not throw a type error, because "ten" is indeed a string — it is the value that is wrong:
>>> int("ten")
ValueError: invalid literal for int() with base 10: 'ten'
Try/except
Catching an exception lets the program handle it gracefully.
try:
    <code>   # this code may throw an error
except ExceptionName:
    <code>   # this code is run when the error is of kind ExceptionName
(Also called try-catch in other languages, e.g. C++.) Typically used in user-facing layers of your software and/or when accessing/interacting with external resources — files, databases, API calls, network calls, and so on.
>>> x = 0
>>> 1/x               # without try-except
Traceback (most recent call last):
  File "<stdin>", line 1, in <module>
ZeroDivisionError: division by zero

>>> x = 0
>>> try:
...     1/x
... except ZeroDivisionError:      # it doesn't halt the execution
...     print("Please don't divide by zero...")
Please don't divide by zero
The except ZeroDivisionError: clause doesn’t halt the execution. That is the whole point of the construct: the same division that aborted the program without it now just prints a message and carries on.
Catching specific vs. all exceptions
We can catch any exception without specifying the error type, but this can lead to undiscovered issues — it’s better to catch specific error types:
>>> x = 0
>>> try:
...     print(y)
...     1/x
... except:
...     print("You did something fishy...")
It is bad practice to ignore all errors.
We can also catch among a list of exceptions:
>>> try:
...     print(y)     # this throws a name error
...     1/x
... except NameError:
...     print("You're using an undefined name...")
... except ZeroDivisionError:
...     print("You divided by zero...")
Exercise: robust input reading
Write a function
def io_double() -> int:which takes no inputs, but rather prompts the user for a number and then doubles that number.
A first attempt:
>>> def io_double() -> int:
...     str_x = input("Number please: ")
...     int_x = int(str_x)
...     return 2*int_x

>>> io_double()
Number please: 2
4
>>> io_double()
Number please: two
    ...
ValueError: invalid literal for int() with base 10: 'two'
Wrapping the cast in a try/except inside a while True: loop lets the user retry until they succeed:
>>> def io_double() -> int:
...     while True:
...         str_x = input("Number please: ")
...         try:
...             int_x = int(str_x)
...             return 2*int_x   # unreachable if the line above errors
...         except ValueError:
...             print("That wasn't a number! Try again...")

>>> io_double()
Number please: two
That wasn't a number! Try again...
Number please: 3
6
The return line is unreachable if the cast above it errors. The return is inside the try, so if int(str_x) raises, control jumps to the except and the loop goes round again. Put the return outside the try and the retry behaviour disappears.
General try/except framework
try:
    <code>
except ExceptionName_0:
    <code>
except ExceptionName_1:
    <code>
    ...
except ExceptionName_k:
    <code>
The clauses are not a set — they are tried in source order, and the first one whose exception type matches wins. Figure 20 shows the search.
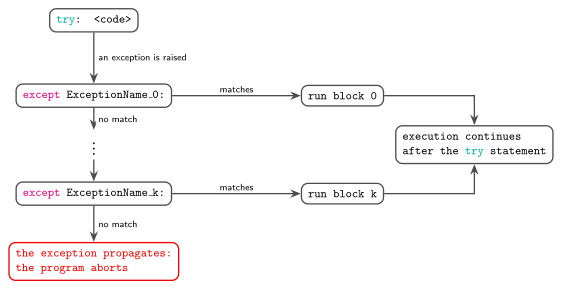
Figure 20: How a raised exception finds its handler: the except clauses are tried top to bottom, the first matching clause runs and the rest are skipped, and if none match the exception propagates and the program aborts. This is why the ‘specific exceptions before general ones’ rule matters — a general clause placed early swallows everything below it.
Python requires that specific exceptions appear before general ones:
try:
    <code>
except ZeroDivisionError:
    <code>
except:
    <code>
else and finally
A try block can carry two further blocks beyond its except clauses. Figure 21 shows how the four fit together.
Figure 21: The four blocks associated with a try. The exception path leaves try on the right and lands in except (the purple crossed circle marks it); the no-exception path leaves on the left and skips straight past except into else (green tick). finally hangs below with no arrow into it at all, because it is not on either path — it runs either way, which is what the dashed border and the blue information glyph mark. Each keyword has its own colour: try teal, except magenta, else blue, finally purple.
try:
    <code>       # run the code under try
except:
    <code>       # execute the code under except, when there is an exception
else:
    <code>       # no exceptions? run the code under else, after try
finally:
    <code>       # always run this code
try:
x = int(input("Type a number: "))
y = 1/x
# note that if an exception is raised on a line of code here,
# the following lines don't execute -- keep try blocks as short
# as possible (don't put everything here!)
except ZeroDivisionError:
print("Cannot enter zero")
except ValueError:
print("Must type in a number")
else:
print(y)
finally:
print("this block gets always executed")Raising
To raise an error (rather than catch it):
>>> def safe_div(x: int, y: int) -> float:
...     """
...     Return 1 / (x-y)
...     """
...     if x == y:
...         raise ZeroDivisionError   # halt execution as soon as zero division
...     return 1/(x-y)

>>> safe_div(1, 1)
ZeroDivisionError
raise ZeroDivisionError halts execution as soon as the zero division is detected. raise is the opposite move to try/except — instead of absorbing a failure it manufactures one, at the earliest point where the failure is knowable, rather than letting a bad value travel further into the program.
def get_applicant_age() -> int:
    age = int(input("Enter your age: "))
    if age < 15:
        raise ValueError(f"Age must be >= 15 to apply for a license -- currently it's {age}")
    else:
        return age

try:
    get_applicant_age()
except ValueError:
    print("do something - don't issue license, etc")
Two exception-handling philosophies
LBYL (Look Before You Leap) — test first, then act:
if b == 0:
    result = None
    print("zero division!")
else:
    result = a/b
EAFP (Easier to Ask for Forgiveness than Permission) — act, then handle the failure:
try:
    result = a/b
except ZeroDivisionError:
    result = None
    print("zero division!")
Summary
We can catch errors which throw at runtime with the try-except control structure. We should only use a try-catch when absolutely necessary.
Next: 2025-09-09-scope (Lecture 7B).
Introduction to Object-Oriented Programming
Lecture 7C. Course logistics are in csse1001. The full reference on classes, instantiation, and encapsulation is python-classes-and-objects.
Outline
- Programming paradigms: imperative vs. declarative
- Objects, classes, and
self - Instantiation, attributes, equality, and aliasing
- Methods
- Private variables, getters, and setters
Programming paradigms
Imperative programming — the programmer says what to do, by:
- Procedural — grouping instructions into functions.
- Object-oriented — grouping instructions into objects that combine data (state, attributes) and behaviour (methods).
(Imperative, the adjective, means giving an authoritative command.)
Declarative programming — the programmer declares what they want, through:
- Functional — a series of function applications.
- Logic — a question about a system of facts and rules.
- Mathematical — optimization.
In one line: imperative is how to do it, declarative is what to do. It is climbing rung by rung to the Moon versus simply floating there.
See programming-paradigms for the full reference, including where each paradigm shows up across this course.
Object-oriented programming
The fundamental building block of object-oriented programming is the class or object. In this paradigm, the design principle is to solve a problem by creating objects that interact with one another.
Definition (Object). An object is a collection of fields and attributes (i.e. data comprising the object’s state) along with methods (i.e. class-scoped functions) that can act on the object itself. An object can reference and change its state, and has a notion of self.
Real-world analogues are in Figure 22. The split into a data half and a behaviour half is the whole idea.
Figure 22: Three real-world classes. Each class is a name above two stacked boxes: the attributes (what it knows) on top and the methods (what it does) beneath. The attributes box is outlined in the dark purple used for class names and the methods box in bright magenta, so the two halves are told apart by outline colour, not just by position.
Convention: names of classes (i.e. objects) in Python are in CamelCaps. That is, ClassNamesAreLikeThis.
I: Structure (holding named attributes)
class Point():                  # Point() is the class name
    def __init__(self):         # the initializer method
        self.x = 0              # -.
        self.y = 0              # -'  attributes
>>> p = Point() # 'instantiation' of the point object
>>> p
<__main__.Point object at 0x10a9e0dd8>
>>> type(p)
<class '__main__.Point'>
>>> p.x
0
>>> p.y
0Point() is the class name, def __init__(self): is the initializer method, and the two self. lines are the attributes. p.x accesses an attribute of an instance with .; these are called instance variables.
What is self?
Think of the class definition as a blueprint with placeholders or actual items. self has an address, self has num_bedrooms, self has num_bathrooms, self has a garage, self has has_solar_panels — these are the placeholders. When you create an instance of that class (e.g. beach_house), self becomes the actual object you’re working with, and each of these becomes a real attribute stored in the object when it’s created. You can create many instances using the same blueprint, each with its own unique values.
(The analogy is inspired by an example from MIT6.100L.)
>>> p = Point()
>>> p.x = 2
>>> p.y = 3
>>> p.x
2
>>> p.y
3
Initializing with input
Instantiating an object with input instead:
class Point():
    def __init__(self, x: int, y: int):
        self.x = x
        self.y = y
>>> p = Point(2, 3) # creates a new object of type Point and passes 2 and 3 to __init__
>>> p.x
2
>>> p.y
3⚠ Do not pass an argument for self — Python handles it automatically.
Equality and aliasing
Two separately-constructed objects with identical attribute values are not == by default; two names for the same object are. The difference is a difference in the picture of memory, not in the code that looks at it — see Figure 23.
>>> p = Point(2, 3)
>>> q = Point(2, 3)
>>> p == q
False
>>> p = Point(2, 3)
>>> q = p # q is an alias for the same object as p
>>> q.x = 1
>>> p.x
1
>>> p == q # because these aliases point to the same object
True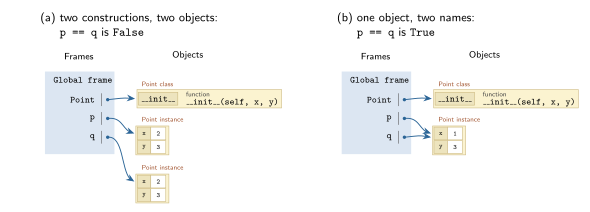
Figure 23: Equality and aliasing side by side, in Python Tutor notation. In (a) q = Point(2, 3) builds a second object, so p and q arrow off to two separate Point instances that happen to hold equal values, and p == q is False. In (b) q = p binds a second name to the one object, so both arrows converge on it — that convergence is the whole notation for aliasing — and mutating q.x is visible as p.x, and p == q is True. Both panels also show Point itself bound in the Global frame to the class object holding init, which is what makes Point(2, 3) callable at all.
Equality (as opposed to identity) has to be defined explicitly — that is what __eq__ is for, and it comes in the next lecture, 2025-09-16-dunder-methods.
II: Methods (object-scoped functions)
class Person():
    def __init__(self, name: str) -> None:   # a method for initializing
        self.name = name

    def foo(self) -> str:            # methods must take self as the first argument
        return f"My name is {self.name}."
>>> p = Person("Slim Shady")
>>> p.foo()
'My name is Slim Shady.'
>>> foo() # you must access foo via the object
NameError: name 'foo' is not definedA method is reached by dot notation: <object_variable>.<method>(<parameters>).
>>> p = Person("What")
>>> q = Person("Who")
>>> r = Person(f"{2*'chka'} Slim Shady")
>>> p.foo()
'My name is What.'
>>> q.foo()
'My name is Who.'
>>> r.foo()
'My name is chka chka Slim Shady.'
Each instance keeps its own independent state.
f"{2*'chka'} Slim Shady"actually evaluates to"chkachka Slim Shady"— for the output above the repeated string would need its own trailing space,f"{2*'chka '}Slim Shady".
Exercise: a Counter object
Often our objects will be analogous to things that exist in the real world. Create an object called Counter that simulates the functionality of a hand-held tally counter.
class Counter():
def __init__(self) -> None:
self._value = 0 # a 'private' variable
def get_value(self) -> int: # this is called a 'getter'
return self._value
def click(self) -> None:
self._value = self._value + 1
def reset(self) -> None:
self._value = 0>>> x = Counter()
>>> x.get_value()
0
>>> x.click()
>>> x.click()
>>> x.click()
>>> x.get_value()
3
>>> x.reset()
>>> x.get_value()
0Separate instances track their own count independently — each Counter() call builds its own object with its own _value, exactly as the two Point instances in Figure 23 (a) do:
>>> x = Counter()
>>> y = Counter()
>>> x.click()
>>> y.click()
>>> x.click()
>>> x.get_value()
2
>>> x.click()
>>> y.get_value()
1Private variables
The underscore on _value in the Counter object is used to denote this name as private. This signals that programmers should never manipulate this value outside the object.
Warning: nothing actually prevents a user from accessing a private variable in Python!
>>> x = Counter()
>>> x.get_value()
0
>>> x.click()
>>> x._value = -10 # accessing private variables is bad practice
>>> x.click()
>>> x.get_value()
-9Setters
It is good practice to use methods for changing an object’s private variables at user level. We usually enable this through a setter method which sets a private value:
class Counter():
def __init__(self) -> None:
self._value = 0
def set_value(self, x: int) -> None: # a 'setter'
if x < 0:
raise ValueError
self._value = xThe raise is the point of routing writes through a method: it is the only place the class gets to reject a value before it becomes state. (See python-exceptions.)
Classic getters and setters
# Classic implementation of getters and setters
class Person():
def __init__(self, name):
self._name = name # leading underscore = "internal use"
def get_name(self):
return self._name
def set_name(self, value):
if not value:
raise ValueError("Name cannot be empty")
self._name = value
p = Person("Alice")
print(p.get_name())
p.set_name("Sara")
print(p.get_name())Pythonic getters and setters
Python’s @property decorator lets a getter/setter pair be used with plain attribute-access syntax, rather than explicit get_/set_ method calls — the validation still runs, but the call sites read like ordinary attribute reads and writes:
# Pythonic implementation of getters and setters
class Person():
def __init__(self, name):
self._name = name
@property
def name(self): # getter
return self._name
@name.setter
def name(self, value): # setter
if not value:
raise ValueError("Name cannot be empty")
self._name = value
p = Person("Alice")
print(p.name) # looks like attribute access (calls the getter)
p.name = "Sara" # looks like assignment (calls the setter)
print(p.name) # SaraSummary
OOP helps organise code using classes and objects.
- Class: a blueprint for creating objects.
- Object: an instance of a class.
- Encapsulation: keep data safe inside classes using attributes and methods.
Next: magic methods — 2025-09-16-dunder-methods.
Scope
Lecture 7B. See csse1001 for course logistics and python-scope for the full reference on global/local scope and the LEGB rule.
Outline
- Definition of scope
- Global variables and constants
- Local variables and shadowing
- The
globalkeyword - The LEGB name-resolution rule
Definition: scope
The scope of a variable is the region of the code where the variable’s name is recognized (i.e. the variable is accessible/visible).
>>> x = 2
>>> y = 3
>>> def foo():
... return x
>>> def bar():
... return foo()*y
>>> foo()
2
>>> bar()
6x and y are global variables available to all functions. The global scope is the whole snippet. Figure 24 below draws global scope as a purple box.
Global variables
A global variable (or simply “global”) is defined outside of any function (at the module level) and can be accessed by all functions in the module. Anything declared outside a function is globally accessible provided there is no local variable with the same name. A variable declared globally is said to have global scope.
Avoid global variables if possible: they can make code difficult to maintain.
Constants
By convention, constants are defined in SNAKE_CASE_CAPS:
PI = 3.14159
NUMBER_OF_DAYS_IN_WEEK = 7
GRID_SIZE = 5Warning: unlike in other languages, the value of a constant is not protected and can be changed at run-time:
>>> PI = 3.14159
>>> PI = 3
>>> PI
3Local variables shadow globals
>>> x = 2
>>> def foo():
... x = 7 # local variable
... return
>>> foo()
>>> x
2Despite having the same name, the x of foo() is assumed local — its scope is foo(). Assigning to x inside the function creates a brand-new local variable rather than touching the global one, which is why x is still 2 after the call.
Figure 24 draws this. A rounded box over a span of code lines is a scope, and the box’s colour names the kind of scope.
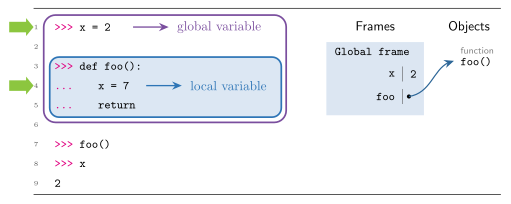
Figure 24: Scope boxes over a snippet. The purple outline is global scope and encloses the whole snippet; the blue outline with a pale blue fill is local scope and encloses only the body of the def, nested inside the purple box. Each box has a short arrow out to a colour-matched label. The green markers in the far-left margin flag lines 1 and 4 — the two assignments to x. Beside the code is the Python Tutor memory picture: the Global frame holds x bound to 2 and foo bound (blue arrow) to a function object, and there is no trace of foo’s x at all, because the local x died when the call returned.
The global keyword
We can specify that foo should be using x as a global. It is good practice to declare your globals when you use one:
>>> x = 2
>>> def foo():
... global x
... x = 7
... return
>>> foo()
>>> x
7If a function only ever creates a local variable (no global declaration), that name doesn’t exist outside the function — outside of foo the variable x does not exist; x is a local variable:
>>> def foo():
... x = 2 # local variable
... return x
>>> foo()
2
>>> x
NameError: name 'x' is not definedA common gotcha: UnboundLocalError
>>> x = 2
>>> def foo():
... x = x + 2
... return
>>> foo()
UnboundLocalError: local variable 'x' referenced before assignment.When foo creates x, it becomes local and thereby has no value at the time of assignment. As soon as foo assigns to x anywhere in its body, Python treats x as local throughout the whole function — so the right-hand side x + 2 tries to read a local x that doesn’t have a value yet. Declaring global x first fixes this, since x then refers to the module-level variable throughout, and the effect accumulates across calls:
>>> x = 2
>>> def foo():
... global x
... x = x + 2
... return
>>> foo()
>>> x
4
>>> foo()
>>> x
6Shadowing
A parameter is the other way a local name comes into existence, and it shadows a global just as an assignment does. Figure 25 applies the same scope boxes to that case.
Figure 25: Shadowing by a parameter, in the same notation as Figure 24. The only structural change from that figure is where the blue local box starts: it opens on the def line itself, because here the local x is the parameter rather than an assignment in the body. foo(7) returns 7 while the global x is still 5 — the green margin markers flag exactly those two lines — and the Python Tutor panel shows why: the only x anywhere in the Global frame is the global one, bound to 5.
Despite having the same name, there are two x’s: one with a global scope and another with local. The parameter shadows the global variable, making it temporarily invisible inside foo.
A function can’t declare a name as both a parameter and global at the same time:
>>> x = 5
>>> def foo(x):
... global x
... return
SyntaxError: name 'x' is parameter and globalMixing globals and locals
>>> x = 5
>>> def foo(y):
... return x*y
>>> foo(7)
35
>>> foo(x)
25Globals and locals can be used in mixed computation.
A global name doesn’t exist until the function runs
Declaring global x inside a function does not, by itself, create the module-level x. The binding only happens when the assignment actually executes — i.e. when the function is invoked:
>>> def foo():
... global x
... x = 2
... return
>>> x
NameError:
>>> foo()
>>> x
2Python’s LEGB rule for resolving names
When Python looks up a name it searches four namespaces in a fixed order, dropping to the next only when the name is not found — and raising an error if it runs out. Figure 26 shows the cascade.
Figure 26: Python’s LEGB rule. Read it top to bottom: each red hook is one ‘if not found’ step down to the next enclosing namespace, and the cascade bottoms out in a red Error! rather than in a default value. The bolded initial letters spell the mnemonic, and red marks the failure path.
- Local — the current function.
- Enclosing — outer functions, for nested functions.
- Global — top-level script/module global variables.
- Built-in — Python’s built-in names.
If the name isn’t found at any level: Error!
Worked: an invocation counter
Write a function foo that returns the number of times the function has been called/invoked. For example:
>>> foo()
1
>>> foo()
2
>>> foo()
3A solution with the global keyword:
count = 0
def foo() -> int:
""" Return the number of times foo() has been called. """
global count
count += 1
return countThe state has to live outside the function: a count = 0 inside foo would be re-created local and reset to 0 on every call, and count += 1 without the global declaration is exactly the UnboundLocalError case above. print(count) in place of return count would produce the identical REPL display — the REPL doesn’t echo a None return — while giving a function that returns nothing, so it would not satisfy the task as stated.
Summary
The places in your program that can access a name is called the scope of that name. The global scope is for things like constants, whereas names declared in functions get locally scoped to that function.
Next: 2025-09-09-object-oriented-programming (Lecture 7C).
Week 8
Dunder (Magic) Methods
Lecture 8A. See csse1001 for course logistics and python-dunder-methods for the full reference on __init__, __str__, __repr__, and operator overloading. Diagrams below follow csse1001-diagram-notation.
Outline
- Recap: class vs. object
- Exercise: a
Clickertally counter - Underscores: anonymous variables, private variables, and dunder names
- Magic methods:
__init__,__str__,__repr__,__eq__,__add__,__sub__ - Overloadable operator tables (binary, unary, comparison)
- Instance variables vs. class variables
Class vs. object
A class collects attributes on one side and methods on the other, and every object is one instantiation of it (Figure 27).
Figure 27: The class as blueprint: the attributes it declares (left, purple outline), the methods it provides (right, magenta outline), and the objects instantiated from it below. The arrows run downward, class to instance. Inheritance arrows run the other way, up into the parent.
| Aspect | Class | Object |
|---|---|---|
| Meaning | Blueprint/template for creating objects | Instance of a class with real data |
| Represents | General concept or idea | Concrete entity based on a class |
| Defined by | class keyword |
Instantiating a class |
| Example | class Animal: |
my_animal = Animal() |
| Memory usage | No direct memory for data | Allocates memory for attributes |
| Purpose | Describes structure and behaviour | Performs actions and stores data |
| Analogy | House blueprint | Actual built house |
Exercise: Clicker
Create an object called
Clickerthat simulates the functionality of a mechanical hand tally counter.
The class this produces is used again under Instance vs. class variables.
Underscores
Python overloads the underscore with several distinct meanings (not an exhaustive list):
- As anonymous variables, e.g.
for _ in [1, 2, 3]:orx, _, z = (1, 2, 3). - For giving special meaning to functions and names:
_privatevariables — a leading single underscore (convention only).__names__— reserved for Python’s magic/dunder methods, like__init__().
III: Magic (overloading built-in functions)
Magic is part III of the OOP material. Parts I (structure) and II (methods) are in Lecture 7C (2025-09-09-object-oriented-programming).
We can create a new type, Fraction, with:
- Data attributes: numerator, denominator.
- Methods: arithmetic operations (
add,eq,sub) to work with+,==,-; and a print-friendly representation.
Initialiser
Runs when the object is instantiated (created):
class Fraction():
def __init__(self, numer: int, denom: int) -> None:
self._numer = numer
self._denom = denomString representation (__str__)
Says what to display when printing the object:
>>> p = Fraction(2, 3)
>>> print(p)
<__main__.Fraction object at 0x7f95c625e9d0>Without a __str__, printing an object just shows its default memory-address representation. Defining one fixes this:
>>> class Fraction():
... def __str__(self) -> str:
... return f"A fraction: {self._numer} / {self._denom}" # must return a string
>>> p = Fraction(2, 3)
>>> print(p)
A fraction: 2 / 3__str__ must return a string. Returning anything else is a TypeError raised at print time, not at definition time: nothing checks the return annotation when the def is executed.
Representation (__repr__)
The representation of an object is what Python displays for it in the console, and should be enough information to re-instantiate the object:
>>> class Fraction():
... def __repr__(self) -> str:
... return f"{self._numer} / {self._denom}"
>>> p = Fraction(2, 3)
>>> p
2 / 3This is equivalent to calling print(repr(p)) or directly invoking print(p.__repr__()) — but we don’t manually invoke these methods; Python does.
__repr__ vs. __str__
__repr__is meant to be used by the programmer:Unambiguous — it should clearly describe the object.
Meant for debugging, logging, and development, not end-users.
Its output should, if possible, be a valid Python expression that could recreate the object when passed to
eval():>>> u Vector2D(x=2, y=3) >>> print(u) 2D Vector: (2, 3) --- length: 3.605551275463989 >>> u_copy = eval(repr(u)) >>> u_copy Vector2D(x=2, y=3)The round trip is
u→repr()→"Vector2D(x=2, y=3)"→eval()→ a second object that prints the same way. (The transcript shows the tworeprs matching; it never evaluatesu == u_copy.)
__str__is meant for pretty prints (a user-friendly string, printed for the user).
In the transcript above, >>> u and >>> print(u) produce different output from the same object: the first goes through __repr__, the second through __str__.
Equality (__eq__)
We can specify that objects are equal for reasons other than sharing a memory location:
>>> class Fraction():
... def __eq__(self, other) -> bool: # note the use of 'other'
... a, b = self._numer, self._denom
... c, d = other._numer, other._denom
... return a*d == b*c
>>> p = Fraction(4, 6)
>>> q = Fraction(2, 3)
>>> p == q
True4/6 == 2/3 because the method cross-multiplies (4·3 == 6·2) rather than comparing the stored pairs. The second parameter is named other, and the convention holds for every binary dunder, which receives the left operand as self and the right one as other.
Addition (__add__)
Instructs Python on how to add two objects together:
>>> from __future__ import annotations # for the class' own type hint
>>> class Fraction():
... def __add__(self, other) -> Fraction:
... a, b = self._numer, self._denom
... c, d = other._numer, other._denom
... return Fraction(a*d + c*b, b*d)
>>> p = Fraction(2, 3)
>>> q = Fraction(1, 2)
>>> p + q
7 / 6The from __future__ import annotations line is there so that -> Fraction can name the class inside its own body, before the class object exists.
The last line shows 7 / 6 only because __repr__ is in the class too: __add__ builds a new Fraction and the console then displays it through __repr__. Two magic methods are cooperating in one line of output. Read literally, though, each of these transcripts re-enters class Fraction(): from scratch at the prompt, so the class here has only __add__. With no __init__, p = Fraction(2, 3) would fail on line 7 with TypeError: Fraction() takes no arguments, long before p + q was reached. The transcripts only work if you read the class as accumulating from one to the next.
Subtraction (__neg__, __sub__)
>>> from __future__ import annotations
>>> class Fraction():
... def __neg__(self) -> Fraction:
... return Fraction(-self._numer, self._denom)
... def __sub__(self, other) -> Fraction:
... return self + -other
>>> p = Fraction(2, 3)
>>> q = Fraction(1, 2)
>>> p - q
1 / 6__sub__ is defined entirely in terms of __add__ and __neg__: p - q becomes p + (-q) = Fraction(2·2 + (−1)·3, 3·2) = Fraction(1, 6).
The negation method is __neg__, not __neq__. Spelled def __neq__(self), the class would define an unused __neq__ and leave -other inside __sub__ unsupported, so p - q would raise TypeError: bad operand type for unary -: 'Fraction' rather than printing 1 / 6.
What “magic” actually means
Every method above is invoked for you. You write the ordinary Python in the left column of Figure 28; the interpreter turns it into the call on the right. The one place above where a dunder method is called by name is print(p.__repr__()). Even that is not an operator being invoked, and it is the equivalent you don’t type. Dunder names do appear elsewhere, in __main__ inside the default repr, in the from __future__ import annotations import, in the three operator tables below and in the wording of the Vector and Currency exercises, but never as a call you write.
Figure 28: What ‘magic’ means: you write the left-hand column, Python calls the right-hand one. We don’t manually invoke these methods; Python is the one doing it. One nuance the arrows flatten: __init__ really runs on the freshly created object before the name p is bound to it.
Overloadable operators
| Binary operator | Magic method |
|---|---|
+ |
__add__ |
- |
__sub__ |
* |
__mul__ |
** |
__pow__ |
// |
__floordiv__ |
/ |
__truediv__ |
| Unary operator | Magic method |
|---|---|
- |
__neg__ |
abs |
__abs__ |
~ |
__invert__ |
| Comparison | Magic method |
|---|---|
< |
__lt__ |
<= |
__le__ |
== |
__eq__ |
!= |
__ne__ |
> |
__gt__ |
>= |
__ge__ |
Instance vs. class variables
The Clicker class for counting clicks:
class Clicker():
def __init__(self) -> None:
self._clicks = 0 # each instance has its own
def click(self) -> None:
self._clicks += 1To calculate the number of clicks across all counters, use a class variable:
class Clicker():
_all_clicks = 0 # every instance has access to this
def __init__(self) -> None:
self._clicks = 0
def click(self) -> None:
self._clicks += 1 # access instance variable
Clicker._all_clicks += 1 # access class variable>>> c = Clicker(); d = Clicker(); e = Clicker() # semi-colons can be used instead of newlines
>>> c.click(); c.click(); c.click();
>>> d.click(); d.click();
>>> e.click()
>>> (c._clicks, d._clicks, e._clicks) # bad practice
(3, 2, 1)
>>> (c._all_clicks, d._all_clicks, e._all_clicks)
(6, 6, 6)
>>> Clicker._all_clicks # you don't even need an instance
6The (3, 2, 1) against (6, 6, 6) is the whole point: three objects, three private counters, one shared total.
Figure 29: The click counts drawn as a memory picture, in Python Tutor’s idiom. Three instances carry three separate _clicks cells; the single Clicker class object carries one _all_clicks cell, which is why c._all_clicks, d._all_clicks, e._all_clicks and Clicker._all_clicks all read 6.
Figure 29 also explains why click writes Clicker._all_clicks += 1 rather than self._all_clicks += 1: the class variable lives on the class object, so the class object is what has to be updated. See python-dunder-methods for what goes wrong if you write it the other way.
Summary
Classes (or objects) are like functions that maintain their state even after returning. Classes have attributes and methods, and provide a public interface — through setters and getters — for manipulating values considered private to the object.
Exercises
Task (Vectors). + concatenates lists:
>>> [1, 2, 3] + [4, 5, 6]
[1, 2, 3, 4, 5, 6]Implement a Vector class so that we can do:
>>> x = Vector(1, 2)
>>> y = Vector(3, 4)
>>> x + y
<4, 6>
>>> -x
<-1, -2>Both output lines come back at a bare prompt, so the <4, 6> format is __repr__’s job, not __str__’s.
Starter code:
class Vector():
def __init__(self, x: int, y: int):
self._x, self._y = x, y
def __add__(self, other):
...
def __neg__(self):
...
def __repr__(self):
...Extension: try creating a Vector class that handles an arbitrary dimension. If two vectors of different sizes are added, __add__ should raise a ValueError.
The Vector2D in the __repr__ vs. __str__ transcript earlier is a related class, with a __repr__ of Vector2D(x=2, y=3) and a __str__ that also reports a length. It is 2D-only, so it is not the arbitrary-dimension extension asked for here. python-dunder-methods has a Vector2D consistent with that transcript.
Task (Currency). Create a class for working with the currencies AUD, EUR, and JPY. Implement the __repr__, __gt__, and __add__ magic methods — you’ll need the dollar/euro/yen symbols, and to do currency conversions when adding different currencies together. Use: 1 AUD is 0.62 EUR; 1 AUD is 79.7 JPY.
Starter code:
class Currency():
def __init__(self, value: float, currency: str) -> None:
""" <currency> is one of 'AUD', 'EUR', 'JPY'. """
self.value = value
self.currency = currency
def __repr__(self) -> str:
...
def __add__(self, other) -> object:
...
def __gt__(self, other) -> bool:
...This starter breaks the convention used everywhere else: value and currency are public, where every other class here uses _value-style private attributes.
Task (Greeter). A fully worked example, using a class variable as a shared lookup table:
class Greeter():
_lang_to_hello = {
"FR": "Bonjour",
"AU": "G'Day",
"DE": "Hallo",
"CN": "Ni Hao"
}
def __init__(self, country: str) -> None:
self._country = country
def greet(self) -> str:
return Greeter._lang_to_hello[self._country]>>> a = Greeter("FR"); b = Greeter("AU")
>>> c = Greeter("DE"); d = Greeter("CN")
>>> a.greet()
'Bonjour'
>>> b.greet()
"G'Day"
>>> c.greet()
'Hallo'
>>> d.greet()
'Ni Hao'b.greet() comes back as "G'Day", in double quotes where the other three are in single quotes: that is the repr Python prints for a string containing an apostrophe.
This is the class-variable idea from Figure 29 used for something other than counting: one dictionary, built once on the class object, read by every instance. Four Greeter objects, four _country strings, one _lang_to_hello.
Next: 2025-09-16-representation-invariants (Lecture 8B).
Representation Invariants
Lecture 8B. Course logistics are in csse1001. The full reference on writing and enforcing invariants is python-representation-invariants. Diagrams below follow csse1001-diagram-notation.
Outline
- What representation invariants are, and why they matter
- Documenting invariants in docstrings
- Enforcing invariants with
assertand a_check_invariants()helper - Encapsulation and avoiding exposed mutable state
- Worked example:
DroneFlight
What are representation invariants?
Representation invariants are conditions or properties that must remain true about the internal state of an object throughout its lifetime (usually enforced during development).
Why do they matter?
- Discover and prevent bugs and inconsistent behaviour.
- Simplify the implementation of methods (you can assume a valid starting state).
- Make code more maintainable and robust.
- Help detect errors early.
- Serve as documentation for developers.
Examples
- A stack’s size must never be negative.
- A list’s length must equal the number of elements it contains.
- All elements in a set must be unique.
- A fraction’s denominator cannot be zero.
- A date must follow calendar rules (e.g. no 30 Feb).
- For free/basic X (Twitter) accounts, the standard limit is 280 characters per tweet.
Writing representation invariants
Clearly state invariants in docstrings, underneath a class’s attributes:
class Fraction():
"""Represents a mathematical fraction.
Representation Invariants:
- denominator != 0
- if fraction is zero, it is represented as 0/1
- if fraction is negative, numerator is negative
"""Each of these three is a checkable statement about the stored attributes, not a description of what the class is for. The second and third are normalisation rules — they pick one representative out of several possible encodings of the same value (so 0/5 and 1/-2 are not valid internal states even though they name valid numbers).
Enforcing representation invariants
Assertions
Directly check conditions in the initialiser and setter methods, using an assert statement to raise an AssertionError if an assumption isn’t met:
assert <statement that should be true>, "Error message if not True"- Assertions can be disabled in production when running Python with optimization (
python -O). - Assertions are meant to find bugs (e.g. invalid states) during development.
class Fraction():
def __init__(self, numer: int, denom: int) -> None:
assert denom != 0, "Denominator cannot be zero."
assert isinstance(numer, int), "Numerator must be an integer."
assert isinstance(denom, int), "Denominator must be an integer."
# Ensure denominator is positive
if denom < 0:
numer, denom = -numer, -denom
self._numer = numer
self._denom = denom
# Special case for zero
if self._numer == 0:
assert self._denom == 1, "Zero must be 0/1"Two things about this listing:
- The sign rule is established, not checked:
if denom < 0: numer, denom = -numer, -denomrewrites the arguments so the invariant “if the fraction is negative, the numerator is negative” holds by construction. - The zero rule is checked, not established:
Fraction(0, 5)passes every earlier assertion, then tripsassert self._denom == 1. So a perfectly reasonable-looking call is rejected rather than normalised to0/1. The two invariants in the same initialiser are enforced by opposite strategies.
Private attributes and encapsulation
- Use private (
_variable) names to discourage direct access. - Provide public methods that maintain the invariants.
- Never expose mutable objects directly:
class Team():
def __init__(self):
self._members = [] # internal mutable state
# classic getter (dangerous!)
# BAD!
def get_members(self):
return self._members
# instead, return a copy
# GOOD!
# def get_members(self):
# return list(self._members) # caller can't modify internal state directly
t = Team()
members = t.get_members() # gets the actual list inside the class
members.append("Alice") # modifies it directly!
print(t.get_members()) # ['Alice'] <-- internal state was changed externallyThe reason this defeats every assertion you could write is that no method of Team is running when the change happens: get_members has already returned, and the caller then mutates the object Team is still holding, from outside (Figure 30). This is the aliasing problem from 2025-08-18-non-primitive-data arriving inside a class.
Figure 30: Why ‘never expose mutable objects directly’. Top: get_members returns the real list, so t._members and the caller’s members name the same object and the caller’s append mutates the Team without any Team method running. Bottom: list(self._members) hands back a copy, so the append lands where the Team cannot see it. Aliasing is two arrows converging on one object; a copy is two arrows to two objects.
Helper methods
Define a private method (e.g. _check_invariants()) that validates the object’s state, and call it after any state changes:
state change →
_check_invariants→ valid
When to call _check_invariants():
- At the end of
__init__. - At the end of methods that modify object state.
- At the beginning of methods that rely on invariants being true.
class Fraction():
def __init__(self, numer: int, denom: int) -> None:
self._numer = numer
self._denom = denom
self._check_invariants()
def _check_invariants(self) -> None:
"""Verify that representation invariants hold."""
assert isinstance(self._numer, int), "Numerator must be an integer."
assert isinstance(self._denom, int), "Denominator must be an integer."
assert self._denom != 0, "Denominator cannot be zero."
assert self._denom > 0, "Denominator must be positive."
if self._numer == 0:
assert self._denom == 1, "Zero must be 0/1"Compared with the assertion version above, the centralised version drops the if denom < 0 normalisation and asserts self._denom > 0 instead. Everything is now checked and nothing is fixed up, so Fraction(1, -2) raises here where the earlier version quietly rewrote it to -1/2. That is the trade the pattern makes — one method that says what a valid object looks like, and no hidden repair.
Best practices
- Document invariants in docstrings.
- Centralise invariant checking in a single method.
- Do not expose methods that could violate invariants.
- Create comprehensive test cases focusing on edge cases (see 2025-09-01-testing).
- Python’s type hints can express some invariants.
- Balance strictness with practicality.
Exercise: DroneFlight
You have joined a start-up that records quick test flights for hobby drones. Write a minimal DroneFlight class that always keeps its state valid by enforcing these representation invariants:
- Drone ID — exactly six alphanumeric characters (e.g.
"A1B2C3"). - Altitude — must stay within 0 m–120 m, the CASA (Civil Aviation Safety Authority) legal ceiling for recreational drones.
- Battery — an integer percentage in the range 0–100.
Solution
class DroneFlight:
"""
Model a quick test-flight for a small hobby drone.
Attributes:
_id (str) : 6-character alphanumeric flight identifier.
_altitude (float): Current altitude in metres above launch point.
_battery (int): Remaining battery charge as a percentage (0-100).
Representation invariants:
- _id is a 6-character alphanumeric string
- 0 ≤ _altitude ≤ 120
- 0 ≤ _battery ≤ 100
"""
_ID_LEN = 6 # one place to change if the rule changes
_MAX_ALT = 120.0 # metres (CASA limit)
def __init__(self, flight_id: str) -> None:
self._id = flight_id
self._altitude = 0.0
self._battery = 100
self._check_invariants()
def _check_invariants(self) -> None:
assert (
isinstance(self._id, str)
and self._id.isalnum()
and len(self._id) == self._ID_LEN
), "ID must be a 6-character alphanumeric string."
assert 0.0 <= self._altitude <= self._MAX_ALT, "Altitude out of range."
assert 0 <= self._battery <= 100, "Battery out of range."
# Getter and setter methods
def get_flight_id(self) -> str:
"""Return the immutable flight identifier."""
return self._id
def get_altitude(self) -> float:
"""Return current altitude in metres."""
return self._altitude
def get_battery(self) -> int:
"""Return remaining battery charge (percentage)."""
return self._battery
def set_altitude(self, value: float) -> None:
"""Set altitude, clamping to legal ceiling."""
if not isinstance(value, (int, float)):
raise TypeError("Altitude must be a number.")
if not 0.0 <= value <= self._MAX_ALT:
raise ValueError(f"Altitude must be 0-{self._MAX_ALT} m.")
self._altitude = float(value)
self._check_invariants()
def __repr__(self) -> str:
return (f"DroneFlight({self._id}, "
f"alt={self._altitude:.1f} m, bat={self._battery} %)")
def ascend(self, metres: float) -> None:
"""Climb *metres* metres (cannot exceed the legal ceiling)."""
if metres < 0:
raise ValueError("ascend() expects a non-negative distance.")
self.set_altitude(min(self._altitude + metres, self._MAX_ALT))
def land(self) -> None:
"""Land the drone and consume 5 % battery."""
self.set_altitude(0.0)
self._battery = max(self._battery - 5, 0)
self._check_invariants()Three techniques in this solution are the transferable part of the exercise:
- Class constants for the limits.
_ID_LENand_MAX_ALTare class variables (see 2025-09-16-dunder-methods), so the code enforcing those two limits reads them from a single place: one place to change if the rule changes, as the comment on_ID_LENsays. The class only half keeps the promise, though: the docstring above still spells out0 ≤ _altitude ≤ 120in words, and the battery bounds are written literally as100in__init__and0/100in_check_invariants()with no constant behind them. assertfor bugs,raisefor callers._check_invariants()usesassert— it is looking for a broken implementation, and it is fine for it to vanish underpython -O.set_altitude()usesraise TypeError/raise ValueError— it is validating an argument the caller supplied, and that check must run in production. Both appear in the same class, deliberately.- Mutation routed through one method.
ascend()andland()do not touchself._altitude; they callset_altitude(), so there is exactly one place that can change the altitude and exactly one place the range check has to live.ascend()also clamps withmin(..., self._MAX_ALT)before calling, so a legal climb past the ceiling stops at the ceiling instead of raising.
>>> d = DroneFlight("ABC123")
>>> d.ascend(50)
>>> print(d)
DroneFlight(ABC123, alt=50.0 m, bat=100 %)
>>> d.altitude = 200
Caught: Altitude must be 0-120 m.
>>> DroneFlight("BAD!")
Caught: ID must be a 6-character alphanumeric string.
>>> d.land()
DroneFlight(ABC123, alt=0.0 m, bat=95 %)
Figure 31: The DroneFlight demo as a state trace: each accepted call lands the object in a snapshot that satisfies all three documented invariants, and _check_invariants() is what asserts it. The panel on the right gives that method’s three assert conditions, with the class constants replaced by their values (_ID_LEN → 6, _MAX_ALT → 120.0) so the bounds can be read off directly; they are the same three invariants the docstring states in words. The rejected calls below never produce a snapshot at all — the guard fires first, so no invalid state is ever reachable. A green tick is an accepted call and a red cross is a rejected one. The rejected altitude change is drawn as d.set_altitude(200), the call that actually raises, because d.altitude = 200 does not call the setter at all; its message reads 0-120.0 m, which is what the class’s own f-string over _MAX_ALT = 120.0 produces.
The
d.altitude = 200line in the transcript appears to raise a “Caught” error, but as written this class only definesset_altitude()as an ordinary method — it has no@property/@altitude.setter. Plain attribute assignment liked.altitude = 200doesn’t callset_altitude()at all; it silently creates a brand-new, unrelatedaltitudeattribute (alongside the real_altitude) and raises nothing. To actually trigger the validation, the call has to bed.set_altitude(200)wrapped in atry/except (TypeError, ValueError) as e: print("Caught:", e). TheCaught:prefix on both error lines comes from a wrapper of that kind. ConstructingDroneFlight("BAD!")is legitimate, though —__init__really does call_check_invariants(), so an invalid ID genuinely raises anAssertionErrorthere (assuming it’s likewise wrapped in atry/except AssertionError)._check_invariants()would not catch the strayaltitudeattribute either: it only ever inspects_id,_altitudeand_battery.One further mismatch:
_MAX_ALTis120.0, so the f-string inset_altitudeproduces"Altitude must be 0-120.0 m.", not the0-120 min the transcript. Figure 31 shows the message the listed code would actually produce, withd.altitude = 200replaced by theset_altitudecall that reaches that f-string.
Summary
- Representation invariants define the valid states of an object.
- They help catch bugs early and document assumptions (mostly during development time).
- We can use
_check_invariants()to verify invariants, and call it after state changes. - Good invariants are specific, testable conditions.
Next: composition and inheritance (Week 9) — 2025-09-23-composition and 2025-09-23-inheritance.
Week 9
Composition
Lecture 9A. See csse1001 for course logistics and python-composition for the full reference on has-a relationships.
Outline
- The DRY principle, and two ways to reuse classes: composition and inheritance
- Composition (“has-a” relationships)
- Worked example:
DroneFlightcomposed ofBattery,Camera, andMotor - Hot-swapping composed objects
Recap
Dunder methods from last lecture (see 2025-09-16-dunder-methods, python-dunder-methods):
| Category | Key methods | What they enable |
|---|---|---|
| Lifecycle | __init__ |
Control object initialisation |
| String rep | __repr__, __str__ |
Unambiguous & user-friendly text |
| Numeric ops | __add__, __sub__, __mul__, … |
Custom arithmetic (1/2 + 1/3, v1 * v2) |
| Comparisons | __eq__, __lt__, __gt__, … |
Sorting, ==, < |
And representation invariants (see 2025-09-16-representation-invariants, python-representation-invariants):
| What? | Why? | How? |
|---|---|---|
| Conditions that must hold for an object’s private state at all times (e.g. \(0 \leq \text{altitude} \leq 120\), ID is 6 digits). | Prevents invalid states; simplifies reasoning & testing (assume invariants true); catches bugs early with clear, localised checks. | Set valid values in __init__; centralise assertions in a private helper like _check_invariants(). |
Reusing code
DRY (don’t repeat yourself) principle: in general, duplication and copy/paste are bad:
- Increased risk of bugs.
- Maintenance overhead.
- Poor readability.
- Code bloat.
- Signals that a common abstraction/refactoring is needed.
There are two ways to reuse classes in a new class: composition and inheritance.
Composition
We can use objects built from other classes (implemented by us or others) as attributes of our new class/object. This isn’t new — we’ve already used integers, strings, lists, etc. as attributes for our classes; we can do this with other (more complex) classes as well. For example, if we are implementing a Robot class, we can use an object from a Battery class (already implemented by us or others) as one of its attributes.
Modularity:
- A
Studenthas aString(e.g. to store the student’s name). - A
Robothas aSensor,Motor, etc.
Has-a relationship
When an object (say Car) includes another object inside itself as an attribute (say Engine), this forms a has-a relationship — we call this class composition:
>>> class Car():
... def __init__(self, engine : Engine) -> None:
... self._engine = engine # Car has-a engine.The relationship is drawn as one box inside another, not as a line between two boxes. The whole encloses the part:
Figure 32: Composition as containment. The steel-blue rectangle is the whole (the car object); the brick-red rounded rectangle nested inside it is the part (the engine object), with its own methods stop() and start() listed under a rule. Nesting is the notation: a has-a relationship is drawn by putting the part inside the whole. A connecting line comes with UML in week 10.
Using it:
engine = Engine()
car = Car(engine)
car.engine.start()
car.engine.stop()
print(car.engine.power)car.engine does not match self._engine
The snippet reaches into the part as car.engine, but the __init__ above stores the part as self._engine, a private attribute. Written literally, car.engine would raise AttributeError.
The snippet is there for the shape of the relationship, not as a runnable transcript. The same mismatch recurs in the hot-swapping example below, where it changes what the code does.
Is-a or has-a
Recall the DroneFlight representation-invariants exercise from last lecture. The brief:
- Drone ID — exactly six alphanumeric characters (e.g.
"A1B2C3"). - Altitude — must stay within 0 m – 120 m, the CASA (Civil Aviation Safety Authority) legal ceiling for recreational drones.
- Battery — an integer percentage in the range 0 – 100.
The recap table above states the ID rule more loosely as “ID is 6 digits”. “Six alphanumeric characters” is the version to work from, since "A1B2C3" is not six digits.
“A Drone has a Camera” reads clearly; “A Drone is a Camera” does not. A drone has a camera, has a motor, and has a battery, so composition is the natural fit here, not inheritance.
Worked example: DroneFlight
class Battery:
def __init__(self, capacity: int = 100) -> None:
if capacity < 0:
raise ValueError("Capacity must be non-negative.")
self._level = capacity # percentage
def use_power(self, amount: int) -> None:
if amount < 0:
raise ValueError(f"Power usage must be non-negative.")
self._level -= amount
if self._level < 0: self._level = 0
print(f"Power used: {amount}%. Remaining: {self._level}%.")
def get_level(self) -> int:
"""Return remaining battery charge (percentage)."""
return self._level
class Camera:
def __init__(self, resolution: str = "12MP") -> None:
self._resolution = resolution
def take_photo(self) -> None:
print(f"Photo taken at {self._resolution} resolution.")
class Motor:
def __init__(self, power_rating: float = 100.0) -> None:
self._power_rating = power_rating # Watts
self._is_running = False
def start(self) -> None:
self._is_running = True
print("Motor started.")
def stop(self) -> None:
self._is_running = False
print("Motor stopped.")Each of the three is a complete, self-contained class that knows nothing about drones. DroneFlight then holds one of each:
class DroneFlight:
_ID_LEN = 6
_MAX_ALT = 120.0 # metres (CASA limit)
def __init__(self, flight_id: str, battery: Battery,
camera: Camera, motor: Motor) -> None:
self._id = flight_id
self._altitude = 0.0
self._battery = battery # Drone has-a Battery
self._camera = camera # Drone has-a Camera
self._motor = motor # Drone has-a Motor
self._check_invariants()
Figure 33: The DroneFlight object: one whole holding three parts, each part a complete class in its own right. The battery, camera and motor boxes are nested inside the drone box, the same containment notation as car and engine, and each part lists its own methods under a rule.
The rest of DroneFlight is written entirely in terms of those three parts. It never touches their internals, only their public methods:
def get_flight_id(self) -> str:
"""Return the immutable flight identifier."""
return self._id
def get_altitude(self) -> float:
"""Return current altitude in metres."""
return self._altitude
def get_battery(self) -> int:
"""Return remaining battery charge (percentage)."""
return self._battery.get_level()
def __str__(self) -> str:
return (f"DroneFlight({self._id}, alt={self._altitude:.1f} m, "
f"bat={self.get_battery()}%)")
def ascend(self, metres: float) -> None:
"""Climb *metres* metres (cannot exceed the legal ceiling)."""
if metres < 0:
raise ValueError(f"ascend() expects a positive distance.")
self.set_altitude(min(self._altitude + metres, self._MAX_ALT))
self._check_invariants()
def land(self) -> None:
"""Land the drone and consume 5% battery."""
self.set_altitude(0.0)
self._battery.use_power(5)
if self._motor.is_running():
self._motor.stop()
self._check_invariants()
def take_photo(self) -> None:
if self._battery.get_level() < 5:
print("Not enough battery to take photo.")
return
self._camera.take_photo()
self._battery.use_power(5)get_battery() delegates straight to self._battery.get_level(). Don’t call use_power(0) here. Just show the level. Even a zero-amount power use would print a spurious Power used: 0%. Remaining: ... line and would be conceptually the wrong operation: a getter reports state, it does not perform an action on the part.
Every method above has the same shape: DroneFlight decides when something happens and what the rules are (the 5% battery threshold, the 120 m ceiling), and the part decides how it happens. That division is the whole point of composition. take_photo() is the clearest case: the drone checks the battery, the camera takes the picture, the battery bills for it, and no class knows more than its own job.
Gaps in the listing
The listing above is not self-contained. It has four gaps:
set_altitude()is called but not defined above. Bothascend()andland()go through it rather than assigningself._altitudedirectly, which is the right instinct, because a setter is where an invariant check belongs. Lecture 8B’sDroneFlightdefines one._check_invariants()is called but not defined above either. It is the helper from the previous lecture.Motorhas nois_running()method.land()callsself._motor.is_running(), but theMotorclass above defines only the attributeself._is_runningand the methodsstart()andstop(). As written,land()would raiseAttributeError; the class needs a getter (orland()needs to consultself._motor._is_running, which would reach into a private attribute and defeat the encapsulation the example is demonstrating)._ID_LEN = 6is declared as a class constant but not used in any method above. It belongs to the invariant check, which is not in the listing.
Transcript
>>> b = Battery(); c = Camera (); m = Motor()
>>> d = DroneFlight("SAD564", b, c, m)
>>> d.ascend(80); d.take_photo()
Photo taken at 12 MP resolution.
Power used: 5%. Remaining: 95%
>>> d.land()
Power used: 5%. Remaining: 90%
>>> print(d)
DroneFlight(SAD564, alt=0.0 m, bat=90 %)This transcript is not exact output. The default resolution is the string "12MP", so the real line reads 12MP resolution. use_power ends its message with a full stop, and __str__ has no space before the %. Read it for the sequence of events, not character by character.
The sequence itself is right: ascend(80) is silent, take_photo() costs 5%, land() costs another 5%, and the final state is 0.0 m and 90%. That holds only once the pieces missing from the listing are supplied. With set_altitude() and _check_invariants() from lecture 8B, which defines both, one gap still bites: land() calls self._battery.use_power(5) before self._motor.is_running(), so it prints its battery line and then raises AttributeError, because Motor has no is_running(). The closing print(d) is not reached in a real session.
Hot-swapping
Because a composed attribute is just a reference to an object, it can in principle be replaced by any other object that supports the operations actually used on it. No shared base class is required. Take a camera that isn’t a Camera:
class ThermalCamera:
def __init__(self, resolution: str = "12MP"):
self.resolution = resolution
def take_photo(self):
print(f"Thermal image saved.")>>> b = Battery(); c = Camera (); m = Motor()
>>> d = DroneFlight("SAD564", b, c, m)
>>> d.take_photo()
Photo taken at 12 MP resolution.
Power used: 5%. Remaining: 95%
>>> d.camera = ThermalCamera()
>>> d.take_photo()
Figure 34: Hot-swapping. The same whole, drawn twice: the part inside it is replaced, and everything around it is untouched. The thick curved orange arrow from the old configuration to the new marks the substitution.
ThermalCamera does not inherit from Camera at all. It just happens to provide a take_photo() method with a compatible signature, so it works as a drop-in replacement. This is duck typing, a standard Python term: Python never checks that the new object is “officially” a Camera, only that it supports the operations actually performed on it. Contrast this with inheritance, where the substitute must be a subclass; see 2025-09-23-inheritance.
d.camera = ... does not actually swap anything
DroneFlight.__init__ stores the camera as self._camera, and take_photo() calls self._camera.take_photo(). Assigning d.camera = ThermalCamera() creates a brand new public attribute called camera and leaves _camera — the one the class actually uses — pointing at the original Camera. The final d.take_photo() above would print Photo taken at 12MP resolution. again, not Thermal image saved.
The idea is sound; the line as written misses the underscore. A working swap needs d._camera = ThermalCamera() (reaching into private state from outside, which the course discourages) or, better, a small setter on DroneFlight that does it deliberately.
python-composition spells out that better version for the Car/Engine pair: a dedicated swap_engine() method that stops the currently-running engine before replacing it. A method gets the chance to clean up the object it is discarding; a bare attribute assignment does not.
Summary
Build by pieces: snap self-contained objects together to create a richer whole.
- Modular: each component handles one clear task.
- Reusable: same parts work in new contexts; no code rewrite.
- Readable: data flow is explicit and easy to trace.
- Few side effects: isolated state keeps surprises and bugs low.
Next: 2025-09-23-inheritance (Lecture 9B), the other way of reusing a class.
Inheritance
See csse1001 for course logistics. This is Lecture 9B. See python-inheritance for the full reference on subclassing, super(), and polymorphism.
Outline
- Inheritance and “is-a” relationships
- Terminology: subclass/superclass, child/parent, extends
- Inheriting, introducing, and overriding methods
super()and extending methods- Polymorphism
Inheritance
Inheritance is another way of reusing code in classes. By inheriting from a class, we can create specialized (sub)classes while reusing attributes/methods from the original class. Key idea: building a hierarchy of classes.
Figure 35: The Robot hierarchy. Parent above, children in a row beneath, joined by a single stem down to a horizontal bus with a drop to each child. The connector carries no arrowhead; the next figure draws inheritance with arrows instead.
This is an “is-a” relationship: a DeliveryRobot is a Robot. DeliveryRobot, CleaningRobot, and HumanoidRobot all specialize the base class (Robot):
- They inherit the attributes and methods of the base class.
- They can override the attributes/methods of the base class — for example,
move()might have a different implementation in each. - They can have new (unique) attributes/methods, or new implementations.
More is-a hierarchies
Three more is-a hierarchies:
Employee→Programmer,Manager,AdminAnimal→Cat,Dog,Fox; and belowDog,ServiceDogPerson→Professor,Student; and belowStudent,UndergradStudentandGradStudent
Figure 36: The Animal hierarchy, drawn in a different style from Figure 35. Here the root is black, each child gets its own fill, and the connectors are thin straight lines — two diagonal, one vertical — each ending in its own arrowhead on the parent’s bottom edge. ServiceDog shows that a child can itself be a parent: it gets its own arrow into Dog. The child fill colours carry no meaning — Dog stays teal even though it is itself a parent.
See csse1001-diagram-notation for the two ways of drawing the inheritance connector, and 2025-10-07-uml for the formal notation that supersedes both in week 10.
Terminology
Given class Student(Person): — all of the following mean the same thing, and can be used interchangeably:
- The
Studentclass inherits from thePersonclass. - The
Studentclass is a subclass of thePersonclass. - The
Studentclass is a child class of thePersonclass. - The
Personclass is a superclass of theStudentclass. - The
Personclass is a parent class of theStudentclass. - (less often) The
Studentclass extends thePersonclass.
Reusing code via inheritance
Start with a base Robot, and a CleaningRobot written without inheritance:
class Robot:
def __init__(self, name: str, batt_level=100):
self.name = name
self.batt_level = batt_level
def charge(self):
self.batt_level = 100
print(f"{self.name} is fully charged!")
# CleaningRobot without inheritance -- repeated code
class CleaningRobot:
def __init__(self, name: str, batt_level: int):
self.name = name
self.batt_level = batt_level
def charge(self):
self.batt_level = 100
print(f"{self.name} is fully charged!")
def clean(self):
print(f"{self.name} is cleaning the floor.")The second listing repeats two members of Robot: charge and __init__. Only clean() is genuinely new. Instead, inherit from Robot:
# Inherit specialized robots from the base class
class CleaningRobot(Robot):
def clean(self):
print(f"{self.name} is cleaning the floor.")That is the entire class. The syntax class Child(Parent): is all it takes — see python-inheritance for the annotated form of that line.
CleaningRobot now inherits all attributes, __init__, and charge from Robot; constructing one runs Robot.__init__, and cleaner.name and cleaner.charge() both work without CleaningRobot mentioning them.
The four things a subclass can do
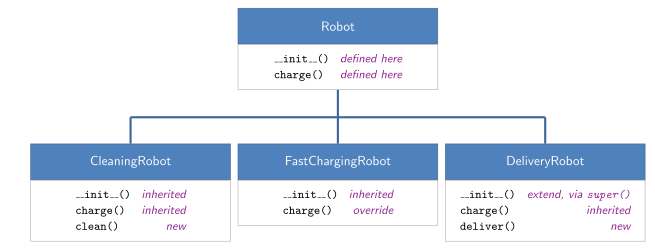
Figure 37: What each subclass does with each member of Robot: inherit it, override it, extend it, or add a new one. Each box lists the class’s members. The purple italic annotation beside each subclass member says which of the four applies; Robot’s own members are marked as defined there. The three-compartment UML class box that does this properly comes in week 10.
Introducing new methods
A child class can define methods that don’t exist on the base class at all. clean() only exists on CleaningRobot objects — calling it on a plain Robot is an error.
Overriding methods
We override a method by declaring one of the same name in the child class, exactly as we would normally declare a method:
class FastChargingRobot(Robot):
def charge(self): # overriding the charge method from the base class
self.batt_level = 100
print(f"{self.name} is fully charged in record time!")Calling charge() on a FastChargingRobot object calls this method, not Robot’s. Nothing else changes: FastChargingRobot still inherits __init__ and name.
Extending methods with super()
super() specifies that we want to use the method from the superclass, rather than the child class. That is what makes it possible to extend inherited behaviour instead of replacing it — most often in __init__, where the parent already knows how to set up the attributes it defined:
class DeliveryRobot(Robot):
def __init__(self, name: str, batt_level: int, load_capacity: int):
# super().__init__(...) calls the __init__ method from the parent (base) class
super().__init__(name, batt_level)
self.load_capacity = load_capacity
def deliver(self):
print(f"{self.name} is delivering a package up to {self.load_capacity}kg.")DeliveryRobot.__init__ handles only what is new (load_capacity) and hands name and batt_level back to Robot.__init__. This signature drops the batt_level=100 default that Robot.__init__ has — a DeliveryRobot must be given a battery level.
Polymorphism
The word polymorphism means to take on many forms. In computer science, an interface that works over different underlying data-types is called polymorphic.
The len function is polymorphic:
>>> len({'a': 1, 'b': 2, 'c': 3})
3
>>> len("Drop Bear")
9
>>> len([1, 2, 3, 4])
4Classes in one hierarchy are polymorphic in exactly the same way: the same call means “do the right thing for whatever this object actually is”.
# Polymorphism
robots = [
CleaningRobot("Roomba", 40),
DeliveryRobot("DHL-Bot", 20, 15),
FastChargingRobot("FlashBot", 5)
]
for r in robots:
r.charge() # behavior depends on class of objectThe list holds three different classes, and the loop body does not test which is which. What each iteration runs is decided by the object, not by the loop. Following each call through the class definitions:
CleaningRobot→ nochargeof its own →Robot.charge→ “Roomba is fully charged!”DeliveryRobot→ nochargeof its own →Robot.charge→ “DHL-Bot is fully charged!”FastChargingRobot→ has its owncharge→ stops there → “FlashBot is fully charged in record time!”
Adding a fourth robot class later does not require touching this loop — that is what the shared interface buys.
Exercise
Implement the SurveyDrone and DeliveryDrone classes, inheriting from the DroneFlight class of 2025-09-23-composition:
>>> class DroneFlight:
... pass # Implemented before
>>> class SurveyDrone(DroneFlight):
... pass # Implement SurveyDrone
>>> class DeliveryDrone(DroneFlight):
... pass # Implement DroneFlightBoth subclasses are left as stubs to implement. The last comment should read # Implement DeliveryDrone.
The exercise uses both techniques: DroneFlight was built by composition in the previous lecture, and these two subclasses extend it by inheritance. The two techniques are not alternatives at the level of a program — a SurveyDrone is a DroneFlight, which has a Camera.
Summary
We can create classes that inherit from other classes. By doing so, the subclass automatically receives all attributes and methods implemented in the superclass. The subclass can have additional methods and attributes, while overriding inherited methods and calling methods from its superclass.
Use inheritance only when there’s a clear “is-a” relationship.
Next: 2025-10-07-uml (Week 10), which gives this hierarchy a formal notation, and 2025-10-07-advanced-inheritance, which takes super() further.
Week 10
Advanced Inheritance
Lecture 10B. See csse1001 for course logistics, python-inheritance for the full reference, now extended with abstract base classes and MRO, and 2025-10-07-uml for the UML notation the diagrams below use.
Outline
- A useful trick for Assignment 2:
type(c).__name__ - Abstract base classes (and, optionally, the
abcmodule) - Method Resolution Order (MRO), and the four inheritance models
- The diamond problem, and C3 linearisation
super()and MRO
A useful trick for A2: getting the class name of an object
class Car():
pass
c = Car()
print(type(c))
print(type(c).__name__) # e.g., can be used in __repr__type(c).__name__ returns the class name. The two prints give <class '__main__.Car'> and Car.
So type(c).__name__ is the class name as a plain string. It is handy inside a __repr__ (see python-dunder-methods), which then stays correct even if the class is renamed or subclassed. The equivalent spelling from inside a method is self.__class__.__name__, used in the abc example below.
Abstract base classes
It is common to have an abstract base class that doesn’t have concrete methods/attributes, but enforces contracts in its children classes. You’re not meant to instantiate objects from these abstract classes directly.
Example: an abstract Shape class has an area() method without a concrete implementation. Every (concrete) child class of Shape must provide a concrete implementation of area(). Abstract base classes can sometimes have concrete implementations for some of their methods too (especially if those are meant to be used as-is by child classes).
import math
# Abstract class -- defines the interfaces (child classes must implement these methods)
class Shape:
def area(self) -> float:
raise NotImplementedError("Subclasses must implement area()")
def perimeter(self) -> float:
raise NotImplementedError("Subclasses must implement perimeter()")
class Circle(Shape):
def __init__(self, r: float):
self.r = r
def area(self) -> float:
return math.pi * self.r * self.r
def perimeter(self) -> float:
return 2 * math.pi * self.r
class Rectangle(Shape):
def __init__(self, w: float, h: float):
self.w, self.h = w, h
def area(self) -> float:
return self.w * self.h
def perimeter(self) -> float:
return 2 * (self.w + self.h)The abstract class is an ordinary class whose methods carry a full signature (including the -> float return annotation) but no body, only a raise. That signature is the contract; the raise is what makes breaking it noisy. The Shape version above is a plain-Python convention, not an enforced restriction:
Shape()on its own raises nothing at all, becauseShapeis still just a regular class. TheNotImplementedErroronly fires later, onShape().area(). Nothing actually stops you from instantiatingShape; only from usefully calling its unimplemented methods.
Optional: enforcing this properly with abc
This part is optional content and non-examinable. The standard-library abc module does enforce the contract at instantiation time:
from abc import ABC, abstractmethod
class Shape(ABC):
@abstractmethod
def area(self) -> float:
...
@abstractmethod
def perimeter(self) -> float:
...
# (optional) concrete helper: allowed in an abstract class
def describe(self) -> str:
return f"{self.__class__.__name__}"With this version, Shape() itself raises a TypeError at the point of instantiation. The abstract methods are enforced immediately, rather than only failing later when called. The exact wording of the message varies by Python version. describe() is the kind of concrete method an abstract base class can have: a real body in an otherwise abstract class, inherited as-is by any concrete subclass.
Two parents with the same method name
If a class inherits from two parents, and both parents have a method with the same name, which one does Python use?
Method Resolution Order (MRO)
MRO stands for Method Resolution Order — it defines the order in which Python looks through classes to find a method or attribute when it’s called on an object. It determines which method gets called when there are multiple implementations, and is stored in cls.__mro__.
Python supports several inheritance models. One running example covers all four: classes A, B, C, D, E.
Single inheritance
A class inherits from a single parent class. This listing is from the course notes. A inherits from object, the universal class:
>>> class A(object):
... def __init__(self, x):
... self.x = x
... def f(self):
... return self.x
... def g(self):
... return 2 * self.x
... def fg(self):
... return self.f() - self.g()>>> a = A(3)
>>> a.x
3
>>> a.f()
3
>>> a.g()
6
>>> a.fg()
-3B overrides exactly one method. First, B in a flattened form: every method B responds to, written out, with a comment saying where each one actually comes from:
>>> class B(A):
... def __init__(self, x): # inherit from A
... self.x = x
...
... def f(self): # inherit from A
... return self.x
...
... def g(self): # override
... return self.x ** 2
...
... def fg(self): # inherit from A
... return self.f() - self.g()That is the effective class. The code you actually write is only the one line that differs:
>>> class B(A): # inherit from A
... def g(self): # override
... return self.x ** 2>>> b = B(7)
>>> b.x
7
>>> b.f() # inherited from A
7
>>> b.g() # overridden
49
>>> b.fg() # inherited from A, but uses B's overridden g()
-42b.fg() is the one to study: fg is A’s code, unchanged, but the self.g() inside it dispatches on the runtime class, so it finds B.g. 7 - 49 = -42.
Multilevel inheritance
A class inherits from a child class, which in turn inherits from another parent class. It forms a linear chain of inheritance, creating a parent → child → grandchild relationship.
Flattened view of C, with the same kind of comments:
>>> class C(B):
... def __init__(self, x, y): # extend from B from A
... super().__init__(x)
... self.y = y
...
... def f(self): # inherit from B from A
... return self.x
...
... def g(self): # inherit from B
... return self.x ** 2
...
... def fg(self): # extend from B from A
... return super().fg() * self.yThere is a third category here. B only ever inherited or overrode; C extends __init__ and fg: it calls up to the parent with super() and then does more. For multilevel inheritance the MRO is simple: it just follows the chain from child to parent to grandparent. Here super() is B.
>>> c = C(3, 5)
>>> c.x
3
>>> c.y
5
>>> c.f() # inherited from B, from A
3
>>> c.g() # inherited from B (overridden there)
9
>>> c.fg() # extends B's fg: (3 - 9) * 5
-30Hierarchical inheritance
Multiple child classes inherit from a single parent class. D is A’s second child, and it overrides a different method from the one B overrode:
>>> class D(A): # inherit from A
... def __init__(self, x): # inherit from A
... self.x = x
...
... def f(self): # override
... return -2 * self.g()
...
... def g(self): # inherit from A
... return 2 * self.x
...
... def fg(self): # inherit from A
... return self.f() - self.g()And, as with B, the code actually written is just the one method that differs:
>>> class D(A): # inherit from A
... def f(self): # override
... return -2 * self.g()>>> d = D(3)
>>> d.x
3
>>> d.f() # overridden: -2 * g() = -2 * 6
-12
>>> d.g() # inherited from A
6
>>> d.fg() # inherited from A, uses D's overridden f(): -12 - 6
-18Three of the four models now fit in a single UML diagram:
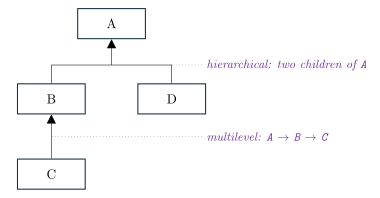
Figure 38: The running example so far: navy single-compartment boxes and the course’s filled inheritance arrowhead. Every edge on its own is single inheritance; A having two children is hierarchical; the A-B-C chain is multilevel. The two purple labels name the hierarchical and multilevel models.
Who defines what
The four listings as one table. Every B, C and D cell restates the comment on that method in the flattened view; A defines all four itself:
| Method | A |
B |
C |
D |
|---|---|---|---|---|
__init__ |
defines | inherits | extends (super()) |
inherits |
f |
defines | inherits | inherits | overrides |
g |
defines | overrides | inherits (from B) |
inherits |
fg |
defines | inherits | extends (super()) |
inherits |
Multiple inheritance
A class inherits from multiple parent classes:
>>> class E(B, D): # inherit from B and D
... passB and D sit above E. Add A back in above them and the shape gives the problem its name.
The diamond problem
Einherits from bothBandD.BandDboth inherit fromA.- Which version of
A’s methods shouldEuse? - Python resolves this with the MRO C3 linearisation.
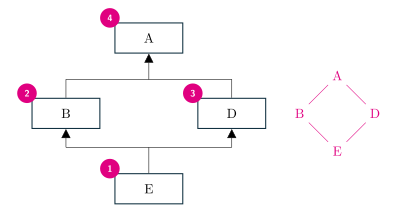
Figure 39: The diamond. The small magenta sketch beside it shows where the name comes from. The magenta numbered badges are E’s method resolution order, as given by E.__mro__, which continues to object after A.
C3 linearisation
Three rules:
- Child classes are checked before parents.
- Parents are checked in the order they are listed in the class definition.
- If a class appears multiple times in the MRO, only the last occurrence is kept.
Two ways to inspect the result:
>>> E.mro() # Method 1: mro() method
[<class '__main__.E'>, <class '__main__.B'>,
<class '__main__.D'>, <class '__main__.A'>,
<class 'object'>]
>>> for cls in E.__mro__: # Method 2: more readable format
... print(cls.__name__)
E
B
D
A
objectE defines nothing at all, so every call walks the MRO from the front:
>>> e = E(3) # which method will be called?
>>> e.x
3
>>> e.f()
-18
>>> e.g()
9
>>> e.fg()
-27| Call | MRO walk | Resolves to | Value |
|---|---|---|---|
e.x |
E, B, D — none of them defines __init__; A does |
A.__init__ → self.x = x |
3 |
e.f() |
E no, B no, D yes |
D.f → -2 * self.g() |
-18 |
e.g() |
E no, B yes |
B.g → self.x ** 2 |
9 |
e.fg() |
E no, B no, D no, A yes |
A.fg → self.f() - self.g() |
-18 - 9 = -27 |
Python resolves each name independently by walking the MRO. It does not pick one winning parent and take everything from it. e.f() lands in D and e.g() lands in B, and then A’s untouched fg calls both of them back through self.
A larger example, showing the general C3 rule in action:
>>> class A: pass
... class B: pass
... class C(A): pass
... class D(A, B): pass
... class E(C, D, B): pass
... print([cls.__name__ for cls in E.__mro__])
['E', 'C', 'D', 'A', 'B', 'object']A is reachable through both C and D, and B both directly from E and through D. Applying the three rules — children before parents, bases in listed order, keep only the last occurrence of a repeat — gives E, then C, then D, then A (D lists A before B), then B, then object. The example exercises multiple inheritance.
super() and MRO
The super() function follows the MRO, not just the immediate parent:
>>> class A:
... def ping(self):
... print("A")
... class B(A):
... def ping(self):
... print("B")
... super().ping()
... class C(A):
... def ping(self):
... print("C")
... super().ping()
... class D(B, C):
... def ping(self):
... print("D")
... super().ping()>>> D().ping()
D
B
C
AD’s MRO is [D, B, C, A, object]. When B.ping() calls super().ping(), it does not jump straight to A — B’s statically-declared parent — it calls the next class in the actual runtime MRO of the instance, which is C. This is what makes cooperative multiple inheritance work: each class’s super() call advances one step through the shared MRO, regardless of what its own declared parent is.
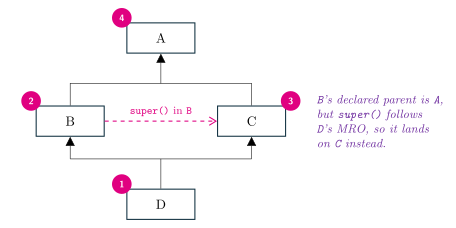
Figure 40: Why super() in B lands on C, for the D(B, C) hierarchy. The class boxes and filled inheritance arrows are the course’s UML notation. The magenta badges give the print order D B C A, and the dashed magenta arrow is the delegation made by super() in B.
If a class in the chain doesn’t call
super()at all, the chain of calls simply stops there — the MRO itself is unaffected (it’s purely a function of the inheritance structure), but fewerping()implementations actually get executed. For example, ifB.ping()omits itssuper().ping()call,D().ping()only printsDandB—CandAare never reached, even though they’re still part ofD’s MRO.
Summary
When a class inherits from multiple parents, it’s possible for more than one parent to define the same method or attribute. To avoid confusion and ensure consistency, Python uses a rule called Method Resolution Order (MRO) to determine the order in which classes are searched. MRO follows a well-defined path based on class hierarchy and inheritance order, ensuring that each method or attribute is found in a predictable and logical way. This is especially important in complex inheritance situations like the diamond pattern.
Next: design patterns and MVC (2025-10-14-model-view-controller, Week 11).
Unified Modelling Language (UML)
See csse1001 for course logistics — this note covers Lecture 10A’s technical content. See uml for the full reference on UML diagram notation, and csse1001-diagram-notation for the drawing conventions this course actually uses.
Outline
- Recap: inheritance vs. composition
- What UML is for
- UML class diagrams: the three-part class box, and visibility
- Relationship diagrams: inheritance, association, multiplicity, composition, aggregation
- A larger, real-world example
Recap: inheritance vs. composition
| Feature | Inheritance | Composition |
|---|---|---|
| Relationship | “Is-a” | “Has-a” |
| Flexibility | Less flexible (changes in parent affect children) | More flexible (components can be changed) |
| Reusability | Extends base class functionality | Contains objects that provide functionality |
| Example | Dog is a Animal |
Drone has a Camera |
See 2025-09-23-inheritance and 2025-09-23-composition for where these two came from.
What UML is for
Each person on a team asks a different question about the same design: “What classes?”, “Who calls what?”, “Where to pass this?”, “When you pass a drone object to…”. A diagram answers these questions cheaply. Source code answers them expensively.
A unified modelling language diagram is the standard way of illustrating relationships among classes. For our Animal class, the simplest possible version is four name-only boxes: Animal on top, with Cat, Dog and Fox beneath it, joined by one arrow pointing up into the parent.
UML class diagram
A class diagram is a type of UML diagram that shows:
- Classes and their attributes/methods.
- Relationships (e.g. inheritance, composition, association).
It is great for object-oriented design.
The class box
A class box has 3 parts, plus a visibility marker on every attribute and method:
- Top section: class name (e.g.
Animal). - Middle section: attributes (e.g.
name: str). - Bottom section: methods (e.g.
speak(): str). - Visibility:
-(private),+(public),#(protected).
Figure 41: The three-part class box: a generic template on the left and the concrete Animal box on the right, outlined in magenta. The purple italic labels name the three parts of the box: name, attributes and methods.
Two details of the notation:
- An empty compartment is kept, not collapsed.
Cathas no attributes of its own, and its box still has a (blank) attributes band. It does not drop to a two-part box. - Return types are optional. The same method can be written
+info(): stror bare+info(). The difference means nothing.
UML inheritance diagram
Each subclass inherits from Animal and overrides speak(). Inheritance is drawn as a solid line with a filled triangular arrowhead pointing up into the parent, with orthogonal (right-angle) routing: one stem up from a horizontal bus, and a vertical drop to each child.
Textbook UML draws generalisation with a hollow triangle. CSSE1001 draws it solid filled, on every inheritance arrow. A diagram that matches the textbook does not match the course. Follow the course. See csse1001-diagram-notation.
Figure 42: The inheritance diagram for Animal and its three subclasses. Cat, Dog and Fox each override speak(); Fox also overrides info(). Magenta marks the inheritance relationship, and the purple box in the corner is the legend for its arrow. The arrowhead is filled, the lines run through an orthogonal bus, and Cat’s attribute compartment is kept although it is empty.
Association, multiplicity, composition and aggregation
Four more relationships can be added to the same Animal/Cat/Dog/Fox tree, one at a time. Figure 43 shows the four additions, each drawn in magenta.
Figure 43: The four non-inheritance relationships, each with its name and symbol in purple on the left; multiplicity has a name and no symbol. Association - Cat drinks Milk. Multiplicity - Animal and Vet, 1..* at both ends, labelled Associated. Composition - Animal has exactly one Heart, filled diamond at the Animal end; the dashed filled-head arrow beneath the diamond symbol is a second symbol with no name. Aggregation - an Owner has 0..* Animals, hollow diamond at the Owner end. Each fragment attaches to the Animal/Cat/Dog/Fox inheritance tree of the previous figure, which is unchanged and so is not repeated.
Association
Association — a plain solid line, no arrowhead — represents one class using or knowing about another, without owning it. The example is a Cat that can drink(Milk): Cat gains a +drink(Milk) method, Milk is a class of its own with -expiration: str and +is_fresh(int): bool, and the line between them carries the verb label drinks at one end.
Multiplicity
Multiplicity shows how many objects are involved in a relationship. The vocabulary:
| Multiplicity | Meaning |
|---|---|
0..1 |
Zero to one |
n |
Specific number |
0..* |
Zero to many |
1..* |
One to many |
m..n |
Specific number range |
The example is Animal 1..* —— Associated —— 1..* Vet: an animal can see one or more vets, and a vet treats one or more animals. The counts sit above the line, next to the end they qualify; the verb sits below it.
Composition
Composition (“has a”, filled diamond at the whole end): the “part” cannot exist independently of the “whole”. An Animal has exactly one Heart — 1 at both ends — and the Heart class carries a single attribute -age.
Aggregation
Aggregation (hollow diamond at the whole end) is a weaker form of composition: the “part” can exist independently of the “whole”. An Owner (-name: str, -pets: [], +feed(), +add_pet()) has 0..* Animals, but an Animal exists perfectly well with no owner.
The mnemonic that falls out of the two diagrams: the diamond always sits at the end that owns, and it is filled when destroying the whole destroys the part.
Exercise
Try modelling a UML diagram for the DroneFlight class (from 2025-09-23-composition) and its child DeliveryDrone class (from 2025-09-23-inheritance’s exercise).
A larger example
Real systems combine all of these. The diagram below has thirteen classes, and it is the only whole-system class diagram in the course. Going by the class names (Battlefield, Tank, Player, Enemy, Guard, Patrol), the system is a simplified tank-battle game.
Figure 44: The tank-battle system diagram, with its multiplicities. Dashed arrows are associations/dependencies (WTController to WTView and WTModel; WTModel to Battlefield and Tank; Battlefield to Tile); solid arrows are inheritance. Both heads are solid: the dependency head is a filled concave-backed arrow, the inheritance head the course’s filled triangle. csse1001-diagram-notation describes the dependency head as open. The boxes are single-compartment with pastel fills, not the three-part black boxes above. The fill colours have no stated meaning.
Reading it off the diagram:
- One
WTControlleris associated with oneWTViewand oneWTModel. - One
WTModelis associated with oneBattlefieldand withNTanks. - One
Battlefieldis associated withNTiles, andTileis specialised intoFloor,WallandRock. Tankis specialised intoPlayerandEnemy;Enemyis further specialised intoGuardandPatrol— a three-level chain, which is the multilevel inheritance pattern taught in the very next lecture.
The WTModel/WTView/WTController split is the Model-View-Controller pattern covered in 2025-10-14-model-view-controller. The naming and the direction of the arrows show it: the controller depends on both, and the model depends on neither.
Summary
UML is a visual language used to design and describe software systems. In object-oriented programming, class diagrams are one of the most-used UML tools. They help represent the structure of a system by showing classes, their attributes and methods, and the relationships between them — such as inheritance, association, aggregation, and composition. Using UML before writing code makes it easier to plan, communicate, and maintain software designs effectively.
Next: 2025-10-07-advanced-inheritance (Lecture 10B).
Week 11
Model View Controller
Lecture 11A, 14 October 2025. See csse1001 for course logistics and [mvc] for the full reference on the Model-View-Controller pattern.
Advanced inheritance (recap)
MRO complexity for each inheritance model (see python-inheritance for the full detail):
| Inheritance type | MRO complexity |
|---|---|
| Single | Simple linear order |
| Multilevel | Chain-like resolution |
| Multiple | C3 linearization |
| Hybrid (e.g. diamond) | C3 linearization |
A few extra facts about MRO:
- Every class has an MRO, computed the moment the class is defined (not when it’s first used) — inspect it with
ClassName.mro()orClassName.__mro__. - The MRO is built by the C3 linearization algorithm and depends on the inheritance structure.
- If two base classes define the same attribute/method, whichever appears earlier in the MRO wins.
- Inside a method of an object of type
MyClass, everysuper()call — whether it’s inMyClassitself or in one of its parents/grandparents — refers to the next class onMyClass’s MRO (i.e. the one after the current class, not the next class up from wherever the method happens to be defined).
MVC
The Model-View-Controller (MVC) pattern separates an application into three interconnected components:
- Model: stores the data and business rules of the application; responsible for every state change.
- View: some (usually visual) representation of the data, without altering it.
- Controller: an interface that receives user input (commands), tells the Model what to do, then selects a View to present the result.
There is an asymmetry buried in that third bullet: the Controller is the only component that talks to both of the others. The View is never described as reading from the Model, and the Model is never described as talking to anyone.
Anatomy of MVC
| Layer | Core question | Owns | MUST NOT |
|---|---|---|---|
| Model | What is the data? | Data & rules | print, parse args, call input() |
| View | How is info shown? | Formatting & rendering | change state, validate data |
| Controller | What happens next? | Workflow & commands | store raw data, format output |
Model knows nothing about the outside world.
Unpacked against the Model row of the table, that means no printing, no argument parsing and no reading input — pure data and logic. [mvc] draws the dependency shape it implies.
MVC flow
The flow is a six-step cycle:
- User issues a command.
- Controller parses input and calls the appropriate Model method.
- Model mutates state and returns domain data.
- Controller selects a View and passes the data.
- View formats the data and pushes it to stdout.
- Control returns to the main loop, waiting for the next user action.
The two things easiest to lose from that list are that step 3 hands data back to the Controller — not to the View — and that the View is chosen by the Controller after the Model has already run.
Figure 45: The six-step MVC flow with the todo-list example’s names filled in. Reading down is reading forward in time. Step 3 is dashed because it is a return, not a call: the Model hands its domain data back to the Controller, which only then picks a View. The monospace lines beneath arrows 1, 2, 4 and 5 give the concrete values for the command add Buy groceries: the call to TodoList.add, which returns a Task, and then show_task. Steps 4 and 5 show the pattern, not a trace of the program: [X] Buy groceries is what show_task would print if the Controller called it, which for an add command the code never does.
Why MVC?
- Modularity — swap in new models, views, or controllers without breaking the application.
- Testability — each component can be tested in isolation.
- Separation of concerns — each component has a distinct responsibility.
Exercise: a minimal todo list manager
Implement a minimal todo list manager with MVC design pattern.
The classes are assigned to layers as follows:
Task+TodoList→ Model (domain)TodoView→ View (presentation only)TodoApp+ run-loop → Controller (input parsing & orchestration)
Figure 46: The four exercise classes and the one-way dependencies between them. Each class is a single-compartment box. A dashed line with a small open arrowhead means a class uses another class, with a bare multiplicity at each end. The Controller and Model classes are filled blue and the View class orange. The dashed boundary groups the two Model classes, TodoList and Task, and the three italic names label the layers. Every dependency shown is read off the constructor and method bodies of the listings below.
The direction of every dashed arrow matters. TodoApp knows about TodoList and TodoView; TodoList knows about Task; and TodoView knows about Task too, because show_task(self, task: Task) names the type and reads two of its attributes. Nothing points back the other way — no arrow from TodoView to TodoList, and none from either Model class to the Controller or the View. That one-way shape is the whole point of the Anatomy of MVC table, and it is drawn out in [mvc].
The four listings below are one program, split by layer.
Model
class Task:
def __init__(self, title: str) -> None:
self._title = title
self._done = False
class TodoList:
def __init__(self) -> None:
self._tasks = []
def add(self, title: str) -> Task:
task = Task(title)
self._tasks.append(task)
return task
def all(self) -> list[Task]:
return list(self._tasks)Two details worth noticing. add both mutates state and returns the domain object it created — that return value is step 3 of the flow. And all returns list(self._tasks), a fresh copy rather than the internal list, so a View that iterates it cannot accidentally mutate the Model (see python-lists on aliasing, and python-representation-invariants on why handing out the internal list would be a leak).
View
class TodoView:
def show_task(self, task: Task) -> None:
mark: str = "/" if task._done else "X"
print(f"[{mark}] {task._title}")
def show_list(self, tasks: list[Task]) -> None:
print("\n My Tasks\n--------")
for t in tasks:
self.show_task(t)TodoView is pure presentation: it holds no state at all, and neither method returns anything. show_list delegates per-row formatting to show_task so the row format is defined in exactly one place.
Controller
class TodoApp:
def __init__(self, todo: TodoList, view: TodoView) -> None:
self._todo = todo
self._view = view
def handle(self, command: str) -> None:
parts = command.strip().split(maxsplit=1)
if not parts:
return
cmd: str = parts[0]
if cmd == "add" and len(parts) == 2:
self._todo.add(parts[1])
print("Task added!")
elif cmd == "list":
self._view.show_list(self._todo.all())
else:
print("Commands: add <title>, list, quit")TodoApp is handed its Model and its View in __init__ rather than constructing them — that’s what makes the modularity claim from Why MVC? actually true here; you change the argument at the call site and nothing inside TodoApp changes.
split(maxsplit=1) is what lets a title contain spaces: add Buy groceries splits into exactly ["add", "Buy groceries"], never three parts.
Run loop
app = TodoApp(TodoList(), TodoView())
while True:
user_cmd: str = input("$")
if user_cmd.strip() in ("quit", "exit"):
break
app.handle(user_cmd)$add Work on A2
Task added!
$add buy groceries
Task added!
$list
My Tasks
--------
[X] Work on A2
[X] buy groceriesprint("\n My Tasks\n--------") would actually emit a blank line before My Tasks, and the transcript above does not show one.
Tracing add Buy groceries through the flow (Figure 45):
- User issues
add Buy groceries. - Controller (
TodoApp.handle) parses the input and callsTodoList.add. - Model (
TodoList) mutates state and returns aTask. - Controller selects a View (e.g.
show_task) and passes the data. - View formats the data and pushes it to stdout.
- Control returns to the main loop, waiting for the next command.
Steps 4 and 5 there describe the pattern, not this program: for an add command the Controller calls no View at all — it prints Task added! from inside handle and returns, which is also the first of the three rule-bends below. show_task runs only by way of show_list, on a list command.
Every [X] in the transcript above is correct, if a little misleading at first glance — X just means “not done” here (mark = "/" if task._done else "X"), and nothing in this exercise ever sets _done = True. It’s not a bug, just an unused feature stub left for extension.
Three places the exercise bends its own rules
Read against the Anatomy of MVC table, the listings break its rules in three places. They don’t change the answer to the exercise. They’re worth noticing because the pattern is easier to remember once you’ve seen where a small example fails to honour it.
- The Controller prints.
handlecallsprint("Task added!")andprint("Commands: ...")directly, and the run loop’sinput("$")prompt is written in the Controller layer too. By the table’s own third row a Controller “MUST NOT … format output”. Doing it properly would mean aTodoView.show_messageand routing both strings through it. - The View reaches into the Model’s private attributes.
show_taskreadstask._doneandtask._title, both single-underscore “private by convention” names (python-classes-and-objects). The View is behaving correctly in spirit — it only reads — but aTaskwith public accessors would keep the boundary honest. quitis handled outsidehandle. The help string advertisesquit, buthandlehas no branch for it; the run loop interceptsquit/exitbeforehandleever sees them. Typingquittherefore works, while askinghandleabout it prints the help text.
Summary
- MVC is a pattern, typically used in web/GUI applications.
- Separation of concerns makes code more organised.
- It’s easier to test, maintain, and extend code built this way.
- It provides a solid foundation for future enhancements.
- Numerous variants of MVC exist.
There is no established shape, layout, arrow direction, or colour for an MVC diagram in this course (see csse1001-diagram-notation). Figure 46 uses the course’s class-diagram conventions, apart from the dashed Model boundary and the three layer names. The layout of Figure 45 is not a course convention, and neither is the dependency figure in [mvc]. Don’t reproduce them in an exam answer as though they were the course’s notation.
Week 12
Recursion
See csse1001 for course logistics. This is Lecture 12A. See python-recursion for the full reference on recursion.
What is recursion?
A function that calls itself is a recursive function. This can feel circular — we’re using the function to define the function — but it’s logically sound, and is essentially an implementation/realization of mathematical induction.
Induction is not tested, and does not need to be really understood — it’s just motivation. There are only one or two questions (of forty) on recursion on the exam. Allocate study time accordingly.
Recursion as induction
The Principle of Mathematical Induction (PMI): for any predicate \(P : \mathbb{N} \to \{\texttt{True}, \texttt{False}\}\),
\[(P(0) \text{ \texttt{and} } (P(n) \implies P(\texttt{succ}(n)))) \implies \forall m \in \mathbb{N},\ P(m)\]
In prose: if the proposition is true for zero, and if it being true for \(n\) implies it’s true for the successor of \(n\), then it’s true in general.
Worked example. Proposition: any \(2^n \times 2^n\) board with \(n \in \mathbb{N}\) can be tiled with “corner-tiles” (L-shaped trominoes) so that only one square is left uncovered, and that square can be anywhere. A standard (\(8 \times 8\)) chess board is one such board. The proof of the general claim:
- Base case (\(n=0\)): a \(2^0 \times 2^0 = 1 \times 1\) board is covered with zero tiles — the single square is the uncovered one.
- Induction hypothesis: assume a \(2^n \times 2^n\) board can be tiled this way.
- Induction step: cut a \(2^{n+1} \times 2^{n+1}\) board into four \(2^n \times 2^n\) quadrants. Every quadrant is tiled by the hypothesis. Put the quadrant carrying the board’s intended uncovered square anywhere you like; orient the other three so that their uncovered squares are the three squares that meet at the centre of the board. Those three squares form a corner-tile shape, so one extra tile covers all three — and the board is left with exactly one uncovered square.
Figure 47: The induction step of the tiling proof. Four \(2^n \times 2^n\) quadrants are each tiled by the induction hypothesis; three of them are oriented so their uncovered squares (magenta discs) meet at the centre, where one extra corner-tile covers all three, leaving the fourth quadrant’s disc as the whole board’s only uncovered square. Tile outlines are cyan, the reference grid is grey and dashed, a magenta disc marks an uncovered square, and the dimension lines are cyan.
The shape of that argument — solve four smaller copies of the same problem, then do one unit of work to glue them together — is exactly the shape of a recursive function. See csse1001-diagram-notation for the drawing conventions the figure follows.
Recursion ingredients
Every recursion must have at least one of each:
Base case: a case defined outright.
if base_case: return constantRecursive step: a line where the function calls itself on “smaller” input.
Factorial: the canonical example
\[n! = \begin{cases} 1 & \text{when } n = 0 \\ n \times (n-1)! & \text{otherwise} \end{cases}\]
For instance \(3! = 3 \times 2 \times 1 = 6\).
A set of \(n\) distinct elements can be arranged in \(n!\) different ways.
>>> def fact(n: int) -> int:
... if not n: # Pythonic zero check
... return 1 # base case
... return n * fact(n-1) # inductive case / recursion>>> fact(0)
1
>>> fact(3)
6
>>> fact(-1)
RecursionError: maximum recursion depth exceededfact(-1) never reaches the base case — n just keeps getting more negative. This is called bottoming out.
Winding and unwinding
Figure 48: How factorial(4) evaluates. The winding phase builds up the nested product until the base case factorial(0) is reached (magenta), then unwinding collapses it from the inside out to 24. The magenta braces with italic labels mark the winding and unwinding phases.
During the winding phase each new recursive call pushes an activation record onto a stack, and those records complete last in, first out. The picture above is not a stack: a stack would be drawn in the reverse order — the deepest call (factorial(0)) is the top of the stack, not the bottom of the page.
Once the base case returns, unwinding resolves each pending multiplication from the inside out: \(1 \times 1 \to 2 \times 1 \to 3 \times 2 \to 4 \times 6 \to 24\).
Stack overflow
Python only allows finitely many recursive calls. When you exceed that limit the recursion has overflowed.
Exceeding the limit does not necessarily mean you are bottoming out — an algorithm may legitimately need more stack than Python provides by default:
>>> import sys
>>> sys.setrecursionlimit(1500) # default is 1000Both cases side by side:
>>> fact(998)
402790050127220994538240674597601587306681545756471103647447357787726238...
>>> fact(999)
RecursionError: maximum recursion depth exceeded
>>> import sys
>>> sys.setrecursionlimit(1001)
>>> fact(999)
402387260077093773543702433923003985719374984210714632543799910429938512...
>>> fact(-1)
RecursionError: maximum recursion depth exceeded # bottoming outSo fact(999) was only limited by the default ceiling and works once it is raised, while fact(-1) fails at any limit — that one is a genuine missing-base-case bug.
Finding base cases
To handle non-obvious base cases, consider an example that makes a single recursive call, and ask what the base case must be in order for that example to work. For instance,
\[2^k = 2 \cdot 2^{k-1} = \underbrace{2 \times \cdots \times 2}_{k \text{ many times}}\]
What does “\(0\) many times” mean? We have \(2^1 = 2\) and \(2^1 = 2 \cdot 2^0\), and therefore \(2^0 = 1\).
Recursive functions defined over lists and strings usually have as their base case the empty list and the empty string:
| Type | Base case |
|---|---|
list |
[] |
str |
'' (empty string) |
Advice:
- Ask yourself how you would solve the problem if you could solve the same problem on smaller examples.
- When in doubt, set the base cases to what they need to be in order for the singleton case to work. The singleton case is the second-smallest one.
Worked exercises
Palindrome check
Determine if a string is a palindrome — a word that is equal to its reverse.
The obvious answer:
def is_palindrome(cs: str) -> bool:
return cs == cs[::-1]>>> is_palindrome("racecar")
True
>>> is_palindrome("deified")
True
>>> is_palindrome("squid")
FalseAvoiding the reversal, iteratively:
def is_palindrome(cs: str) -> bool:
for k in range(len(cs)//2):
if cs[k] != cs[-k-1]:
return False
return TrueWith recursion:
def is_palindrome(cs: str) -> bool:
if not cs: # base case
return True
return cs[0] == cs[-1] and is_palindrome(cs[1:-1]) # recursionSentence palindrome (ignoring spacing, casing, punctuation)
The exercise is to fill in the body so that these hold:
>>> def sentence_palindrome(cs: str) -> bool:
... pass
>>> xs = "Al lets Della call Ed 'Stella'."
>>> sentence_palindrome(xs)
True
>>> ys = "Yo, banana boy!"
>>> sentence_palindrome(ys)
TrueOne implementation follows the “strip from whichever end is not a letter, then compare” shape of the plain palindrome above:
def sentence_palindrome(cs: str) -> bool:
if not cs:
return True
if not cs[0].isalpha():
return sentence_palindrome(cs[1:])
if not cs[-1].isalpha():
return sentence_palindrome(cs[:-1])
return cs[0].lower() == cs[-1].lower() and sentence_palindrome(cs[1:-1])Flatten a list
Flatten a list — that is, remove all internal brackets.
>>> flatten([1, [2], [[3,4]], [[5], [6,7,8], 9]])
[1, 2, 3, 4, 5, 6, 7, 8, 9]def flatten(xs: list) -> list[int]:
if not xs:
return xs # base case
if type(xs[0]) is int:
return xs[0:1] + flatten(xs[1:]) # recursion
return flatten(xs[0]) + flatten(xs[1:]) # recursionThere are two different recursive cases: a leading int is peeled off as a one-element slice (so that + still concatenates lists), while a leading list is flattened in its own right before being joined to the flattened rest.
Monotonically increasing
Check if a list of numbers is monotonically increasing.
def increasing(xs: list[int]) -> bool:
if len(xs) <= 1: # base case
return True
return xs[0] < xs[1] and increasing(xs[1:]) # recursionThis is a case where the base case is chosen so the singleton works: a one-element list has nothing to compare, so it must be True, and len(xs) <= 1 covers the empty list too.
Sum of digits
Sum the digits of a number — the sum of the digits of 123 is \(1 + 2 + 3 = 6\).
def sum_of_digits(n: int) -> int:
if not n:
return 0
return (n % 10) + sum_of_digits(n // 10)Sublist sum (tree recursion)
Determine if xs: list[int] has a sublist that sums to some target.
>>> xs = [3, 5, 6, -3, 1, 2]
>>> sublist_sum(xs, 9)
True # [3, 5, 1]
>>> sublist_sum(xs, -1)
True # [-3, 2]def sublist_sum(xs: list[int], target: int) -> bool:
if not xs:
return not target # true only for target == 0
return sublist_sum(xs[1:], target-xs[0]) \
or sublist_sum(xs[1:], target)This creates a tree of recursive calls, as every function invocation triggers two recursive calls — either xs[0] is part of the sublist (so the rest must make up target - xs[0]) or it isn’t (so the rest must still make up target).
Figure 49: The tree of calls generated by sublist_sum([3, 5], 8). Each node is one invocation, labelled by its arguments; the left edge takes xs[0] into the running total, the right edge skips it. Magenta-outlined nodes are base-case calls, which return not target — only the leftmost, with target driven to 0, returns True, and the chain of ors carries that back to the root. The list has two elements to keep the tree small; the six-element list above would need 64 leaves.
Every earlier example (fact, is_palindrome, flatten’s int branch, increasing, sum_of_digits) makes at most one call per invocation and so unwinds along a single chain; this one doubles at every level, so a list of \(n\) elements costs \(2^n\) leaf calls.
Counting grid paths
Standing on a grid at the origin, you can only move along the \(x\) and \(y\) axes by positive increments. How many distinct paths are there to an arbitrary position on the grid?
def num_paths(x_cord: int, y_cord: int) -> int:
"""
How many paths from (0, 0) to x_cord, y_cord when you can
only move in positive direction.
"""
if (x_cord, y_cord) == (0, 0):
return 1
if x_cord < 0 or y_cord < 0:
return 0
return num_paths(x_cord-1, y_cord) \
+ num_paths(x_cord, y_cord-1)Two base cases here: the origin is reached exactly one way, and stepping off the grid contributes nothing. The recursive step is the same “branch on the last choice” idea as sublist_sum — the last move was either horizontal or vertical.
Towers of Hanoi
Move num_disks disks (labelled 1, 2, …, num_disks, with 1 the smallest) from from_peg to to_peg, pegs numbered 0, 1 and 2, moving one disk at a time and never placing a bigger disk on a smaller one:
def hanoi(num_disks: int, from_peg: int,
to_peg: int) -> list[tuple[int]]:
"""Move <num_disks> many disks labelled 1, 2, ..., num_disks
from peg <from_peg> to <to_peg>. Pegs are numbered 0, 1, and 2.
"""
if not num_disks:
return []
off_peg = 3-from_peg-to_peg
return (hanoi(num_disks-1, from_peg, off_peg)
+ [(num_disks, to_peg)]
+ hanoi(num_disks-1, off_peg, to_peg))>>> hanoi(2, 0, 2)
[(1, 1), (2, 2), (1, 2)]The recursive idea: to move \(n\) disks from from_peg to to_peg, first move the top \(n-1\) disks out of the way (to the spare off_peg), move the single bottom disk directly, then move those \(n-1\) disks from the spare peg onto their final destination. The arithmetic trick off_peg = 3 - from_peg - to_peg picks the remaining peg, because \(0 + 1 + 2 = 3\).
See towers-of-hanoi for a formal induction proof that this always works, plus a fully validated 4-disc move trace drawn out board by board.
Tiling exercise (unsolved)
The exercise is to tile a \(2^n \times 2^n\) board with distinct numbered tiles (rather than just proving a tiling exists, as in the induction example above), leaving 0 for the uncovered square:
>>> def tile(n: int) -> list[list[int]]
... pass
>>> tile(2)
[[0, 2, 3, 3],
[2, 2, 1, 3],
[4, 1, 1, 5],
[4, 4, 5, 5]]This is left as an open exercise. A natural recursive approach mirrors the induction proof in Figure 47: tile the four quadrants recursively, then number one more tile for the three squares that meet at the centre.
Longest common subsequence
The string "abc" has eight substrings: "", "a", "b", "c", "ab", "ac", "bc", "abc". Write a function that, given two strings, returns the longest common subsequence of those two strings.
def lcs(xs: str, ys: str) -> str:
"""
>>> lcs("cbfbcdeb", "cbebcee")
'cbbce'
"""
if not xs or not ys:
return ""
if xs[0] == ys[0]:
return xs[0] + lcs(xs[1:], ys[1:])
return max(lcs(xs[1:], ys), lcs(xs, ys[1:]), key=len)Another branching recursion: when the leading characters differ, both “drop a character from xs” and “drop a character from ys” have to be explored and the longer result kept.
Dynamic programming
One problem with recursion is its efficiency with branching recursions. Caching previous results is a strategy that is quite powerful when the branching recursion has many overlapping subproblems — the classic case being naive Fibonacci:
>>> def fib(n: int) -> int:
... """ Return the nth Fibonacci number."""
... if n < 2:
... return 1
... return fib(n-1) + fib(n-2)With caching it is much faster:
fib_cache = {0: 1, 1: 1} # base cases go here
def fib(n: int) -> int:
global fib_cache
if n in fib_cache:
return fib_cache[n]
fib_cache[n] = fib(n-1) + fib(n-2)
return fib_cache[n]The base cases live in the cache dictionary rather than in an if, and the cache lookup at the top is what turns the tree of calls back into something linear.
Summary
- Recursion is a function calling itself, with a base case and a recursive step.
- It’s the programming realization of mathematical induction — the tiling proof and the recursive
tile/hanoifunctions have the same structure. - Evaluation has a winding phase (building up a stack of activation records) and an unwinding phase (resolving them last in, first out).
- Common base cases:
0for numbers,[]/''for lists/strings; pick the base case so that the singleton case works. - Overflowing the stack is not the same bug as bottoming out — raising
sys.setrecursionlimitfixes the first and never fixes the second. - Some recursions branch into a tree of calls rather than a single chain — caching (dynamic programming) can make those tractable.
Next: 2025-10-28-complexity-and-sorting — functional programming and complexity (Week 13).
Towers of Hanoi (Induction & Recursion, Supplementary)
Supplementary material reinforcing 2025-10-20-recursion and python-recursion — a formal induction proof that the Towers of Hanoi puzzle is always solvable, plus a fully validated worked trace.
The boards in the figures use colours that are not in csse1001-diagram-notation: poles and base are tan bars, disks are pink bars (a different pink from the course’s usual magenta), and disk width increases with disk number.
The puzzle
Move one disk at a time. Bigger disks cannot be stacked on smaller disks. Prove the stack can be moved to the last pole.
The proof says pole and the code says peg. The two words mean the same thing here.
The proposition
The proposition is a biconditional with the two rules attached as a numbered list:
\(P(n) \iff\) a stack of \(n\)-disks can be moved to an arbitrary pole while…
- Moving one disk at a time.
- Bigger disks never stacked on smaller disks.
The word arbitrary is doing real work: the claim is not “the stack can be moved to one particular pole”, but “to whichever pole you name”. That is what makes the hypothesis strong enough to be used twice in the step below — once to reach the spare pole, once to reach the target.
Base case
\(P(0) \iff\) zero disks can be moved to an arbitrary pole while …
With zero disks the board is three empty poles. This is a vacuous case: with nothing to move, there is no move that could break either rule, so the conditions hold trivially.
The inductive step
Assume \(P(n-1)\) — that is, suppose we can move \(n-1\) disks to any pole we like, obeying both rules. A stack of \(n\) disks then crosses the board in four states, and therefore \(P(n)\). By the PMI, \(\forall n; P(n)\).
Figure 50: The inductive step as four board states (tan poles and base, pink disks, widths increasing with disk number). Five disks stand in for a general n. The pegs are numbered 0/1/2. The magenta brace names the top n-1 disks and the bottom disk n. The three monospace code fragments are the three terms of the return statement of hanoi, with num_disks shortened to n. Nothing about the puzzle forces the spare pole to be the middle one — that is simply the arrangement drawn here, and it matches hanoi(4, 0, 2).
Written out:
- Base case \(P(0)\): vacuously true — there is nothing to move.
- Inductive step: assume \(P(n-1)\). Then, for a stack of \(n\) disks:
- Move the top \(n-1\) disks onto the spare pole (possible by the inductive hypothesis).
- Move the remaining, largest disk onto the target pole directly. This one move is legal precisely because step 1 uncovered it and emptied the target.
- Move the \(n-1\) disks from the spare pole onto the target pole, on top of the largest disk (again possible by the inductive hypothesis, and legal because every disk in that stack is smaller than the one it lands on).
- Conclusion: by the Principle of Mathematical Induction, \(P(n)\) holds for all \(n\).
This is exactly the recursive structure of the hanoi function in 2025-10-20-recursion: the inductive hypothesis is the recursive call, and the three steps above are the three terms of that function’s single return statement, in order. The proof establishes only that a solution exists; it says nothing about the solution being the shortest one.
Validating the algorithm: four disks
The worked example is the 15-move solution for four disks, replayed one board at a time. The move list in full:
(1,1),(2,2),(1,2),(3,1),(1,0),(2,1),(1,1),(4,2),(1,2),(2,0),(1,0),
(3,2),(1,1),(2,2),(1,2)A move is written (disk, destination_peg). Disks are labelled 1 through n and pegs are labelled 0, 1, and 2. The order inside the pair is that the first entry is the disk and the second is where it lands, and disk 1 is the smallest. Both are fixed by the code, which appends exactly [(num_disks, to_peg)] for each move, and confirmed by reading the boards.
Figure 51: All sixteen board states of the four-disk solution, in reading order. Each panel is captioned with the move that produced it: a small grey move number and the move itself in magenta. The peg numbers are on the first board. Move 8 is in blue — the single move of the largest disk, the pivot of the whole recursion. The two magenta braces name the calls each half of the trace comes from. The split is exact: the eight boards above it are the start state plus the seven moves of hanoi(3, 0, 1), and the eight below are (4,2) followed by the seven moves of hanoi(3, 1, 2).
Grouping the same 15 moves by the structure of Figure 50 — 7 moves to clear disks 1–3 onto the spare peg, 1 move for disk 4, then 7 moves to bring disks 1–3 back on top:
(1,1) (2,2) (1,2) (3,1) (1,0) (2,1) (1,1)
(4,2)
(1,2) (2,0) (1,0) (3,2) (1,1) (2,2) (1,2)That grouping is exactly what hanoi(4, 0, 2) from 2025-10-20-recursion returns, as three concatenated pieces:
>>> hanoi(4, 0, 2)
[(1, 1), (2, 2), (1, 2), (3, 1), (1, 0), (2, 1), (1, 1),
(4, 2),
(1, 2), (2, 0), (1, 0), (3, 2), (1, 1), (2, 2), (1, 2)]Two details worth reading off Figure 51. First, the largest disk moves exactly once (move 8), and once it is placed nothing above it ever needs to shift it again — the pivot the whole proof turns on. Second, the spare peg is not fixed: the outer call uses peg 1 as its spare, but the nested hanoi(3, 0, 1) uses peg 2, which is why disks appear on the target peg long before disk 4 arrives there. That is off_peg = 3 - from_peg - to_peg doing its work at every level.
How many moves
The count falls straight out of the code’s shape: one call to hanoi(n, ...) emits whatever hanoi(n-1, ...) emits, twice, plus one move of its own, and hanoi(0, ...) emits none.
\[T(0) = 0, \qquad T(n) = 2\,T(n-1) + 1 \quad\implies\quad T(n) = 2^{n} - 1\]
So four disks take \(2^4 - 1 = 15\) moves, which is what the trace above shows, and the cost is exponential in the number of disks — see algorithmic-complexity for that vocabulary.
Exercise stub
The implementation is left as an exercise, starting from only the signature and docstring:
def hanoi(n: int, from_peg: int, target_peg: int) -> list[tuple[int, int]]:
"""
Solve towers of hanoi problem for <n> disks from <from_peg> to
<target_peg>
Disks are labelled 1 through n.
Pegs are labelled 0, 1, and 2.
"""2025-10-20-recursion (Lecture 12A) has a complete implementation, with slightly different naming — num_disks/to_peg rather than n/target_peg — and a return annotation of list[tuple[int]] where this stub writes the more accurate list[tuple[int, int]], since each move really is a pair. It also has the off_peg = 3 - from_peg - to_peg trick that picks the spare peg.
Related: MATH1061’s welcome & intro problems previews the same puzzle (and the \(2^n - 1\) minimum move count) as motivation for MATH1061’s own later induction/recursion content — a nice example of the same idea showing up in two different courses.
Week 13
Complexity and Sorting
See csse1001 for course logistics — this note covers the final lecture’s content. It is numbered Lecture 12B but falls on 28 October, in week 13 of the course profile, paired with the functional programming lecture.
Not testable. The week 13 material is marked “None (not testable)” in the course’s own assessment-coverage schedule. Worth reading for its own sake — and it is the payoff to the definitions in 2025-07-29-a-brief-history-of-computing — but not for exam marks.
Two goals
Sorting a list is a single problem with several different solutions. Five of them are below. Working through them has two goals:
- introduce the notion of an algorithm, and
- formalise how algorithms are compared.
This is part of a transition from software engineering to computer science, and it matches the definition from lecture 1A: computer science is the practice/art of creating algorithms and measuring their relative effectiveness.
The traces and trees below use the layout of the sorting figures at runestone.academy: rows of cells, step captions on the right, and grey shading. This layout matches nothing else in the course (see csse1001-diagram-notation).
The grey shading has no single meaning. Each caption below states what it marks in that particular figure.
Five sorts, five restrictions
Each algorithm is derived by imposing a restriction and asking whether sorting is still possible. See sorting-algorithms for the standalone descriptions.
| Restriction | Algorithm |
|---|---|
| Only select the largest element | Selection sort |
| Only place an element correctly into a sorted list | Insertion sort |
| Only swap adjacent cells | Bubble sort |
| Only merge two sorted lists | Merge sort |
| Only split a list in two by a predicate | Quick sort |
Exercise. Implement selection sort, insertion sort, bubble sort and merge sort.
Selection sort
Suppose we could only select (find the index of) the largest element from a list.
Find the largest member of xs and make it the last element; then find the next largest and make it the second last, and so on.
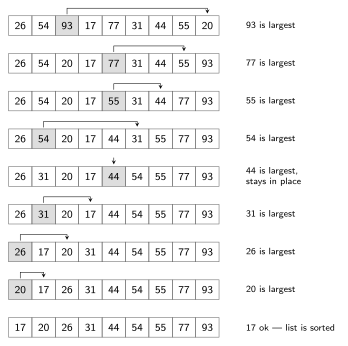
Figure 52: Selection sort on 26 54 93 17 77 31 44 55 20. Time runs downward, one selection per row. The grey cell is the cell being selected on that row: the largest element in the still-unsorted prefix. The arrow above the row shows the long-range swap that sends it to its final position. Each pass shortens the region being searched by one, so the sorted region grows inward from the right — after eight passes the single remaining element (17) is already correct.
Two things the trace makes concrete:
- The invariant is a sorted suffix. Everything at or to the right of each arrowhead is finished and is never touched by a later row; the search region shrinks by one cell per pass.
- A pass whose maximum is already in place still costs a full scan. Row five (“44 is largest, stays in place”) searches the same five-cell region it would have searched anyway and simply performs no swap — selection sort saves nothing from a favourable input.
The starting list differs from every other figure. The selection trace opens on
26 54 93 17 77 31 44 55 20; the insertion, bubble and merge figures all open on54 26 93 17 77 31 44 55 20— the first two elements are transposed. This is a difference between the figures, not a step of the algorithm. Allow for it when comparing the traces row by row.
Insertion sort
Suppose we could only place an element correctly into a sorted list. Could we sort a list?
Sort the list by inserting elements repeatedly into the front of the list. After \(k\) steps the first \(k\) elements of the list will be sorted.
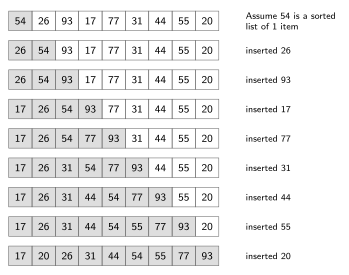
Figure 53: Insertion sort on 54 26 93 17 77 31 44 55 20. Grey marks the sorted prefix, white the untouched tail; each row inserts the leftmost white element into the grey region, so the prefix grows one cell per row. The first row is the base case: a one-element list is already sorted.
Set beside the selection trace, the contrast is the whole point of running both: insertion grows a sorted prefix, selection grows a sorted suffix, and the region insertion has already built keeps being rearranged (inserting 17 shifts three cells right) while selection’s finished suffix is frozen. Insertion also does a variable amount of work per row — inserting 93 costs nothing, inserting 20 shifts seven cells — which is why its behaviour depends on the input in a way selection’s does not.
Bubble sort
Suppose the only operation we could perform on lists was swapping adjacent cells. Could we sort this list?
Pass through the list swapping elements so that larger elements move forward when swapping (for ascending order) — larger elements bubble to the top. Make repeated passes until the list is sorted.
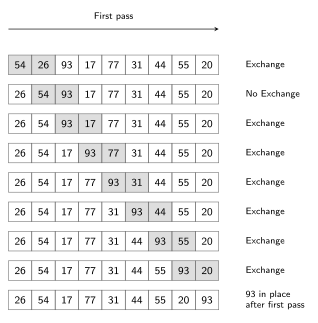
Figure 54: The first pass of bubble sort on 54 26 93 17 77 31 44 55 20. The grey pair is the two adjacent cells being compared on that row; the step caption records whether they were exchanged. The pass makes 8 comparisons and 7 exchanges and ends with 93 — the maximum — parked at the far right. Only the first pass is drawn.
Bubble’s first pass finishes with the maximum where selection’s first pass puts it — parked at the far right — but is only allowed adjacent swaps, so it takes 93 six exchanges to cross the list where selection moved it in one. Only the maximum’s landing place is comparable, mind: the two figures do not start from the same list (see the note above), and everything left of the last cell is in a different order at the end of the two passes. The cost of the restriction is visible directly in the figure: from row three onward 93 steps exactly one cell right per row.
Merge sort
Suppose the only operation we could perform on lists was merging two sorted lists into one sorted list. Could we sort a list?
Break the list in half and sort the halves (using merge sort) then merge these lists. There are two phases: the winding phase, which is the recursive descent, and the unwinding phase, which is the merging on the way back up. This is the winding/unwinding vocabulary from 2025-10-20-recursion.
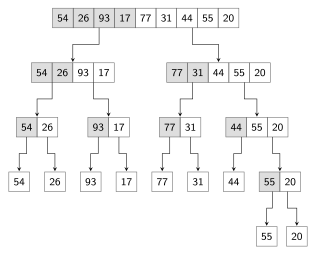
Figure 55: Merge sort winding. The whole list sits at the top and arrows point downward into the two halves of each split; grey marks the left half of every list that is about to be split, so the split point is readable at a glance. Every odd-length row puts the short half first — the nine-element list goes 4/5, not 5/4 — which is why the rightmost branch runs one level deeper than the others.
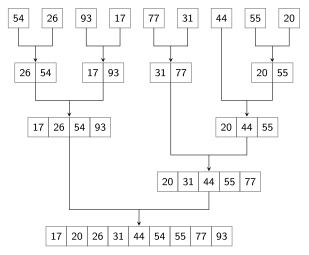
Figure 56: Merge sort unwinding. The singletons are at the top and the sorted list at the bottom; every pair of arrows converges on the merged result. There are two pass-throughs: 44 has no partner at the first merge level and drops straight into 20 44 55, and 31 77 is formed at the first merge level but skips the second, merging only at the third. Both figures use downward arrows — the recursion direction is carried by which end holds the whole list, never by arrow direction.
Read together, the two trees are where merge sort’s better complexity comes from: the winding tree is about \(\log_2 n\) levels deep because each level halves the list, and each level of the unwinding tree touches every element exactly once while merging — depth times work-per-level gives \(n \log n\).
Quick sort
Could we sort a list if all we could do was sort a list into two pieces based on some predicate?
Divide the list into two lists: those bigger than or equal to the head and those less than or equal to the head. Sort those lists and then just connect them.
Which sorting algorithm is best?
Rather than timing, we can count how many times some operations are performed in each sorting algorithm. The operations to count are comparisons and swaps.
Definition (Complexity). We measure the complexity of an algorithm by counting the number of operations performed. However, the number of operations is proportional to the length of the input (usually denoted \(n\)). It is really this proportion we are interested in, rather than a precise accounting of operations.
Big-Oh
Definition (Big-Oh Notation). We say “\(f(n)\) is big-oh of \(g(n)\)” and write \(f(n) = O(g(n))\) when
\[\exists\, c, k \in \mathbb{R}^{>0} : \forall n \geq k;\; 0 \leq f(n) \leq c\,g(n).\]
That is, when there is some positive constant \(c\) such that \(f\) is eventually smaller than \(cg\). Two examples:
- \(2x^2 + x + 1 = O(n^2)\) because for \(x > 2\), \(\;2x^2 + x + 1 < 3x^2\).
- \(x^3 - \sin(x) = O(n^3)\) because for \(x > 1\), \(\;x^3 - \sin(x) \le x^3 + 1 < 2x^3\).
Each example names the witness \(c\) implicitly (3 and 2) and the threshold \(k\) explicitly (2 and 1).
Four worked loops
For each of the four loops below, the complexity of foo comes from counting operations line by line. See algorithmic-complexity for the annotated code of all four.
| Loop shape | Count | Class |
|---|---|---|
while index < n: index += 1 |
\(2n + 2\) | \(O(n)\) Linear |
A while inside a while, both to n |
\(2n^2 + 3n + 1\) | \(O(n^2)\) Quadratic |
while i < 10**10 |
\(2 \cdot 10^{10} + 2\) | \(O(1)\) Constant |
while 2 ** i < n |
\(2\log_2 n + 2\) | \(O(\log n)\) Logarithmic |
The quadratic case is the one that needs its line-by-line working, because it is the only one whose loop lines do not all carry the same count. The other three have two constant assignments and then a matching pair — \(n\) and \(n\), \(10^{10}\) and \(10^{10}\), \(\log_2 n\) and \(\log_2 n\) — whereas this one runs \(n\), \(n \times n\), \(n \times n\), \(n\):
def foo(xs: list[int]):
n = len(xs) # 1
i = 0 # 1
while i < n: # n
j = 0 # n
while j < n: # n * n
j += 1 # n * n
i += 1 # n
# 2n**2 + 3n + 1 = O(n**2)The body of the outer loop runs \(n\) times, and it contains a loop that runs \(n\) times, so the two inner lines each contribute \(n \times n\). Adding the line counts gives \(1 + 1 + n + n + n^2 + n^2 + n = 2n^2 + 3n + 2\), one more than the \(2n^2 + 3n + 1\) in the table and in the last comment. The constant there is off by one. It makes no difference to the class.
The constant case is the one worth pausing on: ten billion iterations is still \(O(1)\), because the count does not depend on n.
Worked: the complexity of each sorting algorithm
Exercise. Find the complexity of each sorting algorithm.
Answer. Insertion, selection, and bubble are \(O(n^2)\) whereas merge-sort is \(O(n \ln n)\).
| Algorithm | Complexity |
|---|---|
| Insertion, selection, bubble | \(O(n^2)\) |
| Merge sort | \(O(n \ln n)\) |
The logarithm here is \(\ln\), not \(\log_2\) — the base is a constant factor and disappears inside the big-oh either way.
Experimental results
Measured times close the argument. All four algorithms are plotted together first. Merge sort is then replotted alone, because on an axis running to 250 seconds it is indistinguishable from the x-axis.
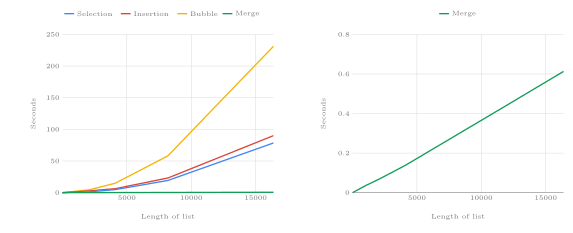
Figure 57: Measured sorting time against list length. Left: all four algorithms on one axis — bubble worst, then insertion, then selection, with merge sort flat on the x-axis. Right: merge sort alone, replotted at roughly 1/300th of the vertical scale. Each quadratic curve roughly quadruples when the list length doubles (bubble 14.9s to 58.2s to 231.2s across n = 4096, 8192, 16384), which is what quadratic growth looks like on a linear axis; merge sort roughly doubles (0.138s to 0.296s to 0.613s). The plotted times and sample lengths are estimates, and the leftmost selection point is interpolated.
At a list of about sixteen thousand elements the separation is roughly 231 s (bubble), 90 s (insertion), 78 s (selection) and 0.6 s (merge) — a factor of nearly 400 between the worst and the best, from algorithm choice alone. The machine, the language and the input used are not known, so take the numbers as one experiment’s shape rather than as a benchmark. This gap is why complexity is worth reasoning about.
The three quadratic sorts also stay within a small constant factor of each other: from about four thousand elements up, bubble runs roughly two and a half times insertion, and insertion a little over selection. The ratio is not fixed all the way down — at the shortest lengths plotted, bubble is under twice insertion — but it is exactly the kind of difference big-oh deliberately throws away. Same class, still very different afternoons.
Previous lecture
2025-10-20-recursion — Lecture 12A. Merge sort and quick sort are both recursive, and the winding/unwinding phases described there are exactly what Figure 55 and Figure 56 show.
Reference material
Algorithmic Complexity (Big-Oh)
An algorithm is an ordered sequence of unambiguous instructions that eventually terminates (see history-of-computing). Once we have more than one algorithm for the same problem, we need a way to say which is better — that measure is complexity.
This is not a side topic bolted on at the end of semester. The entire subject is defined in one sentence:
Computer science is the practice/art of creating algorithms and measuring their relative effectiveness.
First met in lecture 1A. sorting-algorithms is the first half of that sentence; complexity is the second half. The course opens on the definition in week 1 and closes on it in week 13.
Why not just time it?
Timing depends on the machine, the language, what else is running, and the particular input. Instead we count operations. For a sorting algorithm the operations worth counting are comparisons and swaps; more generally we count whatever the algorithm does repeatedly.
The machine matters a great deal. The hardware timeline runs from Konrad Zuse’s Z3 to a current AMD part, and eight of its machines have a quoted speed. Laid on a single logarithmic axis, those speeds are the argument against the stopwatch.
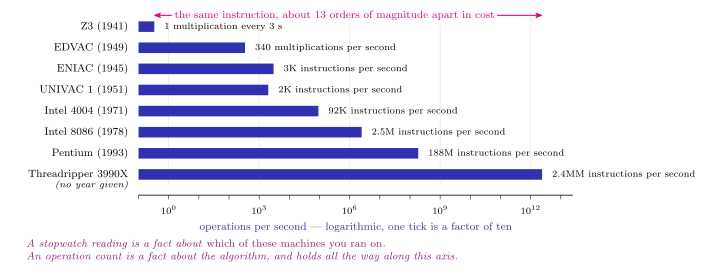
Figure 58: The quoted speeds of the machines in the hardware timeline, on one logarithmic axis. Each bar is one machine. The units are not comparable - Z3 and EDVAC are quoted in multiplications per second and the rest in instructions per second. The rows are not in year order: EDVAC (1949) sits above ENIAC (1945), and the Threadripper has no year. The last figure, 2.4MM, is placed at \(2.4 \times 10^{12}\), reading MM as million-million. The magenta span runs from the slowest machine to the fastest. The full table with prices and manufacturers is in history-of-computing.
Nothing about selection sort changed between 1941 and today. The number of comparisons it makes on a nine-element list is the same on the Z3 as on the Threadripper; only the wall-clock time moves, and it moves by a factor of about \(10^{13}\). That invariant count is what complexity measures.
Definition
We measure the complexity of an algorithm by counting the number of operations performed. But the number of operations is proportional to the length of the input (usually denoted \(n\)) — and it is really this proportion we are interested in, rather than a precise accounting of operations.
That last sentence is the whole idea: 2n + 2 and 5n + 100 are both “linear”, and the difference between them matters far less than the difference between linear and quadratic.
Big-Oh notation
Definition. We say “\(f(n)\) is big-oh of \(g(n)\)”, written \(f(n) = O(g(n))\), when
\[\exists\, c, k \in \mathbb{R}_{>0} : \forall n \geq k,\; 0 \leq f(n) \leq c\,g(n).\]
That is, when there is some positive constant \(c\) such that \(c \cdot g\) is eventually larger than \(f\). The direction matters: “\(f\) is eventually larger than \(cg\)” is backwards and contradicts the inequality.
Worked examples:
- \(2x^2 + x + 1 = O(n^2)\), because for \(x > 2\) we have \(2x^2 + x + 1 < 3x^2\) (take \(c = 3\), \(k = 2\)).
- \(x^3 - \sin(x) = O(n^3)\), because for \(x > 1\) we have \(x^3 - \sin(x) \leq x^3 + 1 < 2x^3\) (take \(c = 2\), \(k = 1\)).
In practice this means: drop the constants and keep only the fastest-growing term.
The four complexity classes in this course
Linear — \(O(n)\)
def linear(xs: list[int]):
n = len(xs) # 1 assignment
index = 0 # 1 assignment
while index < n: # n comparisons
index += 1 # n assignments / additions
# 2n + 2 = O(n) operationsQuadratic — \(O(n^2)\)
A loop nested inside a loop, each running \(n\) times:
def foo(xs: list[int]):
n = len(xs) # 1
i = 0 # 1
while i < n: # n
j = 0 # n
while j < n: # n * n
j += 1 # n * n
i += 1 # n
# 2n**2 + 3n + 1 = O(n**2)Constant — \(O(1)\)
The trap here is that a big number is still a constant: the loop below runs ten billion times, but that count does not depend on n at all.
def foo(xs: list[int]):
n = len(xs) # 1
index = 0 # 1
while i < 10**10: # 10**10
index += 1 # 10**10
# 2*10**10 + 2 = O(1)Logarithmic — \(O(\log n)\)
The loop variable is in an exponent, so the loop runs about \(\log_2 n\) times:
def log(xs: list[int]):
n = len(xs) # 1
index = 0 # 1
while 2 ** i < len(xs): # log[2](n)
i += 1 # log[2](n)
# 2log[2](n) + 2 = O(log(n))Both this listing and the constant one above mix their counter names: each initialises index and then increments i. Neither would run; the operation counts in the comments are still the point.
The base of the logarithm is a constant factor (\(\log_2 n = \log n / \log 2\)), so it disappears inside the big-oh — \(O(\log_2 n)\) and \(O(\log n)\) mean the same thing.
How to read a loop’s complexity
- A loop that advances by a fixed step toward
n→ \(O(n)\). - A loop that multiplies or divides its counter each pass → \(O(\log n)\).
- Nested loops → multiply their counts (\(O(n) \times O(n) = O(n^2)\)).
- A bound that doesn’t mention
n→ \(O(1)\), however large it is. - A bound that is an input value rather than an input length → see the next section, and be careful.
When the input is a value, not a length
Every example above takes n = len(xs): the input is a collection and \(n\) counts its elements. One of the course’s earliest algorithms, integer division from Lecture 1B, does not fit that mould.
Dividing two integers and still getting an integer is grade-school division: for \(x = 17\) and \(y = 3\), 17 ÷ 3 is 5 remainder 2, i.e.
\[17 = 5 \cdot 3 + 2 \qquad\text{or}\qquad \frac{17}{3} = 5 + \frac{2}{3}.\]
Python hands you both halves directly, and the two together reconstruct the input:
>>> 17 // 3
5
>>> 17 % 3
2
>>> 3 * (17 // 3) + (17 % 3)
1717 // 3 is the quotient and 17 % 3 is the remainder. The theorem the two operators rest on:
Division algorithm. Let \(x\) and \(y\) be positive integers. There is a unique quotient \(q\) and unique remainder \(r\) with \(0 \le r < y\) satisfying \(x = q\cdot y + r\).
The remainder can also be computed by hand, subtracting y away until nothing more can be taken (while is not taught until week 4):
>>> def remainder(x: int, y: int) -> int:
... ans = x
... while ans >= y:
... ans = ans - y
... return ans
>>> remainder(17, 7)
3The recursive version (recursion is week 12, python-recursion):
>>> def remainder(x: int, y: int) -> int:
... return x if x < y else remainder(x-y, y)
>>> remainder(17, 7)
3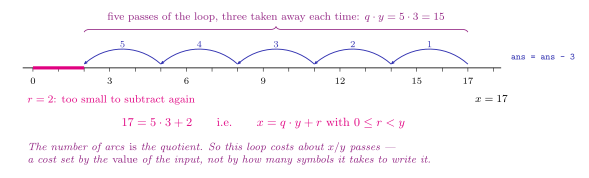
Figure 59: Repeated subtraction for \(17 \div 3\). The number line, the arcs and the count of passes show what the remainder loop does; the equation beneath it is \(17 = 5\cdot 3 + 2\), with the general form \(x = q\cdot y + r\) and \(0 \le r < y\). The code above runs on \((17, 7)\) and the arithmetic on \((17, 3)\); the figure follows the arithmetic.
Now count operations. The loop body runs once per subtraction, and the number of subtractions is exactly \(\lfloor x/y \rfloor\) — the quotient. So remainder(x, y) costs on the order of \(x/y\) operations, and remainder(10**9, 1) would run a billion times while remainder(10, 1) runs ten. The cost is set by the magnitude of the input, not by its length.
That is why complexity is always stated against the size of the input rather than its value. It is also why // and % are worth having: they reach the same two answers without the loop, so the number of subtractions never appears in the running time at all. Whenever you meet a loop whose bound is a number rather than a len, check which of the two kinds you are looking at before naming a complexity class.
Complexity of the sorting algorithms
| Algorithm | Complexity |
|---|---|
| Selection sort | \(O(n^2)\) |
| Insertion sort | \(O(n^2)\) |
| Bubble sort | \(O(n^2)\) |
| Merge sort | \(O(n \ln n)\) |
See sorting-algorithms for how each of these works. Merge sort is written here as \(O(n \ln n)\) — the same class as \(O(n \log n)\), since the base is a constant factor.
Why this matters elsewhere
Complexity is what makes dynamic programming worth doing: a branching recursion like the naive Fibonacci recomputes the same subproblems exponentially many times, and caching collapses that back down to linear. It is also the justification for the dictionary’s “magic” hash function in python-dictionaries — a hash table finds a key in roughly constant time where scanning a list would take linear time.
CSSE1001 Diagram Notation
This note records the drawing conventions CSSE1001 actually uses, inferred from its own lecture slides. It is the reference that later diagrams in this course should be checked against.
There is no written style or notation standard anywhere in the CSSE1001 materials. The course profile lists no prescribed textbook and no drawing guide; the “Learning resources” section points only to the UQ Library, Blackboard and Ed Lessons. Every convention below is inferred from the drawings themselves, not quoted from a rule.
The three exceptions — places where the slides state a rule in words rather than merely demonstrate one — are the naming conventions (see Naming and capitalisation) and the one figure-source note in 12b. Everything else is observation.
How to read the citations
Decks are cited by their lecture code and PDF page number, e.g. 10a p7 = the UML deck, seventh page of the PDF.
Do not cite the printed footer numbers. They are unreliable: 09a runs 1/14 … 4/39, 5/39, 6/14 … 15/14, 16/15 and then ends on a page footed 14/14 that is actually PDF page 17. Several decks have footer totals that disagree with their own length (11a’s last page reads 14/13). PDF page index is the only stable address.
Colours were sampled from the rendered pages, quantised to 16 levels per channel, so hex values are accurate to roughly ±8 per channel.
What I sampled
248 pages read as images, out of 726 across 25 decks — 17 of the 25 decks. Full text was extracted from all 25 decks plus the course profile, and every deck was scanned for embedded raster images, so the unread decks were checked for figures even where I did not read them.
| Deck | Pages read |
|---|---|
| 01a history-of-computing | 22–33 |
| 02a python-memory-model | 4–28 |
| 03a functions | 23–28 |
| 03b sequence-selection-and-iteration | 2–19 |
| 04b non-primitive-data | 2–17 |
| 07a exceptions | 14–21 |
| 07b scope | 5–19 |
| 07c object-oriented-programming | 2–19 |
| 08a dunder-methods | 2–5 |
| 08b representation-invariants | 5–14 |
| 09a composition | 1–17 (all) |
| 09b inheritance | 1–19 (all) |
| 10a uml | 1–14 (all) |
| 10b advanced-inheritance | 1–20 |
| 11a model-view-controller | 1–14 (all) |
| 12a recursion | 2–15 |
| 12b complexity-and-sorting | 2–19 |
Not read as images: 00-welcome, 01b python-as-a-calculator, 02b primitive-data, 04a while-loops, 05a for-loops, 05b comprehensions, 06a string-methods, 06b file-io. An image-extraction scan across all decks found zero embedded raster images in seven of those eight (00-welcome has six photo pages), and they are typeset in the same LaTeX Beamer template as the decks I did sample. So the risk that they hide an unseen diagram idiom is low but not zero — the eight decks above are the blind spot in this note.
The two slide families
Almost every visual inconsistency in this course traces back to one fact: the decks come from two different production pipelines, and many decks mix both on adjacent pages.
LaTeX Beamer family — serif body text (Computer Modern), ruled code listings with line numbers, coloured named block headings, no raster images. Covers 01b, 02a, 02b, 03a, 03b, 04a, 04b, 05a, 05b, 06a, 06b, and most of 07a/07b/12a/12b.
PowerPoint family — sans-serif labels, filled colour boxes, drop shadows, stock photography, dark-theme code screenshots. Every deck carrying Based on slides from Dr. Azadeh Ghari-Neiat on its title page (07a, 07b, 07c, 08a, 08b, 09a, 09b, 10a, 10b, 11a) contains PowerPoint-family pages.
Consistency: this split holds across the whole semester and is the single most useful thing to know before drawing anything for this course.
Colour palette
These five colours carry meaning and recur across many decks. Everything else is decorative.
| Colour | Sampled | Means | Evidence |
|---|---|---|---|
| Dark blue | #3030B0 |
Slide title | 10a p4, p7, p10; 09a p12; 10b p10, p19 |
| Magenta | #E00080 |
Defined term, emphasis, the answer | 10a p4; 02a p6; 12a p2 |
| Purple | #92278F |
Named block heading; margin annotation | 03b p4; 12b p19; 09a p12; 10b p13 |
| Green | #109050 (LaTeX) / #00B050 (PPT) |
A prompt to the student | 02a p5; 03b p11; 10a p12; 11a p8 |
| Red | #F00000 |
Warning / failure path | 12a p10; 07b p13; 04b p14 |
Purple #7030A0 is a different purple. It is used only for the UML legend boxes (10a p7, p8, p10, p11) and for the Warning heading in 07b p6. Do not conflate it with the block-heading purple.
Consistency: the blue/magenta/purple/green assignments hold from week 2 (02a) to week 12 (12b). Red is the least consistent — see Inconsistencies.
Named block headings
LaTeX-family slides open a block with a coloured heading on its own line, no box and no rule.
- Green — a prompt the student is meant to act on:
Question(02a p5, 12b p3, p9, p12),Exercise(03b p11, p14; 12b p5, p8, p11, p15; 09b p17; 10a p12; 11a p8),Example(02a p22, p24, p25),Task(07b p17). - Magenta italic — the resolution:
Answer(02a p6, p7, p8, p9, p23; 12b p18). - Purple — a formal or named block:
Definition (…)(03b p4, p6, p7, p12; 04b p3; 07c p5; 12b p19),Proposition(12a p13),Base Case/Induction Hypothesis(12a p14),Observe(03b p10),Summary/Next(02a p28, 07a p21, 07b p19),Constants(07b p5), and named algorithmsInsertion Sort/Bubble Sort/Merge Sort/Quick Sort(12b p3, p6, p9, p12, p16).
Definition blocks are parenthesised with the term being defined: Definition (Boolean domain), Definition (Predicate), Definition (List), Definition (Complexity).
Consistency: green/magenta/purple hold across at least five decks spanning weeks 2–12. The Warning heading is the exception.
Section divider slides
A section break is a slide bearing one large magenta italic serif word, left-of-centre and high on the page, with a short parenthetical gloss beneath it in small black roman type.
Variables— (Named memory locations.) — 02a p14Sequencing— (Order of instructions matters.) — 02a p21Selection— (Controlling program flow.) — 03b p2Lists— (Mutable Ordered Collections.) — 04b p2Memes— (Recursions through meme examples.) — 12a p3
When a deck runs a numbered series of dividers, they take Roman numerals with a colon, and the series continues across decks:
I: Structure— (Holding named attributes.) — 07c p8II: Methods— (Object scoped functions.) — 07c p15III: Magic— (Overloading built-in functions.) — 08a p5
Consistency: strong — six plain dividers across four decks, plus a three-part numbered series spanning two decks. One divider (08b p11, Exercise) carries no gloss.
Code listings
Code is by far the most frequently drawn thing in this course, and its presentation is a notation in its own right.
Ruled block. A listing is bounded by a horizontal rule above and below, full text width, with no vertical rules and no background fill. Line numbers run in tiny grey type in the left margin. Code is monospace with visible letter-spacing.
REPL vs. file. The two are distinguished by prompts, not by styling:
- A REPL transcript uses a magenta
>>>prompt for the first line of an input and a magenta...for continuation lines; output follows on its own line with no prompt (02a p13, p15–p20; 03b p5, p8, p13, p15–p18; 04b p4–p13; 07b p5–p16; 10b p9, p11, p15, p18). - A file or definition is shown with line numbers but no prompts at all (04b p15, p16, p17; 08b p6, p9, p13, p14; 09a p10–p14).
Colour inside code. Black is the default. Magenta marks the token or line under discussion — class names being introduced (Battery, Camera, Motor, 09a p10, p11), the lines inherited or overridden (10b p10, p13, p17), the assert keyword (08b p6, p9), the constant being referenced (08b p13, p14). Boolean operators are coloured by identity: and in cyan, or in green, held consistently through 03b p9, p10, p11, p14.
Vertical ellipsis. Elided code is a centred ⋮ on its own line (03a p23) or three stacked full stops (07a p15).
Placeholder metasyntax. Things the student must substitute are written in angle brackets in monospace: <code> and ExceptionName_k (07a p15, p16), <object_variable>.<method>(<parameters>) (07c p16), <statement that should be true> (08b p5). Consistency: three decks.
Annotating code
This is the course’s real “diagram” vocabulary — it annotates listings far more often than it draws figures.
Right-margin note. A short purple italic serif phrase, right-aligned, on the same line as the code it comments on. Sampled #92278F in both 09a p12 and 10b p13 — identical colour, three decks apart. (Measured by histogram at 300 dpi. The neighbouring aside on 09a p13 is #92268F, one unit off in green and blue — the same ink to the eye, but the two pages are not bit-identical.)
Examples: inherit from A, override, extend from B from A, Super is B (10b p10, p13, p14, p17, p18); Drone has-a Battery (09a p12); this is the memory location where 42 is stored (02a p13); Note addition happened first (03b p5); ys is an alias of xs, Aliasing relationship broken! (04b p13); a ‘private’ variable, this is called a ‘getter’ (07c p19); unreachable if line 5 errors (07a p14).
Consistency: the strongest single convention in the course — present in 02a, 03b, 04b, 07a, 07b, 07c, 09a, 10b. Weeks 2 through 10.
Boxed token. A thin rectangle drawn around an identifier inside the listing, marking the thing being named. The box colour is not fixed: purple around Point() and self (07c p9, p16), magenta around raise ZeroDivisionError (07a p18), blue around Child and purple around Parent (09b p9). See Inconsistencies.
Brace grouping. A magenta right-brace } spanning consecutive lines, with a magenta italic label beside it — Attributes beside the two self.x = 0 / self.y = 0 lines (07c p9). Single instance.
Pointer arrow. A straight or gently curved arrow from an annotation to the code element it refers to. Magenta in 07c p12 and p16; orange in 09b p12 and p13; blue and purple in 09b p9.
Colour keying. Where an annotation has a coloured box and a coloured arrow and a coloured word in the caption, all three share one colour: on 09b p9 the blue box round Child, the blue arrow, and the word “Child” in the caption are all blue, and Parent is purple throughout. Two instances (09b p9, p12); treat as a good practice rather than a settled rule.
Focus markers. Small green right-pointing triangles in the far-left margin flag the lines the reader should look at (07b p7, p12). Two instances, one deck.
Scope boxes
The clearest original notation in the course, in 07b.
A rounded rectangle drawn over a span of code lines delimits a scope, and its colour names the scope kind:
- Purple outline, no fill — global scope; encloses the whole snippet (07b p7, p12).
- Blue outline, pale blue fill — local/function scope; encloses the
defbody only (07b p7, p9, p12).
Nesting is literal: on 07b p7 and p12 the blue local box sits inside the purple global box.
Each box is paired with a short horizontal arrow leading out to a colour-matched label — purple arrow to purple global variable, blue arrow to blue local variable (07b p7, p8, p9, p12).
Consistency: four pages of one deck, entirely self-consistent. Never reused elsewhere in the semester.
UML class diagrams
The formal UML vocabulary is taught in 10a and reused once in 10b p19.
Class box. A black-outlined rectangle in three compartments, separated by full-width horizontal rules: name (centred, serif) / attributes / methods (both left-aligned). 10a p6 states the rule in words and shows it twice.
Visibility prefixes. Stated explicitly on 10a p6: - private, + public, # protected. Applied consistently on 10a p7–p11: #name: str, -breed: str, +speak().
Attribute typing. name: type with a Python type — #age: int, -nationality: str, -pets: [] (10a p6, p9, p11). Methods show a return type only sometimes: +info(): str (10a p6) but bare +info() (10a p7–p11).
Empty compartments are kept. Cat on 10a p8–p11 keeps a visibly empty attributes compartment rather than collapsing to two compartments.
Single-compartment boxes are acceptable when only structure is being shown — 10a p4 and 10b p19 draw name-only boxes.
Relationship symbols
| Relationship | Symbol | Evidence |
|---|---|---|
| Inheritance | Solid line, solid filled triangular arrowhead, pointing up into the parent | 10a p4, p7–p11; 10b p19 |
| Association | Plain solid line, no head, optional verb label at one end | 10a p8 (drinks), p9 (Associated) |
| Composition | Solid line, filled diamond at the “whole” end | 10a p10 |
| Aggregation | Solid line, hollow (white-filled) diamond at the “whole” end | 10a p11 |
Standard UML draws generalisation as a hollow triangle. This course draws it solid filled, verified at 600 dpi on 10a p7 and again on 10b p19. Every inheritance arrow in the course is filled. If you conform to standard UML you will not match the slides; if you match the slides you will not match standard UML. Follow the course.
Line routing is orthogonal. All relationship lines use right-angle elbows, never diagonals (10a p8–p11). A parent with several children gets a single vertical stem down from the parent to a horizontal bus, with vertical drops to each child (10a p4, p7–p11; 10b p19).
Layout and flow. Parent above, children in a row beneath. A grandchild hangs directly below its own parent with its own vertical arrow (10b p19: C below B). Associated non-hierarchy classes sit to the side at the same height as the class they attach to (10a p9 Vet, p10 Heart, p11 Owner).
Multiplicity. Placed above the line, adjacent to the end it qualifies, in magenta — 1..* at both ends (10a p9), 1 and 1 (10a p10), 0..* (10a p11). 10a p9 gives the vocabulary in a legend box: 0..1 zero to one, n specific number, 0..* zero to many, 1..* one to many, m..n specific range.
Magenta marks the relationship being taught. On each of 10a p7–p11 the relationship introduced on that slide is drawn in magenta while previously-established structure reverts to black. On p7 the inheritance tree is magenta; by p8 it is black and the new association line is magenta. Consistency: holds on all five relationship slides — a deliberate, reusable device.
Legend box. A rounded rectangle with a purple #7030A0 outline, containing the relationship name in purple and the bare symbol drawn beneath it, parked in the top-left corner (10a p7 Inheritance, p8 Association, p10 Composition, p11 Aggregation). The multiplicity legend on 10a p9 uses the same box for a text list instead of a symbol.
Non-UML class and object diagrams
Before UML is taught in week 10, the course draws classes at least four other ways. These are not variants of one style — they are four unrelated idioms.
(a) Uniform blue hierarchy — flat steel-blue #4F81BD filled rectangles, white sans-serif labels, parent above and children in a row, joined by a #3D6696 orthogonal bracket with no arrowhead at all — a darker shade of the box fill, not black, though it reads as black at slide size. Photos of instances sit below each child. (09b p2, p3)
(b) Multi-colour hierarchy — parent box black with white text; each child a different Office-palette fill — and these are the stock Office 2007 accents exactly, which is why they recur: #C0504D brick red, #4BACC6 teal, #F79646 orange, #215968 dark teal, olive. Connectors are thin #4A7EBB straight lines — diagonal from the outer children, vertical from the one directly beneath — and each ends in its own arrowhead. On 09b p5 three arrowheads overlap on Animal’s bottom edge; at slide size they read as one, but there are three. (09b p4, p5, p6)
Black for the root holds in all three of these diagrams (Employee, Animal, Person). The child colours carry no meaning I can find — Dog stays teal on 09b p5 even though it is itself a parent.
(c) Attributes-over-methods box — the class name in purple bold sans-serif above two stacked magenta-outlined boxes: attributes on top, methods beneath, with a photo of an instance alongside. (07c p6, three times: Dog, Student, Smartphone)
(d) Attributes-left / methods-right — the class in a black-outlined box in the centre with its name in black and (class) beneath in magenta; a purple-outlined attributes box to the left and a magenta-outlined methods box to the right, each with a plain black label above it. Instances are photographs below, reached by straight black downward arrows with solid heads. (08a p2)
08a p2 draws class → instance as a downward arrow. Every inheritance arrow in the course points up to the parent. The two are never shown on the same page, so the contrast is safe — but keep it.
(e) Containment (“has-a”) boxes — composition is drawn as nesting, not as a line. A large steel-blue #4080B0 filled rectangle is the whole, labelled in large white text at its right edge (car, drone); a smaller brick-red #C05040 rounded rectangle sits inside it and is the part, labelled in white at its top with its methods listed beneath (engine / stop() / start()). (09a p6, p16)
Substitution is shown by stacking two such figures and joining them with a thick curved orange #F79646 arrow from the old configuration to the new (09a p16, “Hot-Swapping”).
Consistency: (e) holds twice in one deck and is the course’s only purpose-built composition picture. (a)–(d) are one or two pages each.
The large worked example
10a p13 — the only whole-system class diagram in the course — is drawn in a completely different style from the rest of 10a:
- Single-compartment boxes, name only, pastel fills with matching darker strokes.
- Sampled fills
#D0E0F0blue /#D0E0D0green /#F0E0C0orange, with strokes#6080B0/#80B060/#D09000. These are the draw.io / diagrams.net default shape colours, matched exactly — this figure was built in draw.io with stock styling, not drawn to match the deck. - Dashed lines with small open arrowheads for association/dependency (
WTController→WTView,WTModel→Tank), solid lines with the usual filled triangle for inheritance. - Tiny
1/Nmultiplicities at the line ends. - Green fill appears on
Tank,TileandEnemy— the three classes that have subclasses. This is my inference from one figure, andBattlefield(blue, no subclasses) is consistent with it whileWTView(orange, alone) is not explained. Do not rely on it.
Reference and memory diagrams
The course does not draw its own reference diagrams. It uses Python Tutor.
pythontutor.com output is embedded as a screenshot in 07b p7, p12 and 07c p13, p14, and named as a live-demo cue five times in 02a (p22, p24, p25, p26, p27, captioned Python Tutor 1. through Python Tutor 5.).
The Python Tutor rendering, as it appears in those screenshots:
- Two columns under bold headers
Frames(left) andObjects(right). - A frame is a pale blue box with a bold title (
Global frame) and one row per name; each row isnameright-aligned against a value cell. - An object is a pale yellow box with a small red-brown type caption floating above it —
Point class,Point instance,function. - An attribute inside an instance is a two-cell row: grey name cell, white value cell.
- A reference is a curved blue-grey arrow from a frame slot to the object.
- Aliasing is shown by two arrows converging on one object (07c p14), versus two arrows to two separate objects for equal-but-distinct values (07c p13).
Consistency: two decks, four screenshots, plus five named references in a third deck spanning week 2 to week 7. Treat Python Tutor as this course’s canonical memory picture.
Bit and memory notation
Established in 02a and legended explicitly on p4.
- A bit is a square cell. Filled black = on/1. White with a black outline = off/0. 02a p4 draws the two side by side and labels them
OnandOff. - Held on 02a p6, p7, p8, p9, p10, p11, p12 — seven further pages.
- A bit string is a horizontal row of contiguous squares, read left to right, with
. . .after the last cell for continuation (02a p10, p11). - Memory is rows of words stacked vertically, each row prefixed in the left margin by its address as a small decimal number (02a p12: 381–388).
- Enumerating all n-bit patterns stacks one row per pattern (02a p7, p8, p9).
Consistency: very strong within 02a. Never used again — no later deck draws a bit.
Data-structure and algorithm-trace diagrams
12b p2: “Note: The diagrams from today’s lecture are taken from runestone.academy.”
This is the closest thing CSSE1001 has to a textbook lineage, and it governs every sorting and merge-tree figure in 12b (p4, p7, p10, p13, p14). Those figures are Runestone Academy’s, not the lecturer’s, which is why their visual language matches nothing else in the course.
List cells. A list is a horizontal row of adjacent square cells with a thin grey border and a soft drop shadow, one integer per cell in small sans-serif, centred. (12b p4, p7, p10, p13, p14)
Shading marks state. White = untouched; grey fills mark the cells the current step is acting on or the region already sorted. The exact meaning of each grey level is never legended — see Not established.
A trace runs top to bottom. Each row is one step; time advances downward. (12b p4, p7, p10)
Step captions sit to the right of each row, small black sans-serif, in the present tense of what just happened: 93 is largest, inserted 26, Exchange / No Exchange, 91 in place after first pass. (12b p4, p7, p10)
Movement arrows are thin black orthogonal arrows drawn above the row, running from source cell to destination cell (12b p4). A whole pass gets a long labelled arrow spanning the figure above everything else — First pass (12b p10).
Recursion trees (merge sort, 12b p13–p14) are drawn as binary trees of list-rows:
Merge Sort – Winding(p13): the full list at the top, splitting downward, arrows pointing down from a list to its two halves.Merge Sort – Unwinding(p14): the singletons at the top, arrows pointing down into each merged result, ending in the sorted list at the bottom.
Both use downward arrows. The recursion direction is carried by the slide title and by which end of the tree holds the whole list — not by arrow direction. This is easy to get wrong.
Mathematical and logical notation
Truth tables (03b p6, p7). A 3×3 grid with visible black rules; the operator name sits in the top-left cell in cyan monospace (and, or); the header row and header column carry the operand values in black monospace; a double rule separates the headers from the body. The one semantically interesting result is coloured magenta — the single True for and (p6), the single False for or (p7).
Function signatures are given above the table, centred, mixing monospace names with maths: and : 𝔹 × 𝔹 → 𝔹. Also > : ℤ × ℤ → 𝔹 (03b p5) and P : ℕ → {True, False} (12a p11).
Blackboard bold for domains — 𝔹 booleans (03b p4, p5, p6, p7), ℤ integers (03b p5), ℕ naturals (12a p11, p13). 𝔹 = {True, False} is defined with the Python literals inside the set, in monospace (03b p4).
Python literals stay in monospace inside maths. True and False are never italicised into maths variables.
Implication and quantifiers use ⟹ and ∀: (P(0) and (P(n) ⟹ P(succ(n)))) ⟹ ∀m ∈ ℕ, P(m) (12a p11). Note and stays as the Python keyword in monospace even inside a mathematical statement.
Contradiction is ⇒⇐ (02a p20).
Displayed maths is centred on its own line, in magenta when it is the point being made (02a p20, 12a p11).
Arrow chains stand in for flow diagrams. Simple pipelines are written inline as text with → rather than drawn: state change → _check_invariants → valid (08b p8), parent → child → grandchild (10b p12), Task + TodoList → Model (domain) (11a p8). Consistency: three decks. This is why the course has so few real flow diagrams.
Geometric and proof figures
The chessboard-tiling figures for the induction proof (12a p12, p14, p15):
- The construction is drawn in cyan solid lines.
- The underlying reference grid is grey dashed.
- The distinguished (uncovered) square is a filled magenta disc.
- Dimensions are annotated with cyan extension lines outside the figure, labelled in black serif maths (
2ⁿ,2ⁿ⁺¹), placed below and to the right.
Consistency: three pages, one deck, entirely self-consistent.
The one flow diagram
07a p17 is the only control-flow diagram in the 726 pages. It shows try/except/else/finally:
- Nodes are rounded rectangles with a hand-drawn, wobbly grey stroke (a sketch/xkcd style).
- The node label is the bare Python keyword in monospace, coloured per keyword:
tryteal,exceptmagenta,elseblue,finallypurple. finallyis drawn with a dashed sketchy border; the other three are solid.- Flow runs top to bottom, with curved grey arrows looping out to the left.
- Edge captions are bold sans-serif, placed below the arrow they describe: Run the code under try, Execute the code under except when there is an exception, No exceptions? run the code under else after try, Always run this code.
- Status glyphs sit outside the flow: a purple circled ✗ beside the try→except path, a green circled ✓ beside the try→else path, a blue circled i beside
finally.
This is a single instance. It does not establish a general flowchart convention for the course — see Not established.
The LEGB diagram
07b p13 draws name resolution as a vertical cascade:
- Four levels listed top to bottom, each with its initial letter bold — Local, Enclosing, Global, Built-in.
- Between consecutive levels, a large red hook arrow with the small red caption
If not foundto its left. - The cascade terminates in bold red
Error!.
Red marks the failure path. Single instance.
Naming and capitalisation
The three rules the course states in words, not just in examples:
| Kind | Rule | Evidence |
|---|---|---|
| Variables, functions | lowercase, words separated by underscores — descriptive_variable_name |
03a p25 |
| Classes | CamelCaps — “That is ClassNamesAreLikeThis” |
07c p7 |
| Constants | SNAKE_CASE_CAPS |
07b p5 |
03a p24 states the course follows Google’s PEP, “a variant of PEP8”, with both linked as lavender rounded chips. 03a p26: lines must be strictly less than 80 characters.
These rules govern labels in diagrams too. UML boxes use CamelCaps class names (DeliveryRobot, WTController, DroneFlight) and snake_case members (_check_invariants(), has_solar_panels, battery_level) throughout 10a, 10b, 07c and 08a.
Do/don’t pairs. Compared alternatives go in a two-column table headed Yes and No in magenta italic, with a single rule under the headers and no other lines — good on the left, bad on the right (03a p25, p28). The variant form labels two separate ruled listings Not helpful / Helpful in magenta italic (03a p27). Inside dark-theme code screenshots the same judgement is made with an all-caps comment — # BAD! / # GOOD! (08b p7).
Figure sourcing and attribution
No textbook is cited as a figure source anywhere. A full-text search of all 25 decks and the course profile for textbook, figure-source and adaptation language returns only the four items below. The course profile prescribes no textbook at all.
| Attribution | Where | Scope |
|---|---|---|
Based on slides from Dr. Azadeh Ghari-Neiat |
Title page of 07a, 07b, 07c, 08a, 08b, 09a, 09b, 10a, 10b, 11a | Slide lineage, not figure lineage |
Based on slides from Dr. Azadeh Ghari-Neiat and Dr. Paul Vrbik |
07b title page | as above |
Note: The diagrams from today's lecture are taken from runestone.academy. |
12b p2 | All sorting figures in 12b |
Image source: www.freepik.com |
09a p9 | That slide’s stock art |
Images are from WIRED |
09b p2, p3 | Those slides’ photos |
Inspired by the example of MIT6.100L slide. |
07c p10 | The blueprint/house analogy — an idea, not a figure family |
Placement. Credits are set in tiny centred or bottom-right roman type beneath the figure (09a p9, 07c p10) or in the bottom-right corner of the slide (09b p2, p3).
10b p9 refers to “the course notes” as the source of a code snippet — the course has its own written notes (delivered via Ed Lessons) which are not among these materials and may carry conventions this note cannot see.
Page furniture
- Slide titles: dark blue
#3030B0, serif, upper-left, sentence case with title-case content words.Optional Content:is used as a prefix for non-examinable material (10b p5). - Footer:
n / Nin tiny grey at the bottom-right. Unreliable — see How to read the citations. - Title slide: course code and title in blue, lecture number and name in magenta italic, lecturer, date, then the attribution line. (10a p1, 09a p1, 09b p1, 10b p1, 11a p1)
- QR-code slides: a large centred QR code with the URL in small serif beneath, flanked by decorative 3D clip art, no title (07a p19, 07b p18, 09b p19).
Inconsistencies
Places where the course does the same thing more than one way. Both readings are recorded; a decision is needed before drawing.
1. Two entirely different UML idioms inside one deck
10a p4–p11 draws three-compartment black-outlined class boxes with magenta relationship lines, orthogonal routing and no fills. 10a p13 draws single-compartment pastel-filled draw.io boxes with dashed dependency arrows. Same deck, same lecture, same subject. 10b p19 adds a third variant: single-compartment boxes with navy #103040 outlines. Decide: compartments or not, fills or not, box outline colour.
2. Class boxes are drawn four incompatible ways before week 10
Three-compartment black box (10a p6); attributes-box-above-methods-box with the name outside and magenta outlines (07c p6); attributes-left/methods-right around a central black name box (08a p2); plain filled rectangle with name only (09b p2, p4). Decide which is canonical for pre-UML material.
3. Inheritance connectors: three styles
Orthogonal bracket with no arrowhead (09b p2, p3); straight blue lines each with its own arrowhead, overlapping at the parent (09b p4, p5, p6); orthogonal bracket with a filled triangular arrowhead (10a p4, p7–p11; 10b p19). Decide.
4. Hierarchy box colour: uniform vs. per-child
09b p2/p3 fill every box the same steel blue. 09b p4/p5/p6 make the root black and give each child its own colour. The two appear two pages apart. And 10a p13 uses a third scheme where colour may track “has subclasses”. Decide whether fill colour means anything at all.
5. Warning heading: red or purple
Red #F00000 in 12a p10 and 04b p14. Purple #7030A0 in 07b p6. Decide.
6. Two greens for the same role
Question / Exercise / Example / Task are #109050 in the LaTeX decks (02a p5, 03b p11) but #00B050 in the PowerPoint ones (10a p12, 11a p8). Same meaning, two hexes. Additionally 01a p25 sets Question in a magenta/crimson rather than either green (observed visually; my colour sample of that page missed the heading). Decide one green.
7. Boxed-token highlight colour is unfixed
Purple (07c p9, p16), magenta (07a p18), blue-and-purple keyed to two referents (09b p9). Decide.
8. Three code presentations
Ruled + line-numbered LaTeX listings (most decks); dark-theme screenshots of an IDE (09b p8–p13, p16; 10b p2, p4, p5; 08b p7); and plain unruled, unnumbered monospace (07a p16, p20). 09b switches between the first two within a single deck. Decide.
9. Summary styling
Purple block heading (02a p28, 07a p21, 07b p19); blue slide title (10a p14, 11a p14); magenta (09b p18). Decide.
10. Image credits are given inconsistently
09a p9 and 09b p2/p3 credit their stock photography. 01a p23–p29 (Ada Lovelace, Grace Hopper, the Jacquard loom, punch cards, the first computer bug), 07c p6/p10, 08a p2/p4 and 12a p4–p9 (the meme sequence) credit nothing. Decide a credit policy.
11. Bit-string reading order
02a p7–p9 enumerate n-bit patterns by toggling the leftmost cell fastest (off-off, on-off, off-on, on-on), which reads the leftmost cell as least significant. 02a p11 then interprets a word as 1·2³² + 1·2³¹ + … + 1·2⁰, reading the leftmost cell as most significant. If you draw a numbered bit string, decide which end is the high bit.
12. Exercise as heading vs. divider
A green block heading in 03b p11, 12b p5, 09b p17, 10a p12, 11a p8 — but a full magenta italic divider slide in 08b p11. Decide.
Not established by the source
Conventions a diagram in this course will plausibly need, that the materials simply do not settle. This is where the risk of invention lies.
No general flowchart convention. The only flow diagram in 726 pages is 07a p17’s sketch-style try/except figure. There is no established shape vocabulary (no decision diamond, no terminator, no process box), no arrow style, and no rule for labelling branches. If you need a flowchart, you are inventing one. Note that the course’s habit is to write flow as an inline → chain (08b p8, 10b p12, 11a p8) rather than draw it — consider doing that instead.
No MVC diagram. The entire MVC deck (11a, 14 pages) contains no architecture diagram. The Model/View/Controller relationship is given as a six-item numbered list (11a p6, p13) and a four-column table (11a p5). The only place the three appear as boxes is 10a p13, where they are three unremarkable draw.io rectangles among thirteen. There is no established shape, layout, arrow direction, or colour for an MVC diagram in this course.
No hand-drawn reference or memory diagram. The course never draws its own variable/object box-and-arrow picture — it screenshots Python Tutor (07b p7/p12, 07c p13/p14). If you need a reference diagram that Python Tutor cannot produce, there is no house style to follow.
No list or aliasing diagram. 04b (non-primitive data, 45 pages) teaches aliasing, copying and pass-by-reference entirely through REPL transcripts — mutating ys and observing xs change (p10, p12, p13). Not one box-and-arrow picture of a list. The idea of “two names, one list” is never drawn outside Python Tutor.
Grey-level semantics in the sorting traces are never legended. 12b p4, p7, p10 use at least three shades — white, light grey, darker grey — and no slide says which is “being compared”, which is “sorted”, and which is “just moved”. Since these figures are Runestone’s, the course has no stated rule to appeal to.
No stated meaning for fill colour in class boxes. 09b p5’s brick red, teal and orange appear decorative; 10a p13’s green may mark classes with subclasses but this is one figure and WTView’s orange contradicts any simple reading. There is no colour key anywhere.
No convention for showing a method body, call stack, or sequence of calls. Despite 12a (recursion, 47 pages) there is no call-tree or stack-frame diagram of the course’s own making — recursion is taught with memes (p4–p9), induction on chessboards (p12–p15) and code. No UML sequence diagram, activity diagram, state diagram or object diagram appears anywhere in the course.
No rule for typing method returns in UML. 10a p6 writes +info(): str; 10a p7–p11 write +info(). Both are the same method on the same class in the same deck.
No hex values are ever published. Every colour in this note was sampled from the rendered PDFs. The course states no palette, so a redrawn figure matching these hexes matches the slides by measurement, not by declaration.
Abstract classes have no notation. 10b p3–p5 teaches abstract base classes in prose and code only. UML’s italic-name convention for abstract classes is never used; Shape is never drawn.
Line weights, font sizes and box dimensions are never specified, and vary between the two slide families.
The eight unread decks. 00-welcome, 01b, 02b, 04a, 05a, 05b, 06a, 06b were not read as images. They contain no embedded raster images (except 00-welcome’s six photo pages) and are in the LaTeX family, so they are unlikely to hide a new idiom — but this note cannot rule it out.
The written course notes. 10b p9 cites “the course notes” as a source. Those notes are delivered through Ed Lessons and are not part of these materials. If they contain diagrams, they may establish conventions that contradict this note.
See also
- 2025-10-07-uml — Lecture 10A’s content
- uml — the UML reference note
- python-pep8-style-guide — the naming rules cited above
- csse1001 — course index
History of Computing and Foundational Definitions
The course’s opening definitions — what a computer, software, an algorithm, computer science, and software engineering actually are — come with their history. Each is a tentative “perhaps…”, not a formal claim. First met in 2025-07-29-a-brief-history-of-computing.
What is a computer?
A computer is a machine that can carry out sequences of arithmetic or logical operations automatically.
Before it was a machine it was a job title: the Harvard “Computers” of the 1800s were people employed to perform calculations by hand. A photograph of the group shows only women.
The formal definition
A finite state machine is a machine that can change state when given input. A Turing Machine is a finite state machine that additionally has (infinite) read/write memory called tape.
A Turing Machine is a general purpose computer — a single machine that can be programmed to do different tasks, rather than a machine built to do one thing. (Pursued properly in COMP2048, Theory of Computing.)
Alan Turing (1912–1954) gave this formal definition of a computer and of what it means for something to be computable — and in particular demonstrated that there are problems which are not computable. He also played a critical role in breaking the Enigma machine.
A Turing machine that adds two binary numbers makes “changes state when given input” concrete.
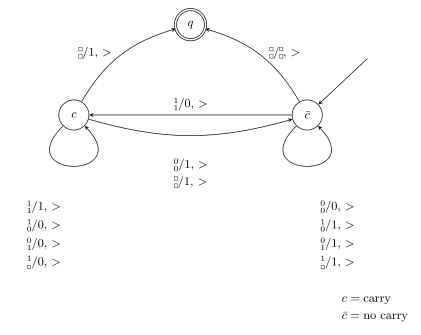
Figure 60: A Turing machine for binary addition. Three states: \(q\), \(c\) = carry and \(\bar c\) = no carry. Every transition is read as what is on the tape / what gets written, which way the head moves: the stacked pair is one bit from each of the two numbers being added, the empty square is a blank cell, and > is a step to the right. The label format, the incoming arrow as the start state, and the double circle on \(q\) as a halting state follow the standard finite-automaton conventions. The transition on a pair of blanks writing 1 appears twice, on both \(c \to q\) and \(c \to \bar c\). The topic belongs to COMP2048.
The labels read as arithmetic. From \(\bar c\), no carry is pending, so \(1 + 1\) writes 0 and moves to \(c\). From \(c\) a carry is pending, so \(1 + 1\) writes 1 and stays in \(c\), while \(0 + 0\) writes 1 and drops back to \(\bar c\). Run off the end of both numbers with a carry still pending and the machine writes the final 1; run off the end without one and it halts leaving the tape alone. It is school-book column addition with the carry held in the state instead of in memory. Two states suffice because a carry is one bit. That is what makes it a usable illustration of “changes state when given input”.
Charles Babbage (1791–1871), an English mathematician, drew the schematics (1840) for the first general purpose computer — the Analytical Engine. It was never built in his lifetime; hardware following the design was assembled in 1910 as a calculator for addition, subtraction, multiplication and division.
The hardware timeline
| Year | Machine | Notes |
|---|---|---|
| 1941 | Z3 | First general purpose computer. Germany, Konrad Zuse. 1 multiplication every 3 seconds. |
| 1945 | ENIAC | Electronic Numerical Integrator and Computer. U. Pennsylvania. $7.3M. 3K instructions/sec. |
| 1949 | EDVAC | Electronic Discrete Variable Automatic Computer. Ballistic Research Laboratory. $1.4M. 340 multiplications/sec. |
| 1951 | UNIVAC 1 | Universal Automatic Computer. Designed for business and admin. $1.8–14M. 2K instructions/sec. |
| 1958 | First integrated circuit | Jack Kilby (Nobel Prize in Physics) — a collection of electronic components fabricated onto silicon. |
| 1962 | UQ’s GE-225 | Installed in the Hawken Building (now the Prentice Centre). Weighed 900kg. |
| 1971 | Intel 4004 | Large scale integration. First commercially produced microprocessor. 92K instructions/sec. |
| 1978 | Intel 8086 | Very large scale integration. 2.5M instructions/sec. |
| 1993 | Pentium | Intel. $1.7K. 188M instructions/sec. |
| — | AMD Ryzen Threadripper 3990x | Ultra large scale integration. $4K. 2.4MM instructions/sec. |
The through-line is integration: a collection of components fabricated onto silicon (1958) → large scale (1971) → very large scale (1978) → ultra large scale (Threadripper).
The speed figures are not in comparable units. Z3 and EDVAC are quoted in multiplications per second, everything else in instructions per second. This is a trend, not a benchmark.
What is software?
Software is the complement of hardware. They are instructions for the machine.
Ada Lovelace (1815–1852), English mathematician and only child of the poet Lord Byron, described an algorithm for the Analytical Engine to compute Bernoulli numbers — she is considered the first computer programmer.
Grace Hopper (1906–1992), a United States Navy rear admiral, pioneered machine independent programming based on English words and invented COBOL. She has both a guided-missile destroyer and a supercomputer named after her.
The “first computer bug” is a moth taped into a 1947 logbook page. The entry, at 15:45 on 9 September, reads:
Relay #70 Panel F (moth) in relay.
First actual case of bug being found.
The page’s other entries — Started Cosine Tape (Sine check), Started Mult+Adder Test — are the ordinary shift log around it. Debugging is routine work, and this is the one entry where the bug was literally an insect.
How do we describe something to a computer?
The earliest answer predates computers entirely: the Jacquard loom used punched cards to control weaving patterns, and punch cards carried programs into machines well into the era of electronic computing. The largest punch card program was 5MB: a shoulder-high bank of loose card stacks.
Above the cards, the same program — integer exponentiation, power(x, y) — walks up through the generations of language:
- Machine code (x86 32-bit): raw bytes,
55/89 E5/B8 01 00 00 00, each one an instruction the CPU decodes directly. The two jumps are a relative jump 9 bytes forward if zero and a relative jump back 11 bytes. - Assembly (1947): the same instructions given mnemonic names and labels —
push ebp,imul eax, ebx,jmp .loop. One line per machine instruction, but readable. - Fortran (1957):
DO 10 I = 1, Y…10 CONTINUE. Numbered statements, but arithmetic looks like arithmetic. - COBOL (1959):
IDENTIFICATION DIVISION.…PERFORM UNTIL COUNTER = 0. Deliberately English-like, designed for business and administration. - C (1972):
for (int i = 0; i < y; i++) { ans = ans * x; }— structured control flow, close to the machine but portable. - Python (1991):
for _ in range(y): ans = ans * x— the loop mechanics disappear entirely.
Each step trades control over the machine for expressiveness to the human. The line count shows it: 19 lines of machine code and 22 of assembly become 5 lines of Python for the same function.
Python
Python was developed by Guido van Rossum and named after the British comedy troupe Monty Python (not the snake). It is a general-purpose, high-level programming language, created to support a variety of programming styles (see programming-paradigms) and to be fun to use.
What is an algorithm?
An algorithm is an ordered sequence of unambiguous instructions that eventually terminates.
The three requirements are each load-bearing: ordered (see the sequencing examples in python-variables-and-memory-model), unambiguous, and eventually terminates — which is exactly what an infinite while True loop fails to do.
The language we use to express an algorithm matters far less than what we are expressing: an instruction sequence that does something useful, like sorting a list. That is why the same exponentiation program above is recognisably the same algorithm in six different languages.
Selection sort on [26, 54, 93, 17, 77, 31, 44, 55, 20] is the example of “something useful”. A nine-row trace shows it with no code, because the code is the part that does not matter yet. The trace is drawn in sorting-algorithms, and selection sort returns in week 13.
What is computer science? What is software engineering?
Computer science is the practice/art of creating algorithms and measuring their relative effectiveness.
Software engineering is the practice/art of creating and maintaining software (realized algorithms) in groups.
The first half of that computer science definition is sorting-algorithms; the second half is algorithmic-complexity. The end of the course does both at once, as a transition from software engineering to computer science.
Model-View-Controller (MVC)
Model-View-Controller (MVC) is a design pattern that separates an application into three interconnected components, each with a single, distinct responsibility.
- Model — stores the data and business rules of the application; responsible for every state change.
- View — some (usually visual) representation of the data, without altering it.
- Controller — an interface that receives user input (commands), tells the Model what to do, then selects a View to present the result.
The asymmetry in that third bullet is the pattern: the Controller is the only component that knows about both of the others. The View does not read from the Model, and the Model does not know about either of the others.
The three components
| Layer | Core question | Owns | MUST NOT |
|---|---|---|---|
| Model | What is the data? | Data & rules | print, parse args, call input() |
| View | How is info shown? | Formatting & rendering | change state, validate data |
| Controller | What happens next? | Workflow & commands | store raw data, format output |
Model knows nothing about the outside world.
The Model never prints, reads input, or otherwise interacts with the user directly — it is pure data and logic.
Figure 61: The dependency shape the three-component table implies. Solid arrows are calls; the two dashed arrows are not calls but returns - the Model’s domain data going back to the Controller and not to the View, and the output the User reads off stdout; the dashed grey boxes are the outside world, not classes. The magenta text beside each layer is its MUST NOT rule, and the crossed magenta stub under the Model marks that it has no route to the outside world. The box fill colours carry no meaning.
Flow of control
- User issues a command.
- Controller parses the input and calls the appropriate Model method.
- Model mutates its own state and returns domain data.
- Controller selects a View and passes it the data.
- View formats the data and presents it (e.g. prints to stdout).
- Control returns to the main loop, waiting for the next user action.
Two steps are routinely misremembered. Step 3 returns the domain data to the Controller, not to the View — that’s why the return arrow in Figure 61 points back left. And step 4 means the View is chosen after the Model has already run, which leaves room for which View gets used to depend on what the Model returned.
See 2025-10-14-model-view-controller for the same six steps against a worked example, drawn out step by step — including the one place that example’s code departs from them.
Why use it?
- Modularity — swap in a new model, view, or controller without breaking the rest of the application.
- Testability — each component can be tested in isolation.
- Separation of concerns — each component has exactly one job.
The Model is the easiest of the three to test, because the table above forbids it any I/O at all. Modularity in particular depends on one implementation habit: the Controller should be given its Model and View rather than constructing them itself, so that swapping either is a change at the call site and not a change inside the Controller. The worked example does this: its run loop builds TodoApp(TodoList(), TodoView()) and hands both in.
Minimal skeleton
This is the worked example with the todo-list domain taken out, so that the shape of the three classes is all that is left.
class Model:
def __init__(self):
self._state = ...
def do_something(self, ...):
# mutate self._state, return domain data
...
class View:
def show(self, data):
# format `data` and present it -- no mutation, no logic
...
class Controller:
def __init__(self, model, view):
self._model = model
self._view = view
def handle(self, command):
# parse `command`, call the right Model method,
# then pass its result to the View
...
# the run loop belongs with the Controller
controller = Controller(Model(), View())
while True:
command = input("$ ")
if command.strip() in ("quit", "exit"):
break
controller.handle(command)The skeleton has no print in Model, no input() anywhere but the run loop, and no reference to Controller from inside View or Model.
Smells that break the pattern
Warning signs that a layer has taken on work belonging to another. Each row is one cell of the MUST NOT column above, turned into something you can spot while reading code.
| Smell | Which rule it breaks |
|---|---|
A print or an f-string inside a Model method |
Model must not format output |
A Model method that calls input() to ask a follow-up question |
Model must not read input |
| A View method that assigns to an attribute of the object it was passed | View must not change state |
| A View that rejects bad data instead of displaying it | View must not validate |
| A Controller that keeps its own copy of the task list, scores, etc. | Controller must not store raw data |
| A Controller that builds the output string itself and prints it | Controller must not format output |
In practice
The worked example keeps the three layers in three separate classes (a todo list manager: Task/TodoList as Model, TodoView as View, TodoApp as Controller). Real GUI and game applications often merge View and Controller into a single class, since rendering and input handling both live inside the same per-frame/per-event loop. The property worth preserving even then is the Model’s isolation: whatever owns rendering and input, the Model itself should stay free of print/input()/UI-framework calls.
Small teaching examples frequently bend the Controller and View rules too — the worked exercise in 2025-10-14-model-view-controller has its Controller printing status messages directly and its View reading private attributes off Model objects — which is worth knowing about, because “does this obey the table?” is a much sharper question than “does this look like MVC?”.
Numerous variants of MVC exist. Treat the version above as the base form.
See python-inheritance for abstract base classes and MRO, and python-composition for is-a vs has-a.
Programming Paradigms
A paradigm is the style in which you describe a computation to a machine. The top-level split is between saying how to do something and saying what you want.
| Question answered | |
|---|---|
| Imperative | How to do it |
| Declarative | What to do |
Imperative programming
The programmer spells out how to do it, step by step. (Imperative, as an adjective, means giving an authoritative command.) It divides further by how those commands are grouped:
- Procedural — groups instructions into functions. This is everything up to week 7: python-functions, python-if-statements, python-while-loops, python-for-loops.
- Object-oriented — groups instructions into objects that combine data (state, attributes) and behaviour (methods). This is weeks 7–11: python-classes-and-objects onward.
Both are imperative — OOP does not stop you writing step-by-step instructions, it just changes what those instructions are attached to.
Declarative programming
The programmer declares what they want, through:
- Functional — a series of function applications.
- Logic — a question asked about a system of facts and rules.
- Mathematical optimization — an objective and a set of constraints.
Python is not a declarative language, but it has declarative moments. A list comprehension is the clearest one:
# imperative: how to build the list
acc = []
for k in range(4):
acc.append(k**2)
# declarative: what the list is
[k**2 for k in range(4)]The comprehension reads like the set-builder notation \(\{k^2 : k \in \{0,1,2,3\}\}\) — you state the set, not the procedure for accumulating it. See python-comprehensions.
Paradigm is not the same as level of abstraction
Take one program written six times over — integer exponentiation, power(x, y) — in six languages, from raw x86 bytes up to Python (the listings themselves are walked through in history-of-computing). It is tempting to read that ladder as a tour of paradigms. It is not. Every rung is imperative: set an accumulator to 1, run a loop y times, multiply.
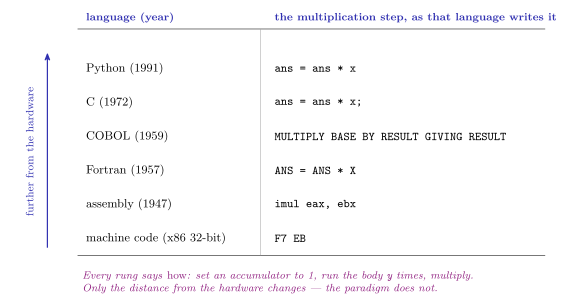
Figure 62: The one step that survives all six languages. Each row is that language’s way of writing multiply the accumulator by x. The rows run from the oldest language at the bottom to the newest at the top. The bottom two rows are the same instruction twice: F7 EB is what the machine stores, imul eax, ebx is the assembly for it.
The loop is the clearest tell. All six spell out how to repeat:
| Language | How it repeats |
|---|---|
| machine code | 74 09 and EB F5 — a conditional jump 9 bytes forward, an unconditional jump 11 bytes back |
| assembly | test ecx, ecx / jz .done … jmp .loop |
| Fortran | DO 10 I = 1, Y … 10 CONTINUE |
| COBOL | PERFORM UNTIL COUNTER = 0 … END-PERFORM. |
| C | for (int i = 0; i < y; i++) |
| Python | for _ in range(y) |
COBOL looks least like the rest. MULTIPLY BASE BY RESULT GIVING RESULT is English, and that was the point: Grace Hopper’s contribution was machine independent programming based on english words. But English-like syntax is not a declarative paradigm — the COBOL program still names every step and every repetition, in order. It is imperative prose.
So the ladder measures a different axis from the imperative/declarative split:
- Level of abstraction — how much of the machine you have to say out loud. This is what changes from
F7 EBtoans = ans * x. - Paradigm — whether you say how or what. This does not change anywhere on the ladder.
Python’s ** operator (see 2025-07-29-python-as-a-calculator) needs no loop written at all, and is one more step up the first axis: x ** y hands the repetition to the language. That still is not a change of paradigm — a single operator call is an abstraction, not a style of description. The genuine paradigm shift is the one shown further up, where a comprehension replaces the accumulation with a statement of what the result is. For ** alongside the rest of the arithmetic, see python-operator-precedence-and-associativity.
Why Python has several
Python was created to support a variety of programming styles rather than enforce one (see history-of-computing). CSSE1001 uses this deliberately: the course is structured as procedural first, then object-oriented, then (in the final, non-assessed week) a look at the functional style.
Where OOP fits
The fundamental building block of object-oriented programming is the class or object. In this paradigm, the design principle is to solve a problem by creating objects that interact with one another.
An object is a collection of fields and attributes (the data comprising the object’s state) along with methods (class-scoped functions) that can act on the object itself. An object can reference and change its own state, and has a notion of self.
Continue in python-classes-and-objects for the mechanics, and 2025-09-09-object-oriented-programming for the lecture that introduces them.
Python Boolean Logic
The basic operands of logic are True, False, or, and, and not.
Boolean domain and predicates
Definition (boolean domain). Let \(\mathbb{B}\) denote the boolean domain, where \(\mathbb{B} = \{\texttt{True}, \texttt{False}\}\).
Definition (predicate). Any function that maps into \(\mathbb{B}\) — i.e. one that evaluates to
TrueorFalse— is called a predicate.
So the boolean function \(> \;:\; \mathbb{Z} \times \mathbb{Z} \to \mathbb{B}\) (“greater than”) is a predicate:
>>> type(True), type(False)
(<class 'bool'>, <class 'bool'>)
>>> 7 > 3
True
>>> 7 >= 7 + 1 # note addition happened first
False
>>> (7 >= 7) + 1
2
>>> int(True), int(False)
(1, 0)
>>> bool(1), bool(0), bool(123), bool(-2) # "truthiness"
(True, False, True, True)The two middle lines are worth pausing on: arithmetic binds tighter than comparison, so 7 >= 7 + 1 is 7 >= 8; but once a comparison has been evaluated its True/False result is an ordinary value that arithmetic will happily consume, so (7 >= 7) + 1 is True + 1 is 2.
and and or
Definition (and). The binary predicate
andis used to express that both of two statements are true, and is false if either is false.
\(\texttt{and} : \mathbb{B} \times \mathbb{B} \to \mathbb{B}\)
and |
True |
False |
|---|---|---|
True |
True |
False |
False |
False |
False |
Definition (or). The binary predicate
oris used to express that at least one of two statements is true, and is false only when both are false.
\(\texttt{or} : \mathbb{B} \times \mathbb{B} \to \mathbb{B}\)
or |
True |
False |
|---|---|---|
True |
True |
True |
False |
True |
False |
>>> 3 > 7 or 7 > 3
True
>>> 3 > 7 and 7 > 3
False
>>> 0 < 3 and 3 < 8
True
>>> 0 < 3 < 8 # shorthand for the above
TruePrecedence
True or False and False is ambiguous without a precedence rule, because
(True or False) and False == False
True or (False and False) == True.Observing what Python actually does settles it:
>>> True or False and False
Trueand thereby and has precedence over or.
Definition (not). The logical statement
notis the negation of a logical statement:not True == Falseandnot False == True. It is evaluated first when combined with other logical operands.
“First” here means first among the logical operands — not binds tighter than and and or, but looser than the comparison operators, so a not in front of a comparison negates the whole comparison rather than just its left operand:
>>> a, b = 6, 7
>>> a == 6 and b != 5
True
>>> not (a == 6 and b != 5)
False
>>> not a == 6 and b != 5 # not happens before and
False
>>> not (a != 6 or not b != 5) # avoid double negations
TrueThe third line is (not (a == 6)) and (b != 5), i.e. False and True. The fourth is valid and correct but is exactly the kind of double negation to avoid — it is far harder to read than the first line it is equivalent to.
The full ladder for these three, tightest first: comparisons (==, !=, <, …) → not → and → or. Arithmetic binds tighter than all of them; see python-operator-precedence-and-associativity. The transcript above does not settle where not sits relative to the comparisons, because (not a) == 6 and not (a == 6) happen to give the same answer on its third line.
Short circuits (lazy evaluation)
or stops as soon as it finds a truthy value and and stops as soon as it finds a falsy one — the remaining operand is then never evaluated, so an error lurking in it never fires:
>>> True or 1/0
True
>>> False or 1/0
ZeroDivisionError: division by zero
>>> True or non_existent_variable
TruePython does not bother looking for non_existent_variable at all. What short-circuiting does not buy you is a pass on being well-formed — the expression still has to parse:
>>> True or !
True or !
^
SyntaxError: invalid syntaxThe and cases are the mirror image:
>>> True and 1/0
ZeroDivisionError: division by zero
>>> False and 1/0
FalseComparisons are still expressions
A comparison produces a value like any other expression, and that value can be named:
>>> a = 3
>>> a == 3
True
>>> a != 3
False
>>> b = (a != 3) # comparisons are still expressions
>>> b
FalseBecause True and False have integer representations 1 and 0, they also survive arithmetic. In the example below, a is True + 2 = 3, b is 7*False = 0, and c is not (a != b) = not (3 != 0) = not True:
>>> a = True + 2
>>> a
3 # True has an integer representation as 1
>>> b = 7*False
>>> b
0 # False has an integer representation as 0
>>> c = not a != b
>>> c
FalseTruthiness
Truthy values are values in Python that evaluate to true — for example non-zero numbers, non-empty strings, and non-empty lists:
>>> bool(1), bool(-10), bool("Hello"), bool([1,2,3])
(True, True, True, True)Falsy values are values that evaluate to false — for example zero, the empty string, and the empty list:
>>> bool(0), bool(""), bool([])
(False, False, False)Question. Which of the following expressions evaluate to True?
bool(not () and "hello")
bool(True or 1/0)
bool(" ")
bool(2 > True)
bool("False")All five, each for a slightly different reason: () is falsy so not () is True and and hands back "hello", which is truthy; or short-circuits before the division; " " is a non-empty string (a space is a character); True is 1 and 2 > 1; and "False" is a non-empty string, its contents notwithstanding.
What and/or actually return
The functions and and or do not always return True and False. and returns its first falsy input and or its first truthy input; if no such value exists, the last input is returned.
>>> 0 or 2
2
>>> 0 and 2
0Because the empty tuple () is falsy and any non-empty tuple is truthy:
>>> () or (1,) or (1, 2)
(1,)
>>> (1, 2) or (1,) or ()
(1, 2)
>>> 1 and 2
2
>>> () and (1,) and (1, 2)
()
>>> (1, 2) and (1,) and ()
()This is what makes the truthiness question above work out the way it does: not () and "hello" evaluates to the string "hello", not to True, and only the outer bool turns it into True.
Python Classes and Objects
An object bundles data (fields/attributes, comprising its state) with methods (class-scoped functions that act on that data). An object can reference and change its own state, and so has a notion of self.
A class is the blueprint; an object is an instance of that class. Keeping the data inside the class and reaching it only through the class’s own attributes and methods is encapsulation.
Introduced in 2025-09-09-object-oriented-programming (Lecture 7C).
Defining a class
class ClassName():
def __init__(self, ...):
self.attribute = ...
def some_method(self, ...):
return ...- Class names use
CamelCapsby convention (ClassNamesAreLikeThis). __init__is the initializer, run automatically when an instance is created.- Every method’s first parameter is
self— Python supplies it automatically; never pass an argument for it explicitly. - Think of the class body as a blueprint with placeholders:
selfhas anx,selfhas ay. On instantiation,selfbecomes the particular object being built and each placeholder becomes a real attribute stored in it, so many instances can share one blueprint while each holds its own values.
Instantiation and attributes
>>> p = ClassName(...) # creates an instance, passing args to __init__
>>> p.attribute # dot notation accesses instance variables
>>> p
<__main__.ClassName object at 0x10a9e0dd8>
>>> type(p)
<class '__main__.ClassName'>A method is called the same way: <object_variable>.<method>(<parameters>). Calling it as a bare name is a NameError — it only exists on the object.
Equality vs. aliasing
- Two separately-constructed instances with identical attributes are not
==by default: the default comparison is identity, so equal-looking objects at two different addresses compareFalse. Defining what equality means for a class is the job of__eq__— see python-dunder-methods. - Assigning
q = pmakesqan alias for the same object asp— mutating one is visible through the other, andp == qholds because they’re literally the same object.
Private variables, getters, and setters
A leading underscore (self._value) signals that an attribute is intended for internal use only — a convention, not an enforced restriction; nothing stops external code from reading or writing it directly (which is bad practice).
Prefer exposing controlled access via methods:
def get_value(self) -> int: # getter
return self._value
def set_value(self, x: int) -> None: # setter
if x < 0:
raise ValueError
self._value = xThe raise is the reason the setter exists: it is the one place the class can reject a bad value before it becomes state (see python-exceptions).
Python’s @property/@<name>.setter decorators let a getter/setter pair be used with ordinary attribute syntax (obj.name / obj.name = value) instead of explicit method calls, so validation still runs while call sites stay readable.
Python Composition
Composition is a way of building a class out of other objects: an object of one class holds an object of another class as one of its attributes. This forms a has-a relationship (e.g. a Car has-a Engine) — as opposed to inheritance’s is-a relationship (e.g. a SportsCar is-a Car).
Figure 63: The two ways of reusing a class, side by side. On the left, composition is containment: the part sits inside the whole, and there is no connecting line. On the right, inheritance is a hierarchy: parent above, children below, joined by a stem-and-bus connector with no arrowhead. has-a is lettered in magenta and is-a in purple.
Basic pattern
class Car():
def __init__(self, engine: Engine) -> None:
self._engine = engine # Car has-a engine
def start(self):
self._engine.start()The outer object (Car) doesn’t need to know how the inner object (Engine) works internally — it just calls the inner object’s public methods. This keeps each class focused on a single responsibility.
Delegation
The method Car.start() above does no work of its own: it forwards the request to the part that knows how to do it. That forwarding is called delegation, and it is what most methods on a composed class end up doing. The outer class keeps the policy — when something may happen, and under what conditions — and the inner class keeps the mechanism.
The DroneFlight example in 2025-09-23-composition is the clearest case: the drone decides that a photo costs 5% battery and is refused below 5%, but it is the Camera that takes the picture and the Battery that tracks the charge.
The part is passed in, not created inside
Car.__init__ takes an Engine as a parameter rather than writing self._engine = Engine(). Both are composition, but only the first lets the caller decide which engine, and only the first makes the part replaceable. It is also what makes the class testable — a test can pass in a stand-in object instead of the real part.
Worked example: Car/Engine
This example stores the part in a public engine attribute, so that swap_engine() has something ordinary to reassign, where the basic pattern above uses the private _engine.
class Engine:
def __init__(self, horsepower, fuel_type="gasoline"):
self.horsepower = horsepower
self.fuel_type = fuel_type
self.running = False
def start(self):
if not self.running:
self.running = True
print(f"{self.fuel_type.capitalize()} engine with {self.horsepower} HP started.")
else:
print("Engine is already running.")
def stop(self):
if self.running:
self.running = False
print("Engine stopped.")
else:
print("Engine is already off.")
class Car:
def __init__(self, make, model, engine: Engine):
self.make = make
self.model = model
self.engine = engine
def start(self):
print(f"Starting the {self.make} {self.model}...")
self.engine.start()
def stop(self):
print(f"Stopping the {self.make} {self.model}...")
self.engine.stop()
def swap_engine(self, new_engine: Engine):
if self.engine.running:
print("Stopping current engine before swap...")
self.engine.stop()
print(f"Swapping engine in {self.make} {self.model}...")
self.engine = new_engine
print("New engine installed!")>>> small_engine = Engine(150, "gasoline")
>>> car = Car("Toyota", "Corolla", small_engine)
>>> car.start()
Starting the Toyota Corolla...
Gasoline engine with 150 HP started.
>>> big_engine = Engine(300, "diesel")
>>> car.swap_engine(big_engine) # safely stops the old engine first, if runningHot-swapping a part
Because a composed attribute is just a reference, it can be replaced at runtime by any object that supports the operations actually performed on it — duck typing, no shared base class required. The replacement need not be a subclass, or related to the original at all; it only needs the right methods.
Two things to get right when doing this:
- Swap the attribute the class actually uses. If
__init__stores the part asself._engine(with the leading underscore that marks it private), then assigningcar.engine = new_enginefrom outside creates an unrelated new public attribute and leaves the real part untouched. The object will carry on using the old one. This is an easy mistake, because the swap looks like it worked and nothing raises an error. - Give the old part a chance to shut down. A bare attribute assignment discards the previous object silently, mid-operation if it happens to be running. A dedicated method (
swap_engine()above) can stop it first.
Composition vs. inheritance
- Use composition (“has-a”) when an object is made up of other objects, or uses another object to do part of its job.
- Use inheritance (“is-a”) when a new class is a more specific version of an existing class — see python-inheritance and 2025-09-23-inheritance.
Composition tends to be more flexible: a composed attribute can be freely swapped for any object supporting the same interface, without needing any shared base class.
The two are not rivals within a single program, either. A class built by composition can perfectly well be subclassed: a SurveyDrone is a DroneFlight, which has a Camera.
Python Comprehensions
A comprehension is a concise way to build a list or dictionary directly from an iterable, without writing an explicit accumulator for-loop.
List comprehension
>>> [k**2 for k in range(4)]
[0, 1, 4, 9]Equivalent to:
>>> acc = []
>>> for k in range(4):
... acc.append(k**2)sum(... for ...), without the surrounding [], computes a running total directly. The bracket-less form is a generator expression, and so totals without building the intermediate list.
>>> sum(k**2 for k in range(4))
14Dictionary comprehension
Same shape, but the output expression is a key: value pair and the braces are {}:
>>> {x: f"value is {x}" for x in range(3)}
{0: 'value is 0', 1: 'value is 1', 2: 'value is 2'}Useful for assigning default values across a set of keys:
>>> {x: 0 for x in "ABC"}
{'A': 0, 'B': 0, 'C': 0}Duplicate keys collapse — iterating a string with repeated characters still yields one entry per distinct character:
>>> cs = "hello world"
>>> {x: cs.count(x) for x in cs}
{'h': 1, 'e': 1, 'l': 3, 'o': 2, ' ': 1, 'w': 1, 'r': 1, 'd': 1}Nested comprehensions
Multiple for clauses can appear in one comprehension. The order of the for clauses matters — it matches the order they’d be nested as for-loops:
>>> [(a, x) for a in "AB" for x in range(2)]
[('A', 0), ('A', 1), ('B', 0), ('B', 1)]
>>> [(a, x) for x in range(2) for a in "AB"]
[('A', 0), ('B', 0), ('A', 1), ('B', 1)]Filtering
A trailing if filters which elements are included:
>>> [x for x in range(101) if not (x % 3) and not (x % 7)]
[0, 21, 42, 63, 84]The general pattern
[x for x in xs if P(x)]
[x for x in xs for y in ys if P(x, y)]
[x for x in xs for y in ys for z in zs if P(x, y, z)]
...where P is some predicate.
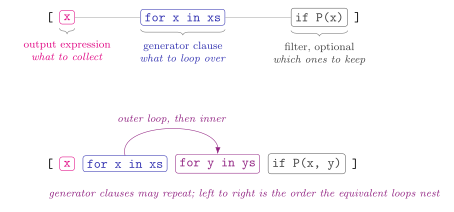
Figure 64: The three parts of a comprehension, named on the first two forms of the general pattern: output expression, generator clause and filter. Magenta is the output expression, blue the first generator clause, purple the second. That key covers the boxed code only: the purple arrow labelled outer loop, then inner and the purple line beneath the second form are annotations, not a fourth part.
The same three parts appear in a dictionary comprehension, except the output expression is a key: value pair.
True/False as 1/0
True/False behave as 1/0 in arithmetic — a common idiom for counting how many elements of an iterable satisfy some condition. It works because Python’s bool is a subtype of int.
>>> True + True + False
2
>>> sum(x > 0 for x in [-1, 2, 3, -4])
2all and any
Python’s built-in all(xs)/any(xs) check whether every/some element of xs is truthy:
>>> all(['A' <= x <= 'Z' for x in "HELLO WORLD"])
False
>>> any(['A' <= x <= 'Z' for x in "HELLO WORLD"])
TrueCareful: redefining a function named
alloranyin your own code shadows these built-ins for the rest of that scope. 2025-08-25-comprehensions’s exercises do exactly that, deliberately, to reimplement them.
See python-for-loops for the equivalent for-loop/accumulator forms these shortcut.
Python Dictionaries
Definition (Dictionary). A dictionary in Python is a data-structure that stores
tuple(key, value)pairings. Python has a “magic” hash function to find a key among the tuples fast. Dictionaries are not ordered and are mutable.
Hash tables are a candidate for the most important/useful data-structure in computer science.
The dictionary is not a new idea so much as a generalised index: see Lecture 4B’s hash-function section for two hand-rolled encodings, and the figure there showing a key being turned into a list position by two different hash functions. dict is what you get when Python supplies that hash function for you, for keys of any (immutable) type. The reason a dictionary has no ordering is precisely that the keys can be of mixed type.
Creating and indexing
>>> h = {
... "red": ["apple", "firetrucks", "cars"],
... "yellow": ["banana", "cars"],
... "blue": ["sky", "cars"]
... }
>>> h["blue"]
['sky', 'cars']
>>> h["green"]
KeyError: 'green'
>>> h["green"] = ["leaves"] # fine, because we're assigning not retrievingAn empty dictionary is dict() (or {}).
keys, values, items
>>> h.keys()
dict_keys(['red', 'yellow', 'blue'])
>>> h.values()
dict_values([['apple', 'firetrucks', 'cars'], ['banana', 'cars'], ['sky', 'cars']])
>>> h.items()
dict_items([('red', ['apple', 'firetrucks', 'cars']), ('yellow', ['banana', 'cars']), ('blue', ['sky', 'cars'])])items() is the one that shows the definition literally: each pairing comes back as a (key, value) tuple.
clear and copy
>>> f = h.copy()
>>> h.clear()
>>> h["blue"]
KeyError: 'blue'
>>> f["blue"]
['sky', 'cars']Like list’s .copy() (see python-lists), dict’s .copy() is only a shallow copy — mutable values are still shared:
>>> f = h.copy()
>>> h["blue"].append("windex")
>>> h["blue"]
['sky', 'cars', 'windex']
>>> f["blue"]
['sky', 'cars', 'windex'] # shallow copy -- same underlying listRead the two transcripts together: clear() empties the dictionary h without touching f, because f is a different dictionary object — but h["blue"].append(...) reaches through both dictionaries to the one list they share. Same shallow/deep split as the shallow-copy figure in python-lists.
get
.get(key) is a safer alternative to h[key] — it returns None instead of raising KeyError if the key is missing:
>>> h.get("red")
['apple', 'firetrucks', 'cars']
>>> h["green"]
KeyError: 'green'
>>> h.get("green")
None # safer, because no error is thrown hereWithout a method, the same “avoid a KeyError” pattern is written explicitly:
>>> if key in table: # avoiding KeyError
... table[key] += 1
... else:
... table[key] = 0This is a sketch of the membership-test idiom, not a working counter. As a frequency counter the else branch would have to be table[key] = 1 — a key seen for the first time has been seen once, not zero times.
Warning: keys must be immutable
The keys of a dictionary must be an immutable type (see python-primitive-data-types and python-lists):
>>> d = dict()
>>> d[ [1,2,3] ] = 1
TypeError: unhashable type: 'list'
>>> d[ (1,2,3) ] = 1 # tuples are immutable
>>> h = dict()
>>> d[ h ] = 1
TypeError: unhashable type: 'dict'“Unhashable” is the error message’s way of saying the same thing the definition does: a key has to be something the hash function can turn into a fixed location, and a value that can change underneath you cannot be.
Python Dunder (Magic) Methods
Dunder (“double underscore”) or magic methods are special methods, named __like_this__, that Python calls automatically to implement built-in behaviour for a type — instantiation, printing, equality, arithmetic operators, and more. You don’t call them directly; Python invokes them on your behalf when the corresponding syntax/built-in is used.
See 2025-09-16-dunder-methods for the lecture note, and python-classes-and-objects for classes generally.
Common dunder methods
| Method | Called by | Purpose |
|---|---|---|
__init__(self, ...) |
ClassName(...) |
Initializes a new instance. Returns None — it fills in an object that already exists rather than producing one. |
__str__(self) |
print(obj), str(obj) |
User-friendly display string. |
__repr__(self) |
the REPL, repr(obj) |
Unambiguous, developer-facing string — ideally a valid Python expression that recreates the object via eval(). |
__eq__(self, other) |
obj == other |
Custom equality (instead of identity). |
__add__(self, other) |
obj + other |
Addition. |
__sub__(self, other) |
obj - other |
Subtraction. |
__neg__(self) |
-obj |
Unary negation. |
__len__(self) |
len(obj) |
Length. |
Every binary method takes the left operand as self and the right one as other.
__repr__ vs. __str__
__repr__is for the programmer: unambiguous, meant for debugging/logging, ideallyeval(repr(obj))reconstructs an equal object. The round trip isobj→repr()→ source text →eval()→ a second object, whosereprmatches the first’s.__str__is for the user: a friendly, readable string, used byprint().- If only
__repr__is defined,print()falls back to it. If neither is defined, printing an object shows its default<... object at 0x...>representation.
A consequence that catches people out: at the interactive prompt, >>> obj and >>> print(obj) can produce completely different text from the same object, because they go through different methods.
Type-hinting a class inside its own body
Methods like __add__ want to say they return the class being defined, but the class object doesn’t exist yet while the body is executing:
from __future__ import annotations # makes annotations lazy (strings)
class Fraction():
def __add__(self, other) -> Fraction: # legal because of the import
...Without that import, -> Fraction is evaluated immediately and raises NameError; the alternative is to quote it, -> "Fraction".
Overloadable operators
| Binary | Method | Unary | Method | Comparison | Method |
|---|---|---|---|---|---|
+ |
__add__ |
- |
__neg__ |
< |
__lt__ |
- |
__sub__ |
abs |
__abs__ |
<= |
__le__ |
* |
__mul__ |
~ |
__invert__ |
== |
__eq__ |
** |
__pow__ |
!= |
__ne__ |
||
// |
__floordiv__ |
> |
__gt__ |
||
/ |
__truediv__ |
>= |
__ge__ |
Operators can be defined in terms of each other rather than from scratch — Fraction.__sub__ is just return self + -other, i.e. __add__ composed with __neg__.
Instance variables vs. class variables
An instance variable (self.x = ...) belongs to one specific object — each instance has its own copy. A class variable (declared directly in the class body) is shared by all instances of the class, and can be accessed either via an instance (obj.class_var) or via the class itself (ClassName.class_var), without needing any instance at all.
class Clicker():
_all_clicks = 0 # class variable -- shared by every instance
def __init__(self) -> None:
self._clicks = 0 # instance variable -- unique per object
def click(self) -> None:
self._clicks += 1
Clicker._all_clicks += 1Why Clicker._all_clicks += 1 and not self._all_clicks += 1. self._all_clicks += 1 expands to self._all_clicks = self._all_clicks + 1. The read on the right-hand side finds the class attribute (attribute lookup falls back to the class when the instance has no such name), but the assignment on the left always writes an instance attribute. So the first click on each object creates a private _all_clicks on that object that shadows the shared one forever, and the class-level total stays at 0. Naming the class explicitly is what makes the update land on the shared cell.
Reading through an instance is fine — c._all_clicks returns the class’s value, which is why the transcript in 2025-09-16-dunder-methods shows (6, 6, 6). It is only assignment through an instance that breaks the sharing.
Worked example: Vector2D
A fuller worked example combining several dunder methods together. The length is Euclidean: for (2, 3) it is sqrt(13), 3.605551275463989.
import math
class Vector2D():
def __init__(self, x, y):
self.x = x
self.y = y
def length(self):
return math.sqrt(self.x**2 + self.y**2)
def __repr__(self):
return f"Vector2D(x={self.x}, y={self.y})"
def __str__(self):
return f"2D Vector: ({self.x}, {self.y}) --- length: {self.length()}"
def __eq__(self, other):
return isinstance(other, Vector2D) and self.x == other.x and self.y == other.y
def __add__(self, other):
if not isinstance(other, Vector2D):
return NotImplemented
return Vector2D(self.x + other.x, self.y + other.y)
def __len__(self):
return 2>>> u = Vector2D(2, 3)
>>> v = Vector2D(4, 5)
>>> print(u + v)
2D Vector: (6, 8) --- length: 10.0
>>> print(u) # calls __str__
2D Vector: (2, 3) --- length: 3.605551275463989
>>> repr(u) # calls __repr__
'Vector2D(x=2, y=3)'
>>> u == v # calls __eq__
False
>>> len(u) # calls __len__
2print(u + v) uses two magic methods in one expression: __add__ builds the new vector, then print displays it through __str__.
Returning NotImplemented (rather than raising or returning False) from a method like __add__ is the standard way to signal “I don’t know how to combine these two types” — it lets Python fall back to the other object’s reflected method, or raise a clean TypeError if nothing handles it.
Python Exceptions
An exception is a run-time error — unlike a syntax error, which Python reports while parsing the file, an exception cannot be detected until the offending line actually executes. Left uncaught it aborts the program, and all intermediate work is lost unless it was already written to a file.
Introduced in 2025-09-09-exceptions (Lecture 7A).
Common built-in exceptions
| Exception | Raised when… |
|---|---|
AssertionError |
an assert fails |
IOError |
a file does not exist |
IndexError |
a sequence index is out of range |
KeyError |
a dict key does not exist |
NameError |
a variable/name does not exist |
TypeError |
an unexpected type is given to a function/operator |
ValueError |
correct type, but an inappropriate value |
ZeroDivisionError |
division by zero |
The TypeError/ValueError boundary follows the function’s type contract: int has the contract int(xs: str) -> int, so int("ten") is given the right type and therefore raises ValueError, not TypeError.
Catching exceptions
try:
<code that may raise>
except SomeError:
<handle SomeError>
except AnotherError:
<handle AnotherError>
else:
<runs only if no exception occurred>
finally:
<always runs>Also called try-catch in other languages (e.g. C++). Typically used in the user-facing layers of a program, and wherever it touches external resources — files, databases, API calls, network calls.
- The
exceptclauses are tried in source order and the first match wins; the rest are skipped. If none match, the exception propagates and the program aborts. - Consequently, specific exceptions must be listed before general ones (and before a bare
except:) — Python enforces this ordering, because a general clause placed first would swallow every case below it. - A bare
except:catches any exception, but hides genuine bugs — prefer catching specific exception types. It is bad practice to ignore all errors. elseruns only when thetryblock completed without raising;finallyruns on every path, exception or not, and is the right home for cleanup.- Keep
tryblocks short: once an exception is raised inside one, none of the remaining lines in that block execute — so areturnplaced after the risky line will simply be skipped.
Raising exceptions
raise SomeError # bare
raise SomeError("message") # with an explanatory messageraise halts execution at the point the failure becomes knowable, rather than letting a bad value travel further into the program. It is the standard way for a setter to reject an invalid value before it becomes an object’s state — see python-classes-and-objects.
LBYL vs. EAFP
Two philosophies for guarding against errors:
- LBYL (Look Before You Leap) — check the condition with an
ifbefore attempting the risky operation. - EAFP (Easier to Ask for Forgiveness than Permission) — attempt the operation inside a
try, and handle the resulting exception if it fails.
Only use a try/except when it is absolutely necessary: an exception handler that is really a misplaced if makes the ordinary path harder to read.
Python File IO
Opening a file
file = open("path", "<mode>")| Mode | Description |
|---|---|
r |
read |
w |
write (creates or overwrites) |
a |
append (creates or adds to the end) |
A bare file name is resolved relative to the directory the running Python is in; os.getcwd() reports that directory and os.chdir() changes it.
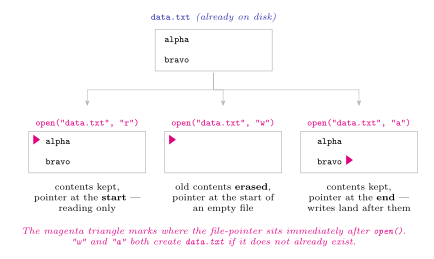
Figure 65: What each mode does to a file that already exists, and where it leaves the file-pointer. This is the difference that matters in practice: w destroys what was there before anything is written, while a keeps it and starts writing past the end.
Reading
file.readline() returns one line (including its trailing \n, except possibly the last line of the file), then '' forever once exhausted. A for-loop iterates line by line and is the idiomatic way to consume a whole file:
with open("path", "r") as file:
for line in file:
...Reading always gives back strings — cast (int(...), float(...), …) as needed.
A file-pointer only moves forward: once a for loop (or repeated readline() calls) has consumed a file, iterating again yields nothing further unless the file is reopened or the pointer is reset with file.seek(0). One consequence is useful: a lone file.readline() before the loop is how you skip a CSV header, because the call’s only lasting effect is on the pointer.
Closing
file.close() releases the file; forgetting to close leaves it vulnerable to side effects (missing or extra data). with open(...) as file: closes it automatically — even if the block raises an exception — so it’s preferred over manual open/close.
Passing files around: str vs TextIO
A function that does something to a file can take either the file’s name or an already-open file-pointer, and the two are genuinely different interfaces:
from typing import TextIO
def f(path: str) -> ...: # takes a name; opens (and closes) the file itself
with open(path, "r") as file:
...
def g(file_pointer: TextIO) -> ...: # takes an open file; the caller owns it
for line in file_pointer:
...TextIO is the type hint (imported from typing) for an open text file. A function of the second shape reads from wherever the pointer currently is, and leaves it wherever it stops — so its behaviour depends on what the caller has already read.
Writing and appending
with open("path", "w") as file:
file.write("a single string\n")
file.writelines(["one string\n", "per element\n"])"w" overwrites any existing file; "a" instead appends to the end without touching existing content. Both write exactly the characters given — any newlines have to be part of the strings.
Python For-Loops
A for-loop is a loop that repeats code for every member of a group (an iterator), in order:
for <name> in <iterator>:
<code>Iterating over strings, lists, and dictionaries
A for-loop iterates a string’s characters, a list’s elements, or a dictionary’s keys (in each case, in order):
>>> for x in "abcd":
... print(x)
a
b
c
d
>>> for x in ['a', 2, 'c']:
... print(x)
a
2
c
>>> for key in {"red": 1, "blue": 2}:
... print(key)
red
blueThe looping name retains its final value after the loop exits.
Nested for-loops
Python disallows empty loop bodies — use pass (the empty instruction, which has no effect) as a placeholder when a loop body needs no code yet:
>>> for d in "01":
... for a in "xy":
... pass
... print(d + a)
0y
1yAccumulator pattern
An accumulator is a variable a loop uses to build up an aggregate value across iterations:
>>> acc = ""
>>> for x in "abcd":
... acc = acc + x
>>> acc
'abcd'range
range([start], stop[, step]) builds an iterator of numbers (square brackets denote optional arguments), similar to list slicing:
>>> list(range(10))
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
>>> list(range(2, 7))
[2, 3, 4, 5, 6]
>>> list(range(2, 7, 3))
[2, 5]
>>> list(range(2, 7, -1))
[]
>>> list(range(7, 2, -1))
[7, 6, 5, 4, 3]One rule accounts for all of these: the walk starts at start, hops by step, and yields every value it lands on that is still short of stop in the direction it is travelling. So stop is never produced, and start is produced only when the walk produces anything at all — range(2, 7, -1) is empty because a negative step walks down from 2, away from 7, and 2 is already past 7 going that way, so not even start comes out.
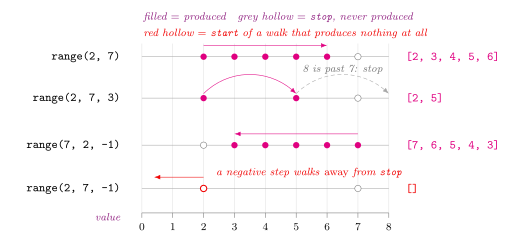
Figure 66: Four of the range calls above on one number line, ordered so the negative step that works is read before the one that does not. Filled dots are values the range produces; a grey hollow dot is stop, which it never produces; the red hollow dot on the bottom row is start, which that call never produces either. Magenta marks the answer and red the failure path. This is the half-open reading that range shares with list slicing.
range returns a range object, not a list — range(10) echoes as range(0, 10) and type(range(10)) is <class 'range'>. Wrap it in list(...) to see its contents.
Commonly used to walk through a list by index: for k in range(len(xs)):.
enumerate
enumerate(xs) pairs each element of xs with its index, roughly enumerate([x0, ..., xn]) == [(0, x0), ..., (n, xn)] (it actually returns an iterable of tuples, not a list):
>>> for k, x in enumerate(["a", "b", "c"]):
... print(k, x)
0 a
1 b
2 cFor-loops vs. while-loops
Every for-loop can be rewritten with only a while-loop:
>>> for x in xs:
... ...
>>> k = 0
>>> while k < len(xs):
... x = xs[k]
... ...
... k += 1The reverse isn’t always true — a while-loop whose number of repetitions isn’t known in advance (e.g. repeatedly prompting a user until they enter valid input) can’t be rewritten as a for-loop.
Out-of-place vs. in-place
Building a new accumulator (e.g. a fresh list) without touching the original input is an out-of-place computation. An in-place change instead mutates the input directly — covered with lists and the object-oriented part of the course.
See python-comprehensions for a more concise way to write many accumulator-style for-loops.
Python Functions
User-defined functions bundle lines of code together so they can be reused, abstracting away complexity. Like mathematical functions, they take input and return output (we’ve already used built-in functions this way, e.g. * and max). Multiplication takes two numbers and returns a number; max takes two or more numbers and returns a number.
Defining a function
A mathematical function such as \(f(x) = x^2 + x + 1\) is written in Python as:
>>> def f(x):
... return x**2 + x + 1
>>> f(3)
13Functions can take multiple parameters, and a call is an expression like any other — so calls nest inside other calls and inside arithmetic:
>>> def f(x, y):
... return x*y
>>> x = f(3, 2)
>>> x
6
>>> x = f( -f(5, 2) + 12, f(2, 3) )
>>> x
12The inner calls are evaluated before the outer one, so the last line is f(-10 + 12, 6), which is f(2, 6), and so 12.
Indentation
Four spaces of indentation are significant in Python — they associate a line of code with the control structure above it (here, the function body with its def). Get the indentation wrong and you get
IndentationError: unexpected indentwhich is a formatting complaint, not a logic error.
The return statement
return is a reserved word — one that cannot be assigned by us. It designates the value the function hands back and terminates the function itself.
Definition (
return). Thereturnstatement causes a function to exit and hand back a value to its caller.
Two consequences follow:
- Statements before the
returnstill run (including their side effects). - Nothing after the first
returnthat is actually reached ever runs — not a furtherprint, not a secondreturn.
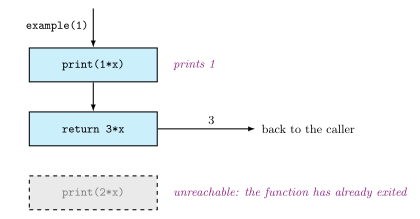
Figure 67: Control through the body of def example(x): print(1*x); return 3*x; print(2*x) when called as example(1). The print above the return runs and displays 1; the return hands 3 back and ends the call there, so the print below it never executes. The dashed grey box marks that unreachable statement.
Three variants of the same function show both. In the first, both prints are above the return, so both run:
>>> def example(x):
... print(1*x)
... print(2*x)
... return 3*x
>>> a = example(1)
1
2
>>> a
3Move the return up one line and the second print is stranded below it:
>>> def example(x):
... print(1*x)
... return 3*x
... print(2*x)
>>> a = example(1)
1
>>> a
3Put the return first and nothing below it runs — not the second return, not the print. The call produces no output at all:
>>> def example(x):
... return 3*x
... return 2*x
... print(1*x)
>>> a = example(1)
>>> a
3If a function has no return statement at all, Python presumes return None is its last line:
>>> def f(x, y):
... print(x+y)
... return None # presumed -- you do not write thisso the “no return” case is not special, it just returns None:
>>> def example(x):
... print(2*x)
>>> a = example(1)
2
>>> a
>>> type(a)
<class 'NoneType'>>>> a displays nothing at all, because the REPL does not echo None.
return versus print
print is a function that returns nothing and whose side effect is that it displays something:
>>> x = print("Hello World")
Hello World
>>> type(x)
<class 'NoneType'>The distinction matters because return and print can look like they are doing the same thing — right up until the result is used in further computation:
>>> def f(x, y):
... print(x+y)
>>> x = f(2, 3)
5
>>> y = f(3, 4)
7
>>> x + y
TypeError: unsupported operand type(s) for +: 'NoneType' and 'NoneType'.Compare with the use of return:
>>> def f(x, y):
... return x + y
>>> x = f(2, 3)
>>> y = f(3, 4)
>>> x + y
12return is a reserved word, not a function — so we write
>>> def f(x, y):
... return x + yand not
>>> def f(x, y):
... return(x + y)Type hints
Type hints annotate the expected type of each parameter and of the return value. In mathematics we would define a mapping \(\text{triangle\_area} : \mathbb{R} \times \mathbb{R} \times \mathbb{R} \to \mathbb{R}\); in Python we write that as:
>>> def triangle_area(a: float, b: float, c: float) -> float:
... s = (a+b+c)/2
... return (s*(s-a)*(s-b)*(s-c))**0.5
>>> triangle_area(2.2, 3.3, 4.4)
3.5147323866832307Type hints are not enforced — they are documentation for making the code more readable, nothing more. Annotating the same function with str everywhere changes nothing about how it runs:
>>> def triangle_area(a: str, b: str, c: str) -> str:
... s = (a+b+c)/2
... return (s*(s-a)*(s-b)*(s-c))**0.5
>>> triangle_area(2.2, 3.3, 4.4)
3.5147323866832307and so this is valid Python too, hints notwithstanding:
def foo(x: int, y: int) -> int:
"""
>>> foo(2, 3)
6
"""
return x
ans = foo("oi", 3)Docstrings
A docstring ("""...""" immediately under the def line) documents what a function does and its preconditions, and gives example calls (written like REPL input/output) that double as tests — see python-testing:
>>> def triangle_area(a: float, b: float, c: float) -> float:
... """
... Return the area of the triangle with sides length <a>,
... <b>, and <c>.
... Preconditions: <a>, <b>, <c> are all nonzero positive.
... >>> triangle_area(3, 4, 5)
... 6.0
... """
... s = (a+b+c)/2
... return (s*(s-a)*(s-b)*(s-c))**0.5Inside a docstring the course refers to a parameter by its name in angle brackets, <a>.
General template
def function_name(arg0: type, arg1: type, ...) -> type:
"""
Short description of function for documentation.
Preconditions (if any).
>>> function_name(x, y, ...)
expected output
"""
...
function body
...
returnWorked question — a function that computes but never returns
A function that computes a value but never returns it still hands back None. What is the type of foo’s return value?
def foo(radius: int):
"""
Precondition: radius > 0
"""
area = 3.14159 * radius**2NoneType. There is no explicit return statement, so the computed area is simply discarded when the call ends.
See python-pep8-style-guide for the naming, spacing, and line-length conventions used when writing functions like this.
Python If Statements
Definition (if-statement). Given a condition \(C\) — i.e. a predicate that evaluates to
TrueorFalse, see python-boolean-logic — an if-statement is a control structure that executes a block of code when \(C\) isTrue(and skips it otherwise).
The four flowcharts use one vocabulary: a pale pink diamond for the condition, a pale blue rectangle for a block of code, and black arrows labelled True / False.
Red is used on only two of the four. In the two chain figures the last False edge — the one taken when every condition has failed — is red, arrow and label both. The single-if bypass and the else edge of a plain if-else are the same “the condition was false” edge and are black. So red marks the end of a chain here, not falsity in general.
If-then
if <cond>:
<code executed when cond == True>
...In Python spaces matter — only code indented within the if-statement gets executed. Everything else carries on regardless.
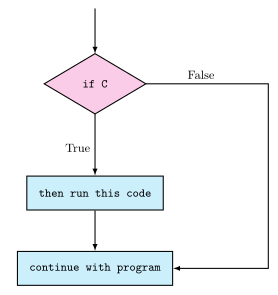
Figure 68: The if-then control structure. The True branch drops into the guarded block; the False branch bypasses it entirely and rejoins the program at the same place, which is why an if-statement can only ever skip code, never choose between alternatives.
Because of truthiness, the condition doesn’t need to literally be True/False. The two pairs below are the same code with a literal and then with a variable in the condition slot:
>>> x = 0 >>> x = 0
>>> if False: >>> if x:
... x = x + 1 ... x = x + 1
>>> x >>> x
0 0
>>> x = 0 >>> x = 1
>>> if True: >>> if x:
... x = x + 1 ... x = x + 1
>>> x >>> x
1 2Warning. A variable only assigned inside an if-block does not exist if the condition was false — the code in the if-statement is skipped, and therefore ans never gets set:
>>> if False:
... ans = 0
>>> ans
NameError: name 'ans' is not definedTwo ifs are not two branches
Successive independent ifs both get tested, so more than one of them can fire. With print that means two lines of output:
>>> def foo(x):
... if x > 0:
... print("Positive")
... if x > 10**5:
... print("Large positive")
>>> ans = foo(10**6)
Positive
Large positive
>>> type(ans)
<class 'NoneType'>Swap the prints for returns and the behaviour changes completely, because return exits the function on the spot (see python-functions) — the second if is never even reached:
>>> def bar(x):
... if x > 0:
... return "Positive"
... if x > 10**5:
... return "Large positive"
>>> ans = bar(10**6)
>>> type(ans)
<class 'str'>
>>> ans
'Positive'If-then-else
Writing two complementary ifs makes the code longer and checks the condition twice:
>>> if balance >= 0:
... in_the_black = True
... in_the_red = False
>>> if balance < 0:
... in_the_black = False
... int_the_red = Trueelse collapses that into one test:
if <cond>:
<code>
else:
<code>>>> if balance >= 0:
... in_the_black = True
... in_the_red = False
... else:
... in_the_black = False
... int_the_red = Trueif-else does not allow you to skip code — it lets you pick between two instruction sets.
int_the_red on the last line of both versions is a typo for in_the_red.
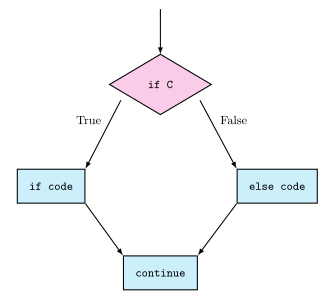
Figure 69: The if-then-else control structure. Unlike Figure 68 there is no bypass edge: every path through the diamond runs exactly one of the two blocks before the branches rejoin.
Elif chains
if <cond0>:
<code>
elif <cond1>:
<code>
...
elif <condN>:
<code>Each elif condition is only checked if every condition above it was False — so later branches can safely assume the earlier conditions failed. If all of them fail, nothing runs at all.
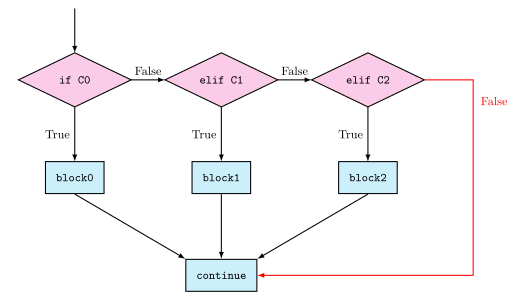
Figure 70: An if/elif/elif chain. Each False edge feeds sideways into the next test, so at most one block runs; the red edge is the path taken when every condition is False, and it runs no block at all. That red path is exactly why a variable first assigned inside such a chain can end up undefined.
Common bug: overlapping conditions in the wrong order
Because a later elif implicitly assumes the earlier ones were false, checking overlapping ranges from the loosest condition down silently picks the wrong branch:
>>> age = 60
>>> if age >= 18:
... beverage = "cheap beer"
... elif age >= 30:
... beverage = "standard beer"
... elif age >= 50:
... beverage = "expensive beer"
>>> beverage
'cheap beer'This code does not work as intended — see 2025-08-11-sequence-selection-and-iteration for the traced flowchart of exactly where age = 60 goes.
Fix 1 — bound each range explicitly. Once the ranges are disjoint the elifs are not doing any work; three plain ifs would behave identically:
>>> age = 60
>>> if 18 <= age < 30:
... beverage = "cheap beer"
... elif 30 <= age < 50:
... beverage = "standard beer"
... elif 50 <= age:
... beverage = "expensive beer"
>>> beverage
'expensive beer'Fix 2 — order the tests from the tightest condition down, and let each elif inherit the guarantee that the ones above it failed:
>>> age = 60
>>> if age >= 50:
... beverage = "expensive beer"
... elif age >= 30: # guaranteed age < 50
... beverage = "standard beer"
... elif age >= 18: # guaranteed age < 50 and age < 30
... beverage = "cheap"
>>> beverage
'expensive beer'Still no catch-all
Fix 2 is correct for adults and silently broken for everyone else — with no branch taken, beverage is never assigned:
>>> age = 9
>>> if age >= 50:
... beverage = "expensive beer"
... elif age >= 30:
... beverage = "standard beer"
... elif age >= 18:
... beverage = "cheap"
>>> beverage
NameError: name 'beverage' is not definedIf-elif-else
if <cond0>:
<code>
elif <cond1>:
<code>
...
elif <condN>:
<code>
else:
<code>else is the catch-all: it runs whenever none of the preceding if/elif conditions were True, which closes off the NameError above.
>>> age = 9
>>> if age >= 50:
... beverage = "expensive beer"
... elif age >= 30:
... beverage = "standard beer"
... elif age >= 18:
... beverage = "cheap"
... else:
... beverage = "apple juice"
>>> beverage
'apple juice'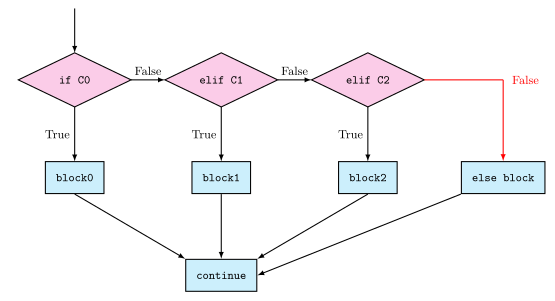
Figure 71: The same chain with an else. Compare with Figure 70: the red all-false edge no longer runs straight to the join, it runs into a block. That single structural difference is the whole of the NameError-versus-apple-juice contrast above.
Factoring and refactoring
Definition (factoring). In computer science factoring means breaking a complex problem into parts that are easier to conceive, understand, program, and maintain.
Definition (refactoring). Code refactoring is the process of restructuring existing computer code — changing the factoring — without changing its behaviour.
Simplifying if-statements
Nested ifs with no other body collapse into a single anded condition:
if x>1: if x>1 and y>2 and z>3:
if y>2: ==> print("hello")
if z>3:
print("hello")An if/else that only returns True/False can be replaced by the condition itself — the condition is already a boolean:
def foo(x): def foo(x):
if x > 0: ==> return x > 0
return True
else:
return FalseThe same for an if/else that only assigns:
if x > 0: y = x > 0
y = True ==>
else:
y = FalseAnd comparing a condition to True/False is redundant:
if x > y == True: ==> if x > y:
if x > y == False: ==> if not x > y:elif can drop what the previous condition already ruled out
These two blocks are equivalent, because reaching the elif already guarantees x <= 0:
>>> if x > 0: >>> if x > 0:
... print("A") ... print("A")
... elif x <= 0 and x % 2 == 0: ... elif x % 2 == 0:
... print("B") ... print("B")These two are not, because the second if is independent of the one before it and does not know it already ran:
>>> if x > 0: >>> if x > 0:
... print("A") ... print("A")
>>> if x <= 0 and x % 2 == 0: >>> if x % 2 == 0:
... print("B") ... print("B")Let x = 2. The first block prints A; the second prints A and B.
Common errors
or does not distribute over bare values. The following will always print:
>>> if x == 1 or 2 or 3:
... print("hello")because it parses as (x == 1) or 2 or 3, and 2 is truthy on its own regardless of x. It is not equivalent to
>>> if x == 1 or x == 2 or x == 3:
... print("hello")which refactors to
>>> if x in [1,2,3]:
... print("hello")An empty branch is a wasted branch. This is a genuine equivalence rather than a bug, but the left-hand form is a roundabout way of writing the right-hand one:
>>> if x: >>> if not x:
... pass ... print("Hello World")
... else:
... print("Hello World")Python Inheritance
Inheritance lets a class (the subclass/child class) reuse the attributes and methods of another class (the superclass/parent class), while adding new behaviour or overriding existing behaviour. It models an “is-a” relationship (a DeliveryRobot is a Robot) — contrast with python-composition’s “has-a” relationship.
Syntax
class Parent():
# Parent class' implementation
# inherit from the Parent class
class Child(Parent):
# Child class' implementationChild inherits everything Parent defines, without naming any of it.
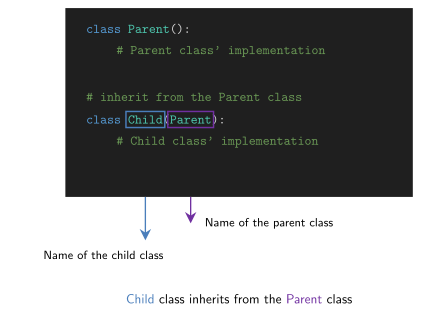
Figure 72: The class Child(Parent): line, annotated: the name being defined comes first, the name being inherited from goes in the parentheses. The box round each name, the arrow leading from it, and the matching word in the sentence beneath are all one colour: blue tracks the child and purple the parent throughout.
A subclass automatically gets all of its parent’s attributes and methods. It can:
- Add new methods/attributes that only it has.
- Override an inherited method by redefining it with the same name.
- Extend an inherited method using
super(), rather than fully replacing it.
Those three, plus plain inheritance, are the four things a subclass can do with any given member:
| The subclass… | …does this | Effect on the parent’s version |
|---|---|---|
| says nothing about the member | inherits it | used unchanged |
| declares a member the parent doesn’t have | adds it | none — the parent has no such member |
| declares a member with the same name | overrides it | shadowed; never runs for this class |
declares it and calls super() inside |
extends it | runs, plus whatever the subclass adds |
A subclass that declares no __init__ of its own uses the parent’s, so constructing it takes the parent’s arguments. Declaring one replaces the parent’s — which is why an extending __init__ almost always opens with super().__init__(...).
super()
super().method(...) calls the parent class’ version of a method — most commonly used inside an overridden __init__ to reuse the parent’s initialization logic before adding subclass-specific setup:
class DeliveryRobot(Robot):
def __init__(self, name: str, batt_level: int, load_capacity: int):
super().__init__(name, batt_level) # reuse Robot's __init__
self.load_capacity = load_capacityTerminology cheat-sheet
Given class Student(Person):
| Term | Refers to |
|---|---|
| subclass / child class | Student |
| superclass / parent class | Person |
“Student inherits from / extends Person” |
the relationship between them |
Polymorphism
Polymorphism (“many forms”) describes an interface that works across different underlying types. Built-ins like len() are polymorphic (works on strings, lists, dicts, …). Classes that share a method name (whether via a common superclass or just by convention) are also polymorphic: the same call, e.g. r.charge(), produces different behaviour depending on which actual class r is an instance of.
Which method actually runs is decided by the object, not by the calling code, and is resolved by walking up the hierarchy until the name is found: object's own class → parent → grandparent → .... A subclass that overrides the name stops that walk at itself; one that doesn’t lets it continue to the parent. Nothing in the caller has to know or ask which case it is — that is what makes a loop over a mixed list of subclasses work, and why adding another subclass later needs no change to the loop.
When to use inheritance
Only when there’s a genuine “is-a” relationship between the two classes. If the relationship is really “has-a” (one object contains or uses another), prefer python-composition instead. See 2025-09-23-inheritance for the worked Robot hierarchy and 2025-09-23-composition for the DroneFlight counter-example.
Abstract base classes
An abstract base class doesn’t provide concrete implementations for some/all of its methods — it just defines the interface that every concrete subclass must implement. You’re not meant to instantiate the abstract class directly.
The simplest (unenforced) version just raises an error from each method that subclasses must override:
class Shape:
def area(self) -> float:
raise NotImplementedError("Subclasses must implement area()")This only fails when the unimplemented method is actually called — Shape() itself still succeeds. The standard-library abc module enforces this properly, raising TypeError at the point of instantiation:
from abc import ABC, abstractmethod
class Shape(ABC):
@abstractmethod
def area(self) -> float:
...
# concrete helpers are still allowed alongside abstract methods
def describe(self) -> str:
return f"{self.__class__.__name__}"With ABC, Shape() raises immediately: TypeError: Can't instantiate abstract class Shape with abstract methods area.
Method Resolution Order (MRO)
When a class inherits from multiple parents (or a chain of parents) that define the same method/attribute name, Python needs a deterministic rule for which one wins. That rule is the Method Resolution Order (MRO) — the order Python searches through classes to resolve a name on an object. It’s stored on the class as cls.__mro__ (or cls.mro()).
Python’s inheritance models
- Single inheritance:
class B(A):— one parent. - Multilevel inheritance:
class C(B):(whereBitself inherits fromA) — a linear chain; the MRO just follows the chain upward. - Hierarchical inheritance: multiple children (
B,D, …) inherit from the same parentA. - Multiple inheritance:
class E(B, D):— a class inherits from more than one parent directly.
The diamond problem and C3 linearisation
If E(B, D) and both B and D inherit from A, which version of A’s methods should E use? Python resolves this with C3 linearisation:
- Child classes are checked before parents.
- Parents are checked in the order they’re listed in the class definition.
- If a class would appear more than once, only its last occurrence is kept.
>>> class E(B, D): pass
>>> [cls.__name__ for cls in E.__mro__]
['E', 'B', 'D', 'A', 'object']Each attribute/method name is resolved independently by walking this list and taking the first class that defines it — so two different method calls on the same object can effectively “come from” two different classes in the hierarchy.
super() follows the MRO
super() doesn’t call the immediate parent named in the class statement — it calls the next class after the current one in the instance’s actual MRO. This is what makes cooperative multiple inheritance work: as long as every class in the chain calls super(), a single call can ripple through every class in the MRO exactly once, in order.
class A:
def ping(self): print("A")
class B(A):
def ping(self): print("B"); super().ping()
class C(A):
def ping(self): print("C"); super().ping()
class D(B, C):
def ping(self): print("D"); super().ping()>>> D().ping()
D
B
C
AIf any class in the chain omits its super() call, the chain simply stops there for that call — the MRO itself doesn’t change (it’s purely a function of the class hierarchy), but fewer methods actually get executed.
Python Lists
A list is a mutable ordered collection of elements. These elements are not necessarily of the same type. Square brackets [] are used to create lists in Python.
>>> xs = [1, "apple"]
>>> type(xs)
<class 'list'>
>>> xs[0]
1
>>> xs[0] = 2*xs[1]
>>> xs[0] # note: lists are mutable
'appleapple'Comparison
Lists compare point-wise from position zero:
>>> [1, 2, 3] < [4, 5, 6]
True
>>> [7, 2, 3] < [4, 5, 6]
False
>>> [] < [1]
TrueThe second line is the one to read carefully: the comparison stops at position zero, where 7 < 4 is False, and never looks at positions one and two.
Membership
>>> 1 in [1, 2, 3]
True
>>> 0 in [1, 2, 3]
False
>>> 123 in [1, 2, 3]
False
>>> [1] in [1, 2, 3]
Falsein tests for an element, not a sub-list — the last line is False because [1, 2, 3] contains the integer 1, not the list [1].
Adding elements: append, extend, concatenation
xs + [y] creates a new list, which must be reassigned back to xs to have an effect:
>>> xs = [0, 1, 2]
>>> xs = xs + [3]
>>> xs
[0, 1, 2, 3] # "this is the original list updated"Read the comment as a statement about the value of xs, not about the object: xs = xs + [...] builds a new list and rebinds xs to it (see the aliasing transcript below), which is exactly why it breaks an alias where append does not.
Alternatively, using a method that list provides — xs.append(y) mutates xs in place:
>>> xs = [0, 1, 2]
>>> xs.append(3)
>>> xs
[0, 1, 2, 3]append adds its argument as a single new element, even when that argument is itself a list:
>>> xs = [1, 2, 3]
>>> xs.append([4,5])
>>> xs
[1, 2, 3, [4, 5]]xs.extend(ys) instead appends every element of ys individually — code similar to xs = xs + ys:
>>> xs = [1, 2, 3]
>>> xs.extend([4,5])
>>> xs
[1, 2, 3, 4, 5]Aliasing
Take care when (trying to) copy lists. Assigning one list variable to another does not copy it — both names refer to the same list object:
>>> xs = [1, 2, 3]
>>> ys = xs
>>> ys[-1] = 9
>>> ys
[1, 2, 9]
>>> xs
[1, 2, 9]Whether an operation preserves this aliasing relationship depends on whether it mutates the list in place or creates a new one:
>>> xs = [1, 2, 3]
>>> ys = xs # ys is an alias of xs
>>> xs.append(4) # appending to a list
>>> ys
[1, 2, 3, 4]
>>> xs += [5] # appending to a list
>>> ys
[1, 2, 3, 4, 5]
>>> xs = xs + [6] # concatenating two lists
>>> ys
[1, 2, 3, 4, 5] # aliasing relationship broken!The trap is that xs += [5] and xs = xs + [6] look like the same operation and are not: the first mutates the object both names share, the second builds a new object and rebinds only xs.
Figure 73: What the transcript above is doing to memory. In (a) xs and ys are two names for one list object, so the in-place operations append and += are visible through both. In (b) xs = xs + [6] builds a second list object and rebinds xs to it; ys still refers to the original, which is what aliasing relationship broken means. The layout is Python Tutor’s: frames on the left in pale blue, objects on the right in pale yellow, a reference as an arrow, and aliasing as two arrows converging on one object.
.copy() breaks the alias for a flat list:
>>> xs = [1, 2, 3]
>>> ys = xs.copy()
>>> ys[-1] = 9
>>> xs
[1, 2, 3]
>>> ys
[1, 2, 9]Passing lists to functions
A more nuanced case is when passing lists (but really list references) to functions — mutating a parameter inside a function mutates the caller’s list too:
>>> def foo(ys):
... ys[0] = -100
>>> xs = [1, 2, 3]
>>> foo(xs)
>>> xs
[-100, 2, 3]This is the same picture as (a) in Figure 73, with ys being a name in foo’s frame rather than the global one.
Nested lists and matrices
A list can have another list as an element:
>>> xs = [ [1,2], [5,6,7] ]
>>> len(xs)
2
>>> len(xs[-1])
3len counts the outer elements — two, not five.
A matrix can therefore be represented by a list-of-lists in Python:
\[\mathbb{A} = \begin{bmatrix} 1 & 2 & 3 \\ 4 & 5 & 6 \\ 7 & 8 & 9 \end{bmatrix} \equiv \texttt{[[1, 2, 3], [4, 5, 6], [7, 8, 9]]}\]
>>> ass = [[1, 2, 3], [4, 5, 6], [7, 8, 9]]
>>> ass[-1]
[7, 8, 9]
>>> ass[1:3]
[[4, 5, 6], [7, 8, 9]]
>>> ass[1]
[4, 5, 6]
>>> ass[1][-1]
6
>>> ass[1,-1]
TypeError: list indices must be integers or slices, not tupleThe last line is the one worth remembering: a nested list is indexed with repeated brackets, ass[1][-1]. The comma form ass[1,-1] is a tuple and is a TypeError for a list.
Deep copying
.copy() only performs a shallow copy — nested mutable elements (like inner lists) are still shared between the original and the copy:
>>> ass = [[1, 2, 3], [4, 5, 6], [7, 8, 9]]
>>> bss = ass.copy()
>>> bss[0][0] = 0
>>> bss
[[0, 2, 3], [4, 5, 6], [7, 8, 9]]
>>> ass
[[0, 2, 3], [4, 5, 6], [7, 8, 9]] # A was changed!
Figure 74: Why ass changed. bss = ass.copy() made a genuinely new outer list — that is why bss and ass are two distinct objects — but it copied the outer list’s three references, not the objects they point at, so both outer lists share the same three inner lists. Writing bss[0][0] = 0 reaches through a shared reference and the change shows up through ass as well. For this to work as expected we need a deep-copy, which is not built-in — see copy.deepcopy. Magenta marks the mutated cell.
A true independent copy of nested structures needs a deep copy, which is not built into list — see copy.deepcopy.
Slicing
>>> xs = [0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
>>> xs[3:6]
[3, 4, 5]
>>> xs[::2]
[0, 2, 4, 6, 8]
>>> xs[7:2:-2]
[7, 5, 3]The three fields are start:stop:step with stop exclusive: xs[3:6] takes positions 3, 4 and 5; xs[::2] takes every second element of the whole list; and a negative step makes xs[7:2:-2] walk backwards from position 7, stopping before position 2.
Type hints
Warning. Type-hinting lists (e.g.
list[int]) is a new feature in Python 3.9 and greater.
Unpacking into function arguments
It is possible to “unbracket” a list when passing it to functions, with *:
>>> def f(x, y, z):
... return x + y + z
>>> x = [1, 2, 3]
>>> f(x)
TypeError: f() missing 2 required positional arguments: 'y' and 'z'
>>> f(*x)
6Tuples
Tuples are immutable ordered collections whereas lists are mutable ordered collections. Both can be sliced and indexed. See python-primitive-data-types; a tuple’s immutability is what makes it usable as a dictionary key, where a list is not — see python-dictionaries.
Python Operator Precedence and Associativity
Syntax vs. semantics
Each construct below has two parts, and it is worth keeping them apart:
- Syntax — what makes the expression a valid Python program.
- Semantics — what the expression evaluates to.
A syntax rule is always of the form “if x and y are valid Python expressions, then this is a valid Python expression” — which is what makes arbitrarily long arithmetic legal without a separate rule for every length. Precedence and associativity do not take this shape; they are plain rules.
Constants and brackets
- A constant (e.g.
2) is the most basic expression. - If
xis a valid expression then(x)is also a valid expression — bracketed expressions get evaluated first. Whitespace inside brackets is ignored, and brackets can nest arbitrarily (((2))). - An unmatched closing bracket (
2)) is aSyntaxError.
Negation and affirmation
- If
xis a valid expression then+xand-xare valid expressions. +xis equivalent to multiplyingxby1;-xis equivalent to multiplyingxby-1.- These can be chained (
--3is3,+-+-+-3is-3), but a trailing operator with nothing after it (3+) is aSyntaxError. - Style: write
3 + -3rather than3 + - 3, and2 - -2rather than2 - - 2— group the sign with the number it belongs to.
Arithmetic operators
If x and y are valid expressions, then all of the following are valid expressions, evaluated according to the rules of math:
| Operator | Meaning |
|---|---|
x + y |
Addition |
x - y |
Subtraction |
x * y |
Multiplication |
x / y |
Division |
x // y |
Integer (floor) division |
x % y |
Remainder |
x ** y |
Exponentiation |
Order of operations
1 + 2 * 3 + 4 evaluates to 11, not 13, so * must happen before +. Without an order of operations that expression is ambiguous.
From highest to lowest precedence:
| Operator | Description |
|---|---|
() |
Parenthesis |
** |
Exponents |
-x, +x |
Negation, Affirmation |
*, /, //, % |
Multiplication, Division, Integer Division, Remainder |
+, - |
Addition, Subtraction |
Two consequences of the middle row that catch people out: exponentiation outranks unary minus, and unary minus outranks multiplication. So 2 * -3 is 2 * (-3) = -6, and 1 - -2 * -3 - 4 is 1 - ((-2) * (-3)) - 4 = -9.
*, /, //, and % share a precedence level, as do + and - — so the table by itself still leaves ties. See Associativity below.
Associativity
An order of operations alone doesn’t remove all ambiguity — e.g. 1 - 2 + 3 needs a rule for whether it means (1 - 2) + 3 or 1 - (2 + 3). Python evaluates 1 - 2 + 3 as 2, matching (1 - 2) + 3 rather than 1 - (2 + 3) = -4, so +/- are left-associative.
Operators of equal precedence are left-associative in general, except exponentiation (**), which is right-associative:
3 * 1 // 2=(3 * 1) // 2=1, whereas3 * (1 // 2)=0(left-associative*///)2 ** 1 ** 0=2 ** (1 ** 0)=2, whereas(2 ** 1) ** 0=1(right-associative**)
In general, if # and @ are operators of equal precedence, a # b @ c = (a # b) @ c (left-associative case).
Putting both rules on one expression
The exam question x = 35 * 2 % 5 ** 2 needs precedence and associativity to settle, which is why it is the one worth working slowly.
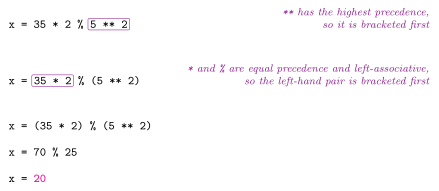
Figure 75: Fully bracketing x = 35 * 2 % 5 ** 2, one rule at a time, to reach (35 * 2) % (5 ** 2) = 70 % 25 = 20. Each step boxes the tokens it brackets and names the rule in purple on the right; magenta marks the answer. Step one is precedence: ** outranks everything else present. Step two is associativity: * and % sit on the same row of the table, so the tie is broken left-first. After that no choices remain.
The other exam question resolves by precedence alone: 2 ** 3 % 5 - 1 is ((2 ** 3) % 5) - 1 = (8 % 5) - 1 = 3 - 1 = 2.
The tempting wrong answers to 35 * 2 % 5 ** 2 (0, 140 and 70) are a good check on the table. Evaluating strictly left to right, ignoring precedence altogether, gives ((35 * 2) % 5) ** 2 = 0 ** 2 = 0. Letting % bind first, then **, and leaving * until last gives 35 * ((2 % 5) ** 2) = 35 * 4 = 140. And 70 is just 35 * 2 with the rest of the expression dropped.
Division and floats
/always returns afloat, even when the division is exact (4 / 2is2.0, not2) —type(2)isint,type(2.0)isfloat.1 / 3gives an approximate result (0.3333333333333333) since floats have finite precision.1 / 0raisesZeroDivisionError;1 / float('inf')is0.0.6 / 2 * (1 + 2)is9.0— brackets first, then/and*left to right, and the/makes the whole result a float.
Exponentiation edge cases
2 ** 3is8(int);2 ** 3.0is8.0(float) — a float exponent/base produces a float result.2 ** -1is0.5.2 ** 0and0 ** 0are both1.
Warning: ^ is not exponentiation
The caret ^ is Python’s bit-wise xor operator, not exponentiation — e.g. 2 ^ 3 is 1 and 4 ^ 1 is 5. Using ^ where you meant ** does not raise an error, so this mistake can silently produce wrong results.
Integer division (the division algorithm)
For positive integers x and y, there is a unique quotient q and remainder r (with 0 <= r < y) satisfying x = q * y + r — “grade school” division. E.g. for x = 17, y = 3: 17 = 5 * 3 + 2, so 17 // 3 is 5 (the quotient) and 17 % 3 is 2 (the remainder), and 3 * (17 // 3) + (17 % 3) == 17.
The division algorithm can be computed directly (repeated subtraction) or recursively:
def remainder(x: int, y: int) -> int:
ans = x
while ans >= y:
ans = ans - y
return ansdef remainder(x: int, y: int) -> int:
return x if x < y else remainder(x - y, y)Both give remainder(17, 7) == 3. They are previews of python-while-loops and python-recursion.
Python PEP8 Style Guide
PEP stands for Python Enhancement Proposal. A PEP is a design document providing information on how to style our code. This course follows Google’s PEP, which is a variant of PEP8. Give it a browse.
Variable and function names
Names must start with a letter and must not include special characters excepting the underscore _.
Function and variable names should be lowercase, with words separated by underscores as necessary to improve readability:
| Yes | No |
|---|---|
descriptive_variable_name |
DescriptiveVariableName |
Spacing
Put single spaces around the loosest-binding operators in an expression and close up the tighter ones, so the spacing mirrors the precedence. A bracketed subexpression is treated as an atom whose interior is closed up.
| Yes | No |
|---|---|
i = i + 1 |
i=i+1 |
x = x*2 - 1 |
x = x * 2 - 1 |
hypot2 = x*x + y*y |
hypot2 = x * x + y * y |
c = (a+b) * (a-b) |
c = (a + b) * (a - b) |
Breaking long computation
According to PEP8 all lines must be strictly less than 80 characters wide.
>>> income = (gross_wages
... + taxable_interest
... + (dividends - qualified_dividends)
... - ira_deduction
... - student_loan_interest)The redundant bracket that encloses the entire expression is what enables the expression to be broken across multiple lines — usually, hitting enter would evaluate the expression instead.
Python Primitive Data Types
The types “built-in” to Python by default are called primitive data: booleans, integers, floats, strings, and tuples. All of them are immutable — once created, an object of one of these types cannot be changed.
Booleans
The boolean type provides, comprehensively, the values True and False:
>>> type(True)
<class 'bool'>
>>> type(False)
<class 'bool'>Comparison operators
Having a boolean type is what makes comparison operators useful — they return a true/false answer:
>>> 3 == 9
False
>>> 3 > 7
False
>>> 3 >= 7
FalseAll comparison operators have equivalent precedence and are left associative; when mixed with arithmetic, comparison is evaluated last (see python-operator-precedence-and-associativity).
| Operator | Description |
|---|---|
== |
Equal |
!= |
Not equal |
<, <= |
Less than, less than or equal |
>, >= |
Greater than, greater than or equal |
>>> 3 + 2 > 1 + 3 # arithmetic first
True
>>> 3+2 > 1+3 # better to group like this
True
>>> 3 + (2>1) + 3 # True has int value 1
7Logical connectors
Functions that return booleans are called predicates, and are (very) important to programming. More sophisticated predicates are built with the logical connectors and, or, and not — covered in detail in 2025-08-11-sequence-selection-and-iteration and python-boolean-logic.
bool — truthy / falsy
Any object can be converted to a boolean with bool. Data that converts to True is truthy; data that converts to False is falsy. Usually the falsy element is whatever acts as zero in the type, and everything else is truthy.
>>> bool(0)
False
>>> bool(1)
TrueIntegers
Definition (Integer). An integer is a number without a fractional part. It can be zero, positive, or negative.
Integers are unbounded in Python: we can work with integers of arbitrary size without worrying about overflow, which is not typical of programming languages.
>>> 2 ** 256 - 1
115792089237316195423570985008687907853269984665640564039457584007913129639935Any object can be converted to an integer with int. True behaves as 1 and False as 0, so booleans can be used in arithmetic:
>>> int(True)
1
>>> int(False)
0
>>> True + False
1
>>> True * False
0Strings
Definition (String). Anything (with some exceptions) enclosed by single-quotes
' 'or double-quotes" "is considered a string by Python. A string is an ordered collection of the characters (e.g. unicode and ascii) allowed by the computer.
The quotes are what make it a string; without them the same text is either a syntax error or a name:
>>> "hello world"
'hello world'
>>> type("hello world")
<class 'str'>
>>> hello world # note the lack of quotes
SyntaxError: invalid syntax
>>> hello # note the lack of quotes
NameError: name 'hello' is not definedstr conversion and formatting
Any object can be converted to a string with str:
>>> str(1)
'1'
>>> str(True)
'True'
>>> str("Hello")
'Hello'Substitution converts values into strings inside a sentence, using the string formatter — an f before the quotes, and {} around each expression to substitute:
>>> x = 1
>>> y = "two"
>>> z = f"x is {x} y is {y}" # formatted string
>>> z
'x is 1 y is two'
>>> print(f"x is {x} y is {y}")
x is 1 y is two
>>> f"{x}" # alternative to str
'1'Concatenation and scalar multiplication
Adding strings concatenates them — and because a string can be added to itself repeatedly, it also makes sense to multiply a string by a positive integer:
>>> "hello" + "world"
'helloworld'
>>> type(" ")
<class 'str'>
>>> space = " "
>>> "hello" + space + "world"
'hello world'
>>> "Hello World!" + "Hello World!" + "Hello World!"
'Hello World!Hello World!Hello World!'
>>> 3 * "Hello World!"
'Hello World!Hello World!Hello World!'When strings are added a new string is created — the originals are untouched, which is what immutability forces.
Comparing strings
Strings compare by character order; ord gives a character’s order and chr recovers the character from the order:
>>> "a" < "b"
True
>>> ord("a"), ord("b") # the "order" of the characters
(97, 98)
>>> chr(97) # get character from order
'a'
>>> "A" < "a"
True
>>> "Z" < "a"
TrueComparison then proceeds character-by-character, with a shorter string counting as less than any extension of itself:
>>> "a" < "aa"
True
>>> "b" < "aa"
False
>>> "aba" < "ab"
False
>>> "aZ" < "aa"
TrueExercise. Write
string_less_than(cs: str, ds: str) -> bool, returningTrueonly whencs < ds, restricting yourself to comparing integers only.string_less_than("aba", "ab")is false andstring_less_than("aZ", "aa")is true.
Escape characters
A new line is an escape character that prints whatever follows it on a new line; the escape character is \n. A tab (\t) is a fixed amount of horizontal space, though how it is displayed depends on the program doing the displaying — which is why tabs are the worst.
>>> "hello\nworld"
'hello\nworld'
>>> print("hello\nworld")
hello
world
>>> "hello\tworld"
'hello\tworld'
>>> print("hello\tworld")
hello worldA string can be stored differently than it is printed.
Numbers versus strings
+ never silently converts between int and str — mixing them is a TypeError, and you have to say which conversion you meant:
>>> 3 + 7
10
>>> "3" + "7"
'37'
>>> 3 + "7"
TypeError: unsupported operand type(s) for +: 'int' and 'str'
>>> str(3) + "7"
'37'
>>> 3 + int("7") # convert string to integer
10Converting a string to a number only works for numbers expressed with digits, and int will not take a fractional literal:
>>> int("3.14")
ValueError: invalid literal for int() with base 10: '3.14'
>>> float("123.456")
123.456
>>> int("seven")
ValueError: invalid literal for int() with base 10: 'seven'Length and inclusion
A string’s length is the number of characters that comprise it:
>>> len("h")
1
>>> len("hello")
5
>>> cs = "world"
>>> len(cs)
5
>>> len(cs+"world") == len(cs) + len("world")
TrueWe can ask whether a string is a substring of another with in:
>>> "h" in "hello world"
True
>>> "hello" in "hello world"
True
>>> cs = "world"
>>> cs in "hello world"
True
>>> "ow" in "hello world"
FalseIndexing
Because a string is ordered, we can number its characters starting from zero and access them with square brackets. We can also index from the end with negative numbers:
>>> cs = "hello world"
>>> cs[0]
'h'
>>> cs[1]
'e'
>>> cs[2]
'l'
>>> cs[len(cs)]
IndexError: string index out of range
>>> cs[-1]
'd'
>>> cs[-2]
'l'
>>> cs[-11]
'h'Slicing
A slice cs[start:stop:step] takes start inclusive through stop exclusive, moving by step. The examples use cs = "0123456789" throughout, so that each index matches the character sitting at it.
Figure 76: The string cs = '0123456789' with both index systems and four of its slices. Positive indices count from the front, negative from the back, and the two agree because a negative index \(i\) names position \(i \bmod 10\) — which is why cs[3:-1] stops at 8, one before position 9.
Omitting an endpoint defaults it to the far end in the direction of travel:
>>> cs = "0123456789"
>>> cs[1:4] # 1st inclusive through 4th exclusive
'123'
>>> cs[0:9]
'012345678'
>>> cs[0:10]
'0123456789'
>>> cs[0:] # omitting the right endpoint defaults to the line above
'0123456789'
>>> cs[:-1] # omitting the left endpoint defaults to zero
'012345678'
>>> cs[:] # omitting both gives everything
'0123456789'Negative endpoints are the same positions counted from the back — read a negative index modulo the length:
>>> cs[-1] == cs[len(cs)-1]
True
>>> cs[3:-1] # consider that (-1) % 10 == 9
'345678'
>>> cs[-7:] # consider that (-7) % 10 == 3
'3456789'A step may be given third, and a negative step travels backwards:
>>> cs[::2] # increment by two, zero inclusive to ten exclusive
'02468'
>>> cs[0:10:2] # the above defaulted to this
'02468'
>>> cs[::-1] # decrement by one, ten inclusive to zero exclusive
'9876543210'
>>> cs[10::-1] # the above defaulted to this
'9876543210'
>>> cs[:10:-1] # not to this, because we are moving backwards
''Mixing all three, forwards and backwards:
>>> cs[1:-3:3] # increment by three, one inclusive to seven exclusive
'14'
>>> cs[-8:-2:2] # increment by two, two inclusive to eight exclusive
'246'
>>> cs[-8:-2:-4] # decrement by four, two inclusive to eight exclusive
''
>>> cs[::-4] # decrement by four, ten inclusive to zero exclusive
'951'Immutability
Something is immutable when it cannot be changed. Strings are immutable — so a word cannot be capitalised by writing over its first character:
>>> cs = "hello"
>>> cs[0] = "H"
TypeError: 'str' object does not support item assignmentStrings as booleans
The empty string is the falsy string; every other string is truthy. It is also “smaller” than every other character:
>>> bool("a")
True
>>> bool("Hello")
True
>>> bool("")
False
>>> "" < "A"
True
>>> "" < chr(0)
TrueA space is not the same thing as empty:
>>> space = " " # a space
>>> len(space)
1
>>> bool(space)
True
>>> empty = "" # empty string
>>> len(empty)
0
>>> bool(empty)
FalseTuples
Definition (tuple). A tuple is an immutable ordered collection of elements. These elements are not necessarily the same type and are not necessarily distinct. Round brackets
()are used to create tuples in Python.
Being ordered, tuples index and slice exactly like strings; being immutable, they refuse item assignment exactly like strings:
>>> xs = (0, 1, 2, 3, 4, 5)
>>> type(xs)
<class 'tuple'>
>>> xs[-1] # indexing
5
>>> xs[0:4] # slicing
(0, 1, 2, 3)
>>> xs[0] = -1 # immutable
TypeError: 'tuple' object does not support item assignmentTuples support the same addition and scalar multiplication as strings, and their elements can be of mixed type:
>>> xs = (1, 'a', 2, 'b') # mixed types are fine
>>> ys = (3, 'c', 4, 'd')
>>> xs + ys # tuple addition
(1, 'a', 2, 'b', 3, 'c', 4, 'd')
>>> 2*xs # tuple scalar multiplication
(1, 'a', 2, 'b', 1, 'a', 2, 'b')Nomenclature
Tuples are named by size: couple (2), triple (3), quadruple (4), quintuple (5), sextuple (6), septuple (7), octuple (8), and an n-tuple in general. The general form (0, 1, 2, ..., n-1) is not valid Python syntax — it is informal notation for the pattern.
Singleton and empty tuples
A single value in round brackets is not a tuple — brackets there are just grouping. The trailing comma is what makes a singleton:
>>> (1) + (2)
3
>>> type((1))
<class 'int'>
>>> (1)
1
>>> type((1,))
<class 'tuple'>
>>> (1,) + (2,)
(1, 2)
>>> (1) + (2,3) # common error
TypeError: unsupported operand type(s)The empty tuple is () — a genuine tuple, the identity for tuple addition, and falsy:
>>> ()
()
>>> type(())
<class 'tuple'>
>>> () + (1,)
(1,)
>>> (1,) + ()
(1,)
>>> bool(())
FalseComparing tuples
Tuples compare element-by-element, and — like strings — a shorter tuple is less than a longer tuple that extends it:
>>> (1, 2, 3) == (1, 2, 3)
True
>>> (1, 2, 3) == (1, 2)
False
>>> (1, 2, 3) < (1, 2, 4)
True
>>> (1, 2, 3) < (1, 2)
False
>>> (1, 2) < (1, 2, 3)
TruePacking and unpacking
Several names can be assigned on one line, and several values printed on one line, through an (implicit) tuple:
>>> x, y, z = 2, 3, 4 # saves vertical space
>>> x
2
>>> y
3
>>> z
4
>>> x, y, z # repl-printing several values
2, 3, 4A real REPL echoes the last line as the tuple it built, brackets included — (2, 3, 4) — which is the more useful way to read it: the right-hand side of a packing assignment is a tuple.
Python Recursion
A recursive function is a function that calls itself. Every recursion needs at least one of each:
- Base case: a case defined outright, with no further recursive call (
if base_case: return constant). - Recursive step: a line where the function calls itself on “smaller” input, making progress toward a base case.
Canonical example: factorial
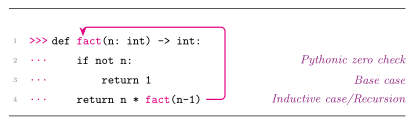
Figure 77: The anatomy of a recursive function. The purple notes on the right name each part. The two occurrences of fact are coloured magenta and joined by an arrow, to show the one thing the definition of recursion turns on: line 4 calls the function being defined on line 1.
def fact(n: int) -> int:
if not n: # base case
return 1
return n * fact(n-1) # recursive stepEvaluation has two phases:
- Winding: recursive calls build up a stack of pending computations (
4 × (3 × (2 × (1 × fact(0))))). Each call pushes an activation record; they complete last in, first out. - Unwinding: once the base case is hit, each pending computation resolves from the inside out.
See 2025-10-20-recursion for the full winding/unwinding trace of fact(4) drawn out line by line.
If a base case is never reached, the recursion bottoms out with a RecursionError: maximum recursion depth exceeded once Python’s call stack limit (1000 by default) is hit — fact(-1) does this, since n only gets more negative. The limit can be raised with sys.setrecursionlimit(n):
>>> import sys
>>> sys.setrecursionlimit(1500)Overflowing the stack and bottoming out are different bugs with the same error message. Raising the limit fixes a recursion that legitimately needs more depth than Python allows (fact(999) works once the limit is 1001); it never fixes a missing or unreachable base case (fact(-1) fails at any limit).
Choosing base cases
| Type | Typical base case |
|---|---|
int (counting down) |
0 |
list |
[] |
str |
'' (empty string) |
For less obvious base cases, take an example that makes a single recursive call and ask what the base case must be for that example to come out right. For example, \(2^k = 2 \cdot 2^{k-1}\) leaves open what “2 multiplied 0 many times” is. Since \(2^1 = 2\) and \(2^1 = 2 \cdot 2^0\), the base case must be \(2^0 = 1\).
The same advice stated the other way round: set the base cases to whatever makes the singleton case (the second-smallest one) work.
Linear vs. tree recursion
Most recursive functions make a single recursive call per invocation (linear recursion, e.g. fact, is_palindrome, increasing, sum_of_digits) and so unwind along one chain. Some make more than one (tree recursion), e.g. checking whether any sublist sums to a target:
def sublist_sum(xs: list[int], target: int) -> bool:
if not xs:
return not target
return sublist_sum(xs[1:], target-xs[0]) or sublist_sum(xs[1:], target)Two calls per invocation means \(2^n\) leaf calls for a list of \(n\) elements. See 2025-10-20-recursion for the call tree drawn out, and for the other branching examples (num_paths, lcs, hanoi, naive fib).
Tree recursion can recompute the same subproblem many times. Dynamic programming — caching previous results — avoids this when subproblems overlap heavily (the classic example being naive recursive Fibonacci, which is exponential without a cache but linear with one). Here the cache is a module-level dict seeded with the base cases:
fib_cache = {0: 1, 1: 1}
def fib(n: int) -> int:
global fib_cache
if n in fib_cache:
return fib_cache[n]
fib_cache[n] = fib(n-1) + fib(n-2)
return fib_cache[n]Relationship to induction
Recursion is essentially the Principle of Mathematical Induction realised as code: a base case (the \(P(0)\) case) plus a step that reduces a general case to a smaller one already known to work (the \(P(n) \implies P(\text{succ}(n))\) step). The recursive call is the appeal to the induction hypothesis — which is easiest to see in the Towers of Hanoi proof, where the hypothesis is used twice and the code makes exactly two recursive calls.
See python-scope for how local variables/recursive calls interact with scope, and python-composition/python-inheritance for other structuring tools. See towers-of-hanoi for a worked induction/recursion example, and algorithmic-complexity for the vocabulary that makes “exponential without a cache, linear with one” precise — merge sort and quick sort in sorting-algorithms are both recursive.
Python Representation Invariants
A representation invariant is a condition or property that must remain true about an object’s internal state throughout its lifetime. They’re primarily a development-time tool: they help catch bugs early, simplify method implementations (since you can assume a valid starting state), and document the assumptions a class relies on.
See 2025-09-16-representation-invariants for the lecture note.
Documenting invariants
State invariants in the class docstring, underneath its attributes:
class Fraction():
"""Represents a mathematical fraction.
Representation Invariants:
- denominator != 0
- if fraction is zero, it is represented as 0/1
- if fraction is negative, numerator is negative
"""A good invariant is a checkable statement about the stored attributes — something a method could evaluate and get True or False from. “The denominator is not zero” is an invariant; “this class models fractions” is not.
Establishing vs. checking
There are two ways to make an invariant hold, and they are easy to confuse:
- Establish it — normalise the input so the property is true by construction, e.g.
if denom < 0: numer, denom = -numer, -denom. - Check it — assert the property and fail if the caller got it wrong, e.g.
assert denom > 0.
Fraction uses both, on different invariants. Centralising all the checks in _check_invariants() pushes you toward the second style: the method can only report, not repair, so anything you want normalised has to be normalised before it is called.
Enforcing invariants
Assertions
assert <condition that should be true>, "message if it's not"- Raises
AssertionErrorif the condition is false. - Disabled when Python is run with optimization (
python -O) — so asserts should catch bugs, not perform real input validation that must always run (useraise ValueError(...)etc. for that).
assert for bugs, raise for callers
The distinction matters enough that DroneFlight uses both in one class:
def _check_invariants(self) -> None:
assert 0.0 <= self._altitude <= self._MAX_ALT, "Altitude out of range."
def set_altitude(self, value: float) -> None:
if not isinstance(value, (int, float)):
raise TypeError("Altitude must be a number.")
if not 0.0 <= value <= self._MAX_ALT:
raise ValueError(f"Altitude must be 0-{self._MAX_ALT} m.")
self._altitude = float(value)
self._check_invariants()_check_invariants() asks “is my own code still correct?” — a false answer is a bug, and it is fine for that check to disappear under -O. set_altitude() asks “did the caller hand me something usable?” — a false answer is expected behaviour, and it must keep raising in production. See python-exceptions for the exception types.
The _check_invariants() helper pattern
Centralise all invariant checks in one private method, and call it:
- At the end of
__init__. - At the end of any method that mutates state.
- At the start of any method that relies on the invariants already holding.
def _check_invariants(self) -> None:
assert self._denom != 0, "Denominator cannot be zero."
...Two habits that keep the number of call sites small:
- Route every mutation through one setter. If
ascend()andland()both callset_altitude()instead of assigningself._altitudedirectly, the range check lives in exactly one place. - Put the limits in class constants.
_ID_LEN = 6and_MAX_ALT = 120.0on the class body give the rule one home, so the assertion and the error message change together when the limit does. Only the code that actually reads the constant is protected, though:DroneFlightstill hard-codes0 ≤ _altitude ≤ 120in its docstring, and interpolating the constant into the message turns it into0-120.0 m, so the wording drifts from the docstring anyway. See 2025-09-16-representation-invariants for that mismatch.
Encapsulation: don’t expose mutable internals
Returning a direct reference to a private mutable attribute (like a list or dict) lets external code silently violate the class’s invariants:
def get_members(self): # BAD -- exposes the real list
return self._members
def get_members(self): # GOOD -- caller gets an independent copy
return list(self._members)This is the aliasing behaviour of python-lists showing up inside a class: the getter hands out a second name for the same list object, so the caller’s append mutates the object’s state without any of its methods running — and therefore without any assertion getting a chance to fire.
Best practices
- Document invariants in docstrings.
- Centralise invariant checking in a single method.
- Don’t expose methods/attributes that could let external code violate invariants.
- Write test cases that target edge cases (see python-testing).
- Type hints can express some invariants, but not all (e.g. numeric ranges still need explicit checks).
- Balance strictness with practicality — not every property needs an assertion.
Python Scope
The scope of a name is the region of code where that name is recognized (i.e. accessible/visible). Python resolves names using the LEGB rule, searching in order:
- Local — the current function.
- Enclosing — an outer function, for nested functions.
- Global — the module’s top-level variables.
- Built-in — Python’s built-in names.
If a name isn’t found at any level, Python raises a NameError.
Introduced in 2025-09-09-scope (Lecture 7B), which also draws the LEGB cascade and the course’s global/local scope boxes.
Global variables
Defined outside any function (module level); accessible everywhere in the module provided no local variable shadows the name. Avoid globals where possible — they make code harder to maintain.
Constants are conventionally named in SNAKE_CASE_CAPS (PI, GRID_SIZE, NUMBER_OF_DAYS_IN_WEEK), but unlike in other languages Python does not protect their value: a constant can simply be reassigned at run-time.
Local variables and shadowing
Assigning to a name anywhere inside a function body makes that name local to the entire function — even before the assignment line executes. So does taking it as a parameter. This causes two common gotchas:
- Shadowing: a local variable (or parameter) with the same name as a global temporarily hides the global inside that function. The global itself is untouched — it still holds its old value after the call returns.
UnboundLocalError: if a function reads a name before assigning to it, and also assigns to that same name later in its body, Python treats it as local throughout — so the read fails, because the local doesn’t have a value yet.
The global keyword
Declares that a name inside a function refers to the module-level variable, rather than creating a local shadow:
def foo():
global x
x = x + 1- It is good practice to declare a global explicitly wherever a function writes to one.
- A name cannot be declared as both a function parameter and
globalin the same function — that is aSyntaxError(“name ‘x’ is parameter and global”). - Declaring
global xdoes not by itself createxat module level. The name only comes into existence when the assignment actually runs, i.e. when the function is invoked — until then, readingxat the prompt is still aNameError. - Globals and locals mix freely in one expression:
def foo(y): return x*yreadsxglobally andylocally.
Python String Methods
Strings are objects with built-in methods — callable via obj.method() syntax, unlike free functions. The receiver goes before the dot, and the parentheses are required even with no arguments: capitalize("hello") is a NameError, "hello".capitalize() is 'Hello'.
Review all of them with help(str), or a specific one with help(str.<name>). In the pager, Enter scrolls and q quits.
Reading a method’s help
Square brackets in a signature indicate optional parameters, and the rule recurses:
S.find(sub[, start[, end]]) -> intmeans sub is required, start is optional, and end is optional but only meaningful once start is given. So find("I"), find("I", 1) and find("I", 1, -1) are the three legal shapes, and find(1, -1) is not one of them.
A signature written the other way, with a default value shown, means the same thing:
center(self, width, fillchar=' ', /)self is the receiver (the string before the dot), fillchar is optional with default ' ', and the trailing / marks the end of the positional-only parameters.
Common string methods
| Method | Description |
|---|---|
s.find(sub[, start[, end]]) |
Lowest index where sub occurs in s[start:end], or -1 |
s.title() |
Title-cased version of s |
s.center(width, fillchar=' ') |
Centre s in a string of length width |
s.split(sep=None) |
Split s on sep (default: any whitespace) into a list |
sep.join(xs) |
Join a list of strings xs, placing sep between each |
s.strip(chars=None) |
Remove leading/trailing whitespace (or chars) from s |
>>> "team".find("I", 1, -1)
-1
>>> "a tale of two cities".title()
'A Tale Of Two Cities'
>>> "spam".center(10, "x")
'xxxspamxxx'
>>> "a, b, c".split(", ")
['a', 'b', 'c']
>>> "xxx".join(["A", "B", "C"])
'AxxxBxxxC'
>>> " 123 \n".strip()
'123'Three behaviours worth naming, because they are the ones that bite when processing files:
findreturns-1on failure rather than raising, so its result must be tested before it is used as an index.splitwith no argument splits on whitespace; with an argument, the argument is an arbitrary string, not a set of characters ("axbxc".split("bx")is['ax', 'c']).stripcounts\nas whitespace, which is what makes it the standard way to clean a line just read from a file.
split and join are inverses — via the separator
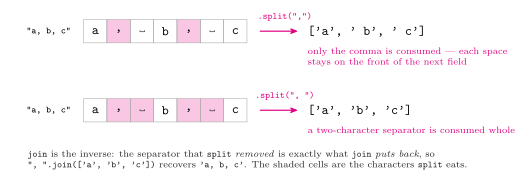
Figure 78: Which characters split actually removes, on a CSV-style example (splitting on a comma is useful for CSV processing). The separator is consumed, so splitting on a comma alone leaves each following space attached to the next field, and splitting on comma-space eats both, which removes the leading spaces. join is the exact inverse: it puts back between elements whatever split took out. The shaded cells are the characters split consumes.
center does not always split the padding evenly
center(width, fillchar) pads s out to width characters. When width - len(s) is odd the padding cannot be halved, and the extra fill character goes on the right:
>>> 'spam'.center(10, 'x') # 10 - 4 = 6, split 3 / 3
'xxxspamxxx'
>>> '101'.center(20, 'x') # 20 - 3 = 17, split 8 / 9
'xxxxxxxx101xxxxxxxxx'See 2025-09-01-string-methods for a drawing of both cases.
Python Testing (doctest & Assertions)
This is the reference note for testing in CSSE1001. 2025-09-01-testing (Lecture 6C) develops it end to end. Two things it leans on come from 2025-09-01-string-methods (Lecture 6A) and 2025-09-01-file-io (Lecture 6B): the REPL transcript, which is the form a doctest is written in, and the file pointer, which is what makes file-reading functions awkward to test. Both are drawn below. Drawing conventions follow csse1001-diagram-notation.
doctest
A docstring test is an >>> example embedded in a function’s docstring. doctest.testmod() actually runs every such example in the current module and reports failures:
>>> import doctest
>>> doctest.testmod()
TestResults(failed=0, attempted=2)doctest.testfile(path) instead runs every >>> example found in an arbitrary text file (useful for a test suite kept outside the functions being tested).
Nothing runs a doctest by itself — a docstring full of examples is inert documentation until testmod or testfile is called on it.
A doctest is a REPL transcript
A REPL transcript is exactly the shape a doctest takes:
>>>marks a line of input;...marks a continuation line, so an entiredefcan be typed this way;- the unprompted line(s) that follow are the expected output;
- a blank line, or the end of the docstring, ends the example.
So a literal transcript can be pasted into a docstring as it stands and becomes a test. The exceptions are transcripts that are abbreviated rather than literal (the strip example below) or that mark newlines with a pilcrow (¶). This title example is already a complete doctest:
>>> "a tale of two cities".title()
'A Tale Of Two Cities'as are the find transcript below and the split/join transcripts in 2025-09-01-string-methods.
What a doctest actually compares
doctest compares Python’s exact printed output against the expected text — not whether two values are ==. The rule underneath that is a rule about the REPL, and it has two halves.
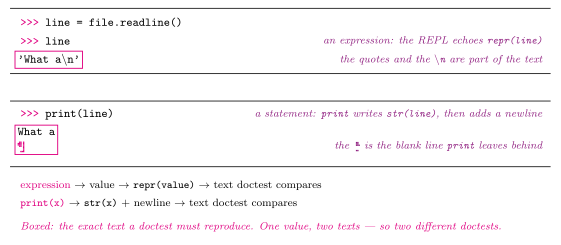
Figure 79: What text a doctest has to reproduce. Evaluating the expression line echoes its repr, 'What a\n', quote marks and newline escape included. print(line) writes the string itself and adds a newline, which leaves a blank line; the magenta pilcrow on a line of its own marks it. Each magenta box holds the exact text doctest matches, and the two arrow chains give the rule for each case.
The blank line print leaves behind cannot be written literally as expected output, because a blank line is how a doctest example ends (see the anatomy above). doctest spells it <BLANKLINE> instead. It is one more reason to prefer the echoing form.
Two practical consequences of the echo rule:
- The quote marks are part of the expected text.
"hello".capitalize()is expected to give'Hello', and the.title()example above'A Tale Of Two Cities'— with the quotes. A doctest expecting bareHellofails. - A call that returns
Noneechoes nothing at all.printis such a call: noNoneappears after the printed lines. So an example that only callsprinthas no expected-output line for the return value.
More pitfalls, all instances of the same rule:
Whitespace matters —
[ ]!=[], and Python always prints,(comma-space) inside collection literals.Unordered types (
set,dict) don’t have a guaranteed print order for non-numeric elements — compare with==inside the doctest instead of relying on printed order:>>> {3, 1, 2} == some_function({1, 2, 3}) TrueFloats are inexact — compare with a tolerance instead of exact equality:
>>> abs(f(x) - expected) < 10**-3 True
Why repr is the friendlier half for testing
Because the echo goes through repr, whitespace that is invisible when printed is visible in a doctest. That is what makes str.strip() testable at all: strip returns a copy with leading and trailing whitespace removed, and a newline counts as whitespace. Abbreviated, the example is the literal " 123 \n" on the input line and 123 on the output line, which drops both the .strip() call and the quotes. Written out as a doctest it is:
>>> " 123 \n".strip()
'123'and there the difference between ' 123 \n' and '123' is plainly on the page. Printed, the two are nearly indistinguishable.
Writing a comprehensive doctest
- Typical cases and edge cases.
- The zero of the data type (
0,[],""). - The singleton of the data type (
1,[1],"a"). - Correctness, not contract violations (don’t test precondition failures).
- No redundant tests.
Worked example: centring a word
The exercise: given a word and an integer width, centre the word in a sequence of xs. The answer is str.center, whose help text is
center(self, width, fillchar=' ', /)
Return a centered string of length width.
Padding is done using the specified fill character
(default is a space).The calls are 'spam'.center(10, 'x') and '101'.center(20, 'x'). Three transcripts of typical calls are three doctest examples already; the checklist above turns them into a suite.
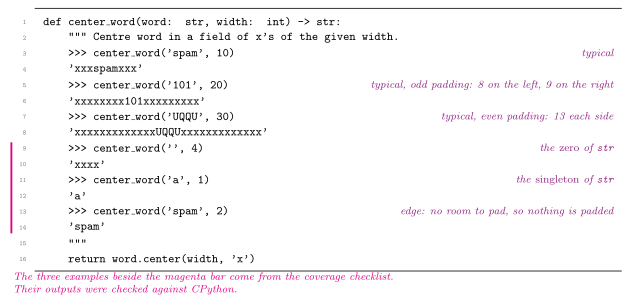
Figure 80: The centring exercise written as a doctest, with each example labelled with the job it does. The function is center_word, and its body is str.center with 'x' as the fill character. The first three examples are typical cases. The three beside the magenta bar come from the coverage checklist above: the zero, the singleton and an edge case. The whole docstring passes testmod with six attempted, zero failed.
The three typical examples might look redundant against checklist rule 5. They are not: '101' in width 20 leaves an odd amount of padding to share out, while 'spam' in 10 and 'UQQU' in 30 leave even amounts, and str.center gives the leftover character to the right-hand side. That is two different paths through the method, not one tested three times.
Implement any string method you use at least once. When you do, the built-in method is a ready-made oracle: a doctest can assert your version agrees with it, e.g. >>> my_center('spam', 10) == 'spam'.center(10, 'x') expecting True.
Optional parameters multiply the calling forms
The help text for find is
S.find(sub[, start[, end]]) -> intThe square brackets mean optional, and the rule recurses — an optional parameter can itself carry optional parameters. So the legal calling forms are exactly
"team".find("I") "team".find("I", 1) "team".find("I", 1, -1)and find(1, -1) is illegal because sub is required. Each form is a different path into the function, so a comprehensive suite needs one example per form. This transcript covers three of them plus the failure return:
>>> "hello world".find("world", 6)
6
>>> "hello hello".find("hello")
0
>>> "hello hello".find("hello", 1)
6
>>> "hello hello".find("hello", 1, 3)
-1The last line is worth its place on its own: the help text says return -1 on failure, so -1 is part of the contract, not an error condition, and a suite that never provokes it has not tested the documented behaviour.
Testing code that reads a file
The same function can be written with two different signatures, and the difference matters for testing.
def num_empty_lines(path: str) -> int: # takes a file name
ans = 0
with open(path, 'r') as file:
for line in file:
if line == '\n':
ans = ans + 1
return ansfrom typing import TextIO # takes a file pointer
def num_empty_lines(file_pointer: TextIO) -> int:
ans = 0
for line in file_pointer:
if line == '\n':
ans = ans + 1
return ansThese are different functions: the first takes a file name, the second a pointer to a file. The testing consequence follows from how the pointer behaves.
Figure 81: The file pointer walking hello.txt. A magenta pilcrow marks each newline in the file. There is no pilcrow after the last line, so that line comes back without a newline. The numbered circles are the pointer positions and the dashed lines are the line boundaries. Each readline() returns one line and moves the pointer past it. Once the pointer is at the end of the file, every further call returns the empty string.
The file-pointer version is not re-runnable. Doctest executes the examples in one docstring in order, in a single namespace, so a second call on the same handle reads an already-exhausted file:
>>> fp = open("notes.txt") # a file with two empty lines
>>> num_empty_lines(fp)
2
>>> num_empty_lines(fp)
0Both lines pass — and the second is a lie about the function. Either re-open the file for each example, or test the name-taking version, which opens the file itself and so starts from position 0 every time.
Either way, a file-reading doctest depends on the file system. A bare name is resolved relative to the directory Python is running in (see os.getcwd() and os.chdir()). So the test passes or fails depending on the working directory, and it needs a fixture file to exist. doctest.testfile is one way out: keep the suite in a text file that sits beside the fixture it reads, so the two travel together.
"w" mode from a test
A "w" open on numbers.dat creates the numbers.dat file, or overwrites the old one if it exists. A doctest that opens its own fixture with "w" destroys the fixture on the first run and then passes forever on an empty file. Use "r" to read it and "a" (which appends, and creates the file only if it is absent) if a test genuinely has to add to one.
Also prefer with in anything a test calls. An unclosed file stays open and vulnerable to side effects: some of the file may go missing, or extra bits may appear in it. with closes the file even if the program crashes while it is executing its code block, which is exactly what a failing test does.
Type hints document; only tests and assertions check
The two file-reading signatures above are a good place to see this. TextIO is the type hint for a file pointer, as in num_empty_lines(file_pointer: TextIO). Write that parameter as file_pointer: str and the function runs just the same. The highest-rated-band function in the next section can annotate its parameter as path: TextIO and then call open(path, 'r') on it, and that runs too, although the parameter is really a str path. Both annotations disagree with their own code and Python runs them anyway. Nothing in the language checks an annotation. In this material the only things that check anything at run time are the doctests you write and the assertions you place.
Assertions
assert <condition> raises AssertionError (halting the program) if <condition> is false — useful for catching impossible situations as soon as they occur, rather than letting them silently propagate:
assert ans > 0 # all factorials are positive/non-zeroassert False documents a line that should be unreachable (e.g. after an exhaustive if/else).
An assertion is the executable form of a claim you would otherwise only argue in a comment. A function that finds the highest-rated band in a file is built on exactly such a claim: it initialises
current_highest_rating = -float('inf') # Guarantees line 11 satisfiedwhere line 11 is the comparison if rating > current_highest_rating:. The comment is a piece of reasoning about program state — this starting value is below every rating the file can hold, so the first row always wins — and nothing checks it.
The same function shows what an assertion buys you. current_most_popular_band starts as "", so on a bands.txt that has only its header row the loop never runs and the function silently returns the empty string. Adding
assert current_most_popular_band != "" # the file held at least one bandbefore the return turns that silent wrong answer into an AssertionError at the point it occurs.
See python-exceptions for AssertionError among Python’s other exceptions, and python-file-io and python-string-methods for the machinery the file and string examples above use.
Python Variables and Memory Model
Memory
Computer memory is a very long series of on/off switches, called bits (short for binary digit). Eight consecutive bits form a byte; 4 or 8 bytes form a word (depending on machine architecture).
A bit is drawn as one square cell: filled black = on, white with a black outline = off. A bit string is then a horizontal row of such cells read left to right, and memory is such rows stacked vertically with an address in the left margin. Both figures below are drawn in that notation, which is collected in csse1001-diagram-notation.
We put something in memory by toggling the bits into some meaningful configuration — in Python, the “somethings” we put in memory are called objects.
Interpreting memory: the integer type
The bits alone do not say what they mean. A word of memory can be interpreted as an arithmetic expression in binary — the place value of each position is a power of two, and the number is the sum of the place values where the bit is on.
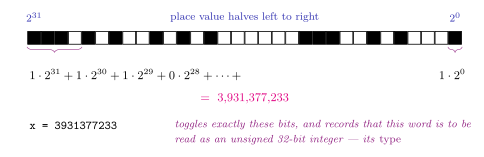
Figure 82: One word of memory read as an unsigned 32-bit integer (filled = on, empty = off). The 32 cells are exactly the binary expansion of 3,931,377,233 with the most significant bit on the left, so the positions run \(2^{31}\) down to \(2^{0}\). The assignment x = 3931377233 toggles exactly these bits and records that the word is to be read as an unsigned 32-bit integer. Nothing in the bits themselves says integer — that is what the type records.
When Python executes x = 3931377233 it toggles the bits at x’s memory location to the above and remembers to interpret that region as an unsigned 32-bit integer — its type. A value’s type ultimately dictates which functions are compatible with the object.
Addresses and id
Memory is divided into words, and each word gets an address.
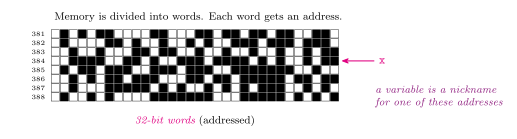
Figure 83: Memory as a stack of addressed 32-bit words, here at addresses 381–388. The bit contents are arbitrary. The magenta x and its arrow show that a variable is a nickname we give to an address in memory.
We can determine any object’s address with id:
>>> 42
42
>>> id(42)
4384160760Simply using a number gets it loaded into memory, and 4384160760 is the memory location where 42 is stored.
Variables
A variable is a nickname we give to an address in memory.
Assigning
>>> x = 3931377233
>>>Assignment toggles the bits at the memory location nicknamed x. Nothing is printed, because the imperative here is to perform an action (a state change to memory), not to evaluate an expression.
Retrieving
Once x has been assigned a value, we retrieve it by evaluating it in the REPL — a variable evaluates to the value it was assigned, and can stand in for that value inside larger expressions:
>>> x
3931377233
>>> x // 100
39313772Evaluating a name that has never been assigned raises a NameError:
>>> bear
NameError: name 'bear' is not definedMeaningful names
Variable names should convey meaning. This is not meaningful:
>>> x = 2
>>> y = 3
>>> z = x*yThese names do convey meaning:
>>> width = 2
>>> height = 3
>>> area = width*heightarea keeps working even after width and height change — another reason we use variables that can vary.
Naming rules
Variable names must start with a letter (a–z, A–Z) or underscore (_). Starting a name with a digit is a SyntaxError; digits are otherwise allowed inside a name.
>>> 1 = "one"
1 = "one"
^
SyntaxError: cannot assign to literal
>>> x1 = 1
>>>The course marks against a fuller naming style: the PEP8 rule for variables and functions is lowercase, words separated by underscores, and class names are CamelCaps. See python-pep8-style-guide.
Reassignment
= in Python means assignment, not mathematical equality. Read = as “is assigned” or “gets”:
>>> x = 1 # x "gets" 1
>>> x = x + 1 # x "gets" x+1
>>> x
2In mathematics \(x = x + 1 \implies 0 = 1\), a contradiction (\(\Rightarrow\Leftarrow\)) — so as a mathematical statement it is illegal. In Python it is perfectly ordinary, because = performs a one-time action: evaluate the right-hand side, then toggle the bits at the location x names to that result.
Because assignment is an action, the order of assignments matters — see 2025-08-04-python-memory-model for five worked examples.
Python While Loops
A loop is a control structure that repeats code that belongs to it. A while-loop is a loop that repeats code while some condition is satisfied:
while <condition>:
<code>The condition is checked before every repetition (including the first) — if it’s false to begin with, the loop body never runs at all:
>>> x = 0
>>> while False:
... print(x)
... x += 1
>>> # nothing printsSee the while-loop control-flow figure in 2025-08-18-while-loops for a picture of this.
Augmented assignment operators
| Operator | Equivalent to |
|---|---|
x += y |
x = x + y |
x *= y |
x = x * y |
x /= y |
x = x / y |
x %= y |
x = x % y |
These are the four used in the course. They are what makes an accumulator loop readable:
>>> x = 0
>>> while x < 10:
... x += 1
>>> x
10break
The break keyword terminates the (innermost) loop immediately and continues with the rest of the program — so code after it inside the loop body is unreachable:
>>> while True:
... print("hello")
... break
... print("world")
helloSimulating a do-while
A do-while (or repeat-until) is a while-loop variant available in other languages but not natively supported in Python. It runs its code at least once, because the condition is only tested after the body:
do:
<code>
while <condition> # not valid Python syntax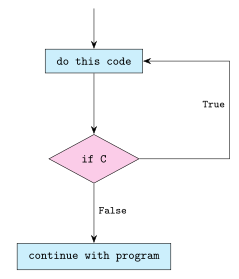
Figure 84: The do-while as a flowchart. Compare the while-loop figure in 2025-08-18-while-loops: the body is above the test rather than below it, so the body always runs once before C is ever evaluated, and the True edge is the one that loops back.
Although not natively supported in Python, we can simulate one with while True and a break (some programmers prefer 1 to True):
>>> x = 0
>>> while 1:
... x += 1
... if x > 0:
... break
>>> x # x retains its value outside the while
1x ends at 1, not 0: the body ran once before the exit test was reached, which is the whole point of the shape.
User input
x = input() waits for input from the keyboard and assigns it to x, always with type(x) is str. Numeric input therefore has to be converted — int(input("Guess: ")).
Random number generation
Random number generation is handled by an external library. It is not built-in and therefore must be imported. Importing the single command:
>>> from random import randint
>>> randint(1, 6) # chosen uniformly over the interval
2or the entire library:
>>> import random
>>> random.randint(1, 6)
2Both endpoints are included: randint(1, 6) is the course’s six-sided die, and its prompt reads Guess in [1..6].
Sorting Algorithms
Five ways to solve one problem — sorting a list. Each is derived from a different restriction: suppose the only thing you could do was X, could you still sort? Taken together they are the course’s worked example for comparing algorithms, which is what algorithmic-complexity formalises.
Sorting is also the course’s very first example of an algorithm at all (2025-07-29-a-brief-history-of-computing). The selection-sort trace below needs no code beside it: what is being expressed matters more than the language it is expressed in.
Selection sort
Suppose we could only select (find the index of) the largest element from a list.
Find the largest member of xs and make it the last element. Then find the next largest and make it the second last, and so on. After \(k\) passes the last \(k\) elements are in their final positions.
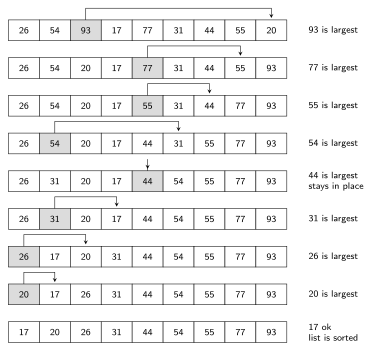
Figure 85: Selection sort on a list of nine. Each row is one pass; time runs downward. The grey cell is the largest element of the still-unsorted prefix and the arrow above the row takes it to the position it will keep, so after \(k\) rows the last \(k\) cells are final. In row five 44 is already where it belongs, so the arrow points straight down and nothing moves.
Two things the trace shows that the one-line description does not. The list of nine takes only eight passes — once the last eight are placed the first element has nowhere else to go, which is the 17 ok row. And the work is invisible in the picture: each row costs a full scan of the unsorted prefix to find its grey cell, and it is those scans, not the eight moves, that make selection sort quadratic.
Insertion sort
Suppose we could only place an element correctly into an already-sorted list.
Sort the list by inserting elements repeatedly into the front portion of the list. After \(k\) steps the first \(k\) elements of the list are sorted (though not necessarily in their final positions relative to the rest).
Bubble sort
Suppose the only operation we could perform was swapping adjacent cells.
Pass through the list swapping neighbouring elements so that larger elements move forward — larger elements “bubble” to the top. Make repeated passes until the list is sorted.
Merge sort
Suppose the only operation we could perform was merging two sorted lists into one sorted list.
Break the list in half, sort each half (using merge sort — this is recursion), then merge the two sorted halves.
The evaluation has the same two phases as any recursion: a winding phase where the list is repeatedly halved down to trivial pieces, and an unwinding phase where the sorted pieces are merged back up.
Quick sort
Could we sort a list if all we could do was split a list into two pieces based on some predicate?
Divide the list into two lists — those greater than or equal to the head, and those less than or equal to the head. Sort those lists (recursively) and then just concatenate them.
Which is best?
Rather than timing them, count how many times the characteristic operations are performed — for sorting, that means comparisons and swaps.
| Algorithm | Complexity |
|---|---|
| Selection sort | \(O(n^2)\) |
| Insertion sort | \(O(n^2)\) |
| Bubble sort | \(O(n^2)\) |
| Merge sort | \(O(n \ln n)\) |
Merge sort’s divide-and-conquer structure is what buys it the better class: the halving contributes a \(\log n\) factor and each level of the recursion does \(O(n)\) merging work.
Exercise: implement selection, insertion, bubble and merge sort. The hanoi function in 2025-10-20-recursion is the closest worked example of the same divide-and-conquer shape that merge sort and quick sort use.
UML Class Diagrams
UML (Unified Modelling Language) diagrams are the standard, language-agnostic way of visually describing the classes in a system and the relationships between them — useful for planning a design before writing code, and for communicating that design to others.
This note is the notation reference. The lecture note is 2025-10-07-uml; for how CSSE1001 draws diagrams generally, see csse1001-diagram-notation.
Class boxes
A class box is a rectangle in three compartments, separated by full-width horizontal rules:
ClassName
-----------------------
attributes
-----------------------
methods()Each attribute/method is prefixed with a visibility marker:
| Symbol | Visibility |
|---|---|
- |
private |
+ |
public |
# |
protected |
CSSE1001 conventions:
- Attributes are typed Python-style:
name: type, e.g.#age: int,-nationality: str,-pets: []. - An empty compartment is kept, not collapsed. A class with no attributes of its own is still drawn with a blank attributes band.
- Names follow the course’s Python naming rules —
CamelCapsfor class names,snake_casefor members (see python-pep8-style-guide). - Single-compartment, name-only boxes are acceptable when only the shape of a hierarchy is being shown.
- Method return types are optional: the same method can be written
+info(): stror+info(). Do not read meaning into the difference.
Relationship types
Figure 86: The relationship symbols as CSSE1001 draws them. The inheritance arrowhead is filled, which is the course’s deviation from textbook UML, and the diamond always sits at the whole end. The dependency head is filled as well. Child, Parent, Whole and Part are generic stand-ins for concrete classes.
| Relationship | Line style | Meaning |
|---|---|---|
| Inheritance | solid line, filled triangular arrowhead pointing at the parent | “is-a” — subclass inherits from superclass |
| Association | plain solid line, no head, optional verb label at one end | one class uses/references another, without ownership |
| Aggregation | solid line, hollow (open) diamond at the “whole” end | weak “has-a” — the part can exist independently of the whole |
| Composition | solid line, filled (solid) diamond at the “whole” end | strong “has-a” — the part cannot exist independently of the whole |
| Dependency | dashed line, small filled arrowhead | one class depends on another |
Standard UML draws generalisation with a hollow triangle. CSSE1001 draws it solid filled on every inheritance arrow. Follow the course, not the textbook. See csse1001-diagram-notation.
The dashed dependency arrow ends in a filled head in CSSE1001, not an open one. The head takes two forms: a filled concave-backed “classic” arrow, or a plain straight-backed filled triangle. Both are solid, and both differ in shape from the inheritance head.
Layout
- Routing is orthogonal. Relationship lines use right-angle elbows, never diagonals.
- A parent with several children gets one bus: a single vertical stem from the parent down to a horizontal line, with a vertical drop to each child — not one arrow per child.
- Parent above, children in a row beneath. A grandchild hangs directly below its own parent with its own arrow.
- Non-hierarchy classes usually sit to the side, at the same height as the class they attach to (
Vet,HeartandOwnerin the examples in 2025-10-07-uml). The exception isMilk, which hangs directly belowCatwith the association line running downCat’s left edge.
Multiplicity
Multiplicity annotations on association/aggregation/composition lines describe how many objects on each end participate in the relationship. They are placed above the line, next to the end they qualify:
| Notation | Meaning |
|---|---|
0..1 |
zero to one |
n |
an exact number |
0..* |
zero to many |
1..* |
one to many |
m..n |
a specific range |
Why use UML?
- Plan a class hierarchy/object graph before writing any code.
- Communicate a design to teammates without needing to read source code.
- Document the intended structure and relationships for future maintenance.
- Class diagrams are the most commonly used UML diagram type in object-oriented design, but UML also includes other diagram types (e.g. sequence diagrams, use-case diagrams) not covered in this course.
Comments
Anything following a
#will be ignored by Python. In addition to docstrings (see python-functions) you can — and should — include comments in your code to explain something not obvious in your design.Not helpful:
Helpful:
The first comment restates what the code already says. The second says why.