flowchart TD
    ID(["ID (key)"]) --- STUDENT[STUDENT]
    Name(["Name"]) --- STUDENT
    Title(["Title"]) --- Name
    Fname(["Fname"]) --- Name
    Initial(["Initial"]) --- Name
    Lname(["Lname"]) --- Name
    Email(["Email"]) --- STUDENT
    Address(["Address"]) --- STUDENT
    Number(["Number"]) --- Address
    Sname(["Sname"]) --- Address
    Suburb(["Suburb"]) --- Address
    Pcode(["Pcode"]) --- Address
    Phone(["Phone (multi)"]) --- STUDENT
INFS1200 — Full Course Notes
Week 1
Conceptual Database Design and the ER Model
Module 1, part 1. See er-diagram-notation and relationship-constraints for the reference symbol legend and the cardinality/participation definitions introduced here.
Module outline
Module 1 has five sections. This note covers the first three, and 2026-03-02-weak-entities-the-eer-model-and-design-choices covers the last two:
- Database design overview
- Entities and relationships
- Relationship constraints
- The EER diagram — next lecture
- Design choices — next lecture
The module answers three questions: why conceptual modelling matters for a successful database application; how the Entity-Relationship model is used to do it; and how to evaluate trade-offs between design choices by comparing alternative ER diagrams for the same system.
Conceptual database design
- Step 1: identify the “Universe of Discourse” (UoD) — the database models some “mini-world”/UoD, not everything in the world.
- Step 2: convert the UoD into a data model that a database can capture.
- A model is never perfect — three categories of phenomena around any conceptual schema: common phenomena (captured in the model, e.g. “every employee works for a department”), phenomena not captured (e.g. “some employees go out for dinner on Fridays” — irrelevant, left out), and phenomena not true in the world (e.g. an over-general assumption like “every secretary can type”).
See conceptual-database-design, which draws the two-step pipeline and the three-phenomena picture.
The ER model
The Entity-Relationship (ER) model provides a graphical representation of data entities — it helps define a project’s scope/requirements for clients and businesses. An entity is a physical or conceptual object with data (attributes) associated with it; the same real-world entity can have different attributes recorded depending on the system’s requirements (e.g. an R&D organisation records an employee’s Degree/Field of Study, a retail organisation records Sales Experience instead).
An entity type provides the format (name + attributes) for recording a particular kind of entity — drawn as a rectangle, with attribute ovals attached. The entity set is the collection of all entities of one entity type in the database at a point in time (maps to a table).
The whole notation fits on one diagram, which is the target to work towards. Every symbol on it is defined later in this note or the next:
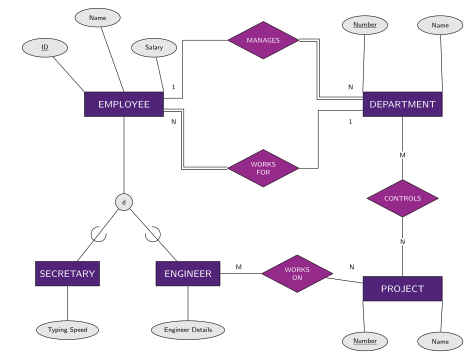
Figure 1: An example company ER diagram. Everything the module teaches is on it: entity types (purple rectangles), relationship types (magenta diamonds), key attributes (underlined ovals), cardinality ratios (1/N/M on the edges), total participation (double edges — every employee must work for a department, every department must have a manager) and an EER disjoint specialisation (the d circle). The diagram exists to gauge how the system works and how data within it is connected.
Attributes
- Key attribute: every entity type has at least one key (or uniqueness) constraint — its value is distinct for each individual entity in the entity set (name underlined). Multiple keys are possible, and a key must hold for every possible extension of the entity type.
- Composite vs simple: a composite attribute (e.g.
Name) can be split into simple attributes with independent meaning (Fname,Mname,Lname). - Composite key: a combination of simple attributes that together must be unique (e.g. a car’s
Registration=State+Number, alongside a separate simple keyVehicleID) — an entity type can have several candidate keys like this. - Single-valued vs multivalued: the split is stated over simple attributes. A multivalued attribute (double-lined oval) can hold more than one value per entity (e.g.
Degree— one person can hold multiple degrees). - Stored vs derived: a derived attribute (dotted oval) is computed from a related attribute value (e.g.
AgefromBirthDate). - Value sets: the set of values that may be assigned to an attribute (e.g.
employeeAge: integers between 21 and 65;vehicleRegistrationNum: a string of three alphabetic characters followed by three integers) — never shown on the diagram itself. Anullvalue represents an inapplicable (tertiaryDegree), unknown (homePhone) or missing (height) value.
entity-types-and-attributes draws the EMPLOYEE figure with every kind of attribute on it, and the CAR candidate-key figure.
Exercise — Student entity
Every student has a unique id, name (title/first/middle initial/last), email, address (number/street/suburb/postcode), and one or more phone numbers. Draw an ER diagram.
NoteSolution
STUDENT entity type with key attribute ID; composite attribute Name (→ Title, Fname, Initial, Lname); simple attribute Email; composite attribute Address (→ Number, Sname, Suburb, Pcode); and multivalued attribute Phone (double-lined oval, since a student can have more than one phone number).
Relationships
A relationship is an association among two or more entities (e.g. “Paris Lane works on the project FileZilla”). A relationship type defines it — drawn as a diamond connected to the associated entity types. A relationship type may have descriptive attributes, and it may have key attributes as well:
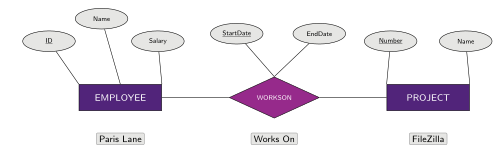
Figure 2: Relationship types carry attributes of their own. WORKSON records a StartDate and an EndDate for each employee/project pairing; StartDate is underlined, so it is a key attribute of the relationship, not merely a descriptive one — a fact the mapping stage has to preserve. The row underneath is the instance-level reading: Paris Lane works on FileZilla.
- Relationship degree = the number of participating entity types: binary (2 entities, e.g.
DEPARTMENT WORKSFOR EMPLOYEE), ternary (3 entities, e.g. a singleSUPPLIESdiamond joiningSUPPLIER,PROJECTandPART), or n-ary (3+) in general. - Roles: each entity type participating in a relationship type plays a particular role, and the role name explains what the relationship means. In
DEPARTMENT WORKSON EMPLOYEE,DEPARTMENTis the Employer andEMPLOYEEis the Worker. - Recursive relationships: the same entity type can participate more than once in one relationship type, under different roles —
EMPLOYEEMANAGESEMPLOYEE, with the two lines labelled Manager and Subordinate. - The relationship set is the collection of all relationships of one relationship type at a point in time. The same relationship set has three representations: the ER fragment (
EMPLOYEEN —WORKSON— MPROJECT), a ball-and-line instance diagram, and a three-column table (WorksOnID,EmployeeID,ProjectID), which is the shape the relationship eventually takes once mapped (er-to-relational-mapping).
Question — Entities and Relationships (courses/students)
Store info about students, courses, courses taken, and grades. Courses have a number/department/title (numbers assigned per-department, so different departments may reuse a number); students have a unique student ID and name; students enrol in courses and receive a grade.
NoteSolution
COURSES (composite key Key = Dept + Number, plus Title) ↔︎ ENROLMENTS (attribute Grade) ↔︎ STUDENTS (key ID, Name) — an M:N relationship, since a student can enrol in many courses and a course has many enrolled students.
flowchart LR
    ID(["ID (key)"]) --- STUDENTS[STUDENTS]
    NameS(["Name"]) --- STUDENTS
    STUDENTS ---|"N"| ENROLMENTS{ENROLMENTS}
    ENROLMENTS ---|"M"| COURSES[COURSES]
    Grade(["Grade"]) --- ENROLMENTS
    CourseKey(["Key (key)"]) --- COURSES
    Dept(["Dept"]) --- CourseKey
    Number(["Number"]) --- CourseKey
    Title(["Title"]) --- COURSES
The composite key comes from the clause that numbers are assigned by departments and different departments may use the same number: Number alone is not unique, so Dept + Number together are the key.
Relationship constraints
Constraints on a relationship type limit the possible combinations of entities that may participate in the corresponding relationship set, and both kinds are determined by the UoD — they are read off the description, not chosen for convenience. There are two:
| Constraint | What it fixes |
|---|---|
| Cardinality constraint | How many relationships of the set one entity can participate in |
| Participation constraint (also called existence dependency) | Whether an entity has to participate at all |
See relationship-constraints for what each ratio and each participation constraint asserts.
Cardinality ratio
A cardinality ratio for a relationship set specifies the number of relationships in the set that an entity can participate in. Take a customer buying items: one customer can purchase many different items, but an individual item (a particular cake) cannot be purchased by several different customers.
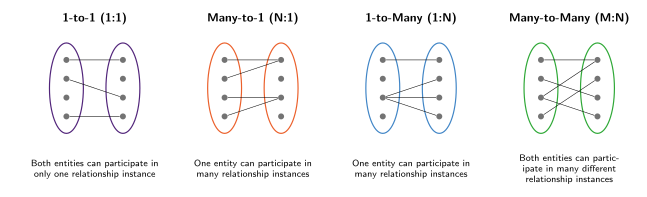
Figure 3: The four cardinality ratios as instance diagrams, colour coded: purple 1:1, orange N:1, blue 1:N, green M:N. Each dot is one entity, each line one relationship instance. Which dots are joined is illustrative; the constraint is the shape — a matching (1:1), a fan-in (N:1), a fan-out (1:N), or an unrestricted graph (M:N).
N:1 and 1:N are the same constraint read from opposite ends. The one relationship EMPLOYEE N — WORKSFOR — 1 DEPARTMENT fits both the orange N:1 picture and the blue 1:N picture. Which name you use depends on which entity type you name first, and the course’s notation guide fixes the reading: E1 —1— R —N— E2 is “cardinality ratio 1:N for E1:E2 in R”. The practical rule for reading a diagram is that the number written next to an entity says how many of that entity may take part with one of the other: N beside EMPLOYEE = many employees per department; 1 beside DEPARTMENT = one department per employee.
Three worked examples:
| UoD sentence | Ratio |
|---|---|
“Each employee can work on any number of projects, and each project can have any number of employees working on it” (WORKSON) |
M:N |
“Each department can have any number of employees, but an employee can work for at most one department” (WORKSFOR) |
N:1 (equivalently 1:N the other way) |
“Each department can have at most one manager and each employee can manage at most one department” (MANAGES) |
1:1 |
Participation constraints (existence dependency)
Existence dependency indicates whether the existence of an entity depends on its relationship to another entity. A double line between an entity type and a diamond means total participation; a single line means partial.
- “Every employee must work for a department” —
EMPLOYEEhas total participation inWORKSFOR, soEMPLOYEEis existentially dependent onDEPARTMENTvia theWORKSFORrelationship type. - “Every department must have a manager” —
DEPARTMENThas total participation inMANAGES, soDEPARTMENTis existentially dependent onEMPLOYEEviaMANAGES, whileEMPLOYEE’s participation stays partial (some employees manage nothing, and legally so).
Worked example — EMPLOYEE / DEPARTMENT
Figure 1 above is the diagram. It encodes four sentences:
- Every department must have a manager — total participation of
DEPARTMENTinMANAGES(double line on that edge). - Every employee can manage 0 or more departments — partial participation of
EMPLOYEEinMANAGES, and the1/Nlabels makeMANAGES1:N forEMPLOYEE:DEPARTMENT(a department has at most one manager; an employee may manage several). - Every employee must work for a department — total participation of
EMPLOYEEinWORKSFOR. - Each department can have any number of employees — with
NbesideEMPLOYEEand1besideDEPARTMENT,WORKSFORis N:1.
The 1:1 example in the table above (“each department can have at most one manager and each employee can manage at most one department”) is a different UoD sentence from statement 2: it is drawn 1 — MANAGES — 1, whereas the company diagram is drawn 1 — MANAGES — N. Two sentences, two ratios, same relationship name, so the ratio has to be read off the UoD and not off the verb.
WORKSON (EMPLOYEE M:N PROJECT) completes the picture: each employee can work on any number of projects, and each project can have any number of employees on it.
Question — Relationship constraints
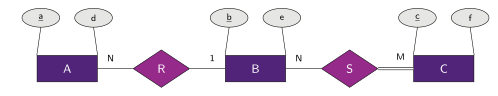
Figure 4: Entity types A, B and C joined by relationship types R and S. A contains a1, a2; B contains b1, b2; C contains c1, c2. Which relationship sets for R and S are possible? The double line into C is the whole difficulty — it constrains the instances, not just the schema.
A. R = {}, S = {}
B. R = {(a1,b1)}, S = {(b2,c2)}
C. R = {(a1,b1), (a1,b2)}, S = {(b1,c1), (b2,c2)}
D. R = {(a1,b2)}, S = {(b1,c2), (b2,c1), (b1,c1)}
NoteSolution
(D). Two constraints have to hold at once:
Ris N:1 forA:B, so eachamay appear at most once inR. That kills C, wherea1is paired with bothb1andb2.Chas total participation inS(the double line), so everycmust appear inS. That kills A (nothing appears) and B (c1is missing).Sbeing M:N places no further limit, so D — which lists bothc1andc2and pairs eachaat most once inR— is legal.
Exercise — ABC Banks
Model a bank with branches (unique name, city, budget, rating 1–10), customers (identified by name + phone, address recorded), accounts and loans (unique number, created/maintained by a single branch), where an account is assigned to one or more customers (balance never negative) and a loan is always assigned to a single customer (fixed interest rate, balance never negative).
NoteSolution
BRANCH (Name, City, Budget, Rating) —1:N OPENS→ ACCOUNT (ID, Balance); BRANCH —1:N GIVES→ LOAN (ID, Rate, Balance); CUSTOMER (ID, Name, Phone, Address) —M:N OWNS→ ACCOUNT; CUSTOMER —1:N TAKES→ LOAN.
flowchart TD
    BRANCH[BRANCH] ---|"1"| OPENS{OPENS}
    OPENS ---|"N"| ACCOUNT[ACCOUNT]
    BRANCH ---|"1"| GIVES{GIVES}
    GIVES ---|"N"| LOAN[LOAN]
    CUSTOMER[CUSTOMER] ---|"M"| OWNS{OWNS}
    OWNS ---|"N"| ACCOUNT
    CUSTOMER ---|"1"| TAKES{TAKES}
    TAKES ---|"N"| LOAN

    NameBr(["Name (key)"]) --- BRANCH
    City(["City"]) --- BRANCH
    Budget(["Budget"]) --- BRANCH
    Rating(["Rating"]) --- BRANCH

    IDa(["ID (key)"]) --- ACCOUNT
    BalanceA(["Balance"]) --- ACCOUNT

    IDl(["ID (key)"]) --- LOAN
    Rate(["Rate"]) --- LOAN
    BalanceL(["Balance"]) --- LOAN

    IDc(["ID (key)"]) --- CUSTOMER
    NameC(["Name"]) --- CUSTOMER
    Phone(["Phone"]) --- CUSTOMER
    AddressC(["Address"]) --- CUSTOMER
Two clauses in the brief are constraints the notation cannot carry: “its balance can never be negative” is a value-set restriction, and value sets are never shown on an ER diagram — it resurfaces later as a domain constraint (integrity-constraints). “Each account and loan is created and maintained by a single branch” is the participation constraint that makes ACCOUNT and LOAN total in OPENS/GIVES.
Practical 1: Course Tools
Introduces the two tools used throughout the course: diagrams.net (draw.io) for building ER diagrams, and Gradescope for submitting assessment. This practical itself is not assessable — it’s onboarding practice before Assignment 1. The semester plan lists it as the first practical, Intro to Course Tools, run in teaching week 2 (infs1200).
WarningUnverified
Nothing on this page (the Always a Gamer UoD, the diagram, or the task breakdown) has been verified against a published version, so treat it as a working reconstruction.
Task 1 — Recreate the “Always a Gamer” diagram in draw.io
UoD: a fictional gaming company’s GAME entity (Name, Year, Language, Description, Console) specialises two separate, disjoint (d) ways:
- How it’s played:
SINGLEPLAYER(Characters) orMULTIPLAYER(MinPlayers,MaxPlayers). - Whether it can be won:
WINNABLE, orNON-WIN(Purpose).
NON-WIN games also have a recursive SEQUEL relationship to other NON-WIN games (roles PrequelTo/SequelTo, 1:1).
flowchart TD
    GAME[GAME] --- d1(("d"))
    d1 --- SINGLEPLAYER[SINGLEPLAYER]
    d1 --- MULTIPLAYER[MULTIPLAYER]
    GAME --- d2(("d"))
    d2 --- WINNABLE[WINNABLE]
    d2 --- NONWIN["NON-WIN"]
    NONWIN ---|"1 PrequelTo"| SEQUEL{SEQUEL}
    SEQUEL ---|"1 SequelTo"| NONWIN

    Name(["Name"]) --- GAME
    Year(["Year"]) --- GAME
    Language(["Language"]) --- GAME
    Description(["Description"]) --- GAME
    Console(["Console"]) --- GAME
    Characters(["Characters"]) --- SINGLEPLAYER
    MinPlayers(["MinPlayers"]) --- MULTIPLAYER
    MaxPlayers(["MaxPlayers"]) --- MULTIPLAYER
    Purpose(["Purpose"]) --- NONWIN
Recreate this EER diagram yourself in draw.io. The mechanics worth finding first are the shape palette, connecting an entity to a relationship diamond, and exporting the finished drawing as an image.
The four subclasses above are drawn as plain rectangles, exactly like GAME itself. Subclass-hood is carried by the edge into the d circle, never by the box outline — a double-line box means weak entity, which is a different idea entirely. See er-diagram-notation for the full symbol table and the Mermaid shape mapping this note follows.
Task 2 — Using the ER diagram
Question 1 — Identifying entities
Which entity type is the superclass that every other entity type in this diagram specialises from (directly or indirectly)?
NoteWorking
GAME is the superclass. Its two disjoint specialisations are SINGLEPLAYER/MULTIPLAYER (one d-circle) and WINNABLE/NON-WIN (a separate d-circle) — four subclasses total, all ultimately specialising GAME.
Task 2.2 — Exporting the diagram
Export the finished diagram from draw.io as an image and attach it to the practical’s Gradescope submission — no fixed “right answer” here, it just confirms the export step works.
Task 3 — Submitting via Gradescope
Submit via the Gradescope link on the course Blackboard site. Not assessable — purely to confirm your Gradescope account is set up correctly ahead of Assignment 1.
Week 2
Weak Entities, the EER Model and Design Choices
Module 1, part 2 — continues on from 2026-02-23-conceptual-database-design-and-the-er-model. See er-diagram-notation and relationship-constraints for the reference symbol legend and weak-entity definition.
Outline
- Weak entities (closing out the “Entities and Relationships” section)
- The Enhanced ER (EER) diagram — superclasses/subclasses
- Design choices for conceptual modelling
Weak entities
Entity types that do not have key attributes of their own are called weak entities. Two rows of data show why: an employer insures dependants, and two different employees (SSN 12345 and SSN 22336) each have a dependant named John. Pname on its own cannot identify a dependant; Pname together with the insuring employee’s SSN can.
That gives the four terms:
- A weak entity can be identified uniquely only by considering the primary key of another owner entity and its own partial key, which is underlined with a dotted line.
- The relationship type that relates a weak entity to its owner is the identifying relationship.
- A weak entity and its identifying relationship are represented with double lines.
- The weak entity always has total participation in the identifying relationship — it cannot exist without an owner.
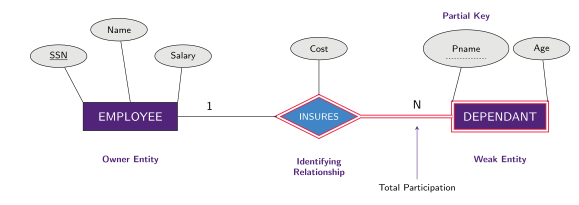
Figure 5: A weak entity and its owner. DEPENDANT has no key of its own: Pname is only a partial key (dotted underline), so its real key is (EMPLOYEE.SSN, DEPENDANT.Pname). INSURES is the identifying relationship and carries its own descriptive attribute Cost. Here the identifying relationship is filled blue and the weak-entity/identifying double lines are crimson; the course’s notation guide draws the same symbols as a magenta diamond and black double lines.
A weak entity can have more than one owner
The identifying relationship does not have to be binary. In this example it is ternary: a CANDIDATE applies to a COMPANY, and the INTERVIEW that results is identified only by both of them together plus its own partial key Details (itself composite — Department + Date).
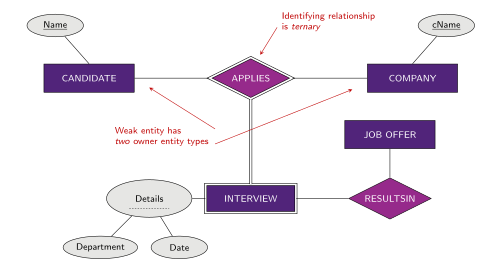
Figure 6: A weak entity with two owners. INTERVIEW is a weak entity with two owner entity types, so its identifying relationship APPLIES is ternary and its full key is (CANDIDATE.Name, COMPANY.cName, Details). Because INTERVIEW is an entity rather than an attribute, it can be the endpoint of a further relationship — RESULTSIN to JOB OFFER.
This matters downstream: a weak entity with two owners takes a foreign key to each of them, and its primary key is the union of both owner keys and its partial key — see er-to-relational-mapping.
Question — Weak Entity (hotel/room)
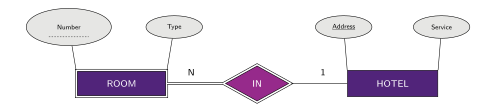
Figure 7: ROOM and HOTEL joined by the identifying relationship IN. ROOM is weak: Number carries a dotted underline (partial key), while Address carries a solid one (key). Everything the four options claim turns on telling those two underline styles apart.
Which of the following is true? (A) Two hotels can have the same address. (B) No two rooms can have the same number. (C) No two hotels can have rooms with the same number. (D) No two rooms with the same number can have the same type. (E) None of the above.
NoteSolution
(E) None of the above. ROOM’s real key is the composite (HOTEL.Address, ROOM.Number) — a room number is only guaranteed unique within its owning hotel, so (B) and (C) are both false; (A) is false since Address is HOTEL’s key attribute and must therefore be unique per hotel; (D) doesn’t follow from any stated constraint, since nothing at all is asserted about Type.
The EER model — superclasses and subclasses
An entity type is called a class in the EER model. Entities in the same class have the same attributes; a class can be a superclass or a subclass:
- Attributes of a superclass are inherited by the subclasses.
- A subclass can have its own specific attributes.
- A subclass can have its own specific relationships.
- Every entity in a subclass is a member of its superclass(es).
The notation is a ⊂ drawn as an open arc on the connecting line, and the direction of the ⊂ is what says which is which: in E1 ⊂ E2, E1 is the subclass of E2.
Motivating example: a supermarket ITEM has a ProductName and a Price in common with everything else on the shelves; a FOOD item additionally has an ExpiryDate. ITEM is the superclass — it captures the data common to a variety of different objects — and FOOD, an extension of a regular item, is the subclass.
Two ways of arriving at the same picture:
- Specialisation (top-down): define a number of subclasses of an entity type. Each subclass contains a subset of the entities of the superclass, and is defined by a more specific distinguishing characteristic of those entities.
- Generalisation (bottom-up): abstraction — ignore the differences amongst some subclasses and generalise them into a superclass.
In summary: subclasses are a specialisation of the superclass, and the superclass is a generalisation of the subclasses. See specialisation-and-generalisation.
Constraints on specialisation
Two independent choices, and one diagram puts all four combinations together by giving EMPLOYEE two specialisations at once:
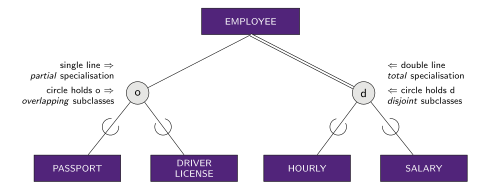
Figure 8: Constraints on specialisation. EMPLOYEE carries two independent specialisations: a partial, overlapping one (single line into an o circle — an employee may hold a passport, a driver licence, both, or neither) and a total, disjoint one (double line into a d circle — every employee is either hourly-paid or salaried, and never both). Line style fixes total vs partial; the letter in the circle fixes disjoint vs overlapping. They are orthogonal: any of the four combinations is legal.
| Choice | Drawn as | Asserts |
|---|---|---|
| Total specialisation | Double line from superclass to the circle | Every superclass entity belongs to at least one subclass |
| Partial specialisation | Single line | A superclass entity need not belong to any subclass |
| Disjoint subclass set | d in the circle |
An entity belongs to at most one of the subclasses |
| Overlapping subclass set | o in the circle |
An entity may belong to more than one subclass at once |
The EMPLOYEE → d → SECRETARY/ENGINEER split on the module’s overview diagram (in 2026-02-23-conceptual-database-design-and-the-er-model) is the same apparatus, with the subclasses carrying their own attributes — TypingSpeed on SECRETARY, EngineerDetails on ENGINEER.
Why bother with a subclass at all?
Subclasses let an attribute be stored for some entity instances rather than all of them, which reduces the number of null/empty values. In the event system of Applied class 2, not every SHOW needs a Rating — only ENTERTAINMENT shows do — so putting Rating on the subclass rather than the superclass is a storage-efficiency argument as well as a modelling one. Compare the three reasons a null appears in entity-types-and-attributes.
Exercise — University database (UofU)
Students: unique student id, name, address, phone, registered in a major; visiting students stay for a year. Courses: identified by department + course#, with title and credits. A course may be offered many times, even in the same semester; each offering gets a section# unique for a given course and semester, and is taught by a single instructor. Every instructor is responsible for some section (no idle instructors); instructors have unique names and a higher degree recorded. A student enrols in a course section and gets a mark. A course may have any number of other courses as prerequisites.
NoteSolution
STUDENT (key SID, Name, Address, Phone, Major) —M:N ENROLS_IN→ SECTION (attribute Mark); STUDENT has a subclass VISITING_STUDENT (HomeInst, StartDate). SECTION is a weak entity (partial key Sec#, owner COURSE, composite key Sec# + Semester), —N:1 OFFERING→ COURSE (key Dept + Course#, Title, Credits); SECTION —N:1 TEACHES← INSTRUCTOR (key Name, Degree), with total participation on the INSTRUCTOR side (“no idle instructors”). COURSE has a recursive M:N PREREQUISITE relationship with itself (roles higher/requires).
flowchart TD
    STUDENT[STUDENT] ---|"M"| ENROLS_IN{ENROLS_IN}
    ENROLS_IN ---|"N"| SECTION[[SECTION]]
    SECTION ===|"N"| OFFERING{OFFERING}
    OFFERING ---|"1"| COURSE[COURSE]
    SECTION ---|"N"| TEACHES{TEACHES}
    TEACHES ===|"1"| INSTRUCTOR[INSTRUCTOR]

    SID(["SID (key)"]) --- STUDENT
    SecNum(["Sec# (partial key)"]) --- SECTION
    CourseKey(["Dept+Course# (key)"]) --- COURSE
    NameI(["Name (key)"]) --- INSTRUCTOR
Two clauses do real work. “Section# is unique for a given course and semester” makes SECTION weak with COURSE as its owner — a section number means nothing without the course it belongs to. “There are no idle instructors” is a participation constraint, not a cardinality one: it makes INSTRUCTOR total in TEACHES without changing the N:1 ratio. “Visiting students stay for a year” is the distinguishing characteristic that earns VISITING_STUDENT its subclass.
Design choices for ER conceptual design
When modelling complex organisations a database designer faces design choices, which fall into two categories:
- Equivalent choices — an aspect of the UoD can be represented in an ER diagram by two different methods which are both equivalent, i.e. the resulting database will be the same.
- Inequivalent choices — when a UoD is slightly ambiguous, an aspect of it can be mapped two different ways which both meet the specification but lead to different limitations/constraints being enforced by the database. Note the assumption you made under the diagram.
The four common choice points, each with a worked before/after pair of diagrams in er-design-choices:
- Attribute vs. (weak) entity type — an interview’s
Details(Department,Date) as a key attribute of theAPPLIESrelationship, vs. pulled out into the weakINTERVIEWentity of - Attribute vs. subclass —
EMPLOYEE.Typeas a plain attribute, vs. splitting intoSECRETARY/ENGINEERsubclasses with their own extra attributes. - Subclass relationship vs. superclass relationship — giving
WORKSON(toPROJECT) to theEMPLOYEEsuperclass vs. only toENGINEER. - Binary relationships vs. N-ary relationships —
SUPPLIER/PROJECT/PARTas three binaries (SUPPLIES,CANSUPPLY,USES) vs. one ternarySUPPLIEScarrying aquantity.
Applied Class 1: Intro to DBMS and Basic ERD
Practice for 2026-02-23-conceptual-database-design-and-the-er-model. See er-diagram-notation and relationship-constraints for reference, and dbms-fundamentals for the Section A material.
Purpose: practical experience in using conceptual modelling, such as ER diagrams, to capture important aspects of a system (Universe of Discourse). By the end of the class you should be able to identify key DBMS architecture concepts, identify key components of an ER diagram, create semantically correct ER diagrams, develop a basic ER diagram from a UoD, and evaluate and justify basic design choices.
TipAbout the diagrams below
The solution diagrams here are drawn in TikZ rather than in the Mermaid approximation described at the bottom of er-diagram-notation, so that the mandatory Chen symbols render literally: a solid underline for a key attribute, a dashed oval for a derived attribute, a double-outlined oval for a multivalued attribute, and a double line into a diamond for total participation. The shapes are unfilled (black on white) rather than in the purple-entity / magenta-diamond / grey-oval house fills.
Section A — DBMS architecture concepts
Question 1 — Three-schema architecture matching
Match each concept to its description: (1) describes the physical storage structure, (2) describes the whole database’s structure for a community of users, (3) change the conceptual schema without changing external views/ applications, (4) modify the physical schema without changing the logical schema, (5) provides access to particular parts of the database to users.
Enter the numbers matching External Level, Logical data independence, Conceptual Level, Physical data independence, Internal Level, in that order, comma-separated:
NoteWorking
External Level → 5, Logical data independence → 3, Conceptual Level → 2, Physical data independence → 4, Internal Level → 1.
The two easy-to-swap pairs are the ones to check. Levels describe structure; independence properties describe what you are allowed to change without disturbing something else. And logical independence is about the conceptual↔︎external boundary, physical independence about the internal↔︎conceptual one — the three-schema figure in dbms-fundamentals brackets each property onto exactly the mapping it rides.
Question 2 — Typical DBMS functions
Select all options that are a typical function of a DBMS: (1) providing secure access, (2) enforcing integrity constraints, (3) normalising the relational schema, (4) handling concurrent access, (5) recommending changes to database design.
Enter the correct option numbers in ascending order, comma-separated (e.g. 1,2,3):
NoteWorking
1, 2, 4 — providing secure access, enforcing integrity constraints, and handling concurrent access are all typical DBMS functions. Normalising a schema and recommending design changes are design-time human decisions, not something the DBMS itself does.
The rule that separates them: a DBMS enforces the design it is handed, it does not choose it. Every option phrased as a design decision is a distractor.
Section B — Entities and attributes
You draw an ER diagram for one entity from a RESTAURANT example. The RESTAURANT database keeps track of a restaurant’s chefs, dishes and other information.
Question 1 — RESTAURANT: CHEF entity
The system stores each chef’s name (which consists of their first name, middle name and last name), which is unique. Their date of birth and age are also recorded, along with any specialisations that they have.
NoteWorking
Four different attribute kinds appear in one small diagram, which is the point of the question:
Nameis both composite (it splits intoFirstName,MiddleName,LastName) and the key — “which is unique” attaches to the whole name, so the underline goes on the parentNameoval, not on the three components.DoBis a plain simple attribute.Ageis derived — it is computable fromDoB, so it is not stored independently.Specialisationsis multivalued — “any specialisations”, plural, with no fixed number.
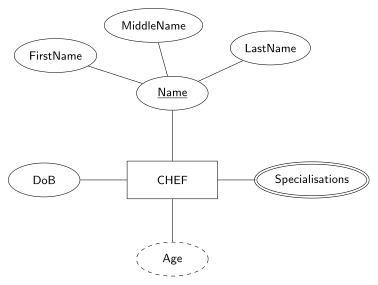
Figure 9: The CHEF entity. Underline = key, dashed oval = derived, double outline = multivalued; the three name components hang off the composite Name oval rather than off CHEF directly. The derived Age has a dashed oval but a solid connecting line here; the course notation dashes the connecting line too.
Section C — Basic relationships
Create an ER (or EER) diagram for each Universe of Discourse below. When choosing a cardinality or participation constraint, justify the choice from the UoD. It is worth doing the same in the assignments. Where the UoD is silent on some aspect, make a reasonable decision and write it down as an assumption beneath the diagram rather than leaving it implicit.
The justification tables in the workings below match each constraint in the diagram back to the sentence in the UoD that motivates it.
Question 1 — Olympics database
An athlete is identified by a unique athleteID and their name, age, sex and representative country are also stored. Each event is given a unique eventID and the name of the event and category are also recorded. For venues, a unique ID is stored, along with the venue’s name and its address.
Each athlete participates in at least one event and their final placement for each event is also recorded. Each event is held at one venue. Some venues are backups and hence not every venue stored in the system will be used to host an event.
NoteWorking
Three entity types, each with its own key; one M:N relationship carrying an attribute; one N:1 relationship.
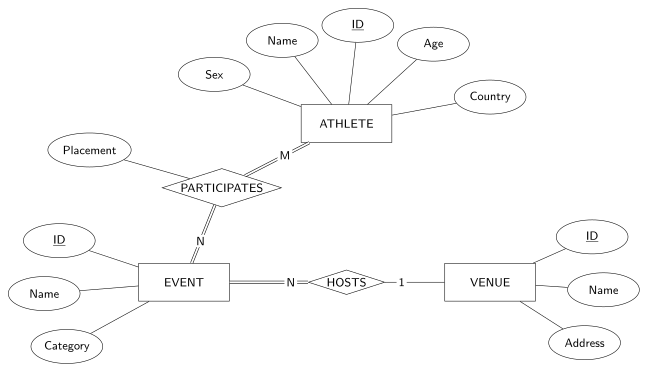
Figure 10: The Olympics ER diagram. Double lines mark total participation, and there are three of them: ATHLETE and EVENT are both total in PARTICIPATES, and EVENT is total in HOSTS. VENUE’s single line into HOSTS is the one partial participation, and it is what encodes the backup venues.
Reading the constraints back off the diagram, each against its sentence in the UoD:
| Constraint | Justification from the UoD |
|---|---|
PARTICIPATES is M:N |
An athlete may enter several events, and an event has many athletes |
Placement sits on the relationship, not on either entity |
A placement belongs to an athlete in an event, not to the athlete alone |
ATHLETE total in PARTICIPATES |
“Each athlete participates in at least one event” |
EVENT total in PARTICIPATES |
Implied — an event with no athletes is not an event being run |
HOSTS is N:1 from EVENT to VENUE |
“Each event is held at one venue”; a venue may host several |
EVENT total in HOSTS |
Every event is held somewhere |
VENUE partial in HOSTS |
“Some venues are backups… not every venue will be used to host an event” |
Question 2 — University transcripts database
The university keeps track of each student’s name, student number and social security number. The department each student majors in is also recorded. If the student has a minor, then that department is also recorded. Both social security number and student number have unique values for each student. Students can also take courses and for each course they take a grade is recorded.
Each department is described by a name, department code and office number. Both name and code have unique values for each department. A department may manage some courses.
Each course has a course name, course number, description and offering department. The value of course number is unique for each course.
NoteWorking
The interesting parts here are the two entity types that each have two candidate keys and the two relationships between the same pair of entity types.
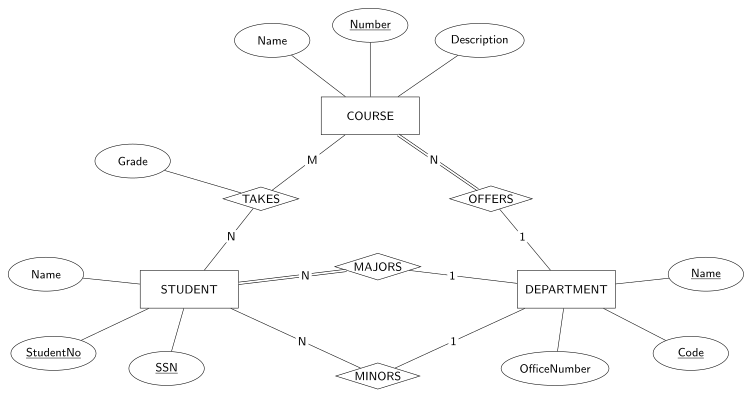
Figure 11: The university-transcripts ER diagram. STUDENT and DEPARTMENT each carry two underlined (candidate-key) attributes. MAJORS and MINORS are two separate N:1 relationships between the same pair of entity types, and only MAJORS gets the double line — every student majors somewhere, but a minor is optional. COURSE is likewise total in OFFERS, since every course has an offering department.
What each decision rests on:
| Decision | Justification from the UoD |
|---|---|
StudentNo and SSN both underlined |
“Both social security number and student number have unique values for each student” — two candidate keys, drawn as two separate underlined ovals |
Name and Code both underlined on DEPARTMENT |
“Both name and code have unique values for each department” |
TAKES is M:N with attribute Grade |
A student takes many courses and a course has many students; the grade belongs to the pair |
Separate MAJORS and MINORS relationships |
They are two different facts about a student, both N:1 to DEPARTMENT — one relationship with a “kind” attribute would lose the constraint that a student has at most one major |
STUDENT total in MAJORS, partial in MINORS |
“The department each student majors in is also recorded” (unconditional) versus “if the student has a minor” (conditional) |
COURSE total in OFFERS |
Every course has an “offering department” listed among its attributes in the UoD |
DEPARTMENT partial in OFFERS |
“A department may manage some courses” |
Section D — Analysis & application
Uses the same Olympics UoD and diagram as Section C question 1 (Figure 10).
Question 1 — Correct statements
Select the correct statements: (1) two different venues may share an address, (2) EVENT has a ternary relationship, (3) ATHLETE is an entity while Age is an attribute, (4) an ATHLETE cannot participate at the same EVENT more than once, (5) all VENUEs must host an EVENT.
Enter the correct option numbers in ascending order, comma-separated:
NoteWorking
1, 3, 4.
- True.
Addressisn’t underlined onVENUE— onlyIDis — so nothing in the diagram stops two venues sharing an address. - False.
EVENTtakes part inPARTICIPATESandHOSTS, and both are binary. A ternary relationship would be one diamond with three entity types on it. - True by definition:
ATHLETEis drawn as a rectangle,Ageas an oval hanging off it. - True. A relationship instance in the ER model is a pair, so the same (athlete, event) pair can occur at most once in
PARTICIPATES— which is also whyPlacementcan sit on the relationship at all. Recording repeat entries would need a different design. - False —
VENUE’s participation inHOSTSis drawn with a single line, i.e. partial, matching “some venues are backups”.
Question 2 — Total participation, semantically
What does the total participation on both sides of the PARTICIPATES relationship mean semantically? Does this align with the specification in the UoD?
NoteWorking
Total participation from ATHLETE and EVENT to the PARTICIPATES relation signifies each athlete in the system participates in at least one event and each event has at least one athlete participating in it. This is in line with the specification presented in the UoD.
The ATHLETE half is stated outright (“each athlete participates in at least one event”). The EVENT half is the one to be able to defend: an Olympic event with no athletes entered is not an event that is being run, so requiring at least one participant per event is the reasonable reading — and under the Section C instruction, exactly the sort of decision you would note as an assumption if challenged on it.
Question 3 — Redraw VENUE with two candidate keys
Redraw the VENUE entity so that a venue can be identified by either its ID or the combination of its name and address.
NoteWorking
VENUE gets two underlined ovals, one per candidate key. The second is a composite key — a parent oval named Key with Name and Address hanging off it, so the underline lands on the composite as a whole rather than on either component separately.
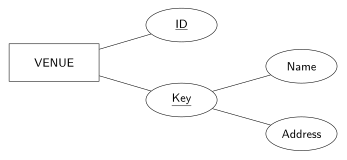
Figure 12: VENUE with two candidate keys. Two underlined ovals, not one: ID alone identifies a venue, and so does the composite Name+Address. Underlining Name and Address individually would say something different and wrong — that each is a key on its own.
This redraw contradicts Section D question 1 statement (1): once Name+Address is a key, two venues can no longer share both — though they could still share an address alone.
Section E — Additional resources
Recommended as revision practice for the assessment.
Question 1 — RESTAURANT: DISH entity
The restaurant serves many dishes, each of which has a unique name on the menu. Each dish also has a unique number and associated description, which consists of a brief history of the dish, the number of calories in the dish, and the price. The preparation time for each dish is also recorded, along with its ingredients.
NoteWorking
Two candidate keys again — Name (“a unique name on the menu”) and Number (“a unique number”) — each drawn as its own underlined oval. Description is a composite attribute splitting into History, Calories and Price. PreparationTime is simple, and Ingredients is multivalued.
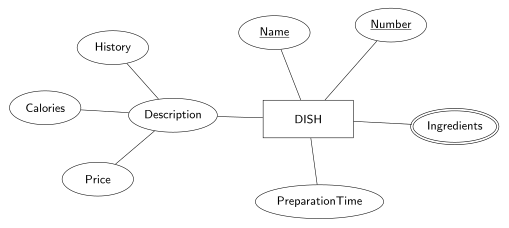
Figure 13: The DISH entity. Only Ingredients carries the double outline of a multivalued attribute; History is an ordinary component of the composite Description.
Compare with the CHEF answer in Section B: same restaurant UoD, same four attribute kinds to distinguish, but here the two keys are two separate simple attributes rather than one composite one, and there is no derived attribute to spot.
Case Study 1: Dirt Road Driving
Group case study applying the ER/EER model in 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices to a real-world brief. See er-diagram-notation and relationship-constraints for reference.
Section A — EER diagram
Dirt Road Driving is a rural rideshare company, gathered from correspondence with the company’s Director of Innovation:
- Users: unique
id, fullName,DOB. A user can register any number of emergency contacts (Nameunique per user,Email,Phone). - Staff: unique
staffID, fullName(first/middle/last),DOB,Phone(s). Split intoAdministration(DeskNumber) andDriver(Licence) — a staff member can be both at once (overlapping). - Vehicles:
VIN,Make,Model. Disjointly splits into4WD(RideHeight,WheelType) and2WD(FrontWheelDrive). - Trip: a user, a vehicle, and a driver (never permanently assigned to one vehicle — recorded per trip), plus a
BookingTimeand start/end timestamps (used to deriveFare); a trip can record multiple stopLocations. After a trip, the user separately rates the driver and the vehicle (integer out of 10, stored asRATESrelationships) — a repeat rating updates the existing one rather than creating a new one.
NoteWorking
The two specialisations
STAFF (key StaffID, composite Name = FirstName/MiddleName/ LastName, DOB, multivalued Phone) specialises overlappingly (o) into DRIVER (Licence) and ADMINISTRATION (DeskNumber) — overlapping because the brief says a staff member can be both at once. VEHICLES (key VIN, Make, Model) specialises disjointly (d) into 4WD (RideHeight, WheelType) and 2WD (FrontWheelDrive) — disjoint because a vehicle is one or the other. Both are drawn below in the notation of er-diagram-notation and specialisation-and-generalisation:
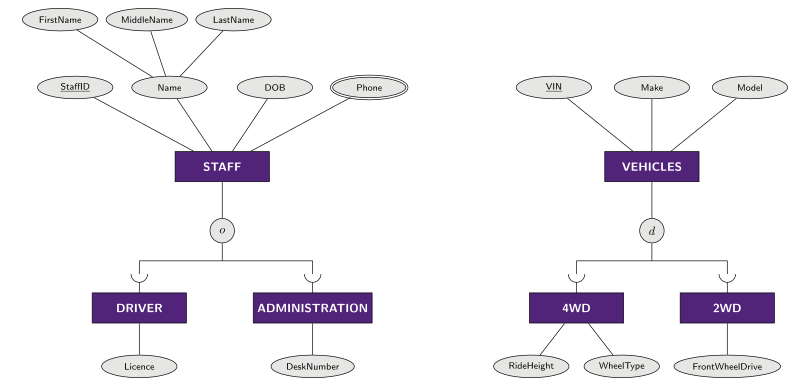
Figure 14: The two specialisations in EER notation: entity types are solid purple rectangles with white ALL-CAPS names, attributes are grey ellipses (key underlined, multivalued double-outlined), and a subclass is joined to the d/o circle by a line carrying the ⊂ arc, whose opening faces the superclass. The brief does not say whether every staff member must be a driver or an administrator, nor whether every vehicle must be a 4WD or a 2WD, so the line from each superclass down to its circle is drawn single (partial specialisation); a double line there would assert total specialisation, and the brief does not settle it.
Note the box shapes. A subclass is an ordinary single-line rectangle — what makes it a subclass is the ⊂ arc on the line into the d/o circle, not the shape of its box. The double-line rectangle means weak entity and nothing else, so in this answer the only double box is EMERGENCYCONTACTS below. Drawing DRIVER, ADMINISTRATION, 4WD or 2WD with a double border would assert the opposite of what they are: a subclass inherits its superclass’s key, whereas a weak entity has no key of its own at all.
The relationships
USER (key ID, Name, DOB) owns the weak entity type EMERGENCYCONTACTS (partial key Name, plus Email and Phone) through the identifying relationship HAS — 1 on the USER side, N on the contact side, and a double line on the contact side because a contact cannot exist without the user it belongs to. Name is only a partial key (unique per user, not globally), which is exactly why the mapping in week4-tutorial-case-study-3-dirt-road-driving gives the resulting relation the composite key (userID, name).
TRIP is a single ternary relationship over USER, DRIVER and VEHICLES carrying BookingTime, StartTime, EndTime, multivalued StopLocation and derived Fare — a driver is not permanently assigned to a vehicle, so the vehicle belongs to the trip rather than to the driver. Ratings are two separate RATES relationships, USER–DRIVER and USER–VEHICLES, each M:N with its own Number (out of 10); because the rating is an attribute of the relationship instance, re-rating updates the one existing tuple instead of adding a second one, which is what the brief asks for.
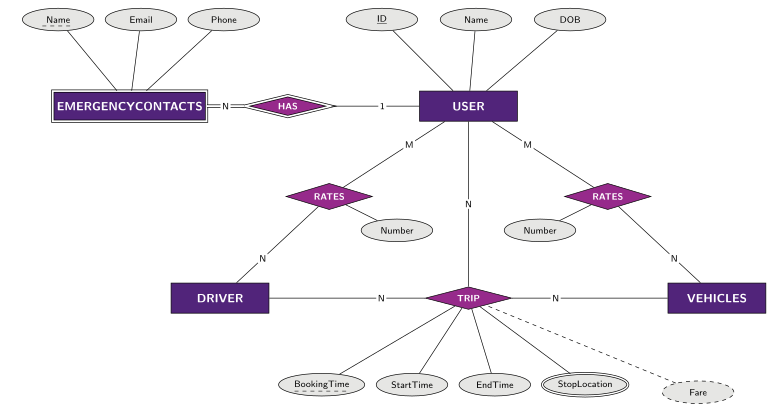
Figure 15: The relationship half of the answer. EMERGENCYCONTACTS is the one weak entity type — double-line rectangle, identifying (double) HAS diamond, double participation line, dash-underlined partial key Name. DRIVER and VEHICLES appear here as plain boxes; their attributes and their place in the class hierarchy are in Figure 14. Two conventions here go beyond what the brief or the notation settles: (1) the dashed underline is defined for a weak entity’s partial key, so using it on the relationship attribute BookingTime is an extension, recording that BookingTime is what distinguishes two trips with the same user, driver and vehicle — the fact the Week 4 mapping’s composite key relies on; (2) the brief does not fix the ternary cardinality ratio, so all three TRIP edges are marked N for many on every side.
Section B — Critical thinking
Propose a change to the EER diagram that would help the company make a new data-informed decision not currently possible.
This is open-ended — no single correct answer. Consider what a rural rideshare operator might want to analyse that today’s schema can’t answer (e.g. tracking incident reports per trip, recording each vehicle’s service/ maintenance history, or logging cancelled vs. completed trips separately) and how you’d extend the entities/relationships above to capture it.
Week 3
The Relational Model and Integrity Constraints
Module 2, part 1. See relational-mapping-notation for the schema notation used here and in 2026-03-16-er-to-relational-mapping.
Outline
- Relational model concepts — relations, attributes, domains, tuples
- Integrity constraints
- The transaction concept
Relational model concepts
Introduced by E.F. Codd in 1970. Many DBMS products are based on this model — a sound theoretical foundation with a simple, uniform data structure called a relation. Four basic concepts: relations, attributes, domains, tuples.
Relations
A relation is the main construct for representing data — informally, a set of records, similar to a table with columns and rows. The term table is used interchangeably with relation, but every relation is a table; not every table is a relation — relations have specific properties based on mathematical set theory.
A counter-example is a spreadsheet-style sales report: a two-tier header (City: Brisbane / Product / Year: 1998 above Region / Suburb / blank / Qtr 1 … Qtr 4) over rows like South | Algester | Disks | 32 | 243 | 23 | 246. Merged and stacked header cells mean the columns are not a flat list of attributes, so it is a table but not a relation.
Relation components
Four of the model’s terms sit on one picture: the relation name labels the whole table, the attribute names label the columns, each row is a tuple, and every value in a column is drawn from that attribute’s domain.
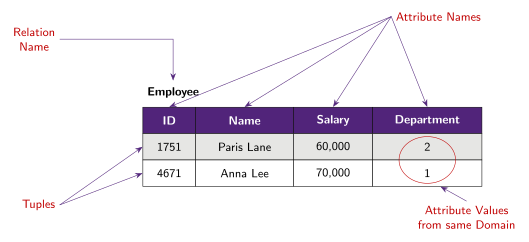
Figure 16: The anatomy of a relation, on an Employee example. Relation name above the table, attribute names in the purple header, tuples as rows, and one column circled: every value in it comes from the same domain.
Domains
A domain D is a set of atomic values — an atomic value is indivisible as far as the relational model is concerned. Each domain has a data type/format: integers, numbers/currency, fixed/variable-length character strings, date/timestamp, a sub-range of a data type (e.g. 1 ≤ grade ≤ 7), or an enumerated type (e.g. Gender ∈ {Male, Female, Other}) — including format-constrained domains like Australian phone numbers (61 + 9 digits) or car registrations (6 alphanumeric characters, no Q).
Attributes
Each attribute A is the name of a role played by some domain D in a relation R. The number of attributes in R is its degree. Same-named attributes across relations don’t necessarily share a domain (Department.id and Employee.id can be different domains despite the shared name id), and differently-named attributes can share a domain (Employee.id and Employee.managerId can both be drawn from the same “employee id” domain, despite the different names).
Tuples
Each tuple t is an ordered list of n values t = <v1, v2, …, vn>, where each value belongs to the corresponding attribute’s domain, or is the special value NULL. t is called an n-tuple.
Relation schema and instance
- Relation schema:
R [A1, A2, …, An]— a relation nameRand its list of attributes; n is the degree of the relation. E.g.Employee [id, name, sex, salary, department]is a schema of degree 5. - Relation instance:
r(R), a set of n-tuplesr = {t1, t2, …, tm}— the actual data, at a point in time.
Question — Schema and Instance
Match each characteristic to Schema or Instance: “data in the database”, “specified during database design”, “data describing the data”, “created through data update operations”.
NoteSolution
Instance: “data in the database”, “created through data update operations” (inserts/updates/deletes change the instance, not the schema). Schema: “specified during database design”, “data describing the data” (the schema is metadata — it describes the shape data must take, not the data itself).
Ordering of tuples and values
Relations are sets of tuples — mathematically, a set has no implied order. Semantically (e.g. when writing queries), tuple order is irrelevant. Physically, tuples reside on blocks of secondary storage, which have a partial ordering, so at that level tuples do have an order — but two instances with the same tuples in a different order are still the same relation. Likewise, an n-tuple is syntactically an ordered list — every tuple in one relation must list values in the same attribute order — but semantically, which order is chosen doesn’t matter, as long as the attribute/value correspondence is maintained consistently.
Integrity constraints
Integrity constraints are rules that enforce the correctness of a database — they must hold on every instance of the schema. Five kinds: domain, key, entity integrity, referential integrity, semantic.
Domain constraint
A domain constraint violation occurs when an attribute’s value doesn’t appear in its corresponding domain. Assuming the domain of Employee.id is a 4-digit integer, inserting ("LOL", Anna Lee, 70,000, 4) is rejected; (4671, Anna Lee, 70,000, 4) is accepted.
Key
A key is a minimal set of attributes that uniquely identifies tuples in a relation — minimal meaning no redundant attributes, not necessarily the smallest possible set. A schema can have more than one key (each a candidate key); the one chosen as the relation’s main key is the primary key (conventionally underlined). A key constraint violation occurs when a tuple is inserted/modified to share a key value with an existing tuple. With Employee holding (1751, Paris Lane, 60,000, 2) and (4671, Anna Lee, 70,000, 1), inserting (4671, Ben Cho, 70,000, 4) is rejected because id = 4671 is taken; (1023, Ben Cho, 70,000, 4) is accepted.
See relational-keys for the minimality argument and for the two key questions below drawn as one picture.
Question — Key
Assuming department IDs are unique, which of the following is a key for Department [id, name, manager]: (A) (id), (B) (id, name), (C) (id, manager), (D) all of the above?
NoteSolution
(A) (id) — since IDs are already unique on their own, (id) is the minimal key; (id, name) and (id, manager) both contain a redundant extra attribute (adding anything to an already-unique set isn’t minimal).
Question — Key (multiple candidate keys)
Assuming department IDs are unique and the combination of Name and Manager is also unique per department, which of the following is a key(s): (A) (id), (B) (id, name), (C) (name, manager), (D) both A and C?
NoteSolution
(D) Both A and C. (id) is still minimal and unique on its own; now (name, manager) is also minimal and unique, making it a second candidate key. (id, name) is still not minimal since (id) alone already suffices.
Entity integrity constraint
An entity integrity constraint violation occurs when a tuple is inserted/modified such that (any part of) its primary key is NULL — for a composite primary key, no part of it can be null. Inserting (NULL, Jack Smith, 40,000, 1) into Employee is rejected; (2034, Jack Smith, 40,000, 1) is accepted.
Foreign keys
A foreign key is a set of attributes in one relation that links it to another relation’s primary key. Formally: let FK be attributes in R1 and PK the primary key of R2. FK in R1 is a foreign key referencing PK in R2 if FK/PK share a domain, and for every tuple t1 in R1, either t1[FK] is NULL, or some tuple t2 in R2 has t1[FK] = t2[PK].
Department [id, name, manager]
Department.manager references Employee.id

Employee [id, name, sex, salary, department]
Employee.department references Department.id
Both directions are live at once here. In the example instance, Department 4 (Human Resources) has a NULL manager, employee 2034 has a NULL department, and both rows are legal — an absent reference is fine, a dangling one is not. The two figures in foreign-keys draw this instance with the foreign-key arrows on it.
Self-referencing relations are also possible — a table can reference itself. For example, add a ManagerID column to Employee and declare Employee.managerID references Employee.id. Composite foreign keys are possible too, referencing a multi-attribute primary key:
Student [sid, name]

Course [cid, department, manager]

Enrollment [sid, cid, department, grade]
Enrollment.sid references Student.sid
Enrollment.{cid, department} references Course.{cid, department}
Course is keyed on the pair (cid, department), so Enrollment has to carry both columns to name one course — one composite constraint over a tuple of columns, not two separate ones.
Referential integrity constraint
A referential integrity constraint violation occurs when a foreign key value doesn’t match any existing primary key value in the referenced relation (and isn’t NULL). The constraint guarantees that a department with number 2 exists before the “Grace Mills” tuple is stored: (2670, Grace Mills, 50,000, 5) is rejected because there is no Department 5, while (2670, Grace Mills, 50,000, 2) is accepted.
Semantic (business-rule) constraint
Semantic constraints are generally defined by the business/organisation during client consultation (not derivable from the schema’s structure alone) — e.g. “the salary of an employee should not exceed the employee’s supervisor’s salary”, or “the maximum number of hours that an employee can work on a project is 56”. Often implemented in a constraint specification language (SQL) using triggers and assertions.
Worked on the example instance: department 1’s manager is Anna Lee, who earns 70,000, so inserting (2967, Arron Dills, 100,000, 1) breaks the salary rule and is rejected; (2967, Arron Dills, 40,000, 1) is accepted. Nothing about the shape of the two relations rules the first one out — that is exactly what makes it semantic rather than structural.
Exercise — name an example of each
Given the schema below, give an example of (1) a key, (2) a foreign key, (3) a domain constraint.
Student [stID, name, email]

Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode

Course [cCode, title, units]
NoteSolution
- Key —
stIDin relationStudent. - Foreign key —
stIDin relationEnrolment. - Domain constraint —
cCode, four letters followed by four numbers.
The same attribute name supplies the first two answers depending on which relation it is read in: it is a key where it identifies, a foreign key where it refers.
Question — Integrity Constraints (password)
Opening an online bank account, you enter your usual password “password123”, but get: “your password must contain at least one capital letter and a number”. What kind of constraint is this?
NoteSolution
Domain constraint — the domain of “password” is defined as strings matching a particular format (≥1 capital, ≥1 digit); “password123” simply isn’t a member of that domain.
Question — Integrity Constraints (which is violated?)
Given Department [id, name, manager] and Employee [id, name, salary, department], with Department rows (1, Marketing, 4671), (2, Development, 1751), and Employee rows (1751, Paris Lane, 60000, 2), (4671, Anna Lee, 70000, 1), (2670, Grace Mills, 50000, 2), (2034, Jack Smith, 40000, 1) — which constraint is violated by each of the following?
- Inserting
(2670, James Smith, 40000, 1)intoEmployee. - Inserting
(2644, James, Smith, 1)intoEmployee(note: only 4 values given for a 4-attribute relation, but shifted). - Inserting
(2644, James Smith, 40000, 3)intoEmployee. - Deleting
(2, Development, 1751)fromDepartment. - Updating
(2, Development, 1751)to(2, Development, 2034)inDepartment.
NoteSolution
- Key constraint —
id = 2670already exists inEmployee. - Domain constraint — the shift means
salaryreceives a non-numeric value ("Smith"), which isn’t a member ofsalary’s domain. - Referential integrity constraint — no
Departmentwithid = 3exists. - Referential integrity constraint —
Employeerows withdepartment = 2still exist (Grace Mills), so deletingDepartment 2would leave a dangling foreign key. - None of the above (by the stated constraints) —
Employeewithid = 2034doesn’t actually work inDepartment 1, but there’s no declared constraint stopping a department’s manager from being an employee of a different department; this would only be a semantic constraint if the business rule “a manager must work in the department they manage” were explicitly specified.
Constraints and operations
Enforcing integrity constraints keeps the database consistent — insert, modify, and delete operations must not leave the database in an inconsistent state; if a database update submitted to the DBMS would violate integrity, it must be rejected.
Insertion and deletion differ in which constraints they can violate:
- Insertion/modification can violate any of the five constraint types (domain, key, entity integrity, referential integrity, semantic).
- Deletion can only violate referential or semantic constraints. A referential integrity violation on delete can be handled by rejecting the delete, cascading it (deleting dependent rows too), or modifying the referencing attribute values to a default value.
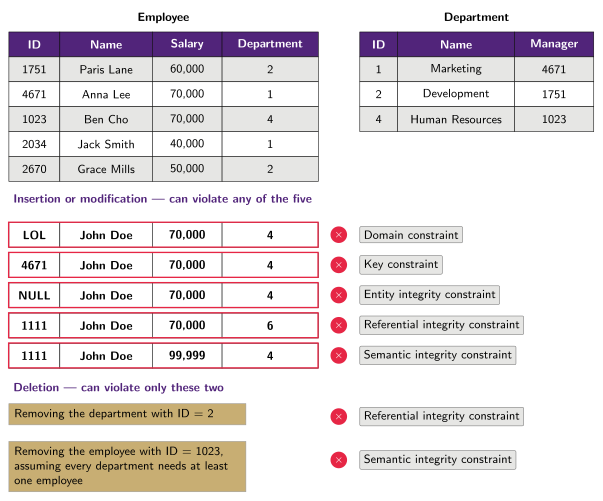
Figure 17: Which operation can violate which constraint, on an Employee/Department instance. Each of the five candidate insertions differs from a legal row in exactly one respect; the two deletion cases sit below them.
Read the five candidate rows as a controlled experiment: each differs from a legal row in exactly one respect, and that one difference names the constraint. The last one is the giveaway that semantic constraints are not structural — (1111, John Doe, 99,999, 4) is a perfectly well-formed tuple with a fresh key, a real department and no nulls, and is still rejected. It breaks the salary rule: 99,999 exceeds the 70,000 earned by Ben Cho, the manager of department 4.
The transaction concept
A transaction is an executing program that includes database operations (reads, inserts, deletes, updates). At the end of a transaction, the database must be left in a valid/consistent state satisfying all constraints — but constraint violations are allowed at intermediate steps within the transaction. That is the whole point: transactions allow a suite of queries to run where constraint violations in intermediate steps are permitted.
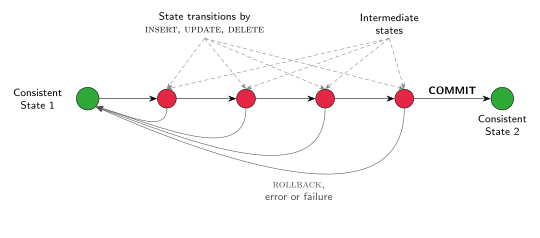
Figure 18: A transaction as a walk between consistent states. INSERT/UPDATE/DELETE move the database through intermediate states that may violate constraints; COMMIT is legal only into a consistent state, and ROLLBACK (or an error or failure) returns to the state the transaction started from. INFS1200 has no house notation for transaction diagrams; the shapes and colours here follow the figure in the SAP MaxDB documentation, not a course convention.
Example: given Department [id, name, manager] and Employee [id, name, sex, salary, department], with the business rules “every department must have ≥1 employee” and “every employee must work for a department” — neither a new department (no employees yet) nor a new employee (no department yet) can be inserted alone without violating one of these rules. A transaction that inserts both the new department and its first employee together resolves this: the intermediate state (after just one insert) is inconsistent, but the final state (after both inserts) is valid.
Applied Class 2: Entity Relationship Diagrams
Practice for 2026-03-02-weak-entities-the-eer-model-and-design-choices. See er-diagram-notation and relationship-constraints for reference.
Section A — ERD components
Given a COMPANY ER diagram (EMPLOYEE, DEPARTMENT, PROJECT, DEPENDENT, plus the relationships MANAGES/WORKS_FOR/CONTROLS/ WORKS_ON/SUPERVISION/DEPENDENTSOF), find an example of each ERD component.
NoteWorking
| Component | Example |
|---|---|
| Strong entity | EMPLOYEE, DEPARTMENT, PROJECT |
| Weak entity | DEPENDENT |
| (Candidate) key | EMPLOYEE.Ssn; DEPARTMENT.Name/Number; PROJECT.Name/Number; DEPENDENT.{Ssn, Name} |
| Partial key | DEPENDENT.Name |
| Composite attribute | EMPLOYEE.Name (→ FirstName, MiddleInitial, LastName) |
| Derived attribute | DEPARTMENT.Number_of_employees |
| Multivalued attribute | DEPARTMENT.Locations |
| 1-1 relationship | MANAGES |
| 1-N relationship | CONTROLS, WORKS_FOR, SUPERVISION |
| M-N relationship | WORKS_ON |
| Identifying relationship | DEPENDENTSOF |
flowchart TD
    EMPLOYEE[EMPLOYEE] ---|"1 supervisor"| SUPERVISION{SUPERVISION}
    SUPERVISION ---|"N supervisee"| EMPLOYEE
    EMPLOYEE ===|"N"| WORKS_FOR{WORKS_FOR}
    WORKS_FOR ---|"1"| DEPARTMENT[DEPARTMENT]
    EMPLOYEE ---|"1"| MANAGES{MANAGES}
    MANAGES ===|"1"| DEPARTMENT
    DEPARTMENT ---|"1"| CONTROLS{CONTROLS}
    CONTROLS ---|"N"| PROJECT[PROJECT]
    EMPLOYEE ---|"M"| WORKS_ON{WORKS_ON}
    WORKS_ON ---|"N"| PROJECT
    EMPLOYEE ---|"1"| DEPENDENTSOF{DEPENDENTSOF}
    DEPENDENTSOF ===|"N"| DEPENDENT[[DEPENDENT]]

    Ssn(["Ssn (key)"]) --- EMPLOYEE
    NameE(["Name"]) --- EMPLOYEE
    Salary(["Salary"]) --- EMPLOYEE

    DeptKey(["Number/Name (key)"]) --- DEPARTMENT
    NumEmp(["Number_of_employees (derived)"]) --- DEPARTMENT
    Locations(["Locations (multi)"]) --- DEPARTMENT

    ProjKey(["Number/Name (key)"]) --- PROJECT

    DepName(["Name (partial key)"]) --- DEPENDENT
Section B — ERD modelling assumptions
Uses a health/vaccination EER diagram: HEALTHWORKER —1:N OVERSEEN→ HEALTH (subclass of PARTICIPANT, alongside an overlapping AGE subclass); VACCINE (ID, composite Key = Brand+Name) has a recursive WITH relationship (roles First/Second, both partial) and —1:N HAS→ BATCH (weak entity, partial key Number).
Evaluate each statement as Correct or Incorrect.
B1 — Each vaccine must have a second dose or a preceding dose.
B2 — A participant can be overseen by several healthcare workers.
B3 — Every participant in the HEALTH subclass is overseen by a health worker during vaccination.
B4 — A vaccine can only be uniquely identified by the combination of its Brand and Name.
B5 — A participant can be in both the HEALTH subclass and the AGE subclass.
B6 — A BATCH is uniquely identified by only its number.
NoteWorking
- B1 Incorrect — the recursive
WITHrelationship lets a vaccine be recorded as a first or second dose, but participation from both sides is partial: a vaccine doesn’t have to be part of a two-shot program. - B2 Incorrect —
OVERSEENis 1:N fromHEALTHWORKERtoHEALTH: one healthcare worker can oversee many participants, but each participant has at most one overseeing healthcare worker. - B3 Correct —
OVERSEENhas total participation from theHEALTHside. - B4 Incorrect —
VACCINEhas two candidate keys: the compositeKey(Brand+Name), or itsID. - B5 Correct —
HEALTHandAGEare overlapping subclasses ofPARTICIPANT— an instance can be a member of both at once. - B6 Incorrect —
BATCHis a weak entity; its real key isBatch Numbercombined with its ownerVACCINE’s key (eitherIDorKey).
flowchart TD
    PARTICIPANT[PARTICIPANT] --- o1(("o"))
    o1 --- HEALTH[[HEALTH]]
    o1 --- AGE[[AGE]]
    HEALTHWORKER[HEALTHWORKER] ---|"1"| OVERSEEN{OVERSEEN}
    OVERSEEN ===|"N"| HEALTH

    VACCINE[VACCINE] ---|"First"| WITH{WITH}
    WITH ---|"Second"| VACCINE
    VACCINE ---|"1"| HAS0{HAS}
    HAS0 ===|"N"| BATCH[[BATCH]]

    IDv(["ID (key)"]) --- VACCINE
    VKey(["Key (key)"]) --- VACCINE
    Brand(["Brand"]) --- VKey
    VName(["Name"]) --- VKey
    Number(["Number (partial key)"]) --- BATCH
Section C — Conceptual modelling
Question 1 — Cinema
Movies (unique Name, Description, RunningTime); attendants (unique StaffID, Name, Phone); customers (unique ID, Name, Email); viewings record a Timestamp (unique per customer+movie) and any Snacks purchased; exactly one attendant oversees each viewing.
NoteWorking
MOVIE —1:N HAS→ VIEWING (Timestamp, multivalued Snack) —1:N OVERSEES←ATTENDANT; CUSTOMER —1:N HAS→ VIEWING. VIEWING’s key is the composite of its owning CUSTOMER+MOVIE+Timestamp (it’s a weak entity in the fuller reading of the UoD, or an M:N relationship with a Timestamp key attribute, depending on the design choice made).
flowchart TD
    MOVIE[MOVIE] ---|"1"| HAS1{HAS}
    HAS1 ---|"N"| VIEWING[[VIEWING]]
    CUSTOMER1[CUSTOMER] ---|"1"| HAS2{HAS}
    HAS2 ---|"N"| VIEWING
    VIEWING ---|"N"| OVERSEES{OVERSEES}
    OVERSEES ---|"1"| ATTENDANT[ATTENDANT]

    NameM(["Name (key)"]) --- MOVIE
    Description(["Description"]) --- MOVIE
    RunningTime(["RunningTime"]) --- MOVIE
    Timestamp(["Timestamp (partial key)"]) --- VIEWING
    Snack(["Snack (multi)"]) --- VIEWING
    StaffID(["StaffID (key)"]) --- ATTENDANT
    IDc(["ID (key)"]) --- CUSTOMER1
Question 2 — Medical clinic
Patients (PatientID) and doctors (LicenceNo); each doctor is either a GP or a specialist (never both), specialists also record their SpecialisationArea; doctors work in clinics (RegistrationNo), one clinic can have several doctors; some clinics are specialist clinics, each run by exactly one specialist doctor; patients make appointments (Fee) to consult doctors.
NoteWorking
PATIENT (PatientID) —M:N CONSULTS (Fee)→ DOCTOR (LicenceNo), which disjointly (d) specialises into GP/SPECIALIST (SpecialisationArea). DOCTOR —M:N WORKSIN→ CLINIC (RegistrationNo), which has a subclass SPECIALIST CLINIC —1:N RUNS←SPECIALIST.
Assumptions: every patient in the DB has made an appointment; every clinic has at least one doctor.
flowchart TD
    PATIENT[PATIENT] ---|"M"| CONSULTS{CONSULTS}
    CONSULTS ---|"N"| DOCTOR[DOCTOR]
    DOCTOR --- d(("d"))
    d --- GP[[GP]]
    d --- SPECIALIST[[SPECIALIST]]
    DOCTOR ---|"M"| WORKSIN{WORKSIN}
    WORKSIN ---|"N"| CLINIC[CLINIC]
    CLINIC --- SPECIALISTCLINIC[["SPECIALIST CLINIC"]]
    SPECIALIST ---|"1"| RUNS{RUNS}
    RUNS ---|"N"| SPECIALISTCLINIC

    PatientID(["PatientID (key)"]) --- PATIENT
    LicenceNo(["LicenceNo (key)"]) --- DOCTOR
    Fee(["Fee"]) --- CONSULTS
    SpecArea(["SpecialisationArea"]) --- SPECIALIST
    RegNo(["RegistrationNo (key)"]) --- CLINIC
Section D — Additional resources (not covered in the applied class)
Question 1 — Bubble tea shop
BUBBLETEA (unique Name, Description, Ingredients, Price); customers sign up with a BubbleID, Name, Phone, Email; each order (BUYS) is timestamped with a PrepTime; customers can friend other customers.
NoteWorking
BUBBLETEA —N:M BUYS (PrepTime, key Timestamp)→ CUSTOMER (BubbleID); CUSTOMER has a recursive M:N FRIENDS relationship with itself (roles Requestor/Requestee).
flowchart LR
    BUBBLETEA[BUBBLETEA] ---|"N"| BUYS{BUYS}
    BUYS ---|"M"| CUSTOMER2[CUSTOMER]
    CUSTOMER2 ---|"Requestor"| FRIENDS{FRIENDS}
    FRIENDS ---|"Requestee"| CUSTOMER2

    NameB(["Name (key)"]) --- BUBBLETEA
    Description2(["Description"]) --- BUBBLETEA
    Ingredients(["Ingredients"]) --- BUBBLETEA
    Price(["Price"]) --- BUBBLETEA
    Timestamp2(["Timestamp (partial key)"]) --- BUYS
    PrepTime(["PrepTime"]) --- BUYS
    BubbleID(["BubbleID (key)"]) --- CUSTOMER2
Question 2 — Bank
Bank (composite key Code+Name, Address) has branches (Number unique per-bank, Address); a branch manages accounts and loans; every account has Type, Balance, unique Number, controlled by ≥1 customers; every loan has unique Number, Type, Amount, connected to ≥1 customers; every loan/account belongs to exactly one branch; customers have Name, Address, Phone, unique ID.
NoteWorking
BANK (key Key = Code+Name) —1:N OPERATES→ BRANCH (weak entity, partial key Number) —1:N OFFERS→ LOAN (Number, Type, Amount); BRANCH —1:N OFFERS→ ACCOUNT (Number, Balance, Type). LOAN —M:N HAS→ CUSTOMER (ID, Name, Address, Phone); ACCOUNT —M:N HAS→ CUSTOMER, both with total participation on the LOAN/ACCOUNT side (“must be associated with… at least one customer”).
flowchart TD
    BANK[BANK] ---|"1"| OPERATES{OPERATES}
    OPERATES ===|"N"| BRANCH[[BRANCH]]
    BRANCH ---|"1"| OFFERS1{OFFERS}
    OFFERS1 ---|"N"| LOAN[LOAN]
    BRANCH ---|"1"| OFFERS2{OFFERS}
    OFFERS2 ---|"N"| ACCOUNT[ACCOUNT]
    LOAN ===|"M"| HAS3{HAS}
    HAS3 ---|"N"| CUSTOMER3[CUSTOMER]
    ACCOUNT ===|"M"| HAS4{HAS}
    HAS4 ---|"N"| CUSTOMER3

    BankKey(["Key (key)"]) --- BANK
    Code(["Code"]) --- BankKey
    BName(["Name"]) --- BankKey
    BranchNum(["Number (partial key)"]) --- BRANCH
    LoanNum(["Number (key)"]) --- LOAN
    AcctNum(["Number (key)"]) --- ACCOUNT
    IDc2(["ID (key)"]) --- CUSTOMER3
Case Study 2: Dirt Road Driving
Group case study applying integrity constraints from 2026-03-09-the-relational-model-and-integrity-constraints to Dirt Road Driving’s internal payroll system. See relational-mapping-notation for reference.
Section A — The schema
Dirt Road Driving’s payroll backend, built by an external developer:
Employee [id, firstName, lastName, role]

Project [name, description, funding, projectLeader]
Project.projectLeader references Employee.id

TimeLog [employeeID, projectName, date, hoursWorked, approved]
TimeLog.employeeID references Employee.id
TimeLog.projectName references Project.name
Company policy (a semantic/business-rule constraint, not enforceable by the schema’s structure alone): administration staff cannot be project leaders.
Question 1 — Identify a key and a foreign key
NoteWorking
Any candidate key works, e.g. Employee.id, Project.name, or TimeLog.{employeeID, projectName, date} (composite). Any foreign key works, e.g. Project.projectLeader, TimeLog.employeeID, or TimeLog.projectName.
Section B — Integrity constraint violations
Sample data: Employee has (1919, Diluen, Smith, Developer), (2014, Daniel, Johnson, Administration), (2019, Annie, Fang, Developer), (2020, Russell, Turner, Manager). Project has ("Website Setup", ..., 12000, 2019), ("2020 Marketing", ..., 40000, 2020). TimeLog has 5 rows, including (1919, "Website Setup", 2/1/2020, 5, true) and (2020, "2020 Marketing", 2/1/2020, 5, true), among others — no row with employeeID = 1919 and projectName = "2020 Marketing". For each operation, does it violate an integrity constraint?
Operation 1 — Update ("Website Setup", ..., 12000, 2019) to ("Website Setup", ..., 20000, 1919) in Project (changes funding and projectLeader; 1919 is a Developer).
Operation 2 — Insert (2014, "Rebecca", "Zhang", "Administration") into Employee.
Operation 3 — Update (2020, "2020 Marketing", 2/1/2020, 5, true) to (1919, "Overall Marketing", 2/1/2020, 5, true) in TimeLog.
Operation 4 — Insert (NULL, "Test", "Test", "Test") into Employee.
Operation 5 — Delete (2014, "Daniel", "Johnson", "Administration") from Employee.
Operation 6 — Insert ("Talent Recruitment Initiative", ..., 10000, 2014) into Project (2014 is Administration).
NoteWorking
- Op 1 No — a well-formed update;
funding/projectLeadervalues both change to valid new values (1919is a real, existing employee), and nothing here conflicts with a key/entity/referential/semantic rule. - Op 2 Yes — Key constraint.
id = 2014already exists inEmployee(idis its primary key), so this insert isn’t unique. - Op 3 Yes — Referential integrity.
TimeLog.projectNamereferencesProject.name, but noProjectnamed"Overall Marketing"exists — the foreign key value doesn’t resolve. - Op 4 Yes — Entity integrity.
Employee.idis the primary key, and it’sNULLhere — no part of a primary key may ever beNULL. - Op 5 Yes — Referential integrity.
TimeLog.employeeID(foreign key toEmployee.id) has a row referencingemployeeID = 2014— deleting thatEmployeerow would leave it dangling. (Strictly: under the defaultON DELETE RESTRICT— see below.) - Op 6 Yes — Semantic (user-defined) constraint.
projectLeader = 2014is anAdministrationstaff member, violating the business rule that administration staff cannot be project leaders — this isn’t something the schema’s structure alone captures (no foreign key/domain/key rule is broken), it’s an organisation-specific policy.
What a deletion actually “violates”
Ops 3 and 5 are both answered “referential integrity”, but only one of them is a fact about the data. Op 3 sets TimeLog.projectName to "Overall Marketing", and no Project row carries that name — nothing the schema can be told will make that value resolve. Op 5 deletes an Employee row that a TimeLog row still points at, and there the foreign key declaration chooses the outcome: what happens to the child rows is a referential triggered action, written alongside the foreign key in the CREATE TABLE (or added later by ALTER TABLE), in the same shape the lecture uses:
CONSTRAINT employee_fk FOREIGN KEY (employeeID) REFERENCES Employee(id)
    ON DELETE RESTRICT ON UPDATE CASCADE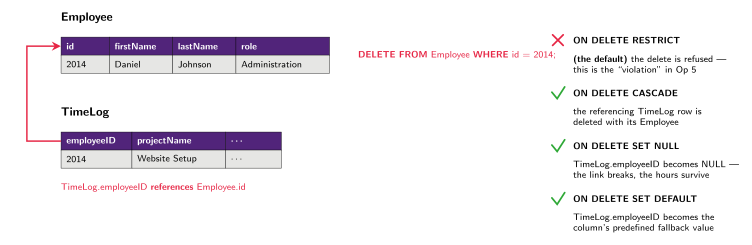
Figure 19: The four referential triggered actions, applied to this case study’s own foreign key. Only the first refuses the delete, so “Op 5 violates referential integrity” is really “Op 5 violates it under the default ON DELETE RESTRICT” — under the other three the delete succeeds and the child row is redefined instead. The crimson arrow is the course’s foreign-key convention: arrowhead on the referenced attribute, pointing from child to parent. The brief states only that some TimeLog row references employee 2014 without spelling that row out; the row drawn stands in for it.
So a “violation” of referential integrity on a delete is a statement about the schema as much as about the data — the same delete is legal, illegal or silently destructive depending on one clause. The identical four choices exist as ON UPDATE … and govern a change to a referenced value: renaming Employee.id 2014 raises exactly the same question as deleting the row. See foreign-keys and sql-ddl.
Question 2 — Original examples
Give an original example (not copied from above) of an operation that would cause (a) a domain constraint violation, (b) a referential integrity constraint violation.
NoteWorking
- Domain constraint: inserting
("A string is not a number", "Joe", "Blog", "Administration")intoEmployee—idis meant to be numeric, not a string. (b) Referential integrity: deleting(2020, "Russell", "Turner", "Manager")fromEmployeewhile aProjectrow still hasprojectLeader = 2020— the deletion would leave that foreign key dangling.
Week 4
ER to Relational Mapping
Module 2, part 2 — continues on from 2026-03-09-the-relational-model-and-integrity-constraints. See relational-mapping-notation for the schema notation used throughout, and er-diagram-notation for the ER/EER diagram notation being mapped from.
Today’s outline
- The (7+1) steps for mapping an ER/EER diagram to a relational schema
- Worked example: the Company database
- Worked example: a Bank database
Why map at all?
The ER model is commonly used for conceptual design (user’s perspective); the relational model is the basis for most commercial DBMSs (storage perspective). Mapping converts a conceptual ER schema into a logical relational schema — input: an ER model; output: relations with primary/foreign key constraints.
The (7+1) steps
- Entity mapping
- Weak entity mapping
- Binary 1:1 relationship mapping
- Binary 1:N relationship mapping
- Binary M:N relationship mapping
- Multivalued attribute mapping
- N-ary relationship mapping
- (+1, for EER only) Super/subclass mapping
Super/subclass mapping (step “+1”) doesn’t happen at one fixed point — it’s generally done after step 1 or 2, whenever the subclass needs to exist for a later relationship-mapping step to reference it.
Running example — the Company database: EMPLOYEE (key Ssn, composite Name → Fname/Mit/Lname, Sex, Salary, Address, DOB), DEPARTMENT (keys Dnumber/Dname, derived NumberOfEmployees, multivalued Locations), PROJECT (keys Pno/Pname, Plocation), DEPENDENT (weak entity, partial key DepName, Sex, DOB, Relationship) — relationships WORKSFOR (EMPLOYEE N:1 DEPARTMENT), MANAGES (EMPLOYEE 1:1 DEPARTMENT, attribute StartDate), CONTROLS (DEPARTMENT 1:N PROJECT), WORKSON (EMPLOYEE M:N PROJECT, attribute Hours), SUPERVISION (EMPLOYEE recursive 1:N, roles supervisor/supervisee), DEPENDENTSOF (EMPLOYEE 1:N DEPENDENT, identifying), and EMPLOYEE disjointly (d) specialises into SECRETARY (TypingSpeed)/ENGINEER (EngineerType).
Step 1 — Entity mapping
For each (strong) entity type: create a relation, choose a key as the primary key, and include all simple attributes (not composite, derived, or multivalued).
Employee [ssn, fName, mIt, lName, dob, address, sex, salary]

Department [dNumber, dName]

Project [pNo, pName, pLocation]
Name isn’t added directly (it’s composite — its simple components fName/mIt/lName are added instead); Locations and NumberOfEmployees aren’t added to Department yet (multivalued and derived respectively — derived attributes are never stored as columns, since they’re computed on demand).
Step 2 — Weak entity mapping
For each weak entity type: create a relation; its primary key is the combination of its owner’s primary key(s) and its own partial key; include a foreign key back to the owner’s primary key; include all simple attributes.
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn
Ssn (Employee’s key) is included as part of Dependent’s own primary key, and depName is its partial key — so Dependent’s full key is (ssn, depName).
If a weak entity has more than one owner entity type, its relation includes a foreign key to each owner’s primary key, and its own primary key is the combination of all owner keys plus its partial key.
Question — Weak Entities (Cities/Provinces)
PROVINCE (key name, premier) —1:N IN→ CITY (partial key name, mayor). Resolving the dual use of “name” reasonably, which schema is the most reasonable translation?
A. Cities [name, mayor], Provinces [name, premier]
B. Cities [cName, pName, mayor], Provinces [pName, premier], Cities.cName references Provinces.pName, Cities.pName references Provinces.pName
C. Cities [cName, pName, mayor], Provinces [pName, premier], Cities.pName references Provinces.pName
D. Cities [cName, pName, mayor], In [cName, pName], Provinces [name, premier], Cities.pName references Provinces.name
NoteSolution
(C). CITY is a weak entity, so its real key is (pName, cName) — (A) is wrong since it drops pName from Cities’ key entirely. (B) is wrong because cName (the partial key) is not a foreign key — only pName (inherited from the owner) is. (D) is wrong because IN is the identifying relationship for a weak entity — it does not get mapped to its own separate relation (unlike a regular 1:N relationship, which doesn’t need one either, but D invents an unnecessary one here on top of misnaming Provinces’ key column).
Step 3 — Binary 1:1 relationship mapping
For each binary 1:1 relationship: choose one participating entity type (prefer the one with total participation); include a foreign key from it back to the other entity’s primary key; include the relationship’s own simple attributes on the chosen side.
MANAGES (EMPLOYEE 1:1 DEPARTMENT, DEPARTMENT has total participation — every department must have a manager) — extend Department, since it’s the side with total participation:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn
Question — Binary Relationship
S —1:1 R→ T (T has attribute b1). Which schema is a reasonable translation?
A. S [a1, b1], T [b1], S.b1 references T.b1
B. S [a1], T [b1]
C. ST [a1, b1]
D. S [a1], T [b1, a1], T.a1 references S.a1
NoteSolution
(A). S should be the side extended with the foreign key, since S has full/total participation in R (shown by the diagram’s 1 cardinality directly against S, no partial-participation gap) — preferred over T for that reason. (B) loses all information about the relationship itself. (C) merges two intentionally-separate entity types into one relation, discarding a conceptual modelling decision. (D) puts the foreign key on the wrong side.
Step 4 — Binary 1:N relationship mapping
For each (non-weak) binary 1:N relationship: identify the entity type on the N side; add a foreign key there, referencing the primary key of the entity type on the 1 side; include the relationship’s simple attributes on the N side.
WORKSFOR (EMPLOYEE N:1 DEPARTMENT), CONTROLS (DEPARTMENT 1:N PROJECT), SUPERVISION (EMPLOYEE recursive, N side = supervisee):
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber
Question — Relationship Mapping
A —N R 1→ B —N S 1→ C (with attributes a/d on A, b/e on B, c/f on C). Which of the following appears in your relational schema: (A) A [a, b, d], A.b references B.b; (B) B [b, c, e], B.c references C.c; (C) S [b, c]; (D) all of the above; (E) none of the above?
NoteSolution
(B). Each 1:N relationship puts the foreign key on the N side: for R that’s A (referencing B), and for S that’s B (referencing C) — so B [b, c, e], B.c references C.c is exactly right. (A) is wrong: b is the right foreign key column for A, but it shouldn’t be part of A’s primary key — 1:N foreign keys are plain (non-key) attributes on the N side, not treated as part of a composite key like a weak entity’s would be (the answer as written implies b joining A’s key, which the mapping rule doesn’t call for). (C) is wrong — S is a relationship, not an entity type, so 1:N mapping doesn’t create a relation for it at all. The full correct schema: A [a, b, d], A.b references B.b; B [b, c, e], B.c references C.c; C [c, f].
Step 5 — Binary M:N relationship mapping
For each binary M:N relationship: create a new relation; include foreign keys to both participating entity types’ primary keys (their combination becomes the new relation’s primary key); include the relationship’s own simple attributes.
WORKSON (EMPLOYEE M:N PROJECT, attribute Hours):
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo
Note: 1:1 and 1:N relationships can also be mapped this same “new relation” way — useful when the relationship is sparse, since it avoids NULL foreign key values that a direct-embedding mapping would otherwise produce for non-participating rows.
Step 6 — Multivalued attribute mapping
For each multivalued attribute: create a new relation; include a foreign key to the owning entity’s primary key; the new relation’s primary key is the combination of that foreign key and the multivalued attribute itself (if the multivalued attribute is composite, include its simple components instead).
DEPARTMENT.Locations:
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Step 7 — N-ary relationship mapping
For each N-ary relationship (excluding all-1-side cases): create a new relation; include foreign keys to all participating entity types; the foreign keys coming from the many-side entity types form the primary key; include the relationship’s own simple attributes.
(No N-ary relationships in the Company database — WORKSON is binary.)
Step “+1” — Super/subclass mapping (EER)
Works for any combination of total/partial and disjoint/overlapping subclasses. For each subclass: create a relation; its primary key is the superclass’s primary key; include a foreign key back to the superclass’s relation; include the subclass’s own simple attributes.
EMPLOYEE disjointly specialises into SECRETARY/ENGINEER:
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn
This step doesn’t happen at one fixed position in the 7-step sequence — it’s usually done right after step 1 or 2 (whichever applies to the superclass), specifically so the subclass relations already exist by the time any later relationship-mapping step needs to reference them.
Final schema — Company database
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn

Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn

Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber

Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn

Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn

Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn

WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo

DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumber
Worked example — Bank database
A bank (unique code, name, hoAddr) has branches (branchNo unique per-bank, addr). A branch has accounts (acNo, type, balance, ≥1 account holders) and loans (loanNo, type, amount, ≥1 loan holders). Customers (ssn, name, address) can hold accounts and/or loans.
Working through the same 7 steps:
After step 1 (entity mapping):
Bank [code, name, hoAddr]

Account [acNo, type, balance]

Loan [loanNo, type, amount]

Customer [ssn, name, address]
After step 2 (BRANCH is a weak entity, owned by BANK):
Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code
After step 4 (BRANCH 1:N ACCOUNT/LOAN — foreign keys added to the N side; note the FK is composite here, since Branch’s own key is composite):
Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}
After step 5 (ACCOUNT/LOAN M:N CUSTOMER — new relations):
AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Final schema:
Bank [code, name, hoAddr]

Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code

Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}

Customer [ssn, name, address]

AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn

LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssn
Applied Class 3: Relational Integrity
Practice for 2026-03-09-the-relational-model-and-integrity-constraints. See relational-mapping-notation for reference.
Section A — Recap and preview
Question 1 — Matching relational concepts
Match each concept to its description: (1) any minimal set of attributes that can uniquely identify tuples in a relation, (2) defines the structure of a relation, specified during database design, (3) a candidate key chosen to identify tuples in a relation, (4) data in a relation, modified via create/update/delete operations.
NoteWorking
Candidate key → 1, Relational Schema → 2, Primary Key → 3, Relational Instance → 4.
Question 2 — Electoral roll schema
Given:
Region [prefix, suffix]

Member [enrolmentId, passportNum, regionPrefix, regionSuffix]
Member.{regionPrefix, regionSuffix} references Region.{prefix, suffix}

Candidate [enrolmentId, name, regionPrefix, regionSuffix]
Candidate.enrolmentId references Member.enrolmentId
Candidate.{regionPrefix, regionSuffix} references Region.{prefix, suffix}
List all examples of each component: candidate key, primary key, composite primary key, foreign key.
The schema comes from this ER diagram, and every answer below can be read straight off it:
Figure 20: The electoral-roll ER diagram the Question 2 schema was mapped from. CANDIDATE is a subclass of MEMBER (the arc on the connecting line, opening towards the superclass), which is why Candidate.enrolmentId is simultaneously its primary key and a foreign key to Member. REGION’s key Code is a composite attribute splitting into Prefix and Suffix, which is why the mapped primary key is the pair. Both EnrolmentID and PassportNum are drawn as key attributes, giving MEMBER two candidate keys.
NoteWorking
- Candidate key:
Member.enrolmentId,Member.passportNum,Candidate.enrolmentId,Region.{prefix, suffix}. - Primary key:
Member.enrolmentId,Candidate.enrolmentId,Region.{prefix, suffix}. - Composite primary key:
Region.{prefix, suffix}. - Foreign key:
Member.{regionPrefix, regionSuffix},Candidate.{regionPrefix, regionSuffix},Candidate.enrolmentId.
Three things to notice, because each is a different rule doing the work: Member.passportNum is a candidate key that lost the nomination, so it is not a primary key (relational-keys); Region.{prefix, suffix} is the only composite primary key here, and it forces every reference to it to be a composite foreign key; and Candidate.enrolmentId is the one attribute that is a primary key and a foreign key at once, because CANDIDATE is a subclass of MEMBER and subclass mapping gives the subclass relation its superclass’s key.
Question 3 — Schema statements
Select all true statements: (1) a schema is the metadata, or data describing the data, (2) a schema is specified during database design, (3) a schema is created during data updates and changes frequently, (4) a schema is the data in the database at a particular time.
Enter the correct option numbers in ascending order, comma-separated:
NoteWorking
1, 2. A schema is metadata specified at design time — it doesn’t change with every data update (that’s the instance), and it isn’t itself “the data” (statements 3 and 4 both describe the instance, not the schema).
Question 4 — Key statements
Select all true statements: (1) a key is a unique identifier of a tuple in the relation, (2) the key constraint implies no two tuples can share the same values for all attributes, (3) a key cannot have multiple attributes, (4) an entity may have more than one primary key, (5) a primary key is a candidate key chosen as the main key for a relation.
Enter the correct option numbers in ascending order, comma-separated:
NoteWorking
1, 5. (2) is a weaker, different notion (that’s just basic set semantics — no two tuples are ever fully identical in a relation regardless of keys — not what makes something a key specifically). (3) is false — composite keys exist (e.g. Region.{prefix, suffix} above). (4) is false — an entity can have several candidate keys, but only one of them is chosen as the primary key.
Section B — Integrity constraints in practice
A company database: Employee [ssn, fName, mInit, lName, bDate, address, sex, salary, superSsn, dNo], Department [dName, dNumber, mgrSsn, mgrStartDate], DeptLocations [dNumber, dLocation], Project [pName, pNumber, pLocation, dNum], WorksOn [essn, pNo, hours], Dependent [essn, depName, sex, bDate, relationship]. Two extra business rules, requested by the Board of Directors on top of the DBMS-enforced ones: an employee’s salary cannot exceed their supervisor’s, and a department cannot have more than three active projects at a time. For each operation below, does it violate an integrity constraint (assume any earlier operations in this list have not been applied)?
Every answer in this section is a question about the arrows below, so read the foreign-key map before the operations:
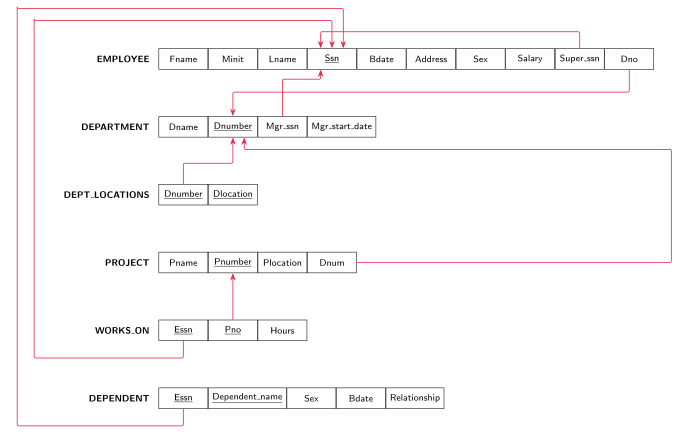
Figure 21: The relational diagram for the company database: eight foreign keys over six relations. Arrowheads land on the referenced attribute: an arrow points child → parent. Three separate relations reference Employee.ssn and Employee references itself through Super_ssn, which is why deleting one employee row is the messiest operation in Section B. Attribute names in the diagram are the textbook spellings (Ssn, Dno, Essn, Pno); the prose above uses the camelCase equivalents for the same columns. Each component of a composite key is underlined in its own box, where the written schema convention runs one continuous underline.
NoteInstance data the operations are judged against
Employee
| fName | mInit | lName | ssn | bDate | address | sex | salary | superSsn | dNo |
|---|---|---|---|---|---|---|---|---|---|
| John | B | Smith | 123456789 | 1965-01-09 | 731 Fondren, Houston, TX | M | 30000 | 333445555 | 5 |
| Franklin | T | Wong | 333445555 | 1955-12-08 | 638 Voss, Houston, TX | M | 40000 | 888665555 | 5 |
| Alicia | J | Zelaya | 999887777 | 1968-01-19 | 3321 Castle, Spring, TX | F | 25000 | 987654321 | 4 |
| Jennifer | S | Wallace | 987654321 | 1941-06-20 | 291 Berry, Bellaire, TX | F | 43000 | 888665555 | 4 |
| Ramesh | K | Narayan | 666884444 | 1962-09-15 | 975 Fire Oak, Humble, TX | M | 38000 | 333445555 | 5 |
| Joyce | A | English | 453453453 | 1972-07-31 | 5631 Rice, Houston, TX | F | 25000 | 333445555 | 5 |
| Ahmad | V | Jabbar | 987987987 | 1969-03-29 | 980 Dallas, Houston, TX | M | 25000 | 987654321 | 4 |
| James | E | Borg | 888665555 | 1937-11-10 | 450 Stone, Houston, TX | M | 55000 | NULL | 1 |
Department and DeptLocations
| dName | dNumber | mgrSsn | mgrStartDate |
|---|---|---|---|
| Research | 5 | 333445555 | 1988-05-22 |
| Administration | 4 | 987654321 | 1995-01-01 |
| Headquarters | 1 | 888665555 | 1981-06-19 |
| dNumber | dLocation |
|---|---|
| 1 | Houston |
| 4 | Stafford |
| 5 | Bellaire |
| 5 | Sugarland |
| 5 | Houston |
Project and WorksOn
| pName | pNumber | pLocation | dNum |
|---|---|---|---|
| ProductX | 1 | Bellaire | 5 |
| ProductY | 2 | Sugarland | 5 |
| ProductZ | 3 | Houston | 5 |
| Computerization | 10 | Stafford | 4 |
| Reorganization | 20 | Houston | 1 |
| Newbenefits | 30 | Stafford | 4 |
| essn | pNo | hours |
|---|---|---|
| 123456789 | 1 | 32.5 |
| 123456789 | 2 | 7.5 |
| 666884444 | 3 | 40.0 |
| 453453453 | 1 | 20.0 |
| 453453453 | 2 | 20.0 |
| 333445555 | 2 | 10.0 |
| 333445555 | 3 | 10.0 |
| 333445555 | 10 | 10.0 |
| 333445555 | 20 | 10.0 |
| 999887777 | 30 | 30.0 |
| 999887777 | 10 | 10.0 |
| 987987987 | 10 | 35.0 |
| 987987987 | 30 | 5.0 |
| 987654321 | 30 | 20.0 |
| 987654321 | 20 | 15.0 |
| 888665555 | 20 | NULL |
Dependent
| essn | depName | sex | bDate | relationship |
|---|---|---|---|---|
| 333445555 | Alice | F | 1986-04-05 | Daughter |
| 333445555 | Theodore | M | 1983-10-25 | Son |
| 333445555 | Joy | F | 1958-05-03 | Spouse |
| 987654321 | Abner | M | 1942-02-28 | Spouse |
| 123456789 | Michael | M | 1988-01-04 | Son |
| 123456789 | Alice | F | 1988-12-30 | Daughter |
| 123456789 | Elizabeth | F | 1967-05-05 | Spouse |
The three facts that decide most of Section B: the only department numbers in use are 1, 4 and 5; department 5 already has three projects (ProductX, ProductY, ProductZ), which is the semantic limit; and 888665555 (James Borg) earns 55000, so any subordinate of his earning more breaks the salary rule.
B1 — Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into Employee (943775543 is not yet an Employee ssn; the supervisor 888665555 is James Borg, who earns 55000 and runs department 1).
B2 — Insert ('ProductA', 'A', 'Bellaire', 2) into Project (no Department with dNumber = 2 exists).
B3 — Insert ('Production', 4, 943775543, '1988-10-01') into Department (a Department with dNumber = 4 already exists; no Employee with ssn = 943775543 exists).
B4 — Insert (677678989, null, 40.0) into WorksOn (no Employee with ssn = 677678989 exists).
B5 — Insert ('Grace', 'G', 'Chan', 31203126, '1962-06-21', '2312 Anchor Rd, Bellaire, TX', 'F', 58000, 888665555, 1) into Employee (supervisor 888665555 earns less than 58000).
B6 — Delete the WorksOn tuples with essn = 333445555.
B7 — Delete the Employee tuple with ssn = 987654321.
B8 — Modify mgrSsn/mgrStartDate of the Department tuple with dNumber = 5 to 123456789/'1988-10-01' (123456789 is an existing Employee SSN).
B9 — Modify superSsn of the Employee tuple with ssn = 999887777 to 943775543 (no Employee with ssn = 943775543 exists).
B10 — Insert ('ProductSuperDuperSecret', 86, 'Washington', 5) into Project (department 5 already has three active projects).
NoteWorking
- B1 No — this is a well-formed, non-conflicting insert: the new
ssndoesn’t already exist (no key violation), the supervisorssndoes exist (no referential violation), and the salary doesn’t exceed the supervisor’s (no semantic violation). - B2 Yes — Referential integrity (
dNum = 2doesn’t exist inDepartment) and domain constraint (pNumbershould be an integer, not the string'A'). - B3 Yes — Key constraint (
dNumber = 4already exists) and referential integrity (mgrSsn = 943775543doesn’t exist inEmployee). - B4 Yes — Entity integrity (
pNo, part ofWorksOn’s primary key, isNULL) and referential integrity (essn = 677678989doesn’t exist inEmployee). - B5 Yes — Semantic constraint (this employee’s salary exceeds their supervisor’s).
- B6 No — nothing else references
WorksOnrows as a foreign key target, and no business rule requires an employee to have work assignments, so deleting them is unconstrained. - B7 Yes — Referential integrity (
WorksOn,Dependent,Department, andEmployeeitself all have tuples referencing thisssn, which would be left dangling). - B8 No —
123456789is a valid existing employee,dNumber = 5already exists (this is an update, not a duplicate insert), and no stated business rule constrains who can be a department’s manager. - B9 Yes — Referential integrity (the new
superSsnvalue doesn’t match any existingEmployee.ssn). - B10 Yes — Semantic constraint (exceeds the “max 3 active projects per department” business rule).
Case Study 3: Dirt Road Driving
Group case study applying ER-to-relational mapping from 2026-03-16-er-to-relational-mapping to a revised Dirt Road Driving EER diagram (the EER diagram itself is week2-tutorial-case-study-1-dirt-road-driving’s, refined per that case study’s open-ended Section B). See relational-mapping-notation for reference.
Section A — Full relational mapping
Elaine’s team maps the revised EER diagram (User, Staff disjointly specialising into Driver/Admin, Vehicles disjointly specialising into 4WD/2WD, weak entities EmergencyContact and TripStop, the ternary-ish Trip, and the UserRatesDriver/ UserRatesVehicle relationships) to a full relational schema.
NoteWorking
User [id, dob, firstName, middleName, lastName]

Staff [id, dob, firstName, middleName, lastName]

Vehicles [vin, make, model]

Driver [id, licence]
Driver.id references Staff.id

Admin [id, deskNumber]
Admin.id references Staff.id

4WD [vin, rideHeight, wheelType]
4WD.vin references Vehicles.vin

2WD [vin, frontWheelDrive]
2WD.vin references Vehicles.vin

EmergencyContact [userID, name, email, phone]
EmergencyContact.userID references User.id

StaffPhone [id, phone]
StaffPhone.id references Staff.id

Trip [userID, driverID, vin, bookingTime, startTime, endTime]
Trip.userID references User.id
Trip.driverID references Driver.id
Trip.vin references Vehicles.vin

TripStop [userID, driverID, vin, bookingTime, location]
TripStop.{userID, driverID, vin, bookingTime} references Trip.{userID, driverID, vin, bookingTime}

UserRatesDriver [userID, driverID, rating]
UserRatesDriver.userID references User.id
UserRatesDriver.driverID references Driver.id

UserRatesVehicle [userID, vin, rating]
UserRatesVehicle.userID references User.id
UserRatesVehicle.vin references Vehicles.vin
Key points:
Driver/Adminand4WD/2WDare standard disjoint-subclass mappings — each subclass’s primary key is its superclass’s key, plus a foreign key back to the superclass.EmergencyContactis a weak entity owned byUser— its real key is(userID, name)(owner’s key + its own partial keyname), not justnamealone (a name is only guaranteed unique per user).StaffPhonemapsStaff’s multivaluedPhoneattribute — its primary key is(id, phone)(the multivalued attribute joins the owner’s key to form the key, per the multivalued-attribute mapping rule), which makes sense of whyphoneisn’t shown as a single extra column onStaffitself.Tripis identified by the combination ofuserID,driverID,vin, andbookingTime— a trip is only unique per that combination (the same user/driver/vehicle triple could recur across different bookings).TripStopis a weak entity too, owned byTrip— it needsTrip’s entire composite key as a foreign key, plus its own partial keylocation.UserRatesDriver/UserRatesVehicleare both M:N relationships (each gets its own new relation, combining both sides’ foreign keys as its primary key, plus the relationship’s ownratingattribute).
Section B — Spot the mistakes
A junior admin partially mapped the same diagram:
User [id, dob, firstName, middleName, lastName]

Staff [id, dob, firstName, middleName, lastName]

Vehicles [vin, make, model]

EmergencyContact [name, userID, email, phone]
EmergencyContact.userID references User.id

Trip [userID, driverID, vin, bookingTime, startTime, endTime]
Trip.userID references User.id
Trip.driverID references Staff.id
Trip.vin references Vehicles.vin

UserRatesDriver [userID, driverID, rating]
UserRatesDriver.userID references User.id
UserRatesDriver.driverID references Driver.id

Driver [id, licence]
Driver.id references Staff.id

4WD [vin, make, model, rideHeight, wheelType]
4WD.vin references Vehicles.vin

StaffPhone [id, phone]
StaffPhone.id references Staff.id
Find 5 mistakes (ignore “missing tables” — some relations from Section A are simply left out here, and that’s not one of the 5).
NoteWorking
EmergencyContact’s primary key is missinguserID. As a weak entity, its key must be(userID, name), notnamealone — otherwise two different users couldn’t each have an emergency contact with the same name (e.g. two users both listing a contact named “Mum”).Trip’s primary key is missingbookingTime. Without it, a user couldn’t take two separate trips with the same driver and vehicle —bookingTimeis exactly what distinguishes repeat trips between the same pair.Trip.driverIDincorrectly referencesStaff.idinstead ofDriver.id. This would let anAdmin-only staff ID (someone who isn’t aDriverat all) be entered as a trip’s driver, corrupting the data and undermining any audit that assumesdriverIDalways names an actual driver.4WDredundantly repeatsmake/model. These are already stored onVehicles(the superclass) — duplicating them wastes space and risks the two copies going out of sync.StaffPhone’s primary key is missingphone. As the mapping of a multivalued attribute, the key must be(id, phone)— withoutphonein the key, each staff member could only ever have one phone number on file, defeating the purpose of the multivalued attribute allowing several.
Week 5
Applied Class 4: Entity Relationship Mapping
Practice for 2026-03-16-er-to-relational-mapping. See relational-mapping-notation and er-diagram-notation for reference.
Section A — Basic mapping
Question 1 — Select the correct mapping
A diagram combining several mapping rules at once: H (strong entity, key i, attribute j) and A (strong entity, key b, attributes c, d) participate in a ternary relationship K (roles: N for H, M for A, 1 for P, own attribute l) together with P (strong entity, key q, attribute r). A —1:N R1→ E (weak entity, partial key f, attribute g). A —1:1 R2— P. P —1:N S→ M (weak entity, partial key o).
NoteWorking
H [i, j]

A [b, c, d]

E [b, f, g]
E.b references A.b

P [q, b, r]
P.b references A.b

K [b, i, q, l]
K.b references A.b
K.i references H.i
K.q references P.q

M [q, o]
M.q references P.qEis a weak entity owned byA— its key is(b, f)(A’s key- its own partial key
f).
- its own partial key
R2is a plain 1:1 relationship betweenAandP— merge it into one side rather than creating a separate relation for it;Pis extended withA’s key as a foreign key here.Kis a ternary relationship — its own relation gets a foreign key to all three participants, but only the foreign keys from the many-cardinality sides (H’sNandA’sM) form the primary key;P’s foreign key (q, the1side) is a plain attribute, not part of the key — same pattern as the N-ary “1:1:1 & N:1:1” worked cases.Mis a second weak entity, this time owned byP— key(q, o).
Question 2 — Subclasses and weak entities
F (key a, composite attribute b → c/d) has a recursive 1:N relationship R (attribute r), and disjointly (d) specialises into G (attributes i, j) and H (attribute k). H —1:N S→ X (weak entity, partial key x, attributes y, z).
(a) What’s the relationship between F, G, H, and how are G/H mapped? (b) Interpret S/X with respect to H.
NoteWorking
(a) G and H are disjoint subclasses of F (an instance is at most one of G/H, never both). Standard subclass mapping — each subclass’s primary key is the superclass’s primary key, plus a foreign key back to it:
F [a, c, d, superF, r]
F.superF references F.a

G [a, i, j]
G.a references F.a

H [a, k]
H.a references F.a(F.superF/r come from R, F’s own recursive 1:N relationship — mapped the same way as any binary 1:N relationship, just back onto F itself.)
(b) X is a weak entity owned by H via the identifying relationship S — each X belongs to exactly one H, but one H can own many Xs. X’s real key is (a, x) (H’s key, inherited from F, plus X’s own partial key x):
X [a, x, y, z]
X.a references H.a
Question 3 — Olympics database
Map the ER diagram: Athlete (id, sex, name, age, country) —M:N Participates (placement)→ Event (id, name, category) —N:1 Venue (id, name, address).
NoteWorking
Athlete [id, sex, name, age, country]

Venue [id, name, address]

Event [id, name, category, venue]
Event.venue references Venue.id

Participates [athleteID, eventID, placement]
Participates.athleteID references Athlete.id
Participates.eventID references Event.idEvent—Venue is 1:N, so Event (the N side) gets a plain foreign key. Athlete—Event is M:N, so Participates is its own new relation, carrying both foreign keys plus the relationship’s own attribute placement.
Section B — Advanced mapping
Question 1 — Cinema
Map: Movie (name, description, runningTime) —1:N Viewing (date, time, multivalued Snack)←1:N Customer (id, name, email), each Viewing overseen by exactly one Attendant (staffId, name, phone).
NoteWorking
Movie [name, description, runningTime]

Customer [id, name, email]

Attendant [staffID, name, phone]

Viewing [name, id, date, time, attendant]
Viewing.name references Movie.name
Viewing.id references Customer.id
Viewing.attendant references Attendant.staffID

ViewingSnack [name, id, date, time, snack]
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}Viewing’s own key is the composite (name, id, date, time) — the movie + customer + timestamp jointly identify one viewing. Snack is multivalued, so it gets its own relation (ViewingSnack) with a composite foreign key back to the full Viewing key.
Question 2 — Student peer evaluation
Map: Student (sid, firstName, secondName) submits Assessments (sid+number); students peer-evaluate each other’s assessment submissions, recording a mark.
NoteWorking
Student [sid, firstName, secondName]

Assessment [sid, number]
Assessment.sid references Student.sid

PeerEvaluation [studentSid, assessmentSid, number, evaluationId, sidGrades, mark]
PeerEvaluation.studentSid references Student.sid
PeerEvaluation.sidGrades references Student.sid
PeerEvaluation.{assessmentSid, number} references Assessment.{sid, number}
PeerEvaluation has two separate foreign keys to Student playing different roles — studentSid (the evaluator submitting the mark) and sidGrades (whose assessment is being marked) — plus a composite foreign key to the specific Assessment being evaluated.
Question 3 — Spot the mistakes
A junior developer mapped question 1’s Cinema diagram as:
Movie [name, description, runningTime]

Customer [id, name, email]

Attendant [staffID, name, phone]

Viewing [name, id, date, time, attendant]
Viewing.name references Movie.name
Viewing.id references Customer.id
Viewing.attendant references Attendant.staffID

ViewingSnack [name, id, date, time, snack]
ViewingSnack.name references Movie.name
ViewingSnack.id references Viewing.id
ViewingSnack.date references Viewing.date
ViewingSnack.time references Viewing.time
Find the mistakes.
NoteWorking
ViewingSnack should reference Viewing’s composite key as one foreign key constraint (ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}), not four separate, independently-named foreign key lines pointing at different tables (Movie for name, Viewing for id, and Viewing again for date/time, inconsistently) — splitting a composite foreign key up like this breaks the link between a ViewingSnack and the specific Viewing it belongs to (nothing actually forces all four columns to jointly match one real Viewing row), and pointing name back at Movie instead of Viewing is simply the wrong target relation for a foreign key that’s supposed to identify which viewing the snack belongs to.
Section C — EER diagram mapping
Question 1 — Medical clinic
Map: Doctor (licenceNo) splits into GP/Specialist (specialisationArea); Doctor —M:N WorksIn→ Clinic (regNo); Clinic has a subclass SpecialistClinic, run by exactly one Specialist (Runs, 1:N); Patient (patientId) —M:N Appointment (dateTime, fee)→ Doctor.
NoteWorking
Doctor [licenceNo]

Patient [patientId]

Clinic [regNo]

GP [licenceNo]
GP.licenceNo references Doctor.licenceNo

Specialist [licenceNo, specialisationArea]
Specialist.licenceNo references Doctor.licenceNo

SpecialistClinic [regNo]
SpecialistClinic.regNo references Clinic.regNo

Appointment [licenceNo, dateTime, patientId, fee]
Appointment.licenceNo references Doctor.licenceNo
Appointment.patientId references Patient.patientId

WorksIn [licenceNo, regNo]
WorksIn.licenceNo references Doctor.licenceNo
WorksIn.regNo references Clinic.regNo

Runs [licenceNo, regNo]
Runs.licenceNo references Specialist.licenceNo
Runs.regNo references SpecialistClinic.regNoGP/Specialist are standard disjoint-subclass mappings of Doctor. SpecialistClinic is a subclass of Clinic with no extra attributes of its own — just a foreign key back to Clinic. Runs is a 1:N relationship between Specialist and SpecialistClinic specifically (not the general Doctor/Clinic pair), so its foreign keys target the subclass relations, not the superclasses.
Week 6
Basic SQL Syntax: Data Definition and Data Manipulation Language
Module 3, part 1. Worked examples use two running schemas — a Company database and a Movie database — introduced below.
Where we are
Module 1 covered conceptual modelling (the ER diagram); Module 2 covered the relational model and ER-to-relational mapping. Module 3 is about expressing queries against a relational schema using SQL. Relational algebra (Codd’s formal query language) is the “logic engine” behind databases — precise, composable, and optimisable — but SQL is the declarative language we actually use to talk to a DBMS: you say what you want, not how to compute it. SQL is (almost) universal across Postgres, MySQL, Oracle, SQL Server, etc., and is the query interface behind tools like Power BI, Tableau, and most data-science workflows.
Example schemas used this module
Department [dNumber, dName, mgrSSN, mgrStartDate]
Employee   [ssn, name, dob, address, sex, salary, mgrSSN, dNum]
Sale       [itemID, custID, timestamp, price, salesPerson]
Item       [itemID, category, colour]
Customer   [custID, cname, gender, dob]
Movie [movieID, title, year]
StarsIn [movieID, starID, role]
MovieStar [starID, name, gender]Foreign keys: Employee.mgrSSN → Employee.ssn (self-referencing — recursive relationship), Employee.dNum → Department.dNumber, Department.mgrSSN → Employee.ssn, Sale.itemID → Item.itemID, Sale.custID → Customer.custID, Sale.salesPerson → Employee.ssn, StarsIn.movieID → Movie.movieID, StarsIn.starID → MovieStar.starID.
The three (main) types of SQL statement
- DDL (Data Definition Language) — statements that define/change the database schema (
CREATE,ALTER,DROP). - DML (Data Manipulation Language) — statements that manipulate data (
INSERT,UPDATE,DELETE,SELECT). - DCL (Data Control Language) — transaction control, semantic integrity (triggers/assertions), authorisation/privilege management, physical storage parameters (file structures, indexes), role-based security controls.
A relational query language should support INSERT (new tuples), DELETE (remove tuples), UPDATE (change attribute values), and SELECT (retrieve attributes/tuples/relations).
Data Definition Language (DDL)
DROP TABLE
DROP TABLE <table name> [CASCADE];Drops all constraints defined on the table (including constraints in other tables that reference it), deletes all tuples, and removes the table definition from the system catalog.
CREATE TABLE
CREATE TABLE <table name>
   (<column name> <column type> [<attribute constraint>]
   {, <column name> <column type> [<attribute constraint>]}
   [<table constraint> {, <table constraint>}])
Notation used throughout this module: KEYWORD, <argument>, [optional], {repeatable}, …|choice|…. Key/entity/referential integrity constraints are specified after the attributes are declared; domain constraints are specified per-attribute (directly, or via a CREATE DOMAIN).
Entity table example — Item [itemID, category, colour]:
CREATE TABLE Item (
    itemID   INTEGER,
    category ENUM('food', 'clothing', 'furniture'),
    colour   CHAR(3),
    PRIMARY KEY (itemID));
Relationship table example — Sale [itemID, custID, timestamp, price, salesPerson], a ternary-degree relation between Item, Customer and Employee:
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    FOREIGN KEY (itemID) REFERENCES Item(itemID),
    FOREIGN KEY (custID) REFERENCES Customer(custID),
    FOREIGN KEY (salesPerson) REFERENCES Employee(ssn));
Constraints
Constraints are rules that limit what data can go into a table:
- PRIMARY KEY — attribute value is unique and not null.
- FOREIGN KEY — attribute value must exist in the referenced (parent) table.
- CHECK — attribute value(s) must satisfy a predefined condition.
- UNIQUE — attribute value is unique or null (unlike a primary key).
CHECK constraints are semantic constraints over a single table, evaluated whenever tuples are inserted or modified:
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    FOREIGN KEY (itemID) REFERENCES Item(itemID),
    FOREIGN KEY (custID) REFERENCES Customer(custID),
    FOREIGN KEY (salesPerson) REFERENCES Employee(ssn),
    CHECK (price >= 8.50 AND price < 150000));
Naming constraints
CREATE TABLE Item (
    itemID   INTEGER,
    category ENUM('food', 'clothing', 'furniture'),
    colour   CHAR(3),
    CONSTRAINT item_pk PRIMARY KEY (itemID));
Giving a constraint a name has two benefits: (1) clearer error messages — a violation names the constraint; (2) the constraint can be modified/removed later, e.g. ALTER TABLE Item DROP CONSTRAINT item_pk;.
Question 1 — DDL constraints
Which SQL statement correctly implements Student [id, firstName, lastName] where {firstName, lastName} is unique?
-- A
CREATE TABLE Student (
    id INT NOT NULL, firstName VARCHAR(50), lastName VARCHAR(50),
    PRIMARY KEY (id));

-- B
CREATE TABLE Student (
    id INT NOT NULL, firstName VARCHAR(50), lastName VARCHAR(50),
    PRIMARY KEY (firstName, lastName));

-- C
CREATE TABLE Student (
    id INT NOT NULL, firstName VARCHAR(50), lastName VARCHAR(50),
    PRIMARY KEY (id), PRIMARY KEY (firstName, lastName));

-- D
CREATE TABLE Student (
    id INT NOT NULL, firstName VARCHAR(50), lastName VARCHAR(50),
    PRIMARY KEY (id), UNIQUE(firstName, lastName));
NoteSolution
D. A has no uniqueness constraint on {firstName, lastName} at all. B makes {firstName, lastName} the primary key instead of id (wrong key). C is invalid SQL — a table cannot declare two PRIMARY KEY clauses. D correctly keeps id as the primary key and adds a UNIQUE constraint over {firstName, lastName}.
Referential integrity: handling broken links
If a row that other rows depend on (e.g. a department’s manager) is deleted, what should happen to the dependent rows?
| Action | Effect |
|---|---|
ON DELETE RESTRICT (default) |
Disallows the deletion |
ON DELETE CASCADE |
Deletes dependent rows too |
ON DELETE SET NULL |
Breaks the link, but doesn’t delete other rows |
ON DELETE SET DEFAULT |
Uses a predefined fallback value |
The same options apply to updates (ON UPDATE ...). These options are attached to the FOREIGN KEY clause, and apply in the direction the foreign key points — from the referencing (child) table’s row being orphaned when the referenced (parent) table’s row is removed, not the reverse.
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    CONSTRAINT itemID_fk FOREIGN KEY (itemID) REFERENCES Item(itemID)
        ON DELETE RESTRICT ON UPDATE CASCADE,
    CONSTRAINT custID_fk FOREIGN KEY (custID) REFERENCES Customer(custID)
        ON DELETE RESTRICT ON UPDATE CASCADE,
    CONSTRAINT ssn_fk FOREIGN KEY (salesPerson) REFERENCES Employee(ssn)
        ON DELETE RESTRICT ON UPDATE CASCADE);
Question 2 — Designing with referential integrity
Given Student [studentID, name, advisorID], Professor [professorID, name], Student.advisorID references Professor.professorID — which statement best explains the design rationale for using ON DELETE SET NULL on advisorID?
A. It automatically reassigns students to a new advisor. B. It prevents the professor’s deletion unless all advisees are manually updated. C. It allows deletion of a professor without losing student records, marking that they no longer have an advisor. D. It deletes all students advised by the professor.
NoteSolution
C. ON DELETE SET NULL preserves student records and referential integrity by clearing the advisor reference — it does not reassign (A), does not block deletion (B, that’s RESTRICT), and does not delete students (D, that’s CASCADE).
Question 3 — Implementing referential integrity
CREATE TABLE ParkingPermit (
    pID     INTEGER,
    staffID INTEGER,
    PRIMARY KEY (pID),
    FOREIGN KEY (staffID) REFERENCES Staff(staffID) ON DELETE CASCADE);
Given a row pID = 1000, staffID = 5678 — which is correct? A. Deleting pID = 1000 cascades to delete staffID = 5678 in Staff. B. Deleting staffID = 5678 in Staff cascades to delete matching rows in ParkingPermit. C. Both A and B. D. None of the above.
NoteSolution
B. ON DELETE CASCADE only propagates from the referenced (parent) table to the referencing (child) table — deleting the Staff row cascades to ParkingPermit. It never works in reverse (deleting a ParkingPermit row has no defined effect on Staff).
ALTER TABLE
ALTER TABLE <table name>
    ADD <column name> <column type> [<attribute constraint>]
        {, <column name> <column type> [<attribute constraint>]}
  | DROP <column name> [CASCADE]
  | MODIFY <column name> <column-options>
  | ADD <constraint name> <constraint-options>
  | DROP <constraint name> [CASCADE];
Used for schema evolution — adding/dropping columns, changing a column definition, adding/dropping constraints. To alter a constraint, it must be dropped and re-added (commercial products vary in exact syntax).
-- Add an attribute (existing rows get NULL, so NOT NULL can't be used)
ALTER TABLE Employee ADD job VARCHAR(12);

-- Drop an attribute (CASCADE if other tables' FKs reference it)
ALTER TABLE Employee DROP address;

-- Add a constraint
ALTER TABLE Sale ADD CONSTRAINT ChkAge CHECK (price BETWEEN 10 AND 10000);

-- Drop a constraint (must have been named)
ALTER TABLE Sale DROP CONSTRAINT itemID_fk;
Cyclical foreign key dependencies
Department.mgrSSN → Employee.ssn and Employee.dNum → Department.dNumber form a cycle — you can’t create either table first with its foreign keys in place, since the other table doesn’t exist yet. Solution: create both tables without the foreign keys, insert the data, then ALTER TABLE to add the foreign keys afterwards.
CREATE Department (without FKs)
CREATE Employee (without FKs)
INSERT data into Department
INSERT data into Employee
ALTER TABLE Department ADD FOREIGN KEY (mgrSSN) REFERENCES Employee(ssn)
ALTER TABLE Employee ADD FOREIGN KEY (dNum) REFERENCES Department(dNumber)
Data Manipulation Language (DML)
Four statements: INSERT (add tuples), UPDATE (modify existing data), DELETE (remove tuples), SELECT (retrieve data).
INSERT
INSERT INTO <table name>
    [(<column name> {, <column name>})]
    (VALUES (<constant value> {, <constant value>}) | <select statement>);
A single-tuple insert lists values in the same order as the columns were declared (or the explicit column list, if given). A multi-tuple insert either comma-separates several value-lists, or loads the result of a query.
-- Insert from values
INSERT INTO Customer VALUES
    ('653298653', 'Ronald West', 'Male', '1995-12-30');

-- Insert from a query: create a customer account for every
-- employee in department 1
INSERT INTO Customer (custID, cname, gender, dob)
    SELECT ssn, name, sex, dob
    FROM   Employee
    WHERE  dNum = 1;
DELETE
DELETE FROM <table name>
    [WHERE <select condition>];
A single DELETE can remove zero, one, several, or all tuples from one table. Deletion may propagate to other tables if ON DELETE referential-triggered actions were declared.
DELETE FROM Employee
    WHERE name = 'Ramesh';
UPDATE
UPDATE <table name>
    SET <column name> = <value expression> {, <column name> = <value expression>}
    [WHERE <select condition>];
Tuples are selected for update from a single table; updating a primary key value may propagate to other tables (referencing foreign keys).
UPDATE Employee
    SET salary = salary * 1.1
    WHERE name = 'Joyce';
Question 4 — Correct use of DELETE
Given a Student [id, fName, lName, degree] table, which query deletes exactly the CompSci students except id = 4?
A. DELETE FROM Student WHERE id = 3 AND id = 5 AND id = 12 B. DELETE FROM Student WHERE fName = 'Diluen' OR fName = 'Peter' OR fName = 'Jason' C. DELETE FROM Student WHERE degree = 'CompSci' D. DELETE FROM Student WHERE degree = 'CompSci' AND NOT id = 4
NoteSolution
D. A is a contradiction (id can never equal three different values at once — nothing is deleted). B also incidentally deletes a non-CompSci student (Peter Park, id=10, is not CompSci). C deletes id = 4 too, which we want to keep. D correctly restricts to degree = 'CompSci' AND NOT id = 4.
Basic SELECT
SELECT <attribute list>
FROM   <table list>
[WHERE <condition>];
SELECT is declarative — you specify what the result should look like, and the DBMS decides the execution plan. The result of any SQL query is itself a table (relation).
Projection
SELECT [DISTINCT] (<attribute list> | *)
FROM   <table list>
[WHERE <condition>];
SQL relations are bags/multisets, not sets — duplicates are not eliminated by default. DISTINCT eliminates duplicates and enforces set semantics; * is a wildcard for “all columns”.
-- Find the titles of movies
SELECT title
FROM   Movie;

-- Find all the years a movie was produced (with vs without duplicates)
SELECT year FROM Movie;
SELECT DISTINCT year FROM Movie;
Question 5 — SQL projection
Given Scores [team1, team2, score1, score2] with rows (Dragons, Tigers, 5, 3), (Carp, Swallows, 4, 6), (Bay Stars, Giants, 2, 1), (Marines, Hawks, 5, 3), (Ham Fighters, Buffaloes, 1, 6), (Lions, Golden Eagles, 8, 12) — for SELECT score1, score2 FROM Scores, which tuple is in the result?
A. (1,2) B. (5,3) C. (8,6) D. All are in the answer E. None are in the answer
NoteSolution
B. (5, 3) appears twice in the source table (Dragons vs Tigers, Marines vs Hawks) — projection just doesn’t eliminate the duplicate by default.
Question 6 — SQL projection with DISTINCT
Same table as Question 5. For SELECT DISTINCT score1, score2 FROM Scores, how many tuples are in the output?
A. 6 B. 5 C. 4 D. 3
NoteSolution
B. Six rows exist, but (5, 3) is duplicated — DISTINCT removes one copy, leaving 5 unique tuples.
Projection with expressions
Expressions can use standard arithmetic operators (+ - * /) on numeric attributes, and can be given an alias with AS.
-- Names, salaries, and salaries with a 17% loading, for dept 6
SELECT name, salary, 1.17 * salary AS 'includingSuper'
FROM   Employee
WHERE  dNum = 6;
Selection (WHERE clause)
SELECT <attribute list>
FROM   <table list>
[WHERE search condition];
-- Find all the male stars
SELECT *
FROM MovieStar
WHERE gender = 'Male';
-- Names of employees in dept 4 earning > 25000, or dept 5 earning > 30000
SELECT name
FROM Employee
WHERE (dNum = 4 AND salary > 25000) OR (dNum = 5 AND salary > 30000);Question 7 — Selection
Given a Scores [team, opponent, runsFor, runsAgainst] table, for
SELECT *
FROM   Scores
WHERE  (runsFor >= 6 AND runsAgainst <= 4) OR (runsFor < 3 AND opponent = 'Giants');
which rows are in the result? A. Swallows vs Carp, 6-4 B. Buffaloes vs Ham Fighters, 6-1 C. Lions vs Golden Eagles, 8-12 D. A and B
NoteSolution
D. Swallows vs Carp (runsFor=6, runsAgainst=4) satisfies the first clause (6>=6 AND 4<=4). Buffaloes vs Ham Fighters (runsFor=6, runsAgainst=1) also satisfies the first clause (6>=6 AND 1<=4). Lions vs Golden Eagles (8, 12) fails both clauses (12<=4 is false, and 8<3 is false) — it’s the archetypal “bigger numbers, so it must match” trap.
Complex WHERE conditions
LIKE— string matching:%= zero-or-more arbitrary characters,_= any one character.WHERE title LIKE '%sin%'finds titles containing “sin” anywhere.IN— membership in a list:WHERE lastName IN ('Jones', 'Wong', 'Harrison').IS— null-checking (=doesn’t work withNULL):WHERE dNum IS NULL.- Arithmetic/date functions,
BETWEEN:WHERE salary BETWEEN 10000 AND 30000.
-- Names of employees in a "Research" department earning 40-60K
SELECT name
FROM   Employee
JOIN   Department ON dNum = dNumber
WHERE  dName LIKE '%Research%' AND salary BETWEEN 40000 AND 60000;
(Multi-relation JOIN queries like this are covered properly next lecture.)
Sorting (ORDER BY)
SELECT [DISTINCT] <target list>
FROM   <table list>
[WHERE search condition]
[ORDER BY column [ASC|DESC] {, column [ASC|DESC]}];
The target list can be a column name, expression, or *; column can be a name or a position in the target list; sorting can use multiple columns.
-- Employee names/salaries, ordered by salary descending
SELECT name, salary
FROM   Employee
ORDER BY salary DESC;

-- Employee names/depts/salaries, by dept ascending then salary descending
SELECT dNum, name, salary
FROM   Employee
ORDER BY dNum ASC, salary DESC;
Question 8 — Sorting
For SELECT a, b, c FROM R ORDER BY c DESC, b ASC, which tuple t necessarily precedes (5, 5, 5)?
A. (3, 6, 3) B. (1, 5, 5) C. (5, 5, 6) D. All of the above
NoteSolution
C. Sorting is primarily by c DESC. (5,5,6) has c=6 > 5, so it sorts strictly before (5,5,5) regardless of a/b. (3,6,3) has c=3 < 5, so it comes after. (1,5,5) ties on c=5 with (5,5,5), so the tie-break (b ASC) applies — both have b=5, so it’s still a tie, and the ordering between them is unspecified (not “necessarily precedes”).
Summary
You should now be able to create, alter and drop relations, enforce integrity constraints, and perform basic insert/update/delete/select operations in SQL. Next lecture: aggregation, grouping, and querying across multiple relations. See week6-tutorial-applied-class-5-basic-sql-ddl-and-dml and week6-tutorial-case-study-4-easydrive-insurance for practice.
Applied Class 5: Basic SQL syntax, DDL and DML
Practice for 2026-03-30-basic-sql-ddl-and-dml.
Schema — BestTechLtd
BestTechLtd have built a simplistic authorisation management system for secure access control within their organisational network. When a new employee joins, their personal details are stored in Employee. Administrative employees (a specific type of employee, recorded additionally in AdministrativeEmployee) can grant roles to employees through a role-granting process. Each Role comes with specific Permissions that determine which company websites/resources an employee holding that role can access.
Employee             [EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt]
AdministrativeEmployee [EmployeeID, Level, Type]
Role                  [RoleID, Name, Description]
RoleGranting          [EmployeeID, RoleID, AdministrationID, Timestamp]
Permission            [WebsiteURI, RoleID, GrantType, Description]

AdministrativeEmployee.EmployeeID references Employee.EmployeeID
RoleGranting.EmployeeID references Employee.EmployeeID
RoleGranting.RoleID references Role.RoleID
RoleGranting.AdministrationID references AdministrativeEmployee.EmployeeID
Permission.RoleID references Role.RoleID
Section 1 — Basic SQL
Question 1
Return all information (all columns) relating to the Roles recorded in the database.
NoteWorking
SELECT * FROM Role;Question 2
Return the distinct first name and last name of all employees, in descending alphabetical order of their last name.
NoteWorking
SELECT DISTINCT FirstName, LastName
FROM   Employee
ORDER BY LastName DESC;
Question 3
Return all the Permission websiteURIs which grant edit permissions to commercial websites (websites ending in .com).
NoteWorking
SELECT WebsiteURI
FROM   Permission
WHERE  GrantType = 'Edit'
  AND  WebsiteURI LIKE '%.com';
Question 4 (Challenge)
Create an Employee code, which is the combination of the employee’s first name, last name, and DOB year with syntax [FirstName]-[Lastname]-[yyyy]. Create the code only if a first name, last name, and Date of Birth is present.
NoteWorking
SELECT CONCAT(FirstName, '-', LastName, '-', YEAR(DOB))
FROM   Employee
WHERE  1 = 1
  AND  FirstName IS NOT NULL
  AND  LastName IS NOT NULL
  AND  DOB IS NOT NULL;
Section 2 — Data Definition Language (DDL)
Question 5
Before BestTechLtd created their authorisation system, employees were assigned only a single role, plus a unique access token granting access for that role. Create a new relation LegacyEmployee, a specialised type of employee (stored in a separate relation), with:
LegacyEmployeeID: a unique reference to theEmployeeIDstored in the authorisation database.GrantAccessToken: a string of exactly 64 characters granting access to old websites.RoleID: a reference to the legacy employee’s original role. This reference cannot be null.
NoteWorking
CREATE TABLE LegacyEmployee (
    LegacyEmployeeID VARCHAR(8) PRIMARY KEY,
    GrantAccessToken CHAR(64) NOT NULL,
    RoleID           INT NOT NULL,
    FOREIGN KEY (LegacyEmployeeID) REFERENCES Employee(EmployeeID),
    FOREIGN KEY (RoleID) REFERENCES Role(RoleID)
);
LegacyEmployee is a specialisation of Employee (recall relational-mapping-notation’s Rule 8b: a 1:1 relation with the subclass’s primary key also being a foreign key referencing the superclass).
Question 6 (Challenge)
BestTechLtd want to migrate password credentials from Employee into a separate Credential relation. Create the new table (fields in any order), assuming there is no existing data, and remove the migrated fields from Employee.
NoteWorking
CREATE TABLE Credential (
    CredentialID VARCHAR(9) PRIMARY KEY,
    EmployeeID   VARCHAR(8) NOT NULL,
    PasswordHash VARCHAR(128) NOT NULL,
    PasswordSalt VARCHAR(64) NOT NULL,
    Timestamp    DATETIME,
    FOREIGN KEY (EmployeeID) REFERENCES Employee(EmployeeID)
);

ALTER TABLE Employee
    DROP COLUMN PasswordHash,
    DROP COLUMN PasswordSalt;
Section 3 — Data Manipulation Language (DML)
Question 7
Revoke all roles granted to EmployeeID E0008.
NoteWorking
DELETE FROM RoleGranting
WHERE  EmployeeID = 'E0008';
Question 8
Revoke the role(s) granted to John Stevens at any time during 22 July 2024. Assume such a role exists and only one John Stevens exists.
NoteWorking
DELETE FROM RoleGranting
WHERE  EmployeeID = (
    SELECT EmployeeID FROM Employee
    WHERE  FirstName = 'John' AND LastName = 'Stevens'
)
AND    Timestamp BETWEEN '2024-07-22 00:00:00' AND '2024-07-22 23:59:59';
Question 9 (Challenge)
A new employee E0024, James Moran, born 21 November 2001, with a given password hash and salt, is granted all the roles that employee Sofia Gonzalez has, granted by admin E0001 today. Insert the new records (assume only one Sofia Gonzalez exists).
NoteWorking
INSERT INTO Employee (EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt)
VALUES ('E0024', 'James', 'Moran', '2001-11-21',
        'e7cf3ef8d8aac2c1c93963e7a58b7b62ade24d0d0ba2c8ae0f7fb6c8b0aa0332',
        'gmAlpLW8cUj');

INSERT INTO RoleGranting
SELECT 'E0024', RoleID, 'E0001', Timestamp
FROM   RoleGranting
WHERE  EmployeeID = (
    SELECT EmployeeID
    FROM   Employee
    WHERE  FirstName = 'Sofia' AND LastName = 'Gonzalez'
);
Case Study 4: EasyDrive Insurance (DDL & DML)
Practice for 2026-03-30-basic-sql-ddl-and-dml. This case study builds practical experience implementing a database in phpMyAdmin (a GUI for MySQL) — running real DDL/DML, and learning to break-test a schema and check edge cases.
Correspondence 1
Sarah Chen, Head of Technology Operations at EasyDrive Insurance (a direct-to-consumer car insurer), emails asking for help migrating their schema to MySQL/phpMyAdmin. When a customer signs up they create a profile (Customer, Address), then may purchase a Policy for a Vehicle, insuring it over consecutive years.
Relational schema:
Customer    [CustomerID, Name, DateOfBirth, Email, Occupation, AddressID]
Address     [AddressID, StreetName, Number, Suburb, Postcode, State, Country]
Vehicle     [VehicleID, VehicleCode, VehiclePurpose, EstYearlyKm]
VehicleType [VehicleCode, Make, Model, Year, MarketValue]
Policy      [PolicyID, CustomerID, VehicleID, PolicyStartYear, PolicyPurchaseDate, Excess, Premium]

Customer.AddressID references Address.AddressID
Policy.VehicleID references Vehicle.VehicleID
Policy.CustomerID references Customer.CustomerID
Vehicle.VehicleCode references VehicleType.VehicleCode
Data types (as specified by Sarah):
Address:AddressID(≤4 chars),StreetName(≤255),Number(≤10, to allow e.g."4/12"),Suburb(≤255),Postcode(≤10),State(≤10),Country(≤50).Customer:CustomerID(integer),Name(≤255),DateOfBirth(date),Email(≤255),Occupation(≤255),AddressID(≤4).VehicleType: a reference table mapping aVehicleCode(≤50) toMake/Model/Year— the combination ofMake,Model,Yearmust be unique, since each distinct vehicle configuration maps to exactly one code (used to determineMarketValue, the accident payout).Vehicle:VehicleID(≤6),VehicleCode(referencesVehicleType),VehiclePurpose(only'Private'or'Business'),EstYearlyKm(integer).Policy:PolicyID(≤6),CustomerID(integer),VehicleID(≤6),PolicyStartYear(integer),PolicyPurchaseDate(date),Excess(integer),Premium(decimal, 2 dp, ≤10 digits total).
Section A — Data Definition Language
Using phpMyAdmin, create a new database EasyDrive and implement the five tables above, with all data types/keys/constraints as described.
NoteWorking
CREATE DATABASE EasyDriveInsurance;
USE EasyDriveInsurance;

CREATE TABLE Address (
    AddressID  VARCHAR(4),
    StreetName VARCHAR(255),
    Number     VARCHAR(10),
    Suburb     VARCHAR(255),
    Postcode   VARCHAR(10),
    State      VARCHAR(10),
    Country    VARCHAR(50),
    PRIMARY KEY (AddressID)
);

CREATE TABLE Customer (
    CustomerID  INT,
    Name        VARCHAR(255),
    DateOfBirth DATE,
    Email       VARCHAR(255),
    Occupation  VARCHAR(255),
    AddressID   VARCHAR(4),
    PRIMARY KEY (CustomerID),
    FOREIGN KEY (AddressID) REFERENCES Address(AddressID)
);

CREATE TABLE VehicleType (
    VehicleCode VARCHAR(50),
    Make        VARCHAR(50),
    Model       VARCHAR(50),
    Year        INT,
    PRIMARY KEY (VehicleCode),
    UNIQUE (Make, Model, Year)
);

CREATE TABLE Vehicle (
    VehicleID      VARCHAR(6),
    VehicleCode    VARCHAR(50),
    VehiclePurpose ENUM('Private', 'Business'),
    EstYearlyKm    INT,
    PRIMARY KEY (VehicleID),
    FOREIGN KEY (VehicleCode) REFERENCES VehicleType(VehicleCode)
);

CREATE TABLE Policy (
    PolicyID           VARCHAR(6),
    CustomerID         INT,
    VehicleID          VARCHAR(6),
    PolicyStartYear    INT,
    PolicyPurchaseDate DATE,
    Excess             INT,
    Premium            DECIMAL(10, 2),
    PRIMARY KEY (PolicyID),
    FOREIGN KEY (CustomerID) REFERENCES Customer(CustomerID),
    FOREIGN KEY (VehicleID) REFERENCES Vehicle(VehicleID)
);
Note: modern AI tools can draft CREATE TABLE statements from a schema description, but the draft must be checked carefully against the description before running it — AI-generated SQL can contain errors or omissions (see 2026-04-13-nested-queries-views-and-generative-ai’s “Generative AI & SQL” section).
Section B — Analysis of Data Manipulation Language
Sarah asks the students to run five INSERT operations, in order, and record for each: whether it succeeded/failed, the error message (if any), and which integrity constraint was violated and why.
-- Operation 1
INSERT INTO Address (AddressID, StreetName, Number, Suburb, Postcode, State, Country)
VALUES ('A001', 'Main Street', '12', 'Brisbane', '4000', 'QLD', 'Australia');

-- Operation 2
INSERT INTO Customer (CustomerID, Name, DateOfBirth, Email, Occupation, AddressID)
VALUES (1001, 'Allan Smith', '2000-01-01', 'allan@uq.edu.au', 'Student', 'A999');

-- Operation 3
INSERT INTO Customer (CustomerID, Name, DateOfBirth, Email, Occupation, AddressID)
VALUES (1001, 'Rebecca Johnson', '1995-06-15', 'rebecca@gmail.com', 'Engineer', 'A001');

-- Operation 4
INSERT INTO VehicleType (VehicleCode, Make, Model, Year)
VALUES ('VT001', 'Toyota', 'Corolla', 2020);
INSERT INTO Vehicle (VehicleID, VehicleCode, VehiclePurpose, EstYearlyKm)
VALUES ('V00001', 'VT001', 'Personal', 15000);

-- Operation 5
INSERT INTO Policy (PolicyID, CustomerID, VehicleID, PolicyStartYear, PolicyPurchaseDate, Excess, Premium)
VALUES ('P00001', 1001, 'V00001', 2024, '2024-03-01', 500, 1200.00);
NoteWorking
| Op | Result | Error / constraint |
|---|---|---|
| 1 | Succeeded | — |
| 2 | Failed | #1452 - Cannot add or update a child row: a foreign key constraint fails. Referential integrity — AddressID = 'A999' doesn’t exist in Address. |
| 3 | Succeeded | — (a different row, correctly referencing A001; note it reuses CustomerID = 1001 from the failed Op 2, which is fine since Op 2 never committed) |
| 4 | Failed | #1265 - Data truncated for column 'VehiclePurpose' at row 1. Domain constraint — 'Personal' is not a valid VehiclePurpose value (only 'Private'/'Business'). |
| 5 | Failed | #1452 - ... FOREIGN KEY (VehicleID) REFERENCES Vehicle(VehicleID). Referential integrity — since Op 4 failed, VehicleID = 'V00001' was never inserted into Vehicle. |
This is a good illustration of cascading failure: a single domain violation in Op 4 also causes Op 5 to fail, even though Op 5’s own values look superficially fine.
Correspondence 2 (Challenge)
Sarah’s team requests further changes now the core schema is in place:
- A new
InsuranceClaimtable: an auto-incrementing claim ID; a reference to thePolicythe claim is against (claims should be automatically deleted if their policy is deleted); the incident date/time; the claimed amount (2 dp decimal); a status restricted to'Pending','Approved', or'Rejected'; and a description (≤255 chars). - Remove the
Occupationcolumn fromCustomer(no longer collected). - Add two constraints to
Customer: a namedUniqueEmailuniqueness constraint onEmail, and a check constraint requiring customers to be at least 18 years old (based onDateOfBirth).
Task 4 — Creating InsuranceClaim
NoteWorking
CREATE TABLE InsuranceClaim (
    ClaimID          INT AUTO_INCREMENT,
    PolicyID         VARCHAR(6),
    ClaimDate        DATE,
    ClaimAmount      DECIMAL(10, 2),
    ClaimStatus      ENUM('Pending', 'Approved', 'Rejected'),
    ClaimDescription VARCHAR(255),
    PRIMARY KEY (ClaimID),
    FOREIGN KEY (PolicyID) REFERENCES Policy(PolicyID) ON DELETE CASCADE
);
Task 5 — Removing Occupation
NoteWorking
ALTER TABLE Customer DROP COLUMN Occupation;Task 6 — Fraud prevention constraints
NoteWorking
ALTER TABLE Customer
    ADD CONSTRAINT UniqueEmail UNIQUE (Email);

ALTER TABLE Customer
    ADD CONSTRAINT AgeOver CHECK (
        TIMESTAMPDIFF(YEAR, DateOfBirth, CURDATE()) >= 18
    );
Week 7
Aggregation, Grouping and Multiple Relation Queries
Module 3, part 2. Continues 2026-03-30-basic-sql-ddl-and-dml, using the same Company (Department/Employee/Sale/Item/Customer) and Movie (Movie/StarsIn/MovieStar) schemas.
Today’s outline
- Aggregation and grouping (
COUNT/SUM/AVG/MAX/MIN,GROUP BY,HAVING) - Multiple relation queries — renaming, joins, set operations
Aggregation
Aggregates are functions that produce a summary value from a set of tuples:
COUNT— counts the number of tuples returned.SUM/AVG— sum/average of a set of numeric values.MAX/MIN— maximum/minimum value from a set with a total ordering (the domain doesn’t have to be numeric — e.g. dates, strings).
Aggregation functions can be used in the SELECT clause and the HAVING clause (below), with or without DISTINCT.
-- Total and average salary of all employees
SELECT AVG(salary), SUM(salary)
FROM   Employee;

-- Total number of employees in department 5
SELECT COUNT(*)
FROM   Employee
WHERE  dNum = 5;

-- Distinct salary count of employees in department 5
SELECT COUNT(DISTINCT salary)
FROM   Employee
WHERE  dNum = 5;
Grouping (GROUP BY)
An aggregate can apply to the whole table, but is often needed per group of rows — e.g. “total employees per department”, “average salary per department”. GROUP BY provides this.
SELECT [DISTINCT] <target list>
FROM   <table list>
[WHERE search condition]
[GROUP BY <grouping attributes>]
[HAVING <group conditions>]
[ORDER BY column [ASC|DESC] {, column [ASC|DESC]}];Rule: any attribute in the SELECT clause must either appear in GROUP BY, or be wrapped in an aggregation function.
-- Total employees (no grouping)
SELECT COUNT(*) FROM Employee;                    -- 8

-- Total employees per department
SELECT dNum, COUNT(*)
FROM   Employee
GROUP BY dNum;
--  dNum | COUNT(*)
--     1 |    1
--     4 |    3
--     5 |    4

-- Total employees earning > 40000, per department
SELECT dNum, COUNT(*)
FROM   Employee
WHERE  salary > 40000
GROUP BY dNum;

-- Average salary per department, per gender
SELECT dNum, sex, AVG(salary)
FROM   Employee
GROUP BY dNum, sex;
WHERE filters rows before grouping; GROUP BY then buckets the remaining rows.
Question 9 — INSERT and GROUP BY
Given Students [id, fName, lName, degree], what does INSERT INTO DegreeStatistics (degree, num) SELECT degree, COUNT(*) FROM Students GROUP BY degree insert?
A. (Arts, 2), (CompSci, 3) B. (Math, 1), (Arts, 2), (CompSci, 3) C. (Math, 1), (Arts, 8), (CompSci, 12) D. None of the above
NoteSolution
B. Every distinct degree value gets its own group and count — missing Math from option A is the trap (there’s no WHERE clause excluding it). C looks like SUM(id) was used instead of COUNT(*).
HAVING — conditions on groups
HAVING (following GROUP BY) filters groups, the way WHERE filters rows — and unlike WHERE, HAVING can include aggregates. Any attribute in HAVING must appear in GROUP BY or be aggregated.
-- Total employees, for departments with more than 2 employees
SELECT   dNum, COUNT(*)
FROM     Employee
GROUP BY dNum
HAVING   COUNT(*) > 2;

-- Departments with more than 2 employees earning > 20000
SELECT   dNum, COUNT(*)
FROM     Employee
WHERE    salary > 20000
GROUP BY dNum
HAVING   COUNT(*) > 2;
In the second example, WHERE and HAVING both operate on “employees earning > 20000” — contrast this with the correlated-subquery version of the same idea, in 2026-04-13-nested-queries-views-and-generative-ai, where HAVING checks a different condition across all employees via a subquery.
Question 10 — HAVING clause
For SELECT team, COUNT(*) AS games_played, SUM(runsFor) AS total_runs FROM Scores GROUP BY team HAVING SUM(runsFor) > 10, what is the HAVING clause doing?
A. Removes rows where runsFor <= 10 before grouping. B. Filters rows before aggregation. C. Limits which teams are included, based on their total runs scored. D. Replaces WHERE for simple conditions. E. Counts opponents that allowed more than 10 runs.
NoteSolution
C. HAVING filters groups (here, teams) by an aggregate condition computed after grouping — it doesn’t touch individual rows before grouping (that’s what WHERE would do).
Question 11 — HAVING clause application
Given Employee [id, dNum, sex, salary] with rows (1,5,M,30000), (2,5,M,40000), (3,5,F,25000), (4,5,M,38000), (5,1,M,55000), for SELECT dNum, sex, COUNT(*) FROM Employee GROUP BY dNum, sex HAVING …, which HAVING clause produces a different result from the others?
A. HAVING COUNT(*) < 2 B. HAVING AVG(salary) = 25000 C. HAVING MAX(salary) <= MIN(salary) D. HAVING SUM(salary) < 60000
NoteSolution
B. Groups are (5,M) [3 rows: 30000/40000/38000], (5,F) [1 row: 25000], (1,M) [1 row: 55000]. A, C and D all select the same two singleton groups (5,F,1) and (1,M,1) (both have COUNT(*)=1<2; both trivially satisfy MAX<=MIN since there’s one value; both have SUM<60000). B selects only (5,F,1), since its average is exactly 25000 but (1,M)’s average is 55000 — a different result set.
Multiple relation queries
Three tools for combining relations: renaming, joins, and set operations (union/intersect/difference).
Renaming
Two ways to rename: qualifying attribute names (table.attribute), or declaring an alias (AS). Renaming removes ambiguity and enables self-joins.
-- Names/salaries/salaries+17% for dept 4
SELECT E.name, salary, 1.17 * salary AS 'includingSuper'
FROM   Employee E
WHERE  dNum = 4;
Cartesian product
R1 × R2: every row of R1 combined with every row of R2; the result schema is the concatenation of both schemas. If |R1| = m and |R2| = n, then |R1 × R2| = m * n.
SELECT *
FROM   MovieStar, StarsIn;
Every MovieStar row is paired with every StarsIn row — almost always not what you want (compare with a join, below).
Equi-join and joins generally
An equi-join combines tuples from two relations that agree on some pair of attributes (a join condition using only =). A join in general combines related tuples into a single result relation:
SELECT <attribute list>
FROM   <table> {<type of join> JOIN <table to join to> ON <join attributes>}
[WHERE search condition]

-- equivalently, using WHERE (Cartesian product + join condition):
SELECT <attribute list>
FROM   <table list of more than one table>
[WHERE join condition AND search condition]
-- Names of the managers of each department
SELECT E.name, D.dName
FROM Department AS D, Employee AS E
WHERE D.mgrSSN = E.ssn;
-- equivalent, using JOIN
SELECT E.name, D.dName
FROM Department AS D
JOIN Employee AS E ON D.mgrSSN = E.ssn;JOIN/ON is generally preferred over the WHERE-based Cartesian product form because it can be more efficiently optimised by the DBMS — but for this course, they’re treated as equivalent.
-- IDs and names of all stars who've been in a movie
SELECT DISTINCT S.starID, name
FROM   StarsIn S
JOIN   MovieStar MS ON S.starID = MS.starID;

-- IDs, names and characters of stars in the movie with movieID 1
SELECT S.starID, name, role
FROM   StarsIn S
JOIN   MovieStar MS ON S.starID = MS.starID
WHERE  S.movieID = 1;

-- Multi-join: stars in "Gone with the Wind"
SELECT S.starID, MS.name, S.role, M.title
FROM   StarsIn S
JOIN   MovieStar MS ON S.starID = MS.starID
JOIN   Movie M ON S.movieID = M.movieID
WHERE  M.title LIKE 'Gone with the Wind';
Question 12 — SQL joins
Which query correctly returns employee names and the name of the department they work in?
A. SELECT e.name, d.dName FROM Employee e, Department d WHERE e.mgrSSN = d.mgrSSN; B. SELECT e.name, d.dName FROM Employee e JOIN Department d ON e.ssn = d.mgrSSN; C. SELECT e.name, d.dName FROM Department d JOIN Employee e ON d.mgrSSN = e.mgrSSN; D. SELECT e.name, d.dName FROM Employee e JOIN Department d ON e.dNum = d.dNumber;
NoteSolution
D. A joins on shared mgrSSN values (matching managers to managers, not employees to their department). B matches an employee’s ssn to a department’s mgrSSN — that’s “departments this employee manages”, not “the department they work in”. C is the same mismatch as B, reversed. D correctly joins each employee’s dNum to the department’s dNumber — “the department they work in”.
Self-joins (recursive relationships)
-- Employees who earn less than their manager
SELECT   A.name AS employee, A.salary AS employeeSalary,
         B.name AS manager, B.salary AS managerSalary
FROM     Employee A
JOIN     Employee B ON A.mgrSSN = B.ssn
WHERE    A.salary < B.salary;
Question 13 — Grouping with join
Given Flight [FlightNo, Origin, Destination], for
SELECT F1.Origin, F2.Destination, COUNT(*)
FROM   Flight F1, Flight F2
WHERE  F1.Destination = F2.Origin
GROUP BY F1.Origin, F2.Destination
(read as: “how many ways can you connect from F1.Origin to F2.Destination via one stopover?”) which is in the result?
A. (Brisbane, Melbourne, 2) B. (Perth, Sydney, 6) C. (Perth, Melbourne, 1) D. All of the above E. None of the above
NoteSolution
D — all of the above. The self-join pairs every F1 flight with every F2 flight departing from where F1 lands, then groups by (F1.Origin, F2.Destination) and counts the pairs. Working through all nine flights (2× Brisbane→Sydney, 1× Sydney→Melbourne, 2× Melbourne→Perth, 3× Perth→Brisbane, 1× Perth→Sydney) gives:
| F1.Origin | F2.Destination | COUNT(*) | Why |
|---|---|---|---|
| Brisbane | Melbourne | 2 | 2 Brisbane→Sydney flights × 1 Sydney→Melbourne flight |
| Sydney | Perth | 2 | 1 Sydney→Melbourne flight × 2 Melbourne→Perth flights |
| Melbourne | Brisbane | 6 | 2 Melbourne→Perth flights × 3 Perth→Brisbane flights |
| Melbourne | Sydney | 2 | 2 Melbourne→Perth flights × 1 Perth→Sydney flight |
| Perth | Sydney | 6 | 3 Perth→Brisbane flights × 2 Brisbane→Sydney flights |
| Perth | Melbourne | 1 | 1 Perth→Sydney flight × 1 Sydney→Melbourne flight |
(Brisbane, Melbourne, 2), (Perth, Sydney, 6) and (Perth, Melbourne, 1) are all genuinely in the result — so A, B and C are all correct.
Theta-join
The most general join type — the join condition can use any of {=, ≠, <, ≤, >, ≥}, not just =.
Question 14 — Theta join
Given Student [id, sName, age], for SELECT DISTINCT S1.sName, S1.age FROM Student S1 JOIN Student S2 ON S1.age > S2.age, what does this return?
A. Name/age of one of the oldest student(s). B. Name/age of all of the oldest student(s). C. Name/age of all of the youngest student(s). D. Name/age of all students older than the youngest student(s). E. None of the above.
NoteSolution
D. S1.age > S2.age only has a match for S1 if some student (S2) is younger — i.e. S1 is not the/a youngest student. So the result is every student who is older than at least one other student: everyone except the youngest.
Inner and outer joins
- Inner join (default, just
JOIN): a tuple appears in the result only if matching tuples exist in both relations. - Outer join: includes the inner join result, plus unmatched rows from one or both tables:
- Left join — all rows from the first table.
- Right join — all rows from the second table.
- Full outer join — all rows from both. Not implemented in MySQL.
-- Misses departments without a manager:
SELECT   D.dName, E.name
FROM     Department AS D
JOIN     Employee AS E ON D.mgrSSN = E.ssn;

-- Includes them (NULL for the manager's name):
SELECT   D.dName, E.name
FROM     Department AS D
LEFT JOIN Employee AS E ON D.mgrSSN = E.ssn;
Set operations
A relation is a set of tuples (no duplicates, no order) — set operators apply directly:
- UNION — tuples in either or both relations.
- INTERSECT — tuples in both.
- EXCEPT (a.k.a.
MINUS) — tuples in the first but not the second.
Union compatibility is required: the same number of columns, with pair-wise compatible domains.
By default each of these eliminates duplicates; append ALL (UNION ALL, INTERSECT ALL, EXCEPT ALL) to keep multiset semantics. If a tuple occurs m times in r and n times in s: it occurs m + n times in r UNION ALL s, min(m, n) times in r INTERSECT ALL s, and max(0, m - n) times in r EXCEPT ALL s.
SELECT ...
UNION [ALL] SELECT ...
[UNION [ALL] SELECT ...]
-- Stars in a movie from 1944 or 1974 — via OR:
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID
WHERE year = 1944 OR year = 1974;
-- ...or equivalently via UNION:
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
UNION
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;INTERSECT is part of the SQL standard but not implemented in MySQL — it can be rewritten with a self-join:
-- Stars in a movie from BOTH 1944 and 1974:
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
INTERSECT
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;

-- Rewritten without INTERSECT, using a self-join on starID:
SELECT DISTINCT S1.starID
FROM   Movie M1
JOIN   StarsIn S1 ON M1.movieID = S1.movieID
JOIN   StarsIn S2 ON S1.starID = S2.starID
JOIN   Movie M2 ON M2.movieID = S2.movieID
WHERE  M1.year = 1944 AND M2.year = 1974;
-- Stars in a movie from 1944 but NOT 1974 (EXCEPT):
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
EXCEPT
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;EXCEPT queries can also always be rewritten as nested queries (next lecture).
Properties of set operators
\[A \cup B = B \cup A \qquad (A \cup B) \cup C = A \cup (B \cup C)\] \[A \cap B = B \cap A \qquad (A \cap B) \cap C = A \cap (B \cap C)\] \[A - B \neq B - A \qquad (A - B) - C \neq A - (B - C)\]
Union and intersection are commutative and associative; difference is neither.
JOIN vs set operations
| Join | Set operation | |
|---|---|---|
| Combines | Rows from many tables into new columns | Result-sets of SELECTs into new rows |
| Column count | May differ between tables | Must match |
| Column types | Can differ | Must be compatible |
| Duplicates | Kept by default | Removed by default |
Question 15 — UNION query
Given Table [A, B, C] with rows (1,X,11), (2,Y,12), (3,Y,13), what does SELECT * FROM Table UNION SELECT a, b FROM Table WHERE b = 'X' OR c = '13' produce?
NoteSolution
D — none of the above; the query raises an error. SELECT * returns 3 columns (A, B, C) but SELECT a, b returns only 2 — the two halves of the UNION are not union-compatible (mismatched column counts), so none of the listed result tables can occur.
Question 16 — UNION query (two tables)
Given Table1 [A,B,C] = (1,X,11), (2,Y,12), (3,Y,13) and Table2 [D,E,C] = (3,X,11), (4,Y,12), (3,Y,13), what does SELECT * FROM Table1 UNION SELECT d, e, c FROM Table2 WHERE E = 'X' OR C = 13 produce?
NoteSolution
C. Table2 rows matching E='X' OR C=13 are (3,X,11) and (3,Y,13); renamed to (A,B,C) these are (3,X,11) and (3,Y,13). Unioned with all of Table1 — (1,X,11), (2,Y,12), (3,Y,13) — and removing the duplicate (3,Y,13), the result is (1,X,11), (2,Y,12), (3,Y,13), (3,X,11): four rows, all of Table1 plus the one genuinely new row (3,X,11). (A is missing a row from Table1; B fails to remove the duplicate (3,Y,13).)
Summary
You can now aggregate and group data, and query across multiple relations using renaming, joins (equi/theta/inner/outer), and set operations. Next lecture: nested queries, views, and Generative AI & SQL. See week7-tutorial-applied-class-6-aggregation-and-grouping, week7-tutorial-case-study-5-easydrive-insurance and week8-tutorial-applied-class-7-multiple-relation-queries for practice.
Applied Class 6: DQL Aggregation and Grouping
Practice for 2026-04-06-aggregation-grouping-and-multiple-relation-queries. Same BestTechLtd schema as week6-tutorial-applied-class-5-basic-sql-ddl-and-dml.
Employee              [EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt]
AdministrativeEmployee [EmployeeID, Level, Type]
Role                   [RoleID, Name, Description]
RoleGranting           [EmployeeID, RoleID, AdministrationID, Timestamp]
Permission             [WebsiteURI, RoleID, GrantType, Description]

AdministrativeEmployee.EmployeeID references Employee.EmployeeID
RoleGranting.EmployeeID references Employee.EmployeeID
RoleGranting.RoleID references Role.RoleID
RoleGranting.AdministrationID references AdministrativeEmployee.EmployeeID
Permission.RoleID references Role.RoleID
Question 1
Return the youngest Employee’s Date of Birth.
NoteWorking
SELECT MAX(DOB)
FROM   Employee;
The youngest employee has the largest (most recent) DOB — a common trap is reaching for MIN by reflex.
Question 2
For each website URI, find the number of roles that can access it. Two columns: the website URI, and the number of roles.
NoteWorking
SELECT   WebsiteURI, COUNT(DISTINCT RoleID)
FROM     Permission
GROUP BY WebsiteURI;
Question 3
Return the EmployeeId of all employees who have been granted more than one role.
NoteWorking
SELECT   EmployeeID
FROM     RoleGranting
GROUP BY EmployeeID
HAVING   COUNT(RoleID) > 1;
Question 4
Return the highest AdministrativeEmployee level, the lowest level, and the difference between both, aliased DifferenceInAdministrativeEmployeeLevels.
NoteWorking
SELECT MAX(Level), MIN(Level),
       (MAX(Level) - MIN(Level)) AS DifferenceInAdministrativeEmployeeLevels
FROM   AdministrativeEmployee;
Question 5 — Discuss
(1) What do you observe using an aggregation function without GROUP BY? Why? (2) What do you observe aggregating (GROUP BY) over a primary key or unique field? Why?
NoteWorking
- Observation: the aggregate operates over the entire table and returns a single row/value. Reason: with no
GROUP BY, the whole result set is treated as one big group. - Observation: the number of rows returned equals the number of rows in the table, and most aggregate functions return values identical to the ungrouped row. Reason: a primary key/unique field is unique and non-null per row, so every “group” contains exactly one tuple.
Question 6
Return the average salary of Employees born after 1 January 1990.
NoteWorking
SELECT AVG(Salary)
FROM   Employee
WHERE  DOB > '1990-01-01';
Question 7
Return the roleID of all roles which have at least two associated website URIs with a grantType of 'Edit'.
NoteWorking
SELECT   RoleId
FROM     Permission
WHERE    GrantType = 'Edit'
GROUP BY RoleId
HAVING   COUNT(WebsiteURI) >= 2;
Question 8 (Challenge)
Return all last names that are shared by multiple employees.
NoteWorking
SELECT   DISTINCT LastName
FROM     Employee
WHERE    LastName IS NOT NULL
GROUP BY LastName
HAVING   COUNT(FirstName) > 1;
Case Study 5: EasyDrive Insurance (Queries)
Practice for 2026-04-06-aggregation-grouping-and-multiple-relation-queries. An analyst at EasyDrive Insurance needs several queries answered against their production data (loaded from a synthetic-data dump), but struggles to write them — this case study writes them on the analyst’s behalf.
Schema
Note this schema has evolved slightly since week6-tutorial-case-study-4-easydrive-insurance — VehicleType has been split into VehicleCodeMapping, VehicleValue and VehicleExcessRange (as transcribed directly from the source materials — the two case studies’ schemas are not perfectly identical).
Customer           [CustomerID, Name, DateOfBirth, Email, Occupation, AddressID]
Address            [AddressID, StreetName, Number, Suburb, Postcode, State, Country]
Vehicle            [VehicleID, VehicleCode, VehiclePurpose, EstYearlyKm]
VehicleCodeMapping [VehicleCode, Make, Model, Year]
VehicleValue       [VehicleCode, MarketValue]
VehicleExcessRange [VehicleCode, MinimumExcess, MaximumExcess]
Policy             [PolicyID, CustomerID, VehicleID, PolicyStartYear, PolicyPurchaseDate, Excess, Premium]

Customer.AddressID references Address.AddressID
Policy.VehicleID references Vehicle.VehicleID
Policy.CustomerID references Customer.CustomerID
Vehicle.VehicleCode references VehicleCodeMapping.VehicleCode
VehicleExcessRange.VehicleCode references VehicleCodeMapping.VehicleCode
VehicleValue.VehicleCode references VehicleCodeMapping.VehicleCode
Task 1a
Return the number of vehicles used for every VehiclePurpose, ordered greatest to least.
NoteWorking
SELECT   VehiclePurpose, COUNT(*)
FROM     Vehicle
GROUP BY VehiclePurpose
ORDER BY COUNT(*) DESC;
Task 2
Which CustomerID(s) have at least 2 Policies?
NoteWorking
SELECT   CustomerID
FROM     Policy
GROUP BY CustomerID
HAVING   COUNT(*) >= 2;
Task 3
The marketing team wants to find the most common suburb of our customers (return the suburb name and street count, two columns). If there are ties, return all of them, in ascending alphabetical order of suburb name. Assume different suburbs never share a name.
NoteWorking
SELECT   Suburb AS 'Suburb Name', COUNT(*) AS 'Street Count'
FROM     Address
GROUP BY Suburb
HAVING   COUNT(*) >= ALL (
    SELECT   COUNT(*)
    FROM     Address
    GROUP BY Suburb
)
ORDER BY Suburb ASC;
>= ALL (...) here means “greater than or equal to every group’s count” — i.e. the maximum. See 2026-04-13-nested-queries-views-and-generative-ai for more on ALL.
Task 4a
A possible fraud was detected — identify all street names containing "et" with at least two customers living on that street.
SELECT   StreetName
FROM     Address
WHERE    StreetName LIKE '%et%'
GROUP BY Postcode, StreetName
HAVING   COUNT(*) >= 2;
NoteWorking
This query is incorrect as written: grouping by (Postcode, StreetName) doesn’t account for whether two customers actually live at the same address (e.g. a shared house sharing one AddressID) versus merely the same street. Correctly answering this requires joining Address to Customer and reasoning about which customers share an address — which needs a multi-relation query, covered next week. This is a useful edge case to notice: grouping by the wrong combination of columns can silently produce a plausible-looking but wrong count.
Task 4b
Duplicate counting can happen for many different reasons — check whether the query above counts each street name correctly.
NoteWorking
Same underlying issue as 4a — grouping by StreetName alone (dropping Postcode from the GROUP BY) doesn’t fix the shared-address double-counting problem either; both versions can overcount when multiple customers share one AddressID.
Week 8
Nested Queries, Views and Generative AI & SQL
Module 3, part 3 — the last SQL lecture. Continues 2026-03-30-basic-sql-ddl-and-dml and 2026-04-06-aggregation-grouping-and-multiple-relation-queries, using the same Company and Movie schemas.
Today’s outline
- Nested queries (subqueries) — output types, correlated vs non-correlated, relational division
- Views
- Generative AI & SQL
Nested queries
A nested query (subquery) is a query that appears inside another query — nesting can occur at multiple levels. The query containing the nested query is the outer query. Subqueries let you compute an intermediate result and feed it into a larger query, without creating a temporary table.
-- INVALID: can't use an aggregate directly in WHERE
SELECT name, salary
FROM   Employee
WHERE  salary > AVG(salary);

-- Valid: wrap the aggregate in a subquery
SELECT name, salary
FROM   Employee
WHERE  salary > (SELECT AVG(salary) FROM Employee);
Subquery output types
| Type | Expected result | Operators | Example |
|---|---|---|---|
| Scalar | A single value | =, <, >, != |
salary > (SELECT AVG(salary) ...) |
| Set | A list of values (1 column) | IN, NOT IN, ANY, ALL |
WHERE dept IN (SELECT dNumber ...) |
| Table | Rows & columns (a relation) | used in FROM |
FROM (SELECT ...) AS sub |
| Boolean | True/false for a row | EXISTS, NOT EXISTS |
WHERE EXISTS (SELECT * FROM ...) |
Always ask: what do I expect this subquery to return — a value, a list, a table, or a yes/no? That determines which clause it can go in and which operators are legal.
Scalar — a single value, for direct comparison. Common pitfall: a scalar subquery that unexpectedly returns more than one row raises an error (“subquery returned more than one row”).
SELECT name, salary
FROM   Employee
WHERE  salary > (SELECT AVG(salary) FROM Employee);
Set — a list of values, for IN/NOT IN/ANY/ALL. Common pitfall: never use = where the subquery can return multiple rows.
-- Departments with (not) a manager named "Jennifer"
SELECT dName FROM Department
WHERE  mgrSSN IN (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');

SELECT dName FROM Department
WHERE  mgrSSN NOT IN (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');
IN is equivalent to = ANY:
SELECT DISTINCT dName FROM Department
WHERE  mgrSSN = ANY (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');
ALL requires the comparison to hold against every value returned:
-- Employees earning more than everyone in department 5
SELECT *
FROM   Employee
WHERE  salary > ALL (SELECT salary FROM Employee WHERE dNum = 5);
Table — used in FROM, must be given an alias.
-- Average salary per department, alongside the department name
SELECT d.dName, avgSal.avg_salary
FROM   Department d
JOIN   (SELECT dNum, AVG(salary) AS avg_salary
        FROM   Employee
        GROUP BY dNum) AS avgSal ON d.dNumber = avgSal.dNum;
Boolean — EXISTS/NOT EXISTS check for the presence of any row; they don’t return data, just yes/no.
-- Employees in a department that currently has a manager assigned
SELECT name, dNum
FROM   Employee e
WHERE  EXISTS (
    SELECT * FROM Department d
    WHERE  d.dNumber = e.dNum AND d.mgrSSN IS NOT NULL
);
Joins vs subqueries
Many nested queries are equivalent to a plain JOIN — but not always.
- Joins can display columns from every table in the
FROMclause; a subquery-based query can only display columns from the outer query’s table(s). - Subqueries can compute an aggregate on the fly and feed it back to the outer query for comparison — an advantage over joins.
Rule of thumb: use a join when displaying results from multiple tables; use a subquery when comparing against an aggregate.
Subqueries with GROUP BY / HAVING
-- WHERE and HAVING both apply to "earning > 20000" (same filtered set)
SELECT   dNum, COUNT(*)
FROM     Employee E1
WHERE    salary > 20000
GROUP BY dNum
HAVING   2 < COUNT(*);

-- HAVING instead checks a DIFFERENT condition, over ALL employees,
-- via a correlated subquery
SELECT   dNum, COUNT(*)
FROM     Employee E1
WHERE    salary > 20000
GROUP BY dNum
HAVING   2 < (SELECT COUNT(*) FROM Employee E2 WHERE E1.dNum = E2.dNum);
The first finds departments with >2 employees earning over 20000; the second finds departments (among those with employees earning over 20000) that have >2 employees in total.
EXISTS / NOT EXISTS
Subqueries using EXISTS/NOT EXISTS are always correlated. EXISTS (subquery) is true if the subquery’s result is non-empty; NOT EXISTS (subquery) is true if it’s empty.
-- Movies that were the ONLY movie produced that year
SELECT *
FROM   Movie M1
WHERE  NOT EXISTS (
    SELECT * FROM Movie M2
    WHERE  M1.movieID <> M2.movieID AND M1.year = M2.year
);

-- Movies that were NOT the only movie produced that year
SELECT *
FROM   Movie M1
WHERE  EXISTS (
    SELECT * FROM Movie M2
    WHERE  M1.movieID <> M2.movieID AND M1.year = M2.year
);
Relational division
Division answers “for all”/“for every” queries — e.g. find movie stars who were in all movies [produced in a given year].
Dividing R1 / R2: the result has R1’s columns except R2’s, where R1 and R2 must be division compatible (R1’s last n columns identically named to R2’s n columns, n = R2’s degree). The result contains a value t if t appears in R1 in combination with every tuple of R2.
Student Degree   Subject          Subject   Student Degree
Anna    BIT      CS114     ÷      CS114  =  Anna    BIT
Anna    BIT      CS115            CS115
Anna    BIT      CS180
Fred    BSc      CS114
Fred    BSc      CS180
(Fred is excluded — Fred hasn’t taken CS115, so Fred doesn’t divide evenly by {CS114, CS115}.)
MySQL has no / division operator for relations — division is expressed via counting or double negation.
Division via counting
“Find the movie star(s) who acted in at least all the movies produced in 1934.” For a candidate star X: count how many 1934 movies X acted in, and compare that count to the total number of 1934 movies — if they’re equal, X acted in all of them.
SELECT   X.starID, X.name
FROM     MovieStar X
JOIN     StarsIn S ON X.starID = S.starID
JOIN     Movie M ON S.movieID = M.movieID
WHERE    M.year = 1934
GROUP BY X.starID
HAVING   COUNT(*) = (SELECT COUNT(*) FROM Movie M2 WHERE M2.year = 1934);
Division via double negation
“Find X such that there is no 1934 movie which X did not act in.” This reformulates “for all” as “there does not exist an exception”:
SELECT starID, name
FROM   MovieStar X
WHERE  NOT EXISTS (
    SELECT *
    FROM   StarsIn S
    JOIN   Movie M ON S.movieID = M.movieID
    WHERE  M.year = 1934
      AND  M.movieID NOT IN (
          SELECT movieID FROM StarsIn M2 WHERE M2.starID = X.starID
      )
);
Reading from the inside out: the innermost subquery is “all movies X acted in”; the middle subquery is “1934 movies X did not act in”; the outer NOT EXISTS is “there is no such movie” — i.e. X acted in every 1934 movie.
Question 17 — Subquery
Given Employee [ID, Name, DepartmentID] and Department [ID, Department, ManagerID], how do you find all employees managed by Michael Scott?
A. WHERE DepartmentID = (SELECT ID FROM Employee WHERE name="Michael Scott") B. WHERE DepartmentID IN (SELECT ID FROM Department WHERE ManagerID = (SELECT ID FROM Employee WHERE name="Michael Scott")) C. WHERE DepartmentID = (SELECT DepartmentID FROM Employee WHERE name="Michael Scott") D. FROM Employee, Department WHERE name="Michael Scott" AND departmentID=ID
NoteSolution
B. We need Michael Scott’s ID (from Employee), then the Department(s) he manages (ManagerID = his ID), then employees whose DepartmentID matches one of those departments. A incorrectly compares an Employee.DepartmentID to an Employee.ID (mismatched domains). C and D make the same mistake — they never consult Department at all, so they can’t find who Michael manages, only who shares his own DepartmentID.
Question 19 — Division
Given R1 [Category, SecondaryCategory, Budget] and R2 [SecondaryCategory, Budget] (values Romance/10 and Horror/10), what is R1 / R2?
NoteSolution
Category = Drama, Comedy (a single-column result). Only Drama and Comedy appear in R1 paired with both (Romance, 10) and (Horror, 10) — Action only pairs with (Horror, 10), so it’s excluded. The result keeps only the columns of R1 not in R2 (just Category), not the full (Category, SecondaryCategory, Budget) tuples.
Question 20 — Division
Given R1 as above, R2 = {(Romance,10), (Horror,10)}, and R3 = {(Horror, 11)} — what tuple is in both R1/R2 and R1/R3?
A. (Drama, Romance, 10) B. (Drama) C. (Action) D. (Comedy, Horror, 10) E. None of the above
NoteSolution
B. From Question 19, R1/R2 = {Drama, Comedy}. R3 has a single tuple (Horror, 11), so R1/R3 contains every category paired with (Horror, 11) in R1 — both Drama (Drama, Horror, 11) and Comedy (Comedy, Horror, 11) qualify, so R1/R3 = {Drama, Comedy} too. The intersection of R1/R2 and R1/R3 is therefore {Drama, Comedy} — Drama is in both, which is what option B asserts (Comedy isn’t offered as a choice here). A and D are the wrong shape (division results keep only the Category column, degree 1 — not the full 3-column tuple); C (Action) never appears in either division, since Action only pairs with (Horror, 10), not (Romance, 10) or (Horror, 11).
Views
A view is a single table derived from other tables (base tables or other views).
- Virtual — does not physically exist on disk; recomputed each time it’s queried.
- Materialized — physically stored, and must be refreshed when base tables change.
CREATE VIEW <view name> (<column name> {, <column name>}) AS <select statement>;-- Count, gender and average salary of employees, per department
CREATE VIEW DepEmpStatus AS
SELECT dNumber, dName, sex, COUNT(*) AS employeeNumber, AVG(salary) AS avgSalary
FROM Department AS D
JOIN Employee AS E ON D.dNumber = E.dNum
GROUP BY dNum, sex;
SELECT * FROM DepEmpStatus;Given DepEmpStatus but not Department/Employee directly, a user can see aggregate departmental statistics without access to confidential per-employee data (address, salary).
Benefits of views
- Simplification — hide the complexity of underlying tables.
- Security — hide sensitive columns from some users.
- Computed columns — computed on the fly.
- Logical data independence — users/programs querying the view are insulated from changes to the underlying logical schema.
View updates and dropping
Updates to a view must ultimately happen on the base table(s) — this can be ambiguous or difficult in general, so DBMSs restrict updates to simple, single-table updatable views (e.g. a view of “employees from department X” that a department manager can edit directly).
DROP VIEW [IF EXISTS] view_name [, view_name] ... [RESTRICT | CASCADE];DROP TABLE ... RESTRICT refuses to drop a table with views defined on it; DROP TABLE ... CASCADE drops the table and recursively drops any dependent views.
Question 21 — Views
Given R [a, b, c],
CREATE VIEW V AS SELECT a+b AS d, c FROM R;
SELECT d, SUM(c) FROM V GROUP BY d HAVING COUNT(*) <> 1;which tuple is returned? A. (2,3) B. (3,12) C. (5,9) D. All are correct E. None are correct
NoteSolution
C. Computing d = a+b for every row of R [a,b,c] = (1,1,3), (1,2,3), (2,1,4), (2,3,5), (2,4,1), (3,2,4), (3,3,6) gives view rows (d=2,c=3), (d=3,c=3), (d=3,c=4), (d=5,c=5), (d=6,c=1), (d=5,c=4), (d=6,c=6). Grouping by d:
| d | rows (c values) | COUNT(*) | SUM(c) |
|---|---|---|---|
| 2 | 3 | 1 | 3 |
| 3 | 3, 4 | 2 | 7 |
| 5 | 5, 4 | 2 | 9 |
| 6 | 1, 6 | 2 | 7 |
HAVING COUNT(*) <> 1 excludes d=2 (only one row), leaving (3,7), (5,9), (6,7). (5, 9) is genuinely in the result; (2,3) was excluded by the HAVING, and (3,12) doesn’t match d=3’s actual sum of 7.
Views as a cleaner alternative to nested subqueries
-- Ugly: nested subquery re-derives the per-department total twice
SELECT d.dName
FROM Department d,
(SELECT dNum, SUM(salary) AS departmentWage
FROM Employee GROUP BY dNum) AS Temp
WHERE d.dNumber = Temp.dNum
AND Temp.departmentWage = (
SELECT MAX(departmentWage)
FROM (SELECT SUM(salary) AS departmentWage
FROM Employee GROUP BY dNum) AS Temp2
);
-- Cleaner: define the intermediate result as a view, once
CREATE VIEW Temp AS
SELECT dNum, SUM(salary) AS departmentWage
FROM Employee
GROUP BY dNum;
SELECT *
FROM Temp
WHERE departmentWage IN (SELECT MAX(departmentWage) FROM Temp);Generative AI & SQL
Generative AI uses machine learning to produce new content (text, images, code, music) from a prompt. It can draft code/queries, explain concepts, summarise data, and much more — but it is not infallible.
Risks to keep in mind
- Hallucination — confident-sounding but false/misleading output: fake sources, incorrect facts, invented code/data/people.
- Deepfakes — digitally altered video/image/audio depicting someone saying or doing something they didn’t; hard to detect, can spread misinformation or damage reputations.
- Bias — AI trained on human-generated data can repeat or amplify existing biases (gender/racial bias in language or image models, cultural bias from uneven data representation, confirmation bias in recommendations).
Five tips for responsible use: remember AI is a tool, not a person; critically evaluate its output; investigate anything that “feels off”; keep private information private; use AI to elevate your skills, not replace them.
Three GenAI-assisted SQL workflows
- Full query workflow (schema + data) — share both the schema and sample data; the AI can generate a full query and the expected result. Good for rapid prototyping and teaching SQL end-to-end. Caution: verify the output manually, since results can still hallucinate.
- Schema-only query generation — share only the schema (useful when the data itself is privacy-sensitive). Good for planning queries before you have data access. Caution: without data, the AI may make incorrect assumptions — review generated queries for correctness.
- Query explanation & debugging — paste an existing query and ask the AI to explain it, or help debug syntax errors, logic problems, or unexpected results. Caution: explanations can still contain inaccuracies — cross-check against the schema and expected logic.
Learning SQL yourself, while building AI confidence
This course’s priority is that you learn to write SQL independently — you’ll be tested on this without AI tools (the final exam, and the Assignment 2 oral interview). At the same time, you’re encouraged to use AI in Assignment 2 to test/check queries and deepen your understanding — the goal is to use AI as a supportive partner, not a substitute for your own skills. The RiPPLE weekly activities are scaffolded to build AI literacy progressively: designing your own questions grounded in course concepts, practising prompt engineering, critical/metacognitive reflection, and structured peer review — moving from passive AI use to critical, ethical, effective collaboration with AI tools.
Summary
You should now be able to write nested (correlated and non-correlated) subqueries, use relational division (via counting or double negation), create/drop views, and use generative AI tools for SQL responsibly. This completes the Module 3 lecture content — see week8-tutorial-applied-class-7-multiple-relation-queries and week9-tutorial-applied-class-8-nested-queries-and-views for practice.
Applied Class 7: DQL Multiple Relation SQL Queries
Practice for 2026-04-06-aggregation-grouping-and-multiple-relation-queries. Same BestTechLtd schema as week6-tutorial-applied-class-5-basic-sql-ddl-and-dml and week7-tutorial-applied-class-6-aggregation-and-grouping:
Employee [EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt]
AdministrativeEmployee [EmployeeID, Level, Type]
Role [RoleID, Name, Description]
RoleGranting [EmployeeID, RoleID, AdministrationID, Timestamp]
Permission [WebsiteURI, RoleID, GrantType, Description]
AdministrativeEmployee.EmployeeID references Employee.EmployeeID
RoleGranting.EmployeeID references Employee.EmployeeID
RoleGranting.RoleID references Role.RoleID
RoleGranting.AdministrationID references AdministrativeEmployee.EmployeeID
Permission.RoleID references Role.RoleIDQuestion 1
Return the distinct role ID, name and descriptions of all roles which permit access to commercial websites (URI ends with .com).
NoteWorking
SELECT DISTINCT R.RoleID, R.Name, R.Description
FROM Role R
JOIN Permission P ON P.RoleID = R.RoleID
WHERE P.WebsiteURI LIKE '%.com';Question 2
Return the First Name, Last Name, Level, Type and Salary of all Administrative Employees.
NoteWorking
SELECT FirstName, LastName, Level, Type, Salary
FROM AdministrativeEmployee AE
JOIN Employee E ON E.EmployeeID = AE.EmployeeID;Question 3
For every role, find the number of websites it gives access to. Two columns: RoleId, number of website URIs.
NoteWorking
SELECT R.RoleID, COUNT(DISTINCT WebsiteURI)
FROM Role R
LEFT JOIN Permission P ON P.RoleId = R.RoleID
GROUP BY R.RoleID;A LEFT JOIN (not an inner join) is needed here so that roles with zero permissions still appear in the result, with a count of 0.
Question 4
For Employee Sofia Gonzalez, return the distinct name and description of the role(s) she was granted, along with the description of the associated permissions.
NoteWorking
SELECT DISTINCT R.Name, R.Description, P.Description
FROM Employee E
JOIN RoleGranting RG ON E.EmployeeID = RG.EmployeeID
JOIN Role R ON RG.RoleID = R.RoleID
LEFT JOIN Permission P ON P.RoleID = RG.RoleID
WHERE E.FirstName = 'Sofia' AND E.LastName = 'Gonzalez';Question 5
The co-founders of BestTechLtd can be identified as either: (A) Administrative Employees with a 'LegacyEngineer' type; (B) Employees granted the FinancialPerformanceOverview role; or (C) Employees with permission to view* (but not edit) https://grafana.besttechltd.com. Return the EmployeeID, first and last name of all co-founders.*
Restriction: use at least one set operation.
NoteWorking
SELECT E.EmployeeID, E.FirstName, E.LastName
FROM Employee E
JOIN AdministrativeEmployee AE ON AE.EmployeeID = E.EmployeeID
WHERE AE.Type = 'LegacyEngineer'
UNION
SELECT E.EmployeeID, E.FirstName, E.LastName
FROM Employee E
JOIN RoleGranting RG ON RG.EmployeeID = E.EmployeeID
JOIN Role R ON R.RoleID = RG.RoleID
WHERE R.Name = 'FinancialPerformanceOverview'
UNION
SELECT E.EmployeeID, E.FirstName, E.LastName
FROM Employee E
JOIN RoleGranting RG ON RG.EmployeeID = E.EmployeeID
JOIN Permission P ON P.RoleID = RG.RoleID
WHERE P.WebsiteURI = 'https://grafana.besttechltd.com' AND P.GrantType = 'View';Three independent conditions, each a join producing the same (EmployeeID, FirstName, LastName) shape, combined with UNION (which also conveniently de-duplicates employees matching more than one condition).
Question 6
Return all employees who have been granted at least two roles, and can edit at least four distinct website URIs.
NoteWorking
SELECT EmployeeID
FROM RoleGranting RG
GROUP BY EmployeeID
HAVING COUNT(RoleID) >= 2
INTERSECT
SELECT EmployeeID
FROM RoleGranting RG
JOIN Permission P ON P.RoleID = RG.RoleID
WHERE P.GrantType = 'Edit'
GROUP BY EmployeeID
HAVING COUNT(DISTINCT WebsiteURI) >= 4;INTERSECT combines two independently-grouped-and-filtered employee lists — “granted ≥2 roles” and “can edit ≥4 distinct websites” — rather than trying to express both conditions in one GROUP BY/HAVING (which would conflate the two different counts). Note INTERSECT isn’t implemented in MySQL — see 2026-04-06-aggregation-grouping-and-multiple-relation-queries for how to rewrite it as a self-join.
Week 9
Applied Class 8: DQL Nested Queries and Views
Practice for 2026-04-13-nested-queries-views-and-generative-ai. Same BestTechLtd schema as week8-tutorial-applied-class-7-multiple-relation-queries:
Employee [EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt]
AdministrativeEmployee [EmployeeID, Level, Type]
Role [RoleID, Name, Description]
RoleGranting [EmployeeID, RoleID, AdministrationID, Timestamp]
Permission [WebsiteURI, RoleID, GrantType, Description]
AdministrativeEmployee.EmployeeID references Employee.EmployeeID
RoleGranting.EmployeeID references Employee.EmployeeID
RoleGranting.RoleID references Role.RoleID
RoleGranting.AdministrationID references AdministrativeEmployee.EmployeeID
Permission.RoleID references Role.RoleIDNested queries
Question 1
Return the Date of Birth, first and last name of the youngest employee(s).
NoteWorking
SELECT E.DOB, E.FirstName, E.LastName
FROM Employee E
WHERE DOB >= (SELECT MAX(DOB) FROM Employee E2);>= (not =) against the max, so ties for youngest are all returned, not just one arbitrary row.
Question 2
Return all information about all employees that have not been granted a role from an Administrator with type 'ProductEngineer'. Restriction: must use a subquery.
NoteWorking
SELECT E.*
FROM Employee E
WHERE EmployeeID NOT IN (
SELECT DISTINCT E2.EmployeeID
FROM Employee E2
JOIN RoleGranting RG ON RG.EmployeeID = E2.EmployeeID
JOIN AdministrativeEmployee AE ON AE.EmployeeID = RG.AdministrationID
WHERE AE.Type = 'ProductEngineer'
);Question 3
Find the number of employees who share a surname with another employee.
NoteWorking
SELECT COUNT(*) AS employees_with_shared_surname
FROM Employee E1
WHERE LastName IS NOT NULL
AND EXISTS (
SELECT * FROM Employee E2
WHERE E1.LastName = E2.LastName AND E1.EmployeeID != E2.EmployeeID
);A correlated EXISTS check — for each E1, is there some other employee E2 with the same last name?
Question 4
Return the EmployeeId of the Administrative Employee(s) that have granted at least as many roles to employees as Mehdi Rahman. Assume only one Mehdi Rahman exists, and include Mehdi Rahman in the result.
NoteWorking
SELECT RG.AdministrationID
FROM AdministrativeEmployee AE
JOIN RoleGranting RG ON AE.EmployeeID = RG.AdministrationID
GROUP BY RG.AdministrationID
HAVING COUNT(DISTINCT RG.EmployeeID, RG.RoleID) >= (
SELECT COUNT(DISTINCT RG.EmployeeID, RG.RoleID)
FROM RoleGranting RG
JOIN Employee E ON RG.AdministrationID = E.EmployeeID
WHERE E.FirstName = 'Mehdi' AND E.LastName = 'Rahman'
GROUP BY RG.AdministrationID
);Question 5
Find the first name and last name of all employees that have access to at least all the website URIs that Employee E0007 has access to.
NoteWorking
SELECT E.FirstName, E.LastName
FROM Employee E
WHERE NOT EXISTS (
SELECT P.WebsiteURI
FROM Employee E2
JOIN RoleGranting RG1 ON RG1.EmployeeID = E2.EmployeeID
JOIN Permission P ON P.RoleID = RG1.RoleID
WHERE E2.EmployeeID = 'E0007'
AND P.WebsiteURI NOT IN (
SELECT P2.WebsiteURI
FROM RoleGranting RG2
JOIN Permission P2 ON P2.RoleID = RG2.RoleID
WHERE RG2.EmployeeID = E.EmployeeID
)
);This is a relational division via double negation — “there is no website E0007 can access that E cannot” — see 2026-04-13-nested-queries-views-and-generative-ai for the general pattern.
Views
Question 6
Return the EmployeeID, FirstName, LastName and RoleId of all employees who were the first to receive a given RoleID.
NoteWorking
DROP VIEW IF EXISTS EarliestRoleGranting;
CREATE VIEW EarliestRoleGranting AS
SELECT RoleID, MIN(TimeStamp) AS EarliestTimeStamp
FROM RoleGranting
GROUP BY RoleID;
SELECT E.EmployeeID, E.FirstName, E.LastName, RG.RoleID
FROM RoleGranting RG
JOIN EarliestRoleGranting ERG
ON ERG.RoleID = RG.RoleID AND ERG.EarliestTimeStamp = RG.TimeStamp
JOIN Employee E ON E.EmployeeID = RG.EmployeeID;Question 7
Return the EmployeeID of the Administrator(s) that have granted the most permissions of any other Administrator. Restriction: must use one or more views.
NoteWorking
DROP VIEW IF EXISTS AdminPermissionsCount;
CREATE VIEW AdminPermissionsCount AS
SELECT AE.EmployeeID,
COUNT(WebsiteURI) AS NumOfPermissionsGranted
FROM AdministrativeEmployee AE
LEFT JOIN RoleGranting RG ON RG.AdministrationID = AE.EmployeeID
LEFT JOIN Permission P ON P.RoleID = RG.RoleID
GROUP BY AE.EmployeeID;
SELECT *
FROM AdminPermissionsCount
WHERE NumOfPermissionsGranted >= (
SELECT MAX(APC2.NumOfPermissionsGranted)
FROM AdminPermissionsCount APC2
);Week 10
Database Design Guidelines and Functional Dependencies
Module 4, part 1. This module concerns database design theory — how to measure the quality of a relational schema, and how to fix a poor one.
Today’s outline
- Informal design guidelines
- Functional dependencies (FDs) — definition, keys, closure
Informal design guidelines
Four informal measures of relational schema quality:
- Make sure the semantics of the attributes are clear in the schema.
- Reduce redundant values in tuples.
- Reduce null values in tuples.
- Disallow spurious tuples (don’t allow lossy joins).
Guideline 1 — one relation, one meaning
Design each relation so its meaning is easy to explain. Don’t combine attributes from multiple entity/relationship types into one relation — this confuses the entity’s meaning and causes redundancy.
EMPLOYEE [Ename, Ssn, Bdate, Address, Dnumber] -- FK: Dnumber
DEPARTMENT [Ename, Dnumber, Dmgr_ssn] -- FK: Dmgr_ssn
-- vs. combining them into one relation:
EMP_DEPT [Ename, Ssn, Bdate, Address, Dnumber, Dname, Dmgr_ssn]Guideline 2 — avoid update anomalies
Design base relations so that no insertion, deletion, or modification anomalies occur. If anomalies can’t be avoided, applications must update relations carefully enough to preserve database integrity.
Motivating example — an Employee [ID, Name, Level, Salary] table where salary is fixed per level (Developer=60,000, Manager=700,000, Driver=50,000, Administration=50,000):
| ID | Name | Level | Salary |
|---|---|---|---|
| 1 | Paris | Developer | 60,000 |
| 2 | Anna | Manager | 700,000 |
| 3 | Ben | Manager | 700,000 |
| 4 | Rose | Driver | 50,000 |
| 5 | Jack | Developer | 60,000 |
| 6 | Charlie | Administration | 50,000 |
- Modification anomaly: updating one developer’s salary makes the “Developer” salary inconsistent with the others.
- Deletion anomaly: deleting Charlie loses the fact that Administration pays 50,000 (Charlie was the only Administration row).
- Insertion anomaly: can’t record a Cook’s salary until an employee actually holds that position; inserting a new Developer row with a different salary makes the Developer salary inconsistent.
These aren’t just textbook abstractions — a widely reported 2021 issue with Australia’s vaccine certificate system arose from essentially this class of problem: state vaccination staff recorded details in a way that didn’t precisely match federal records, so contradicting datasets failed to reconcile automatically.
Decomposition
A decomposition of relation R replaces it with two or more relations such that (1) each new relation’s attributes are a subset of R’s (no foreign attributes), and (2) every attribute of R appears in at least one new relation.
Decomposing the Employee example correctly:
Employee [ID, Name, Level]
Level_Salary [Level, Salary]removes all three anomaly types — modifying one developer’s salary in Level_Salary doesn’t touch Employee; deleting an employee’s row doesn’t touch Level_Salary; a Cook’s salary can be stored in Level_Salary before anyone holds that role. (An incorrect decomposition — e.g. splitting into [ID, Name, Salary] and [Salary, Level] — does not fix the anomalies, since Salary isn’t a valid link back to Level on its own.)
The join operation and lossless joins
R1 ⋈ R2 (natural join): concatenate each tuple of R1 with every tuple of R2 agreeing on their common attributes.
A decomposition of R into R1 and R2 is a lossless join decomposition if, for every legal instance, R = R1 ⋈ R2 — i.e. breaking R apart and rejoining it gives back exactly R, no more, no less.
Lossy join example — decomposing R [A, B, C] into R1 [A, B] and R2 [B, C] when B does not uniquely determine C:
R R1 R2 R1 ⋈ R2 (rejoined)
A B C A B B C A B C
1 2 3 1 2 2 3 1 2 3
4 5 6 → 4 5 + 5 6 → 1 2 9 <- spurious!
7 2 9 7 2 2 9 4 5 6
7 2 3 <- spurious!
7 2 9Here “loss” means loss of information, not loss of tuples — two extra (“spurious”) rows appear because B = 2 maps to two different C values (3 and 9), so the join can’t tell which A goes with which C.
Guideline 4 — join on keys
Design relation schemas so they can be joined using equality conditions on primary/foreign keys, in a way that guarantees no spurious tuples are generated.
Functional dependencies
Motivating question: how can we be sure that all employees at the same level have the same salary, rather than it just happening to be true of the current data? Databases let you declare this formally via a functional dependency (FD): level → salary (“level determines salary” — if we know an employee’s level, we know their salary).
Formal definition
An FD X → Y holds on relation R if, for every legal instance r of R and all tuple pairs t1, t2 ∈ r:
\[t_1[X] = t_2[X] \implies t_1[Y] = t_2[Y]\]
i.e. if two tuples agree on X, they must agree on Y. X → Y is a constraint between two attribute sets X and Y — it restricts which tuples can legally appear together in an instance of R.
Crucially: an FD is a statement about all allowable instances. You can check whether a given instance violates an FD, but you can never prove an FD holds just by looking at one instance — FDs must be identified from the application’s real-world semantics (business rules), not reverse-engineered from a data sample.
Question 1 — Functional dependencies
Given R [A, B, C, D] with rows (1,2,3,4), (2,3,4,6), (6,7,8,9), (1,3,4,5) — which FDs cannot be true?
A. B → C B. B → D C. D → B D. All of the above can be true E. None of the above can be true
NoteSolution
B. Rows 2 and 4 both have B = 3, but row 2 has D = 6 while row 4 has D = 5 — two tuples agreeing on B disagree on D, so B → D is impossible. B → C and D → B are both still possible given this instance (no counterexample rows exist for either) — remember, “possible” here just means “not yet contradicted”, not “proven”.
Fixing anomalies via FDs
Given level → salary, decomposing Employee into [ID, Name, Level] and [Level, Salary] fixes all three anomaly types from before — updating a developer’s salary in [Level, Salary] no longer creates inconsistency; deleting an employee no longer loses level/salary mappings; a new level’s salary can be recorded independent of whether any employee holds it yet.
Question 2 — Anomalies
Given R [A, B, C, D] with D → {A, C} and rows (1,4,2,5), (2,3,4,3), (1,1,2,5) — which is not an example of an update anomaly?
A. Deleting <2,3,4,3> B. Inserting <3,5,3,3> C. Modifying <1,1,2,5> to <1,2,2,5> D. Inserting <1,null,2,4> E. Modifying <1,1,2,5> to <1,2,3,5>
NoteSolution
C. Modifying B from 1 to 2 (row <1,1,2,5> → <1,2,2,5>) doesn’t touch A, C, or D at all — B isn’t constrained by D → {A, C}, so no anomaly results. A is an anomaly (deletes the only row with D=3, losing the fact that D=3 → {A=2, C=4}). B is an anomaly (row 2, <2,3,4,3>, already establishes D=3 → {A=2, C=4}; inserting <3,5,3,3> gives D=3 a different A/C pair, {A=3, C=3}, contradicting it). D is an anomaly (a null in the primary key violates entity integrity). E is an anomaly (both existing D=5 rows have C=2; changing one to C=3 breaks D → C consistency).
Keys
A key is a minimal set of attributes that uniquely identifies a relation’s tuples — equivalently, a minimal set of attributes that functionally determines all attributes in the relation. A superkey is any set of attributes (not necessarily minimal) that uniquely identifies the relation.
Question 3 — Possible keys
Given R [A, B, C, D] with B → C, C → B, D → {A, B, C} — which is a key?
A. B B. C C. {B, D} D. All of the above E. None of the above
NoteSolution
E. B doesn’t determine D or A ({B}⁺ = {B, C}, missing A, D) — not a key. C is symmetric to B ({C}⁺ = {B, C}) — also not a key. {B, D} does determine everything (D alone already does, via D → {A,B,C}), but it’s not minimal — D alone is already a key, so {B, D} is a superkey, not a (candidate) key.
Question 4 — Possible superkeys
Same FDs as Question 3 — which is a superkey?
A. D B. {B, D} C. {B, C, D} D. All are superkeys E. None are superkeys
NoteSolution
D. D → {A, B, C} means D alone determines every attribute — D is a key, and therefore every superset of D ({B,D}, {B,C,D}) is automatically a superkey too.
Explicit and implicit FDs; closure of F
Given a set of explicit FDs, further implicit (inferred) FDs can be derived — e.g. from ID → level and level → salary, we can infer ID → salary. The notation F ⊨ X → Y means X → Y can be inferred from F (X = left-hand side/LHS, Y = right-hand side/RHS).
- Trivial FDs hold regardless of
F(the LHS already contains the RHS) — e.g.A → A,{A,B,C} → {A,B}. - Non-trivial FDs depend on the specific
F— e.g.A → B.
The closure of F, written F⁺, is the set of all FDs (trivial and non-trivial) implied by F. F⁺ can be computed via Armstrong’s Axioms, but that’s outside this course’s scope — instead we focus on attribute closure.
Attribute closure (X⁺)
X⁺ is the set of all attributes determined by X under F:
X+ := X;
repeat
old X+ := X+;
for each FD Y → Z in F:
if Y ⊆ X+ then X+ := X+ ∪ Z;
until (old X+ = X+);Example — Employee (ID, level, salary, name), F = {ID → level, level → salary, ID → name}:
ID⁺ = {ID}ID⁺ = {ID, level}(usingID → level)ID⁺ = {ID, level, salary}(usinglevel → salary)ID⁺ = {ID, level, salary, name}(usingID → name)
Larger example — R [pNumber, pName, pLocation, dNum, dName, mgrSSN, mgrStartDate], F = {pNumber → {pName, pLocation, dNum}, dNum → {dName, mgrSSN, mgrStartDate}}:
{pNumber}⁺ = {pNumber}{pNumber}⁺ = {pNumber, pName, pLocation, dNum}(FD1){pNumber}⁺ = {pNumber, pName, pLocation, dNum, dName, mgrSSN, mgrStartDate}(FD2) — the full relation, sopNumberis a key.
Finding a superkey — show {sName, pNum} is a superkey for SupplierPart (sName, city, status, pNum, pName, qty) with F = {sName → city, city → status, pNum → pName, {sName, pNum} → qty}:
{sName, pNum}+ = {sName, pNum}
{sName, pNum}+ = {sName, pNum, city} using sName → city
{sName, pNum}+ = {sName, pNum, city, status} using city → status
{sName, pNum}+ = {sName, pNum, city, status, pName} using pNum → pName
{sName, pNum}+ = {sName, pNum, city, status, pName, qty} using {sName,pNum}→qtySince the closure covers every attribute of SupplierPart, {sName, pNum} is a superkey.
Tips for finding keys
Given a relation R and FD set F: S ⊆ R is a key iff (1) S⁺ = R, and (2) no proper subset S' ⊂ S also has S'⁺ = R. For n attributes there are 2ⁿ subsets to consider in the worst case, but two shortcuts help:
- If an attribute never appears on the RHS of any FD, it must be part of every key (nothing else can ever produce it).
- If
Sis already a key, don’t test any superset ofS— it’ll be a superkey, not a (minimal) key. - A relation can have multiple keys of different sizes.
To fully show {sName, pNum} is a key (not just a superkey) for SupplierPart, also confirm minimality: {sName}⁺ = {sName, city, status} and {pNum}⁺ = {pNum, pName} — neither proper subset covers all attributes, so {sName, pNum} is minimal.
Question 5 — Finding keys
Given R [A, B, C, D, E, F] with B → {C, F}, C → E, {E, F} → D — which is a key?
A. B B. {B, E} C. {E, F} D. {A, B} E. None of the above
NoteSolution
D. {B}⁺ = {B, C, D, E, F} — misses A. {B, E}⁺ = same, still misses A. {E, F}⁺ = {D, E, F} — misses far more. {A, B}⁺ = {A, B, C, D, E, F} — everything. A never appears on any RHS, so (per the tip above) it must be in every key — confirming why options A–C, none of which include A, can never be keys.
Question 6 — Finding keys
Given R [A, B, C, D, E] with D → C, {C, E} → A, D → A, {A, E} → D — which is a key?
A. {A, B, D, E} B. {B, C, E} C. {C, D, E} D. All of these are keys E. None of these are keys
NoteSolution
B. {A, B, D, E} is a superkey but not minimal: since D → A already holds, A is redundant once D is present, so this isn’t the smallest determining set. {C, D, E}⁺: D → C (redundant, already have C), D → A adds A, {C,E} → A (redundant), {A,E} → D (redundant, already have D) — final closure {A, C, D, E}, missing B, so it’s not even a superkey. {B, C, E}⁺: {C,E} → A adds A (→ {A,B,C,E}), then {A,E} → D adds D (→ {A,B,C,D,E}) — every attribute, and no proper subset of {B,C,E} achieves this, so it’s a minimal key.
Question 7 — Finding keys
Given R [A, B, C, D, E, F] with {A, B} → E, C → {B, E}, {E, D} → F — which is a key?
A. {A, B} B. {A, B, C} C. {A, C, D} D. {A, D} E. None of the above
NoteSolution
C. {A, B}⁺ = {A, B, E} (via {A,B}→E) — misses C, D, F. {A, B, C}⁺ = {A, B, C, E} (C→{B,E} is redundant here) — still misses D, F. {A, D}⁺ = {A, D} — none of the three FDs’ left-hand sides ({A,B}, C, {E,D}) are subsets of {A, D} alone, so nothing can be added at all. {A, C, D}⁺: C → {B, E} adds B, E (→ {A,B,C,D,E}), then {E,D} → F adds F — every attribute. {A, C, D} is minimal and complete — a key.
Summary
You should now be familiar with informal design guidelines, functional dependencies (their formal definition and how to identify them), keys/superkeys, and how to compute attribute closure. These are the foundation for normalisation, covered next lecture. See week10-tutorial-applied-class-9-functional-dependencies and week10-tutorial-case-study-8-dirt-road-driving for practice.
Applied Class 9: Functional Dependencies
Practice for 2026-04-27-database-design-guidelines-and-functional-dependencies.
Section A — Anomalies and functional dependencies
Question A.1
Based on the following data, provide an example and explanation of an insertion, deletion and modification anomaly.
A B C D E
2 2 1 5 6
2 3 1 5 4
3 4 5 3 2
3 5 5 1 3Functional dependencies: {A} → {C}, {B} → {D, E}.
NoteWorking
- Insertion anomaly: insert anything into
B,DandE(withB,D,Evalues that don’t already exist in the data) without also inserting a value intoA— the row is incomplete but there’s noAto attach it to. - Deletion anomaly: deleting the tuple with
B = 4loses the information for the FDB → {D, E}, specifically4 → {3, 2}— no other row records that mapping. - Modification anomaly: updating
{2, 2, 1, 5, 6}to{2, 4, 1, 5, 6}creates an inconsistency inB → {D, E}— it now implies both4 → {3, 2}(from the existing row withB=4) and4 → {5, 6}(from the just-modified row).
Question A.2
Based on A → B, B → C, {C, D} → E, fill in the blanks (?) below so that no FD is violated.
A B C D E
1 2 1 6 2
1 ? 1 4 ?
2 4 2 7 4
3 ? ? 4 ?
NoteWorking
A B C D E
1 2 1 6 2
1 2 1 4 3
2 4 2 7 4
3 2 1 4 3Row 2’s B is forced: A = 1 also appears in row 1 (B = 2), and A → B requires matching A values to share the same B. Row 2’s E is then constrained by {C, D} → E: row 2 has {C=1, D=4}, a combination that will recur in row 4 — both rows sharing that {C, D} pair must agree on E (here, 3).
Row 4’s B and C are not strictly forced by the given FDs (A = 3 doesn’t recur elsewhere, so A → B places no constraint on it) — but choosing B = 2, C = 1 is a valid, self-consistent choice: it matches row 1/2’s B → C mapping (B=2 → C=1), and then {C=1, D=4} → E correctly forces row 4’s E to match row 2’s (E = 3), since both rows now share {C=1, D=4}. Note the knock-on: once B = 2 is chosen for row 4, B → C makes C = 1 no longer free either.
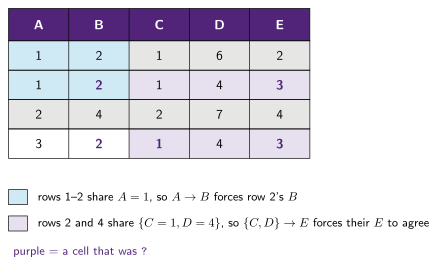
Figure 22: Which FD forces which cell. Purple values are the ones that were ?. Cyan pairs the rows that share an A value with the B values that A → B therefore ties together; lavender pairs the rows that share {C, D} with the E values that {C,D} → E ties together.
Question A.3
Based on the following data, identify which options are potential functional dependencies.
A B C D E
1 X 1 M 1
2 Y 1 M 1
3 Y 4 N 3
4 W 2 L 5
5 W 2 M 1
6 T 5 O 2A → B—B → A—A → C—B → C—C → D—C → E—D → E{A, B} → C—{B, C} → E—{B, C, D} → E
NoteWorking
Potential FDs: A → B, A → C (both trivially hold — every row has a distinct A, so there’s never a repeated-A pair to violate anything). D → E (every repeated D value agrees on E: D=M in rows 1, 2, 5 always has E=1). {A, B} → C (trivially holds, since A alone is already unique per row). {B, C, D} → E (every (B,C,D) triple in the table is distinct, so it trivially holds too).
Not potential (contradicted by the data):
B → A:B=Yappears in rows 2 and 3 with differentA(2vs3).B → C:B=Yappears in rows 2 and 3 with differentC(1vs4).C → D:C=2appears in rows 4 and 5 with differentD(LvsM).C → E:C=2appears in rows 4 and 5 with differentE(5vs1).{B, C} → E:{B=W, C=2}appears in rows 4 and 5 with differentE(5vs1).
Section B — Closures
Question B.1
Given R [A, B, C, D, E, F, G] with {A} → {D}, {B, C} → {A}, {C} → {F}, {F} → {E} — find the following closures.
NoteWorking
{C}⁺ = {C, F, E}(viaC→F, thenF→E).{B, C, A}⁺ = {A, B, C, D, E, F}(viaA→D,C→F,F→E).{B, C}⁺ = {A, B, C, D, E, F}(via{B,C}→A, thenA→D,C→F,F→E) — the same closure, soAadds nothing onceBandCare present.
Mind G. Both closures stop one attribute short of R, so neither set is a superkey as the question is written: G appears in R [A, B, C, D, E, F, G] but on no side of any FD, and an attribute that never appears on a right-hand side must belong to every key. The candidate key is therefore {B, C, G} — {B,C,G}⁺ is all of R, and neither {B, G} nor {C, G} reaches A. (Read the relation instead as R [A, B, C, D, E, F], the shape Section C.1 uses with the same style of FD set, and {B, C} is the candidate key with {A, B, C} a non-minimal superkey.) See attribute-closure.
Question B.2
Given R [A, B, C, D, E, F] with {A} → {B, C}, {C, D} → {E}, {A, C} → {E}, {B} → {D}, {E} → {A, B} — find the following closures.
NoteWorking
{A, F}⁺ = {A, B, C, D, E, F}(viaA→{B,C},B→D,{C,D}→Eor{A,C}→E,E→{A,B}).{C, D, F}⁺ = {A, B, C, D, E, F}(via{C,D}→E,E→{A,B}).- Both
{A, F}and{C, D, F}are minimal — removing any single attribute from either set makes the reduced set no longer a superkey.
Section C — Candidate keys
Question C.1
R [A, B, C, D, E, F] with {A, E} → {D}, {B, C} → {A}, {B} → {F}, {F} → {E}. Find all candidate keys.
NoteWorking
Candidate key(s): {B, C}.
{B, C}⁺: B→F adds F; F→E adds E; {B,C}→A adds A; {A,E}→D adds D — covers everything, and no proper subset of {B,C} does (neither B nor C alone determines the other).
Question C.2
R [A, B, C, D, E, F] with {A} → {B, C}, {C, D} → {E}, {A, C} → {E}, {B} → {D}, {E} → {A, B}. Find all candidate keys.
NoteWorking
Candidate keys: {B, C, F}, {C, D, F}, {A, F}, {E, F}.
F never appears on any FD’s right-hand side, so it must be part of every key. Among {A, B, C, D, E}, the FDs form a tightly-coupled cluster (A, B/D, C/E combinations all inter-derive each other) — A, E, {B,C}, and {C,D} are each independently sufficient to derive the rest of that cluster, giving four minimal keys once F is added to each.
Question C.3
R [A, B, C, D] with {A, B} → {C, D}, {C} → {A, B, D}, {D} → {C}. Find all candidate keys.
NoteWorking
Candidate keys: {C}, {A, B}, {D}.
{C}⁺ = {A,B,C,D} directly. {D}⁺: D→C, then C→{A,B,D} — covers everything. {A,B}⁺ = {A,B,C,D} directly. All three are minimal.
Question C.4
R [A, B, C, D, E, F, G, H, I, J] with {A, B} → {C}, {A} → {D, E}, {B} → {F}, {F} → {G, H}, {D} → {I, J}. Find all candidate keys.
NoteWorking
Candidate key: {A, B}.
{A, B}⁺: A→{D,E} adds D,E; B→F adds F; {A,B}→C adds C; F→{G,H} adds G,H; D→{I,J} adds I,J — every attribute, and neither A nor B alone reaches the other’s attributes.
Section D — Highest normal form
Question D.1
R [A, B, C, D, E, F] with {A, E} → {D}, {B, C} → {A}, {B} → {F}, {F} → {E}. Identify the highest normal form and justify.
NoteWorking
Only candidate key (CK) is {B, C} (from Question C.1). Highest normal form is 1NF, because of the partial dependency {B} → {F} — B is a proper subset of the candidate key {B, C}, and F is a non-prime attribute, violating 2NF.
Question D.2
R [A, B, C, D, E] with {A} → {B, C, D, E}, {B} → {A, C, D, E}. Identify the highest normal form and justify.
NoteWorking
CKs are {A} and {B}. Highest normal form is BCNF, because the LHS of every FD (A and B) is itself a superkey.
Question D.3
R [A, B, C, D, E, F, G] with {A} → {B, C, D}, {D} → {A}, {C} → {F, G}. Identify the highest normal form and justify.
NoteWorking
CKs are {A, E} and {D, E}. Highest normal form is 1NF. Decomposing {A} → {B, C, D} into {A}→{B}, {A}→{C}, {A}→{D}: {A} → {B} and {A} → {C} are both partial dependencies, since A is a proper subset of the candidate key {A, E} and B/C are non-prime attributes. ({D} → {A} is not a partial dependency, since A is a prime attribute — appearing in candidate key {A, E}.)
Question D.4
R [A, B, C, D, E] with {A, B} → {C, E}, {D} → {A}, {A} → {D}. Identify the highest normal form and justify.
NoteWorking
CKs are {A, B} and {D, B}. Highest normal form is 3NF — there are no partial or transitive dependencies. It’s not BCNF, though: the LHS of {A} → {D} (just A) is not a superkey, violating BCNF — but this is not a partial dependency, since D is a prime attribute (appears in candidate key {D, B}). The same reasoning applies symmetrically to {D} → {A}.
Case Study 8: Dirt Road Driving (Payroll System — Anomalies and FDs)
Practice for 2026-04-27-database-design-guidelines-and-functional-dependencies. Dirt Road Driving’s Director of Innovation, Peter Thompson, has asked for student help auditing their payroll/finance system’s database schema — some staff feel the current design is inefficient.
The payroll schema
Note: this is Peter’s first schema email — it’s missing FDs for EmployeeHistory, TripExpenseAllocations and TravelInsuranceHistory (he sends a corrected, more complete version later, used in week11-tutorial-case-study-9-payroll-system). For Section 2 below, those FDs must be identified from the sample data instead.
Employee [id, firstName, lastName, role]
Project [name, description, funding, projectLeader]
Project.projectLeader references Employee.id
TimeLog [employeeID, projectName, date, hoursWorked, approved]
TimeLog.employeeID references Employee.id
TimeLog.projectName references Project.name
AssetUse [employeeID, assetID, timestamp, useDuration, assetType, purchaseDate, insuranceValue]
assetID → assetType, purchaseDate
assetType → insuranceValue
AssetUse.employeeID references Employee.id
Department [code, name, manager, buildingID, buildingName, buildingLocation, floor]
buildingID → buildingLocation, buildingName
buildingName → buildingLocation, buildingID
Department.manager references Employee.id
EmployeeHistory [employeeID, departmentCode, dateStarted, seniorityLevel, baseSalary, securityLevel]
EmployeeHistory.employeeID references Employee.id
EmployeeHistory.departmentCode references Department.code
TripExpenseAllocations [tripName, expenseType, quantity, organiser, startDate, endDate, location, allowance, restrictions, description]
TripExpenseAllocations.organiser references Employee.id
TravelInsuranceHistory [tripName, approved, insuranceLevel, description, maxCoverage, advisedPrecautions]
TravelInsuranceHistory.tripName references TripExpenseAllocations.tripNameSample data (relevant excerpts):
AssetUse
employeeID assetID timestamp useDuration assetType purchaseDate insuranceValue
2014 1200 20-12-2019 11:04:14 00:15:02 Vehicle 16-02-2019 20,000
2014 7900 24-12-2019 18:54:01 01:12:52 Vehicle 23-10-2019 20,000
2020 7901 01-01-2020 13:07:59 05:00:09 Power Tools 05-05-2019 1,000
2014 1200 01-01-2020 14:47:08 02:45:36 Vehicle 16-02-2019 20,000
Department
code name manager buildingID buildingName buildingLocation floor
MAK Marketing 2020 0302 Dumpling Building (-27.4907639, 152.9955379) 8
FIN Finance 2021 0302 Dumpling Building (-27.4907639, 152.9955379) 7
IT Computering 2023 2023 Hotpot Building (-27.4856679, 152.9898608) 2
EmployeeHistory
employeeID departmentCode dateStarted seniorityLevel baseSalary securityLevel
2020 FIN 13-09-2019 Junior 70,000 Limited
2023 IT 23-09-2020 Junior 70,000 Limited
1919 IT 05-11-2019 Junior 70,000 Limited
2014 FIN 07-11-2019 Junior 70,000 Limited
2019 IT 07-11-2019 Junior 70,000 Limited
2020 MAK 09-11-2019 Executive 80,000 Full Access
2021 FIN 18-11-2019 Senior 70,000 Full Access
2022 IT 19-11-2019 Junior 70,000 Limited
2023 IT 07-01-2020 Executive 80,000 Full Access
TripExpenseAllocations
tripName expenseType organiser startDate endDate location allowance restrictions
UQ Partnership Food 2023 02-02-2020 03-02-2020 Brisbane 200 No alcohol over $70
UQ Partnership Hotel 2023 02-02-2020 03-02-2020 Brisbane 500 Food service not included
UQ Partnership Transport 2023 02-02-2020 03-02-2020 Brisbane 100 Cannot use Uber or DiDi
Ride-share Marketing Conf. Hotel 2020 21-03-2020 28-03-2020 Sydney 500 Food service not included
Ride-share Marketing Conf. Transport 2020 21-03-2020 28-03-2020 Sydney 100 Cannot use Uber or DiDi
Investor Meeting Food 2021 27-03-2020 28-03-2020 Cairns 200 No alcohol over $70
TravelInsuranceHistory
tripName insuranceLevel description maxCoverage
UQ Partnership 4 Local travel without unsafe circumstances 1,000,000
Ride-share Marketing Conf. 1 Any travel with unsafe/govt-conflicting circs. 10,000
Investor Meeting 1 Any travel with unsafe/govt-conflicting circs. 10,000Section A — Anomalies
Provide and explain one example each of a modification, deletion, and insertion anomaly for the AssetUse and Department tables. (≤100 words each — the exercise must show practically* how each anomaly applies, not just restate the textbook definition.)*
AssetUse
NoteWorking
Modification anomaly: updating the tuple <2014, 1200, 20-12-2019 11:04:14, 00:15:02, "Vehicle", 16-02-2019, 20,000> to <2014, 1200, 20-12-2019 11:04:14, 00:15:02, "Vehicle", 18-03-2019, 20,000> — since assetID → purchaseDate, and assetID = 1200 also appears in another row (with timestamp = 01-01-2020 14:47:08), that other row’s purchaseDate would also need updating to 18-03-2019, otherwise the table becomes inconsistent about when asset 1200 was purchased.
Deletion anomaly: deleting <2020, 7901, 01-01-2020 13:07:59, 05:00:09, "Power Tools", 05-05-2019, 1,000> — this is the only row recording asset 7901, so deleting it loses that asset’s assetType and purchaseDate entirely, even though those facts are logically about the asset, not about this particular use-event.
Insertion anomaly: to record a new asset that hasn’t been used yet, we’d need to insert <null, 2200, null, null, "Power Tools", 29-11-2019, 1,000> — but employeeID and timestamp form the primary key, so a null primary key violates entity integrity. A new asset can’t be entered until someone has used it.
Department
NoteWorking
Modification anomaly: updating <"FIN", "Finance", 2021, 0302, "Dumpling Building", (-27.4907639, 152.9955379), 7>’s buildingLocation alone — since buildingID → buildingLocation, the other row with buildingID = 0302 (“MAK”) would also need updating, otherwise the two rows disagree about where building 0302 is.
Deletion anomaly: deleting <"IT", "Computering", 2023, 2023, "Hotpot Building", (-27.4856679, 152.9898608), 2> — this is the only row referencing buildingID = 2023, so deleting it loses the buildingName and buildingLocation facts for that building.
Insertion anomaly: recording a new building (buildingID = 2013, “Peking Duck Building”) that isn’t yet occupied by any department requires inserting <null, null, null, 2013, "Peking Duck Building", (-27.566544, 152.917845), null> — a null primary key (code), which violates entity integrity.
Section 2 — Functional dependencies and highest normal form
Based on the sample data above, identify all non-trivial functional dependencies (beyond the given primary keys) for the tables below, and their highest normal form. As the primary keys are given in the schema, ignore FDs for the primary key itself.
EmployeeHistory
NoteWorking
FD: seniorityLevel → baseSalary, securityLevel
Every row sharing a seniorityLevel agrees on baseSalary and securityLevel — all six Junior rows have {70,000, Limited}; both Executive rows have {80,000, Full Access}.
Highest normal form: 2NF. This FD is a transitive dependency — its left-hand side (seniorityLevel) is not a superkey, and its right-hand side contains non-prime attributes, violating 3NF. (The LHS is also not a subset of the candidate key {employeeID, departmentCode}, so it doesn’t violate 2NF.)
TripExpenseAllocations
NoteWorking
FDs: tripName → startDate, endDate, location, organiser; expenseType → allowance, restrictions
All three “UQ Partnership” rows agree on organiser/dates/location; expenseType = 'Food' (rows for “UQ Partnership” and “Investor Meeting”) always has allowance = 200 and the same restriction text.
Highest normal form: 1NF. The first FD is a partial dependency — its left-hand side (tripName) is a prime attribute (part of the candidate key {tripName, expenseType}) but not itself a superkey, and its right-hand side contains non-prime attributes, violating 2NF.
TravelInsuranceHistory
NoteWorking
FD: insuranceLevel → description, maxCoverage
Both rows with insuranceLevel = 1 (“Ride-share Marketing Conference” and “Investor Meeting”) share the same description and maxCoverage = 10,000.
Highest normal form: 1NF. Same shape of violation as above — the left-hand side (insuranceLevel) is a prime attribute but not a superkey, and the right-hand side contains non-prime attributes, violating 2NF.
Week 11
Normalisation and Relational Database Schema Design
Module 4, part 2. Continues 2026-04-27-database-design-guidelines-and-functional-dependencies — now that we can identify FDs and keys, we use them to formally measure and improve schema quality via normalisation.
Outline
- Normalisation: 1NF, 2NF, 3NF, BCNF
- Relational database schema design: BCNF decomposition, minimal cover, 3NF synthesis
Key concepts recap
- Superkey — a set of attributes such that no two tuples share the same values for them (its closure covers every attribute in
R). - (Candidate) key — a minimal superkey (removing any attribute breaks the superkey property). Minimal ≠ shortest; a relation can have several candidate keys, and every superkey contains at least one candidate key.
- Primary key — one candidate key, chosen as the key (only one per relation).
- Prime attribute — an attribute that belongs to any candidate key (not necessarily the primary key).
- Non-prime attribute — belongs to no candidate key.
Approaching normality
Functional dependencies reveal redundancy: in R [A, B, C] with no FDs, there’s no redundancy; but given A → B, several tuples can share the same A value, and whenever they do, they’re forced to repeat the same B value too — that repetition is the redundancy normalisation identifies and removes.
Normalisation is the process of taking a relational schema through a series of tests, using FDs and (candidate/primary) keys, to certify which normal form it satisfies. Schemas that fail a test are decomposed into smaller relations with better properties.
Normal forms overview
| NF | Outcome | Test (for every non-trivial X → A in F⁺) |
|---|---|---|
| 1NF | Identifies non-atomic values | Relation has no multivalued attributes or nested relations |
| 2NF | Identifies partial dependencies (removes some anomalies) | X is not a proper subset of a candidate key, or A is a prime attribute |
| 3NF | Identifies partial + transitive dependencies (removes most anomalies) | X is a superkey, or A is a prime attribute |
| BCNF | Identifies all anomalies (at the cost of not preserving all FDs) | X is a superkey |
BCNF ⊂ 3NF ⊂ 2NF ⊂ 1NF — each normal form is strictly more restrictive than the last.
First Normal Form (1NF)
A relation schema is in 1NF if every attribute’s domain contains only atomic (simple, indivisible) values — no set of values, no tuple of values (nested attributes), and no combination of both.
Non-1NF example — an items column holding a comma-separated list, or a nested name = {firstName, familyName} sub-structure, both violate 1NF. Normalizing to 1NF either:
- repeats the non-nested key columns per value (e.g. one row per
(customerName, orderNum, item)combination) — introduces redundancy; or - flattens into fixed columns (
item1,item2, …) — introduces a lack of flexibility (a hard cap on how many items one order can have, andnulls for orders with fewer items).
Neither is fully satisfactory — this motivates 2NF/3NF/BCNF, which address how to further decompose an already-1NF relation.
Full and partial functional dependencies
X → Yis a full functional dependency if removing any attribute fromXbreaks the dependency (no proper subset ofXdeterminesY).X → Yis a partial dependency if some attribute can be removed fromXand the FD still holds.
Example — Address [houseNum, street, postcode, state, value], F = {{houseNum, street, postcode} → {state, value}, postcode → state}:
{houseNum, street, postcode} → valueis a full dependency (no subset of the LHS determinesvalue).{houseNum, street, postcode} → stateis a partial dependency, sincepostcode → statealone already suffices.
Second Normal Form (2NF)
A relation schema R is in 2NF if every non-prime attribute is fully functionally dependent on the primary key — informally, no partial dependency.
In the Address example: the (only) key is {houseNum, street, postcode}; state is non-prime and only partially dependent on the key (via postcode → state) — this violates 2NF, so Address is not in 2NF.
Fixing it: decompose into Address [houseNum, street, postcode, value] and Postcodes [postcode, state] (Address.postcode → Postcodes.postcode). 2NF identifies anomalies caused by partial dependencies — but not anomalies caused by transitive dependencies, covered next.
2NF doesn’t fix everything: Employee [ID, name, level, salary] with level → salary doesn’t violate 2NF at all (level isn’t even a proper subset of the key {ID} — it’s a whole non-key attribute), so Employee is in 2NF — yet it still has all the same anomalies from before (updating one developer’s salary is still inconsistent, deleting the only “Administration” employee still loses that level’s salary, etc.). 2NF alone isn’t enough.
Transitive dependency
X → Y in R is a transitive dependency if some attribute set Z exists such that Z is neither a candidate key nor a subset of one, and both X → Z and Z → Y hold.
Example — Employee [ID, name, level, salary], F = {level → salary}: consider ID → salary. level is neither a candidate key nor a subset of one; ID → level and level → salary both hold; therefore ID → salary is a transitive dependency (salary depends on ID only through the intermediate level).
Third Normal Form (3NF)
A relation schema R with FD set F is in 3NF iff, for every non-trivial FD X → A in F⁺: X is a superkey, or A is a prime attribute. Equivalently — for any non-trivial X → A where A is non-prime, X must be a superkey.
In the Employee example: level → salary — level is not a superkey, and salary is not a prime attribute — violates 3NF. Fixing it: decompose into StaffAppointment [ID, name, level] and StaffIncome [level, salary]. Most 3NF relations are anomaly-free — but not all of them, as the next example shows.
3NF still isn’t always enough — Teach [studentID, courseID, lecturer], F = {{studentID, courseID} → lecturer, lecturer → courseID} (keys: {studentID, courseID}, {studentID, lecturer}). Teach is in 3NF (lecturer → courseID’s RHS, courseID, is a prime attribute — so it doesn’t violate 3NF even though lecturer isn’t a superkey). Yet it still has anomalies:
- Deletion anomaly: deleting the only row for a given
(studentID, courseID)pair can delete the only record of which lecturer teaches that course. - Insertion anomaly: can’t record which lecturer teaches a course that currently has no enrolled students.
Boyce-Codd Normal Form (BCNF)
A relation schema R with FD set F is in BCNF iff, for every non-trivial FD X → A in F⁺: X is a superkey. Informally: whenever a set of attributes determines another attribute, it must determine all attributes of R.
In Teach: lecturer → courseID — lecturer is not a superkey — violates BCNF, so Teach is not in BCNF (even though it is in 3NF).
The catch: BCNF can lose dependencies
Decomposing Teach to fix the BCNF violation: split into [lecturer, courseID] (from lecturer → courseID) and [studentID, lecturer]. Each piece individually satisfies its own local FDs and is in BCNF. But now rejoin them:
lecturer courseID studentID lecturer
John INFS1200 1234 John
Jane INFS1200 1234 Jane
↓ join ↓
studentID courseID lecturer
1234 INFS1200 John
1234 INFS1200 JaneThe rejoined table violates the original FD {studentID, courseID} → lecturer (both rows share {1234, INFS1200} but disagree on lecturer) — even though neither decomposed piece violated any FD on its own. Decomposing into BCNF can fail to preserve all the original FDs. A dependency-preserving decomposition is one where, if R is split into R1, ..., Rn with FD sets F1, ..., Fn (each Fi containing the FDs of F whose attributes fall entirely within Ri), then (F1 ∪ ... ∪ Fn)⁺ = F⁺ — i.e. no FD information is lost by the split.
BCNF vs 3NF trade-off:
| BCNF | 3NF | |
|---|---|---|
| Removes all anomalies | ✅ | ❌ |
| Preserves all FDs | ❌ | ✅ |
Most organisations aim for one or the other depending on which guarantee matters more for their use case.
Question 8 — Partial vs. transitive dependency
What’s the difference between partial and transitive dependency?
NoteSolution
Partial dependency: an attribute depends on only a subpart of the primary key. Normalizing to 2NF solves this. Transitive dependency: a non-prime attribute depends on other non-prime attributes (rather than directly on the key). Normalizing to 3NF solves this.
Question 9 — Validating normal form
Given R [A, B, C, D, E, F] with {A, B} → {C, D, E}, C → F, E → {A, B} — what is the highest normal form?
NoteSolution
2NF. Keys: {A, B}, {E}. No partial dependencies exist (both {A,B} → {C,D,E} and E → {A,B} have a whole key as LHS), so 2NF holds. But C → F: C is not a superkey, and F is non-prime — violates both 3NF and BCNF.
Question 10 — Validating normal form
Given R [A, B, C, D] with {A, B} → {C, D}, {C, D} → A, D → B — what is the highest normal form?
NoteSolution
3NF. Keys: {A, B}, {C, D}, {A, D} — every attribute is prime. Since every attribute is prime, 2NF and 3NF automatically hold (every FD’s RHS is a prime attribute). But D → B: D is not a superkey — violates BCNF.
Question 11 — Validating normal form
Given R [A, B, C, D, E] with B → {C, D}, A → E — what is the highest normal form?
NoteSolution
1NF. Key: {A, B}. Both A and B are proper subsets of the key — A → E and B → {C, D} are both partial dependencies, violating 2NF.
Question 12 — Validating normal form
Given R [A, B, C, D, E] with A → {B, C, D, E}, E → A — what is the highest normal form?
NoteSolution
BCNF. Keys: {A}, {E}. The LHS of every FD (A and E) is itself a superkey — satisfies BCNF, the strictest test.
Question 13 — BCNF and 3NF
Given R [A, B, C, D] with {A, C, D} → B, {A, C} → D, D → C, {A, C} → B — which is true?
A. Neither BCNF nor 3NF B. BCNF but not 3NF C. 3NF but not BCNF D. Both BCNF and 3NF
NoteSolution
C. Keys: {A, C}, {A, D}. D → C: D is not a superkey, so BCNF is violated. But C is a prime attribute (appears in key {A, C}), so this same FD does not violate 3NF — R is in 3NF but not BCNF.
Relational database schema design
Two complementary algorithms turn a universal relation (all attributes lumped together, plus a set of FDs) into a well-designed multi-relation schema:
- Decomposition (top-down): break the universal relation apart to reach lossless-join, anomaly-free BCNF schemas.
- Synthesis (bottom-up): build up from individual attributes to reach lossless-join, dependency-preserving 3NF schemas.
flowchart LR
U["Universal Relation + FDs"] -->|decomposition| RDB[("Relational DB schema")]
E["EER Diagram (from UoD)"] -->|mapping| RDB
A["All attributes + FDs"] -->|synthesis| RDBDetermining which FDs apply to a decomposed relation
For a decomposed relation S and an FD X → Y from the original F: X → Y holds in S if X ∪ Y ⊆ S’s attributes and Y ⊆ X⁺ (computed using all of F, even attributes not in S).
Question 14 — Determining which FDs apply
Given R [A, B, C, D, E] with {A,B}→C, {B,C}→D, {C,D}→E, {D,E}→A, {A,E}→B — which FDs hold in S [A, B, C, D]?
A. A → B B. {A, B} → E C. {A, E} → B D. {B, C, D} → A E. None of the above
NoteSolution
D. {B, C, D}⁺ (computed against the full F, using E as an intermediate even though it’s not in S): {B,C}→D gives nothing new; {C,D}→E adds E → {B,C,D,E}; {D,E}→A adds A → {A,B,C,D,E} — covers everything, and A ∈ S, so {B,C,D} → A holds in S. A fails (A⁺ = {A} alone — doesn’t even reach B). B and C both fail because their RHS, E, isn’t even an attribute of S — an FD “holding in S” requires both sides to be within S’s attributes.
Minimal cover
To decompose into 3NF (synthesis) — or just to simplify reasoning about BCNF — we first reduce F to a minimal cover G: an equivalent, “as small as possible” set of FDs. G is a minimal cover for F iff:
F⁺ = G⁺(equivalent implied FDs);- every FD in
Ghas a single attribute on its RHS; - deleting any FD in
G, or any attribute from any FD’s LHS, changesG⁺(i.e. every FD, and every LHS attribute, is necessary).
Finding a minimal cover — 3 steps
- RHS simplification — split every FD so its RHS has exactly one attribute (
X → {Y, Z}becomesX → YandX → Z). - LHS simplification — for each FD
X → AwhereXhas multiple attributes including someB: ifX⁺ = (X - {B})⁺(i.e.Bis redundant in the LHS), replace it with(X - {B}) → A. - FD set simplification — delete any FD
X → AifX⁺(computed without that FD) still includesA— i.e. the FD is implied by the rest ofFand can be dropped.
Worked example — R [A,B,C,D,E,F,G,H], F = {A → B, {A,B,C,D} → E, {E,F} → G, {E,F} → H, {A,C,D,F} → {E,G}}:
| Step 1: RHS split | Step 2: LHS simplify | Step 3: delete redundant |
|---|---|---|
A→B |
A→B |
A→B |
{A,B,C,D}→E |
{A,C,D}→E (B redundant, since A→B) |
{A,C,D}→E |
{E,F}→G |
{E,F}→G |
{E,F}→G |
{E,F}→H |
{E,F}→H |
{E,F}→H |
{A,C,D,F}→E |
{A,C,D,F}→E |
(dropped — {A,C,D,F}⁺ already includes E without this FD) |
{A,C,D,F}→G |
{A,C,D,F}→G |
(dropped — same reason) |
Minimal cover: {A → B, {A,C,D} → E, {E,F} → G, {E,F} → H} (often written with the last two combined as {E,F} → {G,H}).
Question 15 — Minimal cover
Given R [A, B, C, D, E, F] with {D, E, F} → C, {A, B} → {D, C}, D → F — which is a minimal cover?
A. {{D,E,F}→C, {A,B}→{D,C}, D→F} B. {{D,E,F}→C, {A,B}→D, D→F} C. {{D,E}→C, {A,B}→D, {A,B}→C, D→F} D. {{D,E}→C, {A,B}→{C,D}}
NoteSolution
C. Step 1 (RHS split): {D,E,F}→C, {A,B}→D, {A,B}→C, D→F. Step 2 (LHS simplify): {D,E,F}→C simplifies to {D,E}→C, since D → F already makes F redundant in that LHS ({D,E}⁺ already includes F via D→F, so {D,E,F}⁺ = {D,E}⁺). Step 3: nothing more to remove — all four remaining FDs are necessary. A keeps the redundant F in the first FD’s LHS. B drops the necessary {A,B}→C FD entirely. D drops the necessary D→F FD.
3NF synthesis algorithm
S := ∅;
Compute a minimal cover G of F;
Combine all FDs in G with the same LHS into one;
For each X → Y in G:
if no relation in S contains X ∪ Y:
add a relation with schema X ∪ Y to S;
if any candidate key is missing from the relations:
add a relation containing all prime attributes;
Eliminate redundant relations (one whose attributes are a
subset of another relation already in S).Example — R [A, B, C, D, E], F = {{A,B}→C, C→D} (already minimal); key: {A, B, E}. Synthesis: R1 [A,B,C] (from {A,B}→C), R2 [C,D] (from C→D); the key {A,B,E} isn’t contained in either, so add R3 [A,B,E]. None of R1/R2/R3 is a subset of another — final answer: R1 [A,B,C], R2 [C,D], R3 [A,B,E].
Question 16 — 3NF synthesis
Given the minimal cover F = {{A,C}→E, {B,D}→A, A→B, E→{C,F}} for R [A, B, C, D, E, F] — which is a correct 3NF synthesis?
A. R1[A,C,E], R2[D,B,A], R3[A,B], R4[E,C,F] B. R1[A,C,E], R2[A,B,D], R3[A,B], R4[E,C,F], R5[A,C,D] C. R1[A,C,E], R2[B,D,A], R3[E,C,F], R4[A,C,D] D. R1[E,C,F], R5[A,B,C,D,E]
NoteSolution
D. Candidate keys are {A,C,D}, {A,D,E}, {B,C,D}, {B,D,E} — note F never appears in any key. Synthesising one relation per FD gives [A,C,E] ({A,C}→E), [A,B,D] ({B,D}→A), [A,B] (A→B), [E,C,F] (E→{C,F}). [A,B] is a subset of [A,B,D] — redundant, drop it. None of the remaining three relations contains a full candidate key (all four keys include D, but neither [A,C,E] nor [E,C,F] has D, and [A,B,D] is missing C/E), so add R5 with all prime attributes: {A, B, C, D, E} (the union of all candidate keys). Now [A,C,E] and [A,B,D] are both subsets of R5 [A,B,C,D,E] — redundant, drop both. [E,C,F] is not a subset of R5 (F isn’t in it) — keep. Final: [E,C,F] and R5 [A,B,C,D,E].
BCNF decomposition algorithm
D := {R};
while (some relation Q in D is not in BCNF):
find an FD X → Y in Q that violates BCNF;
replace Q in D with Q1 [Q - Y] and Q2 [X ∪ Y];(The split point: Q1 keeps everything except the “extra” attributes Y; Q2 becomes the offending FD’s own little BCNF-satisfying table, since X is now trivially a key for it.) The algorithm terminates because every 2-attribute relation is automatically in BCNF (with 0 or 1 non-trivial FDs, the LHS is always a key). Results can vary depending on which order violating FDs are processed in — that’s fine, multiple correct decompositions can exist.
Worked example — R [A, B, C, D], F = {B → C, D → A}: keys — {B,D}⁺ = {A,B,C,D}, the only key. B → C violates BCNF (B isn’t a key) → split into R1 [A,B,D], R2 [B,C]. D → A now violates BCNF in R1 (D isn’t a key for R1) → split into R3 [B,D], R4 [A,D]. Final: R2 [B,C], R3 [B,D], R4 [A,D].
Implicit FDs matter: when checking whether a relation is in BCNF during decomposition, you must also check implied FDs, not just the explicitly given ones — e.g. given A → B and B → C, the implicit A → C might be the one that actually violates BCNF in a sub-relation, even though it was never written down explicitly.
Question 17 — BCNF decomposition
Given R [A, B, C, D, E] with {A,D}→B, C→{D,E}, A→E — which is a correct BCNF decomposition tree?
NoteSolution
The correct order is: apply {A,D} → B first (splitting off R1 [A,B,D], leaving R2 [A,C,D,E]), then apply C → {D,E} to R2 (splitting it into R3 [C,D,E] and R4 [A,C]). Final: R1 [A,B,D], R3 [C,D,E], R4 [A,C].
Common mistakes to watch for: writing R3 as [C,E] instead of the full [C,D,E] (dropping an attribute of the violating FD’s RHS); writing the intermediate relation as [A,B,C,E] instead of the correct [A,C,D,E] (forgetting A → E only removes B, not D, from the first split); or decomposing R2 further using A → E when A is already a key for R2 at that point (no violation left to fix).
Question 18 — BCNF decomposition (with a lossy-join check)
Given R [A, B, C, D] with A → B, C → D, {A,D} → C, {B,C} → A — which is a lossless-join BCNF decomposition?
A. {{A,B}, {A,C}, {B,D}} B. {{A,B}, {A,C}, {C,D}} C. {{A,B}, {A,C}, {B,C,D}} D. All of the above E. None of the above
NoteSolution
B. Keys: {A,D}, {A,C}, {B,C} (all three give closure {A,B,C,D}). A → B violates BCNF → split into R1 [A,C,D], R2 [A,B]. C → D violates BCNF in R1 → split into R3 [A,C], R4 [C,D]. Final: {{A,B}, {A,C}, {C,D}}.
Why not A ({{A,B}, {A,C}, {B,D}})? Concretely: take R rows (1,2,5,6), (1,2,3,7), (8,2,9,4). Decomposing per option A and rejoining produces two extra rows not in the original R (e.g. (1,2,3,4) appears in the rejoined result despite never being an actual tuple of R) — this is a lossy join, since {B,D} isn’t actually a valid join key here (B=2 recurs across all three original rows with different D values, so joining on B alone reintroduces spurious combinations).
Denormalisation
Since anomalies come from redundancy, it’s tempting to decompose as aggressively as possible — but heavily decomposed schemas need more JOINs to answer queries. Denormalisation is the deliberate, controlled process of relaxing a normal form to improve query performance: fewer joins (faster queries), fewer foreign keys (less storage/maintenance overhead) — useful for analytical workloads or when specific frequent queries need pre-joined results. It must be a controlled, deliberate trade-off, not an accident of poor initial design.
Summary
Three skills: testing a relation schema against 1NF/2NF/3NF/BCNF given a set of FDs, decomposing a universal relation into lossless-join anomaly-free BCNF relations (top-down), and computing a minimal cover to synthesise a lossless-join dependency-preserving 3NF schema (bottom-up). This completes Module 4. Next module: Database Security. See week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis and week11-tutorial-case-study-9-payroll-system for practice.
Reading: Elmasri & Navathe Chapters 14 (up to 14.6) and 15 (up to 15.5).
Applied Class 10: Normalisation, BCNF Decomposition and 3NF Synthesis
Practice for 2026-05-04-normalisation-and-relational-database-schema-design. Note: “consider the FDs in the order provided” is a default guideline — only FDs that actually violate BCNF get split on; other correct decompositions can exist depending on split order.
Two things to have at hand before starting Section A:
- Which FDs still apply to a fragment. An FD
X → Yholds in a decomposed relationSwhenScontains all ofX ∪ YandY ⊆ X⁺— whereX⁺is computed against the whole originalF, including attributes that aren’t inSat all. The second half is what makes implicit FDs surface mid-algorithm, as in Question A.3. - Which child gets which attributes. Splitting
Qon a violatingX → YgivesQ1 [Q − Y]andQ2 [X ∪ Y].Xis a key ofQ2, which is exactly what makes the split lossless. See [decomposition].
Section A — BCNF decomposition (top-down)
Question A.1
R [A, B, C, D, E] with {A} → {C}, {A, B} → {D, E}. Decompose into BCNF.
NoteWorking
{A,B}⁺ = {A,B,C,D,E} — {A, B} is the only candidate key.
{A} → {C} violates BCNF (A isn’t a superkey) → split into R1 [A, C] and R2 [A, B, D, E]. Within R2, {A,B} is a key (it already was for the whole relation), so {A,B} → {D,E} doesn’t violate BCNF there — no further splitting needed.
Final answer: R1 [A, C] ({A}→{C}), R2 [A, B, D, E] ({A,B}→{D,E}).
Question A.2
R [A, B, C, D, E] with {A} → {B}, {C} → {D, E}. Decompose into BCNF.
NoteWorking
{A,C}⁺ = {A,B,C,D,E} — {A, C} is the only candidate key.
{A} → {B} violates BCNF (A alone isn’t a superkey) → split into R1 [A, B] and R2 [A, C, D, E]. In R2, {C} → {D, E} violates BCNF (C alone isn’t a superkey for R2) → split into R3 [C, D, E] and R4 [A, C].
Final answer: R1 [A, B], R3 [C, D, E], R4 [A, C] (no non-trivial FD).
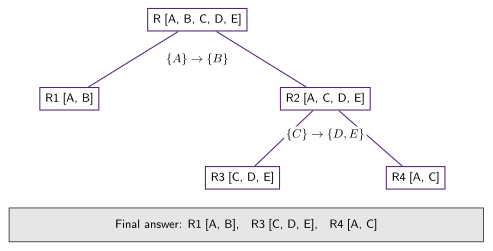
Figure 23: The decomposition tree for A.2 — and, as it turns out, for A.4 as well. Each split is labelled with the FD that violated BCNF; the leaves are the answer. Each split puts X ∪ Y on the left and Q − Y on the right. Nothing hangs on the order — it is the set of leaves that is the decomposition.
Question A.3
R [A, B, C, D, E, F] with {A} → {B, C}, {C} → {D, E}, {E} → {F}. Decompose into BCNF.
NoteWorking
{A}⁺ = {A,B,C,D,E,F} — A is the only candidate key. A → {B, C} does not violate BCNF here, since A is the key — so we skip it and look for an FD whose LHS genuinely isn’t a superkey.
{C} → {D, E} violates BCNF (C isn’t a superkey) → split into R1 [C, D, E] and R2 [A, B, C, F]. Within R2, the explicit FDs don’t obviously violate BCNF — but the implicit FD C → F (derivable transitively via C → E and E → F) does (C isn’t a superkey for R2 either) → split R2 into R3 [C, F] and R4 [A, B, C].
Final answer: R1 [C, D, E] ({C}→{D,E}), R3 [C, F] ({C}→{F}, implicit), R4 [A, B, C] ({A}→{B,C}).
Note: {E} → {F} is lost by this decomposition — E and F never end up together in any final relation, so that FD can no longer be checked directly against the decomposed schema.
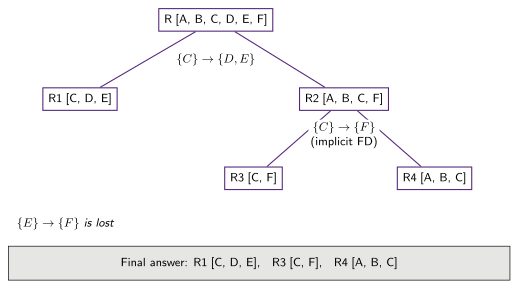
Figure 24: A.3’s tree. The second split is driven by an FD that was never written down: C → F follows from C → E and E → F, and C is not a superkey of R2, so R2 is not in BCNF even though none of the three given FDs says so. Miss it and you stop with R2 [A, B, C, F] wrongly declared finished. Each split puts X ∪ Y on the left.
Question A.4
R [A, B, C, D, E] with {A} → {B}, {C} → {D, E}, {A, D, E} → {C}, {B, C} → {A}. Decompose into BCNF.
NoteWorking
{A, C}, {A, D, E} and {B, C} are all candidate keys.
{A} → {B} violates BCNF → split into R1 [A, B] and R2 [A, C, D, E]. Within R2, {C} → {D, E} violates BCNF → split into R3 [C, D, E] and R4 [A, C].
Final answer: R1 [A, B], R3 [C, D, E], R4 [A, C] — the exact same result as Question A.2, splitting on the same two FDs in the same order, so Figure 23 is A.4’s tree unchanged, even though A.4 started with twice as many FDs. {A, D, E} → {C} and {B, C} → {A} are both lost in this decomposition (their attributes never all end up together in one final relation) — this is worth noticing: extra FDs don’t necessarily survive decomposition, and a differently-ordered decomposition might have preserved different (but not necessarily more) FDs.
Section B — 3NF synthesis (bottom-up)
Question B.1
R [A, B, C, D, E, F, G, H] with {A, B} → {C}, {C, D} → {E}, {D} → {F, G}. Synthesise into 3NF.
NoteWorking
{A,B,D,H}⁺ = {A,B,C,D,E,F,G,H} — the only candidate key. Prime attributes: A, B, D, H. (H appears on no side of any FD, so it must be in every key; dropping any of A, B or D loses C or E.)
This FD set is already a minimal cover. Step 1 splits {D}→{F,G} into {D}→F and {D}→G; step 2 finds nothing to drop from either compound LHS ({A}⁺ = {A} and {B}⁺ = {B} both miss C; {C}⁺ = {C} and {D}⁺ = {D,F,G} both miss E); step 3 finds no FD implied by the others.
Synthesis: R1 [A, B, C] ({A,B}→C), R2 [C, D, E] ({C,D}→E), R3 [D, F, G] ({D}→{F,G}), and — since the candidate key {A,B,D,H} isn’t contained in any of these — R4 [A, B, D, H] (no non-trivial FD). All four are in 3NF.
Question B.2
R [A, B, C, D, E, F] with {A, B} → {C}, {C} → {D, E}. Synthesise into 3NF.
NoteWorking
{A,B,F}⁺ = {A,B,C,D,E,F} — the only candidate key. Prime attributes: A, B, F. Already a minimal cover.
Synthesis: R1 [A, B, C] ({A,B}→C), R2 [C, D, E] ({C}→{D,E}), R3 [A, B, F] (no non-trivial FD, added since the key isn’t otherwise present). All three are in 3NF.
Question B.3
R [A, B, C, D, E] with {A} → {D, E}, {D} → {A}, {B} → {C}, {B, C} → {A, D}, {E, A} → {D}. Synthesise into 3NF.
NoteWorking
{B}⁺ = {A,B,C,D,E} — {B} is the only candidate key. Prime attributes: B.
Minimal cover, step by step:
| Step 1: RHS split | Step 2: LHS simplify | Step 3: delete redundant |
|---|---|---|
{A} → D |
{A} → D |
{A} → D |
{A} → E |
{A} → E |
{A} → E |
{B,C} → A |
{B} → A — C redundant, since B → C |
{B} → A |
{B,C} → D |
{B} → D — same reason |
dropped — {B} → A then {A} → D |
{D} → A |
{D} → A |
{D} → A |
{E,A} → D |
{A} → D — E redundant, A alone reaches D |
dropped — now a duplicate of {A} → D |
{B} → C |
{B} → C |
{B} → C |
leaving {A} → {D, E}, {B} → {A, C}, {D} → {A}.
Synthesis: one relation per FD gives [A, D, E], [A, B, C] and [A, D]; the last is a subset of the first, so it is eliminated and {D} → {A} rides along inside R1. The candidate key {B} is already present in R2, so no extra all-prime-attributes relation is needed.
R1 [A, D, E] ({A}→{D,E}, {D}→{A}), R2 [A, B, C] ({B}→{A,C}). Both are in 3NF.
Question B.4
R [A, B, C, D, E, F] with {A} → {B, C, D, E, F}, {B, C} → {A}, {D, E} → {B}, {C} → {D}. Synthesise into 3NF.
NoteWorking
{A}, {B, C} and {C, E} are all candidate keys. Prime attributes: A, B, C, E.
Minimal cover, step by step. Only step 1 and step 3 do anything: neither compound LHS can be shortened ({B}⁺ = {B} and {C}⁺ = {C,D} both miss A; {D}⁺ = {D} and {E}⁺ = {E} both miss B).
| Step 1: RHS split | Step 2: LHS simplify | Step 3: delete redundant |
|---|---|---|
{A} → B |
{A} → B |
dropped — A → D, A → E, then {D,E} → B |
{A} → C |
{A} → C |
{A} → C |
{A} → D |
{A} → D |
dropped — A → C, then {C} → D |
{A} → E |
{A} → E |
{A} → E |
{A} → F |
{A} → F |
{A} → F |
{B,C} → A |
{B,C} → A |
{B,C} → A |
{D,E} → B |
{D,E} → B |
{D,E} → B |
{C} → D |
{C} → D |
{C} → D |
leaving {A} → {C, E, F}, {B, C} → {A}, {D, E} → {B}, {C} → {D}. Neither removal is visible from a single FD — both take the closure test, and both survive in either order.
Synthesis: R1 [A, C, E, F] ({A}→{C,E,F}), R2 [B, C, A] ({B,C}→{A}), R3 [D, E, B] ({D,E}→{B}), R4 [C, D] ({C}→{D}). The candidate key {A} is already present in R1, so no extra relation is needed. All four are in 3NF.
Case Study 9: Payroll System (BCNF Decomposition and 3NF Synthesis)
Practice for 2026-05-04-normalisation-and-relational-database-schema-design. Continues week10-tutorial-case-study-8-dirt-road-driving — Peter has now resent Dirt Road Driving’s payroll schema with the full set of functional dependencies included (his earlier email accidentally omitted them).
The corrected payroll schema
Employee [id, firstName, lastName, role]
Project [name, description, funding, projectLeader]
Project.projectLeader references Employee.id
TimeLog [employeeID, projectName, date, hoursWorked, approved]
TimeLog.employeeID references Employee.id
TimeLog.projectName references Project.name
AssetUse [employeeID, assetID, timestamp, useDuration, assetType, purchaseDate, insuranceValue]
assetID → assetType, purchaseDate
assetType → insuranceValue
AssetUse.employeeID references Employee.id
Department [code, name, manager, buildingID, buildingName, buildingLocation, floor]
buildingID → buildingLocation, buildingName
buildingName → buildingLocation, buildingID
Department.manager references Employee.id
EmployeeHistory [employeeID, departmentCode, seniorityLevel, baseSalary, securityLevel]
seniorityLevel, securityLevel → baseSalary
EmployeeHistory.employeeID references Employee.id
EmployeeHistory.departmentCode references Department.code
TripExpenseAllocations [tripName, expenseType, quantity, organiser, startDate, endDate, location, allowance, restrictions, description]
tripName, expenseType → quantity, description
tripName → startDate, endDate, location, organiser
expenseType → allowance, restrictions
TripExpenseAllocations.organiser references Employee.id
TravelInsuranceHistory [tripName, approved, insuranceLevel, description, maxCoverage, advisedPrecautions]
tripName → approved, insuranceLevel, description
insuranceLevel → description, maxCoverage
TravelInsuranceHistory.tripName references TripExpenseAllocations.tripNameSection A — BCNF decomposition
Decompose (if needed) AssetUse, Department, EmployeeHistory, TripExpenseAllocations, and TravelInsuranceHistory into BCNF, clearly stating any new tables and all foreign keys.
AssetUse
NoteWorking
CK = {employeeID, assetID, timestamp}. FDs: {employeeID, assetID, timestamp} → {useDuration, assetType, purchaseDate, insuranceValue}, {assetID} → {assetType, purchaseDate}, {assetType} → {insuranceValue}, and the implicit {assetID} → {insuranceValue}. Highest NF: 1NF.
Final answer:
Asset [assetID, assetType, purchaseDate]—{assetID} → {assetType, purchaseDate}Insurance [assetID, insuranceValue]—{assetID} → {insuranceValue}, FKassetIDreferencesAsset.assetIDAssetUse [employeeID, assetID, timestamp, useDuration]— no non-trivial FD, FKassetIDreferencesAsset.assetID
Lost: {assetType} → {insuranceValue} (once decomposed, assetType and insuranceValue never appear together in one relation, so this FD can no longer be directly enforced/checked).
Department
NoteWorking
CK = {code}. FDs: {code} → {name, manager, buildingID, buildingName, location, floor}, {buildingID} → {buildingLocation, buildingName}, {buildingName} → {buildingLocation, buildingID}. Highest NF: 2NF.
Final answer:
Building [buildingID, buildingLocation, buildingName]—{buildingID} → {buildingLocation, buildingName},{buildingName} → {buildingID, buildingLocation}Department [code, name, manager, buildingID, floor]—{code} → {name, manager, buildingID, floor}, FKbuildingIDreferencesBuilding.buildingID
EmployeeHistory
NoteWorking
CK = {employeeID, departmentCode}. FDs: {employeeID, departmentCode} → {seniorityLevel, baseSalary, securityLevel}, {seniorityLevel, securityLevel} → {baseSalary}. Highest NF: 2NF.
Final answer:
Salary [seniorityLevel, securityLevel, baseSalary]—{seniorityLevel, securityLevel} → {baseSalary}EmployeeHistory [employeeID, departmentCode, seniorityLevel, securityLevel]—{employeeID, departmentCode} → {seniorityLevel, securityLevel}, FKs toEmployee.idandDepartment.code
TripExpenseAllocations
NoteWorking
CK = {tripName, expenseType}. FDs: {tripName, expenseType, quantity} → {organiser, startDate, endDate, location, allowance, restrictions, description}, {tripName, expenseType} → {quantity, description}, {tripName} → {startDate, endDate, location, organiser}, {expenseType} → {allowance, restrictions}. Highest NF: 1NF.
Final answer:
| Relation | FD |
|---|---|
Trip [tripName, startDate, endDate, location, organiser] |
{tripName} → {startDate, endDate, location, organiser} |
Expense [expenseType, allowance, restrictions] |
{expenseType} → {allowance, restrictions} |
TripExpenseAllocations [tripName, expenseType, quantity, description] |
{tripName, expenseType} → {quantity, description}, FKs to Trip.tripName and Expense.expenseType |
TravelInsuranceHistory
NoteWorking
CK = {tripName} (the schema’s stated primary key {tripName, approved, insuranceLevel} is not minimal — tripName alone is already a key). FDs: {tripName, approved, insuranceLevel} → {description, maxCoverage, advisedPrecautions}, {tripName} → {approved, insuranceLevel, description}, {insuranceLevel} → {description, maxCoverage}. Highest NF: 2NF.
Final answer:
InsuranceCoverage [insuranceLevel, description, maxCoverage]—{insuranceLevel} → {description, maxCoverage}TravelInsuranceHistory [tripName, approved, insuranceLevel, advisedPrecautions]—{tripName} → {approved, insuranceLevel},{tripName, approved, insuranceLevel} → {advisedPrecautions}, FKinsuranceLevelreferencesInsuranceCoverage.insuranceLevel
Section B — 3NF synthesis
Decompose (if needed) Department and TripExpenseAllocations into 3NF via minimal-cover synthesis.
Department
NoteWorking
CK = {code}. Highest NF (from Section A): 2NF.
Minimal cover: RHS-splitting {code} → {name, manager, buildingID, buildingName, buildingLocation, floor} and removing redundant attributes — code → buildingName and code → buildingLocation are both redundant (derivable transitively via code → buildingID then buildingID → buildingName/buildingLocation); buildingID → buildingLocation is redundant (derivable via buildingID → buildingName then buildingName → buildingLocation). Simplified cover: {code} → {name, manager, buildingID, floor}, {buildingID} → {buildingName}, {buildingName} → {buildingLocation, buildingID}.
Synthesis:
Department [code, name, manager, buildingID, floor]—{code} → {name, manager, buildingID, floor}Building [buildingName, buildingLocation, buildingID]—{buildingID} → {buildingName},{buildingName} → {buildingLocation, buildingID}(a candidate relation[buildingID, buildingName]from{buildingID}→{buildingName}alone is redundant — it’s a subset of thisBuildingrelation, so it’s dropped.)
TripExpenseAllocations
NoteWorking
CK = {tripName, expenseType} (the stated primary key is not minimal). Highest NF (from Section A): 1NF.
Minimal cover: after RHS-splitting and removing every attribute already implied by {tripName} or {expenseType} alone from the {tripName, expenseType, quantity} → ... FD (all seven of its RHS attributes turn out to be redundant there, since each is already determined by tripName or expenseType individually), the simplified cover is exactly: {tripName, expenseType} → {quantity, description}, {tripName} → {startDate, endDate, location, organiser}, {expenseType} → {allowance, restrictions}.
Synthesis:
TripExpenseAllocations [tripName, expenseType, quantity, description]—{tripName, expenseType} → {quantity, description}Trip [tripName, startDate, endDate, location, organiser]—{tripName} → {startDate, endDate, location, organiser}Expense [expenseType, allowance, restrictions]—{expenseType} → {allowance, restrictions}
(Same final relations as the BCNF decomposition in Section A — in this case, decomposition and synthesis happen to converge on the same schema.)
Week 12
Database Security
Module 5 — the final module. Covers threats to database security, the control measures used to defend against them, and SQL injection.
Outline
- Threats to database security
- Access control mechanisms — discretionary, mandatory, role-based
- Other control measures — inference control, flow control, encryption
- SQL injection
Why database security matters
Some of the largest data breaches on record (Yahoo, First American, Facebook, Marriott, MongoDB, Equifax, and others) collectively exposed billions of records — via hacking, poor security practice, or simple misconfiguration. Database security matters for:
- Legal/policy reasons — e.g. government policy protecting access to individuals’ data (medical records, financial ratings).
- Ethical reasons — e.g. controlling who can see employee salary packages or student grades.
- Technical reasons — e.g. protection from malware, performance overloading.
Threats — the CIA principle
- Loss of confidentiality — unauthorized disclosure of confidential information.
- Loss of integrity — improper modification of information.
- Loss of availability — a legitimate user cannot access data objects.
Privacy vs. security
- Security concerns how access to data is controlled — availability for use (with integrity) and permitted access.
- Privacy concerns how data can be used — an individual’s ability to control the terms under which their sensitive data is acquired and used (preventing storage of sensitive data; ensuring appropriate/authorized use of it).
- Security is a required building block for privacy, but they’re distinct: privacy concerns both directly accessible information and information that can be inferred from accessible data.
Sensitive data is often double-edged — patient data is private, but also valuable for biomedical/public-health research; audio from CCTV can capture private conversations, but also evidence of criminal activity. This creates a utility/privacy tradeoff: protect all sensitive data, while making as much nonsensitive data available as possible.
Database control measures
Four broad categories:
- Access control — provide access only to users with the right access authority.
- Inference control — ensure information about individuals cannot be derived even indirectly (applies to statistical databases).
- Flow control — prevent information from flowing to unauthorized users.
- Data encryption — protect sensitive data in transit.
Access control mechanisms
Database access control has two components:
- Authentication — verifying the identity of whoever is accessing the database.
- Authorization — determining whether an authenticated user should be allowed to execute the transaction they’re attempting.
Basic authentication security functions
- User accounts — users log in with an assigned username/password.
- Login session — a sequence of database operations by one user, recorded in the system log (also used for recovery, not just security).
- Database audit — reviewing the log to examine all accesses and operations applied during a period, to identify potential privacy breaches or unauthorised modifications. A log typically records who ran what operation, when, and (for modifications) the before/after values.
Discretionary Access Control (DAC)
Based on granting and revoking privileges.
CREATE USER <username> IDENTIFIED BY "<password>";
GRANT privilegeName
ON objectName
TO {userName | PUBLIC | roleName}
[WITH GRANT OPTION];
REVOKE privilegeName
ON objectName
FROM {userName | PUBLIC | roleName};Two levels of privileges
- Account level — privileges specified per account, independent of any particular relation:
CREATE SCHEMA/TABLE/VIEW,ALTER/DROP TABLE, modification (INSERT/DELETE/UPDATE) andSELECTprivileges. - Relation level — privileges for a specific relation or view (can also be specified at the attribute level): select (read), modification (insert/delete/update), and references privileges. The
REFERENCESprivilege grants permission to create a foreign key reference to the specified table.
Three concrete forms of the above, all of which week12-tutorial-5-1-database-security needs in order to repair a misconfigured set of accounts:
-- everything the account holds on that object, in one statement
REVOKE ALL PRIVILEGES ON `schema`.`Table` FROM 'user';
-- the ability to delegate, revoked separately from the privilege itself
REVOKE GRANT OPTION ON `schema`.`Table` FROM 'user';
-- attribute level: the column list goes on the privilege, not the object
GRANT SELECT (`fName`, `lName`) ON `schema`.`Table` TO 'user';Note there is no statement for narrowing a privilege: downgrading an account from ALL PRIVILEGES to SELECT is always REVOKE ALL PRIVILEGES followed by GRANT SELECT. Backticks quote identifiers that contain spaces or apostrophes, and objects are named `schema`.`table`.
CREATE SCHEMA AUTHORIZATION oe
CREATE TABLE Product (color VARCHAR2(10) PRIMARY KEY, quantity NUMBER)
CREATE VIEW RedProduct AS
SELECT color, quantity FROM Product WHERE color = 'RED'
GRANT select ON RedProduct TO hr;This single statement creates a schema oe, creates Product, creates the view RedProduct, and grants hr the SELECT privilege on RedProduct.
Access matrix model
Each relation R is assigned an owner account. Owners can grant select/modification/references privileges to other users on any owned relation. An access matrix M(i, j) captures the privilege(s) user i has on object j:
| Jake | Aiden | Nelly | Sham | |
|---|---|---|---|---|
| Customer | READ | READ | MODIFY | — |
| CustOrder | — | — | READ | — |
| CustOrder.amt | — | READ | READ | — |
| Supp.status | — | READ | MODIFY | REFERENCE |
| Supp.address | — | READ | MODIFY | MODIFY |
Revoking and propagating privileges
REVOKE cancels a privilege — useful for granting something temporarily. If account A grants a privilege to B WITH GRANT OPTION, B can then grant it onward to other accounts, without A’s direct knowledge — the DBMS must track this chain of dependency to support revocation correctly.
REVOKE privilegeName ON objectName FROM userName [RESTRICT | CASCADE];CASCADE— revokes the privilege and any dependent privileges that were granted as a result of it (following the chain onward).RESTRICT— refuses the revoke (returns an error) if the privilege has already been passed on to someone else.
A user’s authorization is valid iff there is a path from the root of the authorization graph down to that user’s node. So if u1 grants to u2, who grants to u3: revoking u1 → u2 also cuts off u3 (no path remains); but revoking a different branch, or u2’s authorization being revoked by someone else entirely, doesn’t necessarily touch u1 (the grantor’s own authorization is independent of what they’ve granted downstream).
Specifying privileges through views
If owner A wants to give account B a limited capability to SELECT from a relation — e.g. only some columns, or only rows meeting a condition — A can create a view and grant access to the view instead of the base table:
-- Employee [ssn, name, dob, address, sex, salary, mgrSSN, dNum]
CREATE VIEW A3EMPLOYEE AS
SELECT name, dob, address
FROM EMPLOYEE
WHERE dNum = 5;
GRANT SELECT ON A3EMPLOYEE TO A3;A3 can now only ever see name/dob/address for department 5 employees — never salary, ssn, or other departments’ staff.
Question 1 — Discretionary access control
Which statement removes a privilege from a user?
A. Remove update on department from Amir B. Revoke update on employee from Amir C. Delete select on department from Raj D. Grant update on employee from Amir
NoteSolution
B. REVOKE is the actual SQL keyword for removing a privilege. REMOVE and DELETE aren’t valid DCL keywords for this purpose, and GRANT adds a privilege rather than removing one.
Question 2 — Discretionary access control (propagation)
u1 grants authorization to u2, who in turn grants it to u3. Which is correct?
A. If u1 revokes from u3, u2’s authorization is revoked. B. If u1 revokes from u2, u3’s authorization is also revoked. C. If u2’s authorization is revoked, u1’s authorization is also automatically revoked.
NoteSolution
B. A user has an authorization iff there’s a path from the root of the authorization graph down to their node. u1 → u2 → u3 — revoking u1’s grant to u2 removes the only path down to u3 as well, so u3 loses authorization too. Revoking from u3 directly (A) has no effect on u2’s own (separately-granted) authorization. u2 losing authorization (C) doesn’t propagate upward to u1 — u1 is the root/grantor, not a recipient.
Worked exercise — GRANT/REVOKE chains
Four users A1, A2, A3, A4. DBA: GRANT CREATETAB TO A1. A1 creates Employee and Department, then runs:
GRANT INSERT, DELETE ON Employee, Department TO A2;
GRANT SELECT ON Employee, Department TO A3 WITH GRANT OPTION;Q1: Can A3 execute GRANT SELECT ON Employee TO A4?
NoteSolution
Yes — A3 was granted SELECT WITH GRANT OPTION, so A3 can pass that privilege on to A4.
Q2: If A1 then runs REVOKE SELECT ON Employee FROM A3, does A4 still have SELECT on Employee?
NoteSolution
No — A4’s privilege is automatically revoked too, by propagation (there’s no longer a path from the root down to A4).
Q3: What type of access control is this?
NoteSolution
Discretionary access control — privileges are granted/revoked at the discretion of individual account owners, rather than being fixed by a system-wide security classification (MAC) or role hierarchy (RBAC).
Mandatory Access Control (MAC)
An additional policy that classifies both data and users into security classes, for multilevel security. Typical classes (low to high): Unclassified (U) < Confidential (C) < Secret (S) < Top Secret (TS). Users are called subjects; data (table, tuple, or attribute) are objects.
The Bell-LaPadula model
- Simple security property (“no read up”, NRU) — a subject can’t read an object with a higher sensitivity label than the subject’s own. E.g. a user with clearance
Ucannot view a salary value classifiedC. - Star property (“no write down”, NWD) — a subject can’t write to an object with a lower sensitivity label than the subject’s own — this prevents information flowing from a higher to a lower classification. E.g. a user with clearance
Scannot insert a new tuple containing onlyC-classified information (that would let a lower-clearance user infer something about a higher-clearance operation via the write).
Each tuple gets a Tuple Classification (TC) — the highest classification of any of its attribute values — and, by the same rule one level up, a table’s classification is the highest TC of any tuple in it. That second step is what makes the star property bite in practice: in week12-tutorial-5-1-database-security, an Operation table whose tuples top out at S is an S object, so a TS subject inserting into it is writing down and is refused.
(a) EMPLOYEE (original)
Name Salary JobPerformance TC
Smith (U) 40000 (C) Fair (S) S
Brown (C) 80000 (S) Good (C) S
(b) EMPLOYEE, as seen by a Confidential-clearance user
Name Salary JobPerformance TC
Smith (U) 40000 (C) NULL (C) C
Brown (C) NULL (C) Good (C) C
(c) EMPLOYEE, as seen by an Unclassified-clearance user
Name Salary JobPerformance TC
Smith (U) NULL(U) NULL (U) UA C-clearance user sees Smith’s JobPerformance as NULL (it’s actually S-classified — above their clearance) and Brown’s Salary as NULL (S-classified).
Inference attacks and polyinstantiation
Suppose a C-clearance user runs UPDATE EMPLOYEE SET JobPerformance = 'Excellent' WHERE Name = 'Smith' (working from view (b), where they only ever saw NULL for that field). The system must not reject this — rejecting it would let the user infer that a real, higher- classified value already exists (a covert channel leak). The solution is polyinstantiation — maintaining multiple tuples with the same key but different classifications:
(d) EMPLOYEE, polyinstantiated
Name Salary JobPerformance TC
Smith (U) 40000 (C) Fair (S) S
Smith (U) 40000 (C) Excellent (C) C
Brown (C) 80000 (S) Good (C) SBoth the original S-classified fact and the new C-classified “fact” now coexist — a C-clearance user sees “Excellent”; an S-or-higher user still sees the original “Fair” (plus, depending on implementation, awareness that a lower-classified duplicate also exists).
Figure 25: Why a MAC database will store two tuples with the same key. View (b) of EMPLOYEE sits above the stored result (d), with the offending UPDATE on the arrow between them. The point is the chain of forced moves: the C user was shown NULL, so the update is a reasonable thing for them to issue; rejecting it would tell them a higher-classified value is already there, which is the covert channel; accepting it in place would destroy an S-classified fact by writing down over it. Storing both is the only move left, and it is also why an apparently duplicate INSERT succeeds in week12-tutorial-5-1-database-security’s Section B.
DAC vs. MAC
| Discretionary | Mandatory | |
|---|---|---|
| Flexibility | High — owners choose who gets what | Low — rigid, centrally imposed |
| Propagation control | None — DAC doesn’t restrict how information, once accessible, is further shared | Strong — enforces classification rules on every read/write |
| Protection | Weaker | Stronger — prevents illegal information flow |
Role-Based Access Control (RBAC)
Permissions are associated with organisational roles, and users are assigned to the appropriate role(s) — roles can then have DAC or MAC methods applied to them as a unit.
CREATE ROLE manager;
DROP ROLE manager;
GRANT ROLE full-time TO emp_typ1;
GRANT ROLE intern TO emp_typ2;
GRANT privilegeName ON objectName TO {userName | PUBLIC | roleName} [WITH GRANT OPTION];
REVOKE privilegeName ON objectName FROM {userName | PUBLIC | roleName};A typical hierarchy: users → groups → roles → privileges (e.g. alice is in group admin, which maps to admin_role, which grants ALL ON SERVER server1). RBAC’s flexibility and easier administration make it a popular choice for web-based applications.
Other control measures
Inference control
Statistical databases provide aggregate statistics about a population (e.g. for government statisticians or market researchers) without exposing individual-level confidential data — only statistical queries using aggregates (COUNT, SUM, MIN, MAX, AVG, standard deviation) are permitted:
SELECT COUNT(*) FROM PERSON WHERE <condition>;
SELECT AVG(Income) FROM PERSON WHERE <condition>;The risk: a narrow enough WHERE condition can isolate a group small enough (even a single individual) that an “aggregate” query effectively discloses that person’s data. Mitigations:
- k-anonymity — enforce a minimum threshold on the number of tuples any query’s result can be based on.
- Prohibit sequences of queries that all refer to the same (or overlapping) population of tuples, which together could be combined to isolate an individual.
- Differential privacy — introduce carefully calibrated noise/ inaccuracy into results.
Flow control
Regulates the distribution of information among accessible objects, verifying information doesn’t flow — explicitly or implicitly — into less protected objects (this is exactly the Bell-LaPadula “no write down” idea, generalised). A flow policy specifies which channels information may move along — e.g. in a simple confidential (C) / nonconfidential (N) scheme, flow from C to N is prohibited. Example: an income tax computing service might be allowed to retain a customer’s address, but not their income/deductions data.
Data encryption
Encryption converts data into ciphertext, using an encryption algorithm and a key; recovering the original data requires the corresponding decryption key.
- DES (Data Encryption Standard) — developed by the US government for general public use.
- AES (Advanced Encryption Standard) — a newer, more difficult to crack standard.
SQL injection
SQL injection is one of the most common threats to a database system: an attacker injects string input through an (often web-facing) application in a way that changes or manipulates the resulting SQL statement to their advantage.
Methods
- SQL manipulation — changes an existing SQL command, e.g. adding conditions to a
WHEREclause. Classic target: the login form. - Code injection — adds entirely new SQL statements/commands by exploiting improper handling of untrusted input.
- Function call injection — inserts a database or OS function call into a vulnerable SQL statement, to manipulate data or make a privileged system call.
SQL manipulation example
A naive login check builds its query by directly concatenating user input:
SELECT * FROM Users WHERE Username = '<input>' AND Password = '<input>';Normal login (Jack / Pass123) produces WHERE Username = 'Jack' AND Password = 'Pass123' — matches the stored row, access granted. But an attacker who knows the username Jack can enter the password field as:
' OR 'x'='xgiving the executed query:
SELECT * FROM Users WHERE username = 'Jack' AND (password = '' OR 'x'='x');'x'='x' is always true, so the AND collapses to just username = 'Jack' — the row is returned regardless of the actual password, and access is granted.
Code injection example
Going further, appending a second statement via a semicolon:
wrongpass' OR 'x'='x'; drop table Users;If the application naively executes whatever SQL string results (and the driver/DBMS allows statement-stacking), this doesn’t just bypass login — it can destroy the entire Users table.
Risks associated with SQL injection
- Database fingerprinting — determining the type of database in use (to target version-specific exploits).
- Denial of service — denying service to valid users.
- Bypassing authentication — gaining access without valid credentials (as shown above).
- Identifying injectable parameters — learning about the backend structure through error messages/behaviour.
- Executing remote commands — running harmful commands remotely (e.g. via function call injection).
- Performing privilege escalation — upgrading the attacker’s own access level.
Protection techniques
- Bind variables (parameterized statements) — pass user input as bound parameters, never concatenated directly into the SQL string. This is the primary defence: the database driver treats parameter values purely as data, never as executable SQL syntax — and as a bonus, it also improves performance (query plans can be cached and reused).
- Filtering input (input validation) — strip/escape characters (like unescaped quotes) that could otherwise be used to break out of a string literal and inject manipulation.
- Function security — restrict which standard and custom database functions are callable, to limit the blast radius of function call injection.
Summary
You should now be able to explain the threats to database security and the CIA principle; describe DAC, MAC, and RBAC and apply them (given grant/revoke commands, or a Bell-LaPadula classification scenario) to determine resulting access; and explain SQL injection, its risks, and how to defend against it. This completes the course content. See week12-tutorial-5-1-database-security for practice.
Reading: the matching textbook material is the database-security chapter of Elmasri & Navathe — Chapter 30 in the 7th edition.
Tutorial 5.1: Database Security
Practice for 2026-05-11-database-security; the mechanisms themselves are collected in database-access-control.
Purpose: assign and revoke privileges using SQL, identify DBMS access errors for given situations, and gain experience identifying privacy violations that occur through a lack of inference control. By the end you should be able to
- use SQL Data Control Language to apply access control to a database system,
- troubleshoot and remedy incorrect permission assignments,
- determine how mandatory access control settings affect the running of common SQL queries, and
- perform a basic database security audit.
Section A — Discretionary Access Control
Universe of discourse: Rob’s Convenience Store has a database system to manage business activities. System admin Paris has created accounts for herself and four staff members, with these requirements:
- Paris (sysadmin) — full access to the whole database, and can grant permissions to others.
- Rachel (HR manager) — full access to
Employee; can view (but not modify)Restock. - Aaron (supply chain lead) — full access to
Item,Restock, andSale. - Chris (customer service) — full access to
Customer; read access toSale. - Emily (security manager, investigates missing stock) — read access to
SaleandRestock; can view only thefName/lNameattributes of bothEmployeeandCustomer.
Schema: Employee [id, fName, lName, role, email], Restock [employee, item, time, quantity] (FKs to Employee.id, Item.id), Item [id, name, description, price], Sale [customer, item, time, quantity] (FKs to Customer.id, Item.id), Customer [id, fName, lName, dob].
Figure 26: The Rob’s Convenience Store schema the whole of Section A is set on. Each table lists its columns with their types (int(11), varchar(100), timestamp), as a database tool shows them, not in the course’s ER notation. The four foreign keys are crimson arrows pointing FK → PK. The shaded fName/lName columns in Employee and Customer are the four attributes Emily’s column-level grant in A.1/A.2 is about, and they are the reason this exercise needs attribute-level privileges at all.
Question A.1 — Identify and fix incorrect access
The permission table below (as currently configured) contains several errors. Fix it, using the UoD and the schema above. - indicates that the access level for that object is not directly specified; the first column (Paris) has been fixed for you already.
| Paris | Rachel | Aaron | Chris | Emily | |
|---|---|---|---|---|---|
| Employee | ALL PRIVILEGES | ALL PRIVILEGES | UPDATE | - | SELECT |
| Restock | ALL PRIVILEGES | ALL PRIVILEGES | ALL PRIVILEGES | - | SELECT |
| Item | ALL PRIVILEGES | - | ALL PRIVILEGES | - | - |
| Sale | - | - | ALL PRIVILEGES | UPDATE, GRANT | - |
| Customer | SELECT, UPDATE | - | SELECT | ALL PRIVILEGES | - |
| Customer.fName | - | - | - | - | SELECT |
| Customer.lName | - | - | - | - | SELECT |
| Employee.fName | - | - | - | - | - |
| Employee.lName | - | - | - | - | - |
NoteWorking
Corrected table (changed cells in bold):
| Paris | Rachel | Aaron | Chris | Emily | |
|---|---|---|---|---|---|
| Employee | ALL PRIVILEGES | ALL PRIVILEGES | - | - | - |
| Restock | ALL PRIVILEGES | SELECT | ALL PRIVILEGES | - | SELECT |
| Item | ALL PRIVILEGES | - | ALL PRIVILEGES | - | - |
| Sale | ALL PRIVILEGES | - | ALL PRIVILEGES | SELECT | SELECT |
| Customer | ALL PRIVILEGES | - | - | ALL PRIVILEGES | - |
| Customer.fName | - | - | - | - | SELECT |
| Customer.lName | - | - | - | - | SELECT |
| Employee.fName | - | - | - | - | SELECT |
| Employee.lName | - | - | - | - | SELECT |
Ten cells change, and each traces to one line of the UoD:
- Paris,
SaleandCustomer: blank /SELECT, UPDATE→ALL PRIVILEGES. She is the sysadmin with full access to the whole database, so every table isALL PRIVILEGES. - Rachel,
Restock:ALL PRIVILEGES→SELECT. She may viewRestockbut “is not allowed to make changes”. - Aaron,
Employee:UPDATE→-, andCustomer:SELECT→-. His remit isItem,RestockandSaleonly; nothing in the UoD gives him any access to staff or customer records. - Chris,
Sale:UPDATE, GRANT→SELECT. He needs read access toSale, soUPDATEis too much — and the grant option is never justified for anyone but Paris. - Emily,
Sale:-→SELECT. She investigates missing stock and needs read access toSaleas well asRestock. - Emily,
Employee:SELECT→-, withEmployee.fNameandEmployee.lName:-→SELECT. This is the pair of changes worth understanding: the UoD gives her only two columns ofEmployee, so table-levelSELECT(which would exposeroleandemailas well) is withdrawn and replaced by attribute-levelSELECT— the same shape herCustomeraccess already had.
The general rule the whole question drills: grant the narrowest privilege that satisfies the stated responsibility — read-only where someone only needs to look, nothing at all on tables outside their remit, and attribute-level SELECT where they need two columns rather than a whole table.
Question A.2 — SQL grant/revoke queries
Using your answer above, write the appropriate SQL queries to fix the user accounts with incorrect permissions. (Extension: import the sample database and test the queries manually.)
NoteWorking
Only the four accounts with errors need statements — Paris’s own entries were corrected as the worked example, and no account needs a statement for a cell that was already right (Emily keeps her Restock SELECT and her two Customer columns untouched).
-- Rachel
REVOKE ALL PRIVILEGES ON `Rob's Convenience Store`.`Restock` FROM 'Rachel';
GRANT SELECT ON `Rob's Convenience Store`.`Restock` TO 'Rachel';
-- Aaron
REVOKE ALL PRIVILEGES ON `Rob's Convenience Store`.`Employee` FROM 'Aaron';
REVOKE ALL PRIVILEGES ON `Rob's Convenience Store`.`Customer` FROM 'Aaron';
-- Chris
REVOKE ALL PRIVILEGES ON `Rob's Convenience Store`.`Sale` FROM 'Chris';
REVOKE GRANT OPTION ON `Rob's Convenience Store`.`Sale` FROM 'Chris';
GRANT SELECT ON `Rob's Convenience Store`.`Sale` TO 'Chris';
-- Emily
REVOKE ALL PRIVILEGES ON `Rob's Convenience Store`.`Employee` FROM 'Emily';
GRANT SELECT ON `Rob's Convenience Store`.`Sale` TO 'Emily';
GRANT SELECT (`fName`, `lName`) ON `Rob's Convenience Store`.`Employee` TO 'Emily';Three points of syntax the solution turns on:
- Downgrading is revoke-then-grant. There is no “set the privilege to
SELECT” statement: youREVOKE ALL PRIVILEGESand thenGRANTback exactly what is wanted (Rachel, Chris, Emily). Where nothing should be left, theREVOKEstands alone (Aaron). REVOKE GRANT OPTIONis a separate statement from revoking the privilege itself. Chris needs both: one to take awayUPDATE, one to take away his ability to pass anything on.- Attribute-level privileges are written as a column list on the privilege, not on the object:
GRANT SELECT (`fName`, `lName`) ON `…`.`Employee`. Backticks quote identifiers containing spaces and apostrophes — hence`Rob's Convenience Store`— and the schema is qualified as`schema`.`table`.
Section B — Mandatory Access Control
Universe of discourse: ASIO (the Australian Security Intelligence Organisation) has created a database to track the identities of its undercover agents. Because some agents’ assignments are riskier than others, a MAC database was implemented to prevent classified information falling into the wrong hands.
Schema:
Spy [ID, fName, lName, dob, email]
CodeName [spyID, name, dateEffective, dateExpired, operation]
Operation [name, description, budget]
CodeName.spyID references Spy.id
CodeName.operation references Operation.nameCodeName’s key is the composite {spyID, name}, which is what makes B.1’s third query an apparent key violation. (The Spy key is written ID in the schema line but Spy.id in the foreign-key line and id in the sample data; it is the same attribute.)
DBMS accounts, low to high:
| Database user | Access level |
|---|---|
| Cody | U (Unclassified) |
| Jane | C (Confidential) |
| Tanya | S (Secret) |
| Jack | TS (Top Secret) |
Sample data
Each value carries its own classification, shown in parentheses; TC is the Tuple Classification, the highest classification of any attribute in the tuple.
Spy — note that fName and lName are both TS, so only Jack can read an agent’s actual name; id is U, dob is C, email is S.
| id | fName | lName | dob | TC | |
|---|---|---|---|---|---|
| 1 (U) | Daniel (TS) | Teal (TS) | 18/06/1995 (C) | bmw@hotmail.com (S) | TS |
| 2 (U) | May (TS) | Lee (TS) | 03/02/1998 (C) | may@stevefam.com (S) | TS |
| 3 (U) | John (TS) | Smith (TS) | 12/05/1990 (C) | john@smith.com (S) | TS |
| 4 (U) | April (TS) | Fuller (TS) | 25/06/1980 (C) | ilikefood@korea.com (S) | TS |
CodeName — the classification of spyID, name and operation varies row by row (in the BBQ row all three are TS); both date attributes are U in every row.
| spyID | name | dateEffective | dateExpired | operation | TC |
|---|---|---|---|---|---|
| 1 (C) | Handbrake (C) | 01/02/2019 (U) | 03/06/2020 (U) | Le-Ferrari (S) | S |
| 2 (C) | BunnyBunny (S) | 12/03/2019 (U) | 12/04/2019 (U) | Hotpot (C) | S |
| 4 (C) | BubbleTea (C) | 19/04/2019 (U) | 24/04/2019 (U) | Hotpot (C) | C |
| 2 (TS) | BBQ (TS) | 27/09/2019 (U) | 04/10/2019 (U) | KimChi (TS) | TS |
Operation — the highest classification anywhere in this table is S, which is what makes Jack’s insert in B.1 illegal.
| name | description | budget | TC |
|---|---|---|---|
| Hotpot (S) | Infiltrate McDonalds and discover the ingredients in the Big Mac secret sauce. (S) | 1000000 (S) | S |
| Le-Ferrari (C) | Identify the leader of an international Ferrari stealing syndicate. (U) | 10000000 (U) | C |
| KimChi (S) | Someone has stolen ASIO’s secret KimChi supply and now the yearly Korean BBQ party is ruined! The thief must be found! (S) | 500000000 (S) | S |
Figure 27: The two Bell–LaPadula rules, with this exercise’s four accounts on the rungs they occupy. The four classes run low to high, U (green), C (orange), S (red), TS (dark red); the three worked outcomes on the right are B.1’s second, fourth and fifth rows. A subject may read anything at or below its own rung and write anything at or above it, so the only unrestricted position is a subject whose clearance exactly matches the data’s class — which is why Jane’s UPDATE at C succeeds while Cody reading up and Jack writing down both fail.
Question B.1 — Identifying security denials
Based on the information above, identify which of the following queries will succeed and which will return nothing / fail to be executed. The first row is the worked example.
NoteWorking
| User | Query | S / F | Reason |
|---|---|---|---|
| Cody | SELECT id FROM Spy; |
S | Cody’s classification (U) is ≥ the classification of every id value (U), so the query is valid. |
| Cody | SELECT name FROM Operation WHERE budget > 10000000 |
F | Cody’s level (U) is not ≥ the classification of any of the tuples’ name values (S, C, S). So even though the WHERE condition evaluates true for one tuple (KimChi, 500000000), the query still returns nothing. |
| Cody | INSERT INTO CodeName (spyID, name, dateEffective, dateExpired, operation) VALUES (2, "BBQ", "16/05/2019", "26/05/2019", "Hotpot") |
S | This looks like a key violation — {spyID, name} = {2, BBQ} already exists — but the two “identical” tuples have different security classifications, so the DBMS can apply polyinstantiation to let them co-exist. |
| Jack | INSERT INTO Operation (name, description, budget) VALUES ("Ace", "Find an unidentified hacker who has been using SQL injections to change students' grades to all 7's in Universities around Australia.", 350000) |
F | The security classification of the Operation table is S, that being the highest class of any of its tuples. Jack’s class is TS, which is greater than S, so the query is not executed — it would let information flow from a higher to a lower security classification. |
| Jane | UPDATE CodeName SET name = "Iced Coffee" WHERE spyID = 4 |
S | Jane’s classification (C) is ≥ the classification of the spyID attribute (C), so she has read permission; it is also ≤ the classification of that row’s name attribute (C), so she has write permission. Both hold, so the DBMS processes the update. |
Two things are worth pulling out of that table.
An UPDATE needs both directions to hold at once. Jane’s update reads (WHERE spyID = 4) and writes (SET name = …), so it is subject to both rules — read requires clearance ≥ class, write requires clearance ≤ class. Both are satisfied here only because the attributes involved are classified exactly at her own level. Had that row’s name been U, the same statement would have been a write down and failed.
“Fails” and “returns nothing” are the same answer here. The column is Success (S) or Failure (F), and Cody’s second query is F even though the DBMS does not raise an error — it simply returns an empty result. The question counts the two together (“identify which of the following queries will succeed, and which ones will return nothing / fail to be executed”), so the column is really does the user get an answer. The DBMS stays silent rather than refusing outright because telling a U user “permission denied” would itself disclose that a matching higher-classified tuple exists — the same covert-channel argument that motivates polyinstantiation.
Question B.2 — Returning data in a MAC database
Fill the table and identify what data is returned when the specified users run the query. The first row is the worked example.
Figure 28: The worked example of B.2, drawn out: the two different things MAC does to a tuple. The left-hand table is the CodeName sample data with each value’s classification, and the right-hand table is what Jane’s query returns. The distinction it makes is the one the remaining B.2 rows turn on: an over-classified value inside a tuple that is otherwise readable comes back as NULL, but a tuple with nothing readable in it does not come back at all — it is not returned as a row of NULLs.
NoteWorking
Jane — SELECT spyID, name, operation FROM CodeName (the worked example, drawn out in Figure 28):
| spyID | name | operation |
|---|---|---|
| 1 | Handbrake | NULL |
| 2 | NULL | Hotpot |
| 4 | BubbleTea | Hotpot |
Row 1’s operation (Le-Ferrari, S) and row 2’s name (BunnyBunny, S) are above Jane’s C and come back as NULL; the BBQ row, whose spyID, name and operation are all TS, does not appear at all.
A caveat: the EMPLOYEE example in 2026-05-11-database-security drops a tuple whose key value is unreadable (the U user never sees Brown, because Name is C) — though nothing else in that tuple is readable at U either, so it does not settle which rule is doing the work. Applied strictly to CodeName, whose key is {spyID, name}, that rule would also drop row 2 — BunnyBunny is S — yet the model answer keeps it with name masked. So the test these answers actually apply is “is anything in the tuple readable”, not “is the whole key readable”. Answer the same way.
Jane — SELECT name, dob FROM CodeName, Spy WHERE id = spyID AND dateEffective < "01/06/2020":
| name | dob |
|---|---|
| Handbrake | 18/06/1995 |
| NULL | 03/02/1998 |
| BubbleTea | 25/06/1980 |
The join works because Spy.id is U and CodeName.spyID is C in the three surviving rows — both readable at C, so the pairing can be computed. dob is C throughout, so it is returned in full; BunnyBunny is masked as before; and the BBQ row is again absent (its spyID is TS, so it can neither be read nor joined), which is why there are three rows and not four even though every dateEffective in the table satisfies the condition.
Cody — SELECT name, budget FROM Operation WHERE description LIKE "%a%":
| name | budget |
|---|---|
| NULL | 10,000,000 |
Only Le-Ferrari’s description is U, so it is the only row whose WHERE condition Cody can even evaluate — Hotpot’s and KimChi’s descriptions are S and invisible to him. For that row, budget is U and is returned in full, while name is C and is masked to NULL. Note the shape of the leak this prevents: Cody learns that some operation matching %a% has a ten-million-dollar budget, but not which one.
Jane — SELECT spyID, Operation.name, Operation.budget FROM Operation, CodeName WHERE Operation.name = CodeName.operation: empty set returned. When you complete a join on CodeName and Operation using the operation attribute, in each instance one side of the join is of class S or TS, which is above Jane’s clearance. Hence there are no valid joins and no tuples returned. Concretely: the three joinable pairs are Le-Ferrari (S in CodeName, C in Operation), Hotpot (C in CodeName, S in Operation) and KimChi (TS/S) — each has at least one unreadable end, so the equality can never be established at C.
This is the sharpest MAC result in the tutorial: a join can return the empty set even though matching rows plainly exist, and even though the user can see parts of both tables.
Bonus — Completing a database audit
Universe of discourse: SummerStyles is a clothing retailer which uses a DBMS to store all its staff, customer and stock information. Every month it performs a database audit to check for unauthorised changes to company records and to identify potential privacy violations.
Task: using the log below, identify potential cases of privacy breaches or unauthorised modification of data. Hint: there is no exact formula — use your intuition and common sense to flag potential cases where you feel it is possibly a security breach.
The log has the column shape of a MySQL general query log: each entry records event_time, user_host, thread_id, server_id, command_type (every row here is Query) and the argument — the statement as issued. That “who ran what, and when” shape is exactly the system log that database-access-control describes an audit as reading.
event_time user_host argument
17-05-2020 8:27:18am SystemAdmin@localhost SHOW COLUMNS FROM SummerStyles.customer
17-05-2020 8:28:00am SystemAdmin@localhost SHOW INDEXES FROM SummerStyles.customer
17-05-2020 8:30:07am HRManager@localhost UPDATE SummerStyles.staff SET Wage = Wage * 1.1
17-05-2020 8:31:07am CustomerService@localhost SELECT * FROM SummerStyles.customer WHERE fName="Elaine" AND lName="Wang"
17-05-2020 8:33:30am SystemAdmin@localhost SELECT TABLE_NAME FROM information_schema.VIEWS WHERE TABLE_SCHEMA='SummerStyles' AND TABLE_NAME='Customer'
17-05-2020 8:35:05am CustomerService@localhost SELECT fName, lName, max(wage) FROM SummerStyles.staff
17-05-2020 8:35:43am StockManager@localhost DELETE FROM SummerStyles.deliveries WHERE id = 204472
17-05-2020 8:38:32am StockManager@localhost UPDATE SummerStyles.currentStock SET quantity = quantity + 8 WHERE stockID = 1263
17-05-2020 8:41:14am SystemAdmin@localhost ALTER TABLE SummerStyles.staff ADD email varchar(255);
17-05-2020 8:45:41am HRManager@localhost INSERT INTO SummerStyles.staff (id, fName, lName) VALUES (142, "Leya", "Rebecca")
17-05-2020 8:57:37am HRManager@localhost UPDATE SummerStyles.stock SET price = 11.00 WHERE name LIKE "%Calvin Klein%"
NoteWorking
Exactly two entries should be flagged:
- 8:35:05am —
CustomerService:SELECT fName, lName, max(wage) FROM SummerStyles.staff. A customer service account querying staff wage data is well outside its remit — salary information is HR’s domain. A potential privacy breach. - 8:57:37am —
HRManager:UPDATE SummerStyles.stock SET price = 11.00 WHERE name LIKE "%Calvin Klein%". An HR account modifying product pricing is outside HR’s duties — the stock tables areStockManager’s domain, and that account’s own two entries in this log are both stock changes. A potential unauthorised modification.
Both share the same tell, and it is the one the audit is looking for: the statement is perfectly legal SQL that the account had the privileges to run, and it is the role, not the syntax, that is wrong. Which is the argument for A.1’s narrow grants — had CustomerService never been given SELECT on staff in the first place, there would have been nothing to find in the log.
Worth not flagging, and knowing why: the HRManager wage rise at 8:30:07 (an across-the-board UPDATE on staff.Wage with no WHERE looks drastic, but it is HR’s own table and its own business); the CustomerService lookup of one named customer at 8:31:07 (exactly what customer service does); and the SystemAdmin SHOW/ information_schema queries and ALTER TABLE (schema administration, which is that account’s whole purpose).
Reference material
3NF Synthesis
3NF synthesis is the bottom-up route from a universal relation to a good schema: instead of repeatedly splitting one big relation apart (see [decomposition]), it builds relations up from a minimal-cover — one relation per dependency. The result is guaranteed lossless-join, dependency preserving, and in 3NF. Introduced in 2026-05-04-normalisation-and-relational-database-schema-design.
Dependency preservation is the reason to choose synthesis over BCNF decomposition: because every FD in the cover gets its own relation, every FD ends up checkable against a single relation. The price is that 3NF tolerates the residual anomalies BCNF would have removed.
The algorithm
S := ∅;
Compute a minimal cover G of F;
Combine all FDs in G with the same LHS into one;
For each X → Y in G:
if no relation in S contains X ∪ Y:
add a relation with schema X ∪ Y to S;
if any candidate key is missing from the relations:
add a relation with all prime attributes (i.e. all candidate keys);
Eliminate redundant relations from the resulting set of relations;A relation is redundant if it is a projection of another relation already in the schema — that is, if its attributes are a subset of another’s.
Reading it step by step:
| Step | What it does | Why |
|---|---|---|
| Minimal cover | Strips redundant FDs and redundant LHS attributes | Redundant FDs would create redundant relations |
| Combine same LHS | X → A and X → B become X → {A, B} |
Otherwise you’d get two relations that both key on X |
| One relation per FD | Schema X ∪ Y; X is its key |
Puts each dependency somewhere it can be enforced — this is what preserves dependencies |
| Add the key relation | If no relation contains a full candidate key, add one holding all prime attributes | Without it the decomposition need not be lossless — nothing joins the pieces back to the original key |
| Eliminate redundant relations | Drop any relation that is a projection of another — i.e. whose attributes are a subset of another’s | A subset relation stores nothing new |
The key relation step, precisely
This is the step that trips people up, so it’s worth stating exactly.
When it fires. Check whether any relation already in S contains a full candidate key of R among its attributes. If one does, skip the step entirely. If none does, fire it. Note that the FD-derived relations often look key-ish — each has its own LHS as a local key — without any of them containing a candidate key of the original R.
What gets added. A relation containing all the prime attributes — the union of every candidate key of R, not one chosen candidate key. When R has exactly one candidate key the two readings coincide, which is why the distinction is easy to miss; when it has several, they differ and only the union is correct.
Why. The FD-derived relations are chained together by their shared LHS attributes, but nothing guarantees those chains reach the original key. The prime-attribute relation is what makes the join reconstruct R — it is a losslessness patch, not an FD-carrying relation, and it usually carries no non-trivial FD at all.
Then re-run elimination. The prime-attribute relation is typically wide, so relations added earlier can become projections of it. Eliminate redundant relations after adding it, never before.
Worked example — the straightforward shape
R [A, B, C, D, E] with F = {{A,B} → C, C → D} (already a minimal cover). A, B and E never appear on a RHS, so every key contains them; {A,B,E}⁺ = {A,B,C,D,E}, so {A, B, E} is the only candidate key.
- One relation per FD:
R1 [A, B, C](from{A,B} → C) andR2 [C, D](fromC → D). - Neither contains the candidate key
{A, B, E}—Eappears nowhere — so addR3 [A, B, E]. - No relation is a subset of another.
Final: R1 [A, B, C], R2 [C, D], R3 [A, B, E].
R3 carries no non-trivial FD; its job is purely to hold the key together so the join is lossless. A relation like that is a normal, and expected, output of synthesis.
Worked example — same-LHS combination and subset elimination
R [A, B, C, D, E] with {A} → {D,E}, {D} → {A}, {B} → {C}, {B,C} → {A,D}, {E,A} → {D} (from week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis).
{B}⁺ = {A,B,C,D,E}, and B never appears on a RHS, so {B} is the only candidate key.
Minimal cover: after RHS-splitting, {E,A} → D simplifies to {A} → D (E is redundant — A alone already reaches D) and the resulting duplicate collapses into the existing {A} → {D,E}; {B,C} → A and {B,C} → D both lose their C (redundant, since B → C), becoming {B} → A and {B} → D; and {B} → D is then dropped outright, being derivable via {B} → A then {A} → D. What remains is {A} → {D, E}, {B} → {A, C}, {D} → {A}.
Synthesis: one relation per FD gives [A, D, E], [A, B, C] and [A, D]. The last is a subset of [A, D, E], so it goes. The candidate key {B} is already inside [A, B, C], so no extra relation is needed.
Final: R1 [A, D, E] (carrying {A} → {D,E} and {D} → {A}), R2 [A, B, C] (carrying {B} → {A,C}). Both are in 3NF.
Worked example — when the key relation swallows everything
Given the minimal cover {A,C} → E, {B,D} → A, A → B, E → {C, F} for R [A, B, C, D, E, F]. The candidate keys are {A,C,D}, {A,D,E}, {B,C,D} and {B,D,E} — note F appears in none of them, so the prime attributes are {A, B, C, D, E}.
- One relation per FD:
[A, C, E],[B, D, A],[A, B],[E, C, F]. [A, B]is a subset of[B, D, A]— drop it.- No remaining relation contains a full candidate key: every key contains
D, but[A,C,E]and[E,C,F]lackD, and[A,B,D]lacks bothCandE. So addR5with all prime attributes:[A, B, C, D, E]. - Eliminate subsets again:
[A, C, E]and[A, B, D]are now both subsets ofR5— drop both.[E, C, F]is not (it hasF) — keep.
Final: [E, C, F] and R5 [A, B, C, D, E].
This is the case that catches people out. Skipping the second subset-elimination pass leaves three redundant relations behind; skipping step 3 leaves a decomposition that isn’t lossless.
Synthesis vs decomposition
| BCNF decomposition (top-down) | 3NF synthesis (bottom-up) | |
|---|---|---|
| Input | R + F |
A minimal cover of F |
| Method | Split on each violating FD | One relation per FD, plus a key relation |
| Normal form reached | BCNF | 3NF |
| Lossless join | ✅ | ✅ |
| Dependency preserving | ❌ (not guaranteed) | ✅ |
| Anomaly-free | ✅ | Mostly — 3NF’s prime-attribute clause can let some through |
Neither is deterministic — synthesis depends on which minimal cover you land on, decomposition on the order violating FDs are processed — and both inherit any error in the FD set: a missing FD produces a sub-optimal or incorrect design either way.
The two often converge. In week11-tutorial-case-study-9-payroll-system, TripExpenseAllocations decomposes to the same three relations — Trip, Expense, TripExpenseAllocations — whether you take the BCNF or the synthesis route. When they differ, the difference is exactly the FDs BCNF had to sacrifice.
See also
- minimal-cover — compute this first; synthesis is meaningless without it
- [decomposition] · normal-forms · attribute-closure · functional-dependencies
- 2026-05-04-normalisation-and-relational-database-schema-design — Module 4, part 2
- week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis — Section B is pure synthesis drill
Attribute Closure and Finding Keys
Attribute closure is the one algorithm the whole of Module 4 runs on. Every later question — is this a key? is this relation in BCNF? is this FD redundant? does this FD survive a decomposition? — is answered by computing a closure. Introduced in 2026-04-27-database-design-guidelines-and-functional-dependencies.
Definition
Given a relation R, a set of FDs F, and a set of attributes X ⊆ R, the closure of X (written X⁺) is the set of all attributes functionally determined by X under F:
\[X^{+} = \{\, A \in R \;:\; F \models X \rightarrow A \,\}\]
Computing X⁺ is the practical substitute for computing F⁺ — which would need Armstrong’s Axioms and is explicitly out of scope for this course (see functional-dependencies) — and it answers the only question we ever actually ask of F⁺.
The algorithm
Start with X itself, then repeatedly apply any FD whose LHS is already fully contained in the set, until nothing more can be added:
X+ := X;
repeat
old X+ := X+;
for each FD Y → Z in F:
if Y ⊆ X+ then X+ := X+ ∪ Z;
until (old X+ = X+);Two things to watch:
- The LHS must be entirely inside
X⁺before the FD can fire — a partial match does nothing.{A, D}⁺ = {A, D}under{A,B} → E, C → {B,E}, {E,D} → F, because none of the three LHSs is a subset of{A, D}, so the closure never grows past its starting point. - It’s a fixpoint loop, not a single pass: an FD that couldn’t fire earlier may fire once a later FD has added its LHS. Keep sweeping
Funtil a full pass adds nothing.
Worked examples
Employee (id, level, salary, name) with F = {id → level, level → salary, id → name}:
| Step | {id}⁺ |
Using |
|---|---|---|
| 0 | {id} |
— (start) |
| 1 | {id, level} |
id → level |
| 2 | {id, level, salary} |
level → salary |
| 3 | {id, level, salary, name} |
id → name |
{id}⁺ covers every attribute, so id is a superkey — and since it’s a single attribute it’s trivially minimal, so it’s a key.
A chained closure — R [pNumber, pName, pLocation, dNum, dName, mgrSSN, mgrStartDate] with F = {pNumber → {pName, pLocation, dNum}, dNum → {dName, mgrSSN, mgrStartDate}}:
{pNumber}+ = {pNumber}
{pNumber}+ = {pNumber, pName, pLocation, dNum} using FD1
{pNumber}+ = {pNumber, pName, pLocation, dNum, dName, mgrSSN,
mgrStartDate} using FD2The second FD only became applicable after the first added dNum — the fixpoint loop in action. The closure is all of R, so pNumber is a key.
A composite LHS — showing {sName, pNum} is a superkey for SupplierPart (sName, city, status, pNum, pName, qty) with F = {sName → city, city → status, pNum → pName, {sName, pNum} → qty}:
{sName, pNum}+ = {sName, pNum}
{sName, pNum}+ = {sName, pNum, city} using sName → city
{sName, pNum}+ = {sName, pNum, city, status} using city → status
{sName, pNum}+ = {sName, pNum, city, status, pName} using pNum → pName
{sName, pNum}+ = {sName, pNum, city, status, pName, qty} using {sName,pNum} → qtyShowing it is a key rather than merely a superkey takes a second half: every proper subset must fail. {sName}⁺ = {sName, city, status} and {pNum}⁺ = {pNum, pName}, neither of which is all of SupplierPart, so nothing smaller works and {sName, pNum} is minimal. “Cover all attributes, then show each proper subset doesn’t” is the standard two-part answer whenever a question says key rather than superkey.
Key vocabulary
Everything below is defined relative to a set of FDs, and each is decided by a closure computation. See relational-keys for how the same terms are used in the relational model generally.
| Term | Definition | Test |
|---|---|---|
| Superkey | A set of attributes for which no two tuples can share the same values | S⁺ = R |
| (Candidate) key | A minimal superkey — removing any attribute breaks the superkey property | S⁺ = R and no proper subset S' ⊂ S has S'⁺ = R |
| Primary key | One candidate key, chosen as the key (only one per relation) | — (a design choice) |
| Prime attribute | An attribute belonging to any candidate key — not just the primary key | Appears in at least one candidate key |
| Non-prime attribute | Belongs to no candidate key | — |
Minimal ≠ shortest: a relation can have several candidate keys of different sizes, and every superkey contains at least one candidate key. Prime/non-prime is the distinction the 2NF and 3NF tests turn on, so it has to be computed against all candidate keys, not the primary one — see normal-forms.
Finding all candidate keys
For n attributes there are 2ⁿ subsets in the worst case, but three observations cut that down to something you can do by hand:
- An attribute that never appears on the RHS of any FD must be in every key. Nothing can ever derive it, so no set that omits it can have full closure. This is usually the fastest way in.
- Once
Sis known to be a key, skip every superset ofS. Those are superkeys, not candidate keys. - Expect more than one key. Stop only when you’ve checked every minimal combination, not at the first hit.
Worked example — R [A, B, C, D, E, F] with the FDs A → {B, C}, {C,D} → E, {A,C} → E, B → D, E → {A, B} (from week10-tutorial-applied-class-9-functional-dependencies, Section C). Note the attribute named F here has nothing to do with the usual name for the FD set:
The attribute F never appears on any RHS, so by tip 1 it belongs to every key. Among the remaining attributes the FDs form a tightly coupled cluster: A alone reaches B, C, then D (via B → D), then E; E alone reaches A, B and so everything A does; {B, C} reaches D then E then A; {C, D} reaches E then A, B. So there are four minimal ways to cover the cluster, each needing F added:
Candidate keys: {A, F}, {E, F}, {B, C, F}, {C, D, F}.
A negative example — R [A, B, C, D, E, F] with {A,B} → E, C → {B, E}, {E,D} → F. Is {A, B} a key? {A,B}⁺ = {A, B, E} — misses C, D, F, so it isn’t even a superkey. Is {A, B, C}? {A,B,C}⁺ = {A, B, C, E} — still misses D, F. The key is {A, C, D}: C → {B, E} adds B, E, then {E,D} → F adds F, giving all six attributes, and no proper subset gets there.
Superkey ≠ key — with B → C, C → B, D → {A, B, C} on R [A, B, C, D], {B, D} has full closure but is not a candidate key, because D alone already does (D⁺ = R). Every superset of D is a superkey; only D itself is the key.
Where closures get used
| Task | Closure computed |
|---|---|
Is S a superkey? |
S⁺ = R? |
Is S a candidate key? |
S⁺ = R and S'⁺ ≠ R for every S' ⊂ S |
Does R satisfy BCNF for X → A? |
Is X⁺ = R? (see normal-forms) |
Is an LHS attribute B redundant in X → A? |
(X - {B})⁺ = X⁺? (see minimal-cover) |
Is the whole FD X → A redundant? |
X⁺ computed without it still contains A? |
Does X → Y hold in a decomposed relation S? |
X ∪ Y ⊆ S and Y ⊆ X⁺ (see [decomposition]) |
See also
- functional-dependencies · normal-forms · minimal-cover · [decomposition] · 3nf-synthesis
- 2026-04-27-database-design-guidelines-and-functional-dependencies — Module 4, part 1
- week10-tutorial-applied-class-9-functional-dependencies — Sections B and C are pure closure/candidate-key drill
Conceptual Database Design
Conceptual design is everything that happens before a single table exists: deciding which slice of the world the database is about, and expressing that slice as an ER/EER diagram. It is a very important phase in designing a successful database application, and it follows a two-step procedure. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model.
The Universe of Discourse
- Step 1 — identify the Universe of Discourse (UoD): the “mini-world” the database models. A database never models everything in the world, only the part an organisation actually needs to record.
- Step 2 — convert that UoD into a data model a database can capture.
Those two steps are the whole of conceptual design in this course: the world → the UoD → the data model. Everything in entity-types-and-attributes, relationship-types and specialisation-and-generalisation is machinery for step 2.
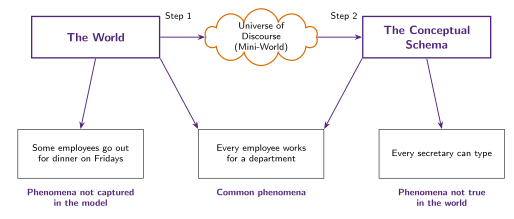
Figure 29: The two-step pipeline and the three categories of phenomena around the finished schema. The pipeline is the World → UoD → Data Model chain, and the three phenomenon boxes fan off the World and the Conceptual Schema. Only the middle box has an arrow from both, which is exactly what makes it common: true in the world and captured in the model.
The UoD is not a formality to get past. Every constraint drawn later — cardinality ratios, participation, disjointness — is read off the UoD rather than chosen arbitrarily (see relationship-constraints), so a vague or ambiguous UoD produces a diagram whose constraints can’t be justified. Where the UoD genuinely is ambiguous, that ambiguity becomes a design decision to record explicitly — see er-design-choices.
A model is never perfect
Around any conceptual schema there are three categories of phenomena (Figure 29):
| Category | Meaning | Example |
|---|---|---|
| Common phenomena | True in the world and captured in the model | “Every employee works for a department” |
| Phenomena not captured | True in the world, deliberately left out as irrelevant | “Some employees go out for dinner on Fridays” |
| Phenomena not true in the world | Captured by the model, but an over-general assumption | “Every secretary can type” |
The first category is the target. The second is fine and unavoidable — a model that captured everything would be the world itself. The third is the dangerous one: the schema will happily enforce a rule that reality violates, and the mismatch only surfaces once real data arrives.
What the ER model is for
The Entity-Relationship (ER) model provides a graphical representation of data entities, which is what makes it useful for defining a project’s scope and requirements with clients and businesses — it’s a communication artefact agreed on before implementation, not an implementation itself. Three questions run through the module: why conceptual modelling matters for designing a successful database application, how the ER model is used to do it, and how to evaluate the trade-offs between design choices by comparing alternative ER diagrams for the same system — the third of which is the whole content of er-design-choices.
An entity is a physical or conceptual object with data (attributes) associated with it. Crucially, the same real-world entity is recorded differently depending on the system’s requirements: an R&D organisation records an employee’s Degree and Field of Study, while a retail organisation records Sales Experience instead. There is no “correct” attribute list for a real-world thing in the abstract — only one that’s correct for a given UoD. See entity-types-and-attributes and relationship-types for the building blocks, specialisation-and-generalisation for the EER extension on top of them, and er-diagram-notation for the symbol legend. Reading a finished diagram back out is its own skill — interpreting-er-diagrams.
Where conceptual design sits
“Conceptual” is also the middle layer of a DBMS’s three-schema architecture (dbms-fundamentals) — the level that describes the whole database for a community of users, as opposed to any one user’s view of it. Conceptual design is where that schema gets written.
This course names no formal design lifecycle. The subject splits into three concerns, worked through in dependency order:
| Concern | Covered by |
|---|---|
| Database design — conceptual database design, then design theory and normalisation | This note, then functional-dependencies and normal-forms |
| Data models — the relational model, its integrity constraints, and ER-to-relational mapping | relational-model, integrity-constraints, er-to-relational-mapping |
| Physical storage — file organisation, hashing, indexing | Explicitly deferred to later INFS courses |
So the working pipeline is: conceptual design produces the ER/EER diagram; mapping turns it into a relational schema; SQL (sql-ddl) declares that schema; and normalisation refines it afterwards. Physical storage — the internal level of the three-schema architecture — never enters the picture here, which is exactly what physical data independence is supposed to buy.
That ordering is why conceptual mistakes are expensive. A decision that looks cosmetic on the diagram propagates into the schema and into the constraints the DBMS can actually enforce — the mapping errors dissected in week4-tutorial-case-study-3-dirt-road-driving are all downstream consequences of getting an entity’s identity or a relationship’s endpoint wrong at the conceptual stage.
Database Access Control
Access control is the DBMS’s answer to “who is allowed to do what to which data”. It’s one of four categories of database control measure, and by far the largest — three distinct authorisation mechanisms (DAC, MAC, RBAC), each with its own model and syntax. Introduced in 2026-05-11-database-security.
What security is protecting against
Threats to a database are usually framed with the CIA principle:
| Threat | Meaning |
|---|---|
| Loss of confidentiality | Unauthorised disclosure of confidential information |
| Loss of integrity | Improper modification of information |
| Loss of availability | A legitimate user cannot access data objects |
The motivations for defending against them are legal or policy-driven (government rules protecting medical records or financial ratings), ethical (who may see salary packages or student grades), and technical (malware, performance overloading).
Privacy is not the same as security
- Security concerns how access to data is controlled — availability for use, with integrity, and permitted access only.
- Privacy concerns how data may be used — an individual’s ability to control the terms under which their sensitive data is acquired and used.
Security is a required building block for privacy, but the two are distinct: privacy also covers information that can be inferred from accessible data, not only what is directly readable. Sensitive data is often double-edged — patient records are private but valuable for public-health research; CCTV audio captures private conversations but also evidence of crime — giving a utility/privacy trade-off: protect all sensitive data while making as much non-sensitive data available as possible.
The four control measures
| Measure | Purpose |
|---|---|
| Access control | Provide access only to users with the right access authority |
| Inference control | Ensure information about individuals can’t be derived indirectly (statistical databases) |
| Flow control | Prevent information flowing to unauthorised users |
| Data encryption | Protect sensitive data in transit |
The rest of this note is access control; the other three are summarised at the end.
Discretionary Access Control (DAC)
DAC is built on granting and revoking privileges — GRANT and REVOKE being SQL’s DCL family, alongside the DDL and DML of sql-ddl:
CREATE USER <username> IDENTIFIED BY "<password>";
GRANT privilegeName
ON objectName
TO {userName | PUBLIC | roleName}
[WITH GRANT OPTION];
REVOKE privilegeName
ON objectName
FROM {userName | PUBLIC | roleName};Two levels of privilege
- Account level — privileges held by an account independent of any particular relation:
CREATE SCHEMA/TABLE/VIEW,ALTER/DROP TABLE, and modification (INSERT/DELETE/UPDATE) andSELECTprivileges. - Relation level — privileges on a specific relation or view, and optionally on individual attributes: select (read), modification (insert/delete/update), and references. The
REFERENCESprivilege grants permission to create a foreign key pointing at the named table (see integrity-constraints) — worth noting because it’s a privilege about schema structure, not data access.
The three statement forms that repairing a real set of accounts needs — all three used in week12-tutorial-5-1-database-security:
-- everything the account holds on that object, in one statement
REVOKE ALL PRIVILEGES ON `schema`.`Table` FROM 'user';
-- the ability to delegate, revoked separately from the privilege itself
REVOKE GRANT OPTION ON `schema`.`Table` FROM 'user';
-- attribute level: the column list attaches to the privilege, not the object
GRANT SELECT (`fName`, `lName`) ON `schema`.`Table` TO 'user';There is no statement that narrows a privilege. Downgrading an account from ALL PRIVILEGES to SELECT is always a REVOKE ALL PRIVILEGES followed by a GRANT SELECT, and taking away someone’s grant option is a second statement on top of taking away the privilege they were delegating.
Privileges can be issued as part of schema creation:
CREATE SCHEMA AUTHORIZATION oe
CREATE TABLE Product (color VARCHAR2(10) PRIMARY KEY, quantity NUMBER)
CREATE VIEW RedProduct AS
SELECT color, quantity FROM Product WHERE color = 'RED'
GRANT select ON RedProduct TO hr;The access matrix model
Every relation is assigned an owner account, and owners may grant select/modification/references privileges on anything they own. The resulting state is an access matrix M(i, j) — the privileges user i holds on object j. Attribute-level entries appear as their own rows:
| Jake | Aiden | Nelly | Sham | |
|---|---|---|---|---|
| Customer | READ | READ | MODIFY | — |
| CustOrder | — | — | READ | — |
| CustOrder.amt | — | READ | READ | — |
| Supp.status | — | READ | MODIFY | REFERENCE |
| Supp.address | — | READ | MODIFY | MODIFY |
Building this matrix from a Universe of Discourse is what Section A of week12-tutorial-5-1-database-security asks for: read each person’s stated responsibilities, and grant the narrowest privilege that satisfies them — read-only where they only need to look, nothing at all on tables outside their remit, attribute-level SELECT where they need two columns rather than a whole table.
Propagation and revocation
REVOKE cancels a privilege, which makes temporary grants possible. The complication is delegation: if A grants a privilege to B WITH GRANT OPTION, B can grant it onward without A’s knowledge, so the DBMS must track the resulting chain of dependency:
REVOKE privilegeName ON objectName FROM userName [RESTRICT | CASCADE];CASCADE— revoke the privilege and every dependent privilege granted as a result of it.RESTRICT— refuse the revoke with an error if the privilege has already been passed on.
The governing rule is graph-shaped:
A user’s authorisation is valid iff there is a path from the root of the authorisation graph down to that user’s node.
So for u1 → u2 → u3: revoking u1’s grant to u2 also cuts off u3, because no path to u3 remains. Revoking directly from u3 leaves u2 untouched, and u2 losing authorisation never propagates upward to u1 — the grantor’s own authorisation is independent of what they’ve handed downstream.
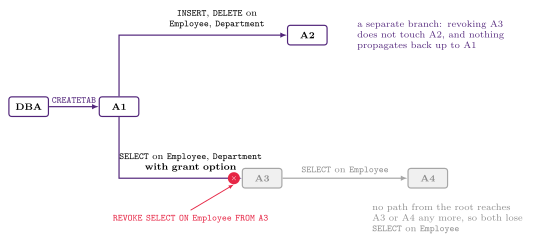
Figure 30: The A1–A4 grant chain from Worked chain below, drawn as the authorisation graph the path rule is stated over. Nothing here is a house convention. Revocation is about reachability, not about who was named in the REVOKE: A4 is never mentioned in the statement and loses the privilege anyway, purely because the edge it depended on is gone, while A2 on the untouched branch keeps everything.
Views as a security mechanism
If an owner wants to give an account a limited read capability — some columns only, or only rows meeting a condition — the idiomatic answer is to create a view and grant on the view rather than the base table (see sql-views):
-- Employee [ssn, name, dob, address, sex, salary, mgrSSN, dNum]
CREATE VIEW A3EMPLOYEE AS
SELECT name, dob, address
FROM EMPLOYEE
WHERE dNum = 5;
GRANT SELECT ON A3EMPLOYEE TO A3;A3 can now only ever see name, dob and address for department 5 — never salary, never ssn, never another department’s staff. The view is doing both column filtering and row filtering that a table-level GRANT could not express.
Worked chain
The DBA runs GRANT CREATETAB TO A1; A1 creates Employee and Department and then runs:
GRANT INSERT, DELETE ON Employee, Department TO A2;
GRANT SELECT ON Employee, Department TO A3 WITH GRANT OPTION;- Can
A3runGRANT SELECT ON Employee TO A4? Yes —A3holds the grant option. - If
A1then runsREVOKE SELECT ON Employee FROM A3, doesA4keepSELECT? No — it’s revoked by propagation; no path from the root reachesA4any more. - What kind of access control is this? Discretionary — privileges are granted and revoked at the discretion of individual account owners, not fixed by a system-wide classification (MAC) or role hierarchy (RBAC).
Mandatory Access Control (MAC)
MAC classifies both data and users into security classes to provide multilevel security. The typical classes, low to high, are Unclassified (U) < Confidential (C) < Secret (S) < Top Secret (TS). Users are subjects; data — a table, tuple, or individual attribute value — are objects.
The Bell-LaPadula model
| Property | Rule | Effect |
|---|---|---|
| Simple security property (“no read up”, NRU) | A subject can’t read an object classified above its own clearance | A U user can’t view a C-classified salary |
| Star property (“no write down”, NWD) | A subject can’t write to an object classified below its own clearance | An S-cleared user can’t insert a tuple containing only C-classified data |
“No write down” is the counter-intuitive one. It exists to stop information flowing downward: if a high-clearance subject could write into a low-classified object, the content of that write would leak higher-clearance context to lower-clearance readers.
Each tuple carries a Tuple Classification (TC) — the highest classification of any of its attribute values — and a table’s classification is in turn the highest TC of any tuple in it, which is the level the star property is applied at when someone writes to the table as a whole. A user sees a filtered version of the relation:
(a) EMPLOYEE (as stored)
Name Salary JobPerformance TC
Smith (U) 40000 (C) Fair (S) S
Brown (C) 80000 (S) Good (C) S
(b) as seen by a Confidential-clearance user
Smith (U) 40000 (C) NULL (C) C
Brown (C) NULL (C) Good (C) C
(c) as seen by an Unclassified-clearance user
Smith (U) NULL (U) NULL (U) UThere are two levels of hiding, both of which the tutorial tests:
- An individual over-classified cell inside a tuple the user can otherwise see is masked to
NULL— Smith’sJobPerformanceabove, and everyNULLin the tutorial’s Section B answers. - A tuple with nothing readable left in it disappears entirely — it is not returned as a row of
NULLs. That is why Brown vanishes from view (c): atU, none ofBrown(C),80000(S) orGood(C) is readable, so there is nothing left to show.
The exact test for the second case is worth being careful about. A high TC alone does not remove a tuple — in the tutorial, rows classified S are still returned to a C user with their S cells masked. Nor is an unreadable key enough on its own: CodeName’s key is the composite {spyID, name}, and the tutorial’s answers still return the BunnyBunny tuple to a C user with its S-classified name masked. What removes a tuple is having no readable value in it at all. A join between two tables can therefore return the empty set even when matching rows plainly exist, if every candidate pairing has at least one over-classified side — the join condition simply cannot be established at the user’s level.
Polyinstantiation
Suppose a C-clearance user, seeing view (b), runs UPDATE EMPLOYEE SET JobPerformance = 'Excellent' WHERE Name = 'Smith'. The system must not reject it — a rejection would reveal that a higher-classified value already exists, which is itself a leak (a covert channel). The resolution is polyinstantiation: keep multiple tuples with the same key at different classifications.
(d) EMPLOYEE, polyinstantiated
Smith (U) 40000 (C) Fair (S) S
Smith (U) 40000 (C) Excellent (C) C
Brown (C) 80000 (S) Good (C) SThe C user sees “Excellent”; an S-or-higher user still sees the original “Fair”. The same mechanism is why an apparent key-constraint violation can succeed in a MAC database — two “identical” tuples at different classifications are allowed to coexist.
DAC vs MAC
| Discretionary | Mandatory | |
|---|---|---|
| Flexibility | High — owners choose who gets what | Low — rigid, centrally imposed |
| Propagation control | None — once information is accessible, DAC doesn’t restrict onward sharing | Strong — classification rules enforced on every read and write |
| Protection | Weaker | Stronger — prevents illegal information flow |
Role-Based Access Control (RBAC)
Permissions attach to organisational roles; users are assigned to roles, and DAC or MAC methods are then applied to the role as a unit:
CREATE ROLE manager;
DROP ROLE manager;
GRANT ROLE full-time TO emp_typ1;
GRANT ROLE intern TO emp_typ2;
GRANT privilegeName ON objectName TO {userName | PUBLIC | roleName} [WITH GRANT OPTION];
REVOKE privilegeName ON objectName FROM {userName | PUBLIC | roleName};The typical hierarchy is users → groups → roles → privileges — e.g. alice is in group admin, which maps to admin_role, which holds ALL ON SERVER server1. RBAC’s flexibility and much easier administration (change the role, not every user) make it the popular choice for web-based applications.
Beyond access control
Inference control
A statistical database publishes aggregate statistics about a population — for government statisticians or market researchers — without exposing individual records, so only aggregate queries (COUNT, SUM, MIN, MAX, AVG, standard deviation) are permitted (see sql-aggregation-and-grouping):
SELECT COUNT(*) FROM PERSON WHERE <condition>;
SELECT AVG(Income) FROM PERSON WHERE <condition>;The risk is that a sufficiently narrow WHERE clause isolates a group small enough — possibly a single person — that the “aggregate” discloses an individual. Mitigations:
- k-anonymity — enforce a minimum number of tuples any result may be based on.
- Prohibit query sequences over the same or overlapping populations, which could be differenced to isolate an individual.
- Differential privacy — add carefully calibrated noise to results.
Flow control
Regulates the distribution of information among accessible objects, verifying that information doesn’t flow — explicitly or implicitly — into less protected objects. This is Bell-LaPadula’s “no write down” generalised beyond a single DBMS. A flow policy names the channels information may travel along; in a simple confidential (C) / nonconfidential (N) scheme, C → N flow is prohibited. Example: an income tax computing service may be allowed to retain a customer’s address, but not their income and deductions.
Data encryption
Encryption converts data into ciphertext using an algorithm and a key; recovering the original requires the corresponding decryption key. DES (Data Encryption Standard) was developed by the US government for general public use; AES (Advanced Encryption Standard) is the newer, harder-to-crack replacement.
See also
- sql-injection — the attack that bypasses all of this by making the application issue the attacker’s SQL under its own privileges
- sql-views · integrity-constraints · sql-aggregation-and-grouping
- 2026-05-11-database-security — Module 5
- week12-tutorial-5-1-database-security — DAC permission-matrix, MAC query and audit practice
DBMS Fundamentals
What a database is, what a Database Management System is layered into, and what it is (and isn’t) responsible for. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and drilled in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd.
Data, information, and where a database sits
Four definitions the course builds on top of each other:
| Term | Definition |
|---|---|
| Data | Facts and statistics collected together for reference or analysis, typically digitised |
| Information | Data put into meaningful and useful context and communicated to recipients who use it to make decisions |
| System | A set of components that interact to accomplish some purpose |
| Information system | A system that manages information |
An information system is built from five blocks — inputs, processes, outputs, databases and technology. This course is about the database block, which is where the data actually lives.
A database is a collection of related data or known facts that:
- represents some aspect of the real world — the mini-world, or Universe of Discourse (UoD);
- is a logically coherent collection of data with some inherent meaning;
- is designed, built and populated with data for a specific purpose, for an intended group of users and some preconceived applications;
- can be of any size and complexity;
- may be maintained manually or computerised.
The third point is the one that does the work later: a database is designed for a purpose, which is why design begins by fixing the UoD rather than by listing tables. See conceptual-database-design.
Data management — capturing, storing, retrieving, analysing, presenting and interpreting (large amounts of) data — is the skill the whole course is in service of. Three application sectors depend on it:
| Sector | Examples |
|---|---|
| Commerce | Cash management, pricing, employee records, purchasing, reordering, trend analysis |
| Government | Law enforcement, election commission, taxation, legal systems, transport and utilities, city councils |
| Science and engineering | Health and medicine, space exploration, geography (GIS), architecture, military and defence, telecommunications |
Banking is an example of an application area where data plays a central role.
What a DBMS is
A database management system (DBMS) is a software system that facilitates the processes of defining, constructing, manipulating and sharing databases among various users and applications. Those four verbs are the standard summary answer to “what is a DBMS”:
| Process | What it covers |
|---|---|
| Defining | Specifying the types, structures and constraints for the data — sql-ddl |
| Constructing | Storing the data on some storage medium controlled by the DBMS |
| Manipulating | Querying to retrieve specific data, updating to reflect changes in the mini-world, and generating reports — sql-select-statement, sql-dml |
| Sharing | Allowing multiple users and programs to access the database simultaneously |
The four components of a database system
The DBMS is only one piece. A database system has four:
| Component | What it is |
|---|---|
| The stored database | The collection of related information itself |
| The DBMS | The software that defines, constructs and manipulates the database |
| The applications | The programs, in specific languages, that manipulate the database |
| The users | People who use the system, either through the DBMS interface or through application programs |
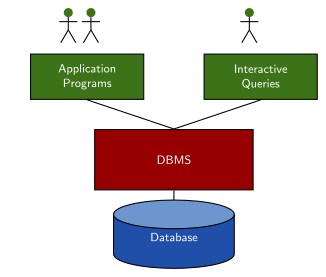
Figure 31: The database system. Users reach the stored database only through one of two front doors — an application program or an interactive query — and both go through the DBMS. Nothing touches the stored database directly.
Users are further split into database administrators, database designers, end users and application programmers. They reach the database through different interfaces by design: query languages for casual end users, programming-language interfaces for application programmers, and forms and commands for parametric users. GUIs, web-enabled interfaces, natural-language interfaces and speech I/O all sit on top of those. A parametric user is someone who runs the same canned transaction over and over.
Getting from the world to a stored database
Conceptual database design is two steps. Keep them separate before any diagram gets drawn:
- Identify the Universe of Discourse. The database will not model everything in the world, only some mini-world — see conceptual-database-design.
- Convert the UoD to a data model that a database can capture.
One example previews the whole arc of the course. An ER diagram has EMPLOYEE (attributes ID, Name, Salary) joined N:1 to DEPARTMENT (attributes Number, Name) through a WORKS FOR relationship. It maps to this relation:
Employee
| ID | Name | Salary | Department |
|---|---|---|---|
| 175 | Paris Lane | 60,000 | 2 |
| 467 | Anna Lee | 70,000 | 1 |
| 1023 | Ben Cho | 70,000 | 4 |
That one mapping is Modules 1 and 2 of this course: the conceptual model on top (entity-types-and-attributes, relationship-types) and the relational model beneath it (relational-model), joined by the mapping rules in er-to-relational-mapping. The WORKS FOR relationship has become the Department column of Employee, not a table of its own. Recognising that column as a foreign key is Module 2’s job (foreign-keys), and the reason a 1:N relationship collapses into a column is in er-to-relational-mapping.
Redundancy: the problem a designed database solves
Redundancy occurs when one fact is stored in more than one place. Take employee records split across two relations:
| ID | Name | Level |
|---|---|---|
| 1 | Paris | Developer |
| 2 | Anna | Manager |
| 3 | Ben | Manager |
| ID | Name | Salary |
|---|---|---|
| 1 | Paris | 60,000 |
| 2 | Anna | 70,000 |
| 3 | Ben | 70,000 |
Two separate facts are stored redundantly here. The ID/name pair is stored twice, once per relation. And assuming an employee’s salary corresponds directly to the level they hold, the fact “Manager earns 70,000” is stored once per manager rather than once — which is why Anna and Ben both carry 70,000 in their own row. Three costs follow:
- duplication of effort,
- wastage of storage space, and
- inconsistent data — the copies drift apart.
The design goal is therefore to minimise redundancy, not merely to store everything somewhere. The systematic machinery for doing that is functional-dependencies and normal-forms; the concrete failure modes are catalogued in update-anomalies. The other thing a database buys you over a pile of files is the ability to represent complex relationships among the data, which is what er-to-relational-mapping turns an ER diagram into.
Typical functions of a DBMS
| Function | What it means | Where it lands in this course |
|---|---|---|
| Data integrity maintenance | Defining and enforcing integrity constraints — restrictions placed on the data, based on the semantics (meaning) of the data | integrity-constraints |
| Query processing | A language simple enough to run a query and get data back in seconds, yet powerful enough to manage millions of tuples without crashing | sql-select-statement |
| Security management | Measures for securing the database against a variety of threats | database-access-control, sql-injection |
| Concurrency control | Control protocols for concurrent access to data files that guarantee serialisability | Deferred to later INFS courses |
| Backup and recovery | Recovering from hardware and software failures via the backup and recovery sub-system | Deferred to later INFS courses |
Integrity constraints are semantic — they come from what the data means, not from how it is stored. Examples: every employee must have a unique code; employee codes must be 4-digit integers; an employee must work in an existing department; an employee cannot work in multiple departments; an employee’s salary should not exceed their supervisor’s salary. Each of those is a constraint the DBMS can be told to police.
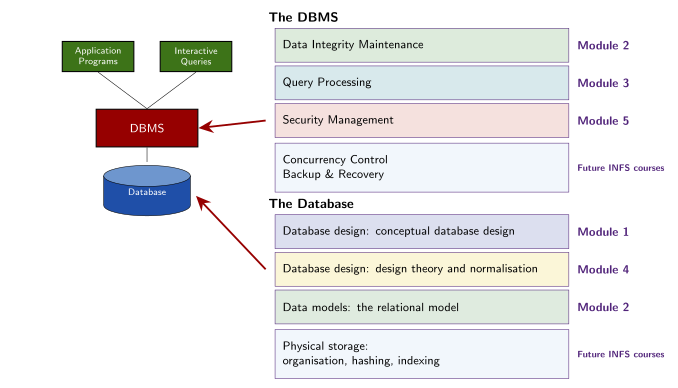
Figure 32: What the two boxes in Figure 31 decompose into, and which module of the course covers each piece: the functions of the DBMS, and what goes into designing and modelling the stored database. Everything greyed as future INFS courses is deferred to those courses.
The recovery example is the one worth remembering. A program transferring $200 from account A to account B is interrupted by a system failure partway through, so the deposit is never recorded in B. The DBMS restores the database to the state prior to the update and restarts the update program, rather than leaving the money in neither account. Concurrency control solves the neighbouring problem: thousands of people editing the same file while each assumes they are the only person using it. Serialisability is the guarantee the control protocols provide: whatever interleaving actually occurred, the result matches some order of running those accesses one at a time.
What a DBMS does — and doesn’t
The dividing line is a single rule: a DBMS enforces the design it is handed, it does not choose the design.
Enforcing integrity constraints, providing secure access, handling concurrent access, and backing up and recovering the database are all DBMS functions. Designing a database is not — and neither is normalising the relational schema (normal-forms) or recommending changes to the database design. Those are design-time decisions made by a human database designer, and no amount of running the database will make them happen by itself. In a list of candidate “DBMS functions”, the design-flavoured option is the odd one out every time.
The three-schema architecture
A DBMS describes the same data at three separate levels, so that each one can change without disturbing the others:
| Level | Describes |
|---|---|
| External level | Provides access to particular parts of the database to particular users, as one or more external views |
| Conceptual level | Describes the structure of the whole database for a community of users, as the conceptual schema |
| Internal level | Describes the physical storage structure of the database, as the internal schema |
The levels are joined by two named mappings: the external/conceptual mapping from each external view down to the conceptual schema, and the conceptual/internal mapping from the conceptual schema down to the internal schema and the stored database beneath it. The mappings are what make data independence possible — a change at one level is absorbed by re-writing the mapping rather than by rewriting the level above.
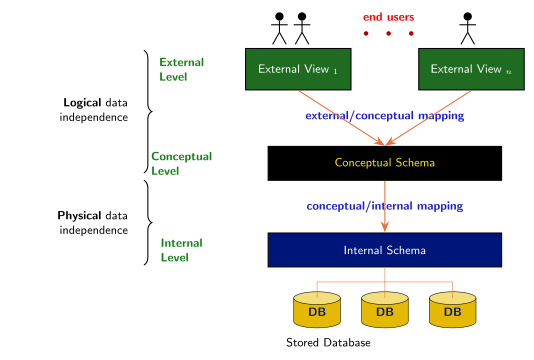
Figure 33: The three-schema architecture, with the two data-independence properties bracketed onto the level pairs they insulate. The colours — green external views, black/yellow conceptual schema, navy internal schema, gold cylinders — are the textbook’s, not INFS1200 notation; the course’s own ER house style is purple/magenta. Each independence property spans exactly one mapping: logical data independence rides the external/conceptual mapping, physical data independence rides the conceptual/internal one.
The external level is per-audience: a user or application sees the slice of the database relevant to it, not the whole thing, and SQL’s views (see sql-views) are the concrete mechanism for carving out that slice. The conceptual level is the one an ER diagram maps onto (see conceptual-database-design and relational-model), and the internal level — file organisation, hashing, indexing — is explicitly out of scope for this course.
Data independence
Data independence is the ability to change the schema at one level of a database system without having to change the schema at the next higher level. The three-schema architecture exists to deliver it in two flavours:
| Kind | What it buys you |
|---|---|
| Logical data independence | The ability to change the conceptual schema without changing the external views or the applications built on them |
| Physical data independence | The ability to modify the physical schema without changing the conceptual schema |
The course treats conceptual schema and logical schema as two names for the same middle level — physical data independence is stated interchangeably as “modify the physical schema without making changes to the logical schema”. So the two independence properties bracket that one level: logical data independence insulates the layer above it, physical data independence insulates it from the layer below.
Two claims that look right and aren’t: logical data independence is not about moving where data is physically stored (that is physical data independence), and the external level provides access to parts of the database, not the ability to change the schema of its relations. Both are distractors in multiple-choice questions. The correct statement is that physical data independence lets you modify the physical schema without changing the logical schema. The same matching is drilled in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd.
Reading
Chapters 1 and 2 of Elmasri & Navathe, Fundamentals of Database Systems (the course textbook, available online via the UQ Library). The module that follows this one is Module 1, conceptual data modelling and ER diagrams — 2026-02-23-conceptual-database-design-and-the-er-model.
Decomposition and BCNF Design
A decomposition of a relation R replaces it with two or more relations such that (1) each new relation’s attributes are a subset of R’s, and (2) every attribute of R appears in at least one of them. That’s a low bar — it says nothing about whether the pieces can be put back together, or whether the original constraints survive. This note covers the two properties that separate a good decomposition from a destructive one, and the top-down algorithm that produces BCNF relations. Introduced in 2026-04-27-database-design-guidelines-and-functional-dependencies and 2026-05-04-normalisation-and-relational-database-schema-design.
The two properties
| Property | Question it answers | Guaranteed by |
|---|---|---|
| Lossless join (non-additive join) | Can R be reconstructed exactly by rejoining the pieces? |
BCNF decomposition and 3NF synthesis |
| Dependency preservation | Can every original FD still be checked against a single relation? | 3NF synthesis only |
Lossless join is non-negotiable — a decomposition that fails it has corrupted the data. Dependency preservation is desirable but sometimes unattainable in BCNF, which is the whole reason 3NF remains in use.
Lossless join and spurious tuples
The natural join R1 ⋈ R2 concatenates each tuple of R1 with every tuple of R2 that agrees on their common attributes (see sql-joins). A decomposition of R into R1 and R2 is a lossless join decomposition if, for every legal instance,
\[R = R_1 \bowtie R_2\]
— breaking R apart and rejoining gives back exactly R, no more and no less.
A lossy decomposition — split R [A, B, C] into R1 [A, B] and R2 [B, C] when B does not determine C:
R R1 R2 R1 ⋈ R2 (rejoined)
A B C A B B C A B C
1 2 3 1 2 2 3 1 2 3
4 5 6 → 4 5 + 5 6 → 1 2 9 <- spurious!
7 2 9 7 2 2 9 4 5 6
7 2 3 <- spurious!
7 2 9“Loss” here means loss of information, not loss of tuples — the rejoined relation has more rows than the original. A better name for the failure would be “addition of spurious information”. Because B = 2 maps to two different C values, the join can’t tell which A belongs with which C, and invents both combinations. Those extra rows are the spurious tuples that guideline 4 of update-anomalies warns about.
Note what would have saved it: if B → C held, each B value would match exactly one R2 row, no A could pair with two Cs, and the join would return exactly R. That is the whole idea — a split is safe when the attributes the two pieces share functionally determine one of them.
Testing for a lossless join
There is no general algebraic test in this course — no tableau or chase procedure, and no separately named binary-decomposition rule to quote. Two things stand in for it, and between them they cover everything the course asks:
1. The structural guarantee, when you built the decomposition yourself. The BCNF algorithm below always splits Q on an FD X → Y into Q1 [Q - Y] and Q2 [X ∪ Y]. The two pieces share exactly X, and X is a key of Q2 — so every Q1 tuple matches at most one Q2 tuple, the join can never multiply rows, and the result is lossless by construction. This is also the answer to “justify why lossless-join decompositions are preferred”: they are the only ones that don’t silently fabricate data.
2. The counter-example test, when you’re handed a decomposition and asked whether it works. Build a small instance of R that satisfies F, project it onto the proposed pieces, natural-join them back, and look for a row that wasn’t in R. A single spurious tuple settles the question; no exhaustive argument is needed.
Worked example — R [A, B, C, D] with A → B, C → D, {A,D} → C, {B,C} → A. Is {{A,B}, {A,C}, {B,D}} a lossless-join decomposition?
R A B A C B D
A B C D 1 2 1 5 2 6
1 2 5 6 → 8 2 1 3 2 7
1 2 3 7 8 9 2 4
8 2 9 4Rejoining [A,B] ⋈ [A,C] ⋈ [B,D] gives nine rows, including (1, 2, 3, 4) — never in R. The decomposition is lossy. The reason is visible without the instance: [A,B] and [B,D] meet only on B, and B determines neither piece, so every A gets paired with every D. Replacing [B,D] with [C,D] fixes it — the pieces then chain on A and on C, and each of those is a key of the piece it determines.
Which FDs hold in a decomposed relation
To test a piece for a normal form, or to check dependency preservation, you first need the FDs that apply to it. For a decomposed relation S and an FD X → Y from the original F:
X → Yholds inSifX ∪ Y ⊆ S’s attributes andY ⊆ X⁺, whereX⁺is computed against all ofF— including attributes that aren’t inS.
The second condition is the one that’s easy to get wrong: attributes outside S may still be used as intermediates in the derivation.
Worked example — R [A, B, C, D, E] with {A,B} → C, {B,C} → D, {C,D} → E, {D,E} → A, {A,E} → B. Which FDs hold in S [A, B, C, D]?
{B,C,D} → A does. Computing {B,C,D}⁺ against the full F: {B,C} → D adds nothing new; {C,D} → E adds E (an attribute not in S); {D,E} → A then adds A. So A ∈ {B,C,D}⁺, and both sides sit inside S — the FD holds. By contrast {A,B} → E and {A,E} → B both fail the first condition: E isn’t an attribute of S at all.
Dependency preservation
When R is decomposed into R1, …, Rn, the FD set F is decomposed alongside it into F1, …, Fn, where Fi contains all the FDs in F whose attributes fall entirely within Ri. The decomposition is dependency preserving if
\[(F_1 \cup \dots \cup F_n)^{+} = F^{+}\]
— no FD information is lost, so every original constraint can still be enforced by checking a single relation, with no join required.
Testing it
The set-closure equality is never computed directly. One direction is free (every Fi ⊆ F, so (∪Fi)⁺ ⊆ F⁺ always), which leaves a finite check on the other:
- For each piece
Ri, write downFi— the FDs ofFwith both sides entirely insideRi. An FD that straddles two pieces belongs to neither. - Union them into
G = F1 ∪ … ∪ Fn. - For each FD
X → Yin the originalF, computeX⁺using onlyG. IfY ⊆ X⁺for every one of them,G⁺ = F⁺and the decomposition is dependency preserving. The first FD that fails is the one that was lost.
Step 3 matters because an FD absent from every Fi may still be recoverable by chaining the ones that survived — only an FD that G cannot derive at all is genuinely lost.
Two minimal examples — R [A, B, C, D] with F = {A → B, A → D}:
| Decomposition | F1 |
F2 |
Verdict |
|---|---|---|---|
R1 [A, B, C], R2 [B, C, D] |
{A → B} |
∅ |
A → D is not preserved — A and D never appear together |
R1 [A, B, C], R2 [A, B, D] |
{A → B} |
{A → D} |
All FDs preserved |
The difference is only where A was placed. Dragging the LHS along into the second piece is what keeps its FD checkable, and it is the instinct 3nf-synthesis turns into an algorithm: give every FD in the cover its own relation X ∪ Y, and preservation is automatic.
A BCNF decomposition that loses one — Teach [studentID, courseID, lecturer] with {studentID, courseID} → lecturer and lecturer → courseID. The second FD violates BCNF, so split into [lecturer, courseID] and [studentID, lecturer]. Each piece is now in BCNF and neither violates any FD locally — but rejoin them:
lecturer courseID studentID lecturer
John INFS1200 1234 John
Jane INFS1200 1234 Jane
↓ join ↓
studentID courseID lecturer
1234 INFS1200 John
1234 INFS1200 JaneThe result violates the original {studentID, courseID} → lecturer: two rows share {1234, INFS1200} but disagree on lecturer. The FD survived nowhere, so nothing was there to reject the insert.
BCNF vs 3NF:
| BCNF | 3NF | |
|---|---|---|
| Removes all anomalies | ✅ | ❌ |
| Preserves all FDs | ❌ | ✅ |
Organisations pick one or the other depending on which guarantee matters more for the workload.
The design landscape
Two complementary algorithms turn a universal relation (all attributes lumped together, plus a set of FDs) into a well-designed multi-relation schema — the third route being to derive the schema from an EER diagram in the first place (see er-to-relational-mapping):
flowchart LR
U["Universal Relation + FDs"] -->|decomposition| RDB[("Relational DB schema")]
E["EER Diagram (from UoD)"] -->|mapping| RDB
A["All attributes + FDs"] -->|synthesis| RDB
- Decomposition (top-down) — design by analysis. Start from the universal relation and its FDs and break it apart until every piece is in BCNF. Lossless-join and anomaly-free; may lose FDs. Covered below.
- Synthesis (bottom-up) — design by synthesis. Start from the individual attributes and the FDs, and build relations up from a minimal-cover. Lossless-join, dependency-preserving and 3NF. See 3nf-synthesis.
Both approaches are non-deterministic — the answer depends on choices made along the way — and both are only as good as their input: a missing FD leads to a sub-optimal or outright incorrect design, which is why the FDs have to come from the Universe of Discourse rather than from a sample instance (see functional-dependencies).
The BCNF decomposition algorithm
D := {R};
while (some relation Q in D is not in BCNF):
find an FD X → Y in Q that violates BCNF;
replace Q in D with Q1 [Q - Y] and Q2 [X ∪ Y];Why it works. After the split, X → Y can no longer violate BCNF in either piece: Q1 doesn’t contain Y any more, so the FD isn’t there to test; and in Q2, X is a key, so the FD passes. Do that to every offending FD in turn and every violation is eventually fixed. The algorithm terminates because every two-attribute relation [a, b] is automatically in BCNF — with no FD there’s no redundancy, with a → b then a is a key, with b → a then b is, and with both, both are. Q2 is also what makes the result lossless: X keys it, so the rejoin on X can never multiply rows.
Results can vary depending on the order violating FDs are processed in. That’s fine: several correct decompositions can exist for the same relation, and they may preserve different sets of FDs.
Worked example — R [A, B, C, D] with B → C and D → A. {B,D}⁺ = {A,B,C,D}, and it’s the only key.
B → Cviolates BCNF (Bisn’t a superkey) → replaceRwithR1 [A, B, D]andR2 [B, C].D → Anow violates BCNF inR1(Disn’t a key forR1) → replace it withR3 [B, D]andR4 [A, D].
Final: R2 [B, C], R3 [B, D], R4 [A, D].
Skip FDs that don’t violate — R [A, B, C, D, E, F] with A → {B,C}, C → {D,E}, E → F. Here A is the only candidate key, so A → {B, C} does not violate BCNF and must be left alone; the first genuine violation is C → {D, E}.
Implicit FDs matter
When testing a relation for BCNF you must consider implied FDs too, not only the explicitly listed ones. The reliable habit is to make them explicit before you start: compute every closure in step 1, and whenever F ⊨ X → Y for some X → Y not written down, add it to F and treat it like any other candidate violation.
Worked example — R [A, B, C, D, E, F] with A → B, {D,E} → F, B → C (the attribute called F is unrelated to the FD set F). Closures: {A}⁺ = {A,B,C}, {B}⁺ = {B,C}, {D,E}⁺ = {D,E,F}; the only key is {A,D,E}. Since F ⊨ A → C, that FD joins the set. Then:
A → Bviolates →R1 [A, C, D, E, F],R2 [A, B]{D,E} → Fviolates inR1→R3 [A, C, D, E],R4 [D, E, F]A → Cviolates inR3→R5 [A, D, E],R6 [A, C]
Final: R2 [A, B], R4 [D, E, F], R5 [A, D, E], R6 [A, C]. Miss the implied A → C and you stop one step early with R3 wrongly declared BCNF.
The same trap appears mid-algorithm. Returning to the A → {B,C}, C → {D,E}, E → F relation above: splitting on C → {D, E} gives [C, D, E] and [A, B, C, F]. No explicit FD obviously violates BCNF in [A, B, C, F] — but the implicit C → F (from C → E and E → F) does, since C isn’t a superkey of it. Splitting again gives [C, F] and [A, B, C].
Final: [C, D, E], [C, F], [A, B, C] — and note E → F is now lost, since E and F never appear together in any final relation.
Common mistakes
From week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis and the decomposition-tree question in 2026-05-04-normalisation-and-relational-database-schema-design:
- Dropping part of the violating FD’s RHS — splitting on
C → {D, E}produces[C, D, E], not[C, E]. - Removing the wrong attributes from the remainder —
Q1isQ - Y, so only the RHS leaves. SplittingR [A,B,C,D,E]on{A,D} → Bleaves[A, C, D, E], not[A, B, C, E]. - Splitting on an FD that no longer violates anything — once
Ais a key of the sub-relation you’re looking at,A → Eis not a violation and must not be split on. - Not checking the result is lossless. For
R [A, B, C, D]withA → B,C → D,{A,D} → C,{B,C} → A(keys{A,D},{A,C},{B,C}), running the algorithm onA → BthenC → Dgives the correct{A,B},{A,C},{C,D}. The plausible-looking{A,B},{A,C},{B,D}is lossy — see the counter-example test above.
Extra FDs don’t guarantee extra survivors, either. On R [A, B, C, D, E], the FD set {A → B, C → {D,E}} and the larger set {A → B, C → {D,E}, {A,D,E} → C, {B,C} → A} decompose to exactly the same three relations [A,B], [C,D,E], [A,C] — the two extra FDs in the second case are simply lost, since their attributes never all end up together in one final relation.
See also
- normal-forms · 3nf-synthesis · minimal-cover · attribute-closure
- update-anomalies — guideline 4 and the informal view of spurious tuples
- 2026-05-04-normalisation-and-relational-database-schema-design — Module 4, part 2
- week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis · week11-tutorial-case-study-9-payroll-system — practice
Entity Types and Attributes
The two smallest building blocks of an ER diagram: the kinds of thing a database records, and the facts it records about them. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd; see er-diagram-notation for the symbols and the naming style guide.
Entity, entity type, entity set
Three words that are easy to blur together, and are worth keeping apart:
| Term | Meaning |
|---|---|
| Entity | A physical or conceptual object with data associated with it — one particular student, one particular chef |
| Entity type | The format for the data that needs to be recorded to represent a particular entity — described by its name and its attributes. Drawn as a rectangle with attribute ovals attached |
| Entity set | The collection of all entities of one entity type in the database at any point in time |
The entity type is the schema-level thing (it doesn’t change as data comes and goes); the entity set is the instance-level thing (it changes with every insert and delete). The entity set is what becomes a table once the diagram is mapped — see er-to-relational-mapping.
Which attributes an entity type carries is decided by the UoD, not by the real-world object: an R&D organisation records an employee’s Degree and Field of Study where a retail organisation records Sales Experience instead. See conceptual-database-design.
Kinds of attribute
Attributes are classified along several independent axes — an attribute can be composite and multivalued, key and composite, and so on:
| Kind | Meaning | Example |
|---|---|---|
| Simple | Can’t be meaningfully split further | Email, DoB |
| Composite | Divides into smaller parts which are simple attributes with independent meaning | Name → Fname, Mname, Lname; Address → Number, Sname, Suburb, Pcode |
| Single-valued | Holds at most one value per entity | DoB |
| Multivalued | Can hold more than one value per entity (double-lined oval) | Degree — one person can hold several; Specialisations, Ingredients, Locations |
| Stored | Physically recorded | BirthDate |
| Derived | Computed from another stored attribute (dashed oval) | Age from BirthDate; Number_of_employees on a department |
| Key | Value is unique across the whole entity set (name underlined) | StudentID, Ssn |
A single EMPLOYEE entity type can carry every kind at once:
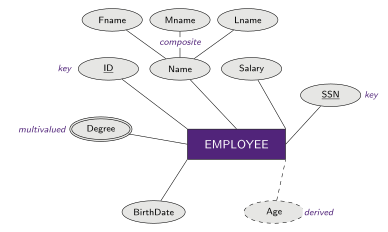
Figure 34: Every kind of attribute on one EMPLOYEE entity type. ID and SSN are two independent key attributes (solid underline). Name is composite — it fans out into Fname/Mname/Lname, and the parent oval itself is unmarked. Degree is multivalued (double outline): one person can hold several degrees. Age is derived from BirthDate, so it gets a dashed outline and a dashed connecting line, and it is never stored.
The single/multivalued split is stated over simple attributes — a composite attribute’s multiplicity is really a property of its components. The distinction between composite and multivalued is the one that catches people out: Name splitting into first/middle/last is composite (one name made of parts), whereas Phone on a student is multivalued (several independent phone numbers). Both attach several ovals to the diagram, but they mean different things and map differently.
Key attributes and candidate keys
Every entity type has at least one key constraint (equivalently, a uniqueness constraint), carried by a key attribute whose value is distinct for each individual entity in the entity set. Two properties matter:
- Multiple keys are possible. An entity type can have several independent candidate keys, each underlined in its own oval — the
EMPLOYEEabove carries bothIDandSSN. Elsewhere in the course: aDISHidentified by either itsNameor itsNumber, aVENUEby either itsIDor the combination ofNameandAddress, aVACCINEby either itsIDorBrand+Name. Any claim that an entity is “only identifiable by X” is false as soon as a second key oval is on the diagram. - A key must hold for every possible extension of the entity type. It isn’t enough that the current data happens to have no duplicates; the key must be a rule about every state the entity set could ever reach.
A composite key is a combination of simple attributes that together must be unique — a car’s Registration = State + Number, alongside a separate simple key VehicleID. On the diagram this is drawn as one underlined parent oval that splits into its component ovals, which is how you can tell “these two attributes are jointly a key” apart from “these are two separate keys”:
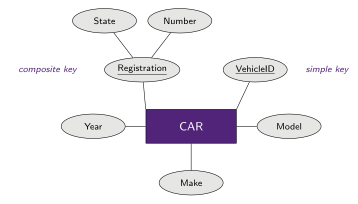
Figure 35: A CAR entity type with two candidate keys side by side: the composite Registration (underlined parent oval, splitting into State and Number — neither of which is unique alone) and the simple VehicleID. Year, Model and Make are ordinary attributes. Which of the two candidate keys is chosen as the primary key is deferred to the mapping stage, and changes the resulting schema — see er-to-relational-mapping.
The single exception to “every entity type has a key” is the weak entity, which has no key attribute of its own and is identified by its owner’s key plus its own partial key — see relationship-constraints. See also relational-keys for the same idea stated over relations rather than entity types.
Value sets and nulls
An attribute’s value set specifies the set of values that may be assigned to that attribute of an entity — employeeAge: integers between 21 and 65; vehicleRegistrationNum: a string of three alphabetic characters followed by three integers. Value sets are never displayed on the ER diagram itself — they resurface later as the domains of the relational-model, enforced as the domain constraint among the integrity-constraints.
A particular entity may not have an applicable value for an attribute, and a null value is used to represent that. Three reasons a null appears are worth keeping apart, because they are different facts about the world:
| Reason | Example |
|---|---|
| Not applicable | tertiaryDegree for a person with no university education |
| Not known whether it exists | homePhone |
| Missing — exists, but not recorded | height |
Nulls are the reason an attribute being “optional” is a real modelling decision rather than an afterthought; see sql-nulls for how they behave once queried.
Why the attribute kind matters later
The classification isn’t decorative — each kind maps differently:
- A multivalued attribute becomes its own relation, keyed on the owner’s key plus the value itself:
Staff’s multivaluedPhonebecomesStaffPhone [id, phone]. It has to — a relational column holds one atomic value (relational-model). Leavingphoneout of that key would cap each staff member at one phone number, defeating the point of making it multivalued in the first place. - A derived attribute is computed on demand, so it gets no column of its own: a trip’s
Fareis derived from its start and end times and simply doesn’t appear in the mappedTriprelation. - A composite attribute is flattened into its simple components (
Name→firstName,middleName,lastName).
All three are worked through in week4-tutorial-case-study-3-dirt-road-driving; the mapping rules themselves live in er-to-relational-mapping.
ER Design Choices
When modelling complex organisations, a database designer faces design choices: two people modelling the same Universe of Discourse will not draw the same diagram, and that isn’t necessarily a sign either of them is wrong. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Equivalent vs inequivalent choices
- Equivalent choices — an aspect of the UoD can be represented in an ER diagram by two different methods which are both equivalent, i.e. the resulting database will be the same. Genuinely a matter of taste; pick either.
- Inequivalent choices — the UoD is slightly ambiguous, and an aspect of it can be mapped two different ways which both meet the specification of the UoD but lead to different limitations/constraints being enforced by the database. Here the choice has consequences, and the right move is to pick one and note the assumption under the diagram.
That second case is the reason a diagram is rarely a complete answer on its own. The medical-clinic model in week3-tutorial-applied-class-2-entity-relationship-diagrams carries the explicit assumptions “every patient in the DB has made an appointment” and “every clinic has at least one doctor” — neither is stated in the brief, both change the participation constraints, so both get written down rather than smuggled into the drawing.
The four common choice points
| Choice | The question | Worked example |
|---|---|---|
| Attribute vs (weak) entity type | Is this a fact about something, or a thing in its own right? | An interview’s Details (Department, Date) as a key attribute of the APPLIES relationship, vs. a separate weak INTERVIEW entity |
| Attribute vs subclass | Is this a value, or a kind? | EMPLOYEE.Type as a plain attribute, vs. splitting into SECRETARY / ENGINEER subclasses |
| Subclass relationship vs superclass relationship | Does this relationship apply to everyone, or only to one kind? | Giving WORKSON (to PROJECT) to the EMPLOYEE superclass, vs. only to ENGINEER |
| Binary relationships vs n-ary relationships | Does the association hold between pairs, or genuinely among all three at once? | SUPPLIER / PROJECT / PART as three binaries (SUPPLIES, CANSUPPLY, USES) vs. one ternary SUPPLIES carrying a quantity |
Each row is a real fork, not a stylistic one:
- Attribute vs entity type. Pulling something out into its own entity type gives it identity — it can then be referred to, counted, and given relationships of its own. The cinema model in the same applied class makes exactly this call about a
VIEWING: it can be read as a weak entity owned byCUSTOMER+MOVIEwithTimestampas its partial key, or as an M:N relationship carryingTimestampas a key attribute. Both fit the brief; they differ in whether a viewing is a thing or a link. (interpreting-er-diagrams shows the reading side of the same call: without a distinguishing attribute, a plain M:N pair can only be recorded once.) - Attribute vs subclass. A subclass earns its place when the subtypes have different attributes or relationships —
SECRETARYrecording aTypingSpeedthat means nothing for an engineer. If the only difference is the label itself, a plain attribute says the same thing with less diagram. Applied class 2 gives the efficiency half of the argument explicitly: subclasses let a data attribute be stored for some entity instances rather than all of them, and so reduce the number of null/empty values — not everySHOWneeds aRating, onlyENTERTAINMENTshows do. See specialisation-and-generalisation. - Binary vs n-ary. Three binary relationships and one ternary relationship are not interchangeable: the binaries record that a supplier can supply a part and that a project uses a part, while the ternary records the specific fact that this supplier supplied this part to this project. Splitting a genuinely three-way fact into pairs loses information; forcing a ternary where only pairwise facts exist invents it. See relationship-types.
- Subclass vs superclass relationship. Attaching a relationship higher up the hierarchy widens what the schema will accept. That looks harmless on a diagram and is not harmless afterwards — see below.
Worked example: attribute vs weak entity type
A candidate applies to a company, and each application involves an interview with a department on a date. Both diagrams below satisfy that description. The world does not choose between them.
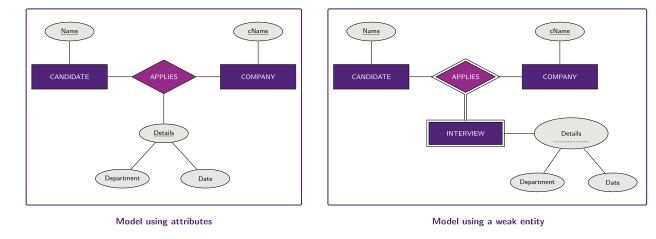
Figure 36: Attribute vs. (weak) entity type: two models of the same description. Left: the interview details hang off the APPLIES relationship as a composite key attribute Details (solid underline) made of Department and Date. Right: the interview becomes a thing — a weak entity owned by both CANDIDATE and COMPANY, so APPLIES becomes an identifying relationship (double diamond, double line into the weak entity) and Details demotes from key attribute to composite partial key (dotted underline). Nothing else on the diagram moves.
The two are alternatives, and the choice between them looks cosmetic. It stops looking cosmetic the moment the UoD says an interview results in a job offer: an attribute cannot be the endpoint of a relationship, so only the weak entity can carry a RESULTSIN link to a JOBOFFER entity. That extended diagram is drawn in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Worked example: binary vs n-ary relationships
Suppliers, projects and parts. Modelled as three binary relationships — a supplier supplies a project, a supplier can supply a part, a project uses a part:
flowchart TD
SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
SUPPLIES ---|"P"| PROJECT[PROJECT]
SUPPLIER ---|"M"| CANSUPPLY{CANSUPPLY}
CANSUPPLY ---|"N"| PART[PART]
PROJECT ---|"P"| USES{USES}
USES ---|"N"| PART
sName(["sName (key)"]) --- SUPPLIER
projName(["projName (key)"]) --- PROJECT
partNo(["partNo (key)"]) --- PART
Modelled as one ternary relationship, with all three lines running into a single diamond that can then carry a quantity:
flowchart TD
SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
SUPPLIES ---|"P"| PROJECT[PROJECT]
SUPPLIES ---|"N"| PART[PART]
SUPPLIES --- quantity(["quantity"])
sName(["sName (key)"]) --- SUPPLIER
projName(["projName (key)"]) --- PROJECT
partNo(["partNo (key)"]) --- PART
The quantity is the tell. It is a fact about a supplier-project-part triple, so there is nowhere to put it in the binary model — hanging it on SUPPLIES there would record how much a supplier sent a project without saying of what. This is the inequivalent case: the two diagrams do not produce the same database.
Worked example: subclass vs superclass relationship
EMPLOYEE specialises disjointly into SECRETARY and ENGINEER, and somebody works on projects. Which box does WORKSON attach to?
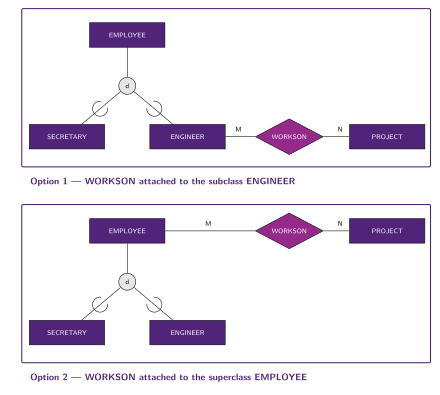
Figure 37: Subclass relationship vs. superclass relationship, reduced to the fragment where the two options differ. Option 1 attaches WORKSON to the subclass ENGINEER; Option 2 attaches it to the superclass EMPLOYEE. The rest of the company diagram (MANAGES, WORKSFOR, CONTROLS and DEPARTMENT) is the same under both options and is left out so the one difference is visible.
This is the clearest inequivalent choice of the four. Option 1 says only engineers work on projects — secretaries cannot be recorded on one at all. Option 2 says anyone may. Both satisfy a brief that only ever mentions engineers working on projects, but they enforce different things: Option 2 will happily accept a secretary on a project, and Option 1 will refuse an engineer’s promotion out of the subclass without also dropping their project assignments. Attaching a relationship higher up the hierarchy always widens what the schema will accept.
Why the choice matters after the diagram
A conceptual choice becomes a constraint the DBMS can or cannot enforce once the diagram is mapped. The clearest example is the third mistake in week4-tutorial-case-study-3-dirt-road-driving: mapping a trip’s driver as a reference to Staff rather than to Driver lets an admin-only staff member be recorded as a trip’s driver, because the schema no longer knows that a driver is a driver. The diagram-level decision about which class a relationship attaches to is the same decision as the schema-level decision about which relation the foreign key points at.
This is also why an assumption noted under a diagram is worth marks and worth memory: it’s the record of a constraint that the notation alone couldn’t distinguish. Once the schema exists, refining it further is a different exercise with different tools — see functional-dependencies and normal-forms for redundancy-driven refinement, and conceptual-database-design for where in the pipeline each one sits.
ER Diagram Notation
Reference legend for the symbols used across every ER/EER diagram in this course — introduced across 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices.
The notation below is the mandatory standard: it is what the lectures’ own notation guide specifies, and it is what assignments and the exam are marked against. (The separately published INFS1200/7900 EER & ER Notation Guide handout only standardises naming — see the style guide at the bottom of this note — and explicitly defers the symbols themselves to the lecture material.)
Core symbols
| Symbol | Meaning |
|---|---|
| Rectangle | Entity type |
| Double-line rectangle | Weak entity type (no key attribute of its own) |
| Oval | Attribute |
| Oval, name underlined | Key attribute |
| Oval, name underlined with a dotted line | Partial key attribute (weak entity’s own distinguishing attribute) |
| Double-line oval | Multivalued attribute (can hold more than one value) |
| Dashed oval, attached by a dashed line | Derived attribute (computed from another stored attribute, e.g. Age from BirthDate) |
| Diamond | Relationship type |
| Double-line diamond | Identifying relationship type (connects a weak entity to its owner entity) |
- Composite attribute: an attribute with its own sub-attributes attached (e.g.
Namesplitting intoFirstName/MiddleName/LastName) — the parent attribute oval isn’t underlined/dashed/doubled itself unless it’s also a key/derived/multivalued attribute. - Value sets (the domain of legal values for an attribute, e.g. “integers 21-65”) are never shown on the diagram itself.
Relationship constraints
| Symbol | Meaning |
|---|---|
1, N, M on the lines into a diamond |
Cardinality ratio — E1 —1— R —N— E2 reads as ratio 1:N for E1:E2 in R |
| Double line between an entity type and a diamond | Total participation of that entity type in that relationship |
| Single line | Partial participation |
See relationship-constraints for what each ratio and each participation constraint actually asserts.
Subclasses / superclasses (EER)
A subclass is drawn as an ordinary rectangle. What makes it a subclass is the ⊂ symbol on the line joining it to its superclass, not the shape of its box — a subclass box is a plain single-line rectangle, never the double-line rectangle that means weak entity. The two are entirely different ideas (a subclass inherits its superclass’s key; a weak entity has no key of its own at all) and the notation keeps them apart.
| Symbol | Meaning |
|---|---|
⊂ on the line between two entity types |
The entity type on the closed (narrow) side of the ⊂ is a subclass of the one on the open (wide) side — read it as the set-inclusion symbol, subclass ⊂ superclass |
A circle joining several subclass lines to one superclass, each line carrying its own ⊂ opening towards the circle |
Several entity types are all subclasses of the same superclass |
d inside that circle |
Disjoint specialisation — an entity instance can belong to at most one of the subclasses |
o inside that circle |
Overlapping specialisation — an entity instance can belong to more than one subclass at once |
| Single line from superclass to the subclass circle | Partial specialisation — not every superclass instance needs to belong to a subclass |
| Double line from superclass to the subclass circle | Total specialisation — every superclass instance must belong to at least one subclass |
Naming conventions (INFS1200/7900 style guide)
Course-specific naming standard for entities/relationships/attributes on ER and EER diagrams (distinct from — and in addition to — the mandatory notation above):
- Entity names: capitalised, no spaces, ideally one word (e.g.
STUDENT,POLICEOFFICER— notPoliceOfficer). - Relationship names: capitalised, no spaces, ideally one word, preferably a verb (e.g.
CREATES,ACTSIN— notLeadActor). - Attribute names: UpperCamelCase — first letter of each word capitalised, no spaces, acronym letters stay capitalised (e.g.
ComputerIP,DateOfBirth— notDate of Birth).
How diagrams are drawn in these notes
Diagrams in this course’s notes are drawn as Mermaid flowchart graphs (renders in both PDF and HTML), using shapes chosen to match the Chen notation above as closely as Mermaid’s flowchart shapes allow:
| Mermaid shape | Used for |
|---|---|
[Entity] (rectangle) |
Entity type — and subclasses, which are ordinary rectangles |
[[WeakEntity]] (subroutine, double vertical bars) |
Weak entity type, and nothing else |
{Relationship} (diamond/rhombus) |
Relationship type |
([Attribute]) (stadium) |
Attribute |
((d)) / ((o)) (small circle) |
Disjoint/overlapping specialisation marker |
The [[X]] shape is reserved for weak entity types. Drawing an EER subclass with it is a notation error, not a stylistic one: it renders the double-line box that the official notation uses for a weak entity, and so asserts the opposite of what a subclass is. Subclasses are plain [X] rectangles; their subclass-ness is carried by the edge into the ((d)) or ((o)) circle, exactly as the ⊂ carries it in the hand-drawn notation.
Since Mermaid can’t reliably underline/dash node text across renderers, attribute qualifiers are written as a plain-text suffix instead: (key), (partial key), (derived), (multi). Composite attributes are drawn as a parent attribute node connected to its component attribute nodes. Cardinality is a text label on the edge ("1", "N", "M"); total participation/identifying relationships use a thick edge (===/==>), partial participation uses a thin edge (---/-->).
Any diagram with more than ~6-8 nodes needs an explicit %%| fig-width: cell option (in inches) or it runs off the right edge of the PDF page - mermaid sizes itself from the diagram’s own SVG bounding box, and there’s no project-wide default that reaches it (a document/project fig-width only applies to executed-code-cell figures, e.g. matplotlib). 5.5 fits this vault’s PDF page width (scrartcl, DIV=11, letter) comfortably:
```{mermaid}
%%| fig-width: 5.5
flowchart TD
...
```ER Mapping Pitfalls
A checklist for reviewing a finished relational schema — every item here is a mistake actually made and corrected in week5-tutorial-applied-class-4-entity-relationship-mapping, week4-tutorial-case-study-3-dirt-road-driving or the worked questions in 2026-03-16-er-to-relational-mapping. The mapping rules themselves are in er-to-relational-mapping; this is what to check after applying them.
Keys
Most of this section is one question asked five ways: what exactly is this relation’s primary key? (relational-keys).
A weak entity’s partial key is not a foreign key. For a weak CITY owned by PROVINCE, the correct mapping is Cities [cName, pName, mayor] with only Cities.pName references Provinces.pName. cName is the city’s own partial key — it references nothing. Declaring both columns as foreign keys is wrong.
A weak entity’s key includes its owner’s key. Mapping Cities [cName, mayor], keyed on cName alone, silently asserts that city names are globally unique — which is precisely the assumption that made CITY weak in the first place.
An ordinary 1:N foreign key is not part of the primary key. For A —N R 1→ B, the answer is A [a, b, d] keyed on a alone, with A.b references B.b as a plain column. Promoting b into A’s key is weak-entity treatment applied to a strong entity. (The genuine exception is an entity with no key of its own, identified through its owners — see foreign-keys.)
A composite foreign key is one constraint, not several. The cinema schema must say
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}and not four separate single-column constraints. Splitting it breaks the link to the specific Viewing row: nothing then forces all four columns to match one real viewing rather than four unrelated ones. In the same botched attempt, name was pointed back at Movie rather than Viewing — a foreign key meant to identify which viewing a snack belongs to must target Viewing.
When the owner’s key is composite, the inherited foreign key is composite. Branch’s key is (bankCode, branchNo), so accounts and loans at a branch carry both columns: Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}.
Relations that shouldn’t exist
An identifying relationship never becomes a relation. A weak entity is connected to its owner purely through the inherited key. Inventing an In [cName, pName] relation alongside the weak entity’s own is a distinctive wrong answer.
1:1 and 1:N relationships don’t get their own relation by default. They are foreign keys on an existing relation. Creating an S [b, c] relation for a 1:N relationship S treats a relationship type as an entity type. (Doing this deliberately for a sparse relationship, to avoid nulls, is a different matter — a considered choice, not the default rule.)
Two entity types don’t merge into one relation. Collapsing S and T into ST [a1, b1] because they happen to be in a 1:1 relationship discards a conceptual modelling decision that was made on purpose.
Nor does a relationship simply vanish. Mapping S —1:1 R— T to S [a1], T [b1] with no foreign key anywhere loses all information about R.
Choosing sides
For 1:1, put the foreign key on the total-participation side. If every department has a manager but only some employees manage, extend Department. Choosing the other side doesn’t lose information, but it fills the column with nulls, and the course’s rule is to prefer the total-participation side. Between a schema putting b1 into S and one putting a1 into T, the first is correct for exactly one reason: S is preferred over T because it has full participation.
For 1:N, the foreign key goes on the N side — no judgement involved. In a chain A —N R 1→ B —N S 1→ C, that means A references B and B references C; each arrow is decided independently by where the N is.
For N-ary, only the many-sides make the key. All participants get foreign keys, but a 1-side participant’s foreign key is a plain attribute — and if the relationship carries a key attribute of its own, that attribute joins the key alongside the many-side foreign keys.
A ternary relationship with no many side gets no relation. 1:1:1 and N:1:1 are explicitly excluded from step 7: creating an R relation for one of them is a wrong answer, because the relationship is absorbed into a participating relation as two foreign keys — into the N side if there is one, otherwise into whichever side is chosen. See step 7 of er-to-relational-mapping.
Attributes
Derived attributes are never columns. NumberOfEmployees is computed from the data, so storing it just creates something that can disagree with the data.
Composite attributes contribute their leaves, not themselves. Name becomes fName, mIt, lName — there is no name column.
Multivalued attributes always become their own relation, keyed on the owner’s key plus the value. A column can only hold one atomic value (see relational-model).
EER
Relationships drawn to a subclass reference the subclass relation. If only a Specialist can run a SpecialistClinic, then Runs.licenceNo references Specialist.licenceNo — not Doctor. Pointing at the superclass silently widens the rule to every doctor and every clinic, losing the constraint the specialisation was drawn to express (specialisation-and-generalisation) — and the same widening is what er-design-choices calls the subclass-vs-superclass relationship fork.
A subclass with no attributes of its own still gets a relation. SpecialistClinic [regNo] with a foreign key back to Clinic records membership, which is information even when there are no extra columns.
Map subclasses before the relationships that use them. The +1 step runs right after step 1 or 2 for a reason — a later step that needs to reference Specialist can’t if Specialist doesn’t exist yet.
Style
Schemas are marked against the course style guide as well as the mapping rules: UpperCamelCase table names, lowerCamelCase attribute names, each relation’s references lines directly beneath it, and a single continuous underline for a composite primary key. See relational-mapping-notation.
ER to Relational Mapping
The (7+1)-step algorithm that converts a conceptual ER/EER diagram into a logical relational schema — input: an ER model; output: relations with primary and foreign key constraints. Introduced in 2026-03-16-er-to-relational-mapping and practised in week5-tutorial-applied-class-4-entity-relationship-mapping and week4-tutorial-case-study-3-dirt-road-driving. See relational-mapping-notation for the notation and naming style used throughout, er-diagram-notation for the diagram being mapped from, and er-mapping-pitfalls for the mistakes to check for afterwards.
Why map at all
The ER model is used for conceptual design — the user’s perspective, good for talking to stakeholders about entities and relationships. The relational model is what commercial DBMSs actually implement — the storage perspective. Mapping is the bridge: every construct that the ER model can draw has to be re-expressed using only relations, primary keys and foreign-keys, because those are the only tools the relational model has (see relational-model).
The steps at a glance
| # | Construct | Produces |
|---|---|---|
| 1 | Strong entity type | A new relation |
| 2 | Weak entity type | A new relation, keyed on owner’s key + partial key |
| 3 | Binary 1:1 relationship | A foreign key on one side |
| 4 | Binary 1:N relationship | A foreign key on the N side |
| 5 | Binary M:N relationship | A new relation |
| 6 | Multivalued attribute | A new relation |
| 7 | N-ary relationship | A new relation — except 1:1:1 and N:1:1, which take foreign keys instead |
| +1 | Subclass (EER) | A new relation per subclass |
Only steps 1, 2, 5, 6, 7 and +1 create relations; steps 3 and 4 only add foreign keys to relations that already exist, and step 7 does the same in its two excluded cases. Working in order matters, because every later step needs the primary keys that earlier steps established.
The running example below is the Company database: EMPLOYEE (key Ssn, composite Name → Fname/Mit/Lname, Sex, Salary, Address, DOB), DEPARTMENT (keys Dnumber/Dname, derived NumberOfEmployees, multivalued Locations), PROJECT (keys Pno/Pname, Plocation), and the weak entity DEPENDENT (partial key DepName), with relationships WORKSFOR (EMPLOYEE N:1 DEPARTMENT), MANAGES (EMPLOYEE 1:1 DEPARTMENT, attribute StartDate), CONTROLS (DEPARTMENT 1:N PROJECT), WORKSON (EMPLOYEE M:N PROJECT, attribute Hours), SUPERVISION (EMPLOYEE recursive 1:N), DEPENDENTSOF (identifying), and EMPLOYEE disjointly specialising into SECRETARY/ENGINEER.
Step 1 — Strong entity types
For each strong (non-weak) entity type: create a relation, choose one of its keys as the primary key, and include all simple attributes.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary]
Department [dNumber, dName]
Project [pNo, pName, pLocation]Three attribute kinds are deliberately not copied across as columns:
- Composite attributes contribute their simple components instead —
Namenever appears,fName/mIt/lNamedo. - Derived attributes are never stored at all —
NumberOfEmployeesis computed on demand, so storing it would only create an opportunity for it to go stale. - Multivalued attributes can’t be stored in an atomic column and are deferred to step 6 —
Locationsis missing fromDepartmentfor now.
Where an entity has several keys (DEPARTMENT has both Dnumber and Dname), one becomes the primary key and the others are simply ordinary attributes in the relational schema — see relational-keys.
Step 2 — Weak entity types
For each weak entity type: create a relation whose primary key is the owner’s primary key plus the weak entity’s partial key; add a foreign key from the inherited part back to the owner; include all simple attributes.
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssnDependent’s full key is (ssn, depName): ssn is Employee’s key inherited through the identifying relationship, depName is the partial key (see relationship-constraints). Note what does not happen — the identifying relationship DEPENDENTSOF gets no relation of its own; it is entirely represented by the inherited key.
If a weak entity has more than one owner, the rule generalises rather than changes: include as foreign keys the primary key attributes of every owner entity type, and make the primary key the combination of all of them plus the partial key. For a weak W (partial key a1) owned by both E1 (key b1) and E2 (key c1):
E1 [b1]
E2 [c1]
W [a1, b1, c1]
W.b1 references E1.b1
W.c1 references E2.c1All three columns are underlined as one key; both inherited keys are foreign keys in their own right.
When the owner’s own key is composite, the foreign key is composite too. In the Bank example, BRANCH is a weak entity owned by BANK (branchNo is only unique within a bank):
Bank [code, name, hoAddr]
Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.codeStep 3 — Binary 1:1 relationships
For each binary 1:1 relationship: pick one participating entity type, add a foreign key there referencing the other’s primary key, and put the relationship’s own simple attributes on that same chosen side.
Preference is given to entity types with total participation (relationship-constraints) — it is part of the rule, not a stylistic tip. In the generic case, with T the totally-participating side (double line) and c1 the relationship’s own attribute:
S [a1, a2]
T [b1, b2, a1, c1]
T.a1 references S.a1If every department must have a manager but not every employee manages, then putting the foreign key on Department gives a value in every row, whereas putting it on Employee would leave it null for almost everyone (sql-nulls). MANAGES is drawn with the double line on the DEPARTMENT side, so DEPARTMENT is the chosen side:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssnmgrStartDate is MANAGES’s own attribute, and travels with the foreign key. The foreign key is a plain attribute here, not part of Department’s key.
Both landed columns are renamed on arrival — Employee.ssn becomes mgrSSN, StartDate becomes mgrStartDate — and the same happens in step 4 (Dnumber → dNumber in Employee, Ssn → superSSN for SUPERVISION). Renaming an inherited attribute to say what role it plays in its new relation is expected, and is the standard fix when the imported name would collide with one already there.
Step 4 — Binary 1:N relationships
For each binary 1:N relationship that isn’t an identifying relationship: find the entity type on the N side, add a foreign key there referencing the primary key of the entity type on the 1 side, and put the relationship’s own simple attributes on the N side too.
The direction is forced, not chosen: one row on the N side relates to exactly one row on the 1 side, so a single foreign key column can hold it. The other direction would need many values in one cell.
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn
Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumberSUPERVISION is recursive, and is handled exactly like any other 1:N relationship — the N-side role (supervisee) carries a foreign key back to the 1-side role (supervisor) in the same relation.
Step 5 — Binary M:N relationships
For each binary M:N relationship: create a new relation; give it foreign keys to both participants’ primary keys; the combination of those foreign keys is its primary key; add the relationship’s own simple attributes.
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNoA new relation is unavoidable here: neither side can hold a single foreign key value, since both sides relate to many rows of the other.
One wrinkle the Company example doesn’t show: the relationship may bring a key attribute of its own, and if it does, that attribute joins the primary key rather than sitting outside it. For an M:N R between S and T carrying an underlined c1 and a plain c2:
S [a1, a2]
T [b1, b2]
R [a1, b1, c1, c2]
R.a1 references S.a1
R.b1 references T.b1R’s key is (a1, b1, c1) — the pair of foreign keys plus c1. This is how a relationship that can repeat between the same two entities (the same employee working on the same project in several different years, say) gets modelled without a duplicate-key clash.
1:1 and 1:N relationships may also be mapped this way, and it is worth doing when the relationship is sparse — a separate relation stores only the rows that actually participate, instead of leaving a null foreign key in every row that doesn’t. In the standard implementation the foreign key column is mostly nulls, while the M:N implementation holds one short relation of just the participating pairs, and no nulls at all.
Step 6 — Multivalued attributes
For each multivalued attribute: create a new relation containing a foreign key to the owning entity’s primary key plus the attribute itself; the primary key is the combination of the two. If the multivalued attribute is composite, include its simple components instead of the attribute itself.
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumberKeying on both columns is what allows one department to have many locations while forbidding the same location twice. If the owning relation’s key is itself composite, the foreign key here is composite — in the cinema example the snack relation carries all four columns of Viewing’s key:
ViewingSnack [name, id, date, time, snack]
ViewingSnack.{name, id, date, time} references Viewing.{name, id, date, time}Step 7 — N-ary relationships
For each N-ary relationship type — excluding the 1:1:1 and N:1:1 cases, which are handled separately below: create a new relation; give it foreign keys to the primary key of every participating entity type; the foreign keys from the participants with many cardinality form the primary key; the relationship’s own attributes may also contribute to that key; add its remaining simple attributes.
One relation body covers every non-excluded case, and only the underline moves. For a ternary R over E1, E2 and E3, with own attributes d1 and d2:
E1 [a1]
E2 [b1]
E3 [c1]
R [a1, b1, c1, d1, d2]
R.a1 references E1.a1
R.b1 references E2.b1
R.c1 references E3.c1| Cardinalities | Primary key of R |
|---|---|
N:M:P — every participant many |
All three foreign keys, (a1, b1, c1) |
N:M:1 |
The two many-side foreign keys (a1, b1); c1 is a plain attribute |
N:M:1 with d1 an underlined attribute of R |
(a1, b1, d1) — the relationship’s own key attribute joins them |
Every participant is always represented, whatever its cardinality: a 1-side foreign key is present but outside the key. For a ternary K over H (role N), A (role M) and P (role 1), with own attribute l, that gives
K [b, i, q, l]
K.b references A.b
K.i references H.i
K.q references P.qwith only b and i underlined. The Company database contains no N-ary relationship — WORKSON is binary.
The excluded cases — 1:1:1 and N:1:1
These get no new relation at all. With at most one participant on a many side, there is no combination of foreign keys that would make a key, and the relationship can be absorbed exactly as in steps 3 and 4: one participating relation takes a foreign key to each of the others, plus the relationship’s own attributes.
- N:1:1 — the entity type on the
Nside is the one that takes them, and the choice is forced, since only its rows relate to exactly one row of each other participant:
E1 [a1, b1, c1, d1]
E1.b1 references E2.b1
E1.c1 references E3.c1
E2 [b1]
E3 [c1]- 1:1:1 — nothing forces the direction, so choose a participant the same way step 3 does, preferring total participation, and put both foreign keys and the relationship’s attributes there. The schema looks identical to the N:1:1 one above; only the reason for picking
E1differs.
The giveaway that a question is testing this exclusion is a ternary diamond with at most one N on its edges: count the many sides before reaching for a new relation, because with fewer than two of them there is nothing to key it on.
Step +1 — Subclasses (EER)
For each subclass (specialisation-and-generalisation): create a relation whose primary key is the superclass’s primary key; add a foreign key from it back to the superclass relation; include the subclass’s own simple attributes. The same rule works for every combination of total/partial and disjoint/overlapping specialisation.
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn
Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssnA subclass with no attributes of its own still gets a relation — it is the row’s membership in that subclass that is being recorded.
This step has no fixed position in the sequence. It is done straight after step 1 or 2 (whichever created the superclass), specifically so the subclass relations exist by the time a later relationship step needs to reference one — and relationships drawn to a subclass must reference the subclass relation, not the superclass.
Final schema — Company database
Employee [ssn, fName, mIt, lName, dob, address, sex, salary, dNumber, superSSN]
Employee.dNumber references Department.dNumber
Employee.superSSN references Employee.ssn
Department [dNumber, dName, mgrSSN, mgrStartDate]
Department.mgrSSN references Employee.ssn
Project [pNo, pName, pLocation, dNumber]
Project.dNumber references Department.dNumber
Dependent [ssn, depName, sex, dob, relationship]
Dependent.ssn references Employee.ssn
Secretary [ssn, typingSpeed]
Secretary.ssn references Employee.ssn
Engineer [ssn, engineerType]
Engineer.ssn references Employee.ssn
WorksOn [ssn, pNo, hours]
WorksOn.ssn references Employee.ssn
WorksOn.pNo references Project.pNo
DeptLocs [dNumber, location]
DeptLocs.dNumber references Department.dNumberEight relations: the three strong entity types became three, the weak entity one, the two subclasses two, the M:N relationship one, and the multivalued attribute one — while all four of the 1:1 and 1:N relationships (MANAGES, WORKSFOR, CONTROLS, SUPERVISION) became nothing more than foreign key columns on relations that already existed.
Second worked example — Bank database
The other complete run-through is the bank: a BANK (unique Code, Name, HOAddr) has several branches; a BANK-BRANCH has a BranchNo unique only within its bank, so it is weak. One branch has many ACCOUNTs (ACNo, Type, Balance) and many LOANs (LoanNo, Type, Amount), and every account and loan has one or more holders drawn from CUSTOMER (SSN, Name, Addr) — two M:N relationships, AHOLDER and LHOLDER.
Bank [code, name, hoAddr]
Branch [bankCode, branchNo, addr]
Branch.bankCode references Bank.code
Account [acNo, type, balance, bankCode, branchNo]
Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}
Loan [loanNo, type, amount, bankCode, branchNo]
Loan.{bankCode, branchNo} references Branch.{bankCode, branchNo}
Customer [ssn, name, address]
AccountHolder [acNo, ssn]
AccountHolder.acNo references Account.acNo
AccountHolder.ssn references Customer.ssn
LoanHolder [loanNo, ssn]
LoanHolder.loanNo references Loan.loanNo
LoanHolder.ssn references Customer.ssnTwo things are worth reading off this schema. First, a weak entity’s composite key propagates: because Branch is keyed on (bankCode, branchNo), every 1:N foreign key drawn from Branch is composite too. Second, it propagates as a plain column — Account has its own key acNo, so bankCode and branchNo sit outside Account’s primary key, exactly as step 4 requires. AccountHolder and LoanHolder, by contrast, have no key of their own and are keyed on their pair of foreign keys.
The result is a logical schema, ready to be implemented with sql-ddl and checked for redundancy with normal-forms. Whether each inherited foreign key is part of its relation’s primary key — the question that decides most of the answers above — is tabulated in foreign-keys.
Foreign Keys
A foreign key is a set of attributes in one relation that links it to another relation’s primary key — the only mechanism the relational model has for expressing a relationship between two relations, and therefore the thing almost every mapping step in er-to-relational-mapping produces. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints; see relational-keys for keys within a relation and relational-mapping-notation for the references notation used throughout.
Definition
Let FK be a set of attributes in relation R1, and PK the primary key of relation R2. FK is a foreign key referencing PK if:
FKandPKare drawn from the same domain(s) — the names need not match, only the domains (see relational-model on why attribute names and domains are independent), and- for every tuple \(t_1\) in
R1, either \(t_1[\mathit{FK}]\) isNULL, or there exists a tuple \(t_2\) inR2with \(t_1[\mathit{FK}] = t_2[\mathit{PK}]\).
Condition 2 is the referential integrity constraint. Note what it permits: a foreign key value may be NULL (the row simply doesn’t participate), but it may never be a value that points nowhere. A dangling reference is the violation; an absent reference is not.
Department [id, name, manager]
Department.manager references Employee.id
Employee [id, name, sex, salary, department]
Employee.department references Department.idForeign keys can point in both directions between the same pair of relations, as here — Department.manager says who runs the department, Employee.department says who works in it. They are two separate constraints expressing two separate relationships.
An instance makes the permission concrete: Department 4 (Human Resources) has a NULL manager and employee 2034 a NULL department, and both rows are legal. An employee whose department read 5, with no department 5 in the referenced relation, would not be.
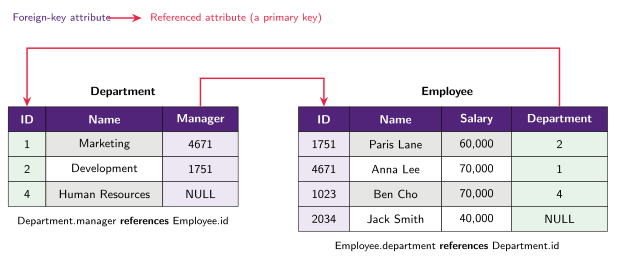
Figure 38: A two-way foreign key between Department and Employee. Each arrow starts at the foreign-key column and its head lands on the referenced primary key — the direction never varies in this course. The tinted columns pair each foreign key with the primary key it points at; the two NULLs are legal, because a foreign key may be absent but may never point nowhere.
Shapes a foreign key can take
Self-referencing
A relation can reference itself, because the two attributes involved share a domain even though they play different roles. Adding a managerId column to the same Employee relation gives one:
Employee [id, name, salary, department, managerId]
Employee.managerId references Employee.id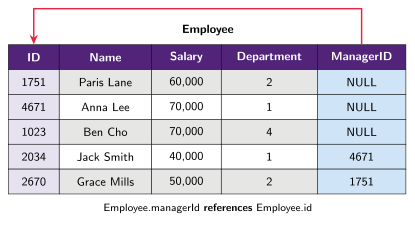
Figure 39: A self-referencing foreign key: the arrow leaves ManagerID and returns to ID in the same relation. The three top-level employees carry NULL, which is what stops the reference chain rather than a special case in the constraint.
The company schema does the same thing with different names:
Employee [ssn, fName, lName, dob, superSSN]
Employee.superSSN references Employee.ssnThis is what a recursive relationship (relationship-types — SUPERVISION: an employee supervises many employees) maps to: the N-side role, the supervisee, carries the foreign key back to the 1-side role, the supervisor. It is also what a sql-joins self-join follows back.
Composite
If the referenced primary key is composite, the foreign key must be composite too, and the whole thing is one constraint over a tuple of columns:
Student [sid, name]
Course [cid, department, manager]
Enrollment [sid, cid, department, grade]
Enrollment.sid references Student.sid
Enrollment.{cid, department} references Course.{cid, department}Course’s key is the pair (cid, department), so Enrollment must carry both columns to name one course, and its own key is all three of (sid, cid, department).
Splitting a composite foreign key into several single-column constraints is a real and commonly-marked mistake — see er-mapping-pitfalls — because it no longer forces all the columns to jointly match one referenced row.
Two foreign keys to the same relation
When a relationship uses the same entity type in two different roles, the referencing relation gets two separate foreign keys to it, given distinct column names so the roles stay readable:
PeerEvaluation [studentSid, assessmentSid, number, evaluationId, sidGrades, mark]
PeerEvaluation.studentSid references Student.sid
PeerEvaluation.sidGrades references Student.sid
PeerEvaluation.{assessmentSid, number} references Assessment.{sid, number}studentSid is the evaluator submitting the mark; sidGrades is the student whose assessment is being marked.
Is the foreign key part of the primary key?
This is the question that decides most mapping answers, and the rule is structural rather than a matter of taste:
| Situation | Foreign key is… |
|---|---|
| 1:N relationship, FK on the N side (an entity with its own key) | A plain, non-key attribute |
| 1:1 relationship, FK on the chosen side | A plain, non-key attribute |
| Weak entity, FK to its owner | Part of the weak entity’s composite primary key |
| M:N relationship’s own relation | Part of the primary key (the pair of FKs is the key) |
| N-ary relationship’s relation, FK from a many-side participant | Part of the primary key |
| N-ary relationship’s relation, FK from a 1-side participant | A plain, non-key attribute |
| Multivalued attribute’s relation | Part of the primary key (with the value itself) |
| Subclass relation | Is the primary key — the subclass’s key is the superclass’s key |
So in Employee [ssn, …, dNumber, superSSN] the department and supervisor foreign keys are ordinary columns, whereas in Dependent [ssn, depName, …] the inherited ssn is underlined as part of the key. Treating an ordinary 1:N foreign key as key material is a standard wrong answer.
The dividing line is whether the referencing entity has a key of its own. An entity that doesn’t — the cinema Viewing, identified only by which movie, which customer and when — is being identified through its owners, so the inherited foreign keys do join its key: Viewing [name, id, date, time, attendant], keyed on all four of (name, id, date, time). That reads as weak-entity behaviour with two owners rather than as an exception to the rule, and the shape is straight out of the mapping rules: a weak entity with more than one owner takes a foreign key to each owner and is keyed on every owner key plus its partial key (step 2 of er-to-relational-mapping). Reading Viewing as a weak entity with two owners or as a strong entity whose key happens to be composite produces the same relation, so the mapping answer is the same either way.
Nulls, and when to avoid them
Because a foreign key may be NULL, embedding a 1:1 or 1:N relationship directly into an existing relation produces a null in every row that doesn’t participate. When a relationship is sparse — few of the rows actually take part — mapping it as its own relation instead (the M:N treatment) avoids all those nulls at the cost of an extra join. That trade-off is noted under step 5 of er-to-relational-mapping; see sql-nulls for what nulls then do to queries.
Enforcement
Referential integrity is declarative — the DBMS rejects any insert, update, or delete that would leave a dangling reference, with no application code involved (see integrity-constraints).
Three operations from week4-tutorial-applied-class-3-relational-integrity show the full range, and they are worth reading together because two of them look dangerous and are not:
| Operation on the company schema | Verdict |
|---|---|
Delete the EMPLOYEE tuple with ssn = 987654321 |
Violates referential integrity — tuples in WORKS_ON, DEPENDENT, DEPARTMENT and EMPLOYEE itself all reference it |
Modify EMPLOYEE.superSSN of 999887777 to 943775543 |
Violates referential integrity — no employee has that ssn; an update to a foreign key is checked exactly like an insert |
Delete the WORKS_ON tuples with essn = 333445555 |
No violation — nothing references WORKS_ON, so removing rows from it cannot dangle anything |
The last row is the shape people get wrong: whether a delete is safe depends on what points at the relation, not on how many foreign keys the relation itself carries. WORKS_ON is all foreign key and is still free to delete from. The EMPLOYEE delete is dangerous precisely because four relations, one of them EMPLOYEE itself through superSSN, point back at it.
What happens to dependent rows when a referenced row is deleted or its key updated is a policy choice attached to the foreign key itself: the violation can be rejected, cascaded, or the referencing attribute values modified to a default value. See update-operations-and-constraint-violations for those conceptual options and sql-ddl for the four named ON DELETE / ON UPDATE actions that spell them out in SQL.
Functional Dependencies
A functional dependency (FD) is the formal way to state a business rule of the form “if you know this, you know that”. It’s the unit of information every design-theory tool in this course consumes: closures, keys, normal forms and both schema-design algorithms are all defined in terms of a set of FDs. Introduced in 2026-04-27-database-design-guidelines-and-functional-dependencies.
The motivating question is the one left hanging by update-anomalies: how can we be sure every employee at the same level earns the same salary, rather than it merely happening to be true of today’s rows? By declaring level → salary — “level determines salary”.
Formal definition
An FD X → Y holds on relation R if, for every legal instance r of R and every pair of tuples \(t_1, t_2 \in r\):
\[t_1[X] = t_2[X] \implies t_1[Y] = t_2[Y]\]
i.e. any two tuples that agree on X must also agree on Y. X is the left-hand side (LHS) or determinant, Y the right-hand side (RHS). Both are sets of attributes, so {sName, pNum} → qty is a perfectly ordinary FD; single-attribute sets are written without braces.
An FD is a constraint between two attribute sets — it restricts which tuples may legally appear together in an instance of R, exactly as a key or referential-integrity constraint does (see integrity-constraints). A key is in fact a special case: X is a superkey of R precisely when X → R holds, which is how relational-keys’s “minimal set that uniquely identifies” becomes something you can compute rather than assert — see attribute-closure.
An FD is a statement about all instances
This is the single most important thing about FDs, and the thing exam questions probe most often:
You can check whether a given instance violates an FD, but you can never prove an FD holds by looking at one instance.
FDs come from the semantics of the application — the Universe of Discourse and its business rules — not from reverse-engineering a data sample. A sample can only ever rule FDs out.
Ruling one out: given R [A, B, C, D] with rows (1,2,3,4), (2,3,4,6), (6,7,8,9), (1,3,4,5) — B → D cannot be true, since rows 2 and 4 both have B = 3 but disagree on D (6 vs 5). B → C and D → B are still possible — meaning only “not yet contradicted”, never “proven”.
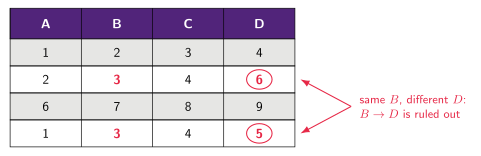
Figure 40: The only thing an instance can do to an FD. Rows 2 and 4 agree on B and disagree on D, so B → D is refuted outright; nothing in the table can establish B → C or D → B, which merely survive un-contradicted. The crimson ellipses mark the two D values that clash.
Reading candidate FDs off a sample instance
Case-study questions do ask you to identify the FDs a sample table suggests. The mechanical procedure is: for each candidate X → Y, group the rows by their X value; if any group disagrees on Y, the FD is dead, otherwise it survives as a potential FD. Two traps:
- An
Xvalue that never repeats makesX → Ytrivially survive — there is no pair of rows to contradict it. In week10-tutorial-applied-class-9-functional-dependencies Section A,A → B,A → Cand{A, B} → Call “hold” only becauseAis distinct in every row. That’s evidence of nothing. - The surviving FDs still have to make sense. In week10-tutorial-case-study-8-dirt-road-driving, the FD worth reporting on
EmployeeHistoryisseniorityLevel → baseSalary, securityLevel— everyJuniorrow has{70,000, Limited}and everyExecutiverow has{80,000, Full Access}— because seniority genuinely determines pay band in the UoD, not merely in the sample.
Trivial and non-trivial FDs
- A trivial FD holds regardless of
F, because the LHS already contains the RHS — e.g.A → A,{A, B, C} → {A, B}. - A non-trivial FD depends on the specific
F— e.g.A → B.
Every normal-form test is stated over non-trivial FDs only, since a trivial FD can never be a design flaw.
Explicit and implicit FDs; the closure of F
Given a set F of explicit FDs, further implicit FDs follow: from id → level and level → salary we can infer id → salary. Implicit FDs are also called inferred FDs. The notation
\[F \models X \rightarrow Y\]
means X → Y can be inferred from F — equivalently, “Y can be derived from X under F”, or “X implies Y under F”.
The closure of F, written F⁺, is the set of all FDs — trivial and non-trivial — implied by F.
Armstrong’s axioms and what is actually examinable
F⁺ can be computed by applying Armstrong’s Axioms as inference rules, but doing so is difficult and time consuming, and it is outside the scope of this course. The individual rules — reflexivity, augmentation, transitivity, and the derived union, decomposition and pseudotransitivity rules — are outside it too, so there is nothing to memorise and no question can ask you to name or apply one.
What replaces them is attribute-closure (X⁺), which answers the only question the rest of the module ever asks of F⁺: given X, which attributes are determined? Every inference you actually need — the transitive chain id → level → salary, say — falls out of one closure computation, and that is the examinable skill.
F⁺ still matters conceptually, because every normal-form test is phrased “for every non-trivial X → A in F⁺” — the implied FDs count too. Missing an implicit FD is the classic way to declare a relation BCNF-compliant when it isn’t; in practice you compute the closures first, spot that F ⊨ A → C, add A → C to F, and then run the algorithm. See [decomposition].
Why FDs create redundancy
FDs are also the precise account of where redundancy comes from. In R [A, B, C] with no FDs at all, no value constrains any other and there is no redundancy. Add A → B, and any two tuples sharing an A value are now forced to repeat the same B value. That forced repetition is exactly what normalisation identifies and removes — which is why the normal-form tests in normal-forms are all conditions on the LHS of an FD relative to the keys.
A running instance makes the mechanism concrete. Employee [ID, name, level, salary] with level → salary stores Developer, 60,000 twice and Manager, 700,000 twice — not by accident but because the FD forbids anything else. Project the relation onto [ID, name, level] and [level, salary] and each level’s salary is recorded exactly once, with nothing lost: the natural join on level rebuilds the original rows. The two halves are named StaffAppointment [ID, name, level] and StaffIncome [level, salary] in the 3NF treatment; see normal-forms and [decomposition].
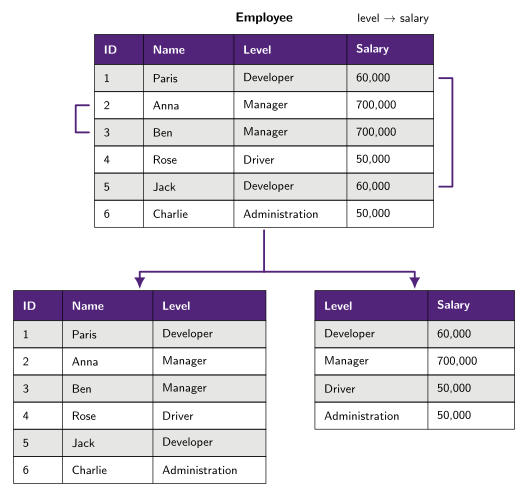
Figure 41: An FD is a redundancy generator, and the split is the cure. level → salary forces every Developer row to carry 60,000 and every Manager row 700,000 — the purple brackets mark the two groups the FD ties together. Splitting off a [level, salary] table records each level’s salary once; the natural join on level rebuilds the six original rows.
The three anomalies that repetition causes — and which the split fixes — are catalogued in update-anomalies.
See also
- attribute-closure · normal-forms · minimal-cover · [decomposition]
- update-anomalies — the symptoms FDs explain
- 2026-04-27-database-design-guidelines-and-functional-dependencies — Module 4, part 1
- week10-tutorial-applied-class-9-functional-dependencies — FD identification and closure practice
INFS1200 Diagram Notation
Reference legend for every diagram family in INFS1200 except ER/EER symbols and ER-to-relational mapping, which are already covered by er-diagram-notation and relational-mapping-notation. This note covers relation schemas and instances drawn as tables, foreign-key figures, constraint-violation figures, relational-algebra notation, SQL presentation, functional-dependency notation, and normalisation/decomposition figures — plus a section confirming whether the ER diagrams really are drawn to the Chen conventions the existing note asserts.
Everything below was inferred from the course’s own PDFs. Where a convention is stated by the course rather than merely practised, that is called out.
What was sampled
The course ships two written guides, both one page, and both already covered by the sibling notes: the EER & ER Notation Guide (naming only — entity/relationship names capitalised and space-free, attributes UpperCamelCase) and the Relational Mapping Guide (Relation [attr, ...] schema form, table names UpperCamelCase, attributes lowerCamelCase, X.fk references Y.pk). Neither guide says anything about symbol shape, colour, line style, table presentation, algebra notation, FD notation or figure layout. Every convention in this note beyond naming was inferred from the drawings.
Deck shorthand used in citations below:
| Cite | File | Pages |
|---|---|---|
| L0 | infs1200-lecture-0.pdf (Module 0: Introduction / DBMS) |
64 |
| L1 | infs1200-lecture-1.pdf (Module 1: ER Model) |
60 |
| L2 | infs1200-lecture-2.pdf (Module 2: Relational Model + Mapping) |
94 |
| L3 | infs1200-lecture-3.pdf (Module 3: SQL) |
191 |
| L4 | infs1200-lecture-4.pdf (Module 4: Design Theory) |
114 |
I read 261 of the 523 deck pages as rendered images, plus both guide pages in full, plus a plain-text extraction of all 523 pages used to locate the pages carrying drawings. Specifically:
- L0: pp. 42–48, 59–63 (12 of 64)
- L1: pp. 28–34, 41–53 (20 of 60)
- L2: pp. 5–36, 43–58, 61–74, 76–93 (80 of 94)
- L3: pp. 5–9, 46–60, 71–82, 86–104, 106–118, 145–161 (81 of 191)
- L4: pp. 8–27, 52–70, 84–112 (68 of 114)
I did not read L0 pp. 1–41 and 49–58, L1 pp. 1–27 and 35–40, L3 pp. 10–45, 61–70, 83–85, 119–144, 162–191, or L4 pp. 1–7, 28–51, 71–83. The unread stretches are mostly prose, quiz slides and the generative-AI section; sampling targeted pages that carry drawings.
There is no Module 5 (Database Security) deck in the source set at all — only roadmap bullets naming it (L0 p63, L3 p2, L4 p3). See Not established.
The palette
Colours are used systematically enough to be treated as notation. Sampled directly from the rendered PDFs, so these are exact:
| Hex | Name used below | Meaning |
|---|---|---|
#51247A |
UQ purple | Entity-type fill; table header fill; section-bar fill; derived/answer text |
#962A8B |
magenta | Relationship-diamond fill |
#E6E6E4 / #E7E6E6 |
light grey | Attribute-oval fill; alternating table body row; definition box; “this one is wrong” query box |
#E6E0EF |
pale lavender | Schema-reference box; SQL syntax-template box; quiz-stimulus box; side-note box |
#D1F2D3 |
pale green | A query being demonstrated as correct |
#2EA836 |
green | ✓ badge; “this is legal / this is the good design” |
#E62645 |
crimson | ✗ badge; foreign-key arrows; “this violates the constraint” outlines |
#C00000 / #CB0000 |
dark red | Emphasis on a term being defined, in running prose |
Consistency: the purple/magenta/light-grey trio holds for every ER diagram in L1 and L2. The green-✓/crimson-✗ pairing holds across L2, L3 and L4 — it is the single most consistent visual convention in the course. The pale-green query box appears throughout L3 only (SQL is only taught there).
Relation schemas written as text
Follows the written guide, and is used identically in all four content decks.
Relation [attr1, attr2, ...], space before the bracket, primary key underlined. L2 pp. 15, 22, 30, 89–93; L3 pp. 49, 51, 56, 60, 87, 92–95, 109, 111, 112, 115; L4 pp. 56–59, 63, 64, 66, 68, 85, 88, 90, 93, 106, 107. Throughout the semester.- A composite primary key gets one continuous underline spanning all its attributes, not one underline per attribute —
Enrollment [sid, cid, department, grade]with a single rule under the first three. L2 pp. 30, 86, 90–93; L3 p49 (StarsIn [movieID, starID, role]); L4 p66. Consistent. - Foreign keys are written on their own line directly under the referencing relation:
Employee.department references Department.id. Composite FKs use brace sets on both sides:Account.{bankCode, branchNo} references Branch.{bankCode, branchNo}. L2 pp. 27, 30, 57, 86, 90–93. Consistent. - Schema listings shown as reference material for a query or example sit in a pale-lavender box with a thin black border. L2 pp. 15, 27, 30; L3 pp. 49, 51, 54, 56, 57, 59, 60, 87, 92–96, 104, 109, 111, 112, 115, 151–161. Throughout Module 3.
Relation instances and result tables
The single most-repeated figure in the course. Identical in L0, L2, L3 and L4.
- Header row: solid UQ purple
#51247A, white bold text, one attribute name per cell. - Body rows: alternate light grey
#E6E6E4and white, starting with grey in row 1. - Borders: thin black, on all cells.
- Relation name: bold black, above the table, centred. L0 p46; L2 pp. 8, 10–13, 15, 17, 18, 23, 25–29, 35, 36, 74; L3 pp. 88, 89, 93–95, 98, 103, 112, 118, 146–150, 159–161; L4 pp. 9, 10, 15, 24, 26, 27, 45, 53, 54, 60, 66. Throughout the semester.
- Alignment is left in every table observed; numbers are not right-aligned.
- Key attributes are underlined in the purple header when the figure is about keys: L2 p74 (
PK1,PK2), L4 p66 (studentID,courseID). Elsewhere headers are not underlined. Used twice — treat as available, not required. - A query result table uses exactly the same styling as a base-relation table; the only difference is that it carries no relation-name caption, and its headers are the projected expressions themselves —
COUNT(*),AVG (salary)wrapping over two lines. L3 pp. 49, 73–76, 79, 93–95, 103, 112. Consistent in Module 3. - Empty cells in a multiple-choice distractor are drawn as a grey cell with no content (L1 p34, L3 p118). Seen twice.
Highlighting inside a table
A small, stable vocabulary:
| Device | Meaning | Citation |
|---|---|---|
| Thin red ellipse drawn over a cell or column | “look at this value” — sometimes the topic, sometimes the offence | L2 pp. 8, 10, 25, 26, 31, 33 |
| Heavy black rectangle outline around a whole row | the row under discussion | L2 pp. 31, 33; L4 p27 |
| Pale cyan/light-blue fill on rows or a rounded cyan outline on cells | the rows that demonstrate the problem | L4 p15; L3 pp. 159–161 |
| Pale tint on a column, matched between two tables | pairs a foreign-key column with the primary-key column it references | L2 pp. 28, 29 |
| Thick black diagonal strike-through across a row | this candidate has been ruled out | L3 pp. 159–161 |
| Green ✓ beside a row | this candidate qualifies | L3 pp. 160, 161 |
| Red text in a result-table cell | a spurious tuple produced by a lossy join | L4 p18 |
Consistency: the red ellipse and the black row-outline recur across L2 and L4. The cyan devices are confined to L3 pp. 159–161 and L4 p15.
Foreign keys drawn as arrows
Two distinct arrow renderings, both meaning the same thing, both with the arrowhead landing on the referenced attribute (i.e. the arrow points FK → PK, from the child to the parent). This direction never varies.
- Over tables: thick crimson
#E62645orthogonal (right-angled) elbow arrows drawn above the tables, from the FK column heading, up and across, down into the referenced PK column heading. L2 pp. 27, 29. - Inside a schema box: thin arrows from the FK attribute to the referenced attribute. Drawn diagonally/curved in L3 pp. 49, 51, 56, 60, 93–95, 109, 111, 112, 115; drawn as black orthogonal elbows in L3 pp. 54, 57, 59, 73–76, 79, 80, 87, 92, 96, 97, 104. Both idioms are used constantly in Module 3.
- L2 p27 is the only slide carrying an explicit legend line for it:
Foreign Keys Attribute ——▸ Referenced attribute, in magenta text under the schema box. That legend is the authority for the direction. - Textual constraint captions sit under the table as plain black prose (
Department.manager references Employee.id), in addition to the arrows. L2 pp. 27, 28, 29.
Constraint-violation figures (✓ / ✗)
The course’s standard way of showing “this is illegal, that is legal”:
- The candidate tuple is drawn as a detached one-row table below the relation it would be inserted into.
- An illegal tuple gets a crimson
#E62645outline and a crimson circle with a white ✗; a legal tuple gets a green outline and a green circle with a white ✓. L2 pp. 21, 25, 26, 31, 33, 35, 36. Consistent through the integrity-constraints section. - The same ✓/✗ badges are reused for anything that has a right and a wrong version: two candidate SQL queries (L3 pp. 104, 111, 113), two candidate decompositions (L4 pp. 15, 26, 27), two design approaches (L4 p109). In L3 the losing query’s box is light grey and the winning one’s is pale green; the badge sits at the box’s top-left (L3 p104) or top-right (L3 pp. 111, 113). Semester-wide for the badges; box-fill pairing is Module 3 only.
- The five integrity-constraint types each get a fixed fill on a rounded “one-square-corner” banner, reused every time that type is discussed: domain = magenta-pink, key = gold/tan, entity integrity = cyan, referential integrity = grey, semantic integrity = UQ purple. L2 pp. 20, 21, 25, 26, 31, 32, 33. Consistent within Module 2; never reused elsewhere.
ER diagrams: do they match the Chen conventions er-diagram-notation states?
Yes — with fills and colours the existing note does not record. The lectures carry their own two-slide Notation Guide (L1 pp. 50–51), which is the authority. Drawn form:
| Symbol | Drawn as | Citation |
|---|---|---|
| Entity type | Solid UQ purple rectangle, white text, ALL CAPS name | L1 pp. 41–44, 46–49, 50, 51; L2 pp. 48, 50–53, 55, 56, 58, 66–72, 85, 88 |
| Weak entity type | The same purple rectangle nested inside a second black rectangle (double border) | L1 pp. 41–44, 50; L2 pp. 48, 55, 56, 58, 88 |
| Attribute | Light grey ellipse, thin black border, black text, joined by a thin plain line | L1 pp. 41–44, 47–50; L2 pp. 48, 50–53, 56, 58, 88 |
| Key attribute | Same, name solid-underlined | L1 pp. 41–44, 48, 50; L2 pp. 48, 88 |
| Partial key attribute | Same, name dash-underlined | L1 pp. 41, 42, 44, 50; L2 pp. 48, 55, 56, 58, 88 |
| Multivalued attribute | Light grey ellipse with a double black outline | L1 p50; L2 pp. 48, 50, 52 |
| Derived attribute | Light grey ellipse with a dashed outline, joined by a dashed line | L1 p50; L2 pp. 48, 52 |
| Relationship type | Magenta diamond, white text, ALL CAPS name | L1 pp. 43, 44, 48–51; L2 pp. 48, 50–53, 66–72, 85, 88 |
| Identifying relationship | Magenta diamond nested inside a second diamond outline | L1 pp. 43, 44, 50; L2 pp. 48, 55, 58, 88 |
| Cardinality ratio | Plain black 1 / N / M, placed on the edge near the entity end |
L1 pp. 31–34, 41–43, 51; L2 pp. 48, 88 |
| Total participation | Double line on that entity’s edge into the diamond | L1 pp. 42, 43, 51; L2 pp. 48, 62, 88 |
| Subclass | ⊂ drawn as an open arc on the connecting line, with the arc’s opening facing the superclass |
L1 pp. 46–49, 51; L2 pp. 48, 85 |
| Several subclasses | A small light-grey circle joining the subclass lines to the superclass; each subclass line carries its own arc | L1 pp. 48, 49, 51; L2 pp. 48, 85 |
| Disjoint / overlapping | d / o inside that circle |
L1 pp. 48, 49, 51; L2 pp. 48, 85 |
| Total / partial specialisation | Double / single line from the superclass down to the circle | L1 p49 (legend + figure) |
| Role name (recursive relationship) | Plain lowercase black text beside the line | L2 p48 (supervisor, supervisee) |
So the existing note’s symbol list is correct; it just does not record that entities are filled purple, relationships filled magenta, and attributes filled grey — which is what makes a hand-drawn INFS1200 diagram look like an INFS1200 diagram. That is also why the Mermaid approximations described at the bottom of er-diagram-notation are a genuine substitute rather than a reproduction: Mermaid cannot produce the double-outline shapes, the dashed ellipse, the underline styles, or the ⊂ arc.
Layout: no fixed flow direction. Entity boxes sit on a rough horizontal spine with attributes fanned above and below (L1 pp. 41–44; L2 p88); specialisation hierarchies run top-down with the superclass on top (L1 pp. 47–49).
Instance-level (“ball and line”) relationship diagrams
Used only to explain cardinality ratios, and the ellipse outline colour is semantic:
- Two (or three) vertical ellipses, each holding dots for entity instances, joined by thin black straight lines for relationship instances.
- Ellipse outline colour encodes the ratio, and the same colour is reused as an inline badge on the worked examples: purple
#51247A= 1:1, orange#EB602B= N:1, blue#4085C6= 1:N, green#2EA836= M:N. Defined on L1 p30 and reused on pp. 31, 32, 33. Consistent across four slides, and used nowhere else. - L1 p29 uses a different idiom for the same idea: purple person/item icons with green arrows inside a solid green box for what is allowed and red arrows inside a dashed red box for what is not. Single instance.
ER-to-relational mapping figures
- Slides are two-panel: “ER Diagram” (bold black heading) on the left/top, “Mapping to Relation” on the right/bottom. L2 pp. 50–53, 55, 56, 61, 62, 65–68, 71, 72, 76, 77, 83–85. Consistent through the mapping section.
- The rule box stating the step is a rounded rectangle with a solid fill and white text, and its fill colour tracks the step group shown on the roadmap slide (L2 p47): UQ purple for steps 1–2 (entities/weak entities), gold/tan for steps 3–5 (binary relationships), magenta for steps 6–7 (multivalued / N-ary), slate for the EER subclass step. L2 pp. 50, 55, 61, 65, 71, 76, 78, 83. Consistent — the colour is load-bearing, not decorative.
- The “Mapping to Relation” panel is a rounded rectangle with a purple border and white fill. What the current step adds is written in red; what was already there stays black. L2 pp. 50, 55, 61, 65–68, 71, 72, 76, 77,
- (One exception — see Inconsistencies.)
- Explanatory side notes sit in a pale-lavender rounded rectangle with a purple border. L2 pp. 51–53, 56, 62.
- Diagram annotations (e.g. “Total Participation”) are black text in a purple-bordered white box, joined to the thing they label by a purple wedge pointer. L2 p62. Single instance.
- Lecturer commentary on a diagram is red text with thin red arrows — L1 p44, L2 pp. 59, 74. Recurs; the standard callout style.
Progressive schema build-up
The course builds a schema across consecutive slides and marks “what is new” — but in two different ways. See Inconsistencies; both are recorded here:
- Grey-out idiom: previously-established lines are grey, the newly-added lines are black, foreign-key lines are italic. L2 pp. 54, 57, 63, 69, 73.
- Bold idiom: everything stays black and the newly-added lines are bold. L2 pp. 89–93.
The “Final Schema” summary is enclosed in a crimson rounded-rectangle outline, laid out in two columns, with all foreign-key lines in italic. L2 p86. Single instance, but it is the canonical worked answer.
The same grey-out idiom marks progress through the normal forms: on the “Normalisation – Overview” slide all four normal forms are listed and every one except the current is greyed. L4 pp. 49, 50, 51, 55, 61, 67, 80. Consistent.
Relational algebra notation
The course teaches relational algebra as motivation for SQL, not as a calculus you write. Only some operators get symbols:
| Operator | Symbol as written | Citation |
|---|---|---|
| Join / natural join | ⋈ (bowtie), written infix: R₁ ⋈ R₂ |
L3 pp. 90, 91 (“Denoted as ⋈”); L4 pp. 16, 17 |
| Cartesian product | X — a plain capital letter X, not ×: R1 X R2 |
L3 pp. 88, 89, 91 (“denoted as X”) |
| Theta-join condition | θ ∈ {=, ≠, <, >, ≤, ≥} |
L3 p99 |
| Union / intersection / difference | ∪ / ∩ / −, named as “the relational algebra operations” |
L3 pp. 106, 107, 116 |
| Division | Written both as A/B (R1/R2) in prose and as ÷ in figures |
L3 pp. 145–151 |
| Relation cardinality | vertical bars around the relation name, e.g. \|R1\| = m, \|R1 X R2\| = m * n |
L3 p88 |
| Result of a decompose-then-join round trip | R' (prime) |
L4 p18 |
There is no σ and no π anywhere in the sampled pages. Selection and projection are introduced purely as SQL clause names — “Projection (SELECT clause)” (L3 p48), “Selection (WHERE clause)” (L3 p55) — never as algebraic operators. Do not write σ_{cond}(R) or π_{attrs}(R) in an INFS1200 note; the course has no such notation.
Operator figures — a relational-algebra operation applied to concrete tables is drawn one of two ways:
- Operand tables at left, a thick UQ-purple block arrow between them and the result, with the expression (
R₁ ⋈ R₂) as a black label above the arrow. L3 p90; L4 pp. 16, 18. Consistent. - Operand tables side by side with the operator glyph set large between them and the result table after an
=. L3 pp. 88 (X), 148 (÷), 151 (÷). - Relation names for schematic tables (
R,R₁,R₂,S,A,B1,B2) are placed to the left of the table (L3 pp. 90, 149, 150; L4 pp. 14, 16,- or centred above it (L3 pp. 103, 146–148; L4 p18 for
RandR'). Both are common.
- or centred above it (L3 pp. 103, 146–148; L4 p18 for
Set-operation Venn diagrams
Two incompatible idioms, both in Module 3:
- Black outline, diagonal hatching for the selected region, in a bordered 3-row legend table (Union / Intersection / Difference). L3 p106.
- Colour-filled circles (yellow intersection, magenta left, orange right) for the join types, with lowercase function-style captions
inner_join(x, y),left_join(x, y). L3 p102 — visibly an imported graphic (dplyr-style), not the course’s own drawing.
SQL presentation
This is where the course is most systematic, and it states its own legend.
Syntax templates (how a statement is specified) sit in a pale-lavender box, and L3 p72 gives the full legend explicitly in its own box:
Notation
KEYWORD reserved word, ALL CAPS, coloured red
<argument> a placeholder you replace
[optional] may be omitted
{multiple} may be repeated
…|..choice..|… pick oneAbbreviated versions of the same legend appear on L3 pp. 48 and 55. Keywords in these templates are red and bold. Consistent for every syntax box in Module 3 (L3 pp. 48, 55, 72, 91, 108, 110, 114).
Worked queries (an actual query being run) sit in a pale-green #D1F2D3 box with a thin dark border. Keywords are plain black, not red, and the query is laid out in two columns: the clause keyword in a left column, its arguments in a right column, one clause per line. L3 pp. 49, 51, 56, 57, 59, 60, 73–76, 79, 80, 87, 92–95, 97, 104, 109, 111–113, 115. Consistent.
Quiz-stimulus queries (a query you are asked about, not one being taught) sit in a pale-lavender box like the templates — L3 pp. 77, 82, 89, 96, 98, 100, 118. So box fill separates “here is how you write it” / “here is one that works” / “here is one to reason about”.
Other SQL conventions:
- Casing: keywords ALL CAPS; table names UpperCamelCase; attribute names lowerCamelCase — matching the Relational Mapping Guide. L3 throughout.
- Aliases: a short uppercase letter or initialism (
D,E,S,MS,M,F1,F2,S1,S2,M1,M2,A,B,X), introduced either bare (Employee E) or withAS(Employee AS E). L3 p87 explicitly says both are acceptable; both appear throughout. - Terminating semicolon is present on some queries and absent on others, with no discernible rule (present L3 pp. 73, 79, 92, 104; absent L3 pp. 49, 56, 60, 75, 76, 93–95, 109, 115).
- Selective red highlighting inside a black query marks the one keyword the slide is about —
DISTINCT(L3 p93),<HAVING …>(L3 p82),INSERT INTO … SELECT(L3 p77). Occasional, not systematic. - Slides that are live in-class exercises carry a purple rounded-square icon of two figures with
</>badges in the top-right. L3 pp. 49, 51, 54, 56, 57, 59, 60, 80, 89, 92, 94, 97, 104, 109, 112. Consistent marker.
Division and double-negation figures
The most elaborate figure family in the course, and internally very disciplined (L3 pp. 152–161):
- Slide split into two panels by a vertical purple rule, headed “Query” (left, the SQL) and “Conceptual” (right, a set picture). Consistent across all ten slides.
- The set picture is two large overlapping circles, thick outline, unfilled, with plain black text captions above each (“Movie IDs from 1934”, “Movie IDs acted in by X”). Regions of interest are filled with a deliberately hand-drawn cyan scribble rather than a flat fill.
- Circle outline colour is tied to a query fragment: the left circle is crimson, the right circle is green (L3 pp. 154–161), and coloured vertical bars in the left margin of the SQL mark which block of the query computes which circle — a crimson bar beside the crimson circle’s subquery, a green bar beside the green circle’s subquery, a cyan bar beside the highlighted region.
- The source tables at the bottom carry matching header colours: crimson header on
StarsIn JOIN Movie(the crimson circle), green header onStarsIn (M2)(the green circle), purple header on ordinary sub-tables. L3 pp. 159–161. This colour-linking is the clearest example of colour carrying meaning anywhere in the course. - Progressive refinement: a natural-language description inside a cyan rounded rectangle stands in for a subquery not yet written, and is replaced by real SQL on the next slide. L3 pp. 154–158.
- Keywords in this section are bold black, not the plain black of the green query boxes elsewhere in L3.
Functional dependency notation
- An FD is written
X → Ywith a single-headed arrow, inline in prose and as a standalone caption. L4 pp. 22–24, 26, 27, 56–59, 62, 63, 66, 68, 69, 84, 85, 87–107. Throughout Module 4. - Composite sides are braced, single attributes are bare:
{houseNum, street, postcode} → {state, value}alongsidepostcode → statein the same FD set. L4 pp. 56–59, 88, 90, 93, 96, 102, 104, 106, 107. Consistent. - An FD set is written
F = { fd, fd, ... }, one FD per line, opening brace on theF =line. L4 pp. 56–59, 63, 66, 68, 69, 88, 89, 94, 96, 102, 104, 106. - Closure:
F⁺for the closure of a set of FDs;X⁺for the closure of an attribute set;{A, B}⁺ = {A, B, C}for a worked one. L4 pp. 34–37, 55, 57, 58, 61, 63, 67, 68, 85, 88, 90, 93, 96, 99, 100. Consistent. - Colour in FD statements: the determinant (LHS) is written in purple, the dependent (RHS) in magenta/plum —
level → salary,B → A,postcode → state. L4 pp. 22, 24, 26, 57, 58, 62, 63, 68, 69, 85, 87, 90, 93. Consistent whenever an FD is called out as the subject of the slide; FDs appearing incidentally inside anF = {...}set stay black. - Derived results — closures, candidate keys, resulting relation schemas — are written in purple. L4 pp. 57, 66, 68, 85, 90, 93, 106, 107. Consistent.
- The formal tuple-comparison form is
if t1[X] = t2[X] → t1[Y] = t2[Y], with square brackets for tuple projection. L4 p23; alsot₁[FK] = t₂[PK]at L2 p28. - Definition boxes are light-grey rectangles with a thin black border and the defined term in bold dark red; a matching white box with a bold black
Exampleheading sits directly under it. L4 pp. 14, 16, 52, 56–58, 62, 63, 68, 88, 105. Consistent through Module 4.
Decomposition and normalisation figures
BCNF decomposition tree — the most distinctive Module 4 figure, and drawn identically every time:
- A binary tree running top-down. Each node is a white rectangle with a thin purple border containing
Rn [A, B, C]. - Parent joins its two children with two thin plain purple lines forming an inverted V.
- The violating FD is written as a plain black label in the crotch of the V —
B→C,{A, B}→C,D→E,A→B. - Left child =
Q1 [Q − Y], right child =Q2 [X ∪ Y]. This ordering never varies. L4 pp. 85, 90, 91 (all four multiple-choice variants), 93. Consistent — four slides plus four distractors. - The result is stated in a light-grey, black-bordered banner spanning the slide:
Final answer: R2 [B, C], R3 [D, B], R4 [D, A]. L4 pp. 85, 90, 93.
The Q1 / Q2 mnemonic: two horizontally overlapping ellipses, black outline, no fill; the left labelled Q1 containing “Others” and X, the right labelled Q2 containing X and Y, with X in the overlap in its own small ellipse. Reproduced verbatim on L4 pp. 84, 85, 87, 90, 92, 93. Consistent.
Minimal-cover step table: columns headed Step 1 / Step 2 / Step 3 (/ Final) with a purple header and white bold text; body cells in pale mauve-grey #D0CCD7; one FD per line; the FDs changed at that step picked out. L4 pp. 98, 99, 100, 102.
Minimal-cover flow diagram (the “Visualised” slides, L4 pp. 101, 103) — a Sankey-like trace, and the arrow style is meaningful:
- Horizontal light-grey bands, one per step, labelled at the far left (
Step 1: RHS simplification, …,Final Answer,Final with Union). - Each FD is a small white rectangle with a black border.
- A thin black arrow with an arrowhead = this FD was transformed at this step (split into several, or shortened).
- A thin grey vertical line with no arrowhead = this FD passed through unchanged.
- A box labelled
Removedis the sink for FDs deleted at Step 3. Both slides use it identically.
Algorithm / pseudocode boxes: light-grey fill, thin black border, plain proportional text using :=, { } blocks, While ( ) { }, For each X → Y in G { }, ∅, ∪, ⊂. The line being emphasised on that slide is turned bold red. L4 pp. 84, 87, 92, 95, 105. Consistent.
Decomposition arrows: a thick UQ-purple block arrow labelled decomposition in red (L4 p14) or Decompose / Join in black (L4 p18); or a purple bracket fanning from the parent table down to the two child tables (L4 p26, L3-style). Two idioms for one idea.
Mathematical and logical symbols in use
Recorded so a new note does not invent alternatives: ⊂ (proper subset, L4 pp. 56, 58, 63, 68, 88), ∈ (L4 pp. 56, 58, 63, 99), ∪ (L4 pp. 84, 86, 88, 95, 105), ∅ (L4 pp. 95, 105), ≠ (L4 p96), ⊨ (entailment, L4 p93 — single occurrence), F⁺, X⁺, G'⁺.
Transactions
Only two slides in the whole sampled set (L2 pp. 43, 44), and neither carries a diagram — the transaction concept is prose plus an SQL example. There is no transaction-diagram notation in this course.
Figure sources and textbook lineage
- The course textbook is named on L0 p8: Elmasri & Navathe, Fundamentals of Database Systems (edition not stated on the slide; linked via UQ Library). No figure caption in the sampled pages names a source, but several figures are visibly lifted from that textbook and are drawn in its style, not the course’s:
- The instance-level
EMPLOYEE / WORKS_ON / PROJECTfigures with grey-filled ellipses, italice₁ … e₇,r₁ … r₇,d₁ … d₃labels and square dots for relationship instances — L1 pp. 31, 32, 33. - The three-schema architecture figure (green “External View” boxes, black box with yellow “Conceptual Schema” text, navy “Internal Schema” bar, gold DB cylinders, blue mapping captions) — L0 pp. 60, 61, 62. Also the red/green/navy DBMS block diagram at L0 pp. 42, 43, 48.
- The EER superclass/subclass figure with white-filled, purple-outlined rectangles and ellipses — L1 p47. These use palettes and shape conventions found nowhere else in the course. Treat them as quotations, not as the house style.
- The instance-level
- L0 p47 shows a MySQL Workbench EER model screenshot — crow’s-foot / IE-style boxes listing typed columns. It is a screenshot of the practical tooling, not a notation the course asks you to draw.
- L3 p102’s join Venn diagrams are an imported graphic with
inner_join(x, y)-style captions.
Inconsistencies
Recorded, not resolved. Each of these needs an explicit decision before the first diagram that touches it.
- How
NULLis spelled. UppercaseNULL(L2 pp. 12, 13, 27, 28, 29), lowercasenull(L2 p74; L4 p54; L3 p91 body text), and title-caseNull(L3 p103). All three within the same course. - String literal quoting in SQL. Double quotes —
gender = "Male"(L3 p56),M.title LIKE "Gone with the Wind"(L3 p95). Single quotes —WHERE gender = 'female'(L3 p60),'Giants'(L3 p58),b = 'X'(L3 p118). Both appear in worked, correct queries. - Attribute-name case in table headers vs. schema text. The schema line says
Employee [id, name, salary, department](lowercase) while the very same slide’s instance table has headersID Name Salary Department(capitalised) — L2 p15, and the same split on pp. 27–29, 35, 36. L4 p60 goes further and mixes them inside one schema:Employee [ID, name, level, salary]. Module 3 is consistently lowerCamel in both places (L3 pp. 51, 60), but L3 p49’s schema box usesMovie [MovieID, Title, Year]while L3 p51’s usesMovie [movieID, title, year]— the same relation, two slides apart. - The same relation’s key attribute is named two ways.
Department.idin the FK caption butNumberas the table’s first column header — L2 pp. 31, 33 versus pp. 27, 28. - Which colour means “newly added” in a mapping box. Red on L2 pp. 50, 55, 61, 65–68, 71, 72; green on L2 p62 (
mgrSSN, mgrStartDate), where purple simultaneously means “relation name” and green means “attribute name”. - Two idioms for progressive schema build-up. Grey-out-the-old (L2 pp. 54, 57, 63, 69, 73) versus bold-the-new (L2 pp. 89–93). Same deck, same worked example genre.
- Whether FK constraint lines are italic. Italic on L2 pp. 56, 62, 67, 68, 71, 72, 86 and on every “Schema (in progress)” slide; upright on L2 pp. 50, 55, 61, 65, 66 and on L2 pp. 90–93.
- The arrow
→is overloaded. It is the FD arrow everywhere in Module 4, but L4 pp. 59 and 64 also use it for a foreign key:Address.postcode → Postcodes.postcode,StaffAppointment.level → StaffIncome.level— where the guide and all of Module 2 sayX.fk references Y.pk. Two different relations written with one glyph. - Weak-entity and identifying-relationship double lines are drawn in two colours. Black in the Notation Guide (L1 p50) and in L1 pp. 43, 44 and L2 pp. 48, 55, 58, 88 — but crimson on L1 pp. 41, 42, where the
INSURESdiamond is also filled blue instead of magenta. ⊂rendering. An open arc on the line (L1 pp. 46–49, 51; L2 pp. 48, 85) versus small arrowhead-like glyphs pointing from thedcircle down at the subclasses (L2 p83). Same meaning, two glyphs.- FD attribute case in Module 4.
level → salary(L4 pp. 22, 24, 26) versusLevel → Salary(L4 p27) — consecutive slides, same FD. - What is emphasised in the minimal-cover step table. Bold red for the changed FDs on L4 pp. 98–100; bold black on L4 p102.
- Minor label drift in the same figure repeated.
Removed(L4 p101) vsremoved(L4 p103);Final W/ Union(p101) vsFinal with Union(p103);Step 3: FD set simplification(p101) vsStep 3: FD removal(p102). - Venn-diagram idiom. Hatched black-and-white (L3 p106) versus colour-filled (L3 p102) — and the “Conceptual” circles change colour mid-run: purple right-hand circle on L3 pp. 152, 153, green on pp. 157–161.
- Relation-name label placement. Bold above the table (most of L2/L4) vs to the left of the table (L2 pp. 31, 33; L3 pp. 90, 149, 150; L4 pp. 14, 16).
- ER shapes in Module 4 are unfilled. L4 pp. 9 and 22 draw an ER fragment with a white rectangle with a black border and bold black text and white ovals — not the purple/grey fills the Notation Guide mandates.
- Result-table colouring for a derived relation. L3 p88 gives the Cartesian-product result a blue header and blue-tinted rows to distinguish it from its purple-headed operands; every other result table in the course is purple. One-off.
- Terminating semicolons on SQL — present on some worked queries, absent on others, with no visible rule (see SQL section for citations).
Not established by the source
Where a future INFS1200 diagram will have to invent something. Be candid about these rather than quietly picking a convention.
- Everything about Module 5 (Database Security). There is no security deck in the source set — only roadmap bullets naming “Database Security Issues / Access control mechanisms / Other Control Measures / SQL Injection” (L0 p63, L3 p2, L4 p3). So there is no established notation for access-control matrices, authorisation/
GRANT–REVOKEgraphs, role hierarchies, discretionary-vs-mandatory access diagrams, or SQL-injection attack flows. Anything drawn for database-access-control, sql-injection or 2026-05-11-database-security is invention, and should say so. - Selection and projection as algebra. No
σ, noπanywhere in the sampled pages. If a note needs to write a projection algebraically there is no course-sanctioned form; use SQL or prose instead. - Rename in algebra.
ρnever appears; renaming is taught only as SQLAS/ qualification (L3 pp. 86, 87). - A symbol for division.
÷appears in figures and/in prose, but the course never states which to write in an answer. - Transaction diagrams. No schedule diagrams, no precedence graphs, no ACID/state figures — the transaction concept is prose only (L2 pp. 43, 44).
- Concurrency, recovery, indexing, storage. Named as DBMS functions in L0 pp. 50–55 but explicitly deferred to later courses (L0 pp. 43, 48); no figures.
- Any notation for
n-ary relationship instance sets. Cardinality for ternary relationships is discussed (L2 pp. 78–80) but the ball-and-line instance diagram is only ever drawn for binary relationships (L1 pp. 30–33). - Whether a subclass box may carry its own key attribute in a drawn EER diagram; the drawn examples only ever give subclasses non-key attributes (L1 pp. 47, 48; L2 p48).
- Line-crossing / routing style in ER diagrams. All sampled diagrams are small enough to avoid crossings; there is no established jump, gap or corner convention.
- Figure captions and numbering. No figure in any sampled deck carries a number or a caption in the “Figure N:” sense; figures are titled only by the slide heading. There is therefore no cross-reference convention to copy.
- Fonts and stroke weights are PowerPoint defaults (Arial-like sans throughout); no monospace font is used for SQL or pseudocode anywhere, which is worth knowing before a note renders SQL in a code font and diverges from the source.
- Dark-mode / print-safe variants. Every figure assumes a white background; the purple/magenta/grey palette has no stated alternative.
Integrity Constraints
Integrity constraints are the rules that enforce the correctness of a database: conditions stated on the schema that must hold on every instance of it. A DBMS’s job is to reject any operation that would leave them unsatisfied. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and practised in week4-tutorial-applied-class-3-relational-integrity; these are constraints on a relational schema, distinct from the relationship-constraints placed on an ER diagram.
The five kinds
| Constraint | Violated when | Enforced by |
|---|---|---|
| Domain | An attribute’s value isn’t a member of its domain | The column’s declared type/format |
| Key | Two tuples share the same value for a key | The declared key |
| Entity integrity | Any part of a tuple’s primary key is NULL |
The declared primary key |
| Referential integrity | A non-null foreign key value matches no primary key value in the referenced relation | The declared foreign key |
| Semantic | A business rule that isn’t derivable from the schema’s structure is broken | Application-level rules — triggers, assertions, CHECK |
The first four are structural: they follow from the schema itself, so the DBMS enforces them for free once the types and keys are declared. The fifth is not — nothing in the schema’s shape implies it, so it has to be stated separately.
Enforcement is unconditional and the default outcome is refusal: any insert, modification or deletion submitted to the DBMS that would violate integrity — that would leave the database in an inconsistent state — must be rejected. The only constraint whose violation has other sanctioned outcomes is referential integrity on a delete, and only because the foreign key was declared with a policy saying so (see update-operations-and-constraint-violations).
Which operation can break which constraint is not symmetric, and the asymmetry is examinable:
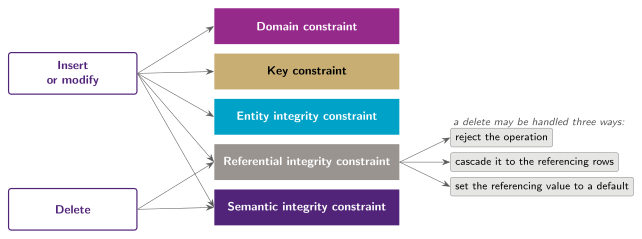
Figure 42: Insert and modify can violate all five constraints; delete can only violate the last two, and a referential violation on delete has three sanctioned outcomes rather than one. The banner colours are the course’s fixed fills for the five constraint types.
A delete cannot break a domain, key or entity-integrity constraint because it adds no value and duplicates no key — it can only strand something that was pointing at the row it removed, or break a business rule about what must continue to exist.
Domain constraint
The domain is the set of legal atomic values for an attribute (see relational-model), so a domain violation is simply a value that isn’t in that set. Employee.id = "LOL" violates it when id is a four-digit integer.
The domain need not be a plain data type — a format counts. A bank rejecting the password password123 with “your password must contain at least one capital letter and a number” is enforcing a domain constraint: the domain of password is defined as the strings matching that format, and password123 isn’t a member of it. Likewise a course code declared as four letters followed by four digits, or an enumerated domain: inserting VehiclePurpose = 'Personal' when the column is ENUM('Private', 'Business') is a domain violation, not a semantic one.
The commonest exam version of a domain violation is subtler — a value of the wrong kind in the right position. Inserting (2644, James, Smith, 1) into Employee [id, name, salary, department] breaks the domain constraint because the third value lands in salary, whose domain is integer or float, not a surname.
Key constraint
No two tuples may share a value for a key. Violated by inserting a tuple whose key duplicates an existing one, or by modifying an existing tuple into a duplicate. See relational-keys for what qualifies as a key in the first place.
Entity integrity constraint
No part of a primary key may be NULL — for a composite primary key, no component may be null, not merely “not all of them”. Inserting (677678989, null, 40.0) into WorksOn [essn, pNo, hours] violates entity integrity because pNo is half of the primary key.
The rationale is that the primary key is the relation’s identity: a tuple with an unknown key value cannot be distinguished from, or referred to by, anything. This is the one place a NULL is categorically banned — sql-nulls has the table of which declarations do and don’t permit one.
Referential integrity constraint
A non-null foreign key value must match some existing primary key value in the referenced relation. Inserting an Employee with department = 5 when no Department has id = 5 violates it; so does deleting Department 5 while employees still reference it, and so does updating a foreign key to a value that doesn’t exist. NULL is always allowed — see foreign-keys for the formal statement.
Semantic (business-rule) constraint
Semantic constraints are defined by the business or organisation during client consultation — they come from the organisation, not from the data structure:
- “An employee’s salary must not exceed their supervisor’s.”
- “The maximum number of hours an employee can work on a project is 56.”
- “A department cannot have more than three active projects at a time.”
- “A customer must be at least 18 years old.”
Take the first and third. Inserting Grace Chan on 58000 with superSSN = 888665555 — James Borg, on 55000 — violates the salary rule and nothing else; inserting a fourth project for department 5, which already has ProductX, ProductY and ProductZ, violates the three-project rule and nothing else. In both cases every structural check passes, which is exactly the signal that the answer is “semantic”.
Nothing about the relations’ shape rules these out, so they’re expressed in a constraint specification language — in SQL’s case, the mechanisms are CHECK clauses, assertions and triggers. This course files the latter two under DCL, alongside transaction control and privilege management. Only CHECK is developed and examined (see sql-ddl for the CHECK and named-constraint syntax); assertions and triggers are the general-purpose fallback and are not defined further, so “enforced by an assertion or a trigger” is as far as the course goes. This is also the category to fall back on when asking “which constraint does this break?” and none of the structural four apply.
The converse matters just as much: a rule that was never stated isn’t a constraint. Updating Department (2, Development, 1751) to (2, Development, 2034) where employee 2034 works in a different department violates nothing, unless the business rule “a manager must work in the department they manage” has actually been specified.
Naming an example of each
The other exam shape is the reverse: given a schema, point at one instance of each kind of constraint. For the enrolment schema
Student [stID, name, email]
Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode
Course [cCode, title, units]a key is stID in Student, a foreign key is stID in Enrolment, and a domain constraint is cCode being four letters followed by four digits. stID supplies both of the first two answers depending on which relation it is read in — the same attribute name is a key where it identifies and a foreign key where it refers.
Diagnosing a violation
Given an operation and a schema, work down the five in a fixed order. The order isn’t significant in itself; checking all five every time is, since one operation can break several at once.
- Domain — is every value of the right type/format for its column?
- Key — does this key value already exist?
- Entity integrity — is any part of the primary key null?
- Referential integrity — does every non-null foreign key point at a row that exists? And, for a delete, does anything still point at the row being removed?
- Semantic — does it break a stated business rule?
A single operation can violate more than one at once. Inserting ('ProductA', 'A', 'Bellaire', 2) into Project [pName, pNumber, pLocation, dNum] breaks both the domain constraint (pNumber is an integer, not 'A') and referential integrity (no department 2). Inserting ('Production', 4, 943775543, …) into Department breaks the key constraint (dNumber = 4 exists) and referential integrity (mgrSSN isn’t a real employee). Don’t stop at the first one found.
And the operations that violate nothing
Three of the applied class’s ten answers are “No”, and they are the ones worth rehearsing, because each looks like a violation and isn’t:
| Operation on the company schema | Why it is legal |
|---|---|
Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into EMPLOYEE |
Fresh ssn, every value in its domain, superSSN 888665555 and dNo 1 both exist, and 50000 is under the supervisor’s 55000 |
Delete the WORKS_ON tuples with essn = 333445555 |
Nothing references WORKS_ON, so no reference is stranded |
Modify DEPARTMENT’s mgrSSN/mgrStartDate for dNumber = 5 to 123456789 and '1988-10-01' |
123456789 is a real employee (John Smith), so the foreign key still resolves, and no other constraint touches the manager column |
Compare that last row with the case where the new manager works in a different department: it still violates nothing. A manager who works elsewhere offends intuition, not any declared constraint.
See update-operations-and-constraint-violations for which constraints each kind of operation can possibly violate, and what a DBMS does about it; sql-dml shows the same violations as the error messages MySQL actually returns.
Interpreting ER Diagrams
Drawing a diagram and reading one are different skills, and the applied classes test the second at least as hard as the first: given an ER/EER diagram and a plain-English claim about the world, decide whether the diagram actually says it. Practised in the statement-evaluation questions in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd and week3-tutorial-applied-class-2-entity-relationship-diagrams, and in the questions in 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices. See er-diagram-notation for what each symbol is.
The checklist
| If the claim is about… | Check | Trap |
|---|---|---|
| How many X per Y | The cardinality ratio, from the far side | Reading 1:N in the wrong direction |
| Whether every X does something | Participation (double vs single line) | Assuming total participation because the relationship exists |
| Uniqueness of an attribute | Whether that attribute is underlined | Treating a non-key attribute as if it were unique |
| “Only identifiable by…” | Whether a second key oval exists | Missing a second candidate key |
| A weak entity’s identity | Owner’s key + partial key | Treating the partial key as a full key |
| An instance being two kinds at once | d vs o on the specialisation circle |
Reading two separate circles as one |
| A relationship’s degree | Count the lines into the diamond | Calling a pair of binaries “ternary” |
| Whether a given relationship set is possible | Every cardinality ratio and every participation constraint, tuple by tuple | Checking the ratios and forgetting the double lines |
Cardinality: read it from the far side
A 1:N relationship constrains both ends, and the interesting constraint is usually the one on the “many” side. HEALTHWORKER —1:N OVERSEEN→ HEALTH means one health worker can oversee many participants, and therefore each participant has at most one overseeing health worker. “A participant can be overseen by several healthcare workers” is incorrect against that diagram — a claim that reads naturally in English and is contradicted by the diagram in the direction most people don’t check. See relationship-constraints.
An M:N relationship with no distinguishing attribute also says something: each pair appears at most once. An athlete/event pair in a plain PARTICIPATES relationship cannot be recorded twice, so “an athlete cannot participate at the same event more than once” is correct. Making repeats possible requires a distinguishing key attribute (a Timestamp, say) or a weak entity — see er-design-choices.
Participation: absence of a double line is a fact
Total participation (double line) says every instance must participate; partial participation (single line) says it need not. Both are claims, and the partial one is easy to skip over:
- The recursive
WITHrelationship onVACCINEis partial on both sides, so “each vaccine must have a second dose or a preceding dose” is incorrect — the relationship allows a two-dose program, it doesn’t require one. OVERSEENhas total participation on theHEALTHside, so “every participant in the HEALTH subclass is overseen by a health worker” is correct.- Some venues are backups and never host an event, which is exactly why
VENUE’s participation inHOSTSis partial — “all venues must host an event” is incorrect.
Keys: what isn’t underlined can repeat
If an attribute isn’t marked as a key, the diagram is asserting nothing about its uniqueness — so two different venues may share an Address when only ID is underlined. Conversely, HOTEL.Address being the key attribute is what makes “two hotels can share an address” false.
Claims of the form “X can only be identified by Y” need the whole attribute list checked, because entity types routinely have more than one candidate key: VACCINE has both ID and the composite Brand + Name, so “a vaccine can only be identified by the combination of its brand and name” is incorrect. See entity-types-and-attributes.
Weak entities: the partial key is not the key
A weak entity’s partial key is unique only within its owner, so any claim that treats it as globally unique is false. The hotel/room question is the canonical case: ROOM’s real key is (HOTEL.Address, ROOM.Number), so neither “no two rooms share a number” nor “no two hotels have rooms with the same number” holds — room numbers repeat freely across hotels, which is the entire reason ROOM is weak. The same logic makes “a BATCH is uniquely identified by only its number” incorrect, and makes an emergency contact named “Mum” registrable by two different users.
The hotel/room question is also a reminder that “none of the above” is a live option: with HOTEL.Address as the key and ROOM.Number as a partial key, every uniqueness claim on offer — two hotels sharing an address, no two rooms sharing a number, no two hotels having rooms with the same number — is false at once.
Checking a candidate relationship set
A second question format hands you a small diagram plus several candidate relationship sets written out as tables of tuples, and asks which one is possible. It is mechanical once you know the two things to check:
| Notation on the diagram | What it forbids in the table |
|---|---|
A 1 on E’s side of R |
An entity of E appearing in more than one row of R |
An N or M on E’s side of R |
Nothing — that side is unconstrained |
| A double line between E and R | An entity of E appearing in no row of R |
Worked instance. Take A —N— R —1— B —N— S ═M═ C, with entity sets {a₁, a₂}, {b₁, b₂} and {c₁, c₂}. The 1 on B’s side of R means each a may appear at most once in R; the double line on C’s side of S means every c must appear somewhere in S; M:N on S constrains nothing else. So:
R = ∅,S = ∅fails —c₁andc₂are missing fromS.R = {(a₁,b₁)},S = {(b₂,c₂)}fails —c₁is still missing.R = {(a₁,b₁), (a₁,b₂)}fails —a₁appears twice, violating the1.R = {(a₁,b₂)},S = {(b₁,c₂), (b₂,c₁), (b₁,c₁)}is possible — noarepeats and bothcs appear.
Note that an empty relationship set is perfectly legal wherever participation is partial; it is only the double line that forces rows to exist. That is the half of the check people skip.
Subclasses: d and o are per circle
An overlapping (o) specialisation permits an instance to be in several subclasses at once, so “a participant can be in both the HEALTH subclass and the AGE subclass” is correct when those two hang off an o circle. A disjoint (d) specialisation forbids it. The per-circle part matters: a superclass with two separate specialisation circles constrains each one independently, and membership in a subclass under one circle says nothing about membership under the other. See specialisation-and-generalisation.
Degree: count the lines
“EVENT has a ternary relationship” is incorrect when EVENT’s relationships are PARTICIPATES (to ATHLETE) and HOSTS (to VENUE) — two separate binary relationships, not one three-way one. An entity type participating in several relationships is not the same as participating in a high-degree relationship. See relationship-types.
Minimal Cover
A minimal cover (or canonical cover) G of an FD set F is an equivalent set of FDs with all the slack squeezed out — nothing can be deleted or shortened without changing what the set implies. It’s the required input to 3nf-synthesis, and it makes reasoning about BCNF easier by hand too. Introduced in 2026-05-04-normalisation-and-relational-database-schema-design.
Equivalence of FD sets
Two FD sets are equivalent when they imply exactly the same FDs: F⁺ = G⁺. Equivalence is what makes the reduction safe — a minimal cover constrains the data identically to the original set, it just says so with fewer, smaller rules.
Definition
The goal is to transform the FDs to be as small as possible while still implying exactly the same things.
G is a minimal cover for F iff:
- Equivalent —
F⁺ = G⁺. - Nothing redundant — deleting any FD from
G, or any attribute from any FD’s LHS, gives someG'withG'⁺ ≠ G⁺. Every FD and every LHS attribute is necessary.
Informally: every FD in G is needed, and is as small as possible, while still closing to the same set as F.
The smallest illustration: F = {A → B, B → C, A → {B, C}} reduces to G = {A → B, B → C} — the third FD asserts nothing the first two don’t already imply.
The textbook definition adds a third condition — single-attribute RHS, every FD in G having exactly one attribute on its right — but this course explicitly does not require it. Splitting the RHS is still the first working step, because condition 2’s tests are only correct per-attribute; but the answer may then be written back up with same-LHS FDs recombined ({E,F} → G and {E,F} → H as {E,F} → {G, H}). Both presentations are accepted, and 3nf-synthesis recombines them anyway as its second step.
Finding a minimal cover — three steps
The steps run in this order, and each is decided by an attribute-closure computation:
| Step | What to do | Test |
|---|---|---|
| 1. RHS simplification | Split every FD so its RHS is a single attribute: X → {Y, Z} becomes X → Y and X → Z |
— (always applies) |
| 2. LHS simplification | For an FD X → A whose LHS has several attributes, drop any attribute B that isn’t pulling its weight |
Replace X → A with (X - {B}) → A when (X - {B})⁺ = X⁺ |
| 3. FD set simplification | Delete any FD that the rest of the set already implies | Delete X → A if X⁺, computed without that FD, still contains A |
Two things make this reliable in practice:
- Do step 1 first, completely. A compound RHS can hide the fact that one of its attributes is redundant while another isn’t — the case-study
Departmentexample below is exactly that. - In steps 2 and 3, recompute the closure against the FD set as it currently stands, including edits already made. Each removal changes what the remaining FDs can derive.
Worked example — the mechanical case
R [A, B, C, D, E, F, G, H] with F = {A → B, {A,B,C,D} → E, {E,F} → G, {E,F} → H, {A,C,D,F} → {E, G}}:
| Step 1: RHS split | Step 2: LHS simplify | Step 3: delete redundant |
|---|---|---|
A → B |
A → B |
A → B |
{A,B,C,D} → E |
{A,C,D} → E (B redundant, since A → B) |
{A,C,D} → E |
{E,F} → G |
{E,F} → G |
{E,F} → G |
{E,F} → H |
{E,F} → H |
{E,F} → H |
{A,C,D,F} → E |
{A,C,D,F} → E |
dropped — {A,C,D,F}⁺ already contains E without it |
{A,C,D,F} → G |
{A,C,D,F} → G |
dropped — same reason (E then {E,F} → G) |
Minimal cover: {A → B, {A,C,D} → E, {E,F} → G, {E,F} → H}, often written with the last two recombined as {E,F} → {G, H}.
The B in {A,B,C,D} → E is the classic step-2 case: A → B already puts B in the closure of anything containing A, so naming it in the LHS adds nothing.
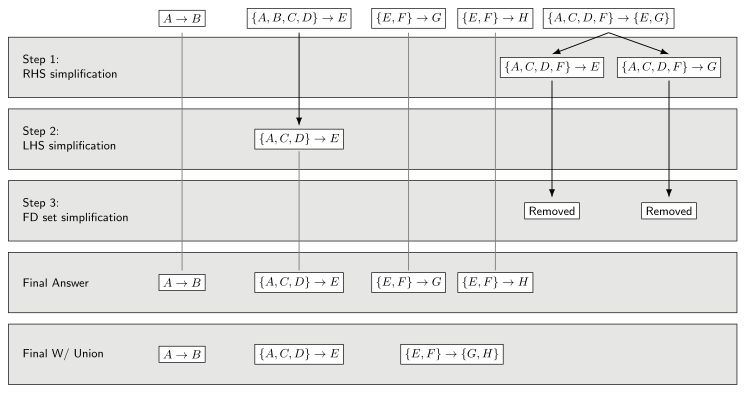
Figure 43: The same reduction seen as a flow, one band per step. Each original FD enters at the top; a black arrow means that step transformed it (split it, or shortened its LHS), a thin grey line means it passed through untouched, and the Removed boxes are where step 3’s closure test deleted an FD outright.
Worked example — a wide right-hand side
Here step 1 does almost all the work. R [C, S, J, D, P, Q, V] with
F = {C → {S, J, D, P, Q, V}, {J,P} → C, {S,D} → P, J → S}.
| Step 1: RHS split | Step 2: LHS simplify | Step 3: delete redundant |
|---|---|---|
C → S |
C → S |
dropped |
C → J |
C → J |
C → J |
C → D |
C → D |
C → D |
C → P |
C → P |
dropped |
C → Q |
C → Q |
C → Q |
C → V |
C → V |
C → V |
{J,P} → C |
{J,P} → C |
{J,P} → C |
{S,D} → P |
{S,D} → P |
{S,D} → P |
J → S |
J → S |
J → S |
- Step 2 changes nothing. Only
{J,P} → Cand{S,D} → Phave a compound LHS, and neither attribute can go:{J}⁺ = {J,S}and{P}⁺ = {P}both missC;{S}⁺ = {S}and{D}⁺ = {D}both missP. - Step 3 deletes two.
C → Sgoes becauseC → JthenJ → Salready reachesS.C → Pthen goes too: with it removed,Cstill reachesS(viaC → J,J → S) andDdirectly, and{S,D} → PsuppliesP. Neither removal depends on the other being made first — test them in the opposite order and both still come out redundant.
Minimal cover: {C → J, C → D, C → Q, C → V, {J,P} → C, {S,D} → P, J → S}, or with same-LHS FDs recombined, {C → {J, D, Q, V}, {J,P} → C, {S,D} → P, J → S}.
With C → P removed, the only surviving statement about P is {S,D} → P, which is exactly the FD 3nf-synthesis will turn into its own relation. Steps 2 and 3 are not tidying — they decide the shape of the schema you end up with.
Worked example — spotting a false answer
R [A, B, C, D, E, F] with {D,E,F} → C, {A,B} → {D, C}, D → F.
- Step 1 gives
{D,E,F} → C,{A,B} → D,{A,B} → C,D → F. - Step 2: in
{D,E,F} → C, isFredundant?{D,E}⁺already containsFviaD → F, so{D,E}⁺ = {D,E,F}⁺— yes. It becomes{D,E} → C. - Step 3: nothing further can go; all four are necessary.
Minimal cover: {{D,E} → C, {A,B} → D, {A,B} → C, D → F}.
The wrong answers to this question are instructive: keeping the redundant F in the first LHS (step 2 skipped), dropping {A,B} → C (it is not implied by the others — {A,B}⁺ without it reaches D and F, never C), or dropping D → F (which the simplified {D,E} → C now depends on).
Worked example — on a real schema
From week11-tutorial-case-study-9-payroll-system, the Department relation [code, name, manager, buildingID, buildingName, buildingLocation, floor] with code as the key, plus buildingID → {buildingLocation, buildingName} and buildingName → {buildingLocation, buildingID}.
After splitting the key’s FD into single-attribute FDs, step 3 removes three of them:
code → buildingName— derivable viacode → buildingIDthenbuildingID → buildingName.code → buildingLocation— derivable the same way.buildingID → buildingLocation— derivable viabuildingID → buildingNamethenbuildingName → buildingLocation.
Minimal cover: {code} → {name, manager, buildingID, floor}, {buildingID} → {buildingName}, {buildingName} → {buildingLocation, buildingID}.
Feeding that straight into 3nf-synthesis yields Department [code, name, manager, buildingID, floor] and Building [buildingName, buildingLocation, buildingID] — the transitive code → building… redundancy removed exactly because step 3 removed the transitive FDs.
Redundancy can hide behind a chain
Step 3’s test is “is A still reachable without this FD”, which catches FDs whose work is done indirectly by two or more others. From week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis, R [A, B, C, D, E, F] with A → {B,C,D,E,F}, {B,C} → A, {D,E} → B, C → D:
A → Bis redundant —A → D,A → E, then{D,E} → B.A → Dis redundant —A → C, thenC → D.
leaving A → {C, E, F}, {B,C} → A, {D,E} → B, C → D. Neither removal is visible from a single FD; both need the closure test.
See also
- 3nf-synthesis — the algorithm that consumes a minimal cover
- attribute-closure · functional-dependencies · normal-forms · [decomposition]
- 2026-05-04-normalisation-and-relational-database-schema-design — Module 4, part 2
- week11-tutorial-applied-class-10-normalisation-bcnf-3nf-synthesis · week11-tutorial-case-study-9-payroll-system — practice
Normal Forms (1NF to BCNF)
Normalisation is the process of putting a relation schema through a series of tests — defined in terms of its FDs and its keys — to certify which normal form it satisfies. A schema that fails a test is decomposed into smaller relations with better properties. Put another way, it is the process of identifying redundancy in data: an FD A → B is precisely the statement that every tuple sharing an A value is forced to repeat the same B value, and each normal form rules out a different way that forcing can go wrong. Introduced in 2026-05-04-normalisation-and-relational-database-schema-design.
Each normal form names a class of redundancy and rules it out. The guarantees stack: BCNF ⊂ 3NF ⊂ 2NF ⊂ 1NF, so a BCNF relation is automatically in all the others, and the “highest normal form” of a relation is the strictest test it passes.
Overview
| NF | Identifies | Test — for every non-trivial X → A in F⁺ |
|---|---|---|
| 1NF | Non-atomic values | Relation has no multivalued attributes or nested relations |
| 2NF | Partial dependencies (removes some anomalies) | X is not a proper subset of a candidate key, or A is a prime attribute |
| 3NF | Partial + transitive dependencies (removes most anomalies) | X is a superkey, or A is a prime attribute |
| BCNF | All anomalies — at the cost of not preserving all FDs | X is a superkey |
Note the tests quantify over F⁺, not F — implied FDs count too (see functional-dependencies). Trivial FDs are always exempt.
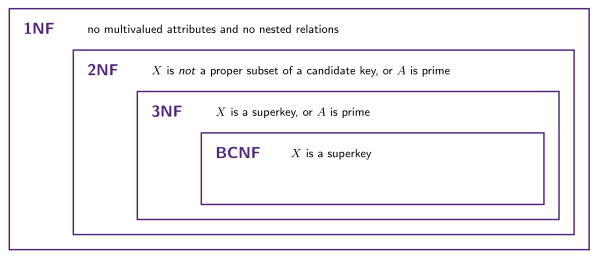
Figure 44: The four normal forms nest: each test is the previous one with an escape hatch removed, so a relation in an inner band is automatically in every band outside it. Each band carries its one-line test, and every test reads for every non-trivial X → A in F⁺.
Read the figure from the inside out and the whole module fits on one line: BCNF asks only that every determinant is a superkey; 3NF adds the escape hatch “…or the determined attribute is prime”; 2NF weakens the superkey demand to “not a proper subset of a key”; 1NF stops asking about FDs at all and only asks that the values be atomic.
What you need before testing
Every test above mentions candidate keys or prime attributes, so the first step is always the same: compute all candidate keys with attribute-closure, then mark each attribute prime (in at least one candidate key) or non-prime. Doing this against only the primary key is the most common source of wrong answers — 2NF’s “proper subset of a candidate key” clause and 3NF’s “or A is a prime attribute” escape hatch both depend on every candidate key, and a relation with several keys can pass against one and fail against another.
First Normal Form (1NF)
A relation is in 1NF if every attribute’s domain contains only atomic (simple, indivisible) values — no set of values, no tuple of values (nested attributes), and no combination of the two.
An items column holding a comma-separated list violates 1NF; so does a name attribute that nests into {firstName, familyName}. Both standard ways of fixing it are unsatisfying:
- Repeat the non-nested columns once per value — one row per
(customerName, orderNum, item)— which introduces redundancy; or - Flatten into fixed columns (
item1,item2, …) — which caps how many items an order can have and forces nulls on the shorter ones (guideline 3 of update-anomalies).
That neither option is good is exactly the motivation for 2NF/3NF/BCNF, which say how to decompose an already-1NF relation.
Full and partial dependencies, and 2NF
X → Yis a full functional dependency if removing any attribute fromXbreaks it — no proper subset ofXdeterminesY.X → Yis a partial dependency if some attribute can be dropped fromXand the FD still holds.
A relation R is in 2NF if every non-prime attribute is fully functionally dependent on the primary key — informally, no partial dependency on a key.
Primary key or all candidate keys? The informal sentence above says “the primary key”. The formal definition — the one given alongside every exam question, and the one that decides marks — is stated over candidate keys:
Rwith FD setFis in 2NF iff, for every non-trivialX → AinF⁺withX ⊂ RandA ∈ R, either (1)Xis not a proper subset of a candidate key forR, or (2)Ais a prime attribute.
Use the formal version. It differs from the primary-key reading whenever a relation has more than one candidate key: a partial dependency on any candidate key breaks 2NF, not just one on the key you happened to nominate as primary. It also gives you a free shortcut in the other direction — if every attribute is prime, clause (2) is satisfied by every FD, so the relation is automatically in 2NF (and in 3NF).
Example — Address [houseNum, street, postcode, state, value] with {houseNum, street, postcode} → {state, value} and postcode → state. The only key is {houseNum, street, postcode}.
{houseNum, street, postcode} → valueis full — no subset of the LHS determinesvalue.{houseNum, street, postcode} → stateis partial —postcodealone already suffices.
state is non-prime and only partially dependent on the key, so Address is not in 2NF. Decompose into Address [houseNum, street, postcode, value] and Postcodes [postcode, state] with Address.postcode references Postcodes.postcode.
2NF doesn’t fix much. Employee [id, name, level, salary] with level → salary satisfies 2NF — level isn’t a proper subset of the key {id}, it’s a whole non-key attribute — yet it still has all three anomalies from update-anomalies. 2NF only catches redundancy hanging off part of a composite key.
Transitive dependencies, and 3NF
X → Y in R is a transitive dependency if some attribute set Z exists such that Z is neither a candidate key nor a subset of one, and both X → Z and Z → Y hold — i.e. Y depends on X only through an intermediate that isn’t a key.
In Employee [id, name, level, salary] with level → salary: level is neither a candidate key nor part of one, id → level holds and level → salary holds, so id → salary is a transitive dependency.
R is in 3NF iff, for every non-trivial X → A in F⁺, X is a superkey or A is a prime attribute. Equivalently: whenever A is non-prime, X must be a superkey.
level → salary fails both halves — level isn’t a superkey and salary isn’t prime — so Employee violates 3NF. Decompose into StaffAppointment [id, name, level] and StaffIncome [level, salary].
3NF still isn’t always enough. Teach [studentID, courseID, lecturer] with {studentID, courseID} → lecturer and lecturer → courseID (keys: {studentID, courseID} and {studentID, lecturer}) is in 3NF — lecturer → courseID escapes via the prime-attribute clause, since courseID is prime. Yet:
- Deletion anomaly — deleting the last row for a
(studentID, courseID)pair can destroy the only record of who teaches that course. - Insertion anomaly — you can’t record which lecturer teaches a course that currently has no enrolled students.
Partial vs transitive, in one line each
The distinction is a recurring exam question, and the marked answer is phrased like this:
A partial dependency is where an attribute depends on only a subpart of the primary key; normalising to 2NF solves it. A transitive dependency is where a non-prime attribute depends on other non-prime attributes; normalising to 3NF solves it.
The trap in the distractors is the swap — attaching partial dependencies to 3NF and transitive ones to 2NF.
Boyce-Codd Normal Form (BCNF)
R is in BCNF iff, for every non-trivial X → A in F⁺, X is a superkey. Informally: whenever a set of attributes determines anything, it must determine everything. BCNF is 3NF with the prime-attribute escape hatch removed.
In Teach, lecturer → courseID now fails — lecturer is not a superkey — so Teach is not in BCNF even though it is in 3NF. That gap between 3NF and BCNF is exactly the set of relations where 3NF’s prime-attribute clause is letting an anomaly through.
BCNF is strictly stronger, but not strictly better: decomposing to reach it can lose FDs that 3NF would have kept.
3NF or BCNF? What each one buys
Real designs aim for one of these two, and the choice is a straight swap:
| Removes all anomalies | Preserves all FDs | |
|---|---|---|
| BCNF | ✓ | ✗ |
| 3NF | ✗ | ✓ |
Neither dominates. BCNF eliminates the redundancy but a BCNF decomposition may scatter an FD’s attributes across relations so that the constraint can no longer be checked without a join; 3NF keeps every FD checkable inside a single relation but leaves the Teach-shaped anomalies above in place. See [decomposition] for dependency preservation and the BCNF algorithm, and 3nf-synthesis for the algorithm that guarantees the 3NF side of the table.
Determining the highest normal form
- Compute all candidate keys (attribute-closure); mark prime and non-prime attributes.
- Split every FD so its RHS is a single attribute — the tests are stated per-attribute, and a compound RHS can pass on one attribute and fail on another.
- Test each non-trivial FD
X → Afrom the strictest end down: isXa superkey (BCNF)? If not, isAprime (3NF)? If not, isXa proper subset of a candidate key (breaks 2NF) or not (breaks 3NF only)? - The relation’s normal form is the strictest one no FD violates.
| Relation and FDs | Candidate keys | Highest NF | Why |
|---|---|---|---|
R [A,B,C,D,E], A → {B,C,D,E}, E → A |
{A}, {E} |
BCNF | Every FD’s LHS is itself a superkey |
R [A,B,C,D], {A,B} → {C,D}, {C,D} → A, D → B |
{A,B}, {C,D}, {A,D} |
3NF | Every attribute is prime, so nothing can break 3NF; but D → B has a non-superkey LHS, breaking BCNF |
R [A,B,C,D], {A,C,D} → B, {A,C} → D, D → C, {A,C} → B |
{A,C}, {A,D} |
3NF | D → C: D isn’t a superkey (not BCNF), but C is prime (3NF survives) |
R [A,B,C,D,E,F], {A,B} → {C,D,E}, C → F, E → {A,B} |
{A,B}, {E} |
2NF | No FD’s LHS is a proper subset of a key, so 2NF holds; C → F has a non-superkey LHS and non-prime RHS, breaking 3NF |
R [A,B,C,D,E], B → {C,D}, A → E |
{A,B} |
1NF | Both A and B are proper subsets of the key with non-prime RHSs — partial dependencies, breaking 2NF |
R [A,B,C,D,E,F], {A,E} → D, {B,C} → A, B → F, F → E |
{B,C} |
1NF | B → F is a partial dependency: B ⊂ {B,C} and F is non-prime |
The fourth and fifth rows are the pair worth internalising — the same shape of violation (non-superkey LHS, non-prime RHS) lands on 3NF or 2NF purely depending on whether the LHS sits inside a candidate key.
A subtlety from the tutorial: in R [A,B,C,D,E,F,G] with A → {B,C,D}, D → A, C → {F,G} (keys {A,E} and {D,E}), splitting A → {B,C,D} gives A → B, A → C and A → D. The first two are partial dependencies (A ⊂ {A,E}, and B/C are non-prime) so the relation is only in 1NF — but A → D is not a partial dependency, because D is prime (it appears in key {D,E}). That’s why step 2 above insists on splitting the RHS first.
Denormalisation
Since anomalies come from redundancy it’s tempting to decompose as aggressively as possible — but a heavily decomposed schema needs more JOINs to answer the same query. Denormalisation is the deliberate, controlled relaxation of a normal form to improve query performance: fewer joins (faster queries) and fewer foreign keys (less storage and maintenance overhead), which suits analytical workloads or a small set of very frequent pre-joined queries.
The word “deliberate” is load-bearing. Denormalisation is a trade-off made knowingly, accepting the anomalies it reintroduces — not an excuse for a schema that was never normalised in the first place.
See also
- functional-dependencies · attribute-closure · [decomposition] · 3nf-synthesis · minimal-cover
- update-anomalies — the anomalies each normal form is removing
- 2026-05-04-normalisation-and-relational-database-schema-design — Module 4, part 2
- week10-tutorial-applied-class-9-functional-dependencies · week10-tutorial-case-study-8-dirt-road-driving — highest-normal-form practice
Relational Division
Division is the operation that answers “for all” / “for every” questions — find the X that are related to every Y, such as the movie stars who appeared in all the movies produced in a given year, or the employees who can access all the websites some other employee can. It is the one common query shape that neither a join nor a simple aggregate expresses directly, which is why it gets its own name and its own two standard SQL patterns. Introduced in 2026-04-13-nested-queries-views-and-generative-ai; applied in week9-tutorial-applied-class-8-nested-queries-and-views.
The operation
Dividing \(R1 / R2\) requires the operands to be division compatible: R1’s last \(n\) columns must be identically named to R2’s \(n\) columns, where \(n\) is R2’s degree. The result has R1’s columns except R2’s, and contains a value \(t\) only if \(t\) appears in R1 in combination with every tuple of R2.
Student Degree Subject Subject Student Degree
Anna BIT CS114 ÷ CS114 = Anna BIT
Anna BIT CS115 CS115
Anna BIT CS180
Fred BSc CS114
Fred BSc CS180Fred is excluded: he hasn’t taken CS115, so he doesn’t divide evenly by {CS114, CS115}. Two things about the shape of the result are easy to get wrong:
- The result is narrower than R1 — it keeps only the columns not contributed by R2. Dividing a 3-column relation by a 2-column one gives a 1-column answer, not whole 3-column tuples.
- Extra rows in R1 are harmless; only the required combinations matter. Anna still qualifies despite also having taken
CS180, which isn’t in the divisor at all.
Dividing the same relation by successively larger divisors shows how the demand tightens. With A [sno, pno] holding s1→{p1,p2,p3,p4}, s2→{p1,p2}, s3→{p2}, s4→{p2,p4}:
| Divisor | Requires | A / B |
|---|---|---|
B1 = {p2} |
p2 |
s1, s2, s3, s4 |
B2 = {p2, p4} |
p2 and p4 |
s1, s4 |
B3 = {p1, p2, p4} |
all three | s1 |
Every divisor row is an extra hurdle, so the result can only shrink as the divisor grows — a useful sanity check on an exam answer. And an empty divisor would be satisfied by everybody, which is the degenerate end of the same pattern.
In SQL
The first move on any division question is to name the dividend and the divisor before writing a line of SQL. “Find the movie star(s) who acted in at least all the movies produced in the year 1934” resolves to
StarsIn ÷ (the movieIDs of Movies from 1934) = the qualifying stars— the dividend is the relationship table, the divisor is the filtered set of things that must all be covered, and the result is the dividend’s remaining column.
SQL has no / operator for relations, so division is expressed either by counting or by double negation. Both are worth having ready: the counting form is shorter, while the double-negation form is a direct transcription of the logical reading of the question.
The two are the same picture read from opposite sides. Draw the movies produced in 1934 as one circle and the movies X acted in as another; X qualifies exactly when the first circle sits wholly inside the second.
| Form | What it checks |
|---|---|
| Counting | The overlap is as large as the whole first circle — X acted in as many 1934 movies as there are 1934 movies |
| Double negation | The part of the first circle outside the second is empty — there is no 1934 movie X did not act in |
Via counting
For a candidate X, count how many of the required Ys it is related to, and compare that against the total number of Ys. Equal counts mean X is related to all of them.
-- Star(s) who acted in at least all the movies produced in 1934
SELECT X.starID, X.name
FROM MovieStar X
JOIN StarsIn S ON X.starID = S.starID
JOIN Movie M ON S.movieID = M.movieID
WHERE M.year = 1934
GROUP BY X.starID
HAVING COUNT(*) = (SELECT COUNT(*) FROM Movie M2 WHERE M2.year = 1934);The WHERE M.year = 1934 restricts the count to the relevant movies, and the scalar subquery in HAVING supplies the target (sql-aggregation-and-grouping, sql-nested-queries).
Via double negation
Reformulate “X is related to every Y” as “there does not exist a Y that X is not related to”:
-- "Find X such that there is no 1934 movie which X did not act in"
SELECT starID, name
FROM MovieStar X
WHERE NOT EXISTS (
SELECT *
FROM StarsIn S
JOIN Movie M ON S.movieID = M.movieID
WHERE M.year = 1934
AND M.movieID NOT IN (
SELECT movieID FROM StarsIn M2 WHERE M2.starID = X.starID
)
);Read it inside out: the innermost subquery is “all the movies X acted in”; the middle one is “1934 movies X did not act in”; the outer NOT EXISTS says “there is no such movie” — i.e. X acted in every one. The correlation on X.starID is what makes the inner queries mean “this star” rather than “any star”.
Recognising it in the wild
The giveaway phrasings are all, every, and at least all — the last of which is division rather than equality: X may reach more than the divisor requires and still qualify. The same skeleton, with a subquery supplying the divisor, answers “employees with access to at least all the websites E0007 has access to”: there is no website E0007 can reach that this employee cannot.
SELECT E.FirstName, E.LastName
FROM Employee E
WHERE NOT EXISTS (
SELECT P.WebsiteURI
FROM Employee E2
JOIN RoleGranting RG1 ON RG1.EmployeeID = E2.EmployeeID
JOIN Permission P ON P.RoleID = RG1.RoleID
WHERE E2.EmployeeID = 'E0007'
AND P.WebsiteURI NOT IN (
SELECT P2.WebsiteURI
FROM RoleGranting RG2
JOIN Permission P2 ON P2.RoleID = RG2.RoleID
WHERE RG2.EmployeeID = E.EmployeeID
)
);Relational Keys
A key is a minimal set of attributes that uniquely identifies the tuples of a relation. Everything else in this note is a refinement of that one sentence. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and drilled in week4-tutorial-applied-class-3-relational-integrity; see relational-mapping-notation for how keys are written down (the primary key is underlined) and foreign-keys for the cross-relation case.
Minimality is the whole point
Uniqueness alone isn’t enough — a key must also be minimal, meaning it contains no redundant attributes. Minimal does not mean “the shortest set anyone could find”: it means that removing any attribute from the set destroys the uniqueness property.
Given Department [id, name, manager] where department IDs are unique:
| Candidate set | Unique? | Minimal? | Key? |
|---|---|---|---|
(id) |
Yes | Yes | Yes |
(id, name) |
Yes | No — id alone already suffices |
No |
(id, manager) |
Yes | No — same reason | No |
Adding anything to an already-unique set keeps it unique but destroys minimality, so (id, name) is never a key while (id) is one.
Ask the same key question twice on one instance, changing only the assumptions, and the pair is the whole lesson:
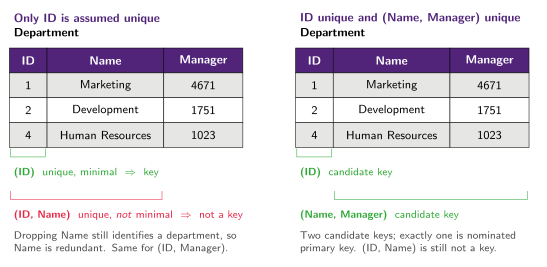
Figure 45: Two key questions on one instance. Left: only ID is assumed unique, so (ID) is the sole key and (ID, Name) fails minimality. Right: (Name, Manager) is also assumed unique, which adds a second candidate key without making (ID, Name) one.
Nothing in the data changed between the two panels — only what the question tells you to assume. Keys are a property of the schema and its stated uniqueness assumptions, never something you can read off one instance.
The vocabulary
| Term | Meaning |
|---|---|
| Superkey | Any set of attributes that uniquely identifies tuples — not necessarily minimal |
| Candidate key | A minimal superkey; a relation may have several |
| Primary key | The one candidate key chosen as the key for the relation; exactly one per relation |
| Composite key | A key made of more than one attribute |
Every key is a superkey; the reverse doesn’t hold. In the table above, (id, name) is a superkey but not a candidate key. The relational-model material works with key, candidate key and primary key only — superkey enters later, with design theory, where the formal treatment of it lives: attribute closure, and how to find all the candidate keys of a relation from its functional dependencies (see functional-dependencies and attribute-closure).
Textbook terms the course never uses are worth not importing: there is no alternate key, secondary key or surrogate key anywhere in INFS1200. A candidate key that lost the nomination is just “another candidate key” and becomes an ordinary attribute in the relational schema; an artificial identifier is just a key that was chosen. Answers should stay inside the four terms above.
Several candidate keys
If department IDs are unique and the combination of name and manager is also unique per department, then Department has two candidate keys: (id) and (name, manager). Both are minimal and both are unique; (id, name) still isn’t a key because (id) alone already suffices. Exactly one of the candidate keys is then nominated as the primary key — a design choice, not something the data dictates.
Composite keys
A key can perfectly well span several attributes. Composite primary keys turn up constantly, and mostly for structural reasons rather than arbitrary ones:
- A weak entity’s relation is keyed on its owner’s primary key plus its own partial key, e.g.
Dependent [ssn, depName, …]. - An M:N relationship’s relation is keyed on the pair of foreign keys it carries, e.g.
WorksOn [ssn, pNo, hours]. - A multivalued attribute’s relation is keyed on the owner’s key plus the value itself, e.g.
DeptLocs [dNumber, location].
All three come out of er-to-relational-mapping. In this course’s notation a composite primary key is written as one continuous underline spanning all of its attributes — one key, not several.
Common misconceptions
From the true/false drill in week4-tutorial-applied-class-3-relational-integrity:
| Statement | Verdict |
|---|---|
| A key is a unique identifier of a tuple in the relation | True — that’s the definition |
| The key constraint (or uniqueness constraint) implies that no two tuples in a relation can have the same values for all attributes | True (as the course marks it) |
| A primary key is a candidate key chosen as the main key for a relation | True |
| A key cannot have multiple attributes | False — composite keys exist |
| An entity may have more than one primary key | False — several candidate keys, but only one is the primary key |
The second row is worth pausing on, because the obvious objection is a good one: no two tuples can agree on all attributes in any relation, declared key or not, since a relation is a set. The course still marks it true, reading it as “the key constraint implies uniqueness of tuples” — so answer it the course’s way, and keep the set-semantics point as the reason the statement is weak rather than as a reason to call it false.
Matching the four terms
Matching definitions to names is a compact statement of all four:
| Definition | Term |
|---|---|
| Any minimal set of attributes that can uniquely identify tuples in a relation | Candidate key |
| A candidate key that is chosen to identify tuples in a relation | Primary key |
| Defines the structure of a relation; specified during database design | Relational schema |
| Data in a relation, modified via create, update and delete operations | Relational instance |
Worked example — electoral roll
Region [prefix, suffix]
Member [enrolmentId, passportNum, regionPrefix, regionSuffix]
Member.{regionPrefix, regionSuffix} references Region.{prefix, suffix}
Candidate [enrolmentId, name, regionPrefix, regionSuffix]
Candidate.enrolmentId references Member.enrolmentId
Candidate.{regionPrefix, regionSuffix} references Region.{prefix, suffix}- Candidate keys:
Member.enrolmentId,Member.passportNum,Candidate.enrolmentId,Region.{prefix, suffix}—Memberhas two, since a passport number identifies a member just as well as an enrolment ID does. - Primary keys:
Member.enrolmentId,Candidate.enrolmentId,Region.{prefix, suffix}— one per relation,passportNumlosing out toenrolmentIdas a design choice. - Composite primary key:
Region.{prefix, suffix}. - Foreign keys:
Member.{regionPrefix, regionSuffix},Candidate.{regionPrefix, regionSuffix},Candidate.enrolmentId— note the last one is simultaneouslyCandidate’s primary key and a foreign key, which is exactly what a subclass relation looks like.
What keys enforce
Two of the five integrity-constraints exist to protect keys:
- The key constraint — no two tuples may share a value for a key. Violated by inserting or modifying a tuple so that it duplicates an existing key value.
- The entity integrity constraint — no part of a primary key may be
NULL. For a composite primary key this means every component must be non-null; a single null component is already a violation.
Both are declarative: the DBMS enforces them automatically once the key is declared, without any application code (see sql-ddl for the PRIMARY KEY / UNIQUE syntax that declares them).
Relational Mapping Notation
Reference legend + course style guide for writing relational schemas — introduced across 2026-03-09-the-relational-model-and-integrity-constraints and 2026-03-16-er-to-relational-mapping. These notations are specific to INFS1200/7900 and may differ from textbooks and online resources, so they are what to follow in an assignment or exam. The guide covers naming and layout only: it recommends nothing about which relations to produce. The mapping steps themselves are in er-to-relational-mapping.
Schema notation
Relation [attr1, attr2, ...]— a relation schema; the (primary) key attribute(s) are underlined.- A composite primary key gets a single continuous underline spanning all of its attributes, e.g.
Enrolment [studentId, courseCode, sem, year]. Relation.fk references OtherRelation.pk— a foreign key constraint, listed directly under the relation it belongs to.Relation.{fk1, fk2} references OtherRelation.{pk1, pk2}— a composite foreign key referencing a composite primary key.
Naming convention (INFS1200/7900 style guide)
- Table names: UpperCamelCase (first letter of each word capitalised, no spaces) — e.g.
Flight, notFLIGHT. - Attribute names: lowerCamelCase (first letter of each word from the second word onwards capitalised) — e.g.
departureTime, notDeparture Time. Acronym attribute names stay entirely lowercase (e.g.eta, notETA). - A space separates the table name from the opening bracket:
Flight [planeNumber, ...], notFlight[planeNumber, ...].
The guide’s compliant and non-compliant pair puts every rule in one line each:
Flight [planeNumber, departureTime, duration, eta] ✓
FLIGHT[planeNumber, departure time, Duration, ETA] ✗The second breaks five rules at once — shouted table name, no space before the bracket, a space inside an attribute name, a capitalised attribute, and an upper-case acronym.
Layout convention
A table’s foreign key constraint lines go directly underneath that table’s own definition, with a blank line before the next table starts — not all grouped together under a separate “Foreign Keys:” heading at the end:
Employee [ssn, firstName, lastName, dob, manager]
Employee.manager references Employee.ssn
Dependant [ssn, name, dob]
Dependant.ssn references Employee.ssn
DependantPhoneNumber [ssn, name, phoneNumber]
DependantPhoneNumber.{ssn, name} references Dependant.{ssn, name}The Relational Model
The data model underlying almost every commercial DBMS, introduced by E.F. Codd in 1970: a sound theoretical foundation built on set theory, with a single simple, uniform data structure called a relation. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints; see relational-mapping-notation for how schemas are written down in this course, and er-to-relational-mapping for how a conceptual ER design becomes one.
The four basic concepts
| Concept | Definition |
|---|---|
| Domain | A set of atomic values, with a data type/format |
| Attribute | The name of a role played by some domain in a relation |
| Tuple | An ordered list of values, one per attribute |
| Relation | A set of tuples — informally, a table of rows and columns |
All four are visible at once in the anatomy figure, which is worth reading before the definitions below:
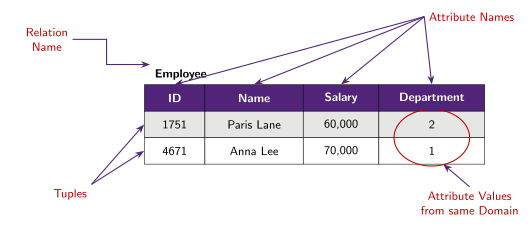
Figure 46: The four components of a relation, on an annotated Employee table. The relation name sits above the table; the attribute names are the header row; each body row is a tuple; and every value down one column — here Department — is drawn from that attribute’s single domain.
Domains
A domain \(D\) is a set of atomic values — atomic meaning indivisible as far as the relational model is concerned. Each domain carries a data type or format: integers, numbers/currency, fixed- or variable-length character strings, dates/timestamps, a sub-range of a data type (e.g. \(1 \le \text{grade} \le 7\)), or an enumerated type (e.g. \(\text{Gender} \in \{\text{Male}, \text{Female}, \text{Other}\}\)). Format-constrained domains count too — an Australian phone number (61 + 9 digits), or a car registration (6 alphanumeric characters, no Q).
The domain is what makes a value legal or illegal, which is why the domain constraint is the first of the five integrity-constraints: a value that isn’t a member of its attribute’s domain simply cannot be stored.
Attributes
Each attribute \(A\) names a role that some domain plays in a relation \(R\). Name and domain are independent in both directions:
- Same-named attributes in different relations need not share a domain —
Department.idandEmployee.idcan be drawn from entirely different domains despite the shared nameid. - Differently-named attributes can share a domain —
Employee.idandEmployee.managerIdare both drawn from the same “employee id” domain, which is precisely what makes a self-referencing foreign key possible (see foreign-keys).
The number of attributes in \(R\) is its degree — Employee [id, name, sex, salary, department] is of degree 5, and “degree of the relation” and “degree of the relation schema” are used interchangeably for the \(n\) in R [A1, …, An]. Degree is the only size measure Module 2 names. Unqualified “cardinality” in this course almost always means a relationship’s cardinality ratio on an ER diagram (relationship-constraints) or the “many cardinality” side of a relationship in the mapping rules; a relation’s row count only acquires a notation later, when Module 3 writes it as \(|R|\) to size a Cartesian product (\(|R_1 \times R_2| = m \cdot n\)) — see infs1200-diagram-notation.
Tuples
Each tuple \(t\) is an ordered list of \(n\) values \(t = \langle v_1, v_2, \ldots, v_n \rangle\), where each \(v_i\) either belongs to the domain of the corresponding attribute or is the special value NULL. A tuple with \(n\) values is an \(n\)-tuple.
Relation schema vs relation instance
The single most-tested distinction in this part of the course — the schema is metadata, the instance is data.
| Relation schema | Relation instance | |
|---|---|---|
| Written | R [A1, A2, …, An] |
r(R) = {t1, t2, …, tm} |
| Is | The relation’s name and attribute list | The actual set of tuples, at one point in time |
| Also called | Metadata — “data describing the data” | The data in the database |
| Comes from | Database design | Insert/update/delete operations |
| Changes | Rarely (a design decision) | Constantly |
Employee [id, name, sex, salary, department] is a schema of degree 5; the rows currently sitting in that table are its instance. Because the schema is fixed at design time and the instance changes with every update, an integrity constraint is a property of the schema that must hold on every instance of it.
Properties of relations
A relation is a mathematical set of tuples, and the consequences of that are what separate a relation from an arbitrary table.
- Tuple order is irrelevant. A set has no implied order. Two instances holding the same tuples in a different sequence are the same relation. Physically, tuples do sit in some order on blocks of secondary storage, but nothing semantic (queries included) may depend on it.
- Value order is a syntactic convention only. An \(n\)-tuple is syntactically an ordered list, so every tuple in one relation must list its values in the same attribute order — but which order is chosen carries no meaning, as long as the attribute-to-value correspondence is maintained consistently.
- Values are atomic. Each cell holds one indivisible value from its domain (or
NULL) — no repeating groups and no nested structure, which is why a multivalued attribute has to become a relation of its own during mapping. - Every relation is a table; not every table is a relation. A “pivoted” presentation table — a quarterly sales report with merged header cells, broken down by region and suburb — is a perfectly good table and not a valid relation at all. The word table is used interchangeably with relation in practice, but only relations obey the properties above.
One caveat for later: SQL does not enforce the set property. A SELECT returns a bag, duplicates and all, unless you ask for DISTINCT — see sql-select-statement. The properties above describe the model, not what a query result happens to look like.
Where the relational model sits
The relational model is the logical layer: what a DBMS actually implements, and the target of the mapping algorithm in er-to-relational-mapping (which is also where the conceptual/logical split is spelled out). The relational model is the middle box below: still a description of what is stored, not of how the bytes sit on disk (dbms-fundamentals has the three-schema architecture the right-hand column belongs to).
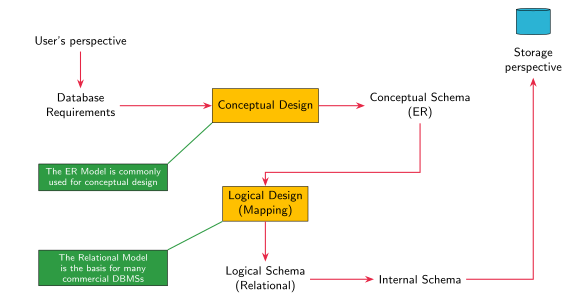
Figure 47: Where the relational model sits. Two design steps (gold) turn requirements into two schemas: conceptual design produces an ER schema, logical design — the mapping — produces a relational one. The green notes say what each model is for: the ER model is what conceptual design is done in, the relational model is what commercial DBMSs implement.
What that algorithm emits is relations plus their primary and foreign key constraints — from there, sql-ddl turns the schema into real CREATE TABLE statements, and normalisation (functional-dependencies, normal-forms) checks that the resulting relations are well-designed.
Relationship Constraints
Constraints on a relationship type limit the possible combinations of entities that may participate in its relationship set — determined by the Universe of Discourse (UoD), not chosen arbitrarily. There are exactly two kinds, cardinality constraints and participation constraints. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model; see er-diagram-notation for the full symbol legend.
Cardinality ratio
A cardinality ratio for a relationship set specifies the number of relationships in the set that an entity can participate in. The intuition is a customer buying items: one particular customer can purchase many different items, however an individual item — this particular cake — cannot be purchased by several different customers.
| Ratio | Name | Meaning |
|---|---|---|
| 1:1 | One-to-one | Both entities can participate in only one relationship instance |
| N:1 | Many-to-one | One entity can participate in many relationship instances, the other in only one |
| 1:N | One-to-many | The same constraint, viewed from the other side |
| M:N | Many-to-many | Both entities can participate in many different relationship instances |
Three worked readings, all on the same two entity types, are worth memorising as a set because the English is nearly identical each time and only the ratio changes:
| Statement of the UoD | Ratio |
|---|---|
| “Each employee can work on any number of projects, and each project can have any number of employees working on it” | EMPLOYEE —N— WORKSON —M— PROJECT (M:N) |
| “Each department can have any number of employees, but an employee can work for at most one department” | EMPLOYEE —N— WORKSFOR —1— DEPARTMENT (N:1) |
| “Each department can have at most one manager and each employee can manage at most one department” | EMPLOYEE —1— MANAGES —1— DEPARTMENT (1:1) |
Note where the N sits in the second row: on the EMPLOYEE side, because it is employees that are many. Reading the label on the wrong end is the standard error — see interpreting-er-diagrams.
Participation constraint (existence dependency)
The course’s own name for the participation constraint is existence dependency: it indicates whether the existence of an entity depends on its relationship to another entity — i.e. whether every instance of the entity type must participate in at least one relationship instance.
- Total participation (double line in the diagram) — every entity instance must participate. “Every employee must work for a department” makes
EMPLOYEEtotally participate inWORKSFOR, and the phrasing to use is thatEMPLOYEEis existentially dependent onDEPARTMENTvia theWORKSFORrelationship type. - Partial participation (single line) — an entity instance is not required to participate. “Every employee can manage 0 or more departments” makes
EMPLOYEE’s participation inMANAGESpartial.
The two ends are constrained independently, and MANAGES is the example that shows it: EMPLOYEE participates partially (most employees manage nothing) while DEPARTMENT participates totally (every department must have a manager), so DEPARTMENT is existentially dependent on EMPLOYEE via MANAGES and not the other way round.
Why the participation constraint is worth getting right
It is not just documentation: it decides where a foreign key ends up. The Module 2 mapping rule for a binary 1:1 relationship says to pick one of the two participating entity types and give it the foreign key, and that preference is given to entity types with total participation. MANAGES is exactly that case — because DEPARTMENT totally participates, the mapping extends Department with mgrSSN (plus the relationship’s own startDate, renamed mgrStartDate) rather than putting a department reference in Employee, which would be null for almost every employee. The mirror-image answer fails for precisely this reason: given S ═1═ R ─1─ T, putting the foreign key in T is wrong, because S has full participation and is preferred over T. See er-to-relational-mapping for the rule in full.
Weak entities
An entity type with no key attribute of its own is a weak entity — it can be identified uniquely only by considering the primary key of another owner entity together with its own partial key (underlined with a dotted line). The relationship type that relates a weak entity to its owner is the identifying relationship, and the weak entity always has total participation in it: it cannot exist without its owner. Both the weak entity box and the identifying relationship diamond are drawn with double lines.
An example is an EMPLOYEE (key SSN) who INSURES a DEPENDANT (partial key Pname, plus Age), 1:N, with Cost as a descriptive attribute on the identifying relationship. Two different employees can each insure a dependant named John, which is precisely why Pname cannot be a key on its own — the identity of a dependant is (SSN, Pname).
Provinces and cities have the same shape, and it is the compact example to memorise because all three notations — cardinality, participation and partial key — are on it at once:
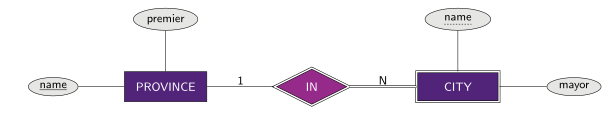
Figure 48: A weak entity in full notation. CITY is weak (double box) with the partial key name (dash-underlined); IN is the identifying relationship (double diamond); the CITY–IN edge is doubled for CITY’s total participation, and the ratio is 1:N, so one province holds many cities. PROVINCE’s own name is a full key (solid underline). Entity boxes are purple, relationship diamonds magenta and attribute ovals grey.
The two names do different jobs. PROVINCE.name identifies a province outright; CITY.name identifies a city only within a province, so the mapped Cities relation needs a pName column as part of its primary key and as a foreign key to Provinces — the mapping is Cities [cName, pName, mayor] with Cities.pName references Provinces.pName, and the wrong mappings are the ones that drop pName from the key, make cName a foreign key, or turn the identifying relationship IN into a relation of its own. See er-to-relational-mapping for the mapping rule that produces this.
A weak entity can have two (or more) owner entity types, in which case the identifying relationship is n-ary rather than binary. The generic version shows how the constraints are placed in that case — many weak entities per combination of owners, one owner of each kind per weak entity:
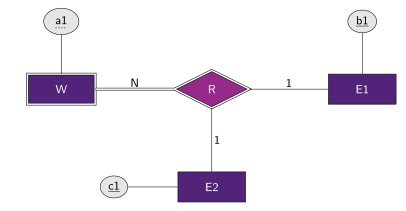
Figure 49: A weak entity with two owner entity types. The identifying relationship R is ternary: N on the weak side, 1 towards each owner, with the double edge marking W‘s total participation. W’s identity is its partial key a1 plus both owners’ keys, which is why the mapped relation is W [a1, b1, c1] with b1 and c1 as foreign keys.
INTERVIEW is the worked case: it is owned by both CANDIDATE and COMPANY, so the identifying relationship APPLIES is ternary, and INTERVIEW’s composite partial key Details (Department, Date) only distinguishes interviews within one candidate/company pair. INTERVIEW is a full entity type despite being weak, so it can carry relationships of its own — it RESULTSIN a JOB OFFER. See er-design-choices for the decision that produced it and interpreting-er-diagrams for the claims it makes false.
Relationship Types
The other half of an ER diagram: the associations between entity types. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week3-tutorial-applied-class-2-entity-relationship-diagrams; see er-diagram-notation for the symbols and entity-types-and-attributes for what sits at each end.
Relationship, relationship type, relationship set
The same schema/instance split as entity types:
| Term | Meaning |
|---|---|
| Relationship | An association among two or more entities — “Paris Lane works on the project FileZilla” |
| Relationship type | The definition of that association, drawn as a diamond connected to the participating entity types |
| Relationship set | The collection of all relationships of one relationship type in the database at any point in time |
A relationship set can be drawn as lines between two ovals of entities, or written out as a table of pairs — WORKSON as rows (e1, p1), (e2, p1), (e2, p4), and so on. The tabular form is the one exam questions use when they ask whether a given relationship set is possible under a diagram’s constraints; see interpreting-er-diagrams.
A relationship type may carry its own descriptive attributes, which belong to the pairing rather than to either entity on its own — EMPLOYEE WORKSON PROJECT hangs StartDate and EndDate off the diamond, because a start date belongs to one employee’s stint on one project and to nothing else. A Grade belongs to the enrolment of one student in one course, not to the student and not to the course. Other examples across the notes: a Placement on PARTICIPATES (athlete/event), a Fee on CONSULTS (patient/doctor), a PrepTime on BUYS (customer/bubble tea).
A relationship type may also carry key attributes of its own — on WORKSON it is StartDate that is underlined, which says one employee cannot start on the same project twice on the same day. The Timestamp that distinguishes repeat orders on BUYS does the same job.
Degree
The degree of a relationship type is the number of participating entity types:
| Degree | Name | Example |
|---|---|---|
| 2 | Binary | DEPARTMENT WORKSFOR EMPLOYEE |
| 3 | Ternary | SUPPLIER / PROJECT / PART in one SUPPLIES diamond |
| \(n\) | n-ary | The general case, 3+ entity types |
Degree is decided by counting the lines into the diamond, and it is a real design decision rather than a description — the same UoD can often be modelled as one ternary relationship or as three binary ones, with different consequences. See er-design-choices.
Roles
Each entity type that participates in a relationship type plays a particular role in it. The role name signifies the role a participating entity from that entity type plays in each relationship instance — that is to say, it explains what the relationship means. DEPARTMENT is the Employer and EMPLOYEE is the Worker in WORKSFOR, the relationship between those two entity types. WORKSON is a different relationship: the M:N EMPLOYEE/PROJECT one (relationship-constraints, er-to-relational-mapping).
Roles are optional labelling on an ordinary binary relationship between two different entity types, where the meaning is usually obvious from the names — but they become mandatory in the recursive case below, where they’re the only thing distinguishing the two ends.
Recursive relationships
The same entity type can participate more than once in one relationship type, under different roles — an EMPLOYEE who MANAGES another EMPLOYEE. Both lines run from the same rectangle back to the same diamond, so the role labels carry all of the meaning:
flowchart LR
EMPLOYEE[EMPLOYEE] ---|"1 Manager"| MANAGES{MANAGES}
MANAGES ---|"N Subordinate"| EMPLOYEE
Two different relationships share the name MANAGES, and they are not the same thing: this recursive EMPLOYEE/EMPLOYEE one, and the 1:1 EMPLOYEE/DEPARTMENT one that records who runs each department (relationship-constraints, and the mgrSSN foreign key in er-to-relational-mapping). The recursive relationship is also named SUPERVISION in the company diagram used for mapping, and that is the name used for it elsewhere in these notes.
Recursive relationships turn up constantly once you start looking, and they take every cardinality:
| Relationship | Roles | Ratio |
|---|---|---|
EMPLOYEE SUPERVISION EMPLOYEE |
supervisor / supervisee | 1:N |
COURSE PREREQUISITE COURSE |
higher / requires | M:N |
CUSTOMER FRIENDS CUSTOMER |
Requestor / Requestee | M:N |
VACCINE WITH VACCINE |
First / Second | partial on both sides |
NON-WIN SEQUEL NON-WIN |
PrequelTo / SequelTo | 1:1 |
The WITH example from week3-tutorial-applied-class-2-entity-relationship-diagrams is the instructive one: because participation is partial on both sides, the relationship records that a vaccine may be part of a two-dose program — it does not assert that every vaccine has a second dose. Reading a recursive relationship as if it were total is a standard trap.
Constraints
Cardinality ratio (1:1, 1:N, M:N) and participation (total/partial) are covered in relationship-constraints; how to read a claim off them without tripping over the direction is covered in interpreting-er-diagrams.
What happens to a relationship on mapping
The relationship type’s cardinality decides its fate in the relational schema. An M:N relationship becomes its own relation, combining both sides’ foreign keys into one composite primary key (relational-keys), plus any descriptive attributes it carried — UserRatesDriver [userID, driverID, rating] in week4-tutorial-case-study-3-dirt-road-driving. A 1:N relationship doesn’t need a relation of its own; it shows up as a foreign key on the N side, the way EmergencyContact.userID carries the User/EmergencyContact link in the same schema. The full set of rules is in er-to-relational-mapping.
Specialisation and Generalisation
The Enhanced ER (EER) model’s one big addition to plain ER: the ability to say that one entity type is a kind of another. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices; see er-diagram-notation for the notation.
Classes, superclasses and subclasses
In the EER model an entity type is called a class, and entities in the same class share the same attributes. A class can be a superclass or a subclass of another:
- Attributes of a superclass are inherited by its subclasses, and a subclass can add its own specific attributes and its own specific relationships on top.
- Every entity in a subclass is also a member of its superclass(es). The subclass never holds entities the superclass doesn’t.
The motivating example is a supermarket ITEM (ProductName, Price) versus a FOOD item, which is just an ITEM that additionally records an ExpiryDate. Modelling FOOD as a subclass says exactly that — it is an extension of a regular item, not a separate thing that happens to look similar.
Two directions, one relationship
Specialisation and generalisation describe the same superclass/ subclass structure discovered from opposite ends:
| Direction | Starting point | Move | |
|---|---|---|---|
| Specialisation | Top-down | One existing entity type | Define a number of subclasses of it, each containing a subset of the superclass’s entities, on the basis of a more specific distinguishing characteristic |
| Generalisation | Bottom-up | Several existing entity types | Abstraction — ignore the differences amongst the subclasses and generalise them into a common superclass |
The two are duals, not alternatives: the subclasses are a specialisation of the superclass, and the superclass is a generalisation of the subclasses. Which word you use just records how you arrived at the diagram.
Constraints on a specialisation
Two independent constraints apply to every specialisation, and both come from the UoD rather than from preference. They are stated over different things: a specialisation may be total or partial, while the subclass sets may be overlapping or disjoint.
| Constraint | Applies to | Options | Question it answers |
|---|---|---|---|
| Completeness | The specialisation | Total (double line) vs partial (single line) | Must every superclass entity belong to some subclass? |
| Disjointness | The subclass sets | Disjoint (d) vs overlapping (o) |
Can one superclass entity belong to more than one subclass at once? |
Worked readings from the tutorials:
DOCTORspecialises disjointly intoGP/SPECIALIST— “each doctor is either a GP or a specialist, never both”.PARTICIPANTspecialises into overlappingHEALTH/AGEsubclasses — a participant can legitimately be in both at once.STAFFspecialises into overlappingDRIVER/ADMINin week2-tutorial-case-study-1-dirt-road-driving, because a staff member at a small rideshare company can be both at once. Getting this one wrong as disjoint would silently forbid a perfectly ordinary real employee.
flowchart TD
STAFF[STAFF] --- o1(("o"))
o1 --- DRIVER[DRIVER]
o1 --- ADMIN[ADMIN]
Licence(["Licence"]) --- DRIVER
DeskNumber(["DeskNumber"]) --- ADMIN
One superclass, several independent specialisations
A superclass can be specialised more than once, along different characteristics, each with its own circle and its own independent pair of constraints. The canonical case is EMPLOYEE carrying two specialisations side by side:
| Specialisation | Subclasses | Disjointness | Completeness |
|---|---|---|---|
| Documents held | PASSPORT / DRIVERLICENSE |
Overlapping (o) |
Partial (single line) |
| How they are paid | HOURLY / SALARY |
Disjoint (d) |
Total (double line) |
All four boxes are ordinary subclasses of EMPLOYEE — none of them is a category or a union type, and each is drawn as a plain rectangle. The o on the left circle is what permits an employee to hold a passport and a driver licence; the single line into it permits one to hold neither. The d on the right circle forbids an employee from being both hourly and salaried, and the double line into it requires every employee to be one or the other. The two circles say nothing about each other: an hourly employee is neither more nor less likely to hold a passport.
flowchart TD
EMPLOYEE[EMPLOYEE] --- o1(("o"))
EMPLOYEE === d1(("d"))
o1 --- PASSPORT[PASSPORT]
o1 --- DRIVERLICENSE[DRIVERLICENSE]
d1 --- HOURLY[HOURLY]
d1 --- SALARY[SALARY]
The same structure turns up elsewhere: GAME in week1-lab-practical-1-course-tools splits disjointly into SINGLEPLAYER / MULTIPLAYER (how it’s played) and, separately, disjointly into WINNABLE / NON-WIN (whether it can be won) — four subclasses, but two unrelated specialisations. EMPLOYEE is also specialised disjointly into SECRETARY / ENGINEER (with TypingSpeed and EngineerDetails respectively) in the running company diagram, which is a third, separate characteristic again.
Reading two circles as one is a common misreading: subclasses under different circles say nothing about each other, so disjointness in one specialisation places no restriction on membership in the other. See interpreting-er-diagrams for the statement-evaluation version of this trap.
Subclasses carry their own relationships
Because a subclass is a full entity type in its own right, relationships can attach to it directly, and this is often the whole point of creating it. SPECIALIST (not DOCTOR) is what RUNS a SPECIALIST CLINIC, and HEALTHWORKER oversees HEALTH participants specifically, not every PARTICIPANT. Attaching a relationship at the subclass level rather than the superclass level is itself a design decision — see er-design-choices.
What happens on mapping
Each subclass becomes its own relation whose primary key is the superclass’s key, plus a foreign key back to the superclass — Driver [id, licence] with Driver.id references Staff.id. The subclass relation holds only its own specific attributes: repeating the superclass’s attributes there (e.g. copying make/model from Vehicles onto 4WD) is a mapping error, since it wastes space and lets the two copies drift apart. See step +1 of er-to-relational-mapping, er-mapping-pitfalls for the rest of the subclass mistakes, and week4-tutorial-case-study-3-dirt-road-driving.
Aggregation and Grouping
An aggregate function produces a single summary value from a set of tuples, and GROUP BY is what lets that summary be computed per bucket of rows rather than over the whole table. Together they turn a query from “which rows?” into “how many / how much / what is the extreme?”. Introduced in 2026-04-06-aggregation-grouping-and-multiple-relation-queries; practised in week7-tutorial-applied-class-6-aggregation-and-grouping and week7-tutorial-case-study-5-easydrive-insurance.
The aggregate functions
| Function | Returns |
|---|---|
COUNT |
The number of tuples |
SUM |
The sum of a set of numeric values |
AVG |
The average of a set of numeric values |
MAX / MIN |
The largest/smallest value of any domain with a total ordering — not just numbers |
MAX/MIN working on any ordered domain is the source of a recurring trap: dates order chronologically, so the youngest employee is the one with the largest (most recent) date of birth.
SELECT MAX(DOB) FROM Employee; -- youngest, not oldestAny aggregate can be applied with or without DISTINCT, which matters most for COUNT: COUNT(*) counts tuples, while COUNT(DISTINCT attr) counts how many different values of attr those tuples hold.
SELECT COUNT(*) FROM Employee WHERE dNum = 5;
SELECT COUNT(DISTINCT salary) FROM Employee WHERE dNum = 5;
-- How many distinct roles reach each website — not how many
-- Permission rows mention it
SELECT WebsiteURI, COUNT(DISTINCT RoleID)
FROM Permission
GROUP BY WebsiteURI;Aggregation functions may be used in the SELECT clause and the HAVING clause — and never in WHERE, which runs before any grouping exists (see sql-select-statement). To filter rows against an aggregate, compute it in a subquery: sql-nested-queries. To sort by one, name the target-list position the aggregate occupies rather than repeating the aggregate in ORDER BY.
Aggregating without GROUP BY
With no GROUP BY, the entire result set is treated as one group: the aggregate spans the whole table and the query returns a single row.
SELECT AVG(salary), SUM(salary) FROM Employee;
-- Several aggregates and an expression over them, in one row
SELECT MAX(Level), MIN(Level),
(MAX(Level) - MIN(Level)) AS DifferenceInAdministrativeEmployeeLevels
FROM AdministrativeEmployee;GROUP BY
GROUP BY and HAVING are stages 3 and 4 of the clause pipeline in sql-select-statement, which is where their ordering rules come from. WHERE filters rows first; GROUP BY then buckets the survivors, one group per distinct combination of the grouping attributes, and one output row per group.
-- Total employees per department
SELECT dNum, COUNT(*)
FROM Employee
GROUP BY dNum;
-- dNum | COUNT(*)
-- 1 | 1
-- 4 | 3
-- 5 | 4
-- Only employees earning > 40000 are counted
SELECT dNum, COUNT(*)
FROM Employee
WHERE salary > 40000
GROUP BY dNum;
-- Grouping by two attributes: one group per (department, gender) pair
SELECT dNum, sex, AVG(salary)
FROM Employee
GROUP BY dNum, sex;The rule: when GROUP BY is used, any attribute appearing in the SELECT clause must either also appear in the GROUP BY clause or be inside an aggregation function. There is no other option, because a group has exactly one value for each grouping attribute but many values for everything else — SQL would not know which one to print.
A useful degenerate case: grouping by a primary key or other unique field puts exactly one tuple in every group, so the query returns as many rows as the table has, and each aggregate just echoes that row’s own value.
HAVING — conditions on groups
HAVING filters groups the way WHERE filters rows, and unlike WHERE it can contain aggregates. The same attribute rule applies in its own words: any attribute appearing in the HAVING clause must either appear in the GROUP BY clause or be inside an aggregation function.
-- Departments with more than 2 employees
SELECT dNum, COUNT(*)
FROM Employee
GROUP BY dNum
HAVING COUNT(*) > 2;
-- Departments with more than 2 employees earning > 20000
SELECT dNum, COUNT(*)
FROM Employee
WHERE salary > 20000
GROUP BY dNum
HAVING COUNT(*) > 2;In the second query WHERE and HAVING both talk about the same filtered population (“employees earning over 20000”). Making HAVING test a different population — e.g. the department’s total headcount, not just its well-paid staff — needs a correlated subquery, see sql-nested-queries.
Idioms worth recognising:
-- "at least two X per group"
SELECT RoleId FROM Permission
WHERE GrantType = 'Edit'
GROUP BY RoleId
HAVING COUNT(WebsiteURI) >= 2;
-- "values shared by more than one row"
SELECT DISTINCT LastName FROM Employee
WHERE LastName IS NOT NULL
GROUP BY LastName
HAVING COUNT(FirstName) > 1;The IS NOT NULL guard there isn’t decoration. “Unknown” is not a shared surname, and the course never settles what a null does once it reaches a GROUP BY bucket or an aggregate — see sql-nulls for exactly what Module 3 does and doesn’t specify. Excluding nulls explicitly is the habit the material teaches, precisely so the answer doesn’t depend on a rule you were never given.
Comparing a group’s count against a count computed elsewhere is the basis of the counting form of relational-division — “this X is related to as many Ys as there are Ys, so it is related to all of them”.
Note that different HAVING conditions can coincide on a given data set without being equivalent: over singleton groups, COUNT(*) < 2, MAX(salary) <= MIN(salary) and SUM(salary) < 60000 may all select exactly the same groups, while AVG(salary) = 25000 picks out a different set. Reason about what each condition means per group, not about which rows it happens to return once.
Choosing the grouping attributes carefully
The GROUP BY list defines what “one thing” means for the whole query, so getting it wrong produces a plausible-looking but wrong count rather than an error. Counting customers per street by grouping Address on (Postcode, StreetName) overcounts if several customers share one AddressID — the question was about people per street, but the grouping was over address rows. Ask what a single output row is supposed to represent, and check that the grouping produces exactly one row per such thing; often the honest answer requires joining another table in first (sql-joins).
SQL Data Definition Language (DDL)
DDL is the subset of SQL that defines and changes the database schema — CREATE, ALTER, DROP — as opposed to the data held in it. It is where the relational schema produced by er-to-relational-mapping (written in relational-mapping-notation) becomes a real set of tables, and where the integrity constraints of the relational model are actually declared and enforced. Introduced in 2026-03-30-basic-sql-ddl-and-dml; practised in week6-tutorial-applied-class-5-basic-sql-ddl-and-dml and week6-tutorial-case-study-4-easydrive-insurance.
Where DDL sits among SQL statement types
| Family | Purpose | Statements |
|---|---|---|
| DDL (Data Definition Language) | Define/change the schema | CREATE, ALTER, DROP |
| DML (Data Manipulation Language) | Manipulate data | INSERT, UPDATE, DELETE, SELECT |
| DCL (Data Control Language) | Transaction control, semantic integrity (triggers/assertions), authorisation and privileges, role-based security, physical storage parameters | GRANT / REVOKE, see database-access-control |
See sql-dml for the data-modification statements and sql-select-statement for querying.
Syntax notation used in this course
Statement templates throughout Module 3 are written with a fixed convention:
| Written | Means |
|---|---|
KEYWORD |
A literal SQL keyword |
<argument> |
A name or value you supply |
[optional] |
May be omitted |
{multiple} |
May be repeated |
…\|..choice..\|… |
Pick exactly one of the alternatives |
CREATE TABLE
CREATE TABLE <table name>
(<column name> <column type> [<attribute constraint>]
{, <column name> <column type> [<attribute constraint>]}
[<table constraint> {, <table constraint>}])Domain constraints are specified per attribute; key, entity and referential integrity constraints are specified after all the attributes are declared.
An attribute’s data type can be given directly on the column, or by declaring a named domain with CREATE DOMAIN and using that instead. The course names CREATE DOMAIN as the alternative but never gives its syntax or an example, so the only form actually examinable here is the direct one — a type (and optionally a CHECK) written on the column.
An entity table — Item [itemID, category, colour]:
CREATE TABLE Item (
itemID INTEGER,
category ENUM('food', 'clothing', 'furniture'),
colour CHAR(3),
PRIMARY KEY (itemID));A relationship table — Sale [itemID, custID, timestamp, price, salesPerson], a ternary-degree relation between Item, Customer and Employee, whose primary key is composite and whose foreign keys carry the relationship:
CREATE TABLE Sale (
itemID INTEGER,
custID INTEGER,
timestamp TIMESTAMP,
price DOUBLE(8, 2),
salesPerson CHAR(9),
PRIMARY KEY (itemID, custID, timestamp),
FOREIGN KEY (itemID) REFERENCES Item(itemID),
FOREIGN KEY (custID) REFERENCES Customer(custID),
FOREIGN KEY (salesPerson) REFERENCES Employee(ssn));Column types used in this course
| Type | Used for |
|---|---|
INTEGER / INT |
Whole numbers (IDs, counts, years) |
CHAR(n) |
Fixed-length strings — e.g. a 64-character access token, a 9-character SSN |
VARCHAR(n) |
Variable-length strings up to n characters |
ENUM('a', 'b', …) |
A domain restricted to a fixed list of literal values |
DECIMAL(p, s) / DOUBLE(p, s) |
Fixed-precision numbers — e.g. DECIMAL(10, 2) for money |
DATE |
A calendar date |
DATETIME / TIMESTAMP |
A date and time |
AUTO_INCREMENT (MySQL) on an integer column makes the DBMS generate successive key values, e.g. ClaimID INT AUTO_INCREMENT.
Choosing ENUM (or a CHECK) over a plain string is what turns “should only ever be 'Private' or 'Business'” into a constraint the DBMS enforces — inserting 'Personal' then fails with a domain violation rather than silently storing bad data.
Declaring constraints
Constraints are rules limiting what data can go into a table. See integrity-constraints for what each one means in the relational model, and relational-keys/foreign-keys for the key concepts they enforce; this is how each is written in SQL:
| Constraint | Meaning |
|---|---|
PRIMARY KEY |
Value is unique and not null |
FOREIGN KEY … REFERENCES |
Value must exist in the referenced (parent) table |
UNIQUE |
Value is unique or null — unlike a primary key |
CHECK |
Value(s) must satisfy a condition |
NOT NULL |
Value must be supplied |
A table may declare only one PRIMARY KEY clause, but any number of UNIQUE clauses — so “id is the key, but {firstName, lastName} must also be unique” is a primary key plus a separate UNIQUE over the pair, not two primary keys:
CREATE TABLE Student (
id INT NOT NULL,
firstName VARCHAR(50),
lastName VARCHAR(50),
PRIMARY KEY (id),
UNIQUE (firstName, lastName));CHECK constraints are semantic constraints over a single table, evaluated whenever tuples are inserted or modified:
CREATE TABLE Sale (
itemID INTEGER,
custID INTEGER,
timestamp TIMESTAMP,
price DOUBLE(8, 2),
salesPerson CHAR(9),
PRIMARY KEY (itemID, custID, timestamp),
FOREIGN KEY (itemID) REFERENCES Item(itemID),
FOREIGN KEY (custID) REFERENCES Customer(custID),
FOREIGN KEY (salesPerson) REFERENCES Employee(ssn),
CHECK (price >= 8.50 AND price < 150000));Naming constraints
Prefixing a constraint with CONSTRAINT <name> has two benefits: error messages name the violated constraint, and the constraint can later be modified or removed by name.
CREATE TABLE Item (
itemID INTEGER,
category ENUM('food', 'clothing', 'furniture'),
colour CHAR(3),
CONSTRAINT item_pk PRIMARY KEY (itemID));
ALTER TABLE Item DROP CONSTRAINT item_pk;An unnamed constraint can’t be dropped later — so name anything you may plausibly want to evolve.
Referential actions (ON DELETE / ON UPDATE)
Deleting a row other rows point at would leave those rows orphaned. The referential action attached to a FOREIGN KEY clause decides what happens instead:
| Action | Effect |
|---|---|
ON DELETE RESTRICT (default) |
Disallows the deletion |
ON DELETE CASCADE |
Deletes the dependent rows too |
ON DELETE SET NULL |
Breaks the link, but doesn’t delete other rows |
ON DELETE SET DEFAULT |
Uses a predefined fallback value |
These are the SQL spelling of the reject/cascade/set-null policies in update-operations-and-constraint-violations.
The same four options apply to updates, written ON UPDATE …. The difference is only in what fires them: ON DELETE responds to the referenced row being deleted, ON UPDATE to its referenced key value being changed. So on an update, RESTRICT refuses to change the parent’s key while children still point at the old value, CASCADE rewrites the children’s foreign key to the new value, SET NULL clears it, and SET DEFAULT substitutes the column’s default. RESTRICT on delete with CASCADE on update is the common pairing, and the one the course’s worked schema uses throughout — a key that is renumbered should carry its dependants along, while a parent that is removed should not silently destroy them.
CREATE TABLE Sale (
itemID INTEGER,
custID INTEGER,
timestamp TIMESTAMP,
price DOUBLE(8, 2),
salesPerson CHAR(9),
PRIMARY KEY (itemID, custID, timestamp),
CONSTRAINT itemID_fk FOREIGN KEY (itemID) REFERENCES Item(itemID)
ON DELETE RESTRICT ON UPDATE CASCADE,
CONSTRAINT custID_fk FOREIGN KEY (custID) REFERENCES Customer(custID)
ON DELETE RESTRICT ON UPDATE CASCADE,
CONSTRAINT ssn_fk FOREIGN KEY (salesPerson) REFERENCES Employee(ssn)
ON DELETE RESTRICT ON UPDATE CASCADE);Direction matters, and only one direction exists. The action fires in the direction the foreign key points: from the referenced (parent) table to the referencing (child) table. Given
CREATE TABLE ParkingPermit (
pID INTEGER,
staffID INTEGER,
PRIMARY KEY (pID),
FOREIGN KEY (staffID) REFERENCES Staff(staffID) ON DELETE CASCADE);deleting a Staff row cascades into ParkingPermit; deleting a ParkingPermit row has no defined effect on Staff whatsoever.
Choosing between the actions is a design decision about what the data should mean. For Student.advisorID references Professor.professorID, ON DELETE SET NULL says “a professor can leave without their students’ records being destroyed — they simply have no advisor for now”; RESTRICT would instead block the professor’s deletion until every advisee is reassigned, and CASCADE would delete the students.
ALTER TABLE
ALTER TABLE <table name>
ADD <column name> <column type> [<attribute constraint>]
{, <column name> <column type> [<attribute constraint>]}
| DROP <column name> [CASCADE]
| MODIFY <column name> <column-options>
| ADD <constraint name> <constraint-options>
| DROP <constraint name> [CASCADE];ALTER TABLE is the schema-evolution statement: add or drop columns, change a column definition, add or drop constraints. A constraint cannot be altered in place — drop it and re-add it (exact syntax varies between commercial products).
-- Add an attribute (existing rows get NULL, so NOT NULL can't be used)
ALTER TABLE Employee ADD job VARCHAR(12);
-- Drop an attribute (CASCADE if other tables' FKs reference it)
ALTER TABLE Employee DROP address;
-- Add named constraints after the fact
ALTER TABLE Sale ADD CONSTRAINT ChkAge CHECK (price BETWEEN 10 AND 10000);
ALTER TABLE Customer ADD CONSTRAINT UniqueEmail UNIQUE (Email);
ALTER TABLE Customer ADD CONSTRAINT AgeOver CHECK (
TIMESTAMPDIFF(YEAR, DateOfBirth, CURDATE()) >= 18);
-- Drop a constraint (must have been named)
ALTER TABLE Sale DROP CONSTRAINT itemID_fk;The NOT NULL restriction on a newly added column is worth remembering — see sql-nulls.
DROP TABLE
DROP TABLE <table name> [CASCADE];Dropping a table drops every constraint defined on it — including constraints in other tables that reference it — deletes all its tuples, and removes the table definition from the system catalog. RESTRICT refuses the drop while dependent objects (e.g. views) still exist; CASCADE drops them too (see sql-views).
Cyclical foreign key dependencies
Department.mgrSSN → Employee.ssn and Employee.dNum → Department.dNumber reference each other, so neither table can be created with its foreign keys in place — the other table doesn’t exist yet. The fix is to defer the constraints:
CREATE Department (without FKs)
CREATE Employee (without FKs)
INSERT data into Department
INSERT data into Employee
ALTER TABLE Department ADD FOREIGN KEY (mgrSSN) REFERENCES Employee(ssn)
ALTER TABLE Employee ADD FOREIGN KEY (dNum) REFERENCES Department(dNumber)The insertions sit between the CREATEs and the ALTERs for a reason: with both foreign keys already in place, whichever table you populated first would be referencing rows that don’t exist yet.
SQL Data Manipulation: INSERT, UPDATE, DELETE
DML is the subset of SQL that manipulates data rather than the schema. A relational query language needs four operations — INSERT (new tuples), DELETE (remove tuples), UPDATE (change attribute values) and SELECT (retrieve data) — and SQL provides exactly those. This note covers the three that modify stored data; SELECT is large enough to have its own note, sql-select-statement. Introduced in 2026-03-30-basic-sql-ddl-and-dml; practised in week6-tutorial-applied-class-5-basic-sql-ddl-and-dml and week6-tutorial-case-study-4-easydrive-insurance.
INSERT
INSERT INTO <table name>
[(<column name> {, <column name>})]
(VALUES (<constant value> {, <constant value>}) | <select statement>);A single-tuple insert lists values in the same order as the columns were declared, or in the order of the explicit column list if one is given:
-- Positional: values in declaration order
INSERT INTO Customer VALUES
('653298653', 'Ronald West', 'Male', '1995-12-30');
-- With an explicit column list
INSERT INTO Employee (EmployeeID, FirstName, LastName, DOB, PasswordHash, PasswordSalt)
VALUES ('E0024', 'James', 'Moran', '2001-11-21',
'e7cf3ef8d8aac2c1c93963e7a58b7b62ade24d0d0ba2c8ae0f7fb6c8b0aa0332',
'gmAlpLW8cUj');A multi-tuple insert either comma-separates several value lists, or — much more powerfully — takes the result of a query in place of the VALUES clause. The query’s result columns must line up with the target column list:
-- Create a customer account for every employee in department 1
INSERT INTO Customer (custID, cname, gender, dob)
SELECT ssn, name, sex, dob
FROM Employee
WHERE dNum = 1;The query may itself be grouped, which turns INSERT … SELECT into a way of materialising a summary into a table (sql-aggregation-and-grouping). One row goes in per group, and the target table’s existing rows are left alone — the new rows are appended, so a Science row already sitting in DegreeStatistics survives untouched:
-- One row per degree, holding that degree's headcount
INSERT INTO DegreeStatistics (degree, num)
SELECT degree, COUNT(*)
FROM Students
GROUP BY degree;Getting the aggregate wrong here is silent: SUM(id) in place of COUNT(*) inserts perfectly well-formed rows holding the wrong numbers.
The inserted rows can mix constants with values pulled from the query, which is how “give this new employee the same roles as Sofia Gonzalez” becomes a single statement:
INSERT INTO RoleGranting
SELECT 'E0024', RoleID, 'E0001', Timestamp
FROM RoleGranting
WHERE EmployeeID = (
SELECT EmployeeID
FROM Employee
WHERE FirstName = 'Sofia' AND LastName = 'Gonzalez'
);DELETE
DELETE FROM <table name>
[WHERE <select condition>];One DELETE removes zero, one, several, or all tuples from a single table — the WHERE clause is what stands between the two extremes, and omitting it empties the table. The condition may itself contain a subquery (see sql-nested-queries):
DELETE FROM Employee
WHERE name = 'Ramesh';
-- Revoke the role(s) granted to John Stevens on 22 July 2024
DELETE FROM RoleGranting
WHERE EmployeeID = (
SELECT EmployeeID FROM Employee
WHERE FirstName = 'John' AND LastName = 'Stevens'
)
AND Timestamp BETWEEN '2024-07-22 00:00:00' AND '2024-07-22 23:59:59';Because a deletion is only as precise as its predicate, “delete all the CompSci students except student 4” is
DELETE FROM Student WHERE degree = 'CompSci' AND NOT id = 4;and this turns on operator precedence: NOT binds tighter than AND, so the condition reads degree = 'CompSci' AND (NOT (id = 4)) — CompSci students other than #4 — rather than NOT (degree = 'CompSci' AND id = 4), which would spare nobody but #4 and delete the whole rest of the table. See sql-select-statement for the precedence order.
Two neighbouring formulations both fail. WHERE id = 3 AND id = 5 AND id = 12 is a contradiction — one column cannot equal three values at once — and quietly deletes nothing at all; id IN (3, 5, 12) is the form that was meant. And listing by hand the rows you happened to notice (fName = 'Diluen' OR fName = 'Peter' OR …) is unsafe in the other direction: it catches rows that merely share a name without satisfying the condition you actually meant.
Deletion may propagate to other tables when ON DELETE referential-triggered actions were declared — see sql-ddl’s referential actions section.
UPDATE
UPDATE <table name>
SET <column name> = <value expression> {, <column name> = <value expression>}
[WHERE <select condition>];Tuples are selected for update from a single table, and the new value can be an expression over the row’s existing values:
UPDATE Employee
SET salary = salary * 1.1
WHERE name = 'Joyce';Updating a primary key value may propagate to other tables through foreign keys that reference it, according to the declared ON UPDATE action.
Modifications are where constraints bite
Every constraint declared in sql-ddl is checked at modification time, so a failed INSERT is usually a precise diagnostic about the data rather than the SQL — see update-operations-and-constraint-violations for which operation can break which constraint. Running a batch of inserts against the EasyDrive schema shows the typical failure modes:
| Insert | Outcome |
|---|---|
Customer.AddressID = 'A999' when no such Address row exists |
Fails — referential integrity: #1452 Cannot add or update a child row: a foreign key constraint fails |
Vehicle.VehiclePurpose = 'Personal' against ENUM('Private','Business') |
Fails — domain constraint: #1265 Data truncated for column 'VehiclePurpose' |
Policy.VehicleID = 'V00001' after that Vehicle insert failed |
Fails — referential integrity, purely as a knock-on |
Two things are worth taking from that. First, a rejected statement changes nothing, so a key value “used” by a failed insert is still free for the next one. Second, failures cascade through a sequence: the Policy row’s own values look perfectly fine and it still fails, because the row it depends on was never created. When debugging a batch, fix the first failure before reading anything into the later ones.
See integrity-constraints for the underlying entity/referential integrity rules these errors report.
SQL Injection
SQL injection is one of the most common threats to a database system: an attacker supplies string input through an (often web-facing) application in a way that changes or manipulates the resulting SQL statement to their advantage. Introduced in 2026-05-11-database-security.
It sidesteps everything in database-access-control rather than breaking it — the injected statement runs under the application’s own, legitimately granted privileges, so no GRANT was violated and nothing in the access matrix looks wrong afterwards.
The three methods
| Method | What the attacker does |
|---|---|
| SQL manipulation | Changes an existing SQL command — typically by adding conditions to a WHERE clause. Classic target: the login form |
| Code injection | Adds entirely new SQL statements or commands, exploiting improper handling of untrusted input |
| Function call injection | Inserts a database or OS function call into a vulnerable statement, to manipulate data or make a privileged system call |
All three have the same root cause: user input is concatenated into an SQL string, so the database can no longer tell where the developer’s query ends and the user’s data begins.
SQL manipulation — bypassing a login
A naive login check builds its query by direct concatenation:
SELECT * FROM Users WHERE Username = '<input>' AND Password = '<input>';A normal login (Jack / Pass123) produces WHERE Username = 'Jack' AND Password = 'Pass123', matches the stored row, and access is granted. But an attacker who knows the username enters this as the password:
' OR 'x'='xThe closing quote terminates the password literal early, and everything after it is read as SQL rather than data:
SELECT * FROM Users WHERE username = 'Jack' AND (password = '' OR 'x'='x');'x'='x' is always true, so the condition collapses to just username = 'Jack'. The row comes back regardless of the actual password, and the application grants access.
Code injection — going further
A semicolon ends one statement and begins another. If the application executes whatever SQL string results, and the driver or DBMS permits statement stacking:
wrongpass' OR 'x'='x'; drop table Users;This doesn’t merely bypass the login — it destroys the entire Users table. The step from manipulation to code injection is small; the damage is not.
Risks
| Risk | What it gets the attacker |
|---|---|
| Database fingerprinting | Identifying the DBMS in use, to target version-specific exploits |
| Denial of service | Denying service to valid users |
| Bypassing authentication | Access without valid credentials, as above |
| Identifying injectable parameters | Learning the backend structure from error messages and behaviour |
| Executing remote commands | Running harmful commands remotely, e.g. via function call injection |
| Privilege escalation | Upgrading the attacker’s own access level |
Note that several of these are reconnaissance: verbose error messages are themselves a vulnerability, because they tell an attacker which parameters are injectable and what the schema looks like.
Protection techniques
- Bind variables (parameterised statements) — the primary defence. Pass user input as bound parameters rather than concatenating it into the SQL string; the driver then treats every parameter value purely as data and never as executable syntax, so a quote in the input can’t close a literal. As a bonus, parameterised queries improve performance, since the query plan can be cached and reused across executions.
- Filtering input (input validation) — strip or escape characters, such as unescaped quotes, that could break out of a string literal. Useful as defence in depth, but it’s a blocklist by nature: it depends on anticipating every dangerous character, whereas bind variables remove the ambiguity entirely.
- Function security — restrict which standard and custom database functions are callable, to limit the blast radius of function call injection.
The ordering matters: bind variables fix the structural problem (data being parsed as code), while filtering and function restrictions only narrow what an attacker can do once that structural problem exists.
See also
- database-access-control — the privileges an injected statement inherits
- sql-ddl · sql-select-statement · sql-views
- 2026-05-11-database-security — Module 5
- week12-tutorial-5-1-database-security — practice
SQL Joins
A join combines related tuples from two (or more) relations into a single wider result relation. Joins are how a normalised schema is put back together at query time: the foreign keys created by er-to-relational-mapping are precisely the paths a join follows. Introduced in 2026-04-06-aggregation-grouping-and-multiple-relation-queries; practised in week8-tutorial-applied-class-7-multiple-relation-queries.
Renaming and qualification
With more than one table in scope, attribute names can be ambiguous. Two ways to resolve it: qualify the name (table.attribute), or declare an alias with AS (which may be omitted) and qualify with that. Aliasing is not just cosmetic — it is what makes a self-join expressible at all, since a table joined to itself needs two distinct names.
SELECT E.name, salary, 1.17 * salary AS 'includingSuper'
FROM Employee E
WHERE dNum = 4;Cartesian product
R1 × R2 pairs every row of R1 with every row of R2; the result schema is the concatenation of both schemas, and if \(|R1| = m\) and \(|R2| = n\) then \(|R1 \times R2| = m \times n\). A join, written \(\bowtie\), is built on top of that product: it is the product restricted to the pairs that satisfy a condition.
SELECT *
FROM MovieStar, StarsIn;This is almost never what you want — a join is a Cartesian product with a condition that keeps only the meaningfully related pairs. Forgetting the condition is exactly how a query silently returns thousands of rows.
Two syntaxes for the same thing
SELECT <attribute list>
FROM <table> {<type of join> JOIN <table to join to> ON <join attributes>}
[WHERE search condition]
-- equivalently, as a Cartesian product plus a join condition:
SELECT <attribute list>
FROM <table list of more than one table>
[WHERE join condition AND search condition]-- Names of the managers of each department, older comma form
SELECT E.name, D.dName
FROM Department AS D, Employee AS E
WHERE D.mgrSSN = E.ssn;
-- ...and the explicit JOIN form
SELECT E.name, D.dName
FROM Department AS D
JOIN Employee AS E ON D.mgrSSN = E.ssn;JOIN/ON is generally preferred, because it can be more efficiently optimised by the DBMS’s query optimiser and it keeps the join condition visually separate from the filtering condition — but in the context of this course the two forms are equivalent. These are also the only two join syntaxes the course uses: there is no NATURAL JOIN and no USING (…) anywhere in the material, so a join condition is always written out in full.
Kinds of join
| Kind | Join condition |
|---|---|
| Equi-join | Tuples must agree on a pair of attributes — the condition uses only = |
| Theta-join | The most general form: the condition uses any \(\theta \in \{=, \neq, <, >, \leq, \geq\}\) |
A theta-join is worth reaching for whenever the relationship between the rows is an inequality rather than a match. It is also easy to misread: SELECT DISTINCT S1.sName, S1.age FROM Student S1 JOIN Student S2 ON S1.age > S2.age returns all the students who are older than the youngest student(s) — every student for whom some younger student exists. That is everybody except the youngest, not “the oldest student”. The DISTINCT matters too: a student older than three others is paired three times by the join and would otherwise appear three times.
Inner vs outer joins
- Inner join — a tuple appears in the result only if matching tuples exist in both relations; unmatched rows are dropped silently. Using the
JOINkeyword on its own specifies an inner join, so plainJOINandINNER JOINmean the same thing. - Outer join — the inner join result plus the unmatched rows, with
NULLfilling the columns that had no match:LEFT JOIN— all rows from the first table.RIGHT JOIN— all rows from the second table.FULL OUTER JOIN— all rows from both. Not implemented in MySQL.
The four are easiest to hold in mind on one small instance. Given R [A, B] = {(1,2), (3,3)} and S [B, C] = {(2,4), (4,6)}, joined on B, only (1,2) and (2,4) match:
| Join | Result [A, B, C] |
|---|---|
R JOIN S ON R.B = S.B |
(1, 2, 4) |
R LEFT JOIN S ON R.B = S.B |
(1, 2, 4), (3, 3, NULL) |
R RIGHT JOIN S ON R.B = S.B |
(1, 2, 4), (NULL, 4, 6) |
R FULL OUTER JOIN S ON R.B = S.B |
(1, 2, 4), (3, 3, NULL), (NULL, 4, 6) |
The unmatched row is padded, not dropped: (3, 3) keeps its own A and B values and takes a null only in S’s column.
-- Misses departments that have no manager:
SELECT D.dName, E.name
FROM Department AS D
JOIN Employee AS E ON D.mgrSSN = E.ssn;
-- Includes them, with NULL for the manager's name:
SELECT D.dName, E.name
FROM Department AS D
LEFT JOIN Employee AS E ON D.mgrSSN = E.ssn;The choice matters most when counting (see sql-aggregation-and-grouping): an inner join makes the zero-cases disappear entirely rather than counting them as zero.
-- Every role, including those granting access to no websites at all
SELECT R.RoleID, COUNT(DISTINCT WebsiteURI)
FROM Role R
LEFT JOIN Permission P ON P.RoleId = R.RoleID
GROUP BY R.RoleID;The NULLs an outer join introduces are the query’s own doing, not missing data in the base tables — see sql-nulls.
Self-joins
A recursive relationship (an employee’s manager is also an employee) is queried by joining a table to itself under two aliases:
-- Employees who earn less than their manager
SELECT A.name AS employee, A.salary AS employeeSalary,
B.name AS manager, B.salary AS managerSalary
FROM Employee A
JOIN Employee B ON A.mgrSSN = B.ssn
WHERE A.salary < B.salary;The same trick chains a relation to itself to traverse two hops — e.g. pairing each flight with the flights departing from where it lands, to count one-stopover connections:
SELECT F1.Origin, F2.Destination, COUNT(*)
FROM Flight F1, Flight F2
WHERE F1.Destination = F2.Origin
GROUP BY F1.Origin, F2.Destination;Joining more than two tables
Each additional JOIN … ON extends the row further:
-- Stars in "Gone with the Wind"
SELECT S.starID, MS.name, S.role, M.title
FROM StarsIn S
JOIN MovieStar MS ON S.starID = MS.starID
JOIN Movie M ON S.movieID = M.movieID
WHERE M.title LIKE 'Gone with the Wind';StarsIn here is a pure link table: it exists only to connect Movie to MovieStar, and a query that needs attributes from both ends must pass through it.
Choosing the join condition
Most wrong-join bugs are semantic, not syntactic — the query runs and returns plausible rows that answer a different question. The condition should almost always match a foreign key to the primary key it references (foreign-keys). For “employees and the department they work in”, that is Employee.dNum = Department.dNumber; joining Employee.ssn to Department.mgrSSN instead answers “departments this employee manages”, and joining Employee.mgrSSN to Department.mgrSSN matches managers to managers. Before writing ON, name the relationship the join is meant to follow.
Joins are not the only way to combine relations: sql-set-operations stack result sets as new rows rather than new columns, and sql-nested-queries feed one query’s result into another.
The number of joins a query needs is also the running cost of a well-normalised schema — the trade-off normal-forms discusses under denormalisation, and the operation [decomposition] must keep lossless.
Nested Queries (Subqueries)
A nested query (subquery) is a query written inside another query; the containing query is the outer query, and nesting can go several levels deep. Subqueries let you compute an intermediate result and feed it straight into a larger query without creating a temporary table — including results, such as aggregates, that the outer query is not allowed to compute for itself. Introduced in 2026-04-13-nested-queries-views-and-generative-ai; practised in week9-tutorial-applied-class-8-nested-queries-and-views.
The motivating case is the aggregate that cannot go in a WHERE clause (see sql-select-statement for why):
-- INVALID: an aggregate cannot appear directly in WHERE
SELECT name, salary
FROM Employee
WHERE salary > AVG(salary);
-- Valid: the aggregate is computed by a subquery
SELECT name, salary
FROM Employee
WHERE salary > (SELECT AVG(salary) FROM Employee);What shape does the subquery return?
The single most useful question to ask before writing a subquery is what do I expect this to return — a value, a list, a table, or a yes/no? The answer decides which clause it can sit in and which operators are legal.
| Type | Expected result | Operators | Goes in |
|---|---|---|---|
| Scalar | A single value | =, <, >, != |
WHERE, HAVING |
| Set | A list of values (one column) | IN, NOT IN, ANY, ALL |
WHERE, HAVING |
| Table | Rows and columns (a relation) | — | FROM |
| Boolean | True/false per outer row | EXISTS, NOT EXISTS |
WHERE |
Scalar
A single value, compared directly. The classic failure is a scalar subquery that unexpectedly matches more than one row — the DBMS raises “subquery returned more than one row” rather than picking one.
SELECT name, salary
FROM Employee
WHERE salary > (SELECT AVG(salary) FROM Employee);Set
A one-column list, tested with IN/NOT IN/ANY/ALL. Never use = where the subquery could return several rows.
-- Departments whose manager is named "Jennifer"
SELECT dName FROM Department
WHERE mgrSSN IN (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');
-- ...and those whose manager is not
SELECT dName FROM Department
WHERE mgrSSN NOT IN (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');ANY succeeds if the comparison holds for at least one returned value; ALL requires it to hold for every returned value. IN is exactly = ANY, and the course states the equivalence with both forms written out side by side:
-- These two are the same query
SELECT DISTINCT dName FROM Department
WHERE mgrSSN IN (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');
SELECT DISTINCT dName FROM Department
WHERE mgrSSN = ANY (SELECT ssn FROM Employee WHERE name LIKE 'Jennifer');(ANY is the course’s spelling; the standard’s synonym SOME does not appear in the material, so write ANY.)
-- Employees earning more than everyone in department 5
SELECT *
FROM Employee
WHERE salary > ALL (SELECT salary FROM Employee WHERE dNum = 5);>= ALL (…) over a set of group totals is the idiomatic “is this the maximum?” test, and it keeps ties rather than discarding them:
-- The most common suburb(s), ties included
SELECT Suburb AS 'Suburb Name', COUNT(*) AS 'Street Count'
FROM Address
GROUP BY Suburb
HAVING COUNT(*) >= ALL (SELECT COUNT(*) FROM Address GROUP BY Suburb)
ORDER BY Suburb ASC;NOT IN expresses “none of these” — the natural way to write an exclusion:
-- Employees never granted a role by a 'ProductEngineer' administrator
SELECT E.*
FROM Employee E
WHERE EmployeeID NOT IN (
SELECT DISTINCT E2.EmployeeID
FROM Employee E2
JOIN RoleGranting RG ON RG.EmployeeID = E2.EmployeeID
JOIN AdministrativeEmployee AE ON AE.EmployeeID = RG.AdministrationID
WHERE AE.Type = 'ProductEngineer'
);Table
A subquery in the FROM clause behaves like a table and must be given an alias, after which it can be joined like any other:
-- Average salary per department, alongside the department name
SELECT d.dName, avgSal.avg_salary
FROM Department d
JOIN (SELECT dNum, AVG(salary) AS avg_salary
FROM Employee
GROUP BY dNum) AS avgSal ON d.dNumber = avgSal.dNum;If the same derived table is needed twice, define it once as a view instead — see sql-views.
Boolean
EXISTS/NOT EXISTS test whether the subquery returns any row at all; they return no data themselves, only yes/no, so the subquery’s target list is irrelevant (SELECT * is conventional).
-- Employees in a department that currently has a manager assigned
SELECT name, dNum
FROM Employee e
WHERE EXISTS (
SELECT * FROM Department d
WHERE d.dNumber = e.dNum AND d.mgrSSN IS NOT NULL
);Subqueries in HAVING
A subquery inside HAVING lets a group (sql-aggregation-and-grouping) be tested against a population the WHERE clause has already filtered away:
-- Departments with >2 employees EARNING OVER 20000
SELECT dNum, COUNT(*)
FROM Employee E1
WHERE salary > 20000
GROUP BY dNum
HAVING 2 < COUNT(*);
-- Departments (among those with employees earning over 20000)
-- that have >2 employees IN TOTAL
SELECT dNum, COUNT(*)
FROM Employee E1
WHERE salary > 20000
GROUP BY dNum
HAVING 2 < (SELECT COUNT(*) FROM Employee E2 WHERE E1.dNum = E2.dNum);Another idiom worth memorising: comparing against MAX/MIN with >= rather than = returns all the tied extremes rather than one arbitrary row.
-- Every youngest employee, ties included
SELECT E.DOB, E.FirstName, E.LastName
FROM Employee E
WHERE DOB >= (SELECT MAX(DOB) FROM Employee E2);Joins or subqueries?
Many nested queries can be rewritten as a plain join (sql-joins) — but not all, and the two have different strengths:
- A join can display columns from every table in its
FROMclause; a subquery-based query can only display columns from the outer query’s tables. - A subquery can compute an aggregate on the fly and feed it back to the outer query for comparison, which a join cannot.
Rule of thumb: use joins when you are displaying results from multiple tables; use subqueries when you need to compare aggregates to other values.
Nesting is also the standard fallback for the set operators. “In this result but not that one” is EXCEPT, and the course notes that any EXCEPT query can be implemented using nested queries — a NOT IN or NOT EXISTS subquery says the same thing and runs on dialects that lack the operator (sql-set-operations).
“For all” queries
The one common shape subqueries express that neither joins nor plain aggregates do is “related to every …” — the movie stars who were in all of a year’s movies, the employees who can reach all of another employee’s websites. Both standard patterns for it (counting, and NOT EXISTS double negation) are nested-query patterns: see relational-division.
NULLs in SQL
NULL is the special value a relational attribute takes when there is no ordinary value to store — it represents an inapplicable, unknown or missing value rather than zero or the empty string. Because a null is not a value in the attribute’s domain, it needs its own handling everywhere it appears: in constraints, in WHERE conditions, and in the results a query produces. Defined in 2026-02-23-conceptual-database-design-and-the-er-model, constrained in 2026-03-09-the-relational-model-and-integrity-constraints, and handled in SQL from 2026-03-30-basic-sql-ddl-and-dml onwards.
Which constraints permit a null
| Declaration | Nulls allowed? |
|---|---|
PRIMARY KEY |
No — a primary key value is unique and not null; for a composite key, no part of it may be null (entity integrity) |
FOREIGN KEY |
Yes — a foreign key value must either be null, or match an existing row of the referenced relation (referential integrity) |
UNIQUE |
Yes — the value must be unique or null; this is the one difference from a primary key |
NOT NULL |
No — a value must be supplied |
See integrity-constraints for the underlying entity and referential integrity rules, relational-keys and foreign-keys for what the keys themselves are, and sql-ddl for how each is declared.
The nullable foreign key is what makes several mappings work at all: an employee with no manager, or a department with no manager assigned yet, is represented by a null foreign key rather than by a missing row. It is also why er-to-relational-mapping prefers to hang a 1:1 foreign key off the total-participation side — the other side would be null for almost every row.
Testing for a null
NULL is tested with IS, never with =. IS sits alongside LIKE, IN and BETWEEN in the course’s catalogue of things a WHERE search condition may contain (sql-select-statement):
SELECT * FROM Employee WHERE dNum IS NULL;
SELECT * FROM Employee WHERE dNum IS NOT NULL;This shows up inside subqueries as well as at the top level — here, restricting the result to employees whose department currently has a manager assigned:
SELECT name, dNum
FROM Employee e
WHERE EXISTS (
SELECT * FROM Department d
WHERE d.dNumber = e.dNum AND d.mgrSSN IS NOT NULL
);An explicit IS NOT NULL is also the usual guard before grouping or building a derived value out of several columns, so that rows with missing components are excluded rather than silently contributing:
-- Last names shared by more than one employee, ignoring unknown names
SELECT DISTINCT LastName FROM Employee
WHERE LastName IS NOT NULL
GROUP BY LastName
HAVING COUNT(FirstName) > 1;
-- Build FirstName-LastName-yyyy only where all three parts exist
SELECT CONCAT(FirstName, '-', LastName, '-', YEAR(DOB))
FROM Employee
WHERE FirstName IS NOT NULL
AND LastName IS NOT NULL
AND DOB IS NOT NULL;The limits of what the course specifies
Module 3 treats nulls operationally rather than logically. It gives the IS operator, the constraint rules above, and the places a null can come from — and it stops there. The lectures do not develop a three-valued logic of TRUE/FALSE/UNKNOWN, do not state how an aggregate function treats the nulls inside a group, and do not cover what happens when a NOT IN subquery returns a null among its values. Those questions are simply not settled by the material, so don’t reason from a rule the course never gave you.
What the course does teach is the defensive habit: write the IS NOT NULL guard explicitly wherever a null could reach a comparison, a grouping, or a derived value, rather than relying on the DBMS to do something sensible with it. Every example above follows that habit.
Where nulls come from
Not every null is data someone failed to enter — several are created by the schema or the query itself:
| Source | Why |
|---|---|
| A genuinely inapplicable/unknown/missing value | The original meaning of a null |
ALTER TABLE … ADD <column> |
Every existing row gets a null in the new column — which is exactly why the new column cannot be declared NOT NULL (sql-ddl) |
ON DELETE SET NULL |
The referential action deliberately clears the link instead of deleting the dependent rows (update-operations-and-constraint-violations) |
| An outer join | Unmatched rows are padded with nulls in the columns of the table that had no match (sql-joins) |
| Access-control masking | A cell above a user’s clearance is presented to them as null rather than withheld (database-access-control) |
The last two matter when reading results: a null in the output of a LEFT JOIN means “no matching row existed”, which is information about the relationship, not about the row’s stored data.
-- Departments with no manager still appear, with NULL for the name
SELECT D.dName, E.name
FROM Department AS D
LEFT JOIN Employee AS E ON D.mgrSSN = E.ssn;Nulls as a design smell
A schema that produces many nulls is usually telling you something. Reducing the number of null values in tuples is guideline 3 of the informal design guidelines behind normalisation (update-anomalies) — an attribute that is null for most rows of a relation often belongs in a separate relation instead. See 2026-04-27-database-design-guidelines-and-functional-dependencies and normal-forms.
The SELECT Statement and Its Clause Order
SELECT is the retrieval half of SQL, and the reason SQL is called a declarative language: you specify what the result should look like and the DBMS decides the execution plan. The result of any SQL query is itself a table, which is what makes queries composable — it can be joined (sql-joins), nested inside another query (sql-nested-queries), stacked with another result set (sql-set-operations), or stored as a view (sql-views). Introduced in 2026-03-30-basic-sql-ddl-and-dml and extended across 2026-04-06-aggregation-grouping-and-multiple-relation-queries and 2026-04-13-nested-queries-views-and-generative-ai.
The full clause skeleton
SELECT [DISTINCT] <target list>
FROM <table list>
[WHERE search condition]
[GROUP BY <grouping attributes>]
[HAVING <group conditions>]
[ORDER BY column [ASC|DESC] {, column [ASC|DESC]}];Only SELECT and FROM are compulsory; the clauses must appear in this order when present.
Logical evaluation order
The order the clauses are written is not the order they take effect. Reading a query as a pipeline — each stage handing a table to the next — explains most of SQL’s otherwise arbitrary-looking rules:
| # | Clause | Operates on | Produces |
|---|---|---|---|
| 1 | FROM |
The named tables (joined, if more than one) | One combined table |
| 2 | WHERE |
Individual rows | The rows that satisfy the condition |
| 3 | GROUP BY |
The surviving rows | One group per distinct combination of grouping attributes |
| 4 | HAVING |
Whole groups | The groups that satisfy the condition |
| 5 | SELECT |
Each group (or each row, if no grouping) | The output columns |
| 6 | ORDER BY |
The finished result table | The same rows, sorted |
Three of the course’s recurring rules fall straight out of this:
- An aggregate cannot appear in
WHERE. At stage 2 no groups exist yet, so there is nothing to aggregate over —WHERE salary > AVG(salary)fails with invalid use of group function, and the fix is to compute the aggregate in a subquery instead (see sql-nested-queries). HAVINGmay use aggregates,WHEREmay not, becauseHAVINGruns at stage 4, after the groups exist.WHEREfilters rows,HAVINGfilters groups. They are not interchangeable, and a query can sensibly use both — see sql-aggregation-and-grouping.
The placement of SELECT before ORDER BY is not a guess: a sort key may be given as a column position in the target list (ORDER BY 2 DESC), which is only meaningful if the target list has already been built. Correspondingly, the two clauses that must be able to see raw rows — WHERE and GROUP BY — can only name attributes of the tables in FROM, never an alias invented by SELECT.
Projection and selection
The course names the two halves of a simple query after the relational operations they perform:
| Clause | Operation | Cuts the table |
|---|---|---|
SELECT |
Projection — choose the attributes | Vertically |
WHERE |
Selection — choose the tuples | Horizontally |
Note the terminological trap: the relational operation called selection is the WHERE clause, not the SELECT clause.
Projection, duplicates and bag semantics
SELECT [DISTINCT] (<attribute list> | *)
FROM <table list>
[WHERE <condition>];SQL relations are bags (multisets), not sets: projection does not eliminate duplicates by default, unlike the pure relational-model. DISTINCT restores set semantics; * is the wildcard for “all columns”.
-- All the years a movie was produced, with and without duplicates
SELECT year FROM Movie;
SELECT DISTINCT year FROM Movie;The consequence to watch for: projecting away the columns that made rows distinct leaves duplicate rows behind. Projecting (score1, score2) from a table of match results keeps two separate (5, 3) rows if two different fixtures both ended 5–3; SELECT DISTINCT collapses them into one and the row count drops accordingly.
Expressions and aliases
The target list can contain arithmetic (+ - * /) over numeric attributes, string/date functions, and aggregates — each optionally renamed with AS:
-- Names, salaries, and salaries with a 17% loading, for dept 6
SELECT name, salary, 1.17 * salary AS 'includingSuper'
FROM Employee
WHERE dNum = 6;
-- Build an employee code FirstName-LastName-yyyy
SELECT CONCAT(FirstName, '-', LastName, '-', YEAR(DOB))
FROM Employee;Aliases also disambiguate attributes across tables and enable self-joins — see sql-joins.
The WHERE clause
The <search condition> is a conditional (Boolean) expression identifying the tuples to retrieve. It may contain:
| Form | Use |
|---|---|
=, <>, <, <=, >, >= |
Compare an attribute to a value or another attribute |
AND, OR, NOT |
Combine conditions — bracket them, the grouping is the whole meaning |
LIKE |
Substring matching: % is zero or more arbitrary characters, _ is exactly one |
IN |
Membership in a list: lastName IN ('Jones', 'Wong', 'Harrison') |
IS |
Null-checking — dNum IS NULL; = does not work here, see sql-nulls |
+ - * /, date/time functions |
Arithmetic on the row’s own values: salary * 2 > 50000, YEAR(GETDATE() - dob) > 55 |
BETWEEN … AND … |
Inclusive range: salary BETWEEN 10000 AND 30000 |
-- Names of employees in dept 4 earning > 25000, or dept 5 earning > 30000
SELECT name
FROM Employee
WHERE (dNum = 4 AND salary > 25000) OR (dNum = 5 AND salary > 30000);
-- Permissions to edit commercial (.com) websites
SELECT WebsiteURI
FROM Permission
WHERE GrantType = 'Edit' AND WebsiteURI LIKE '%.com';A disjunction of conjunctions is exactly as literal as it looks: a row qualifies only if it satisfies one whole bracket. Rows with impressive values in the right columns but the wrong combination — 8 runs scored but 12 conceded, against (runsFor >= 6 AND runsAgainst <= 4) — do not qualify.
Dates are compared either as a quoted 'YYYY-MM-DD' literal or as the bare number in that order; both forms appear in the course and both work, because the ordering is the same either way:
SELECT name, dob FROM Employee WHERE dob < '1965-01-01';
SELECT name, dob FROM Employee WHERE dob < 19650101;Grouping the connectives
The course brackets its compound conditions rather than leaning on precedence, and that is the habit to copy: (A AND B) OR (C AND D) written out is unambiguous to you and to the marker. Where precedence still decides the meaning, it is NOT first, then AND, then OR — so NOT binds to the single comparison next to it, not to the rest of the condition. sql-dml works that case through on a DELETE, where misreading it costs the whole table rather than a few rows.
Written without brackets, A AND B OR C AND D groups as (A AND B) OR (C AND D) — which is usually what was meant, but relying on that is how a condition ends up meaning something you did not intend. Bracket it.
ORDER BY
[ORDER BY column [ASC|DESC] {, column [ASC|DESC]}]Sorting is the last stage, applied to the finished result. A sort key is either a column name or a column position in the target list; multiple keys are applied left to right, each with its own ASC (default) or DESC.
-- By department ascending, then salary descending within each department
SELECT dNum, name, salary
FROM Employee
ORDER BY dNum ASC, salary DESC;
-- Sorting a grouped result by its count, greatest first: the count is
-- the 2nd column of the target list
SELECT VehiclePurpose, COUNT(*)
FROM Vehicle
GROUP BY VehiclePurpose
ORDER BY 2 DESC;The positional form is what makes a computed column sortable at all — the aggregate itself belongs to SELECT and HAVING (sql-aggregation-and-grouping), and ORDER BY reaches it by pointing at the column it produced.
Later keys only break ties left by earlier ones, so ORDER BY c DESC, b ASC puts every row with a larger c ahead of (5, 5, 5) regardless of its b. Where two rows tie on all the sort keys, their relative order is unspecified — never rely on it.
SQL Set Operations
A relation in the relational-model is a set of tuples — no duplicates, no order — so the ordinary set operators apply directly to whole query results. These are the one corner of SQL that keeps that set discipline by default, where plain SELECT returns a bag (sql-select-statement). Where a join (sql-joins) combines tables into wider rows, a set operation stacks two result sets into more rows of the same shape. Introduced in 2026-04-06-aggregation-grouping-and-multiple-relation-queries; practised in week8-tutorial-applied-class-7-multiple-relation-queries.
The three operators
| Operator | Relational algebra | Result |
|---|---|---|
UNION |
\(\cup\) | Tuples appearing only in R1, only in R2, or in both |
INTERSECT |
\(\cap\) | Tuples appearing in both R1 and R2 |
EXCEPT (a.k.a. MINUS) |
\(-\) | Tuples appearing in R1 but not in R2 |
SELECT ...
UNION [ALL] SELECT ...
[UNION [ALL] SELECT ...]Union compatibility
Both operands must be union compatible: the same number of columns, with pair-wise compatible domains. The result takes its column names from the first SELECT, so the second query’s names are irrelevant — only its column order matters.
-- Error: 3 columns UNION 2 columns
SELECT * FROM Table1
UNION
SELECT a, b FROM Table1 WHERE b = 'X';A mismatch is an error, not a silently odd result — which makes it one of the easier SQL mistakes to catch.
Duplicates: set vs multiset semantics
Each operator eliminates duplicates by default. Appending ALL keeps multiset semantics instead. If a tuple occurs \(m\) times in \(r\) and \(n\) times in \(s\), it occurs:
| Expression | Occurrences |
|---|---|
r UNION ALL s |
\(m + n\) |
r INTERSECT ALL s |
\(\min(m, n)\) |
r EXCEPT ALL s |
\(\max(0,\ m - n)\) |
Deduplication is often the reason to reach for UNION: three independent ways of qualifying as a co-founder, unioned together, yield each person once even if they qualify twice.
SELECT E.EmployeeID, E.FirstName, E.LastName
FROM Employee E
JOIN AdministrativeEmployee AE ON AE.EmployeeID = E.EmployeeID
WHERE AE.Type = 'LegacyEngineer'
UNION
SELECT E.EmployeeID, E.FirstName, E.LastName
FROM Employee E
JOIN RoleGranting RG ON RG.EmployeeID = E.EmployeeID
JOIN Role R ON R.RoleID = RG.RoleID
WHERE R.Name = 'FinancialPerformanceOverview';Algebraic properties
\[A \cup B = B \cup A \qquad (A \cup B) \cup C = A \cup (B \cup C)\] \[A \cap B = B \cap A \qquad (A \cap B) \cap C = A \cap (B \cap C)\] \[A - B \neq B - A \qquad (A - B) - C \neq A - (B - C)\]
Union and intersection are commutative and associative; difference is neither — so with EXCEPT the order of the operands, and the bracketing of a chain of them, is part of the meaning.
Join or set operation?
| Join | Set operation | |
|---|---|---|
| Combines | Rows from many tables into new columns | Result sets of SELECTs into new rows |
| Column count | May differ between tables | Must match |
| Column types | Can differ | Must be compatible |
| Duplicates | Kept by default | Removed by default |
A set operation earns its place when the two halves need different grouping or filtering that cannot be expressed in one pass — for example “granted at least 2 roles” and “can edit at least 4 distinct websites”, which are two different COUNTs over two different groupings:
SELECT EmployeeID
FROM RoleGranting
GROUP BY EmployeeID
HAVING COUNT(RoleID) >= 2
INTERSECT
SELECT EmployeeID
FROM RoleGranting RG
JOIN Permission P ON P.RoleID = RG.RoleID
WHERE P.GrantType = 'Edit'
GROUP BY EmployeeID
HAVING COUNT(DISTINCT WebsiteURI) >= 4;Conversely, a simple UNION of two queries differing only in a WHERE condition is usually just an OR written the long way:
-- These two are equivalent
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID
WHERE year = 1944 OR year = 1974;
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
UNION
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;Note that OR and UNION coincide here only because the condition is about a single row’s year. “Stars who were in a 1944 movie and a 1974 movie” cannot be an AND over one row — no single row has two years — which is exactly the case INTERSECT handles.
Dialect support, and the two rewrites
The course is precise about what is missing where, and the two claims are different in scope:
| Feature | What the course says |
|---|---|
INTERSECT, EXCEPT/MINUS |
Some SQL dialects do not support intersection and difference — a portability caveat about dialects generally, not about MySQL specifically |
FULL OUTER JOIN |
Not implemented in MySQL (sql-joins) |
UNION is the only one of the three set operators you can rely on everywhere. For the other two the course supplies a rewrite each, and they are different rewrites: an INTERSECT becomes a join, an EXCEPT becomes a nested query.
INTERSECT becomes a self-join that requires both conditions to hold for the same key:
-- Stars in a movie from BOTH 1944 and 1974
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
INTERSECT
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;
-- Rewritten without INTERSECT, joining StarsIn to itself on starID
SELECT DISTINCT S1.starID
FROM Movie M1
JOIN StarsIn S1 ON M1.movieID = S1.movieID
JOIN StarsIn S2 ON S1.starID = S2.starID
JOIN Movie M2 ON M2.movieID = S2.movieID
WHERE M1.year = 1944 AND M2.year = 1974;EXCEPT queries can likewise always be implemented using nested queries — “in the first result but not the second” becomes a NOT IN or NOT EXISTS subquery (sql-nested-queries):
-- Stars in a movie from 1944 but NOT 1974
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1944
EXCEPT
SELECT starID FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID WHERE year = 1974;
-- Rewritten without EXCEPT
SELECT DISTINCT S.starID
FROM Movie M JOIN StarsIn S ON M.movieID = S.movieID
WHERE M.year = 1944
AND S.starID NOT IN (
SELECT S2.starID
FROM Movie M2 JOIN StarsIn S2 ON M2.movieID = S2.movieID
WHERE M2.year = 1974);The rewrite is not just a workaround — NOT IN/NOT EXISTS is also the building block of the double-negation form of relational-division, so it is the pattern worth being fluent in regardless of dialect.
SQL Views
A view is a single table derived from other tables — base tables or other views — and defined by a query rather than by stored rows. Once created it is queried exactly like a table, which makes a view the natural way to name an intermediate result, hide complexity, or expose a restricted slice of the database to a class of users — the external level of the three-schema architecture, made concrete (dbms-fundamentals). Introduced in 2026-04-13-nested-queries-views-and-generative-ai; practised in week9-tutorial-applied-class-8-nested-queries-and-views.
Virtual vs materialized
- Virtual — the view does not physically exist on disk; it is recomputed each time it is queried, so it is always current. Think of it as a way of specifying a table you need to reference frequently, even though no such table exists.
- Materialized — the view table is physically created, and must be updated whenever the base tables are updated.
Creating and querying a view
CREATE VIEW <view name> (<column name> {, <column name>}) AS <select statement>;The column-name list is optional, even though the syntax above does not put it in [...]: supply it and the view’s columns take those names, omit it and they take the names of the target list — which is why a computed column needs an AS alias to have a name at all.
-- Count, gender and average salary of employees, per department
CREATE VIEW DepEmpStatus AS
SELECT   dNumber, dName, sex, COUNT(*) AS employeeNumber, AVG(salary) AS avgSalary
FROM     Department AS D
JOIN     Employee AS E ON D.dNumber = E.dNum
GROUP BY dNum, sex;

SELECT * FROM DepEmpStatus;A view has a schema like any other relation, and is written the same way in relational-mapping-notation — the aliases given in the target list become its column names. It is listed in the same schema as the base tables it is derived from, directly under them:
Department [dNumber, dName, mgrSSN, mgrStartDate]
Employee [ssn, name, dob, address, sex, salary, mgrSSN, dNum]
VIEW DepEmpStatus [dNumber, dName, sex, employeeNumber, avgSalary]That placement is the point: from the query writer’s side a view is one more relation in the schema, and nothing in a SELECT distinguishes it from a stored table.
Querying a view that computes its own columns
Because the view is just a table to the queries that follow, it can be joined, filtered, grouped and aggregated over in turn — including aggregating over columns the view itself computed:
CREATE VIEW V AS SELECT a + b AS d, c FROM R;
SELECT d, SUM(c)
FROM V
GROUP BY d
HAVING COUNT(*) <> 1;Worked exercise: given R below, which tuples does the second query return?
R.a |
R.b |
R.c |
V.d = a+b |
V.c |
|
|---|---|---|---|---|---|
| 1 | 1 | 3 | 2 | 3 | |
| 1 | 2 | 3 | 3 | 3 | |
| 2 | 1 | 4 | 3 | 4 | |
| 2 | 3 | 5 | 5 | 5 | |
| 2 | 4 | 1 | 6 | 1 | |
| 3 | 2 | 4 | 5 | 4 | |
| 3 | 3 | 6 | 6 | 6 |
Grouping V by d gives four groups — d = 2 (one row), d = 3 (c = 3, 4), d = 5 (c = 5, 4) and d = 6 (c = 1, 6). HAVING COUNT(*) <> 1 throws away the singleton group d = 2, so the answer is (3, 7), (5, 9) and (6, 7). Two things are worth taking from it: the grouping attribute d does not exist in any base table — it is created by the view and grouped over as if it were stored; and HAVING filters groups, so (2, 3) is excluded even though its underlying row is perfectly ordinary.
Why views exist
| Benefit | What it buys you |
|---|---|
| Simplification | Hides the complexity of the underlying tables behind one name |
| Security | Hides sensitive columns from users who should not see them |
| Computed columns | Derived values are computed on the fly, not stored |
| Logical data independence | Users and programs querying the view are insulated from changes to the underlying logical schema |
The security case is concrete: a user granted access to DepEmpStatus but not to Department/Employee can read departmental statistics without ever seeing an individual employee’s address or salary. See database-access-control for where this sits among the course’s authorisation mechanisms — granting a privilege on a view rather than on the base table restricts which columns and which rows an account can read at the same time, which a table-level grant cannot express.
Views instead of repeated subqueries
The worked example is “find the name of the department that spends the largest sum of money on salaries”. A query that needs the same derived table twice ends up computing it twice inside itself, which is hideously ugly:
-- Hideously ugly: the per-department total is re-derived in two places
SELECT d.dName
FROM Department d,
(SELECT dNum, SUM(salary) AS departmentWage
FROM Employee GROUP BY dNum) AS Temp
WHERE d.dNumber = Temp.dNum
AND Temp.departmentWage = (
SELECT MAX(departmentWage)
FROM (SELECT SUM(salary) AS departmentWage
FROM Employee GROUP BY dNum) AS Temp2
);
-- Cleaner: define the intermediate result once
CREATE VIEW Temp AS
SELECT dNum, SUM(salary) AS departmentWage
FROM Employee
GROUP BY dNum;
SELECT *
FROM Temp
WHERE departmentWage IN (SELECT MAX(departmentWage) FROM Temp);Both halves of the ugly version compute the same grouped aggregate; the view names it once and both the outer query and the MAX subquery then read that one name. (The second query selects from Temp only, so it returns the winning dNum/departmentWage pair — recovering dName needs one further join back to Department, which is the step drawn at the bottom of Figure 50.)
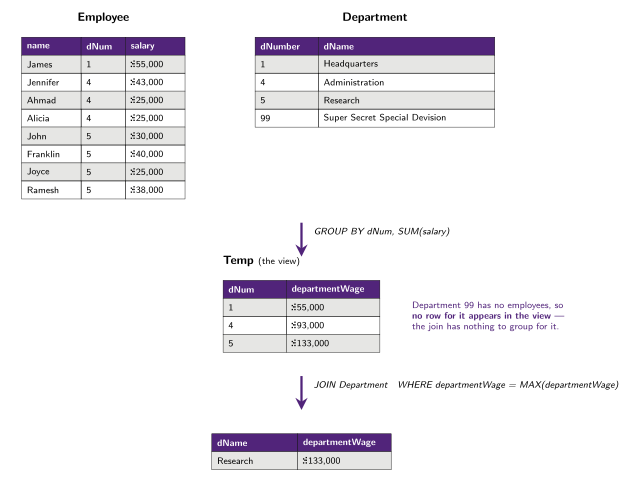
Figure 50: The worked view example, run on sample data: the per-department salary total is computed once into the view, and only then filtered down to the maximum. Department 99, a department with no employees, produces no row in the view at all, because the grouped join has nothing to group for it; a question phrased which department spends the most never notices, but one phrased list every department’s total would.
This is the standard way to answer “the group with the largest total” questions: a view holding one row per group with its aggregate, then a second query selecting the rows matching the extreme (sql-nested-queries covers the >= MAX(...) / >= ALL idioms that keep ties). Because a view definition is persistent, a script that recreates one should drop it first:
DROP VIEW IF EXISTS EarliestRoleGranting;
CREATE VIEW EarliestRoleGranting AS
SELECT RoleID, MIN(TimeStamp) AS EarliestTimeStamp
FROM RoleGranting
GROUP BY RoleID;
-- Who received each role first: join the base table back to the view
SELECT E.EmployeeID, E.FirstName, E.LastName, RG.RoleID
FROM RoleGranting RG
JOIN EarliestRoleGranting ERG
ON ERG.RoleID = RG.RoleID AND ERG.EarliestTimeStamp = RG.TimeStamp
JOIN Employee E ON E.EmployeeID = RG.EmployeeID;That join-back pattern — aggregate in a view, then join the view to the base table on the aggregated value — is how you retrieve the rows that achieve an aggregate, which a GROUP BY alone cannot give you (sql-aggregation-and-grouping).
Updating through a view
A view has no rows of its own, so view updates must occur at the base tables — and working out which base rows an update to a view row should touch is ambiguous and difficult. Consider DepEmpStatus above: its avgSalary column is an average over many employees, so an instruction to change it names no particular salary to change, and its employeeNumber column cannot be changed at all without inventing or destroying employees.
DBMSs therefore restrict view updates to some simple views on single tables, which are the ones called updatable views. The characteristic shape is a view that selects a subset of the rows and columns of one base table, with no join, no grouping and no aggregate, so each view row corresponds to exactly one base row.
That restriction is what makes the security case in the table above practical rather than read-only: the manager of each department can be given a view of the employees of their department, and because it is a plain row-and-column slice of one table, they can access and edit through it.
Dropping views
DROP VIEW [IF EXISTS] view_name [, view_name] ... [RESTRICT | CASCADE];
DROP VIEW DepEmpStatus;Dropping a view does not affect any tuples of the underlying relation — only the definition goes away. That asymmetry is the whole point of a virtual view: nothing of the data lives in it.
Views do, however, constrain what can be done to the tables under them: DROP TABLE … RESTRICT drops the table unless there is a view on it, while DROP TABLE … CASCADE drops the table and recursively drops any view referencing it (see sql-ddl).
Update Anomalies and Informal Design Guidelines
Before any of the formal machinery — functional dependencies, closures, normal forms — there are four informal measures of relational schema quality, and one recurring symptom (update anomalies) that a bad schema produces. Introduced in 2026-04-27-database-design-guidelines-and-functional-dependencies.
The four guidelines
| # | Guideline | What it protects against |
|---|---|---|
| 1 | Make sure the semantics of the attributes are clear in the schema | A relation whose meaning can’t be stated in one sentence |
| 2 | Reduce redundant values in tuples | Insertion, deletion and modification anomalies |
| 3 | Reduce null values in tuples | Wasted space, ambiguous meaning, broken entity integrity |
| 4 | Disallow spurious tuples — don’t allow lossy joins | Information silently invented by a join |
They’re informal because they’re qualitative: they tell you a schema looks wrong, but they don’t tell you which normal form it satisfies or how to fix it. That’s what functional-dependencies and normal-forms add.
Guideline 1 — one relation, one meaning
Design each relation so that it is easy to explain its meaning. Two halves: do use meaningful names, and don’t combine attributes from multiple entity types and relationship types into a single relation — that makes the meaning of an entity type confusing, and it leads to redundancy.
Take a schema with one relation per entity type, joined by a foreign key each way (see foreign-keys):
EMPLOYEE [Ename, Ssn, Bdate, Address, Dnumber]
P.K. Ssn
F.K. Dnumber references DEPARTMENT.Dnumber
DEPARTMENT [Dname, Dnumber, Dmgr_ssn]
P.K. Dnumber
F.K. Dmgr_ssn references EMPLOYEE.Ssnversus lumping both entity types into one relation:
EMP_DEPT [Ename, Ssn, Bdate, Address, Dnumber, Dname, Dmgr_ssn]EMP_DEPT can’t be described without the word “and” — it’s about employees and the departments they work for — and every employee of a department repeats that department’s name and manager. Guideline 1 is the informal statement of what er-to-relational-mapping does automatically when a schema is derived from an ER diagram: one relation per entity type.
Guideline 2 — the three update anomalies
Design the base relation schemas so that no insertion, deletion or modification anomalies occur in the relations. Where an anomaly can’t be designed out, the fallback is procedural: every application that touches the database must update the relations in a way that doesn’t compromise its integrity — which is a far weaker guarantee than a schema that makes the anomaly impossible.
The underlying design goal is to minimise the storage space base relations occupy, and how attributes are grouped into relation schemas has a large effect on that. An incorrect grouping costs more than space, though: it causes update anomalies, and those produce inconsistent data or outright loss of data.
Take Employee [id, name, level, salary], where salary is fixed per level in the real world (Developer = 60,000, Manager = 700,000, Driver = 50,000, Administration = 50,000):
| id | name | level | salary |
|---|---|---|---|
| 1 | Paris | Developer | 60,000 |
| 2 | Anna | Manager | 700,000 |
| 3 | Ben | Manager | 700,000 |
| 4 | Rose | Driver | 50,000 |
| 5 | Jack | Developer | 60,000 |
| 6 | Charlie | Administration | 50,000 |
The level→salary fact is stored once per employee rather than once per level, and that single design mistake produces three distinct failure modes:
| Anomaly | What goes wrong | Example |
|---|---|---|
| Modification | The same fact is stored in several tuples, so updating one copy leaves the others contradicting it | Raising Paris’s salary makes the two Developer rows disagree about what a Developer earns |
| Deletion | Deleting a tuple destroys an unrelated fact that happened to be stored only there | Deleting Charlie loses the fact that Administration pays 50,000 — he was the only one |
| Insertion | A fact can’t be recorded until some other, unrelated entity exists to hang it on; or inserting one introduces a contradiction | A Cook’s salary can’t be recorded until someone is actually employed as a Cook; and inserting a new Developer with a different salary contradicts the existing ones |
These aren’t only a textbook concern. A widely reported 2021 issue with Australia’s vaccine certificate system came from essentially this class of problem — state vaccination staff recorded details in a way that didn’t precisely match federal records, so contradicting datasets failed to reconcile automatically.
Arguing an anomaly concretely
Exam and case-study answers want the mechanism, not the definition restated. The pattern that works: name the tuple, name the FD it duplicates, and name the other tuple(s) that now disagree. From week10-tutorial-case-study-8-dirt-road-driving, on AssetUse [employeeID, assetID, timestamp, useDuration, assetType, purchaseDate, insuranceValue] with assetID → assetType, purchaseDate:
- Modification — changing the
purchaseDateof the row<2014, 1200, 20-12-2019 11:04:14, ...>requires changing the other row withassetID = 1200too, or the table now disagrees about when asset 1200 was bought. - Deletion — the row for asset
7901is the only one recording that asset, so deleting that use event also destroys the asset’s type and purchase date, which are facts about the asset, not the event. - Insertion — recording an asset nobody has used yet means inserting
<null, 2200, null, null, "Power Tools", 29-11-2019, 1,000>; sinceemployeeIDandtimestampare part of the primary key, that’s a null in the key and violates entity integrity (see integrity-constraints).
Spotting anomalies on an abstract relation
The drill version gives a relation, its FDs and an instance, and asks which of several operations is not an anomaly. Take R [A, B, C, D] with primary key B and D → {A, C}:
| A | B | C | D |
|---|---|---|---|
| 1 | 4 | 2 | 5 |
| 2 | 3 | 4 | 3 |
| 1 | 1 | 2 | 5 |
| Operation | Verdict |
|---|---|
Delete <2, 3, 4, 3> |
Deletion anomaly — the only row with D = 3, so the fact 3 → {2, 4} is lost |
Insert <3, 5, 3, 3> |
Insertion anomaly — asserts 3 → {3, 3} while the table already says 3 → {2, 4} |
Modify <1, 1, 2, 5> to <1, 2, 2, 5> |
No anomaly — only the key value changes; 5 → {1, 2} still holds everywhere |
Insert <1, null, 2, 4> |
Insertion anomaly — null in the primary key B |
Modify <1, 1, 2, 5> to <1, 2, 3, 5> |
Modification anomaly — now 5 → {1, 2} and 5 → {1, 3} |
Every verdict is the same one test: does the operation leave two tuples that agree on an FD’s LHS but disagree on its RHS (or put a null in the primary key)? Anomalies are FD violations waiting to happen, which is why functional-dependencies come next in the module.
Guideline 3 — reduce nulls
As far as possible, avoid placing attributes in a base relation whose values may be null. There are three reasons, worth keeping distinct because they fail in different ways:
| Problem | Consequence |
|---|---|
| Nulls waste storage space | Every row pays for a column most rows can’t use |
| Nulls introduce ambiguity | The reader can’t tell “not applicable”, “unknown” and “not recorded” apart |
| Nulls cannot be used for comparison | Predicates and aggregates over the column stop behaving as expected — see sql-nulls |
Where nulls are unavoidable, the requirement is that they apply in exceptional cases only — a column that is null for most rows is the signal that those attributes belong in a separate relation.
Two concrete cases: flattening a repeating group into fixed columns (item1, item2, item3, …) to reach 1NF leaves every short order carrying nulls; and the insertion anomaly above is really a null-in-the-primary-key problem, which integrity-constraints forbids outright.
Guideline 4 — join on keys
Design relation schemas so they can be (relationally) joined with equality conditions on attributes that are either primary keys or foreign keys (foreign-keys), in a way that guarantees no spurious tuples are generated. Joining on a non-key attribute lets a join manufacture rows that were never in the original relation — see [decomposition] for the worked lossy-join example, the lossless-join property, and how to test a proposed decomposition for it.
Decomposition as the fix
The cure for all three anomalies is to split the relation so each fact is stored once — a decomposition, defined and formalised in [decomposition].
For the Employee example, the anomalies come from level → salary being stored per-employee. Splitting on exactly that dependency:
Employee [id, name, level]
Employee.level references LevelSalary.level
LevelSalary [level, salary]removes all three anomaly types at once — modifying a level’s salary touches one row; deleting an employee can’t lose a level’s salary; a new level’s salary can be recorded before anyone holds that role.
Not every decomposition works. Splitting the same relation into [id, name, salary] and [salary, level] keeps all the attributes but fixes nothing: salary isn’t a valid link back to level (two levels share 50,000), so the pieces can’t be rejoined faithfully. Which split is correct isn’t a matter of taste — it’s determined by the FDs, which is why the rest of Module 4 exists.
See also
- functional-dependencies · normal-forms · [decomposition] · 3nf-synthesis
- 2026-04-27-database-design-guidelines-and-functional-dependencies — Module 4, part 1
- week10-tutorial-case-study-8-dirt-road-driving — anomaly write-ups on a real schema
Update Operations and Constraint Violations
There are three update operations on a relational database — insert, delete, and modify — and each can break a different subset of the integrity-constraints. Knowing which subset turns “does this operation violate anything?” from a search into a checklist. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints, drilled across week4-tutorial-applied-class-3-relational-integrity and week6-tutorial-case-study-4-easydrive-insurance. This is the model-level account; sql-dml is the same three operations as SQL statements.
Which operation can violate what
| Domain | Key | Entity integrity | Referential integrity | Semantic | |
|---|---|---|---|---|---|
| Insert | ✓ | ✓ | ✓ | ✓ | ✓ |
| Delete | ✓ | ✓ | |||
| Modify | ✓ | ✓ | ✓ | ✓ | ✓ |
Insert can violate all five: it supplies fresh values for every attribute, so any of them can be out of domain, duplicate an existing key, leave a primary key component null, point at a nonexistent row, or break a business rule. Five candidate tuples for the same two-table schema, differing in one value each, show one of each:
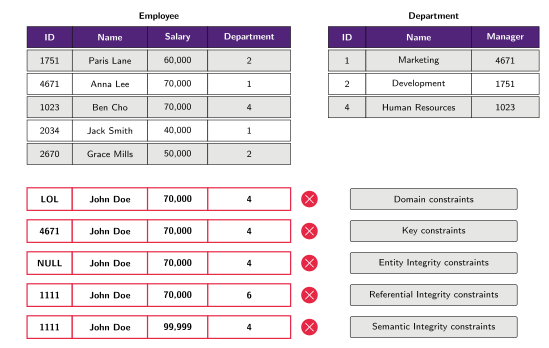
Figure 51: One insert, five ways to break it. Each candidate row differs from a legal Employee tuple in exactly one value, and each trips a different constraint: LOL is not a four-digit integer (domain), 4671 already exists (key), a null ID is a null primary key (entity integrity), department 6 is not in Department (referential integrity), and 99,999 exceeds the supervisor’s salary, which the business rule forbids (semantic). The crimson outline plus ✗ badge is the course’s notation for an illegal tuple.
Modification is the same picture: it can produce any of those five rows out of a legal one, so it inherits the whole column.
Delete is the interesting row. It supplies no values at all, so it cannot possibly produce an out-of-domain value, a duplicate key, or a null primary key. What it can do is remove a row that something else still references — a referential integrity violation on the other relation — or break a business rule. Both happen on the same two-table Employee/Department schema: deleting the department with id = 2 violates referential integrity, because employees still sit in it, while deleting employee 1023 violates a semantic constraint if the rule “every department must have at least one employee” has been stated. This asymmetry is worth remembering: for a delete, the only question is who points at the row being deleted.
Modify behaves like an insert restricted to the columns it touches: changing a key column risks a key violation, changing a foreign key risks a referential one, and changing a primary key component to NULL risks entity integrity.
Handling a referential violation on delete
Rejecting the operation isn’t the only option. At the relational-model stage there are exactly three outcomes for a referential integrity violation — it can be:
| Policy | Effect |
|---|---|
| Rejected | Refuse the delete; the referencing rows keep the referenced row alive |
| Cascaded | Delete the dependent rows too |
| Modified to a default value | Keep the dependent rows, but reset the referencing attribute’s value |
That three-way choice is what is examinable here; the finer-grained named actions — RESTRICT (the default), CASCADE, SET NULL and SET DEFAULT, each available on both delete and update — arrive with SQL DDL and are examined there, not at the model level. See sql-ddl for their exact semantics and syntax, and foreign-keys for the constraint itself.
The choice is a property of the foreign key, decided at design time from what the dependent rows mean without the row they reference: an insurance claim makes no sense without its policy, so EasyDrive declares its claims ON DELETE CASCADE.
Worked diagnoses
Against the company schema Employee [ssn, …, superSSN, dNumber], Department [dName, dNumber, mgrSSN, mgrStartDate], DeptLocations [dNumber, dLocation], Project [pName, pNumber, pLocation, dNum], WorksOn [essn, pNo, hours], Dependent [essn, depName, …], plus two business rules — an employee’s salary cannot exceed their supervisor’s, and a department cannot have more than three active projects:
| Operation | Violates |
|---|---|
Insert an employee with a fresh ssn, a real supervisor, salary below the supervisor’s |
Nothing — a well-formed insert |
Insert ('ProductA', 'A', 'Bellaire', 2) into Project when no department 2 exists |
Referential integrity and domain (pNumber is an integer, not 'A') |
Insert a department whose dNumber already exists and whose mgrSSN doesn’t |
Key and referential integrity |
Insert (677678989, null, 40.0) into WorksOn, essn not an employee |
Entity integrity (pNo is part of the key) and referential integrity |
| Insert an employee earning more than their supervisor | Semantic |
Delete the WorksOn rows for one employee |
Nothing — nothing references WorksOn, and no rule requires an employee to have assignments |
Delete an Employee row |
Referential integrity — WorksOn, Dependent, Department and Employee itself may all reference that ssn |
Modify a department’s mgrSSN to another existing employee |
Nothing, absent a stated rule about who may manage a department |
Modify an employee’s superSSN to an ssn that doesn’t exist |
Referential integrity |
| Insert a fourth active project for a department | Semantic |
Two habits fall out of this. First, always check whether the row being deleted is referenced, not just whether it exists. Second, “no violation” is a legitimate answer — several of the operations above are perfectly legal, and the temptation is to invent a rule that forbids them.
Failures cascade
A rejected operation changes nothing, which means later operations that assumed it succeeded fail too. In the EasyDrive case study, inserting a Vehicle with VehiclePurpose = 'Personal' fails on a domain constraint (the column is ENUM('Private', 'Business')); the next insert, a Policy referencing that vehicle, then fails on referential integrity even though its own values look fine. When a sequence of operations is being analysed, each one has to be judged against the state the previous ones actually left behind — not the state they were intended to leave.
The transaction concept
A transaction is an executing program containing database operations — reads, inserts, deletes, updates. The consistency requirement applies at the end of a transaction, not between its individual steps: constraint violations are permitted at intermediate points, as long as the final state satisfies every constraint specified on the schema.
A transaction is a walk between two consistent states. It starts from consistent state 1, and each INSERT, UPDATE or DELETE moves the database through intermediate states that need not satisfy the constraints; a COMMIT ends the walk at consistent state 2, while a ROLLBACK — or any error or failure along the way — returns the database to consistent state 1 as though nothing had happened. Either way the database is never left inconsistent.
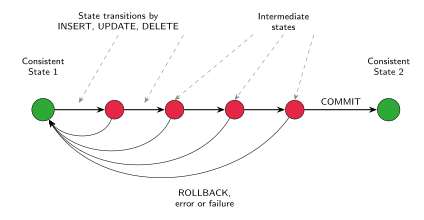
Figure 52: The transaction as a walk between consistent states. Green = a state satisfying every constraint, red = an intermediate state that need not. Only COMMIT and ROLLBACK end the walk, and both end it on a green state. The course has no house notation for transaction diagrams, so the shapes and colours here are not a convention to reproduce in an answer.
This is what makes mutually-dependent business rules satisfiable at all. Given “every department must have at least one employee” and “every employee must work for a department”, neither a new department (no employees yet) nor a new employee (no department yet) can be inserted on its own without breaking a rule. A single transaction that inserts the department and its first employee resolves the deadlock: the intermediate state after the first insert is inconsistent, but the final state after both inserts is valid, and that is the state the constraints are judged against.