flowchart TD
EMPLOYEE[EMPLOYEE] ---|"1 supervisor"| SUPERVISION{SUPERVISION}
SUPERVISION ---|"N supervisee"| EMPLOYEE
EMPLOYEE ===|"N"| WORKS_FOR{WORKS_FOR}
WORKS_FOR ---|"1"| DEPARTMENT[DEPARTMENT]
EMPLOYEE ---|"1"| MANAGES{MANAGES}
MANAGES ===|"1"| DEPARTMENT
DEPARTMENT ---|"1"| CONTROLS{CONTROLS}
CONTROLS ---|"N"| PROJECT[PROJECT]
EMPLOYEE ---|"M"| WORKS_ON{WORKS_ON}
WORKS_ON ---|"N"| PROJECT
EMPLOYEE ---|"1"| DEPENDENTSOF{DEPENDENTSOF}
DEPENDENTSOF ===|"N"| DEPENDENT[[DEPENDENT]]
Ssn(["Ssn (key)"]) --- EMPLOYEE
NameE(["Name"]) --- EMPLOYEE
Salary(["Salary"]) --- EMPLOYEE
DeptKey(["Number/Name (key)"]) --- DEPARTMENT
NumEmp(["Number_of_employees (derived)"]) --- DEPARTMENT
Locations(["Locations (multi)"]) --- DEPARTMENT
ProjKey(["Number/Name (key)"]) --- PROJECT
DepName(["Name (partial key)"]) --- DEPENDENT
INFS1200 — Week 3 Notes
The Relational Model and Integrity Constraints
Module 2, part 1. See relational-mapping-notation for the schema notation used here and in 2026-03-16-er-to-relational-mapping.
Outline
- Relational model concepts — relations, attributes, domains, tuples
- Integrity constraints
- The transaction concept
Relational model concepts
Introduced by E.F. Codd in 1970. Many DBMS products are based on this model — a sound theoretical foundation with a simple, uniform data structure called a relation. Four basic concepts: relations, attributes, domains, tuples.
Relations
A relation is the main construct for representing data — informally, a set of records, similar to a table with columns and rows. The term table is used interchangeably with relation, but every relation is a table; not every table is a relation — relations have specific properties based on mathematical set theory.
A counter-example is a spreadsheet-style sales report: a two-tier header (City: Brisbane / Product / Year: 1998 above Region / Suburb / blank / Qtr 1 … Qtr 4) over rows like South | Algester | Disks | 32 | 243 | 23 | 246. Merged and stacked header cells mean the columns are not a flat list of attributes, so it is a table but not a relation.
Relation components
Four of the model’s terms sit on one picture: the relation name labels the whole table, the attribute names label the columns, each row is a tuple, and every value in a column is drawn from that attribute’s domain.
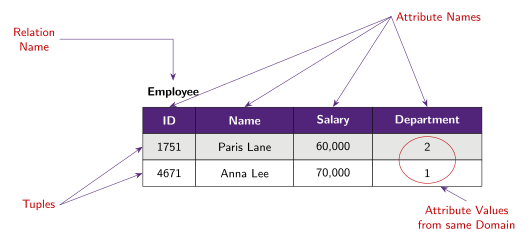
Figure 1: The anatomy of a relation, on an Employee example. Relation name above the table, attribute names in the purple header, tuples as rows, and one column circled: every value in it comes from the same domain.
Domains
A domain D is a set of atomic values — an atomic value is indivisible as far as the relational model is concerned. Each domain has a data type/format: integers, numbers/currency, fixed/variable-length character strings, date/timestamp, a sub-range of a data type (e.g. 1 ≤ grade ≤ 7), or an enumerated type (e.g. Gender ∈ {Male, Female, Other}) — including format-constrained domains like Australian phone numbers (61 + 9 digits) or car registrations (6 alphanumeric characters, no Q).
Attributes
Each attribute A is the name of a role played by some domain D in a relation R. The number of attributes in R is its degree. Same-named attributes across relations don’t necessarily share a domain (Department.id and Employee.id can be different domains despite the shared name id), and differently-named attributes can share a domain (Employee.id and Employee.managerId can both be drawn from the same “employee id” domain, despite the different names).
Tuples
Each tuple t is an ordered list of n values t = <v1, v2, …, vn>, where each value belongs to the corresponding attribute’s domain, or is the special value NULL. t is called an n-tuple.
Relation schema and instance
- Relation schema:
R [A1, A2, …, An]— a relation nameRand its list of attributes; n is the degree of the relation. E.g.Employee [id, name, sex, salary, department]is a schema of degree 5. - Relation instance:
r(R), a set of n-tuplesr = {t1, t2, …, tm}— the actual data, at a point in time.
Question — Schema and Instance
Match each characteristic to Schema or Instance: “data in the database”, “specified during database design”, “data describing the data”, “created through data update operations”.
NoteSolution
Instance: “data in the database”, “created through data update operations” (inserts/updates/deletes change the instance, not the schema). Schema: “specified during database design”, “data describing the data” (the schema is metadata — it describes the shape data must take, not the data itself).
Ordering of tuples and values
Relations are sets of tuples — mathematically, a set has no implied order. Semantically (e.g. when writing queries), tuple order is irrelevant. Physically, tuples reside on blocks of secondary storage, which have a partial ordering, so at that level tuples do have an order — but two instances with the same tuples in a different order are still the same relation. Likewise, an n-tuple is syntactically an ordered list — every tuple in one relation must list values in the same attribute order — but semantically, which order is chosen doesn’t matter, as long as the attribute/value correspondence is maintained consistently.
Integrity constraints
Integrity constraints are rules that enforce the correctness of a database — they must hold on every instance of the schema. Five kinds: domain, key, entity integrity, referential integrity, semantic.
Domain constraint
A domain constraint violation occurs when an attribute’s value doesn’t appear in its corresponding domain. Assuming the domain of Employee.id is a 4-digit integer, inserting ("LOL", Anna Lee, 70,000, 4) is rejected; (4671, Anna Lee, 70,000, 4) is accepted.
Key
A key is a minimal set of attributes that uniquely identifies tuples in a relation — minimal meaning no redundant attributes, not necessarily the smallest possible set. A schema can have more than one key (each a candidate key); the one chosen as the relation’s main key is the primary key (conventionally underlined). A key constraint violation occurs when a tuple is inserted/modified to share a key value with an existing tuple. With Employee holding (1751, Paris Lane, 60,000, 2) and (4671, Anna Lee, 70,000, 1), inserting (4671, Ben Cho, 70,000, 4) is rejected because id = 4671 is taken; (1023, Ben Cho, 70,000, 4) is accepted.
See relational-keys for the minimality argument and for the two key questions below drawn as one picture.
Question — Key
Assuming department IDs are unique, which of the following is a key for Department [id, name, manager]: (A) (id), (B) (id, name), (C) (id, manager), (D) all of the above?
NoteSolution
(A) (id) — since IDs are already unique on their own, (id) is the minimal key; (id, name) and (id, manager) both contain a redundant extra attribute (adding anything to an already-unique set isn’t minimal).
Question — Key (multiple candidate keys)
Assuming department IDs are unique and the combination of Name and Manager is also unique per department, which of the following is a key(s): (A) (id), (B) (id, name), (C) (name, manager), (D) both A and C?
NoteSolution
(D) Both A and C. (id) is still minimal and unique on its own; now (name, manager) is also minimal and unique, making it a second candidate key. (id, name) is still not minimal since (id) alone already suffices.
Entity integrity constraint
An entity integrity constraint violation occurs when a tuple is inserted/modified such that (any part of) its primary key is NULL — for a composite primary key, no part of it can be null. Inserting (NULL, Jack Smith, 40,000, 1) into Employee is rejected; (2034, Jack Smith, 40,000, 1) is accepted.
Foreign keys
A foreign key is a set of attributes in one relation that links it to another relation’s primary key. Formally: let FK be attributes in R1 and PK the primary key of R2. FK in R1 is a foreign key referencing PK in R2 if FK/PK share a domain, and for every tuple t1 in R1, either t1[FK] is NULL, or some tuple t2 in R2 has t1[FK] = t2[PK].
Department [id, name, manager]
Department.manager references Employee.id

Employee [id, name, sex, salary, department]
Employee.department references Department.id
Both directions are live at once here. In the example instance, Department 4 (Human Resources) has a NULL manager, employee 2034 has a NULL department, and both rows are legal — an absent reference is fine, a dangling one is not. The two figures in foreign-keys draw this instance with the foreign-key arrows on it.
Self-referencing relations are also possible — a table can reference itself. For example, add a ManagerID column to Employee and declare Employee.managerID references Employee.id. Composite foreign keys are possible too, referencing a multi-attribute primary key:
Student [sid, name]

Course [cid, department, manager]

Enrollment [sid, cid, department, grade]
Enrollment.sid references Student.sid
Enrollment.{cid, department} references Course.{cid, department}
Course is keyed on the pair (cid, department), so Enrollment has to carry both columns to name one course — one composite constraint over a tuple of columns, not two separate ones.
Referential integrity constraint
A referential integrity constraint violation occurs when a foreign key value doesn’t match any existing primary key value in the referenced relation (and isn’t NULL). The constraint guarantees that a department with number 2 exists before the “Grace Mills” tuple is stored: (2670, Grace Mills, 50,000, 5) is rejected because there is no Department 5, while (2670, Grace Mills, 50,000, 2) is accepted.
Semantic (business-rule) constraint
Semantic constraints are generally defined by the business/organisation during client consultation (not derivable from the schema’s structure alone) — e.g. “the salary of an employee should not exceed the employee’s supervisor’s salary”, or “the maximum number of hours that an employee can work on a project is 56”. Often implemented in a constraint specification language (SQL) using triggers and assertions.
Worked on the example instance: department 1’s manager is Anna Lee, who earns 70,000, so inserting (2967, Arron Dills, 100,000, 1) breaks the salary rule and is rejected; (2967, Arron Dills, 40,000, 1) is accepted. Nothing about the shape of the two relations rules the first one out — that is exactly what makes it semantic rather than structural.
Exercise — name an example of each
Given the schema below, give an example of (1) a key, (2) a foreign key, (3) a domain constraint.
Student [stID, name, email]

Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode

Course [cCode, title, units]
NoteSolution
- Key —
stIDin relationStudent. - Foreign key —
stIDin relationEnrolment. - Domain constraint —
cCode, four letters followed by four numbers.
The same attribute name supplies the first two answers depending on which relation it is read in: it is a key where it identifies, a foreign key where it refers.
Question — Integrity Constraints (password)
Opening an online bank account, you enter your usual password “password123”, but get: “your password must contain at least one capital letter and a number”. What kind of constraint is this?
NoteSolution
Domain constraint — the domain of “password” is defined as strings matching a particular format (≥1 capital, ≥1 digit); “password123” simply isn’t a member of that domain.
Question — Integrity Constraints (which is violated?)
Given Department [id, name, manager] and Employee [id, name, salary, department], with Department rows (1, Marketing, 4671), (2, Development, 1751), and Employee rows (1751, Paris Lane, 60000, 2), (4671, Anna Lee, 70000, 1), (2670, Grace Mills, 50000, 2), (2034, Jack Smith, 40000, 1) — which constraint is violated by each of the following?
- Inserting
(2670, James Smith, 40000, 1)intoEmployee. - Inserting
(2644, James, Smith, 1)intoEmployee(note: only 4 values given for a 4-attribute relation, but shifted). - Inserting
(2644, James Smith, 40000, 3)intoEmployee. - Deleting
(2, Development, 1751)fromDepartment. - Updating
(2, Development, 1751)to(2, Development, 2034)inDepartment.
NoteSolution
- Key constraint —
id = 2670already exists inEmployee. - Domain constraint — the shift means
salaryreceives a non-numeric value ("Smith"), which isn’t a member ofsalary’s domain. - Referential integrity constraint — no
Departmentwithid = 3exists. - Referential integrity constraint —
Employeerows withdepartment = 2still exist (Grace Mills), so deletingDepartment 2would leave a dangling foreign key. - None of the above (by the stated constraints) —
Employeewithid = 2034doesn’t actually work inDepartment 1, but there’s no declared constraint stopping a department’s manager from being an employee of a different department; this would only be a semantic constraint if the business rule “a manager must work in the department they manage” were explicitly specified.
Constraints and operations
Enforcing integrity constraints keeps the database consistent — insert, modify, and delete operations must not leave the database in an inconsistent state; if a database update submitted to the DBMS would violate integrity, it must be rejected.
Insertion and deletion differ in which constraints they can violate:
- Insertion/modification can violate any of the five constraint types (domain, key, entity integrity, referential integrity, semantic).
- Deletion can only violate referential or semantic constraints. A referential integrity violation on delete can be handled by rejecting the delete, cascading it (deleting dependent rows too), or modifying the referencing attribute values to a default value.
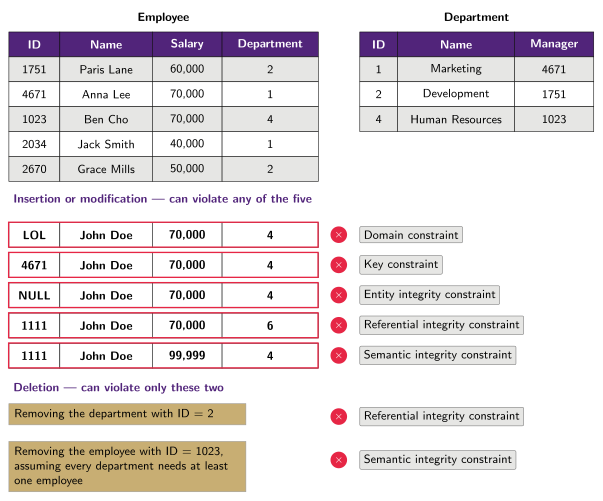
Figure 2: Which operation can violate which constraint, on an Employee/Department instance. Each of the five candidate insertions differs from a legal row in exactly one respect; the two deletion cases sit below them.
Read the five candidate rows as a controlled experiment: each differs from a legal row in exactly one respect, and that one difference names the constraint. The last one is the giveaway that semantic constraints are not structural — (1111, John Doe, 99,999, 4) is a perfectly well-formed tuple with a fresh key, a real department and no nulls, and is still rejected. It breaks the salary rule: 99,999 exceeds the 70,000 earned by Ben Cho, the manager of department 4.
The transaction concept
A transaction is an executing program that includes database operations (reads, inserts, deletes, updates). At the end of a transaction, the database must be left in a valid/consistent state satisfying all constraints — but constraint violations are allowed at intermediate steps within the transaction. That is the whole point: transactions allow a suite of queries to run where constraint violations in intermediate steps are permitted.
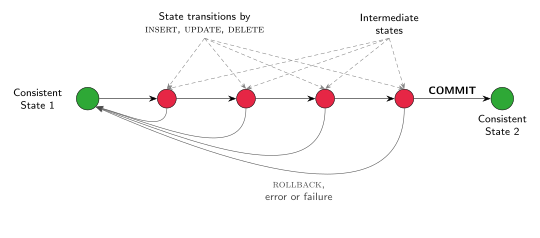
Figure 3: A transaction as a walk between consistent states. INSERT/UPDATE/DELETE move the database through intermediate states that may violate constraints; COMMIT is legal only into a consistent state, and ROLLBACK (or an error or failure) returns to the state the transaction started from. INFS1200 has no house notation for transaction diagrams; the shapes and colours here follow the figure in the SAP MaxDB documentation, not a course convention.
Example: given Department [id, name, manager] and Employee [id, name, sex, salary, department], with the business rules “every department must have ≥1 employee” and “every employee must work for a department” — neither a new department (no employees yet) nor a new employee (no department yet) can be inserted alone without violating one of these rules. A transaction that inserts both the new department and its first employee together resolves this: the intermediate state (after just one insert) is inconsistent, but the final state (after both inserts) is valid.
Applied Class 2: Entity Relationship Diagrams
Practice for 2026-03-02-weak-entities-the-eer-model-and-design-choices. See er-diagram-notation and relationship-constraints for reference.
Section A — ERD components
Given a COMPANY ER diagram (EMPLOYEE, DEPARTMENT, PROJECT, DEPENDENT, plus the relationships MANAGES/WORKS_FOR/CONTROLS/ WORKS_ON/SUPERVISION/DEPENDENTSOF), find an example of each ERD component.
NoteWorking
| Component | Example |
|---|---|
| Strong entity | EMPLOYEE, DEPARTMENT, PROJECT |
| Weak entity | DEPENDENT |
| (Candidate) key | EMPLOYEE.Ssn; DEPARTMENT.Name/Number; PROJECT.Name/Number; DEPENDENT.{Ssn, Name} |
| Partial key | DEPENDENT.Name |
| Composite attribute | EMPLOYEE.Name (→ FirstName, MiddleInitial, LastName) |
| Derived attribute | DEPARTMENT.Number_of_employees |
| Multivalued attribute | DEPARTMENT.Locations |
| 1-1 relationship | MANAGES |
| 1-N relationship | CONTROLS, WORKS_FOR, SUPERVISION |
| M-N relationship | WORKS_ON |
| Identifying relationship | DEPENDENTSOF |
Section B — ERD modelling assumptions
Uses a health/vaccination EER diagram: HEALTHWORKER —1:N OVERSEEN→ HEALTH (subclass of PARTICIPANT, alongside an overlapping AGE subclass); VACCINE (ID, composite Key = Brand+Name) has a recursive WITH relationship (roles First/Second, both partial) and —1:N HAS→ BATCH (weak entity, partial key Number).
Evaluate each statement as Correct or Incorrect.
B1 — Each vaccine must have a second dose or a preceding dose.
B2 — A participant can be overseen by several healthcare workers.
B3 — Every participant in the HEALTH subclass is overseen by a health worker during vaccination.
B4 — A vaccine can only be uniquely identified by the combination of its Brand and Name.
B5 — A participant can be in both the HEALTH subclass and the AGE subclass.
B6 — A BATCH is uniquely identified by only its number.
NoteWorking
- B1 Incorrect — the recursive
WITHrelationship lets a vaccine be recorded as a first or second dose, but participation from both sides is partial: a vaccine doesn’t have to be part of a two-shot program. - B2 Incorrect —
OVERSEENis 1:N fromHEALTHWORKERtoHEALTH: one healthcare worker can oversee many participants, but each participant has at most one overseeing healthcare worker. - B3 Correct —
OVERSEENhas total participation from theHEALTHside. - B4 Incorrect —
VACCINEhas two candidate keys: the compositeKey(Brand+Name), or itsID. - B5 Correct —
HEALTHandAGEare overlapping subclasses ofPARTICIPANT— an instance can be a member of both at once. - B6 Incorrect —
BATCHis a weak entity; its real key isBatch Numbercombined with its ownerVACCINE’s key (eitherIDorKey).
flowchart TD
    PARTICIPANT[PARTICIPANT] --- o1(("o"))
    o1 --- HEALTH[[HEALTH]]
    o1 --- AGE[[AGE]]
    HEALTHWORKER[HEALTHWORKER] ---|"1"| OVERSEEN{OVERSEEN}
    OVERSEEN ===|"N"| HEALTH

    VACCINE[VACCINE] ---|"First"| WITH{WITH}
    WITH ---|"Second"| VACCINE
    VACCINE ---|"1"| HAS0{HAS}
    HAS0 ===|"N"| BATCH[[BATCH]]

    IDv(["ID (key)"]) --- VACCINE
    VKey(["Key (key)"]) --- VACCINE
    Brand(["Brand"]) --- VKey
    VName(["Name"]) --- VKey
    Number(["Number (partial key)"]) --- BATCH
Section C — Conceptual modelling
Question 1 — Cinema
Movies (unique Name, Description, RunningTime); attendants (unique StaffID, Name, Phone); customers (unique ID, Name, Email); viewings record a Timestamp (unique per customer+movie) and any Snacks purchased; exactly one attendant oversees each viewing.
NoteWorking
MOVIE —1:N HAS→ VIEWING (Timestamp, multivalued Snack) —1:N OVERSEES←ATTENDANT; CUSTOMER —1:N HAS→ VIEWING. VIEWING’s key is the composite of its owning CUSTOMER+MOVIE+Timestamp (it’s a weak entity in the fuller reading of the UoD, or an M:N relationship with a Timestamp key attribute, depending on the design choice made).
flowchart TD
    MOVIE[MOVIE] ---|"1"| HAS1{HAS}
    HAS1 ---|"N"| VIEWING[[VIEWING]]
    CUSTOMER1[CUSTOMER] ---|"1"| HAS2{HAS}
    HAS2 ---|"N"| VIEWING
    VIEWING ---|"N"| OVERSEES{OVERSEES}
    OVERSEES ---|"1"| ATTENDANT[ATTENDANT]

    NameM(["Name (key)"]) --- MOVIE
    Description(["Description"]) --- MOVIE
    RunningTime(["RunningTime"]) --- MOVIE
    Timestamp(["Timestamp (partial key)"]) --- VIEWING
    Snack(["Snack (multi)"]) --- VIEWING
    StaffID(["StaffID (key)"]) --- ATTENDANT
    IDc(["ID (key)"]) --- CUSTOMER1
Question 2 — Medical clinic
Patients (PatientID) and doctors (LicenceNo); each doctor is either a GP or a specialist (never both), specialists also record their SpecialisationArea; doctors work in clinics (RegistrationNo), one clinic can have several doctors; some clinics are specialist clinics, each run by exactly one specialist doctor; patients make appointments (Fee) to consult doctors.
NoteWorking
PATIENT (PatientID) —M:N CONSULTS (Fee)→ DOCTOR (LicenceNo), which disjointly (d) specialises into GP/SPECIALIST (SpecialisationArea). DOCTOR —M:N WORKSIN→ CLINIC (RegistrationNo), which has a subclass SPECIALIST CLINIC —1:N RUNS←SPECIALIST.
Assumptions: every patient in the DB has made an appointment; every clinic has at least one doctor.
flowchart TD
    PATIENT[PATIENT] ---|"M"| CONSULTS{CONSULTS}
    CONSULTS ---|"N"| DOCTOR[DOCTOR]
    DOCTOR --- d(("d"))
    d --- GP[[GP]]
    d --- SPECIALIST[[SPECIALIST]]
    DOCTOR ---|"M"| WORKSIN{WORKSIN}
    WORKSIN ---|"N"| CLINIC[CLINIC]
    CLINIC --- SPECIALISTCLINIC[["SPECIALIST CLINIC"]]
    SPECIALIST ---|"1"| RUNS{RUNS}
    RUNS ---|"N"| SPECIALISTCLINIC

    PatientID(["PatientID (key)"]) --- PATIENT
    LicenceNo(["LicenceNo (key)"]) --- DOCTOR
    Fee(["Fee"]) --- CONSULTS
    SpecArea(["SpecialisationArea"]) --- SPECIALIST
    RegNo(["RegistrationNo (key)"]) --- CLINIC
Section D — Additional resources (not covered in the applied class)
Question 1 — Bubble tea shop
BUBBLETEA (unique Name, Description, Ingredients, Price); customers sign up with a BubbleID, Name, Phone, Email; each order (BUYS) is timestamped with a PrepTime; customers can friend other customers.
NoteWorking
BUBBLETEA —N:M BUYS (PrepTime, key Timestamp)→ CUSTOMER (BubbleID); CUSTOMER has a recursive M:N FRIENDS relationship with itself (roles Requestor/Requestee).
flowchart LR
    BUBBLETEA[BUBBLETEA] ---|"N"| BUYS{BUYS}
    BUYS ---|"M"| CUSTOMER2[CUSTOMER]
    CUSTOMER2 ---|"Requestor"| FRIENDS{FRIENDS}
    FRIENDS ---|"Requestee"| CUSTOMER2

    NameB(["Name (key)"]) --- BUBBLETEA
    Description2(["Description"]) --- BUBBLETEA
    Ingredients(["Ingredients"]) --- BUBBLETEA
    Price(["Price"]) --- BUBBLETEA
    Timestamp2(["Timestamp (partial key)"]) --- BUYS
    PrepTime(["PrepTime"]) --- BUYS
    BubbleID(["BubbleID (key)"]) --- CUSTOMER2
Question 2 — Bank
Bank (composite key Code+Name, Address) has branches (Number unique per-bank, Address); a branch manages accounts and loans; every account has Type, Balance, unique Number, controlled by ≥1 customers; every loan has unique Number, Type, Amount, connected to ≥1 customers; every loan/account belongs to exactly one branch; customers have Name, Address, Phone, unique ID.
NoteWorking
BANK (key Key = Code+Name) —1:N OPERATES→ BRANCH (weak entity, partial key Number) —1:N OFFERS→ LOAN (Number, Type, Amount); BRANCH —1:N OFFERS→ ACCOUNT (Number, Balance, Type). LOAN —M:N HAS→ CUSTOMER (ID, Name, Address, Phone); ACCOUNT —M:N HAS→ CUSTOMER, both with total participation on the LOAN/ACCOUNT side (“must be associated with… at least one customer”).
flowchart TD
    BANK[BANK] ---|"1"| OPERATES{OPERATES}
    OPERATES ===|"N"| BRANCH[[BRANCH]]
    BRANCH ---|"1"| OFFERS1{OFFERS}
    OFFERS1 ---|"N"| LOAN[LOAN]
    BRANCH ---|"1"| OFFERS2{OFFERS}
    OFFERS2 ---|"N"| ACCOUNT[ACCOUNT]
    LOAN ===|"M"| HAS3{HAS}
    HAS3 ---|"N"| CUSTOMER3[CUSTOMER]
    ACCOUNT ===|"M"| HAS4{HAS}
    HAS4 ---|"N"| CUSTOMER3

    BankKey(["Key (key)"]) --- BANK
    Code(["Code"]) --- BankKey
    BName(["Name"]) --- BankKey
    BranchNum(["Number (partial key)"]) --- BRANCH
    LoanNum(["Number (key)"]) --- LOAN
    AcctNum(["Number (key)"]) --- ACCOUNT
    IDc2(["ID (key)"]) --- CUSTOMER3
Case Study 2: Dirt Road Driving
Group case study applying integrity constraints from 2026-03-09-the-relational-model-and-integrity-constraints to Dirt Road Driving’s internal payroll system. See relational-mapping-notation for reference.
Section A — The schema
Dirt Road Driving’s payroll backend, built by an external developer:
Employee [id, firstName, lastName, role]

Project [name, description, funding, projectLeader]
Project.projectLeader references Employee.id

TimeLog [employeeID, projectName, date, hoursWorked, approved]
TimeLog.employeeID references Employee.id
TimeLog.projectName references Project.name
Company policy (a semantic/business-rule constraint, not enforceable by the schema’s structure alone): administration staff cannot be project leaders.
Question 1 — Identify a key and a foreign key
NoteWorking
Any candidate key works, e.g. Employee.id, Project.name, or TimeLog.{employeeID, projectName, date} (composite). Any foreign key works, e.g. Project.projectLeader, TimeLog.employeeID, or TimeLog.projectName.
Section B — Integrity constraint violations
Sample data: Employee has (1919, Diluen, Smith, Developer), (2014, Daniel, Johnson, Administration), (2019, Annie, Fang, Developer), (2020, Russell, Turner, Manager). Project has ("Website Setup", ..., 12000, 2019), ("2020 Marketing", ..., 40000, 2020). TimeLog has 5 rows, including (1919, "Website Setup", 2/1/2020, 5, true) and (2020, "2020 Marketing", 2/1/2020, 5, true), among others — no row with employeeID = 1919 and projectName = "2020 Marketing". For each operation, does it violate an integrity constraint?
Operation 1 — Update ("Website Setup", ..., 12000, 2019) to ("Website Setup", ..., 20000, 1919) in Project (changes funding and projectLeader; 1919 is a Developer).
Operation 2 — Insert (2014, "Rebecca", "Zhang", "Administration") into Employee.
Operation 3 — Update (2020, "2020 Marketing", 2/1/2020, 5, true) to (1919, "Overall Marketing", 2/1/2020, 5, true) in TimeLog.
Operation 4 — Insert (NULL, "Test", "Test", "Test") into Employee.
Operation 5 — Delete (2014, "Daniel", "Johnson", "Administration") from Employee.
Operation 6 — Insert ("Talent Recruitment Initiative", ..., 10000, 2014) into Project (2014 is Administration).
NoteWorking
- Op 1 No — a well-formed update;
funding/projectLeadervalues both change to valid new values (1919is a real, existing employee), and nothing here conflicts with a key/entity/referential/semantic rule. - Op 2 Yes — Key constraint.
id = 2014already exists inEmployee(idis its primary key), so this insert isn’t unique. - Op 3 Yes — Referential integrity.
TimeLog.projectNamereferencesProject.name, but noProjectnamed"Overall Marketing"exists — the foreign key value doesn’t resolve. - Op 4 Yes — Entity integrity.
Employee.idis the primary key, and it’sNULLhere — no part of a primary key may ever beNULL. - Op 5 Yes — Referential integrity.
TimeLog.employeeID(foreign key toEmployee.id) has a row referencingemployeeID = 2014— deleting thatEmployeerow would leave it dangling. (Strictly: under the defaultON DELETE RESTRICT— see below.) - Op 6 Yes — Semantic (user-defined) constraint.
projectLeader = 2014is anAdministrationstaff member, violating the business rule that administration staff cannot be project leaders — this isn’t something the schema’s structure alone captures (no foreign key/domain/key rule is broken), it’s an organisation-specific policy.
What a deletion actually “violates”
Ops 3 and 5 are both answered “referential integrity”, but only one of them is a fact about the data. Op 3 sets TimeLog.projectName to "Overall Marketing", and no Project row carries that name — nothing the schema can be told will make that value resolve. Op 5 deletes an Employee row that a TimeLog row still points at, and there the foreign key declaration chooses the outcome: what happens to the child rows is a referential triggered action, written alongside the foreign key in the CREATE TABLE (or added later by ALTER TABLE), in the same shape the lecture uses:
CONSTRAINT employee_fk FOREIGN KEY (employeeID) REFERENCES Employee(id)
    ON DELETE RESTRICT ON UPDATE CASCADE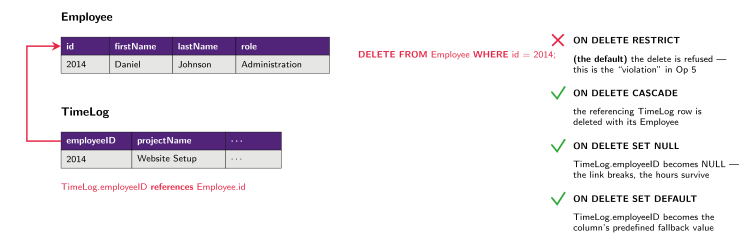
Figure 4: The four referential triggered actions, applied to this case study’s own foreign key. Only the first refuses the delete, so “Op 5 violates referential integrity” is really “Op 5 violates it under the default ON DELETE RESTRICT” — under the other three the delete succeeds and the child row is redefined instead. The crimson arrow is the course’s foreign-key convention: arrowhead on the referenced attribute, pointing from child to parent. The brief states only that some TimeLog row references employee 2014 without spelling that row out; the row drawn stands in for it.
So a “violation” of referential integrity on a delete is a statement about the schema as much as about the data — the same delete is legal, illegal or silently destructive depending on one clause. The identical four choices exist as ON UPDATE … and govern a change to a referenced value: renaming Employee.id 2014 raises exactly the same question as deleting the row. See foreign-keys and sql-ddl.
Question 2 — Original examples
Give an original example (not copied from above) of an operation that would cause (a) a domain constraint violation, (b) a referential integrity constraint violation.
NoteWorking
- Domain constraint: inserting
("A string is not a number", "Joe", "Blog", "Administration")intoEmployee—idis meant to be numeric, not a string. (b) Referential integrity: deleting(2020, "Russell", "Turner", "Manager")fromEmployeewhile aProjectrow still hasprojectLeader = 2020— the deletion would leave that foreign key dangling.
Reference material
ER Design Choices
When modelling complex organisations, a database designer faces design choices: two people modelling the same Universe of Discourse will not draw the same diagram, and that isn’t necessarily a sign either of them is wrong. Introduced in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Equivalent vs inequivalent choices
- Equivalent choices — an aspect of the UoD can be represented in an ER diagram by two different methods which are both equivalent, i.e. the resulting database will be the same. Genuinely a matter of taste; pick either.
- Inequivalent choices — the UoD is slightly ambiguous, and an aspect of it can be mapped two different ways which both meet the specification of the UoD but lead to different limitations/constraints being enforced by the database. Here the choice has consequences, and the right move is to pick one and note the assumption under the diagram.
That second case is the reason a diagram is rarely a complete answer on its own. The medical-clinic model in week3-tutorial-applied-class-2-entity-relationship-diagrams carries the explicit assumptions “every patient in the DB has made an appointment” and “every clinic has at least one doctor” — neither is stated in the brief, both change the participation constraints, so both get written down rather than smuggled into the drawing.
The four common choice points
| Choice | The question | Worked example |
|---|---|---|
| Attribute vs (weak) entity type | Is this a fact about something, or a thing in its own right? | An interview’s Details (Department, Date) as a key attribute of the APPLIES relationship, vs. a separate weak INTERVIEW entity |
| Attribute vs subclass | Is this a value, or a kind? | EMPLOYEE.Type as a plain attribute, vs. splitting into SECRETARY / ENGINEER subclasses |
| Subclass relationship vs superclass relationship | Does this relationship apply to everyone, or only to one kind? | Giving WORKSON (to PROJECT) to the EMPLOYEE superclass, vs. only to ENGINEER |
| Binary relationships vs n-ary relationships | Does the association hold between pairs, or genuinely among all three at once? | SUPPLIER / PROJECT / PART as three binaries (SUPPLIES, CANSUPPLY, USES) vs. one ternary SUPPLIES carrying a quantity |
Each row is a real fork, not a stylistic one:
- Attribute vs entity type. Pulling something out into its own entity type gives it identity — it can then be referred to, counted, and given relationships of its own. The cinema model in the same applied class makes exactly this call about a
VIEWING: it can be read as a weak entity owned byCUSTOMER+MOVIEwithTimestampas its partial key, or as an M:N relationship carryingTimestampas a key attribute. Both fit the brief; they differ in whether a viewing is a thing or a link. (interpreting-er-diagrams shows the reading side of the same call: without a distinguishing attribute, a plain M:N pair can only be recorded once.) - Attribute vs subclass. A subclass earns its place when the subtypes have different attributes or relationships —
SECRETARYrecording aTypingSpeedthat means nothing for an engineer. If the only difference is the label itself, a plain attribute says the same thing with less diagram. Applied class 2 gives the efficiency half of the argument explicitly: subclasses let a data attribute be stored for some entity instances rather than all of them, and so reduce the number of null/empty values — not everySHOWneeds aRating, onlyENTERTAINMENTshows do. See specialisation-and-generalisation. - Binary vs n-ary. Three binary relationships and one ternary relationship are not interchangeable: the binaries record that a supplier can supply a part and that a project uses a part, while the ternary records the specific fact that this supplier supplied this part to this project. Splitting a genuinely three-way fact into pairs loses information; forcing a ternary where only pairwise facts exist invents it. See relationship-types.
- Subclass vs superclass relationship. Attaching a relationship higher up the hierarchy widens what the schema will accept. That looks harmless on a diagram and is not harmless afterwards — see below.
Worked example: attribute vs weak entity type
A candidate applies to a company, and each application involves an interview with a department on a date. Both diagrams below satisfy that description. The world does not choose between them.
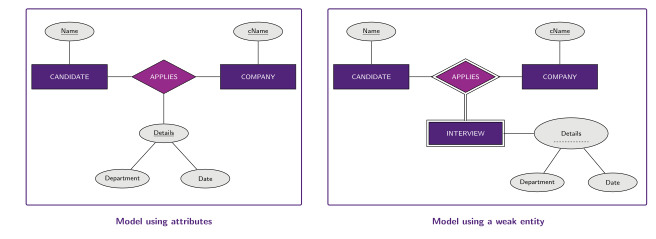
Figure 5: Attribute vs. (weak) entity type: two models of the same description. Left: the interview details hang off the APPLIES relationship as a composite key attribute Details (solid underline) made of Department and Date. Right: the interview becomes a thing — a weak entity owned by both CANDIDATE and COMPANY, so APPLIES becomes an identifying relationship (double diamond, double line into the weak entity) and Details demotes from key attribute to composite partial key (dotted underline). Nothing else on the diagram moves.
The two are alternatives, and the choice between them looks cosmetic. It stops looking cosmetic the moment the UoD says an interview results in a job offer: an attribute cannot be the endpoint of a relationship, so only the weak entity can carry a RESULTSIN link to a JOBOFFER entity. That extended diagram is drawn in 2026-03-02-weak-entities-the-eer-model-and-design-choices.
Worked example: binary vs n-ary relationships
Suppliers, projects and parts. Modelled as three binary relationships — a supplier supplies a project, a supplier can supply a part, a project uses a part:
flowchart TD
    SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
    SUPPLIES ---|"P"| PROJECT[PROJECT]
    SUPPLIER ---|"M"| CANSUPPLY{CANSUPPLY}
    CANSUPPLY ---|"N"| PART[PART]
    PROJECT ---|"P"| USES{USES}
    USES ---|"N"| PART
    sName(["sName (key)"]) --- SUPPLIER
    projName(["projName (key)"]) --- PROJECT
    partNo(["partNo (key)"]) --- PART
Modelled as one ternary relationship, with all three lines running into a single diamond that can then carry a quantity:
flowchart TD
    SUPPLIER[SUPPLIER] ---|"M"| SUPPLIES{SUPPLIES}
    SUPPLIES ---|"P"| PROJECT[PROJECT]
    SUPPLIES ---|"N"| PART[PART]
    SUPPLIES --- quantity(["quantity"])
    sName(["sName (key)"]) --- SUPPLIER
    projName(["projName (key)"]) --- PROJECT
    partNo(["partNo (key)"]) --- PART
The quantity is the tell. It is a fact about a supplier-project-part triple, so there is nowhere to put it in the binary model — hanging it on SUPPLIES there would record how much a supplier sent a project without saying of what. This is the inequivalent case: the two diagrams do not produce the same database.
Worked example: subclass vs superclass relationship
EMPLOYEE specialises disjointly into SECRETARY and ENGINEER, and somebody works on projects. Which box does WORKSON attach to?
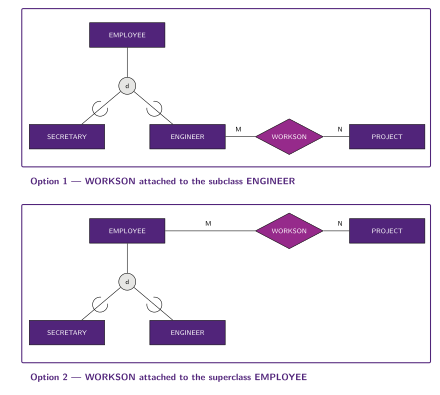
Figure 6: Subclass relationship vs. superclass relationship, reduced to the fragment where the two options differ. Option 1 attaches WORKSON to the subclass ENGINEER; Option 2 attaches it to the superclass EMPLOYEE. The rest of the company diagram (MANAGES, WORKSFOR, CONTROLS and DEPARTMENT) is the same under both options and is left out so the one difference is visible.
This is the clearest inequivalent choice of the four. Option 1 says only engineers work on projects — secretaries cannot be recorded on one at all. Option 2 says anyone may. Both satisfy a brief that only ever mentions engineers working on projects, but they enforce different things: Option 2 will happily accept a secretary on a project, and Option 1 will refuse an engineer’s promotion out of the subclass without also dropping their project assignments. Attaching a relationship higher up the hierarchy always widens what the schema will accept.
Why the choice matters after the diagram
A conceptual choice becomes a constraint the DBMS can or cannot enforce once the diagram is mapped. The clearest example is the third mistake in week4-tutorial-case-study-3-dirt-road-driving: mapping a trip’s driver as a reference to Staff rather than to Driver lets an admin-only staff member be recorded as a trip’s driver, because the schema no longer knows that a driver is a driver. The diagram-level decision about which class a relationship attaches to is the same decision as the schema-level decision about which relation the foreign key points at.
This is also why an assumption noted under a diagram is worth marks and worth memory: it’s the record of a constraint that the notation alone couldn’t distinguish. Once the schema exists, refining it further is a different exercise with different tools — see functional-dependencies and normal-forms for redundancy-driven refinement, and conceptual-database-design for where in the pipeline each one sits.
ER Diagram Notation
Reference legend for the symbols used across every ER/EER diagram in this course — introduced across 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices.
The notation below is the mandatory standard: it is what the lectures’ own notation guide specifies, and it is what assignments and the exam are marked against. (The separately published INFS1200/7900 EER & ER Notation Guide handout only standardises naming — see the style guide at the bottom of this note — and explicitly defers the symbols themselves to the lecture material.)
Core symbols
| Symbol | Meaning |
|---|---|
| Rectangle | Entity type |
| Double-line rectangle | Weak entity type (no key attribute of its own) |
| Oval | Attribute |
| Oval, name underlined | Key attribute |
| Oval, name underlined with a dotted line | Partial key attribute (weak entity’s own distinguishing attribute) |
| Double-line oval | Multivalued attribute (can hold more than one value) |
| Dashed oval, attached by a dashed line | Derived attribute (computed from another stored attribute, e.g. Age from BirthDate) |
| Diamond | Relationship type |
| Double-line diamond | Identifying relationship type (connects a weak entity to its owner entity) |
- Composite attribute: an attribute with its own sub-attributes attached (e.g.
Namesplitting intoFirstName/MiddleName/LastName) — the parent attribute oval isn’t underlined/dashed/doubled itself unless it’s also a key/derived/multivalued attribute. - Value sets (the domain of legal values for an attribute, e.g. “integers 21-65”) are never shown on the diagram itself.
Relationship constraints
| Symbol | Meaning |
|---|---|
1, N, M on the lines into a diamond |
Cardinality ratio — E1 —1— R —N— E2 reads as ratio 1:N for E1:E2 in R |
| Double line between an entity type and a diamond | Total participation of that entity type in that relationship |
| Single line | Partial participation |
See relationship-constraints for what each ratio and each participation constraint actually asserts.
Subclasses / superclasses (EER)
A subclass is drawn as an ordinary rectangle. What makes it a subclass is the ⊂ symbol on the line joining it to its superclass, not the shape of its box — a subclass box is a plain single-line rectangle, never the double-line rectangle that means weak entity. The two are entirely different ideas (a subclass inherits its superclass’s key; a weak entity has no key of its own at all) and the notation keeps them apart.
| Symbol | Meaning |
|---|---|
⊂ on the line between two entity types |
The entity type on the closed (narrow) side of the ⊂ is a subclass of the one on the open (wide) side — read it as the set-inclusion symbol, subclass ⊂ superclass |
A circle joining several subclass lines to one superclass, each line carrying its own ⊂ opening towards the circle |
Several entity types are all subclasses of the same superclass |
d inside that circle |
Disjoint specialisation — an entity instance can belong to at most one of the subclasses |
o inside that circle |
Overlapping specialisation — an entity instance can belong to more than one subclass at once |
| Single line from superclass to the subclass circle | Partial specialisation — not every superclass instance needs to belong to a subclass |
| Double line from superclass to the subclass circle | Total specialisation — every superclass instance must belong to at least one subclass |
Naming conventions (INFS1200/7900 style guide)
Course-specific naming standard for entities/relationships/attributes on ER and EER diagrams (distinct from — and in addition to — the mandatory notation above):
- Entity names: capitalised, no spaces, ideally one word (e.g.
STUDENT,POLICEOFFICER— notPoliceOfficer). - Relationship names: capitalised, no spaces, ideally one word, preferably a verb (e.g.
CREATES,ACTSIN— notLeadActor). - Attribute names: UpperCamelCase — first letter of each word capitalised, no spaces, acronym letters stay capitalised (e.g.
ComputerIP,DateOfBirth— notDate of Birth).
How diagrams are drawn in these notes
Diagrams in this course’s notes are drawn as Mermaid flowchart graphs (renders in both PDF and HTML), using shapes chosen to match the Chen notation above as closely as Mermaid’s flowchart shapes allow:
| Mermaid shape | Used for |
|---|---|
[Entity] (rectangle) |
Entity type — and subclasses, which are ordinary rectangles |
[[WeakEntity]] (subroutine, double vertical bars) |
Weak entity type, and nothing else |
{Relationship} (diamond/rhombus) |
Relationship type |
([Attribute]) (stadium) |
Attribute |
((d)) / ((o)) (small circle) |
Disjoint/overlapping specialisation marker |
The [[X]] shape is reserved for weak entity types. Drawing an EER subclass with it is a notation error, not a stylistic one: it renders the double-line box that the official notation uses for a weak entity, and so asserts the opposite of what a subclass is. Subclasses are plain [X] rectangles; their subclass-ness is carried by the edge into the ((d)) or ((o)) circle, exactly as the ⊂ carries it in the hand-drawn notation.
Since Mermaid can’t reliably underline/dash node text across renderers, attribute qualifiers are written as a plain-text suffix instead: (key), (partial key), (derived), (multi). Composite attributes are drawn as a parent attribute node connected to its component attribute nodes. Cardinality is a text label on the edge ("1", "N", "M"); total participation/identifying relationships use a thick edge (===/==>), partial participation uses a thin edge (---/-->).
Any diagram with more than ~6-8 nodes needs an explicit %%| fig-width: cell option (in inches) or it runs off the right edge of the PDF page - mermaid sizes itself from the diagram’s own SVG bounding box, and there’s no project-wide default that reaches it (a document/project fig-width only applies to executed-code-cell figures, e.g. matplotlib). 5.5 fits this vault’s PDF page width (scrartcl, DIV=11, letter) comfortably:
```{mermaid}
%%| fig-width: 5.5
flowchart TD
    ...
```
Foreign Keys
A foreign key is a set of attributes in one relation that links it to another relation’s primary key — the only mechanism the relational model has for expressing a relationship between two relations, and therefore the thing almost every mapping step in er-to-relational-mapping produces. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints; see relational-keys for keys within a relation and relational-mapping-notation for the references notation used throughout.
Definition
Let FK be a set of attributes in relation R1, and PK the primary key of relation R2. FK is a foreign key referencing PK if:
FKandPKare drawn from the same domain(s) — the names need not match, only the domains (see relational-model on why attribute names and domains are independent), and- for every tuple \(t_1\) in
R1, either \(t_1[\mathit{FK}]\) isNULL, or there exists a tuple \(t_2\) inR2with \(t_1[\mathit{FK}] = t_2[\mathit{PK}]\).
Condition 2 is the referential integrity constraint. Note what it permits: a foreign key value may be NULL (the row simply doesn’t participate), but it may never be a value that points nowhere. A dangling reference is the violation; an absent reference is not.
Department [id, name, manager]
Department.manager references Employee.id

Employee [id, name, sex, salary, department]
Employee.department references Department.id
Foreign keys can point in both directions between the same pair of relations, as here — Department.manager says who runs the department, Employee.department says who works in it. They are two separate constraints expressing two separate relationships.
An instance makes the permission concrete: Department 4 (Human Resources) has a NULL manager and employee 2034 a NULL department, and both rows are legal. An employee whose department read 5, with no department 5 in the referenced relation, would not be.
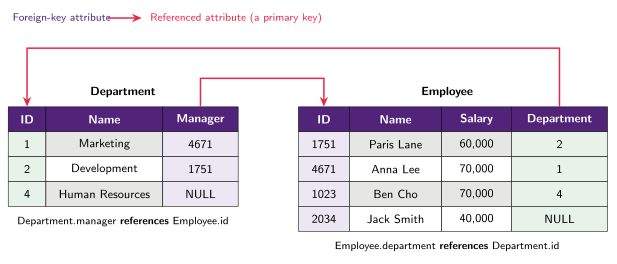
Figure 7: A two-way foreign key between Department and Employee. Each arrow starts at the foreign-key column and its head lands on the referenced primary key — the direction never varies in this course. The tinted columns pair each foreign key with the primary key it points at; the two NULLs are legal, because a foreign key may be absent but may never point nowhere.
Shapes a foreign key can take
Self-referencing
A relation can reference itself, because the two attributes involved share a domain even though they play different roles. Adding a managerId column to the same Employee relation gives one:
Employee [id, name, salary, department, managerId]
Employee.managerId references Employee.id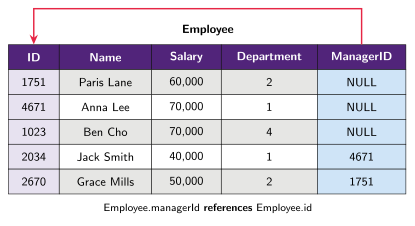
Figure 8: A self-referencing foreign key: the arrow leaves ManagerID and returns to ID in the same relation. The three top-level employees carry NULL, which is what stops the reference chain rather than a special case in the constraint.
The company schema does the same thing with different names:
Employee [ssn, fName, lName, dob, superSSN]
Employee.superSSN references Employee.ssn
This is what a recursive relationship (relationship-types — SUPERVISION: an employee supervises many employees) maps to: the N-side role, the supervisee, carries the foreign key back to the 1-side role, the supervisor. It is also what a sql-joins self-join follows back.
Composite
If the referenced primary key is composite, the foreign key must be composite too, and the whole thing is one constraint over a tuple of columns:
Student [sid, name]

Course [cid, department, manager]

Enrollment [sid, cid, department, grade]
Enrollment.sid references Student.sid
Enrollment.{cid, department} references Course.{cid, department}Course’s key is the pair (cid, department), so Enrollment must carry both columns to name one course, and its own key is all three of (sid, cid, department).
Splitting a composite foreign key into several single-column constraints is a real and commonly-marked mistake — see er-mapping-pitfalls — because it no longer forces all the columns to jointly match one referenced row.
Two foreign keys to the same relation
When a relationship uses the same entity type in two different roles, the referencing relation gets two separate foreign keys to it, given distinct column names so the roles stay readable:
PeerEvaluation [studentSid, assessmentSid, number, evaluationId, sidGrades, mark]
PeerEvaluation.studentSid references Student.sid
PeerEvaluation.sidGrades references Student.sid
PeerEvaluation.{assessmentSid, number} references Assessment.{sid, number}
studentSid is the evaluator submitting the mark; sidGrades is the student whose assessment is being marked.
Is the foreign key part of the primary key?
This is the question that decides most mapping answers, and the rule is structural rather than a matter of taste:
| Situation | Foreign key is… |
|---|---|
| 1:N relationship, FK on the N side (an entity with its own key) | A plain, non-key attribute |
| 1:1 relationship, FK on the chosen side | A plain, non-key attribute |
| Weak entity, FK to its owner | Part of the weak entity’s composite primary key |
| M:N relationship’s own relation | Part of the primary key (the pair of FKs is the key) |
| N-ary relationship’s relation, FK from a many-side participant | Part of the primary key |
| N-ary relationship’s relation, FK from a 1-side participant | A plain, non-key attribute |
| Multivalued attribute’s relation | Part of the primary key (with the value itself) |
| Subclass relation | Is the primary key — the subclass’s key is the superclass’s key |
So in Employee [ssn, …, dNumber, superSSN] the department and supervisor foreign keys are ordinary columns, whereas in Dependent [ssn, depName, …] the inherited ssn is underlined as part of the key. Treating an ordinary 1:N foreign key as key material is a standard wrong answer.
The dividing line is whether the referencing entity has a key of its own. An entity that doesn’t — the cinema Viewing, identified only by which movie, which customer and when — is being identified through its owners, so the inherited foreign keys do join its key: Viewing [name, id, date, time, attendant], keyed on all four of (name, id, date, time). That reads as weak-entity behaviour with two owners rather than as an exception to the rule, and the shape is straight out of the mapping rules: a weak entity with more than one owner takes a foreign key to each owner and is keyed on every owner key plus its partial key (step 2 of er-to-relational-mapping). Reading Viewing as a weak entity with two owners or as a strong entity whose key happens to be composite produces the same relation, so the mapping answer is the same either way.
Nulls, and when to avoid them
Because a foreign key may be NULL, embedding a 1:1 or 1:N relationship directly into an existing relation produces a null in every row that doesn’t participate. When a relationship is sparse — few of the rows actually take part — mapping it as its own relation instead (the M:N treatment) avoids all those nulls at the cost of an extra join. That trade-off is noted under step 5 of er-to-relational-mapping; see sql-nulls for what nulls then do to queries.
Enforcement
Referential integrity is declarative — the DBMS rejects any insert, update, or delete that would leave a dangling reference, with no application code involved (see integrity-constraints).
Three operations from week4-tutorial-applied-class-3-relational-integrity show the full range, and they are worth reading together because two of them look dangerous and are not:
| Operation on the company schema | Verdict |
|---|---|
Delete the EMPLOYEE tuple with ssn = 987654321 |
Violates referential integrity — tuples in WORKS_ON, DEPENDENT, DEPARTMENT and EMPLOYEE itself all reference it |
Modify EMPLOYEE.superSSN of 999887777 to 943775543 |
Violates referential integrity — no employee has that ssn; an update to a foreign key is checked exactly like an insert |
Delete the WORKS_ON tuples with essn = 333445555 |
No violation — nothing references WORKS_ON, so removing rows from it cannot dangle anything |
The last row is the shape people get wrong: whether a delete is safe depends on what points at the relation, not on how many foreign keys the relation itself carries. WORKS_ON is all foreign key and is still free to delete from. The EMPLOYEE delete is dangerous precisely because four relations, one of them EMPLOYEE itself through superSSN, point back at it.
What happens to dependent rows when a referenced row is deleted or its key updated is a policy choice attached to the foreign key itself: the violation can be rejected, cascaded, or the referencing attribute values modified to a default value. See update-operations-and-constraint-violations for those conceptual options and sql-ddl for the four named ON DELETE / ON UPDATE actions that spell them out in SQL.
Integrity Constraints
Integrity constraints are the rules that enforce the correctness of a database: conditions stated on the schema that must hold on every instance of it. A DBMS’s job is to reject any operation that would leave them unsatisfied. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and practised in week4-tutorial-applied-class-3-relational-integrity; these are constraints on a relational schema, distinct from the relationship-constraints placed on an ER diagram.
The five kinds
| Constraint | Violated when | Enforced by |
|---|---|---|
| Domain | An attribute’s value isn’t a member of its domain | The column’s declared type/format |
| Key | Two tuples share the same value for a key | The declared key |
| Entity integrity | Any part of a tuple’s primary key is NULL |
The declared primary key |
| Referential integrity | A non-null foreign key value matches no primary key value in the referenced relation | The declared foreign key |
| Semantic | A business rule that isn’t derivable from the schema’s structure is broken | Application-level rules — triggers, assertions, CHECK |
The first four are structural: they follow from the schema itself, so the DBMS enforces them for free once the types and keys are declared. The fifth is not — nothing in the schema’s shape implies it, so it has to be stated separately.
Enforcement is unconditional and the default outcome is refusal: any insert, modification or deletion submitted to the DBMS that would violate integrity — that would leave the database in an inconsistent state — must be rejected. The only constraint whose violation has other sanctioned outcomes is referential integrity on a delete, and only because the foreign key was declared with a policy saying so (see update-operations-and-constraint-violations).
Which operation can break which constraint is not symmetric, and the asymmetry is examinable:
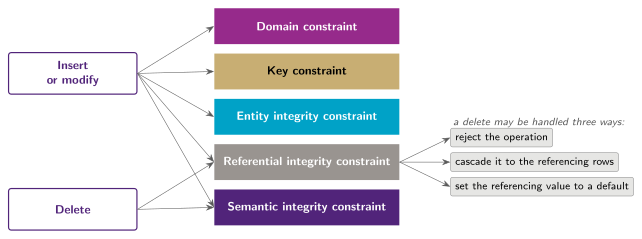
Figure 9: Insert and modify can violate all five constraints; delete can only violate the last two, and a referential violation on delete has three sanctioned outcomes rather than one. The banner colours are the course’s fixed fills for the five constraint types.
A delete cannot break a domain, key or entity-integrity constraint because it adds no value and duplicates no key — it can only strand something that was pointing at the row it removed, or break a business rule about what must continue to exist.
Domain constraint
The domain is the set of legal atomic values for an attribute (see relational-model), so a domain violation is simply a value that isn’t in that set. Employee.id = "LOL" violates it when id is a four-digit integer.
The domain need not be a plain data type — a format counts. A bank rejecting the password password123 with “your password must contain at least one capital letter and a number” is enforcing a domain constraint: the domain of password is defined as the strings matching that format, and password123 isn’t a member of it. Likewise a course code declared as four letters followed by four digits, or an enumerated domain: inserting VehiclePurpose = 'Personal' when the column is ENUM('Private', 'Business') is a domain violation, not a semantic one.
The commonest exam version of a domain violation is subtler — a value of the wrong kind in the right position. Inserting (2644, James, Smith, 1) into Employee [id, name, salary, department] breaks the domain constraint because the third value lands in salary, whose domain is integer or float, not a surname.
Key constraint
No two tuples may share a value for a key. Violated by inserting a tuple whose key duplicates an existing one, or by modifying an existing tuple into a duplicate. See relational-keys for what qualifies as a key in the first place.
Entity integrity constraint
No part of a primary key may be NULL — for a composite primary key, no component may be null, not merely “not all of them”. Inserting (677678989, null, 40.0) into WorksOn [essn, pNo, hours] violates entity integrity because pNo is half of the primary key.
The rationale is that the primary key is the relation’s identity: a tuple with an unknown key value cannot be distinguished from, or referred to by, anything. This is the one place a NULL is categorically banned — sql-nulls has the table of which declarations do and don’t permit one.
Referential integrity constraint
A non-null foreign key value must match some existing primary key value in the referenced relation. Inserting an Employee with department = 5 when no Department has id = 5 violates it; so does deleting Department 5 while employees still reference it, and so does updating a foreign key to a value that doesn’t exist. NULL is always allowed — see foreign-keys for the formal statement.
Semantic (business-rule) constraint
Semantic constraints are defined by the business or organisation during client consultation — they come from the organisation, not from the data structure:
- “An employee’s salary must not exceed their supervisor’s.”
- “The maximum number of hours an employee can work on a project is 56.”
- “A department cannot have more than three active projects at a time.”
- “A customer must be at least 18 years old.”
Take the first and third. Inserting Grace Chan on 58000 with superSSN = 888665555 — James Borg, on 55000 — violates the salary rule and nothing else; inserting a fourth project for department 5, which already has ProductX, ProductY and ProductZ, violates the three-project rule and nothing else. In both cases every structural check passes, which is exactly the signal that the answer is “semantic”.
Nothing about the relations’ shape rules these out, so they’re expressed in a constraint specification language — in SQL’s case, the mechanisms are CHECK clauses, assertions and triggers. This course files the latter two under DCL, alongside transaction control and privilege management. Only CHECK is developed and examined (see sql-ddl for the CHECK and named-constraint syntax); assertions and triggers are the general-purpose fallback and are not defined further, so “enforced by an assertion or a trigger” is as far as the course goes. This is also the category to fall back on when asking “which constraint does this break?” and none of the structural four apply.
The converse matters just as much: a rule that was never stated isn’t a constraint. Updating Department (2, Development, 1751) to (2, Development, 2034) where employee 2034 works in a different department violates nothing, unless the business rule “a manager must work in the department they manage” has actually been specified.
Naming an example of each
The other exam shape is the reverse: given a schema, point at one instance of each kind of constraint. For the enrolment schema
Student [stID, name, email]

Enrolment [stID, cCode, sem, year]
Enrolment.stID references Student.stID
Enrolment.cCode references Course.cCode

Course [cCode, title, units]
a key is stID in Student, a foreign key is stID in Enrolment, and a domain constraint is cCode being four letters followed by four digits. stID supplies both of the first two answers depending on which relation it is read in — the same attribute name is a key where it identifies and a foreign key where it refers.
Diagnosing a violation
Given an operation and a schema, work down the five in a fixed order. The order isn’t significant in itself; checking all five every time is, since one operation can break several at once.
- Domain — is every value of the right type/format for its column?
- Key — does this key value already exist?
- Entity integrity — is any part of the primary key null?
- Referential integrity — does every non-null foreign key point at a row that exists? And, for a delete, does anything still point at the row being removed?
- Semantic — does it break a stated business rule?
A single operation can violate more than one at once. Inserting ('ProductA', 'A', 'Bellaire', 2) into Project [pName, pNumber, pLocation, dNum] breaks both the domain constraint (pNumber is an integer, not 'A') and referential integrity (no department 2). Inserting ('Production', 4, 943775543, …) into Department breaks the key constraint (dNumber = 4 exists) and referential integrity (mgrSSN isn’t a real employee). Don’t stop at the first one found.
And the operations that violate nothing
Three of the applied class’s ten answers are “No”, and they are the ones worth rehearsing, because each looks like a violation and isn’t:
| Operation on the company schema | Why it is legal |
|---|---|
Insert ('Robert', 'F', 'Scott', 943775543, '1942-06-21', '2365 Newcastle Rd, Bellaire, TX', 'M', 50000, 888665555, 1) into EMPLOYEE |
Fresh ssn, every value in its domain, superSSN 888665555 and dNo 1 both exist, and 50000 is under the supervisor’s 55000 |
Delete the WORKS_ON tuples with essn = 333445555 |
Nothing references WORKS_ON, so no reference is stranded |
Modify DEPARTMENT’s mgrSSN/mgrStartDate for dNumber = 5 to 123456789 and '1988-10-01' |
123456789 is a real employee (John Smith), so the foreign key still resolves, and no other constraint touches the manager column |
Compare that last row with the case where the new manager works in a different department: it still violates nothing. A manager who works elsewhere offends intuition, not any declared constraint.
See update-operations-and-constraint-violations for which constraints each kind of operation can possibly violate, and what a DBMS does about it; sql-dml shows the same violations as the error messages MySQL actually returns.
Interpreting ER Diagrams
Drawing a diagram and reading one are different skills, and the applied classes test the second at least as hard as the first: given an ER/EER diagram and a plain-English claim about the world, decide whether the diagram actually says it. Practised in the statement-evaluation questions in week2-tutorial-applied-class-1-intro-to-dbms-and-basic-erd and week3-tutorial-applied-class-2-entity-relationship-diagrams, and in the questions in 2026-02-23-conceptual-database-design-and-the-er-model and 2026-03-02-weak-entities-the-eer-model-and-design-choices. See er-diagram-notation for what each symbol is.
The checklist
| If the claim is about… | Check | Trap |
|---|---|---|
| How many X per Y | The cardinality ratio, from the far side | Reading 1:N in the wrong direction |
| Whether every X does something | Participation (double vs single line) | Assuming total participation because the relationship exists |
| Uniqueness of an attribute | Whether that attribute is underlined | Treating a non-key attribute as if it were unique |
| “Only identifiable by…” | Whether a second key oval exists | Missing a second candidate key |
| A weak entity’s identity | Owner’s key + partial key | Treating the partial key as a full key |
| An instance being two kinds at once | d vs o on the specialisation circle |
Reading two separate circles as one |
| A relationship’s degree | Count the lines into the diamond | Calling a pair of binaries “ternary” |
| Whether a given relationship set is possible | Every cardinality ratio and every participation constraint, tuple by tuple | Checking the ratios and forgetting the double lines |
Cardinality: read it from the far side
A 1:N relationship constrains both ends, and the interesting constraint is usually the one on the “many” side. HEALTHWORKER —1:N OVERSEEN→ HEALTH means one health worker can oversee many participants, and therefore each participant has at most one overseeing health worker. “A participant can be overseen by several healthcare workers” is incorrect against that diagram — a claim that reads naturally in English and is contradicted by the diagram in the direction most people don’t check. See relationship-constraints.
An M:N relationship with no distinguishing attribute also says something: each pair appears at most once. An athlete/event pair in a plain PARTICIPATES relationship cannot be recorded twice, so “an athlete cannot participate at the same event more than once” is correct. Making repeats possible requires a distinguishing key attribute (a Timestamp, say) or a weak entity — see er-design-choices.
Participation: absence of a double line is a fact
Total participation (double line) says every instance must participate; partial participation (single line) says it need not. Both are claims, and the partial one is easy to skip over:
- The recursive
WITHrelationship onVACCINEis partial on both sides, so “each vaccine must have a second dose or a preceding dose” is incorrect — the relationship allows a two-dose program, it doesn’t require one. OVERSEENhas total participation on theHEALTHside, so “every participant in the HEALTH subclass is overseen by a health worker” is correct.- Some venues are backups and never host an event, which is exactly why
VENUE’s participation inHOSTSis partial — “all venues must host an event” is incorrect.
Keys: what isn’t underlined can repeat
If an attribute isn’t marked as a key, the diagram is asserting nothing about its uniqueness — so two different venues may share an Address when only ID is underlined. Conversely, HOTEL.Address being the key attribute is what makes “two hotels can share an address” false.
Claims of the form “X can only be identified by Y” need the whole attribute list checked, because entity types routinely have more than one candidate key: VACCINE has both ID and the composite Brand + Name, so “a vaccine can only be identified by the combination of its brand and name” is incorrect. See entity-types-and-attributes.
Weak entities: the partial key is not the key
A weak entity’s partial key is unique only within its owner, so any claim that treats it as globally unique is false. The hotel/room question is the canonical case: ROOM’s real key is (HOTEL.Address, ROOM.Number), so neither “no two rooms share a number” nor “no two hotels have rooms with the same number” holds — room numbers repeat freely across hotels, which is the entire reason ROOM is weak. The same logic makes “a BATCH is uniquely identified by only its number” incorrect, and makes an emergency contact named “Mum” registrable by two different users.
The hotel/room question is also a reminder that “none of the above” is a live option: with HOTEL.Address as the key and ROOM.Number as a partial key, every uniqueness claim on offer — two hotels sharing an address, no two rooms sharing a number, no two hotels having rooms with the same number — is false at once.
Checking a candidate relationship set
A second question format hands you a small diagram plus several candidate relationship sets written out as tables of tuples, and asks which one is possible. It is mechanical once you know the two things to check:
| Notation on the diagram | What it forbids in the table |
|---|---|
A 1 on E’s side of R |
An entity of E appearing in more than one row of R |
An N or M on E’s side of R |
Nothing — that side is unconstrained |
| A double line between E and R | An entity of E appearing in no row of R |
Worked instance. Take A —N— R —1— B —N— S ═M═ C, with entity sets {a₁, a₂}, {b₁, b₂} and {c₁, c₂}. The 1 on B’s side of R means each a may appear at most once in R; the double line on C’s side of S means every c must appear somewhere in S; M:N on S constrains nothing else. So:
R = ∅,S = ∅fails —c₁andc₂are missing fromS.R = {(a₁,b₁)},S = {(b₂,c₂)}fails —c₁is still missing.R = {(a₁,b₁), (a₁,b₂)}fails —a₁appears twice, violating the1.R = {(a₁,b₂)},S = {(b₁,c₂), (b₂,c₁), (b₁,c₁)}is possible — noarepeats and bothcs appear.
Note that an empty relationship set is perfectly legal wherever participation is partial; it is only the double line that forces rows to exist. That is the half of the check people skip.
Subclasses: d and o are per circle
An overlapping (o) specialisation permits an instance to be in several subclasses at once, so “a participant can be in both the HEALTH subclass and the AGE subclass” is correct when those two hang off an o circle. A disjoint (d) specialisation forbids it. The per-circle part matters: a superclass with two separate specialisation circles constrains each one independently, and membership in a subclass under one circle says nothing about membership under the other. See specialisation-and-generalisation.
Degree: count the lines
“EVENT has a ternary relationship” is incorrect when EVENT’s relationships are PARTICIPATES (to ATHLETE) and HOSTS (to VENUE) — two separate binary relationships, not one three-way one. An entity type participating in several relationships is not the same as participating in a high-degree relationship. See relationship-types.
Relational Keys
A key is a minimal set of attributes that uniquely identifies the tuples of a relation. Everything else in this note is a refinement of that one sentence. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints and drilled in week4-tutorial-applied-class-3-relational-integrity; see relational-mapping-notation for how keys are written down (the primary key is underlined) and foreign-keys for the cross-relation case.
Minimality is the whole point
Uniqueness alone isn’t enough — a key must also be minimal, meaning it contains no redundant attributes. Minimal does not mean “the shortest set anyone could find”: it means that removing any attribute from the set destroys the uniqueness property.
Given Department [id, name, manager] where department IDs are unique:
| Candidate set | Unique? | Minimal? | Key? |
|---|---|---|---|
(id) |
Yes | Yes | Yes |
(id, name) |
Yes | No — id alone already suffices |
No |
(id, manager) |
Yes | No — same reason | No |
Adding anything to an already-unique set keeps it unique but destroys minimality, so (id, name) is never a key while (id) is one.
Ask the same key question twice on one instance, changing only the assumptions, and the pair is the whole lesson:
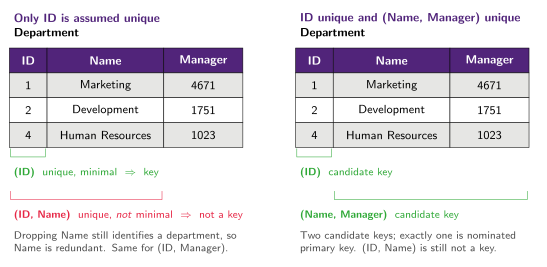
Figure 10: Two key questions on one instance. Left: only ID is assumed unique, so (ID) is the sole key and (ID, Name) fails minimality. Right: (Name, Manager) is also assumed unique, which adds a second candidate key without making (ID, Name) one.
Nothing in the data changed between the two panels — only what the question tells you to assume. Keys are a property of the schema and its stated uniqueness assumptions, never something you can read off one instance.
The vocabulary
| Term | Meaning |
|---|---|
| Superkey | Any set of attributes that uniquely identifies tuples — not necessarily minimal |
| Candidate key | A minimal superkey; a relation may have several |
| Primary key | The one candidate key chosen as the key for the relation; exactly one per relation |
| Composite key | A key made of more than one attribute |
Every key is a superkey; the reverse doesn’t hold. In the table above, (id, name) is a superkey but not a candidate key. The relational-model material works with key, candidate key and primary key only — superkey enters later, with design theory, where the formal treatment of it lives: attribute closure, and how to find all the candidate keys of a relation from its functional dependencies (see functional-dependencies and attribute-closure).
Textbook terms the course never uses are worth not importing: there is no alternate key, secondary key or surrogate key anywhere in INFS1200. A candidate key that lost the nomination is just “another candidate key” and becomes an ordinary attribute in the relational schema; an artificial identifier is just a key that was chosen. Answers should stay inside the four terms above.
Several candidate keys
If department IDs are unique and the combination of name and manager is also unique per department, then Department has two candidate keys: (id) and (name, manager). Both are minimal and both are unique; (id, name) still isn’t a key because (id) alone already suffices. Exactly one of the candidate keys is then nominated as the primary key — a design choice, not something the data dictates.
Composite keys
A key can perfectly well span several attributes. Composite primary keys turn up constantly, and mostly for structural reasons rather than arbitrary ones:
- A weak entity’s relation is keyed on its owner’s primary key plus its own partial key, e.g.
Dependent [ssn, depName, …]. - An M:N relationship’s relation is keyed on the pair of foreign keys it carries, e.g.
WorksOn [ssn, pNo, hours]. - A multivalued attribute’s relation is keyed on the owner’s key plus the value itself, e.g.
DeptLocs [dNumber, location].
All three come out of er-to-relational-mapping. In this course’s notation a composite primary key is written as one continuous underline spanning all of its attributes — one key, not several.
Common misconceptions
From the true/false drill in week4-tutorial-applied-class-3-relational-integrity:
| Statement | Verdict |
|---|---|
| A key is a unique identifier of a tuple in the relation | True — that’s the definition |
| The key constraint (or uniqueness constraint) implies that no two tuples in a relation can have the same values for all attributes | True (as the course marks it) |
| A primary key is a candidate key chosen as the main key for a relation | True |
| A key cannot have multiple attributes | False — composite keys exist |
| An entity may have more than one primary key | False — several candidate keys, but only one is the primary key |
The second row is worth pausing on, because the obvious objection is a good one: no two tuples can agree on all attributes in any relation, declared key or not, since a relation is a set. The course still marks it true, reading it as “the key constraint implies uniqueness of tuples” — so answer it the course’s way, and keep the set-semantics point as the reason the statement is weak rather than as a reason to call it false.
Matching the four terms
Matching definitions to names is a compact statement of all four:
| Definition | Term |
|---|---|
| Any minimal set of attributes that can uniquely identify tuples in a relation | Candidate key |
| A candidate key that is chosen to identify tuples in a relation | Primary key |
| Defines the structure of a relation; specified during database design | Relational schema |
| Data in a relation, modified via create, update and delete operations | Relational instance |
Worked example — electoral roll
Region [prefix, suffix]

Member [enrolmentId, passportNum, regionPrefix, regionSuffix]
Member.{regionPrefix, regionSuffix} references Region.{prefix, suffix}

Candidate [enrolmentId, name, regionPrefix, regionSuffix]
Candidate.enrolmentId references Member.enrolmentId
Candidate.{regionPrefix, regionSuffix} references Region.{prefix, suffix}- Candidate keys:
Member.enrolmentId,Member.passportNum,Candidate.enrolmentId,Region.{prefix, suffix}—Memberhas two, since a passport number identifies a member just as well as an enrolment ID does. - Primary keys:
Member.enrolmentId,Candidate.enrolmentId,Region.{prefix, suffix}— one per relation,passportNumlosing out toenrolmentIdas a design choice. - Composite primary key:
Region.{prefix, suffix}. - Foreign keys:
Member.{regionPrefix, regionSuffix},Candidate.{regionPrefix, regionSuffix},Candidate.enrolmentId— note the last one is simultaneouslyCandidate’s primary key and a foreign key, which is exactly what a subclass relation looks like.
What keys enforce
Two of the five integrity-constraints exist to protect keys:
- The key constraint — no two tuples may share a value for a key. Violated by inserting or modifying a tuple so that it duplicates an existing key value.
- The entity integrity constraint — no part of a primary key may be
NULL. For a composite primary key this means every component must be non-null; a single null component is already a violation.
Both are declarative: the DBMS enforces them automatically once the key is declared, without any application code (see sql-ddl for the PRIMARY KEY / UNIQUE syntax that declares them).
Relational Mapping Notation
Reference legend + course style guide for writing relational schemas — introduced across 2026-03-09-the-relational-model-and-integrity-constraints and 2026-03-16-er-to-relational-mapping. These notations are specific to INFS1200/7900 and may differ from textbooks and online resources, so they are what to follow in an assignment or exam. The guide covers naming and layout only: it recommends nothing about which relations to produce. The mapping steps themselves are in er-to-relational-mapping.
Schema notation
Relation [attr1, attr2, ...]— a relation schema; the (primary) key attribute(s) are underlined.- A composite primary key gets a single continuous underline spanning all of its attributes, e.g.
Enrolment [studentId, courseCode, sem, year]. Relation.fk references OtherRelation.pk— a foreign key constraint, listed directly under the relation it belongs to.Relation.{fk1, fk2} references OtherRelation.{pk1, pk2}— a composite foreign key referencing a composite primary key.
Naming convention (INFS1200/7900 style guide)
- Table names: UpperCamelCase (first letter of each word capitalised, no spaces) — e.g.
Flight, notFLIGHT. - Attribute names: lowerCamelCase (first letter of each word from the second word onwards capitalised) — e.g.
departureTime, notDeparture Time. Acronym attribute names stay entirely lowercase (e.g.eta, notETA). - A space separates the table name from the opening bracket:
Flight [planeNumber, ...], notFlight[planeNumber, ...].
The guide’s compliant and non-compliant pair puts every rule in one line each:
Flight [planeNumber, departureTime, duration, eta]     ✓

FLIGHT[planeNumber, departure time, Duration, ETA]     ✗
The second breaks five rules at once — shouted table name, no space before the bracket, a space inside an attribute name, a capitalised attribute, and an upper-case acronym.
Layout convention
A table’s foreign key constraint lines go directly underneath that table’s own definition, with a blank line before the next table starts — not all grouped together under a separate “Foreign Keys:” heading at the end:
Employee [ssn, firstName, lastName, dob, manager]
Employee.manager references Employee.ssn

Dependant [ssn, name, dob]
Dependant.ssn references Employee.ssn

DependantPhoneNumber [ssn, name, phoneNumber]
DependantPhoneNumber.{ssn, name} references Dependant.{ssn, name}
The Relational Model
The data model underlying almost every commercial DBMS, introduced by E.F. Codd in 1970: a sound theoretical foundation built on set theory, with a single simple, uniform data structure called a relation. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints; see relational-mapping-notation for how schemas are written down in this course, and er-to-relational-mapping for how a conceptual ER design becomes one.
The four basic concepts
| Concept | Definition |
|---|---|
| Domain | A set of atomic values, with a data type/format |
| Attribute | The name of a role played by some domain in a relation |
| Tuple | An ordered list of values, one per attribute |
| Relation | A set of tuples — informally, a table of rows and columns |
All four are visible at once in the anatomy figure, which is worth reading before the definitions below:
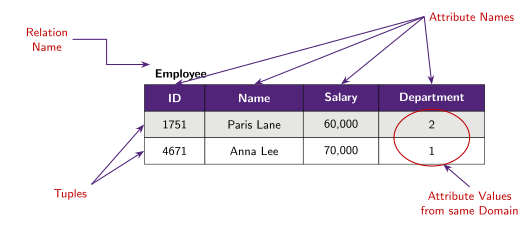
Figure 11: The four components of a relation, on an annotated Employee table. The relation name sits above the table; the attribute names are the header row; each body row is a tuple; and every value down one column — here Department — is drawn from that attribute’s single domain.
Domains
A domain \(D\) is a set of atomic values — atomic meaning indivisible as far as the relational model is concerned. Each domain carries a data type or format: integers, numbers/currency, fixed- or variable-length character strings, dates/timestamps, a sub-range of a data type (e.g. \(1 \le \text{grade} \le 7\)), or an enumerated type (e.g. \(\text{Gender} \in \{\text{Male}, \text{Female}, \text{Other}\}\)). Format-constrained domains count too — an Australian phone number (61 + 9 digits), or a car registration (6 alphanumeric characters, no Q).
The domain is what makes a value legal or illegal, which is why the domain constraint is the first of the five integrity-constraints: a value that isn’t a member of its attribute’s domain simply cannot be stored.
Attributes
Each attribute \(A\) names a role that some domain plays in a relation \(R\). Name and domain are independent in both directions:
- Same-named attributes in different relations need not share a domain —
Department.idandEmployee.idcan be drawn from entirely different domains despite the shared nameid. - Differently-named attributes can share a domain —
Employee.idandEmployee.managerIdare both drawn from the same “employee id” domain, which is precisely what makes a self-referencing foreign key possible (see foreign-keys).
The number of attributes in \(R\) is its degree — Employee [id, name, sex, salary, department] is of degree 5, and “degree of the relation” and “degree of the relation schema” are used interchangeably for the \(n\) in R [A1, …, An]. Degree is the only size measure Module 2 names. Unqualified “cardinality” in this course almost always means a relationship’s cardinality ratio on an ER diagram (relationship-constraints) or the “many cardinality” side of a relationship in the mapping rules; a relation’s row count only acquires a notation later, when Module 3 writes it as \(|R|\) to size a Cartesian product (\(|R_1 \times R_2| = m \cdot n\)) — see infs1200-diagram-notation.
Tuples
Each tuple \(t\) is an ordered list of \(n\) values \(t = \langle v_1, v_2, \ldots, v_n \rangle\), where each \(v_i\) either belongs to the domain of the corresponding attribute or is the special value NULL. A tuple with \(n\) values is an \(n\)-tuple.
Relation schema vs relation instance
The single most-tested distinction in this part of the course — the schema is metadata, the instance is data.
| Relation schema | Relation instance | |
|---|---|---|
| Written | R [A1, A2, …, An] |
r(R) = {t1, t2, …, tm} |
| Is | The relation’s name and attribute list | The actual set of tuples, at one point in time |
| Also called | Metadata — “data describing the data” | The data in the database |
| Comes from | Database design | Insert/update/delete operations |
| Changes | Rarely (a design decision) | Constantly |
Employee [id, name, sex, salary, department] is a schema of degree 5; the rows currently sitting in that table are its instance. Because the schema is fixed at design time and the instance changes with every update, an integrity constraint is a property of the schema that must hold on every instance of it.
Properties of relations
A relation is a mathematical set of tuples, and the consequences of that are what separate a relation from an arbitrary table.
- Tuple order is irrelevant. A set has no implied order. Two instances holding the same tuples in a different sequence are the same relation. Physically, tuples do sit in some order on blocks of secondary storage, but nothing semantic (queries included) may depend on it.
- Value order is a syntactic convention only. An \(n\)-tuple is syntactically an ordered list, so every tuple in one relation must list its values in the same attribute order — but which order is chosen carries no meaning, as long as the attribute-to-value correspondence is maintained consistently.
- Values are atomic. Each cell holds one indivisible value from its domain (or
NULL) — no repeating groups and no nested structure, which is why a multivalued attribute has to become a relation of its own during mapping. - Every relation is a table; not every table is a relation. A “pivoted” presentation table — a quarterly sales report with merged header cells, broken down by region and suburb — is a perfectly good table and not a valid relation at all. The word table is used interchangeably with relation in practice, but only relations obey the properties above.
One caveat for later: SQL does not enforce the set property. A SELECT returns a bag, duplicates and all, unless you ask for DISTINCT — see sql-select-statement. The properties above describe the model, not what a query result happens to look like.
Where the relational model sits
The relational model is the logical layer: what a DBMS actually implements, and the target of the mapping algorithm in er-to-relational-mapping (which is also where the conceptual/logical split is spelled out). The relational model is the middle box below: still a description of what is stored, not of how the bytes sit on disk (dbms-fundamentals has the three-schema architecture the right-hand column belongs to).
Figure 12: Where the relational model sits. Two design steps (gold) turn requirements into two schemas: conceptual design produces an ER schema, logical design — the mapping — produces a relational one. The green notes say what each model is for: the ER model is what conceptual design is done in, the relational model is what commercial DBMSs implement.
What that algorithm emits is relations plus their primary and foreign key constraints — from there, sql-ddl turns the schema into real CREATE TABLE statements, and normalisation (functional-dependencies, normal-forms) checks that the resulting relations are well-designed.
Relationship Constraints
Constraints on a relationship type limit the possible combinations of entities that may participate in its relationship set — determined by the Universe of Discourse (UoD), not chosen arbitrarily. There are exactly two kinds, cardinality constraints and participation constraints. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model; see er-diagram-notation for the full symbol legend.
Cardinality ratio
A cardinality ratio for a relationship set specifies the number of relationships in the set that an entity can participate in. The intuition is a customer buying items: one particular customer can purchase many different items, however an individual item — this particular cake — cannot be purchased by several different customers.
| Ratio | Name | Meaning |
|---|---|---|
| 1:1 | One-to-one | Both entities can participate in only one relationship instance |
| N:1 | Many-to-one | One entity can participate in many relationship instances, the other in only one |
| 1:N | One-to-many | The same constraint, viewed from the other side |
| M:N | Many-to-many | Both entities can participate in many different relationship instances |
Three worked readings, all on the same two entity types, are worth memorising as a set because the English is nearly identical each time and only the ratio changes:
| Statement of the UoD | Ratio |
|---|---|
| “Each employee can work on any number of projects, and each project can have any number of employees working on it” | EMPLOYEE —N— WORKSON —M— PROJECT (M:N) |
| “Each department can have any number of employees, but an employee can work for at most one department” | EMPLOYEE —N— WORKSFOR —1— DEPARTMENT (N:1) |
| “Each department can have at most one manager and each employee can manage at most one department” | EMPLOYEE —1— MANAGES —1— DEPARTMENT (1:1) |
Note where the N sits in the second row: on the EMPLOYEE side, because it is employees that are many. Reading the label on the wrong end is the standard error — see interpreting-er-diagrams.
Participation constraint (existence dependency)
The course’s own name for the participation constraint is existence dependency: it indicates whether the existence of an entity depends on its relationship to another entity — i.e. whether every instance of the entity type must participate in at least one relationship instance.
- Total participation (double line in the diagram) — every entity instance must participate. “Every employee must work for a department” makes
EMPLOYEEtotally participate inWORKSFOR, and the phrasing to use is thatEMPLOYEEis existentially dependent onDEPARTMENTvia theWORKSFORrelationship type. - Partial participation (single line) — an entity instance is not required to participate. “Every employee can manage 0 or more departments” makes
EMPLOYEE’s participation inMANAGESpartial.
The two ends are constrained independently, and MANAGES is the example that shows it: EMPLOYEE participates partially (most employees manage nothing) while DEPARTMENT participates totally (every department must have a manager), so DEPARTMENT is existentially dependent on EMPLOYEE via MANAGES and not the other way round.
Why the participation constraint is worth getting right
It is not just documentation: it decides where a foreign key ends up. The Module 2 mapping rule for a binary 1:1 relationship says to pick one of the two participating entity types and give it the foreign key, and that preference is given to entity types with total participation. MANAGES is exactly that case — because DEPARTMENT totally participates, the mapping extends Department with mgrSSN (plus the relationship’s own startDate, renamed mgrStartDate) rather than putting a department reference in Employee, which would be null for almost every employee. The mirror-image answer fails for precisely this reason: given S ═1═ R ─1─ T, putting the foreign key in T is wrong, because S has full participation and is preferred over T. See er-to-relational-mapping for the rule in full.
Weak entities
An entity type with no key attribute of its own is a weak entity — it can be identified uniquely only by considering the primary key of another owner entity together with its own partial key (underlined with a dotted line). The relationship type that relates a weak entity to its owner is the identifying relationship, and the weak entity always has total participation in it: it cannot exist without its owner. Both the weak entity box and the identifying relationship diamond are drawn with double lines.
An example is an EMPLOYEE (key SSN) who INSURES a DEPENDANT (partial key Pname, plus Age), 1:N, with Cost as a descriptive attribute on the identifying relationship. Two different employees can each insure a dependant named John, which is precisely why Pname cannot be a key on its own — the identity of a dependant is (SSN, Pname).
Provinces and cities have the same shape, and it is the compact example to memorise because all three notations — cardinality, participation and partial key — are on it at once:
Figure 13: A weak entity in full notation. CITY is weak (double box) with the partial key name (dash-underlined); IN is the identifying relationship (double diamond); the CITY–IN edge is doubled for CITY’s total participation, and the ratio is 1:N, so one province holds many cities. PROVINCE’s own name is a full key (solid underline). Entity boxes are purple, relationship diamonds magenta and attribute ovals grey.
The two names do different jobs. PROVINCE.name identifies a province outright; CITY.name identifies a city only within a province, so the mapped Cities relation needs a pName column as part of its primary key and as a foreign key to Provinces — the mapping is Cities [cName, pName, mayor] with Cities.pName references Provinces.pName, and the wrong mappings are the ones that drop pName from the key, make cName a foreign key, or turn the identifying relationship IN into a relation of its own. See er-to-relational-mapping for the mapping rule that produces this.
A weak entity can have two (or more) owner entity types, in which case the identifying relationship is n-ary rather than binary. The generic version shows how the constraints are placed in that case — many weak entities per combination of owners, one owner of each kind per weak entity:
Figure 14: A weak entity with two owner entity types. The identifying relationship R is ternary: N on the weak side, 1 towards each owner, with the double edge marking W‘s total participation. W’s identity is its partial key a1 plus both owners’ keys, which is why the mapped relation is W [a1, b1, c1] with b1 and c1 as foreign keys.
INTERVIEW is the worked case: it is owned by both CANDIDATE and COMPANY, so the identifying relationship APPLIES is ternary, and INTERVIEW’s composite partial key Details (Department, Date) only distinguishes interviews within one candidate/company pair. INTERVIEW is a full entity type despite being weak, so it can carry relationships of its own — it RESULTSIN a JOB OFFER. See er-design-choices for the decision that produced it and interpreting-er-diagrams for the claims it makes false.
Relationship Types
The other half of an ER diagram: the associations between entity types. Introduced in 2026-02-23-conceptual-database-design-and-the-er-model and practised in week3-tutorial-applied-class-2-entity-relationship-diagrams; see er-diagram-notation for the symbols and entity-types-and-attributes for what sits at each end.
Relationship, relationship type, relationship set
The same schema/instance split as entity types:
| Term | Meaning |
|---|---|
| Relationship | An association among two or more entities — “Paris Lane works on the project FileZilla” |
| Relationship type | The definition of that association, drawn as a diamond connected to the participating entity types |
| Relationship set | The collection of all relationships of one relationship type in the database at any point in time |
A relationship set can be drawn as lines between two ovals of entities, or written out as a table of pairs — WORKSON as rows (e1, p1), (e2, p1), (e2, p4), and so on. The tabular form is the one exam questions use when they ask whether a given relationship set is possible under a diagram’s constraints; see interpreting-er-diagrams.
A relationship type may carry its own descriptive attributes, which belong to the pairing rather than to either entity on its own — EMPLOYEE WORKSON PROJECT hangs StartDate and EndDate off the diamond, because a start date belongs to one employee’s stint on one project and to nothing else. A Grade belongs to the enrolment of one student in one course, not to the student and not to the course. Other examples across the notes: a Placement on PARTICIPATES (athlete/event), a Fee on CONSULTS (patient/doctor), a PrepTime on BUYS (customer/bubble tea).
A relationship type may also carry key attributes of its own — on WORKSON it is StartDate that is underlined, which says one employee cannot start on the same project twice on the same day. The Timestamp that distinguishes repeat orders on BUYS does the same job.
Degree
The degree of a relationship type is the number of participating entity types:
| Degree | Name | Example |
|---|---|---|
| 2 | Binary | DEPARTMENT WORKSFOR EMPLOYEE |
| 3 | Ternary | SUPPLIER / PROJECT / PART in one SUPPLIES diamond |
| \(n\) | n-ary | The general case, 3+ entity types |
Degree is decided by counting the lines into the diamond, and it is a real design decision rather than a description — the same UoD can often be modelled as one ternary relationship or as three binary ones, with different consequences. See er-design-choices.
Roles
Each entity type that participates in a relationship type plays a particular role in it. The role name signifies the role a participating entity from that entity type plays in each relationship instance — that is to say, it explains what the relationship means. DEPARTMENT is the Employer and EMPLOYEE is the Worker in WORKSFOR, the relationship between those two entity types. WORKSON is a different relationship: the M:N EMPLOYEE/PROJECT one (relationship-constraints, er-to-relational-mapping).
Roles are optional labelling on an ordinary binary relationship between two different entity types, where the meaning is usually obvious from the names — but they become mandatory in the recursive case below, where they’re the only thing distinguishing the two ends.
Recursive relationships
The same entity type can participate more than once in one relationship type, under different roles — an EMPLOYEE who MANAGES another EMPLOYEE. Both lines run from the same rectangle back to the same diamond, so the role labels carry all of the meaning:
flowchart LR
    EMPLOYEE[EMPLOYEE] ---|"1 Manager"| MANAGES{MANAGES}
    MANAGES ---|"N Subordinate"| EMPLOYEE
Two different relationships share the name MANAGES, and they are not the same thing: this recursive EMPLOYEE/EMPLOYEE one, and the 1:1 EMPLOYEE/DEPARTMENT one that records who runs each department (relationship-constraints, and the mgrSSN foreign key in er-to-relational-mapping). The recursive relationship is also named SUPERVISION in the company diagram used for mapping, and that is the name used for it elsewhere in these notes.
Recursive relationships turn up constantly once you start looking, and they take every cardinality:
| Relationship | Roles | Ratio |
|---|---|---|
EMPLOYEE SUPERVISION EMPLOYEE |
supervisor / supervisee | 1:N |
COURSE PREREQUISITE COURSE |
higher / requires | M:N |
CUSTOMER FRIENDS CUSTOMER |
Requestor / Requestee | M:N |
VACCINE WITH VACCINE |
First / Second | partial on both sides |
NON-WIN SEQUEL NON-WIN |
PrequelTo / SequelTo | 1:1 |
The WITH example from week3-tutorial-applied-class-2-entity-relationship-diagrams is the instructive one: because participation is partial on both sides, the relationship records that a vaccine may be part of a two-dose program — it does not assert that every vaccine has a second dose. Reading a recursive relationship as if it were total is a standard trap.
Constraints
Cardinality ratio (1:1, 1:N, M:N) and participation (total/partial) are covered in relationship-constraints; how to read a claim off them without tripping over the direction is covered in interpreting-er-diagrams.
What happens to a relationship on mapping
The relationship type’s cardinality decides its fate in the relational schema. An M:N relationship becomes its own relation, combining both sides’ foreign keys into one composite primary key (relational-keys), plus any descriptive attributes it carried — UserRatesDriver [userID, driverID, rating] in week4-tutorial-case-study-3-dirt-road-driving. A 1:N relationship doesn’t need a relation of its own; it shows up as a foreign key on the N side, the way EmergencyContact.userID carries the User/EmergencyContact link in the same schema. The full set of rules is in er-to-relational-mapping.
SQL Data Definition Language (DDL)
DDL is the subset of SQL that defines and changes the database schema — CREATE, ALTER, DROP — as opposed to the data held in it. It is where the relational schema produced by er-to-relational-mapping (written in relational-mapping-notation) becomes a real set of tables, and where the integrity constraints of the relational model are actually declared and enforced. Introduced in 2026-03-30-basic-sql-ddl-and-dml; practised in week6-tutorial-applied-class-5-basic-sql-ddl-and-dml and week6-tutorial-case-study-4-easydrive-insurance.
Where DDL sits among SQL statement types
| Family | Purpose | Statements |
|---|---|---|
| DDL (Data Definition Language) | Define/change the schema | CREATE, ALTER, DROP |
| DML (Data Manipulation Language) | Manipulate data | INSERT, UPDATE, DELETE, SELECT |
| DCL (Data Control Language) | Transaction control, semantic integrity (triggers/assertions), authorisation and privileges, role-based security, physical storage parameters | GRANT / REVOKE, see database-access-control |
See sql-dml for the data-modification statements and sql-select-statement for querying.
Syntax notation used in this course
Statement templates throughout Module 3 are written with a fixed convention:
| Written | Means |
|---|---|
KEYWORD |
A literal SQL keyword |
<argument> |
A name or value you supply |
[optional] |
May be omitted |
{multiple} |
May be repeated |
…\|..choice..\|… |
Pick exactly one of the alternatives |
CREATE TABLE
CREATE TABLE <table name>
   (<column name> <column type> [<attribute constraint>]
   {, <column name> <column type> [<attribute constraint>]}
   [<table constraint> {, <table constraint>}])
Domain constraints are specified per attribute; key, entity and referential integrity constraints are specified after all the attributes are declared.
An attribute’s data type can be given directly on the column, or by declaring a named domain with CREATE DOMAIN and using that instead. The course names CREATE DOMAIN as the alternative but never gives its syntax or an example, so the only form actually examinable here is the direct one — a type (and optionally a CHECK) written on the column.
An entity table — Item [itemID, category, colour]:
CREATE TABLE Item (
    itemID   INTEGER,
    category ENUM('food', 'clothing', 'furniture'),
    colour   CHAR(3),
    PRIMARY KEY (itemID));
A relationship table — Sale [itemID, custID, timestamp, price, salesPerson], a ternary-degree relation between Item, Customer and Employee, whose primary key is composite and whose foreign keys carry the relationship:
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    FOREIGN KEY (itemID) REFERENCES Item(itemID),
    FOREIGN KEY (custID) REFERENCES Customer(custID),
    FOREIGN KEY (salesPerson) REFERENCES Employee(ssn));
Column types used in this course
| Type | Used for |
|---|---|
INTEGER / INT |
Whole numbers (IDs, counts, years) |
CHAR(n) |
Fixed-length strings — e.g. a 64-character access token, a 9-character SSN |
VARCHAR(n) |
Variable-length strings up to n characters |
ENUM('a', 'b', …) |
A domain restricted to a fixed list of literal values |
DECIMAL(p, s) / DOUBLE(p, s) |
Fixed-precision numbers — e.g. DECIMAL(10, 2) for money |
DATE |
A calendar date |
DATETIME / TIMESTAMP |
A date and time |
AUTO_INCREMENT (MySQL) on an integer column makes the DBMS generate successive key values, e.g. ClaimID INT AUTO_INCREMENT.
Choosing ENUM (or a CHECK) over a plain string is what turns “should only ever be 'Private' or 'Business'” into a constraint the DBMS enforces — inserting 'Personal' then fails with a domain violation rather than silently storing bad data.
Declaring constraints
Constraints are rules limiting what data can go into a table. See integrity-constraints for what each one means in the relational model, and relational-keys/foreign-keys for the key concepts they enforce; this is how each is written in SQL:
| Constraint | Meaning |
|---|---|
PRIMARY KEY |
Value is unique and not null |
FOREIGN KEY … REFERENCES |
Value must exist in the referenced (parent) table |
UNIQUE |
Value is unique or null — unlike a primary key |
CHECK |
Value(s) must satisfy a condition |
NOT NULL |
Value must be supplied |
A table may declare only one PRIMARY KEY clause, but any number of UNIQUE clauses — so “id is the key, but {firstName, lastName} must also be unique” is a primary key plus a separate UNIQUE over the pair, not two primary keys:
CREATE TABLE Student (
    id        INT NOT NULL,
    firstName VARCHAR(50),
    lastName  VARCHAR(50),
    PRIMARY KEY (id),
    UNIQUE (firstName, lastName));
CHECK constraints are semantic constraints over a single table, evaluated whenever tuples are inserted or modified:
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    FOREIGN KEY (itemID) REFERENCES Item(itemID),
    FOREIGN KEY (custID) REFERENCES Customer(custID),
    FOREIGN KEY (salesPerson) REFERENCES Employee(ssn),
    CHECK (price >= 8.50 AND price < 150000));
Naming constraints
Prefixing a constraint with CONSTRAINT <name> has two benefits: error messages name the violated constraint, and the constraint can later be modified or removed by name.
CREATE TABLE Item (
    itemID   INTEGER,
    category ENUM('food', 'clothing', 'furniture'),
    colour   CHAR(3),
    CONSTRAINT item_pk PRIMARY KEY (itemID));

ALTER TABLE Item DROP CONSTRAINT item_pk;
An unnamed constraint can’t be dropped later — so name anything you may plausibly want to evolve.
Referential actions (ON DELETE / ON UPDATE)
Deleting a row other rows point at would leave those rows orphaned. The referential action attached to a FOREIGN KEY clause decides what happens instead:
| Action | Effect |
|---|---|
ON DELETE RESTRICT (default) |
Disallows the deletion |
ON DELETE CASCADE |
Deletes the dependent rows too |
ON DELETE SET NULL |
Breaks the link, but doesn’t delete other rows |
ON DELETE SET DEFAULT |
Uses a predefined fallback value |
These are the SQL spelling of the reject/cascade/set-null policies in update-operations-and-constraint-violations.
The same four options apply to updates, written ON UPDATE …. The difference is only in what fires them: ON DELETE responds to the referenced row being deleted, ON UPDATE to its referenced key value being changed. So on an update, RESTRICT refuses to change the parent’s key while children still point at the old value, CASCADE rewrites the children’s foreign key to the new value, SET NULL clears it, and SET DEFAULT substitutes the column’s default. RESTRICT on delete with CASCADE on update is the common pairing, and the one the course’s worked schema uses throughout — a key that is renumbered should carry its dependants along, while a parent that is removed should not silently destroy them.
CREATE TABLE Sale (
    itemID      INTEGER,
    custID      INTEGER,
    timestamp   TIMESTAMP,
    price       DOUBLE(8, 2),
    salesPerson CHAR(9),
    PRIMARY KEY (itemID, custID, timestamp),
    CONSTRAINT itemID_fk FOREIGN KEY (itemID) REFERENCES Item(itemID)
        ON DELETE RESTRICT ON UPDATE CASCADE,
    CONSTRAINT custID_fk FOREIGN KEY (custID) REFERENCES Customer(custID)
        ON DELETE RESTRICT ON UPDATE CASCADE,
    CONSTRAINT ssn_fk FOREIGN KEY (salesPerson) REFERENCES Employee(ssn)
        ON DELETE RESTRICT ON UPDATE CASCADE);
Direction matters, and only one direction exists. The action fires in the direction the foreign key points: from the referenced (parent) table to the referencing (child) table. Given
CREATE TABLE ParkingPermit (
    pID     INTEGER,
    staffID INTEGER,
    PRIMARY KEY (pID),
    FOREIGN KEY (staffID) REFERENCES Staff(staffID) ON DELETE CASCADE);
deleting a Staff row cascades into ParkingPermit; deleting a ParkingPermit row has no defined effect on Staff whatsoever.
Choosing between the actions is a design decision about what the data should mean. For Student.advisorID references Professor.professorID, ON DELETE SET NULL says “a professor can leave without their students’ records being destroyed — they simply have no advisor for now”; RESTRICT would instead block the professor’s deletion until every advisee is reassigned, and CASCADE would delete the students.
ALTER TABLE
ALTER TABLE <table name>
    ADD <column name> <column type> [<attribute constraint>]
        {, <column name> <column type> [<attribute constraint>]}
  | DROP <column name> [CASCADE]
  | MODIFY <column name> <column-options>
  | ADD <constraint name> <constraint-options>
  | DROP <constraint name> [CASCADE];
ALTER TABLE is the schema-evolution statement: add or drop columns, change a column definition, add or drop constraints. A constraint cannot be altered in place — drop it and re-add it (exact syntax varies between commercial products).
-- Add an attribute (existing rows get NULL, so NOT NULL can't be used)
ALTER TABLE Employee ADD job VARCHAR(12);

-- Drop an attribute (CASCADE if other tables' FKs reference it)
ALTER TABLE Employee DROP address;

-- Add named constraints after the fact
ALTER TABLE Sale ADD CONSTRAINT ChkAge CHECK (price BETWEEN 10 AND 10000);
ALTER TABLE Customer ADD CONSTRAINT UniqueEmail UNIQUE (Email);
ALTER TABLE Customer ADD CONSTRAINT AgeOver CHECK (
    TIMESTAMPDIFF(YEAR, DateOfBirth, CURDATE()) >= 18);

-- Drop a constraint (must have been named)
ALTER TABLE Sale DROP CONSTRAINT itemID_fk;
The NOT NULL restriction on a newly added column is worth remembering — see sql-nulls.
DROP TABLE
DROP TABLE <table name> [CASCADE];Dropping a table drops every constraint defined on it — including constraints in other tables that reference it — deletes all its tuples, and removes the table definition from the system catalog. RESTRICT refuses the drop while dependent objects (e.g. views) still exist; CASCADE drops them too (see sql-views).
Cyclical foreign key dependencies
Department.mgrSSN → Employee.ssn and Employee.dNum → Department.dNumber reference each other, so neither table can be created with its foreign keys in place — the other table doesn’t exist yet. The fix is to defer the constraints:
CREATE Department (without FKs)
CREATE Employee (without FKs)
INSERT data into Department
INSERT data into Employee
ALTER TABLE Department ADD FOREIGN KEY (mgrSSN) REFERENCES Employee(ssn)
ALTER TABLE Employee ADD FOREIGN KEY (dNum) REFERENCES Department(dNumber)
The insertions sit between the CREATEs and the ALTERs for a reason: with both foreign keys already in place, whichever table you populated first would be referencing rows that don’t exist yet.
NULLs in SQL
NULL is the special value a relational attribute takes when there is no ordinary value to store — it represents an inapplicable, unknown or missing value rather than zero or the empty string. Because a null is not a value in the attribute’s domain, it needs its own handling everywhere it appears: in constraints, in WHERE conditions, and in the results a query produces. Defined in 2026-02-23-conceptual-database-design-and-the-er-model, constrained in 2026-03-09-the-relational-model-and-integrity-constraints, and handled in SQL from 2026-03-30-basic-sql-ddl-and-dml onwards.
Which constraints permit a null
| Declaration | Nulls allowed? |
|---|---|
PRIMARY KEY |
No — a primary key value is unique and not null; for a composite key, no part of it may be null (entity integrity) |
FOREIGN KEY |
Yes — a foreign key value must either be null, or match an existing row of the referenced relation (referential integrity) |
UNIQUE |
Yes — the value must be unique or null; this is the one difference from a primary key |
NOT NULL |
No — a value must be supplied |
See integrity-constraints for the underlying entity and referential integrity rules, relational-keys and foreign-keys for what the keys themselves are, and sql-ddl for how each is declared.
The nullable foreign key is what makes several mappings work at all: an employee with no manager, or a department with no manager assigned yet, is represented by a null foreign key rather than by a missing row. It is also why er-to-relational-mapping prefers to hang a 1:1 foreign key off the total-participation side — the other side would be null for almost every row.
Testing for a null
NULL is tested with IS, never with =. IS sits alongside LIKE, IN and BETWEEN in the course’s catalogue of things a WHERE search condition may contain (sql-select-statement):
SELECT * FROM Employee WHERE dNum IS NULL;
SELECT * FROM Employee WHERE dNum IS NOT NULL;
This shows up inside subqueries as well as at the top level — here, restricting the result to employees whose department currently has a manager assigned:
SELECT name, dNum
FROM   Employee e
WHERE  EXISTS (
    SELECT * FROM Department d
    WHERE  d.dNumber = e.dNum AND d.mgrSSN IS NOT NULL
);
An explicit IS NOT NULL is also the usual guard before grouping or building a derived value out of several columns, so that rows with missing components are excluded rather than silently contributing:
-- Last names shared by more than one employee, ignoring unknown names
SELECT   DISTINCT LastName FROM Employee
WHERE    LastName IS NOT NULL
GROUP BY LastName
HAVING   COUNT(FirstName) > 1;

-- Build FirstName-LastName-yyyy only where all three parts exist
SELECT CONCAT(FirstName, '-', LastName, '-', YEAR(DOB))
FROM   Employee
WHERE  FirstName IS NOT NULL
  AND  LastName  IS NOT NULL
  AND  DOB       IS NOT NULL;
The limits of what the course specifies
Module 3 treats nulls operationally rather than logically. It gives the IS operator, the constraint rules above, and the places a null can come from — and it stops there. The lectures do not develop a three-valued logic of TRUE/FALSE/UNKNOWN, do not state how an aggregate function treats the nulls inside a group, and do not cover what happens when a NOT IN subquery returns a null among its values. Those questions are simply not settled by the material, so don’t reason from a rule the course never gave you.
What the course does teach is the defensive habit: write the IS NOT NULL guard explicitly wherever a null could reach a comparison, a grouping, or a derived value, rather than relying on the DBMS to do something sensible with it. Every example above follows that habit.
Where nulls come from
Not every null is data someone failed to enter — several are created by the schema or the query itself:
| Source | Why |
|---|---|
| A genuinely inapplicable/unknown/missing value | The original meaning of a null |
ALTER TABLE … ADD <column> |
Every existing row gets a null in the new column — which is exactly why the new column cannot be declared NOT NULL (sql-ddl) |
ON DELETE SET NULL |
The referential action deliberately clears the link instead of deleting the dependent rows (update-operations-and-constraint-violations) |
| An outer join | Unmatched rows are padded with nulls in the columns of the table that had no match (sql-joins) |
| Access-control masking | A cell above a user’s clearance is presented to them as null rather than withheld (database-access-control) |
The last two matter when reading results: a null in the output of a LEFT JOIN means “no matching row existed”, which is information about the relationship, not about the row’s stored data.
-- Departments with no manager still appear, with NULL for the name
SELECT    D.dName, E.name
FROM      Department AS D
LEFT JOIN Employee AS E ON D.mgrSSN = E.ssn;
Nulls as a design smell
A schema that produces many nulls is usually telling you something. Reducing the number of null values in tuples is guideline 3 of the informal design guidelines behind normalisation (update-anomalies) — an attribute that is null for most rows of a relation often belongs in a separate relation instead. See 2026-04-27-database-design-guidelines-and-functional-dependencies and normal-forms.
Update Operations and Constraint Violations
There are three update operations on a relational database — insert, delete, and modify — and each can break a different subset of the integrity-constraints. Knowing which subset turns “does this operation violate anything?” from a search into a checklist. Introduced in 2026-03-09-the-relational-model-and-integrity-constraints, drilled across week4-tutorial-applied-class-3-relational-integrity and week6-tutorial-case-study-4-easydrive-insurance. This is the model-level account; sql-dml is the same three operations as SQL statements.
Which operation can violate what
| Domain | Key | Entity integrity | Referential integrity | Semantic | |
|---|---|---|---|---|---|
| Insert | ✓ | ✓ | ✓ | ✓ | ✓ |
| Delete | ✓ | ✓ | |||
| Modify | ✓ | ✓ | ✓ | ✓ | ✓ |
Insert can violate all five: it supplies fresh values for every attribute, so any of them can be out of domain, duplicate an existing key, leave a primary key component null, point at a nonexistent row, or break a business rule. Five candidate tuples for the same two-table schema, differing in one value each, show one of each:
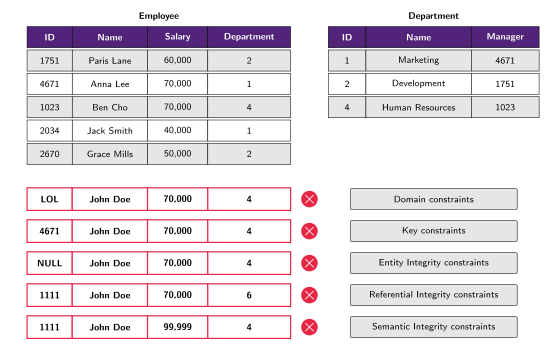
Figure 15: One insert, five ways to break it. Each candidate row differs from a legal Employee tuple in exactly one value, and each trips a different constraint: LOL is not a four-digit integer (domain), 4671 already exists (key), a null ID is a null primary key (entity integrity), department 6 is not in Department (referential integrity), and 99,999 exceeds the supervisor’s salary, which the business rule forbids (semantic). The crimson outline plus ✗ badge is the course’s notation for an illegal tuple.
Modification is the same picture: it can produce any of those five rows out of a legal one, so it inherits the whole column.
Delete is the interesting row. It supplies no values at all, so it cannot possibly produce an out-of-domain value, a duplicate key, or a null primary key. What it can do is remove a row that something else still references — a referential integrity violation on the other relation — or break a business rule. Both happen on the same two-table Employee/Department schema: deleting the department with id = 2 violates referential integrity, because employees still sit in it, while deleting employee 1023 violates a semantic constraint if the rule “every department must have at least one employee” has been stated. This asymmetry is worth remembering: for a delete, the only question is who points at the row being deleted.
Modify behaves like an insert restricted to the columns it touches: changing a key column risks a key violation, changing a foreign key risks a referential one, and changing a primary key component to NULL risks entity integrity.
Handling a referential violation on delete
Rejecting the operation isn’t the only option. At the relational-model stage there are exactly three outcomes for a referential integrity violation — it can be:
| Policy | Effect |
|---|---|
| Rejected | Refuse the delete; the referencing rows keep the referenced row alive |
| Cascaded | Delete the dependent rows too |
| Modified to a default value | Keep the dependent rows, but reset the referencing attribute’s value |
That three-way choice is what is examinable here; the finer-grained named actions — RESTRICT (the default), CASCADE, SET NULL and SET DEFAULT, each available on both delete and update — arrive with SQL DDL and are examined there, not at the model level. See sql-ddl for their exact semantics and syntax, and foreign-keys for the constraint itself.
The choice is a property of the foreign key, decided at design time from what the dependent rows mean without the row they reference: an insurance claim makes no sense without its policy, so EasyDrive declares its claims ON DELETE CASCADE.
Worked diagnoses
Against the company schema Employee [ssn, …, superSSN, dNumber], Department [dName, dNumber, mgrSSN, mgrStartDate], DeptLocations [dNumber, dLocation], Project [pName, pNumber, pLocation, dNum], WorksOn [essn, pNo, hours], Dependent [essn, depName, …], plus two business rules — an employee’s salary cannot exceed their supervisor’s, and a department cannot have more than three active projects:
| Operation | Violates |
|---|---|
Insert an employee with a fresh ssn, a real supervisor, salary below the supervisor’s |
Nothing — a well-formed insert |
Insert ('ProductA', 'A', 'Bellaire', 2) into Project when no department 2 exists |
Referential integrity and domain (pNumber is an integer, not 'A') |
Insert a department whose dNumber already exists and whose mgrSSN doesn’t |
Key and referential integrity |
Insert (677678989, null, 40.0) into WorksOn, essn not an employee |
Entity integrity (pNo is part of the key) and referential integrity |
| Insert an employee earning more than their supervisor | Semantic |
Delete the WorksOn rows for one employee |
Nothing — nothing references WorksOn, and no rule requires an employee to have assignments |
Delete an Employee row |
Referential integrity — WorksOn, Dependent, Department and Employee itself may all reference that ssn |
Modify a department’s mgrSSN to another existing employee |
Nothing, absent a stated rule about who may manage a department |
Modify an employee’s superSSN to an ssn that doesn’t exist |
Referential integrity |
| Insert a fourth active project for a department | Semantic |
Two habits fall out of this. First, always check whether the row being deleted is referenced, not just whether it exists. Second, “no violation” is a legitimate answer — several of the operations above are perfectly legal, and the temptation is to invent a rule that forbids them.
Failures cascade
A rejected operation changes nothing, which means later operations that assumed it succeeded fail too. In the EasyDrive case study, inserting a Vehicle with VehiclePurpose = 'Personal' fails on a domain constraint (the column is ENUM('Private', 'Business')); the next insert, a Policy referencing that vehicle, then fails on referential integrity even though its own values look fine. When a sequence of operations is being analysed, each one has to be judged against the state the previous ones actually left behind — not the state they were intended to leave.
The transaction concept
A transaction is an executing program containing database operations — reads, inserts, deletes, updates. The consistency requirement applies at the end of a transaction, not between its individual steps: constraint violations are permitted at intermediate points, as long as the final state satisfies every constraint specified on the schema.
A transaction is a walk between two consistent states. It starts from consistent state 1, and each INSERT, UPDATE or DELETE moves the database through intermediate states that need not satisfy the constraints; a COMMIT ends the walk at consistent state 2, while a ROLLBACK — or any error or failure along the way — returns the database to consistent state 1 as though nothing had happened. Either way the database is never left inconsistent.
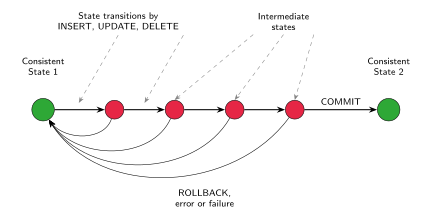
Figure 16: The transaction as a walk between consistent states. Green = a state satisfying every constraint, red = an intermediate state that need not. Only COMMIT and ROLLBACK end the walk, and both end it on a green state. The course has no house notation for transaction diagrams, so the shapes and colours here are not a convention to reproduce in an answer.
This is what makes mutually-dependent business rules satisfiable at all. Given “every department must have at least one employee” and “every employee must work for a department”, neither a new department (no employees yet) nor a new employee (no department yet) can be inserted on its own without breaking a rule. A single transaction that inserts the department and its first employee resolves the deadlock: the intermediate state after the first insert is inconsistent, but the final state after both inserts is valid, and that is the state the constraints are judged against.